In-Context LoRA (IC-LoRA)
🔥 Latest News!
- [2024-12-17] 🚀 We are excited to release IDEA-Bench, a comprehensive benchmark designed to assess the zero-shot task generalization abilities of generative models. The benchmark includes 100 real-world design tasks across 275 unique cases. Despite its general-purpose focus, the top-performing model, EMU2, achieves a score of only 6.81 out of 100, highlighting the current challenges in this domain. Explore the benchmark and challenge the limits of model performance!
- [2024-11-16] 🌟 The community continues to innovate with IC-LoRA! Exciting projects include models, ComfyUI nodes and workflows for Virtual Try-on, Product Design, Object Mitigation, Role Play, and more. Explore their creations in Community Creations Using IC-LoRA. Huge thanks to all contributors for their incredible efforts!
- [2024-11-07] 🚀 We have released 10 pretrained models for In-Context LoRA, covering diverse tasks such as Film Storyboard Generation, Visual Identity Design, and Visual Effects. See MODEL ZOO for details. We also provide an example workflow for ComfyUI.
- [2024-11-01] 📂 Data and training configurations for In-Context LoRA are now available!
- [2024-10-31] 📜 Our latest paper, In-Context LoRA, introduces a flexible framework adaptable to a wide range of tasks.
- [2024-10-19] 🎨 We released the paper Group Diffusion Transformers, the predecessor of In-Context LoRA, offering zero-shot support for 30 visual generation tasks.
- [2024-4-18] 💻 We release the code and models for FlashFace, a precursor to Group Diffusion Transformers, verifies attention token concatenation for customized generation scenarios.
Welcome to the official repository of In-Context LoRA for Diffusion Transformers (Paper and Project Page).
Community Creations Using IC-LoRA
We are thrilled to showcase the community's innovative projects leveraging In-Context LoRA (IC-LoRA). If you have additional recommendations or projects to share, please don't hesitate to send a Pull Request!
| Project Name | Type | Supported Tasks | Sample Results |
|---|---|---|---|
| 1. Comfyui_Object_Migration | ComfyUI Node & Workflow & LoRA Model | Clothing Migration, Cartoon Clothing to Realism, and More | 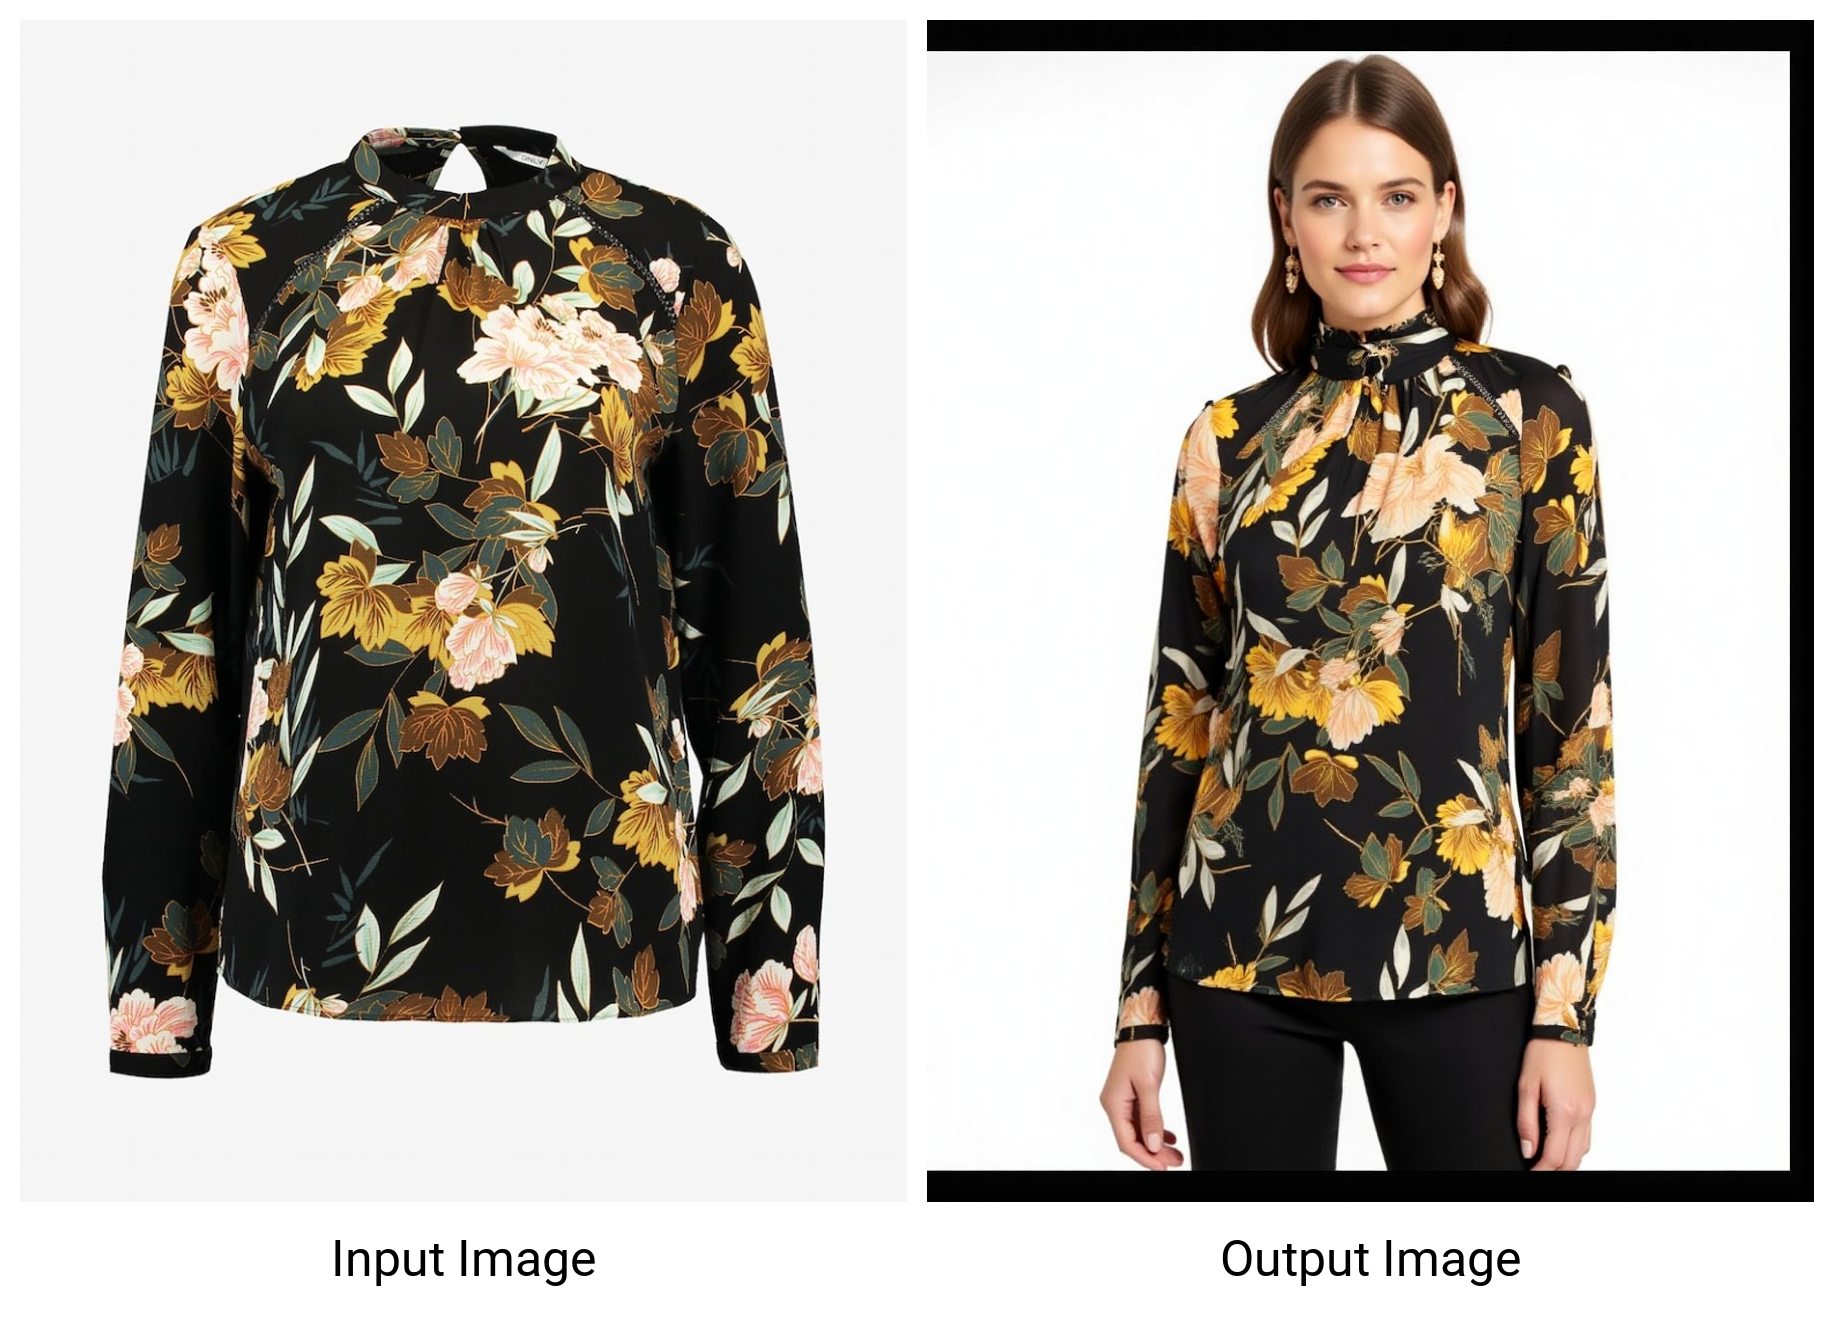 |
| 2. Flux Simple Try On - In Context Lora | LoRA Model & ComfyUI Workflow | Virtual Try-on |   |
| 3. Flux In Context - visual identity Lora in Comfy | ComfyUI Workflow | Visual Identity Transfer | 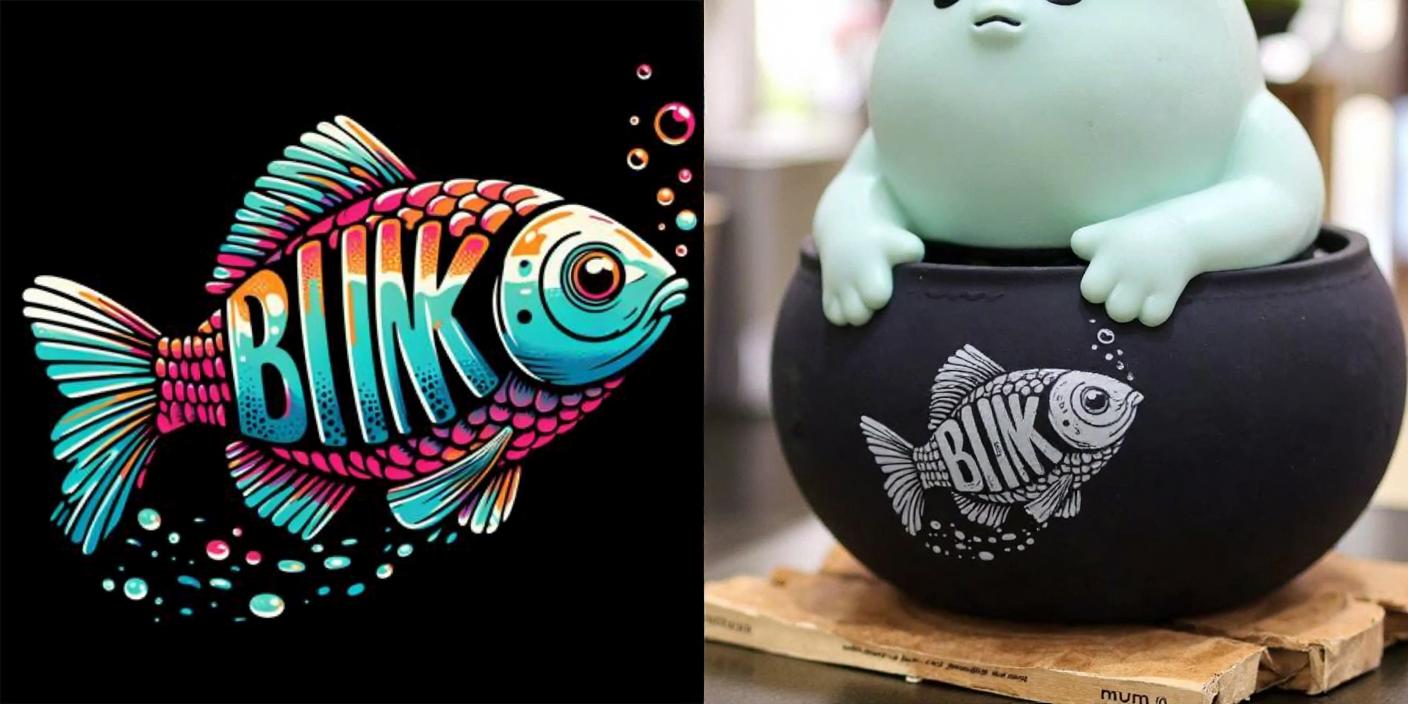 |
| 4. Workflows Flux In Context Lora For Product Design | ComfyUI Workflow | Product Design, Role Play, and More |  |
| 5. Flux Product Design - In Context Lora | LoRA Model & ComfyUI Workflow | Product Design | 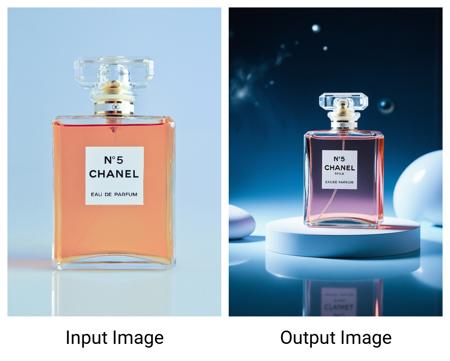 |
| 6. In Context lora + Character story generator + flux+ shichen | ComfyUI Workflow | Character Movie Story Generator | 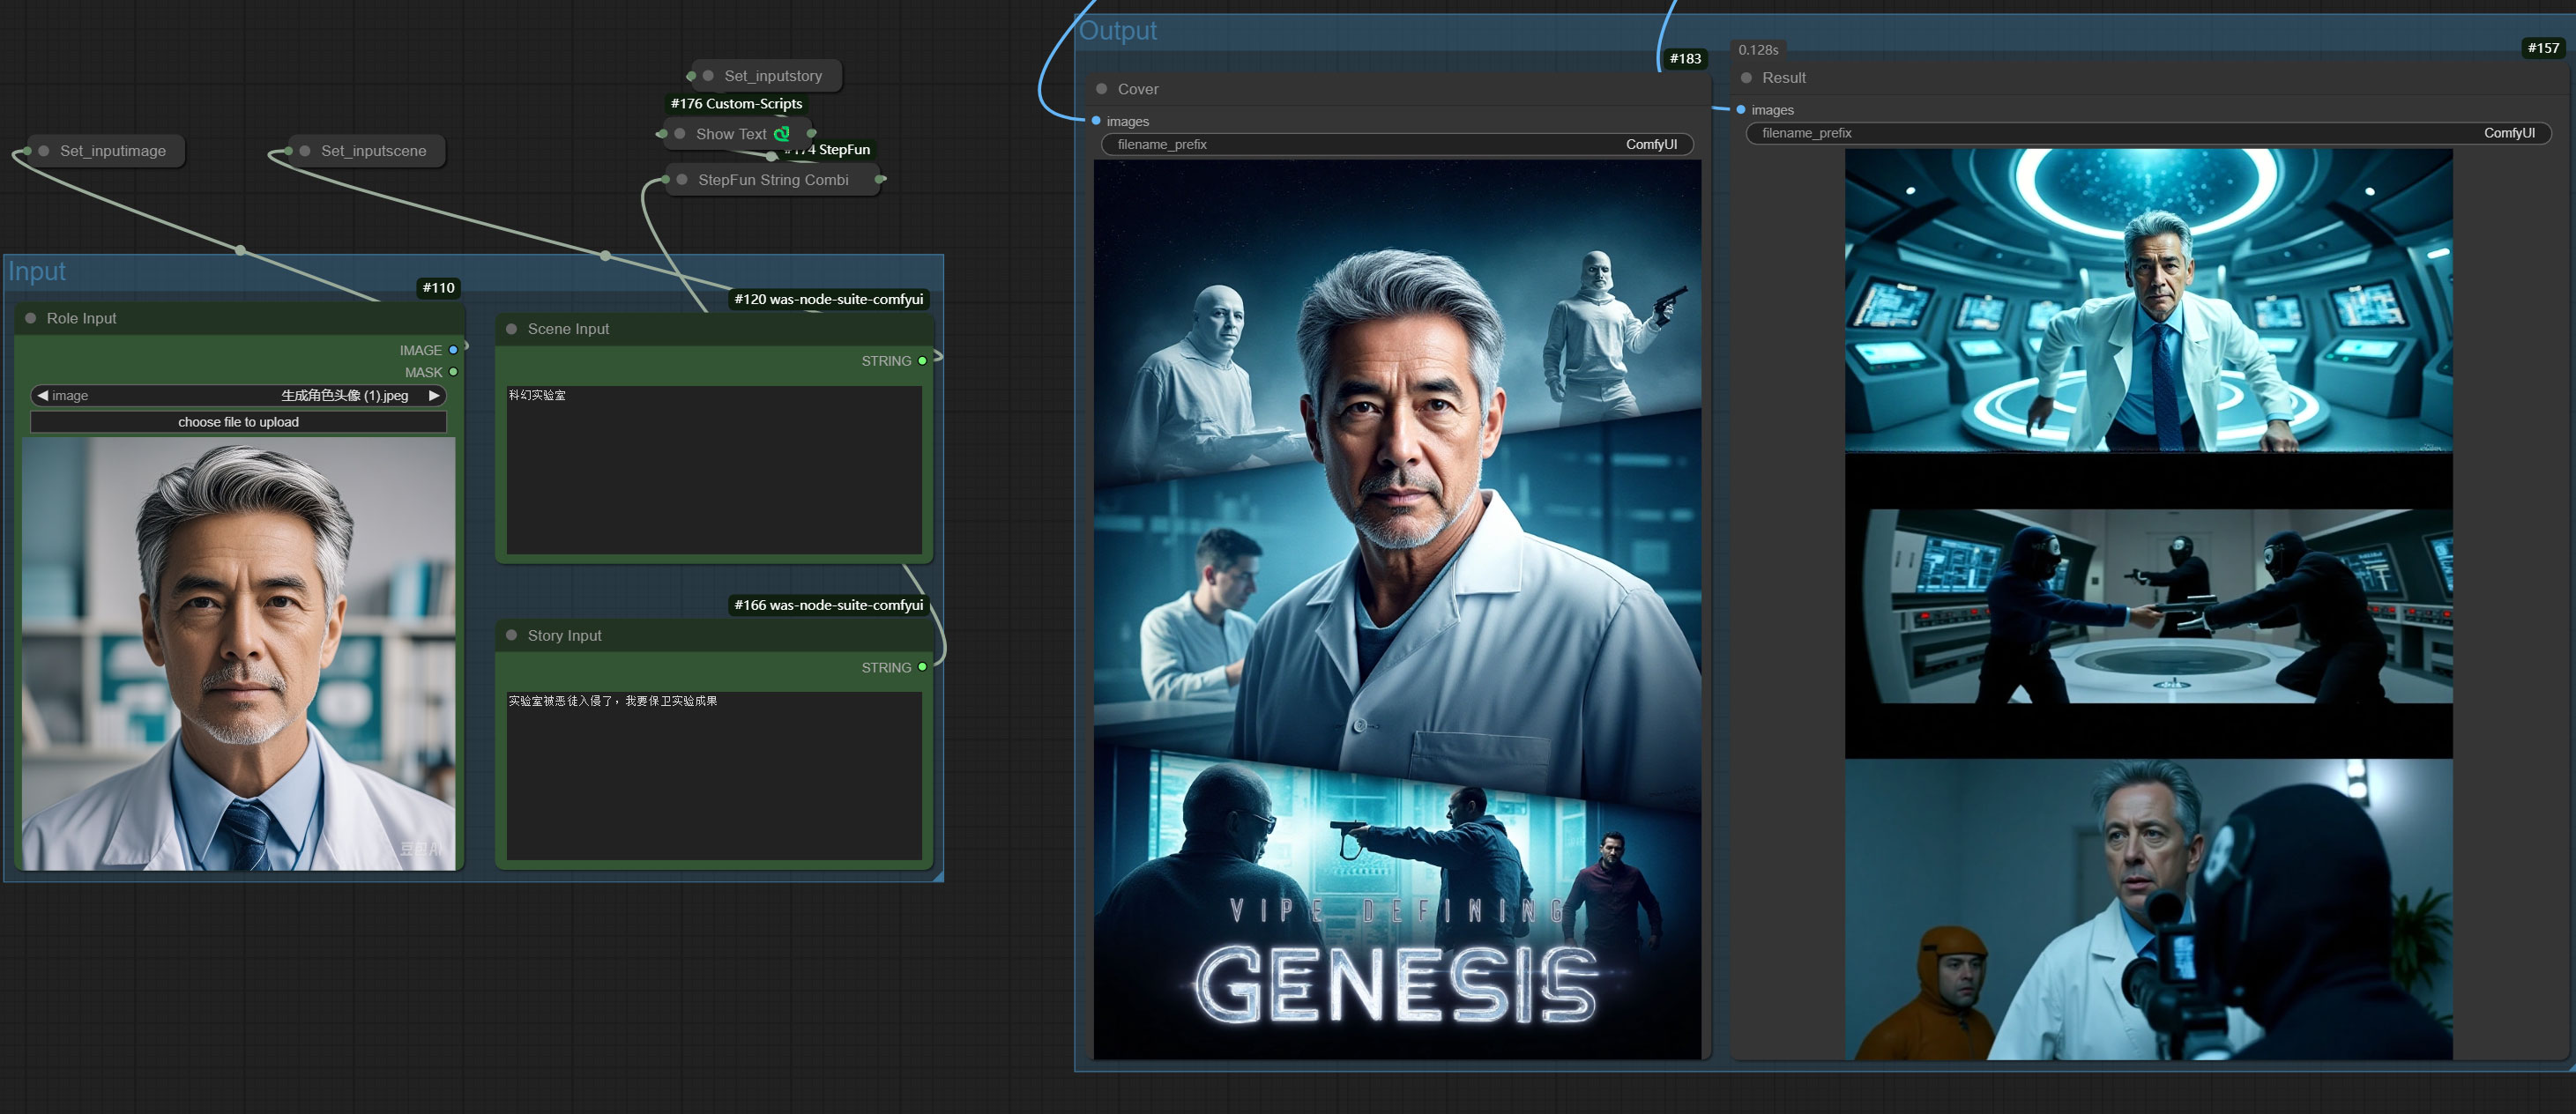 |
| 7. In- Context-Lora|Cute 4koma 可爱四格漫画 | LoRA Model & ComfyUI Workflow | Comic Strip Generation | 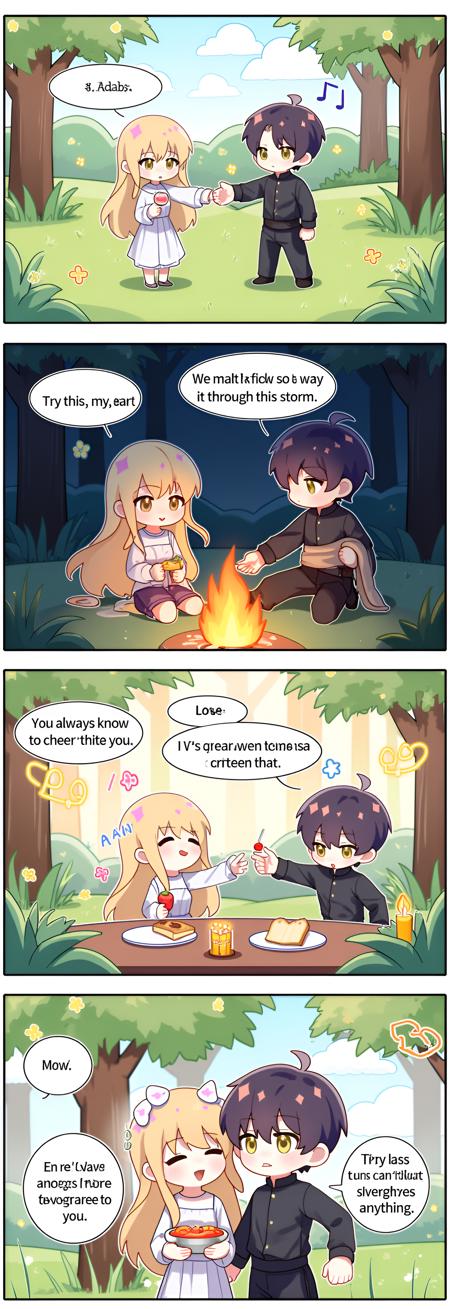 |
| 8. Creative Effects & Design LoRA Pack (In-Context LORA) | LoRA Model & ComfyUI Workflow | Movie-Shot Generation and More | 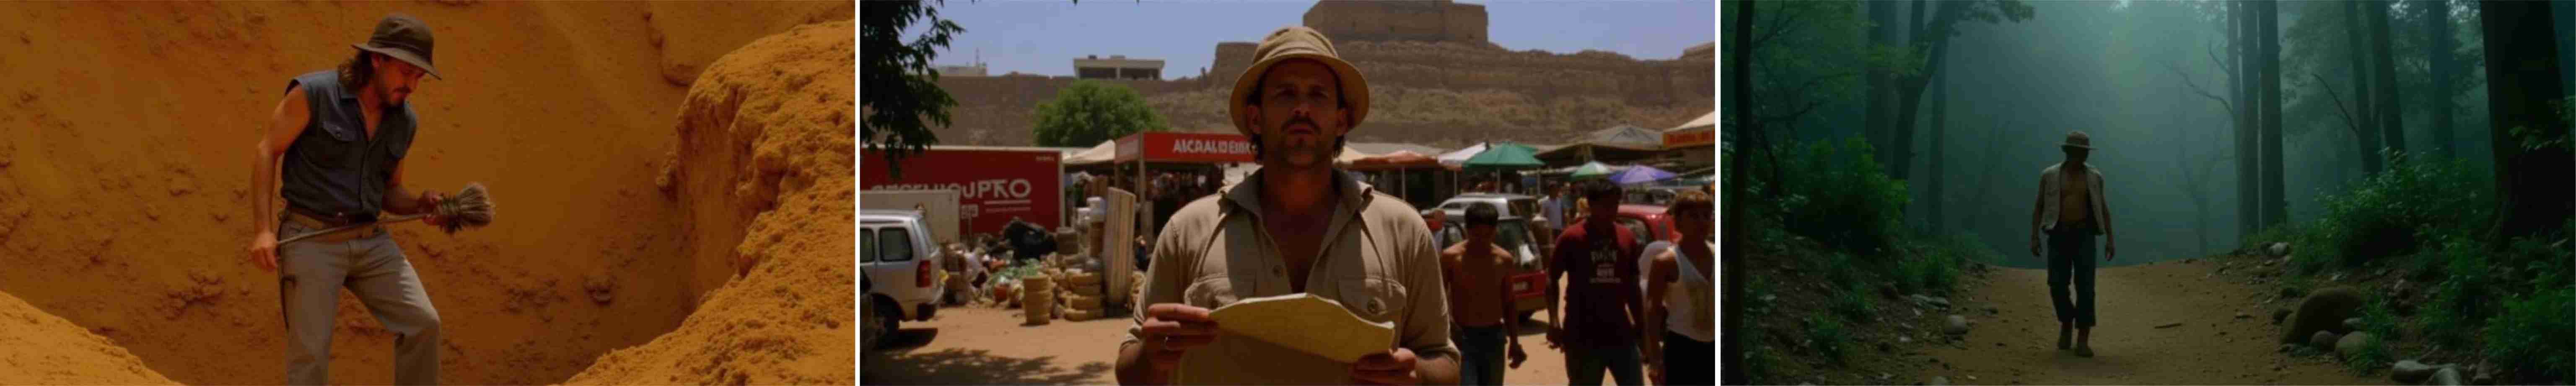 |
We extend our heartfelt thanks to all contributors for their exceptional work in advancing the IC-LoRA ecosystem.
Key Idea
The core concept of IC-LoRA is to concatenate both condition and target images into a single composite image while using Natural Language to define the task. This approach enables seamless adaptation to a wide range of applications.
Features
- Task-Agnostic Framework: IC-LoRA serves as a general framework, but it requires task-specific fine-tuning for diverse applications.
- Customizable Image-Set Generation: You can fine-tune text-to-image models to generate image sets with customizable intrinsic relationships.
- Condition on Image-Set: You can also condition the generation of a set of images on another set of images, enabling a wide range of controllable generation applications.
For more detailed information and examples, please read our Paper or visit our Project Page.
Getting Started
You can directly use the open-source AI-Toolkit to train IC-LoRA models. We have provided sample training data with a configuration file in this repo:
- Configuration File:
config/movie-shots.yml(place it in theconfig/directory of AI-Toolkit) - Sample Training Data:
data/movie-shots.zip(extract it todata/movie-shotsof AI-Toolkit)
After installing the necessary dependencies and setting up AI-Toolkit, you can start training by running:
python run.py config/movie-shots.yml
The training runs on a single GPU with at least 24GB of memory (adjust the resolution parameter in config/movie-shots.yml for different GPU memory limits). The training should complete in a few hours.
Prompt for Multi-Scene Image Captioning
As a reference, we provide an example prompt used to generate captions for multi-scene images:
Create a short description of this three-scene image featuring movie shots, beginning with the prefix [MOVIE-SHOTS] for the entire caption, followed by an overall summary of the image. Each scene detail should flow within the same sentence, with specific markers [SCENE-1], [SCENE-2], [SCENE-3], indicating the start of each scene’s description. Name the role(s) with random name(s) if necessary, and wrap the name(s) with "<" and ">". Ensure the entire description is cohesive, flows as one sentence, and remains within 512 words.
MODEL ZOO
Below lists 10 In-Context LoRA models and their recommend settings. We provide an example workflow for ComfyUI.
| Task | Model | Recommend Settings | Example Prompt |
|---|---|---|---|
| 1. Couple Profile Design | couple-profile.safetensors |
width: 2048, height: 1024 |
This two-part image portrays a couple of cartoon cats in detective attire; [LEFT] a black cat in a trench coat and fedora holds a magnifying glass and peers to the right, while [RIGHT] a white cat with a bow tie and matching hat raises an eyebrow in curiosity, creating a fun, noir-inspired scene against a dimly lit background. |
| 2. Film Storyboard | film-storyboard.safetensors |
width: 1024, height: 1536 |
[MOVIE-SHOTS] In a vibrant festival, [SCENE-1] we find , a shy boy, standing at the edge of a bustling carnival, eyes wide with awe at the colorful rides and laughter, [SCENE-2] transitioning to him reluctantly trying a daring game, his friends cheering him on, [SCENE-3] culminating in a triumphant moment as he wins a giant stuffed bear, his face beaming with pride as he holds it up for all to see. |
| 3. Font Design | font-design.safetensors |
width: 1792, height: 1216 |
The four-panel image showcases a playful bubble font in a vibrant pop-art style. [TOP-LEFT] displays "Pop Candy" in bright pink with a polka dot background; [TOP-RIGHT] shows "Sweet Treat" in purple, surrounded by candy illustrations; [BOTTOM-LEFT] has "Yum!" in a mix of bright colors; [BOTTOM-RIGHT] shows "Delicious" against a striped background, perfect for fun, kid-friendly products. |
| 4. Home Decoration | home-decoration.safetensors |
width: 1344, height: 1728 |
This four-panel image showcases a rustic living room with warm wood tones and cozy decor elements; [TOP-LEFT] features a large stone fireplace with wooden shelves filled with books and candles; [TOP-RIGHT] shows a vintage leather sofa draped in plaid blankets, complemented by a mix of textured cushions; [BOTTOM-LEFT] displays a corner with a wooden armchair beside a side table holding a steaming mug and a classic book; [BOTTOM-RIGHT] captures a cozy reading nook with a window seat, a soft fur throw, and decorative logs stacked neatly. |
| 5. Portrait Illustration | portrait-illustration.safetensors |
width: 1152, height: 1088 |
This two-panel image presents a transformation from a realistic portrait to a playful illustration, capturing both detail and artistic flair; [LEFT] the photograph shows a woman standing in a bustling marketplace, wearing a wide-brimmed hat, a flowing bohemian dress, and a leather crossbody bag; [RIGHT] the illustration panel exaggerates her accessories and features, with the bohemian dress depicted in vibrant patterns and bold colors, while the background is simplified into abstract market stalls, giving the scene an animated and lively feel. |
| 6. Portrait Photography | portrait-photography.safetensors |
width: 1344, height: 1728 |
This [FOUR-PANEL] image illustrates a young artist's creative process in a bright and inspiring studio; [TOP-LEFT] she stands before a large canvas, brush in hand, adding vibrant colors to a partially completed painting, [TOP-RIGHT] she sits at a cluttered wooden table, sketching ideas in a notebook with various art supplies scattered around, [BOTTOM-LEFT] she takes a moment to step back and observe her work, adjusting her glasses thoughtfully, and [BOTTOM-RIGHT] she experiments with different textures by mixing paints directly on the palette, her focused expression showcasing her dedication to her craft. |
| 7. PPT Template | ppt-templates.safetensors |
width: 1984, height: 1152 |
This four-panel image showcases a rustic-themed PowerPoint template for a culinary workshop; [TOP-LEFT] introduces "Farm to Table Cooking" in warm, earthy tones; [TOP-RIGHT] organizes workshop sections like "Ingredients," "Preparation," and "Serving"; [BOTTOM-LEFT] displays ingredient lists for seasonal produce; [BOTTOM-RIGHT] includes chef profiles with short bios. |
| 8. Sandstorm Visual Effect | sandstorm-visual-effect.safetensors |
width: 1408, height: 1600 |
[SANDSTORM-PSA] This two-part image showcases the transformation of a cyclist through a sandstorm visual effect; [TOP] the upper panel features a cyclist in vibrant gear pedaling steadily on a clear, open road with a serene sky in the background, highlighting focus and determination, [BOTTOM] the lower panel transforms the scene as the cyclist becomes enveloped in a fierce sandstorm, with sand particles swirling intensely around the bike and rider against a stormy, darkened backdrop, emphasizing chaos and power. |
| 9. Sparklers Visual Effect | sparklers-visual-effect.safetensors |
width: 960, height: 1088 |
[REAL-SPARKLERS-OVERLAYS] The two-part image vividly illustrates a woodland proposal transformed by sparkler overlays; [TOP] the first panel depicts a man kneeling on one knee with an engagement ring before his partner in a forest clearing at dusk, with warm, natural lighting, [BOTTOM] while the second panel introduces glowing sparklers that form a heart shape around the couple, amplifying the romance and joy of the moment. |
| 10. Visual Identity Design | visual-identity-design.safetensors |
width: 1472, height: 1024 |
The two-panel image showcases the joyful identity of a produce brand, with the left panel showing a smiling pineapple graphic and the brand name “Fresh Tropic” in a fun, casual font on a light aqua background; [LEFT] while the right panel translates the design onto a reusable shopping tote with the pineapple logo in black, held by a person in a market setting, emphasizing the brand’s approachable and eco-friendly vibe. |
License
This repository uses FLUX as the base model. Users must comply with FLUX's license when using this code. Please refer to FLUX's License for more details.
DISCLAIMER: Please be aware that the training data provided in this repository may contain copyrighted material. The open-source data is intended for reference and educational purposes only. If you plan to use this data for commercial purposes, you are responsible for obtaining the necessary permissions and ensuring compliance with all applicable copyright laws and regulations.
Citation
If you find this work useful in your research, please consider citing:
@article{lhhuang2024iclora,
  title={In-Context LoRA for Diffusion Transformers},
  author={Huang, Lianghua and Wang, Wei and Wu, Zhi-Fan and Shi, Yupeng and Dou, Huanzhang and Liang, Chen and Feng, Yutong and Liu, Yu and Zhou, Jingren},
  journal={arXiv preprint arxiv:2410.23775},
  year={2024}
}
@article{lhhuang2024groupdiffusion,
  title={Group Diffusion Transformers are Unsupervised Multitask Learners},
  author={Huang, Lianghua and Wang, Wei and Wu, Zhi-Fan and Dou, Huanzhang and Shi, Yupeng and Feng, Yutong and Liang, Chen and Liu, Yu and Zhou, Jingren},
  journal={arXiv preprint arxiv:2410.15027},
  year={2024}
}