← 开源
NVIDIA-AI-IOT

Lidar_AI_Solution

A project demonstrating Lidar related AI solutions, including three GPU accelerated Lidar/camera DL networks (PointPillars, CenterPoint, BEVFusion) and the related libs (cuPCL, 3D SparseConvolution, YUV2RGB, cuOSD,).

InfrastructureInference service optimizationC++
在 GitHub 打开
增长势头
+024 小时新增 Star0.0%
1.90k
Star
340
Fork
+3
本周
8
贡献者
创建于 2023-05-15 · 更新于 2026-10-15 · 今日第 9286 名
主要开发者
hopefbyte-devenvqiezi

NVIDIA-AI-IOT/Lidar_AI_Solution 排名第 9,286,有 1,897 个星标。

同类别比较

NVIDIA-AI-IOT/Lidar_AI_Solution 排名第 9,286,此处有 8 个同类条目;NVIDIA-AI-IOT/deepstream_python_apps 排名第 9,287。

同类别比较
名称排名指标
uTensor/uTensor9,228
语言:
C++
星标数:
1,935
分叉数:
251
简介:
TinyML AI inference library
NVlabs/nvdiffrast9,230
语言:
C++
星标数:
1,932
分叉数:
248
简介:
Nvdiffrast - Modular Primitives for High-Performance Differentiable Rendering
S-LoRA/S-LoRA9,243
语言:
Python
星标数:
1,924
分叉数:
129
简介:
S-LoRA: Serving Thousands of Concurrent LoRA Adapters
Tencent/plato9,261
语言:
C++
星标数:
1,910
分叉数:
328
简介:
腾讯高性能分布式图计算框架Plato
NVIDIA-AI-IOT/deepstream_python_apps9,287
语言:
Jupyter Notebook
星标数:
1,897
分叉数:
534
简介:
DeepStream SDK Python bindings and sample applications
uber/petastorm9,294
语言:
Python
星标数:
1,895
分叉数:
286
简介:
Petastorm library enables single machine or distributed training and evaluation of deep learning models from datasets in Apache Parquet format. It supports ML frameworks such as Tensorflow, Pytorch, and PySpark and can be used from pure Python code.
7836246/cursor2api9,300
语言:
TypeScript
星标数:
1,891
分叉数:
517
简介:
将 Cursor Web Docs 免费 API 转换为 OpenAI/Anthropic 兼容格式的代理服务。提供 Claude Code工具及图片支持。
lakshayg/tensorflow-build-archived9,303
语言:
Shell
星标数:
1,891
分叉数:
218
简介:
TensorFlow binaries supporting AVX, FMA, SSE
关键参数与规格
关键参数与规格
参数值
语言C++
类别Infrastructure
子类别Inference service optimization
星标数1,897
分叉数340
贡献者8
创建日期2023-05-15
更新日期2026-10-15
1 天星标数0
7 天星标数3
排名9,286
上次排名5,430
排名变化-3,856
7 天星标排名6,826
上次 7 天星标排名7,926
7 天星标排名变化1,100
总星标排名6,631
上次总星标排名6,624
总星标排名变化-7
国家USA
README 摘录

Lidar AI Solution This is a highly optimized solution for self-driving 3D-lidar repository. It does a great job of speeding up sparse convolution/CenterPoint/BEVFusion/OSD/Conversion. Pipeline overview GetStart For each specific task please refer to the readme in the sub-folder. 3D Sparse Convolution A tiny inference engine for 3d sparse convolutional networks using int8/fp16. **Tiny Engine:** Tiny Lidar-Backbone inference engine independent of TensorRT. **Flexible:** Build execution graph from ONNX. **Easy To Use:** Simple

interface and onnx export solution. **High Fidelity:** Low accuracy drop on nuScenes validation. **Low Memory:** 422MB@SCN FP16, 426MB@SCN INT8. **Compact:** Based on the CUDA kernels and independent of cutlass. CUDA BEVFusion CUDA & TensorRT solution for BEVFusion inference, including: **Camera Encoder**: ResNet50 and finetuned BEV pooling with TensorRT and onnx export solution. **Lidar Encoder**: Tiny Lidar-Backbone inference independent of TensorRT and onnx export solution. **Feature Fusion**: Camera & Lidar feature fuser with TensorRT and onnx export solution. **Pre/Postprocess

**: Interval precomputing, lidar voxelization, feature decoder with CUDA kernels. **Easy To Use**: Preparation, inference, evaluation all in one to reproduce torch Impl accuracy. **PTQ**: Quantization solutions for mmdet3d/spconv, Easy to understand. CUDA CenterPoint CUDA & TensorRT solution for CenterPoint inference, including: **Preprocess**: Voxelization with CUDA kernel **Encoder**: 3D backbone with NV spconv-scn and onnx export solution. **Neck & Header**: RPN & CenterHead with TensorRT and onnx export solution. **Postprocess**: Decode & NMS with CUDA kernel **Easy To Use**: Preparation, inference, evaluation all

in one to reproduce torch Impl accuracy. **QAT**: Quantization solutions for traveller59/spconv, Easy to understand. CUDA PointPillars CUDA & TensorRT solution for pointpillars inference, including: **Preprocess**: Voxelization & Feature Extending with CUDA kernel **Detector**: 2. 5D backbone with TensorRT and onnx export solution. **Postprocess**: Parse bounding box, class type and direction **Easy To Use**: Preparation, inference, evaluation all in one to reproduce torch Impl accuracy. CUDA-V2XFusion Training and inference solutions for V2XFusion. **Easy To Use**: Provides easily reproducible solutions for

training, quantization, and ONNX export. **Quantification friendly**:PointPillars based backbone with pre-normalization which can reduce quantization error. **Feature Fusion**: Camera & Lidar feature fuser and onnx export solution. **PTQ**: Quantization solutions for V2XFusion, easy to understand. **Sparsity**: 4:2 structural sparsity support. **Deepstream sample**: Sample inference using CUDA, TensorRT/Triton in NVIDIA DeepStream SDK 7. cuOSD(CUDA On-Screen Display Library) Draw all elements using a single CUDA kernel. **Line:** Plotting lines by interpolation(Nearest or Linear). **RotateBox:** Supports drawn

with different border colors and fill colors. **Circle:** Supports drawn with different border colors and fill colors. **Rectangle:** Supports drawn with different border colors and fill colors. **Text:** Supports stb_truetype and pango-cairo backends, allowing fonts to be read via TTF or using font-family. **Arrow:** Combination of arrows by 3 lines. **Point:** Plotting points by interpolation(Nearest or Linear). **Clock:** Time plotting based on text support cuPCL(CUDA Point Cloud Library) Provide several GPU accelerated Point Cloud operations

with high accuracy and high performance at the same time: cuICP, cuFilter, cuSegmentation, cuOctree, cuCluster, cuNDT, Voxelization(incoming). **cuICP:** CUDA

常见问题

记录了多少星标和分叉?

NVIDIA-AI-IOT/Lidar_AI_Solution 有 1,897 个星标和 340 个分叉。

仓库排名是多少?

NVIDIA-AI-IOT/Lidar_AI_Solution 排名第 9,286。

记录的语言和类别是什么?

NVIDIA-AI-IOT/Lidar_AI_Solution 有 1,897 个星标,语言为 C++,类别为 Infrastructure。

哪个仓库排名最接近?

NVIDIA-AI-IOT/Lidar_AI_Solution 与 NVIDIA-AI-IOT/deepstream_python_apps 比较,后者排名第 9,287,有 1,897 个星标。

README

Lidar AI Solution

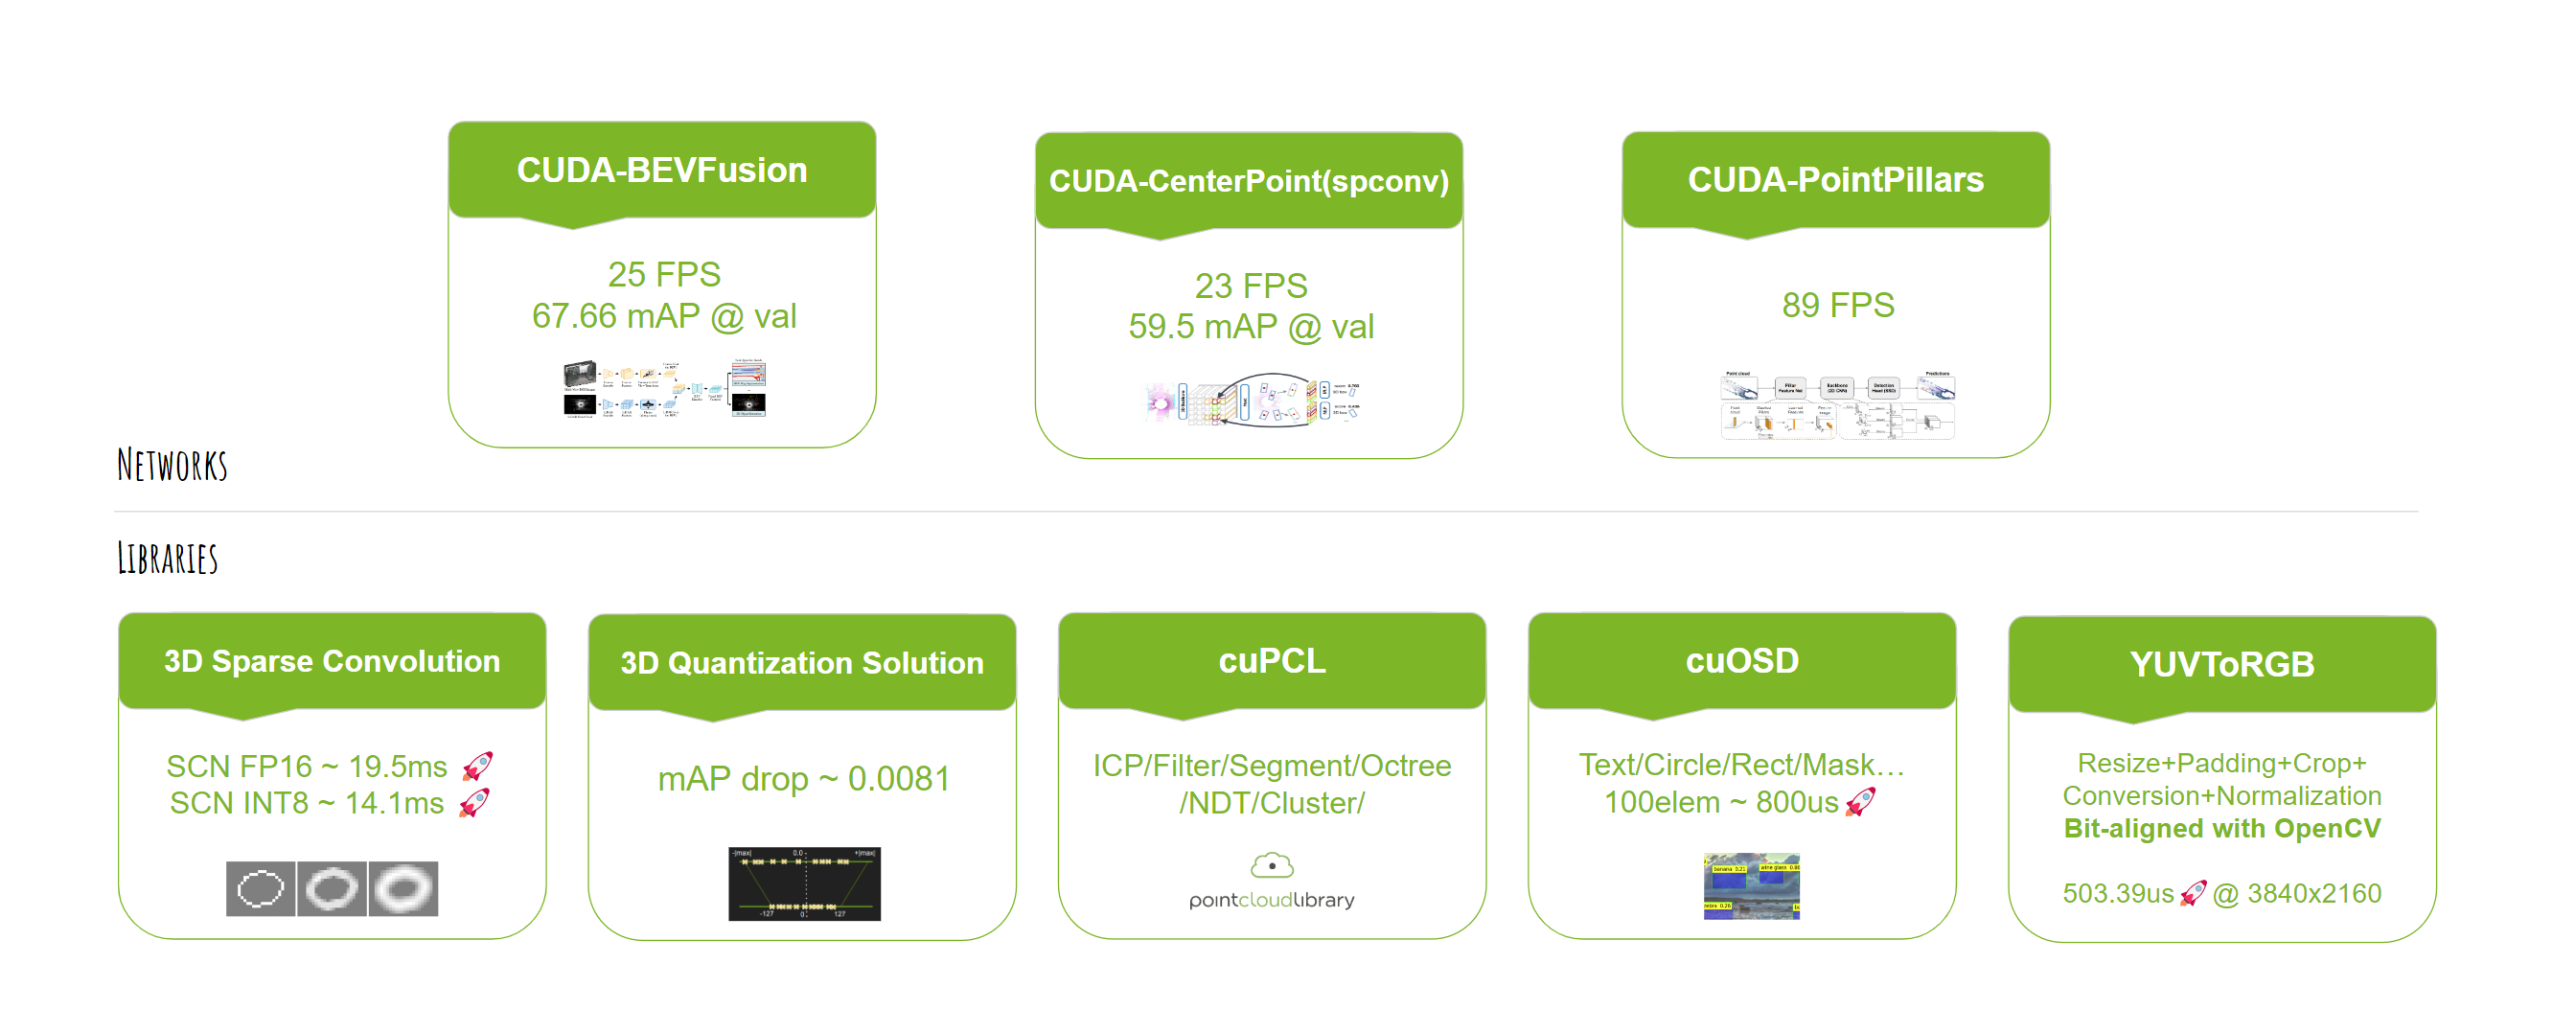
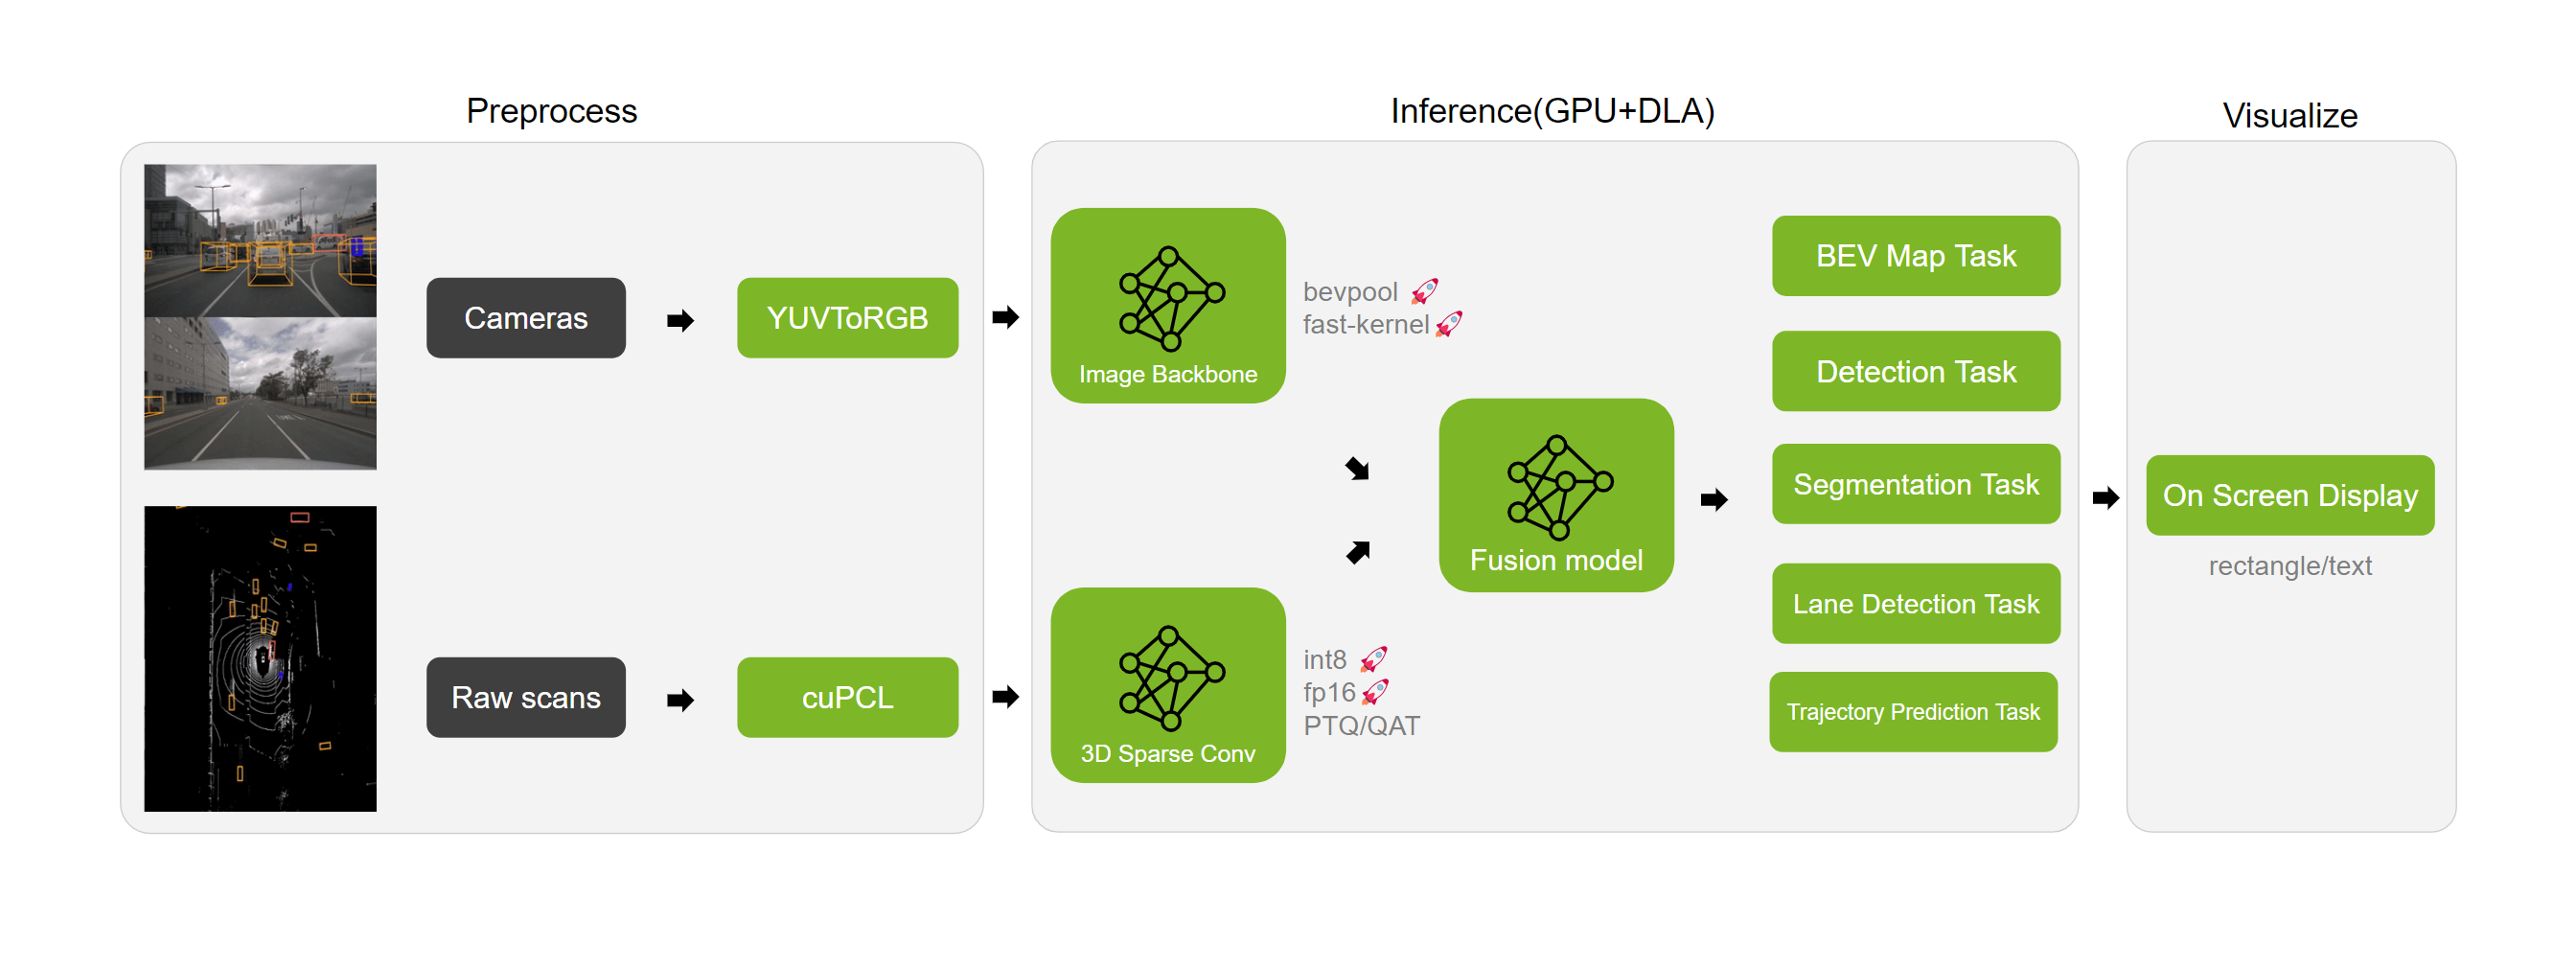
This is a highly optimized solution for self-driving 3D-lidar repository. It does a great job of speeding up sparse convolution/CenterPoint/BEVFusion/OSD/Conversion.
Pipeline overview
GetStart

$ git clone --recursive https://github.com/NVIDIA-AI-IOT/Lidar_AI_Solution
$ cd Lidar_AI_Solution
  • For each specific task please refer to the readme in the sub-folder.

3D Sparse Convolution

A tiny inference engine for 3d sparse convolutional networks using int8/fp16.

  • Tiny Engine: Tiny Lidar-Backbone inference engine independent of TensorRT.
  • Flexible: Build execution graph from ONNX.
  • Easy To Use: Simple interface and onnx export solution.
  • High Fidelity: Low accuracy drop on nuScenes validation.
  • Low Memory: 422MB@SCN FP16, 426MB@SCN INT8.
  • Compact: Based on the CUDA kernels and independent of cutlass.

CUDA BEVFusion

CUDA & TensorRT solution for BEVFusion inference, including:

  • Camera Encoder: ResNet50 and finetuned BEV pooling with TensorRT and onnx export solution.
  • Lidar Encoder: Tiny Lidar-Backbone inference independent of TensorRT and onnx export solution.
  • Feature Fusion: Camera & Lidar feature fuser with TensorRT and onnx export solution.
  • Pre/Postprocess: Interval precomputing, lidar voxelization, feature decoder with CUDA kernels.
  • Easy To Use: Preparation, inference, evaluation all in one to reproduce torch Impl accuracy.
  • PTQ: Quantization solutions for mmdet3d/spconv, Easy to understand.

CUDA CenterPoint

CUDA & TensorRT solution for CenterPoint inference, including:

  • Preprocess: Voxelization with CUDA kernel
  • Encoder: 3D backbone with NV spconv-scn and onnx export solution.
  • Neck & Header: RPN & CenterHead with TensorRT and onnx export solution.
  • Postprocess: Decode & NMS with CUDA kernel
  • Easy To Use: Preparation, inference, evaluation all in one to reproduce torch Impl accuracy.
  • QAT: Quantization solutions for traveller59/spconv, Easy to understand.

CUDA PointPillars

CUDA & TensorRT solution for pointpillars inference, including:

  • Preprocess: Voxelization & Feature Extending with CUDA kernel
  • Detector: 2.5D backbone with TensorRT and onnx export solution.
  • Postprocess: Parse bounding box, class type and direction
  • Easy To Use: Preparation, inference, evaluation all in one to reproduce torch Impl accuracy.

CUDA-V2XFusion

Training and inference solutions for V2XFusion.

  • Easy To Use: Provides easily reproducible solutions for training, quantization, and ONNX export.
  • Quantification friendly:PointPillars based backbone with pre-normalization which can reduce quantization error.
  • Feature Fusion: Camera & Lidar feature fuser and onnx export solution.
  • PTQ: Quantization solutions for V2XFusion, easy to understand.
  • Sparsity: 4:2 structural sparsity support.
  • Deepstream sample: Sample inference using CUDA, TensorRT/Triton in NVIDIA DeepStream SDK 7.0.

cuOSD(CUDA On-Screen Display Library)

Draw all elements using a single CUDA kernel.

  • Line: Plotting lines by interpolation(Nearest or Linear).
  • RotateBox: Supports drawn with different border colors and fill colors.
  • Circle: Supports drawn with different border colors and fill colors.
  • Rectangle: Supports drawn with different border colors and fill colors.
  • Text: Supports stb_truetype and pango-cairo backends, allowing fonts to be read via TTF or using font-family.
  • Arrow: Combination of arrows by 3 lines.
  • Point: Plotting points by interpolation(Nearest or Linear).
  • Clock: Time plotting based on text support

cuPCL(CUDA Point Cloud Library)

Provide several GPU accelerated Point Cloud operations with high accuracy and high performance at the same time: cuICP, cuFilter, cuSegmentation, cuOctree, cuCluster, cuNDT, Voxelization(incoming).

  • cuICP: CUDA accelerated iterative corresponding point vertex cloud(point-to-point) registration implementation.
  • cuFilter: Support CUDA accelerated features: PassThrough and VoxelGrid.
  • cuSegmentation: Support CUDA accelerated features: RandomSampleConsensus with a plane model.
  • cuOctree: Support CUDA accelerated features: Approximate Nearest Search and Radius Search.
  • cuCluster: Support CUDA accelerated features: Cluster based on the distance among points.
  • cuNDT: CUDA accelerated 3D Normal Distribution Transform registration implementation for point cloud data.

YUVToRGB(CUDA Conversion)

YUV to RGB conversion. Combine Resize/Padding/Conversion/Normalization into a single kernel function.

  • Most of the time, it can be bit-aligned with OpenCV.
    • It will give an exact result when the scaling factor is a rational number.
    • Better performance is usually achieved when the stride can divide by 4.
  • Supported Input Format:
    • NV12BlockLinear
    • NV12PitchLinear
    • YUV422Packed_YUYV
  • Supported Interpolation methods:
    • Nearest
    • Bilinear
  • Supported Output Data Type:
    • Uint8
    • Float32
    • Float16
  • Supported Output Layout:
    • CHW_RGB/BGR
    • HWC_RGB/BGR
    • CHW16/32/4/RGB/BGR for DLA input
  • Supported Features:
    • Resize
    • Padding
    • Conversion
    • Normalization

ROI Conversion (ROIs To Continuous Tensor Conversion)

Combine Resize/Padding/Conversion/Normalization into a single kernel function.

  • Most of the time, it can be bit-aligned with OpenCV.
    • It will give an exact result when the scaling factor is a rational number.
    • Better performance is usually achieved when the stride can divide by 4.
  • Supported Input Format:
    • NV12BlockLinear
    • NV12PitchLinear
    • YUV422Packed_YUYV
  • Supported Interpolation methods:
    • Nearest
    • Bilinear
  • Supported Output Data Type:
    • Uint8
    • Float32
    • Float16
  • Supported Output Layout:
    • CHW_RGB/BGR
    • HWC_RGB/BGR
    • CHW16/32/4/RGB/BGR for DLA input
    • Gray
  • Supported Features:
    • Resize
    • Padding
    • Conversion
    • Normalization

Thanks

This project makes use of a number of awesome open source libraries, including:

  • stb_image for PNG and JPEG support
  • pybind11 for seamless C++ / Python interop
  • and others! See the dependencies folder.

Many thanks to the authors of these brilliant projects!

排名相邻
同类项目