TANGO: Co-Speech Gesture Video Reenactment with Hierarchical Audio-Motion Embedding and Diffusion Interpolation
)
News
Welcome contributors! Feel free to submit the pull requests!
- [2024/10] Welcome to try our TANGO on Hugging face space !
- [2024/10] Code for creating gesture graph is available.
- [2024/10] Video data download Google Drive (show-oliver and harward business)
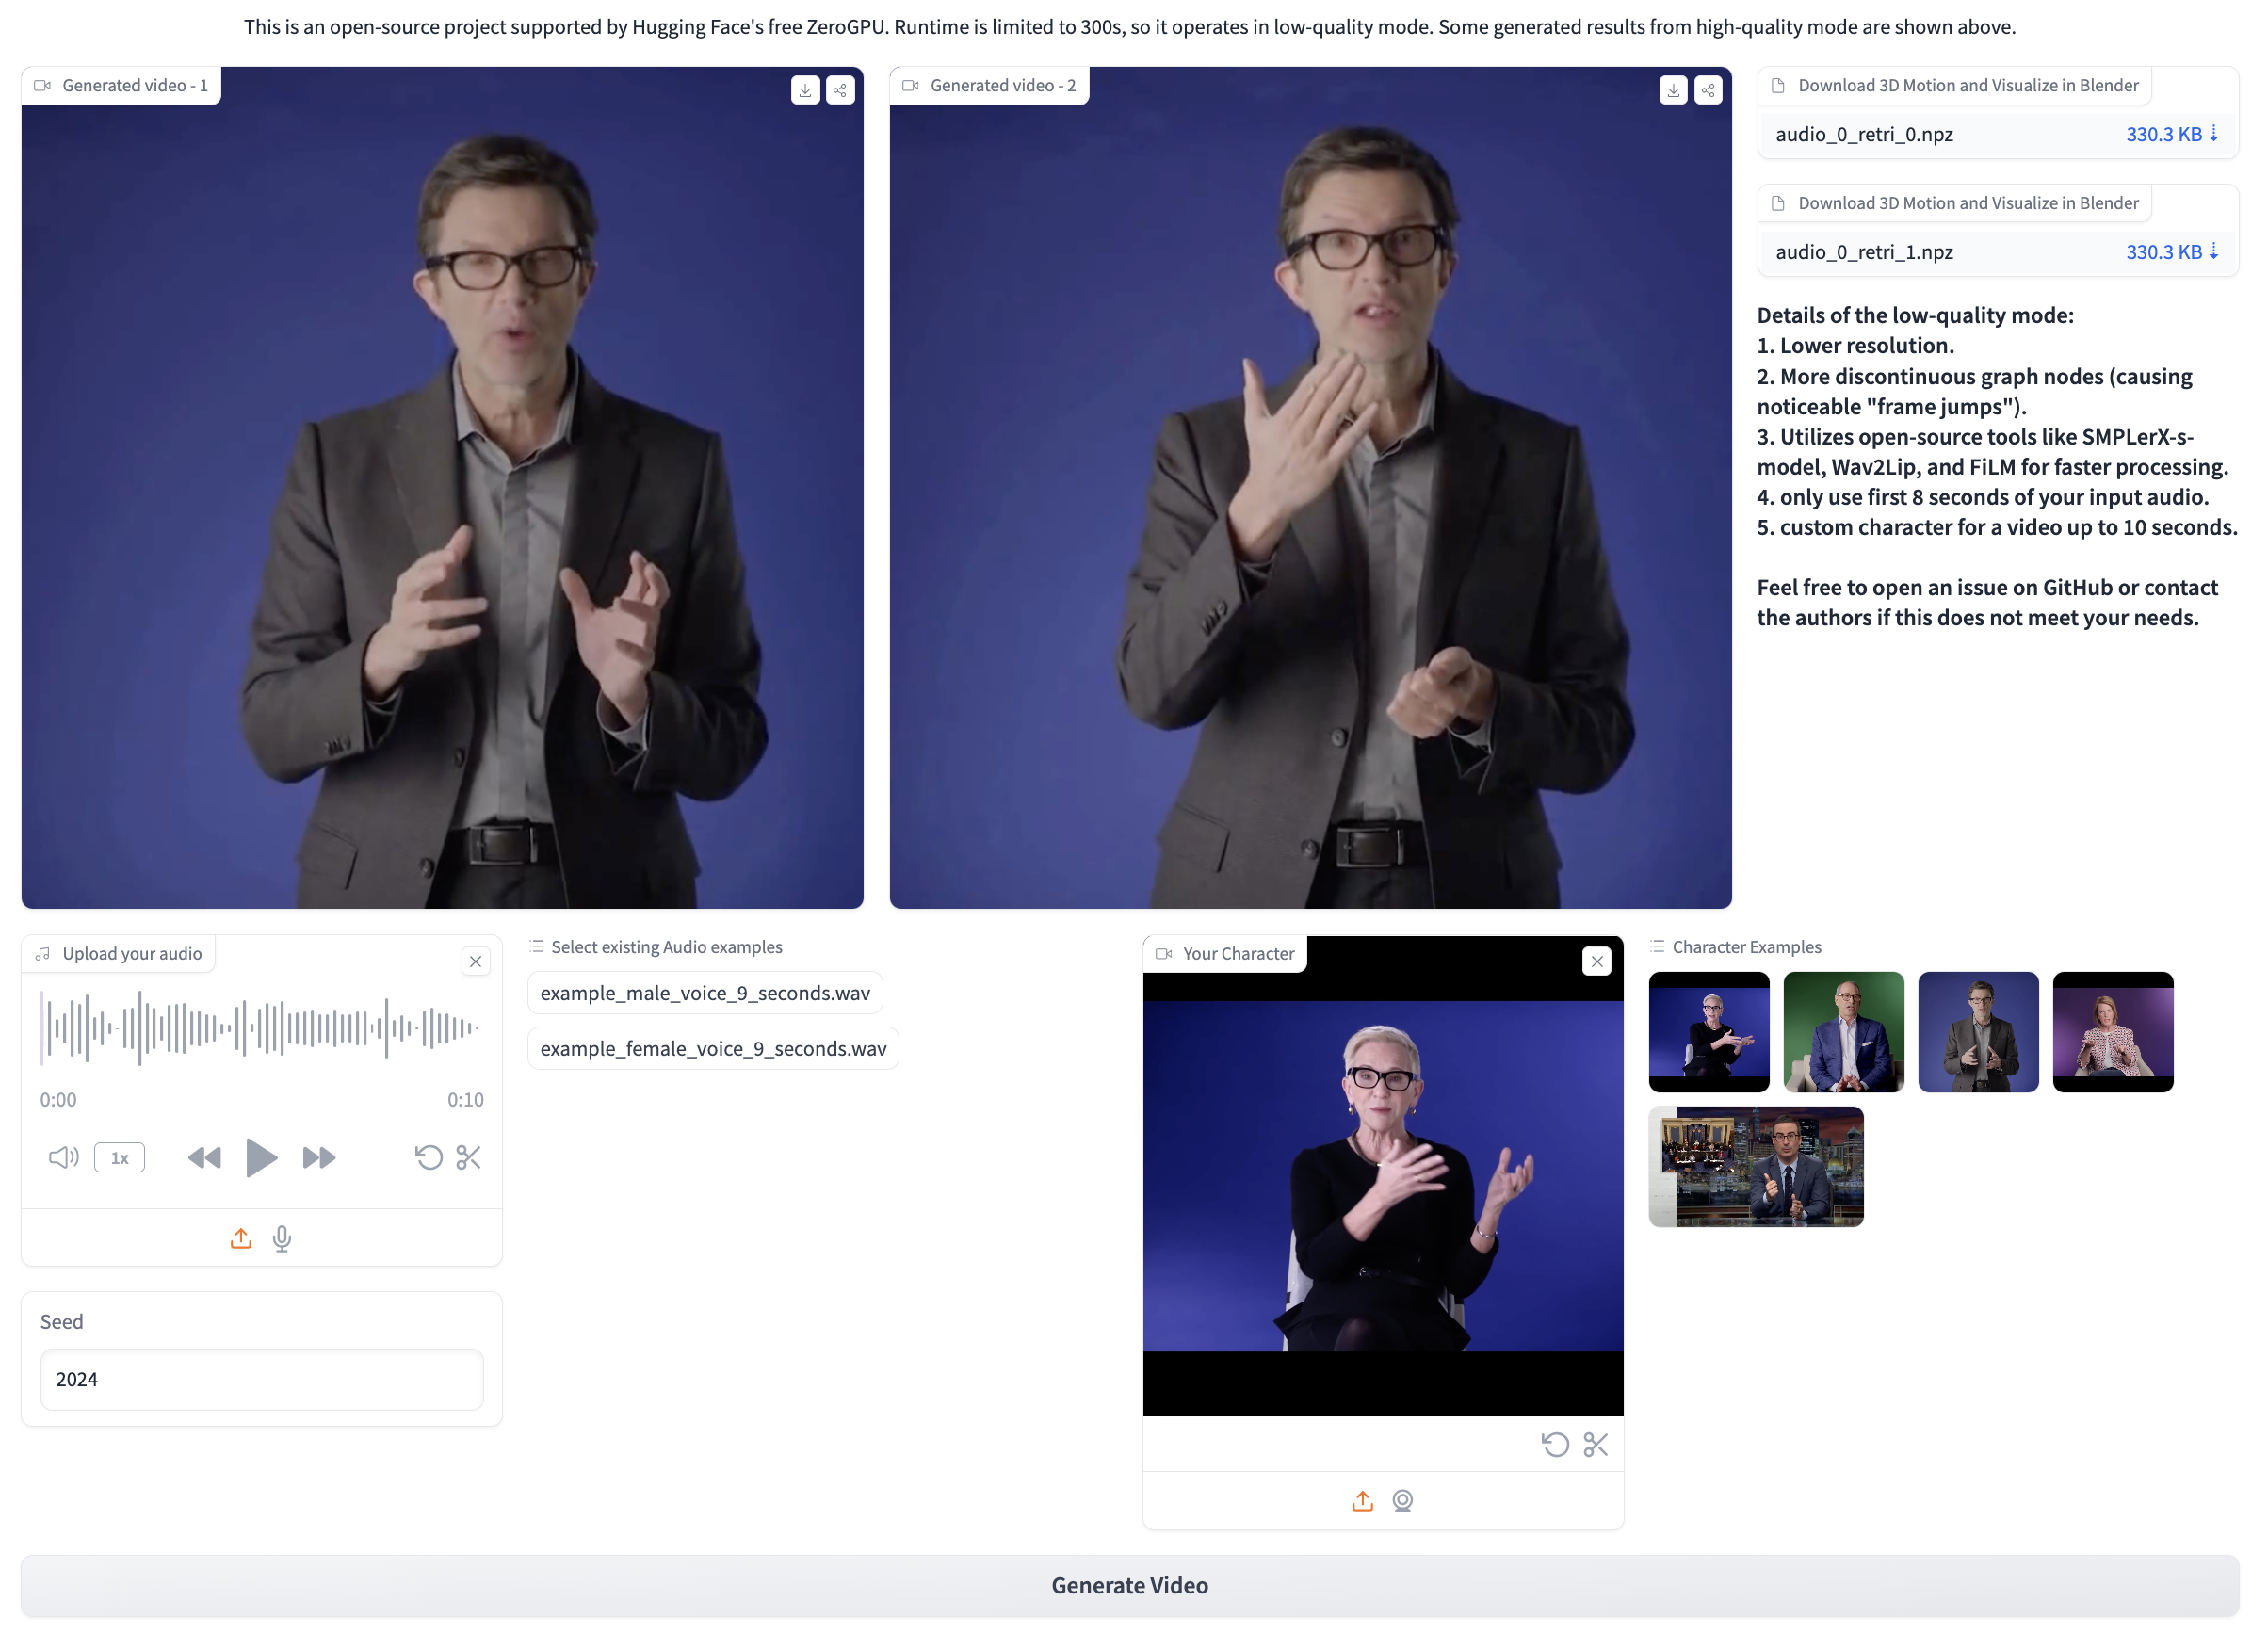
Results Videos
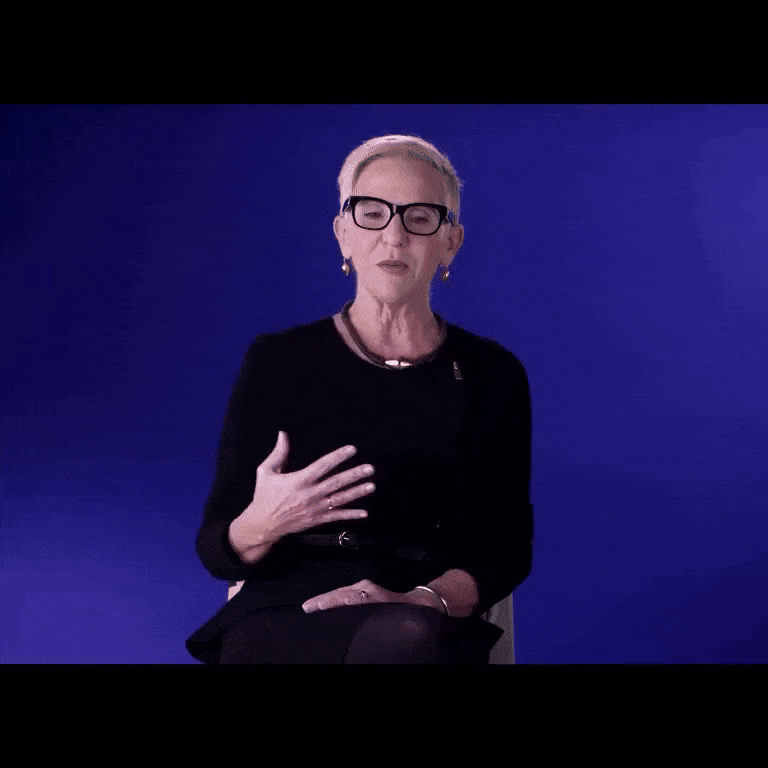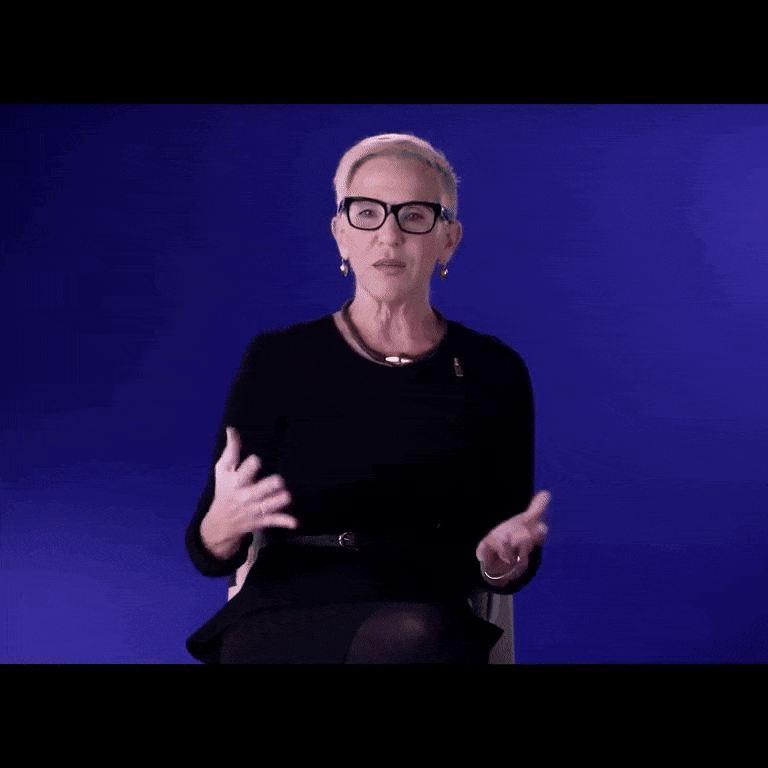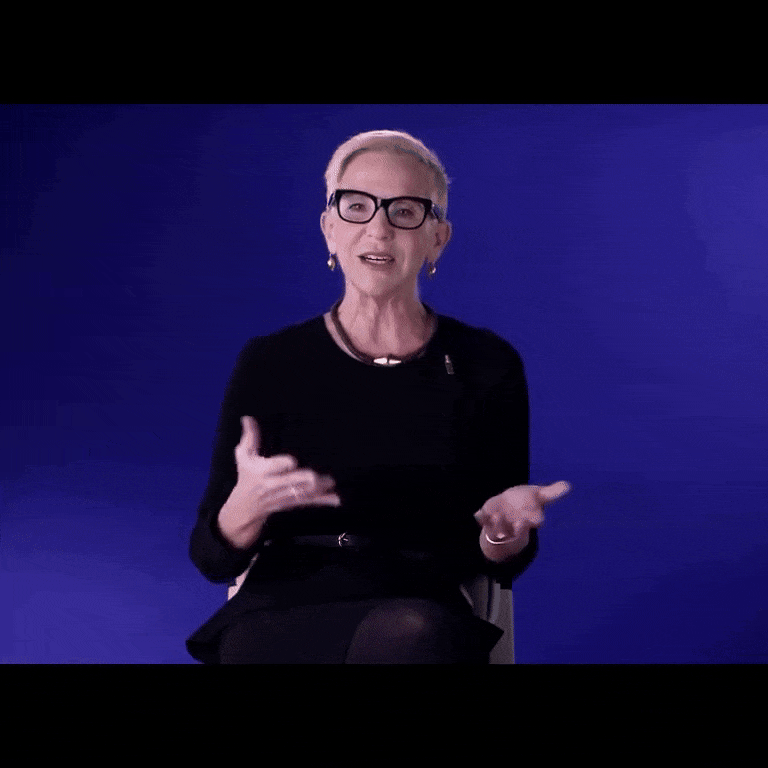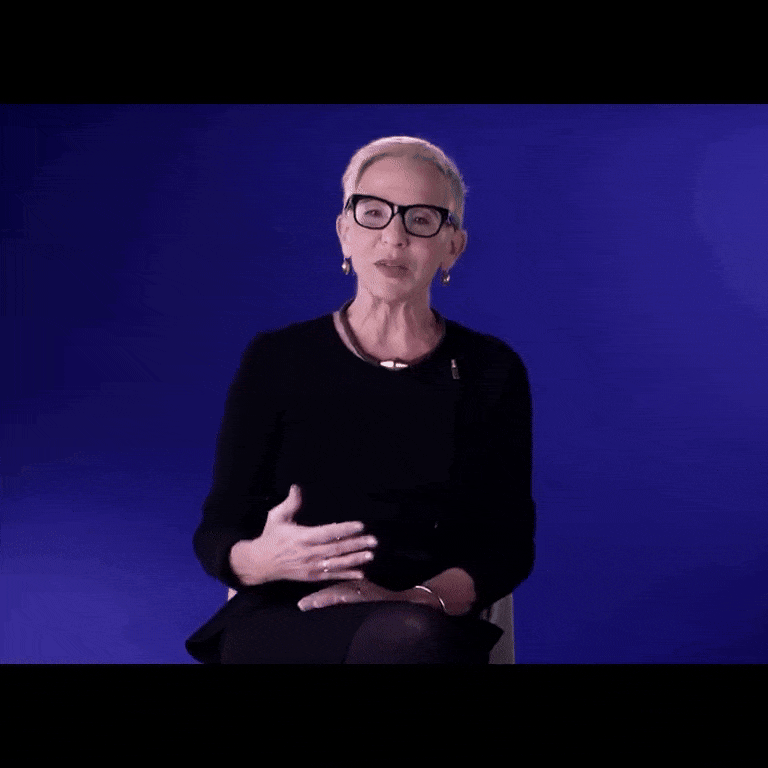
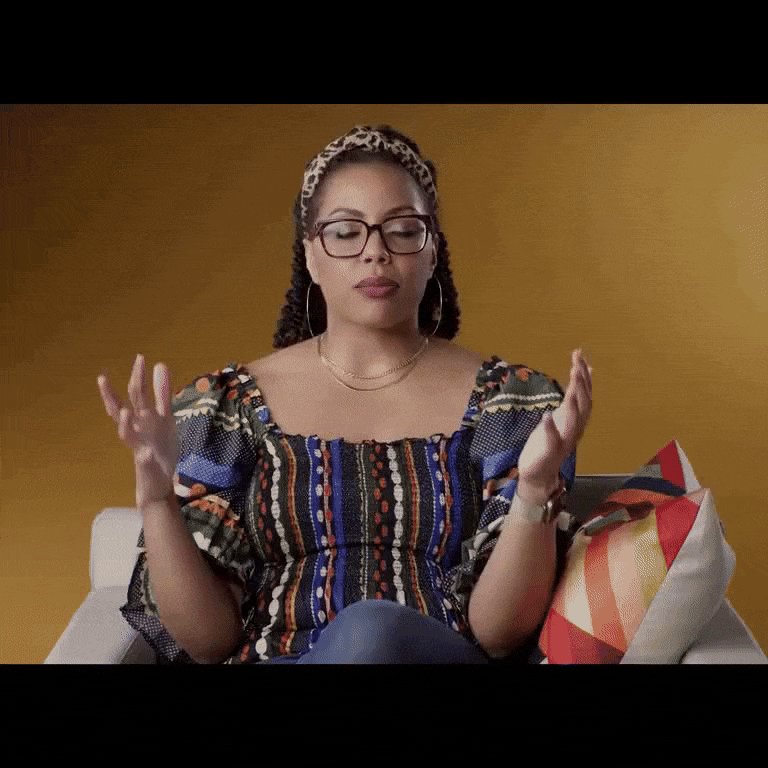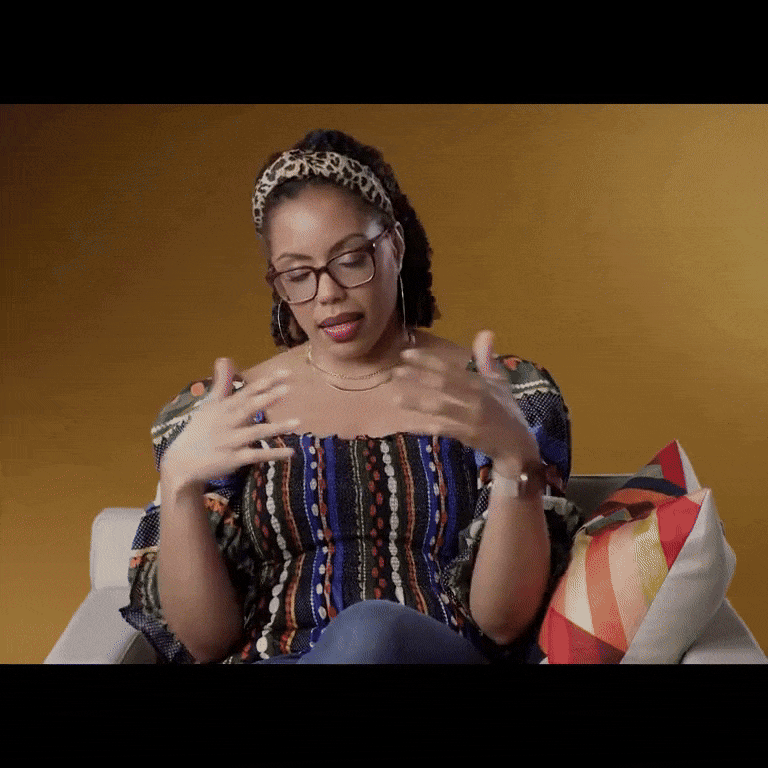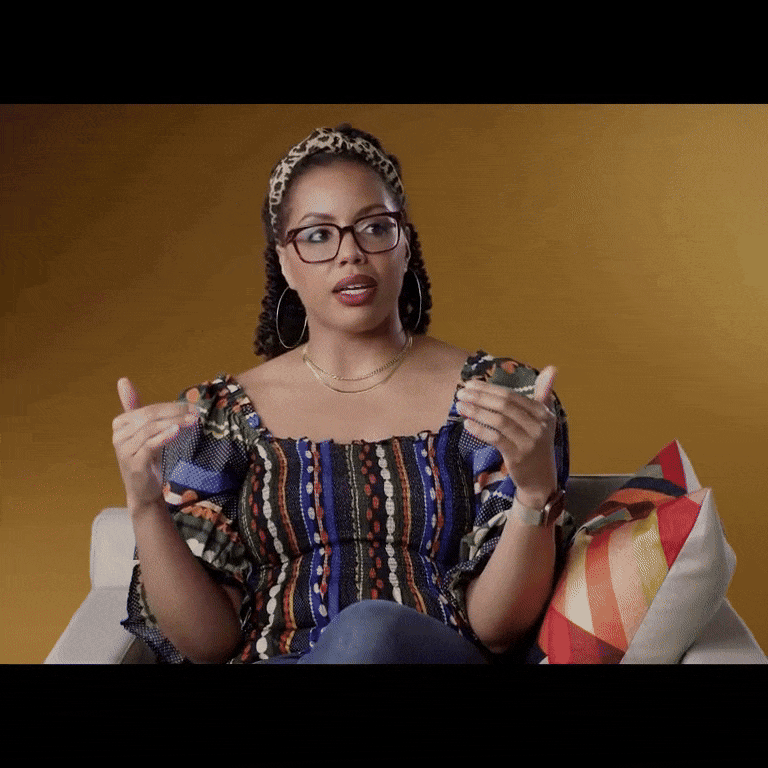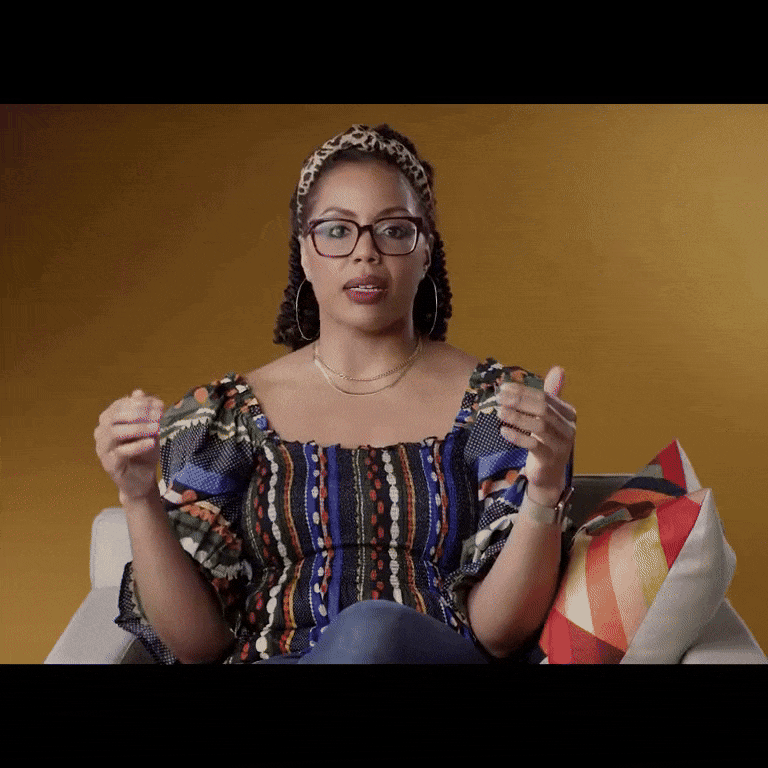
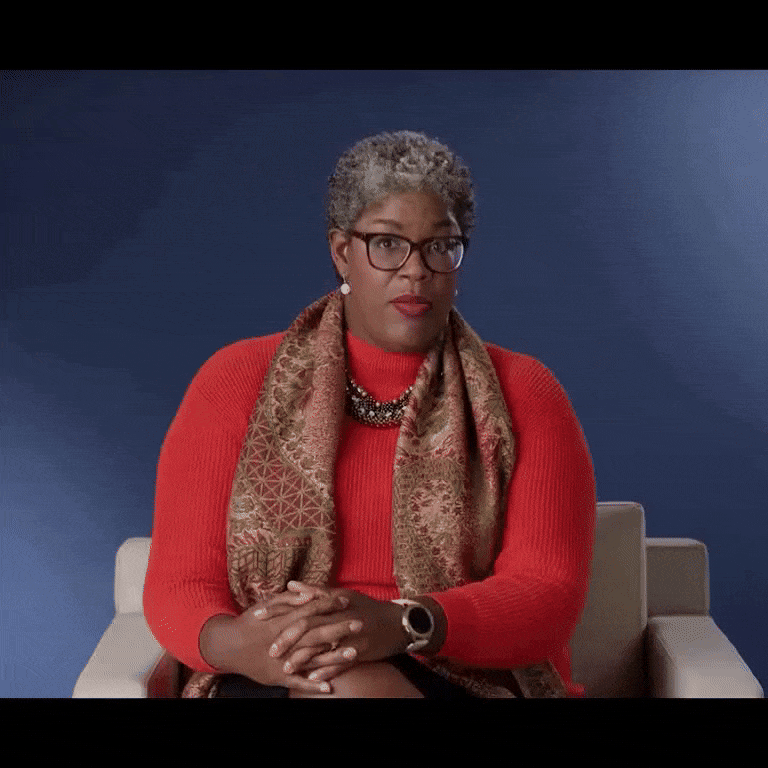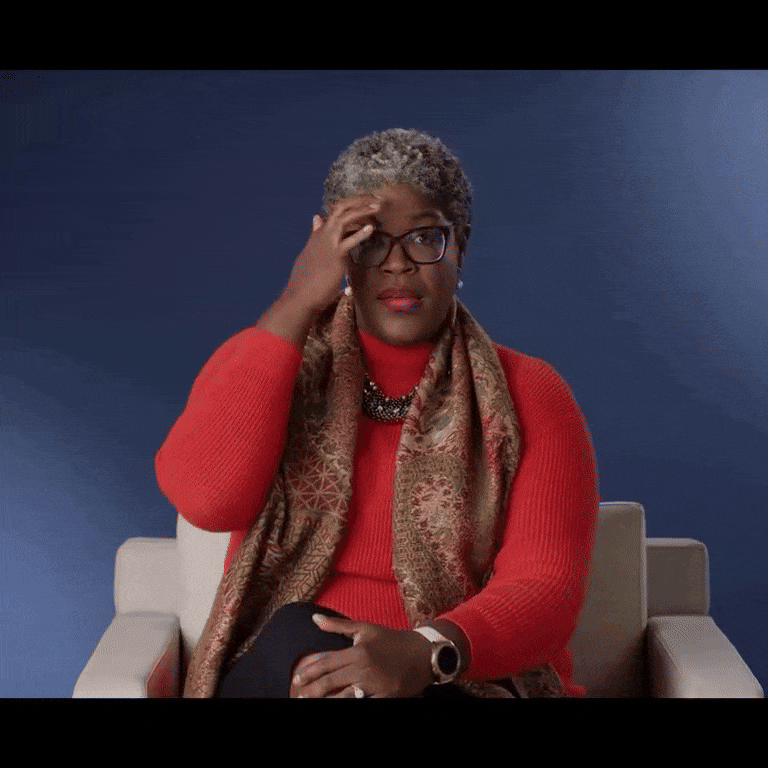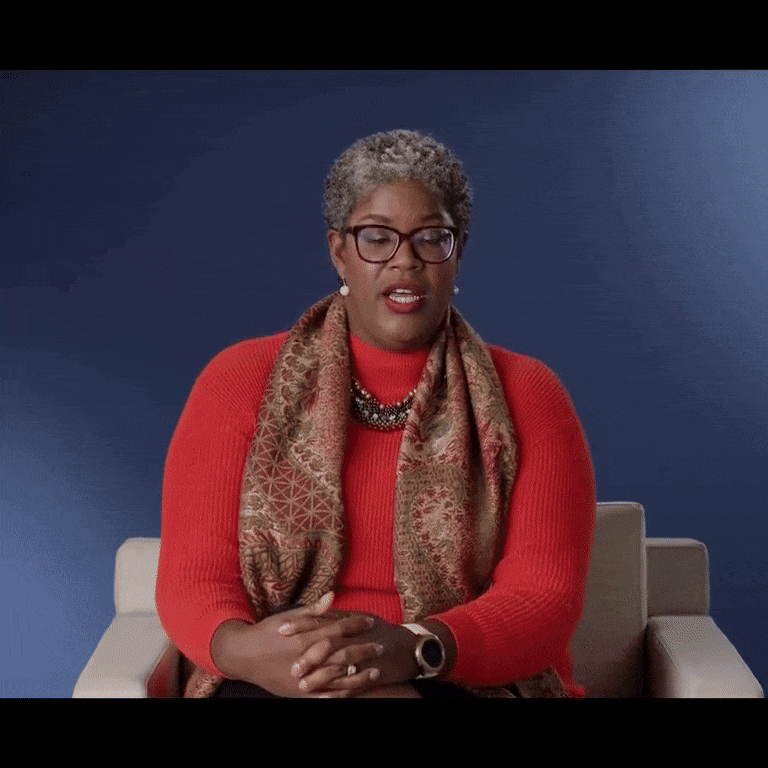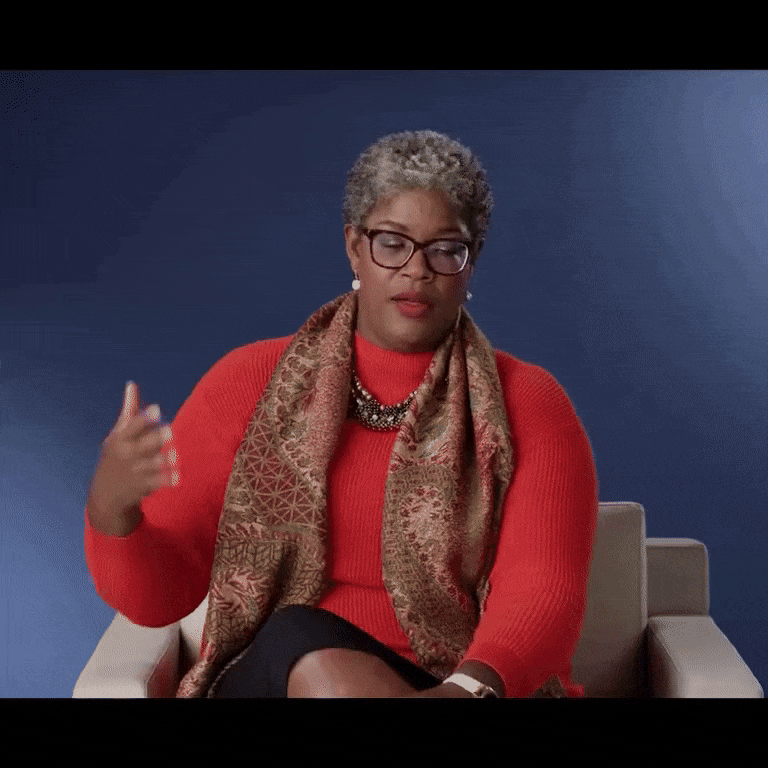
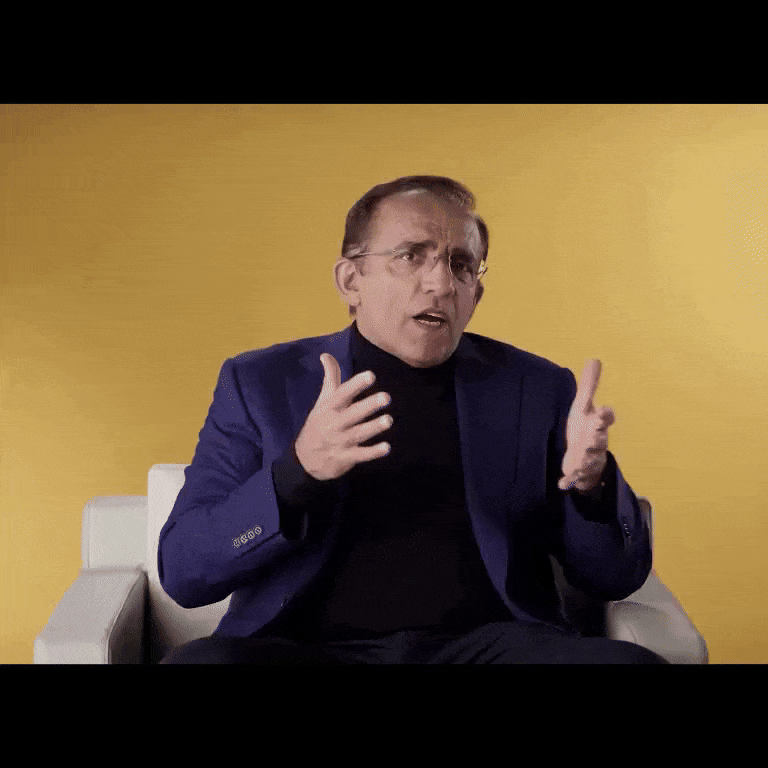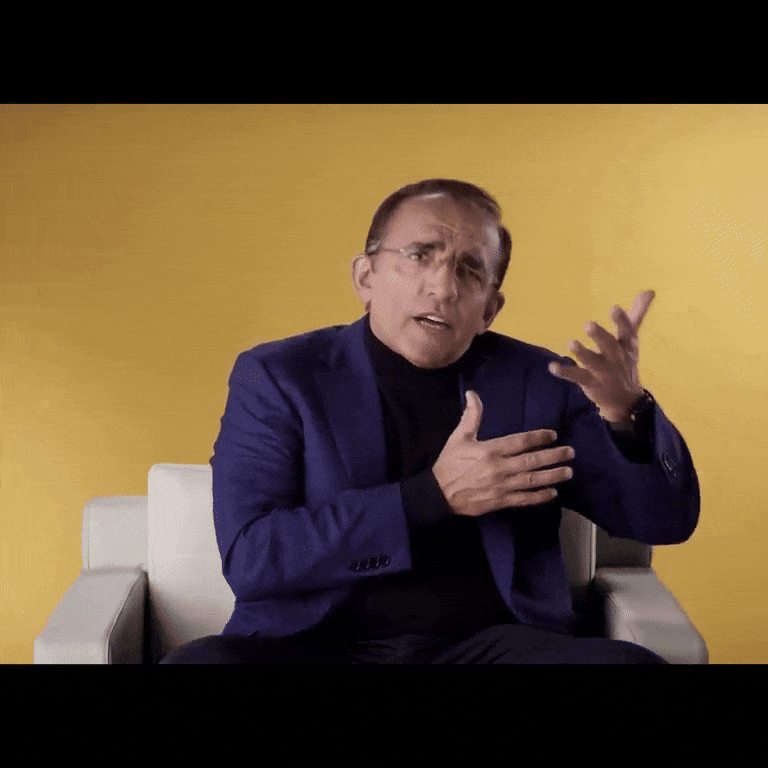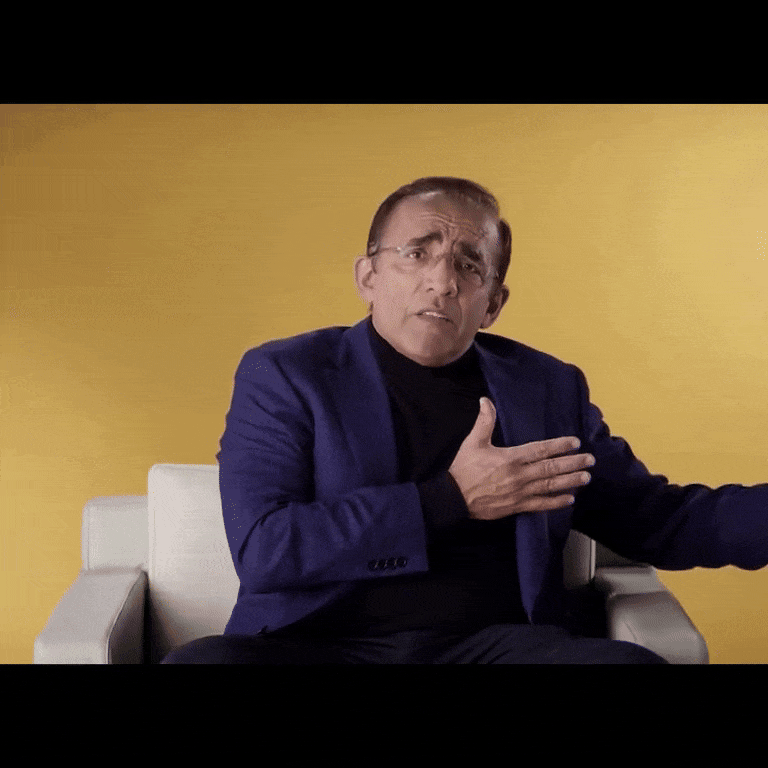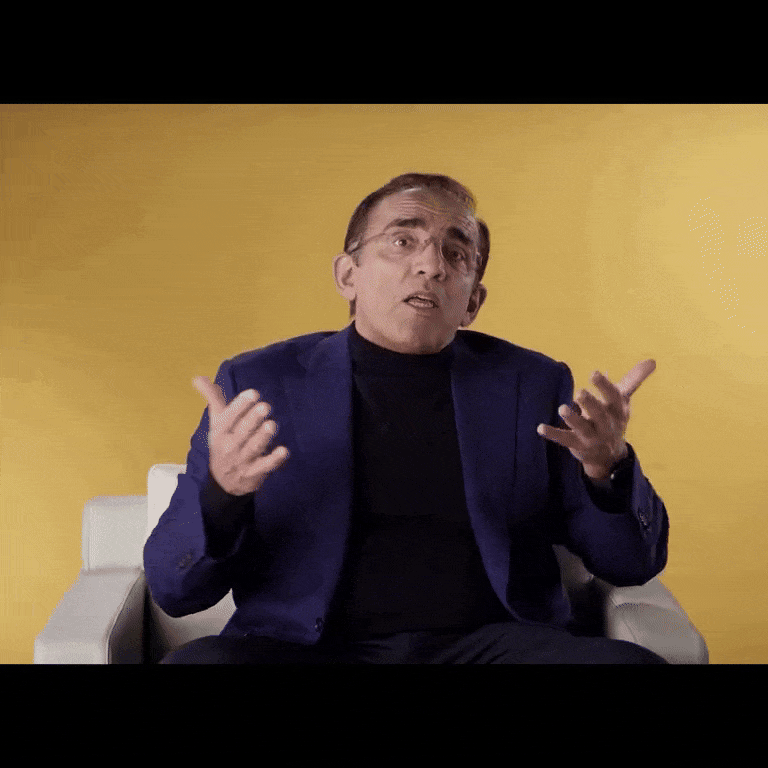
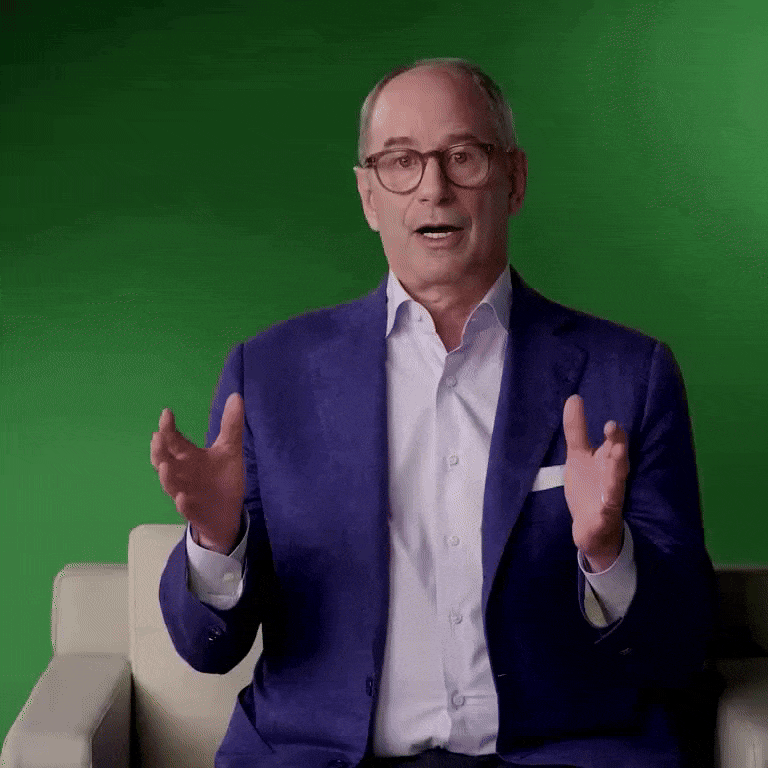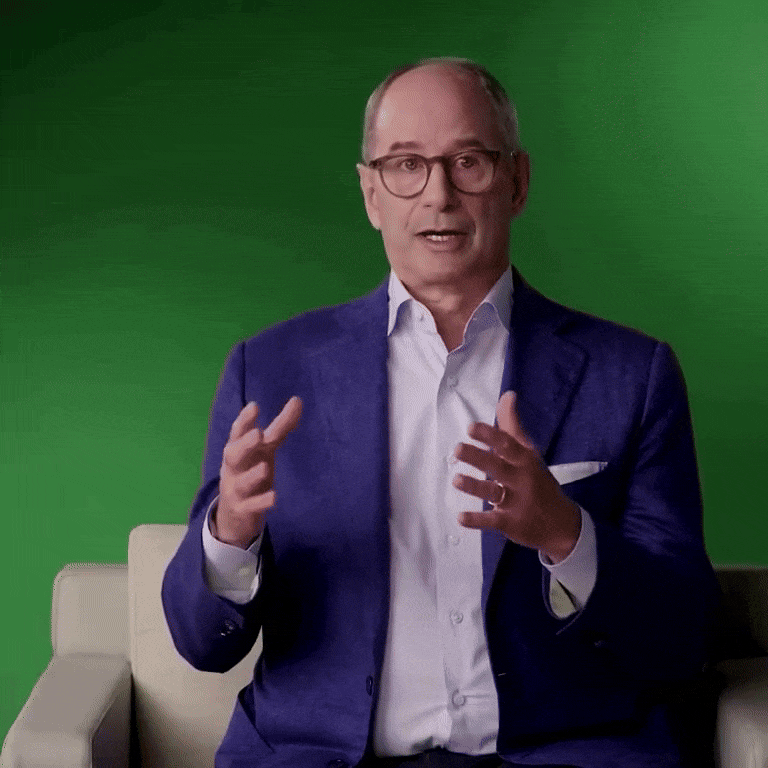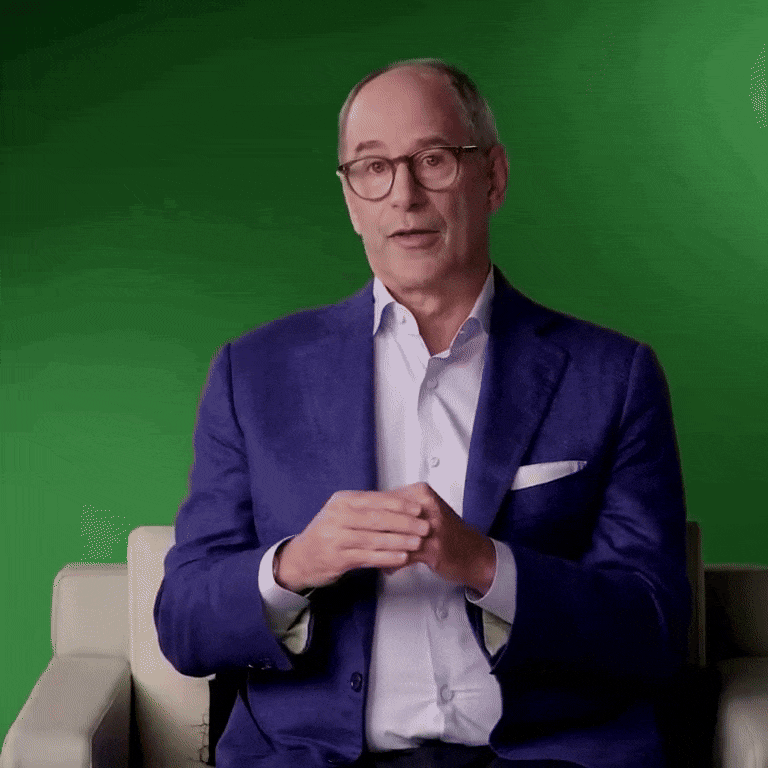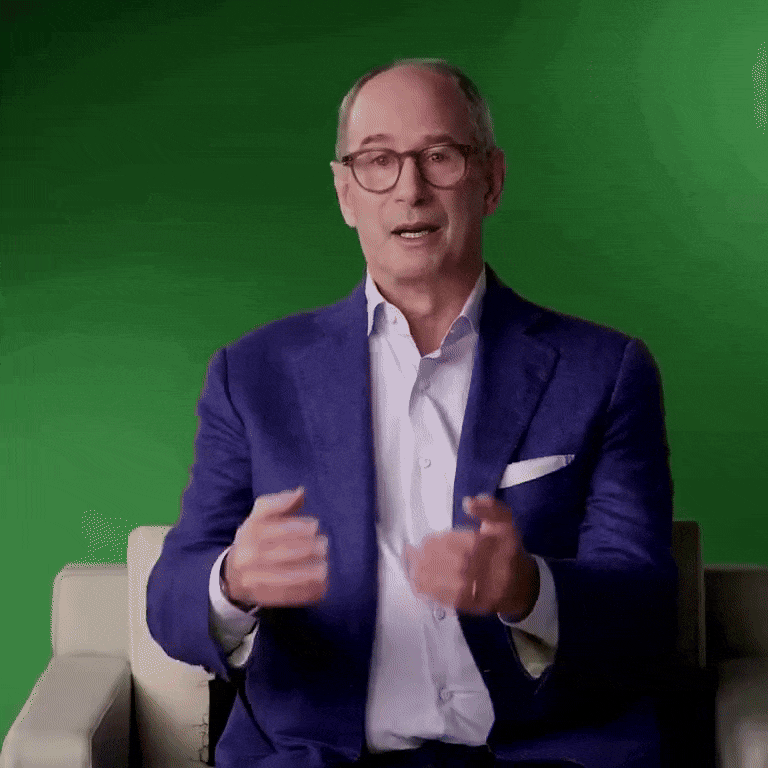
Demo Video (on Youtube)
[](https://youtu.be/xuhD_-tMH1w?si=Tr6jHAhOR1fxWIjb)
📝 Release Plans
- [x] Training codes for AuMoClip
- [x] Processed Youtube Buiness Video data (very small, around 15 mins)
- [x] Scripts for creating gesture graph
- [x] Inference codes with AuMoClip and pretrained weights
⚒️ Installation
Clone the repository
git clone https://github.com/CyberAgentAILab/TANGO.git
cd TANGO
Build Environment
For inference and training CLIP part, we recommend a python version ==3.10.16 and cuda version ==11.8. Now HuggingFace Space version is py310 version:
# [Optional] Create a virtual env
conda create -n tango_py310 python==3.10.16
conda activate tango_py310
# Install with pip:
python -m pip install -r ./pre-requirements.txt
python -m pip install -r ./requirements.txt
🚀 Training and Inference
Inference
Here is the command for running inference scripts under the path /TANGO/, it will take around 3 min to generate two 8s videos. You can visualize by directly check the video or check the result .npz files via blender using our blender addon in EMAGE.
Necessary checkpoints and pre-computed graphs will be automatically downloaded during the first run. Please ensure that at least 10GB of disk space is available.
# inference
python inference.py --audio_path ./datasets/cached_audio/example_male_voice_9_seconds.wav --character_name ./datasets/cached_audio/speaker9_o7Ik1OB4TaE_00-00-38.15_00-00-42.33.mp4

# start gradio app like hugging face space
python app.py
Training JointEmbedding (CLIP)
# download the training data from https://drive.google.com/file/d/11ZQI8mB7mP8OtlIdcjtxKvg7OxVZ4t7d/view?usp=drive_link

torchrun --nproc_per_node=1 train_high_env0.py --config ./configs/baseline_high_env0.yaml
Create the graph for custom character
For building a motion graph, we recommend a python version ==3.9.20 and cuda version ==11.8 to support mmcv and mmpose.
# [Optional] Create a virtual env
conda create -n tango_py39 python==3.9.20
conda activate tango_py39
# Install with pip:
python -m pip install -r ./pre-requirements_py39.txt
python -m pip install -r ./requirements_py39.txt
# set up the py39
python create_graph.py
Copyright Information
We thank the open-source project Wav2Lip, FiLM, SMPLerX.
Check out our previous works for Co-Speech 3D motion Generation DisCo, BEAT, EMAGE.
This project is only for research or education purposes, and not freely available for commercial use or redistribution. The script is available only under the terms of the Attribution-NonCommercial 4.0 International (CC BY-NC 4.0) license.