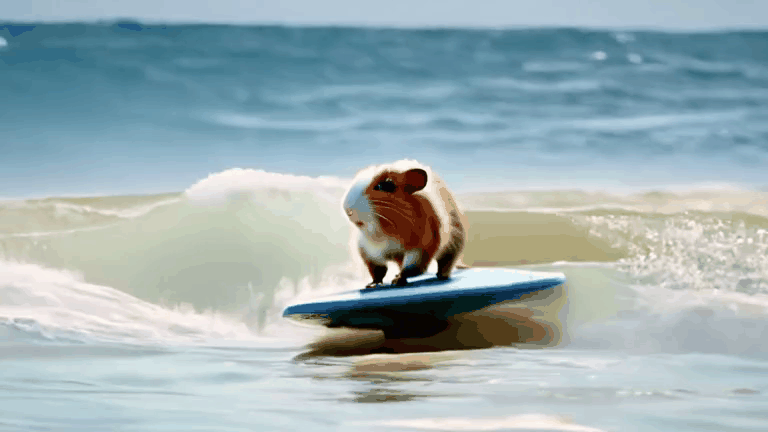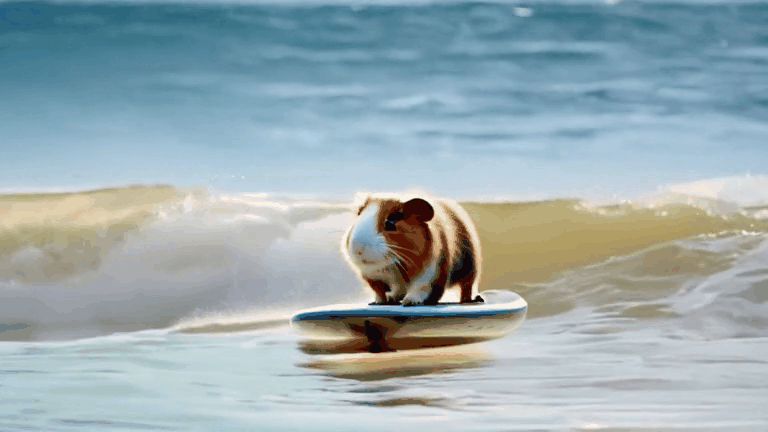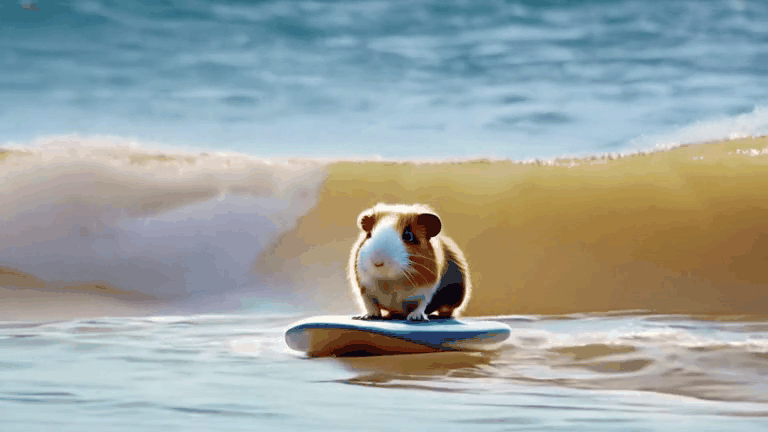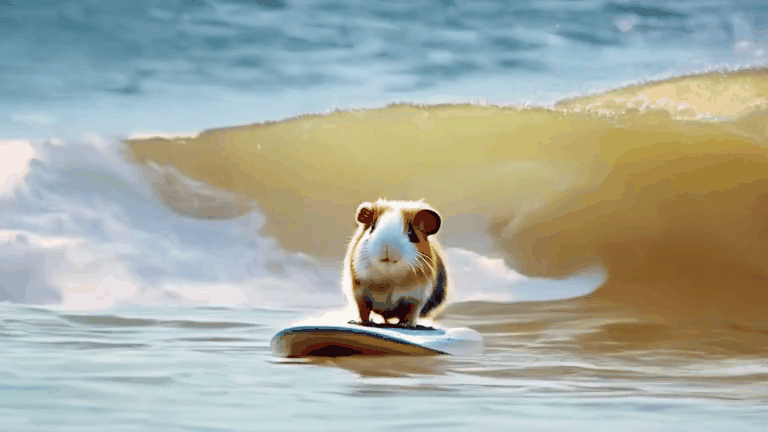
GIM: Learning Generalizable Image Matcher From Internet Videos (ICLR 2024 Spotlight).
Key parameters and specifications
Key parameters and specifications
Parameter
Value
Language
Python
Category
Models
Subcategory
Vision models
Keywords
Datasets, Model architecture, Video production
Stars
921
Forks
22
Contributors
2
Created date
2024-09-09
Updated date
2026-09-09
Stars in 1 day
0
Stars in 7 days
0
Rank
12,621
Previous rank
12,536
Rank change
-85
7-day stars rank
13,515
Previous 7-day stars rank
13,523
7-day stars rank change
8
Total stars rank
11,848
Previous total stars rank
11,828
Total stars rank change
-20
Country
China
README summary
17] 🔥 Our Vchitect-T2V-Dataverse is released. 14] Inference code and checkpoint are released. Create a conda environment and install PyTorch Note: You may want to adjust the CUDA version according to your driver version. Install dependencies Inference **First download the checkpoint. py, arguments for inference: **num_inference_steps**: Denoising steps, default is 100 **guidance_scale**: CFG scale to use, default is 7. 5 **width**: The width of the output video, default is 768 **height**: The height of the output
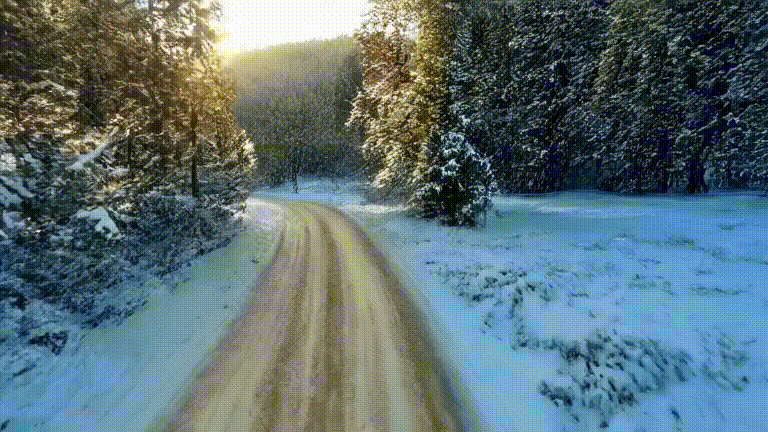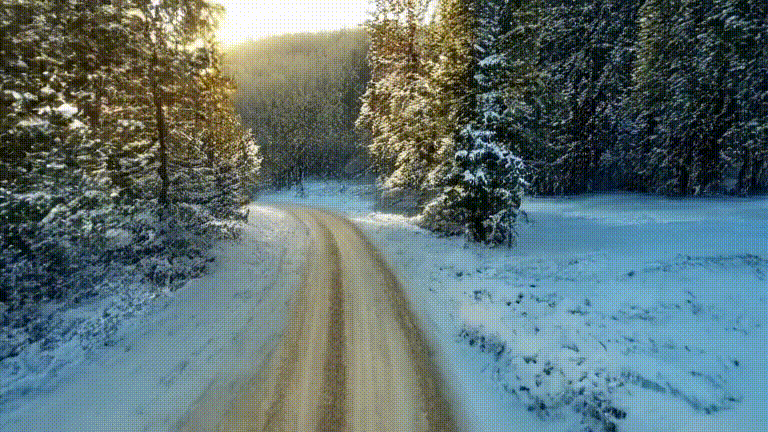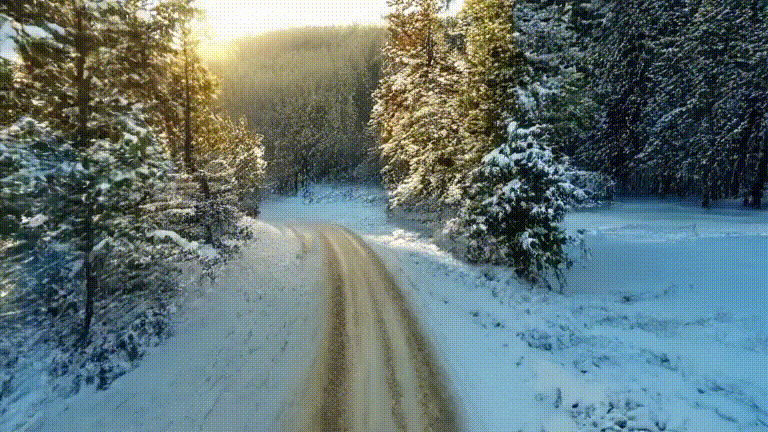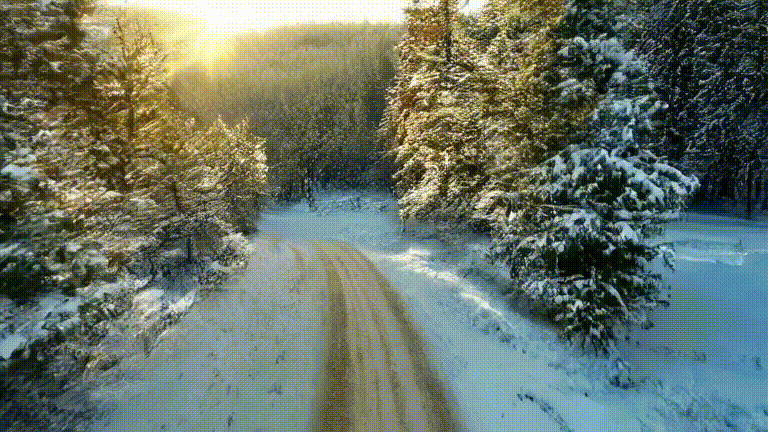
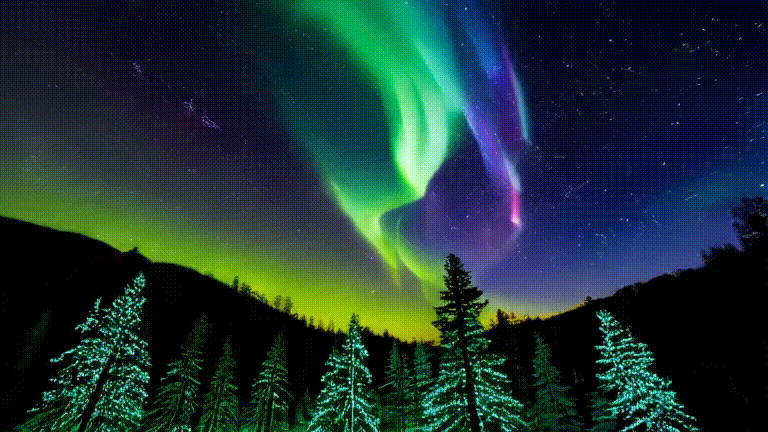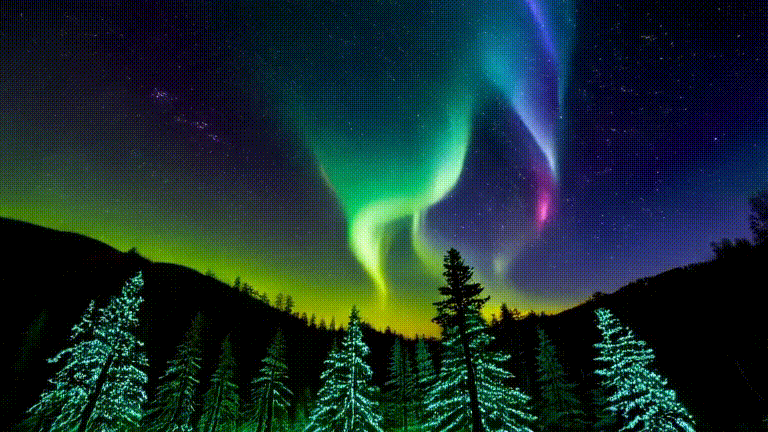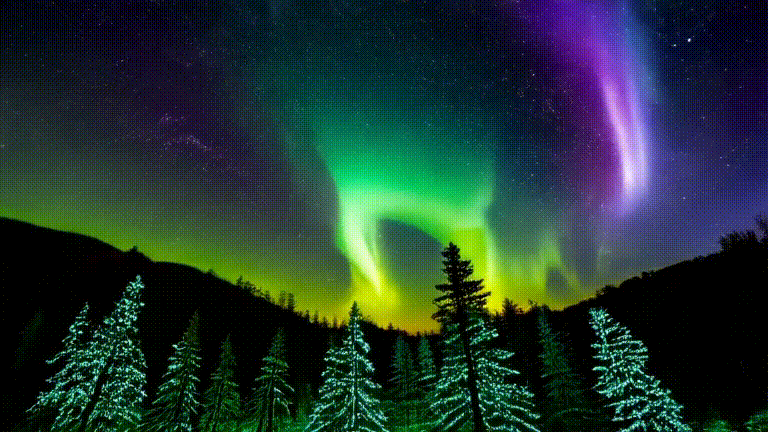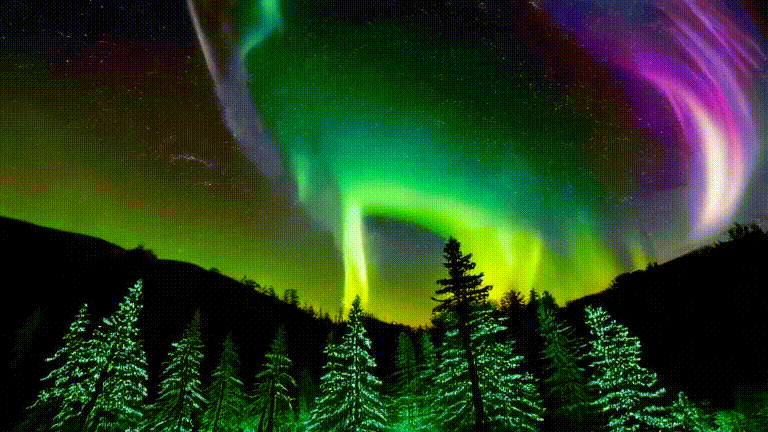
video, default is 432 **frames**: The number of frames, default is 40 The results below were generated using the example prompt. The road is flanked by trees covered in snow, and the ground is also covered in snow. The sun is shining, creating a bright and serene atmosphere. The road appears to be empty, and there are no people or animals visible in the video. The video opens with a breathtaking view of a starry sky and vibrant auroras. The
camera pans to reveal a glowing black hole surrounded by swirling, luminescent gas and dust. Below, an enchanted forest of bioluminescent trees glows softly. The scene is a mesmerizing blend of cosmic wonder and magical landscape. The base T2V model supports generating videos with resolutions up to 720x480 and 8fps. Then,VEnhancer is used to upscale the resolution to 2K and interpolate the frame rate to 24fps. BibTex 🔑 License This code is licensed under Apache-2. The framework is fully
open for academic research and also allows free commercial usage. Disclaimer We disclaim responsibility for user-generated content. The model was not trained to realistically represent people or events, so using it to generate such content is beyond the model's capabilities. It is prohibited for pornographic, violent and bloody content generation, and to generate content that is demeaning or harmful to people or their environment, culture, religion, etc. Users are solely liable for their actions. The project contributors are not
legally affiliated with, nor accountable for users' behaviors. Use the generative model responsibly, adhering to ethical and legal standards.
Frequently asked questions
How many stars and forks are recorded?
Vchitect/Vchitect-2.0 has 921 stars and 22 forks.
What is the repository rank?
Vchitect/Vchitect-2.0 is ranked 12,621.
What language and category are recorded?
Vchitect/Vchitect-2.0 has 921 stars, uses Python and belongs to Models.
Which repository is closest in rank?
Vchitect/Vchitect-2.0 is compared with 360CVGroup/FancyVideo, ranked 12,628 with 920 stars.
README
Vchitect-2.0: Parallel Transformer for Scaling Up Video Diffusion Models
num_inference_steps: Denoising steps, default is 100
guidance_scale: CFG scale to use, default is 7.5
width: The width of the output video, default is 768
height: The height of the output video, default is 432
frames: The number of frames, default is 40
The results below were generated using the example prompt.
A snowy forest landscape with a dirt road running through it. The road is flanked by trees covered in snow, and the ground is also covered in snow. The sun is shining, creating a bright and serene atmosphere. The road appears to be empty, and there are no people or animals visible in the video.
The video opens with a breathtaking view of a starry sky and vibrant auroras. The camera pans to reveal a glowing black hole surrounded by swirling, luminescent gas and dust. Below, an enchanted forest of bioluminescent trees glows softly. The scene is a mesmerizing blend of cosmic wonder and magical landscape.
The base T2V model supports generating videos with resolutions up to 720x480 and 8fps. Then,VEnhancer is used to upscale the resolution to 2K and interpolate the frame rate to 24fps.
BibTex
@article{fan2025vchitect,
  title={Vchitect-2.0: Parallel Transformer for Scaling Up Video Diffusion Models},
  author={Fan, Weichen and Si, Chenyang and Song, Junhao and Yang, Zhenyu and He, Yinan and Zhuo, Long and Huang, Ziqi and Dong, Ziyue and He, Jingwen and Pan, Dongwei and others},
  journal={arXiv preprint arXiv:2501.08453},
  year={2025}
}
🔑 License
This code is licensed under Apache-2.0. The framework is fully open for academic research and also allows free commercial usage.
Disclaimer
We disclaim responsibility for user-generated content. The model was not trained to realistically represent people or events, so using it to generate such content is beyond the model's capabilities. It is prohibited for pornographic, violent and bloody content generation, and to generate content that is demeaning or harmful to people or their environment, culture, religion, etc. Users are solely liable for their actions. The project contributors are not legally affiliated with, nor accountable for users' behaviors. Use the generative model responsibly, adhering to ethical and legal standards.