← Open Source
SkyworkAI

SkyReels-A1

SkyReels-A1: Expressive Portrait Animation in Video Diffusion Transformers.

ModelsVision modelsPython
Open on GitHub
Momentum
+0stars in 24 hours0.0%
581
Stars
61
Forks
+0
This week
4
Contributors
Created 2025-02-13 · Updated 2026-10-07 · #16616 today
Top developers

SkyworkAI/SkyReels-A1 is ranked 16,616 with 581 stars.

Same-category comparison

SkyworkAI/SkyReels-A1 is ranked 16,616 among these 8 peers; SkyworkAI/SkyReels-V3 is ranked 16,617.

Same-category comparison
NameRankMetrics
microsoft/GenerativeImage2Text16,576
Language:
Python
Stars:
584
Forks:
75
Description:
GIT: A Generative Image-to-text Transformer for Vision and Language.
yfzhang114/Thyme16,577
Language:
Python
Stars:
584
Forks:
37
Description:
✨✨ [ICLR 2026] Think Beyond Images.
LTH14/mage16,580
Language:
Python
Stars:
583
Forks:
33
Description:
A PyTorch implementation of MAGE: MAsked Generative Encoder to Unify Representation Learning and Image Synthesis.
JAMESYJL/ShapeLLM-Omni16,613
Language:
Python
Stars:
581
Forks:
30
Description:
[NeurIPS 2025 Spotlight] A Native Multimodal LLM for 3D Generation and Understanding.
SkyworkAI/SkyReels-V316,617
Language:
Python
Stars:
581
Forks:
93
Description:
SkyReels V3: Multimodal Video Generation Model.
Doby-Xu/WithAnyone16,636
Language:
Python
Stars:
580
Forks:
25
Description:
✨ [ICLR'26] WithAnyone is capable of generating high-quality, controllable, and ID consistent images.
chinhsuanwu/mobilevit-pytorch16,643
Language:
Python
Stars:
580
Forks:
74
Description:
A PyTorch implementation of "MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer".
Vchitect/VEnhancer16,653
Language:
Python
Stars:
579
Forks:
33
Description:
Official codes of VEnhancer: Generative Space-Time Enhancement for Video Generation.
Key parameters and specifications
ParameterValue
LanguagePython
CategoryModels
SubcategoryVision models
KeywordsComputer vision, Image production, Video production
Stars581
Forks61
Contributors4
Created date2025-02-13
Updated date2026-10-07
Stars in 1 day0
Stars in 7 days0
Rank16,616
Previous rank16,407
Rank change-209
7-day stars rank15,630
Previous 7-day stars rank15,637
7-day stars rank change7
Total stars rank17,211
Previous total stars rank17,182
Total stars rank change-29
CountrySingapore
README summary

SkyReels-A1: Expressive Portrait Animation in Video Diffusion Transformers Mingyuan Fan   Guibin Chen   Xiang Wen   🔥 For more results, visit our homepage 🔥 This repo, named **SkyReels-A1**, contains the official PyTorch implementation of our paper SkyReels-A1: Expressive Portrait Animation in Video Diffusion Transformers. Jun 1, 2025: 🎉 We published the technical report, SkyReels-Audio: Omni Audio-Conditioned Talking Portraits in Video Diffusion Transformers. This is an open-sourced controllable video generation framework capable of assembling arbitrary visual elements

. Mar 4, 2025: 🔥 We release audio-driven portrait image animation pipeline. Feb 18, 2025: 👋 We release the inference code and model weights of SkyReels-A1. Download Feb 18, 2025: 🎉 We have made our technical report available as open source. Read Feb 18, 2025: 🔥 Our online demo of LipSync is available on SkyReels now! Feb 18, 2025: 🔥 We have open-sourced I2V video generation model SkyReels-V1. This is the first and most advanced open-source human-centric video foundation model

. Clone the code and prepare the environment 🛠️ First git clone the repository with code: Then, install the remaining dependencies: 2. Download pretrained weights 📥 You can download the pretrained weights is from HuggingFace: The FLAME, mediapipe, and smirk models are located in the SkyReels-A1/extra_models folder. The directory structure of our SkyReels-A1 code is formulated as: Download DiffposeTalk assets and pretrained weights (For Audio-driven) We use diffposetalk to generate flame coefficients from audio, thereby constructing motion signals

. Download the diffposetalk code and follow its README to download the weights and related data. Then place them in the specified directory. Or you can download style files from link and stats_train. Download Frame interpolation Model pretrained weights (For Long Video Inference and Dynamic Resolution) We use FILM to generate transition frames, making the video transitions smoother (Set to True). pt, and place it in the specified directory. Inference 🚀 You can simply run the inference scripts as: If the

script runs successfully, you will get an output mp4 file. This file includes the following results: driving video, input image or video, and generated result. Long Video Inference Now, you can run the long video inference scripts to obtain portrait animation of any length: Dynamic Resolution All inference scripts now support dynamic resolution, simply set to any desired fps, recommended fps include: 12fps (Native), 24fps, 48fps, 60fps, other settings such as 25fps and 30fps may cause unstable frame rates. Gradio

Interface 🤗 We provide a Gradio interface for a better experience, just run by: The graphical interactive interface is shown as below: Metric Evaluation 👓 We also provide all scripts for automatically calculating the metrics, including SimFace, FID, and L1 distance between expression and motion, reported in the paper. After setting the video result path, run the following commands in sequence: Acknowledgements 💐 We would like to thank the contributors of CogvideoX, finetrainers and DiffPoseTalkrepositories, for their open research and contributions. Citation 💖 If

you find SkyReels-A1 useful for your research, welcome to 🌟 this repo and cite our work using the following BibTeX

Frequently asked questions

How many stars and forks are recorded?

SkyworkAI/SkyReels-A1 has 581 stars and 61 forks.

What is the repository rank?

SkyworkAI/SkyReels-A1 is ranked 16,616.

What language and category are recorded?

SkyworkAI/SkyReels-A1 has 581 stars, uses Python and belongs to Models.

Which repository is closest in rank?

SkyworkAI/SkyReels-A1 is compared with SkyworkAI/SkyReels-V3, ranked 16,617 with 581 stars.

README

SkyReels-A1: Expressive Portrait Animation in Video Diffusion Transformers

[Di Qiu](https://scholar.google.com/citations?user=6D_nzucAAAAJ&hl=en) 
[Zhengcong Fei](https://scholar.google.com/citations?user=_43YnBcAAAAJ&hl=zh-CN) 
Rui Wang 
Jialin Bai 
[Changqian Yu](https://scholar.google.com/citations?user=Hv-vj2sAAAAJ&hl=en) 

Mingyuan Fan  Guibin Chen  Xiang Wen 

Skywork AI, Kunlun Inc.

![](https://img.shields.io/badge/arXiv-SkyReels A1-red) ![](https://img.shields.io/badge/Project-SkyReels A1-green)

🔥 For more results, visit our homepage 🔥

👋 Join our [Discord](https://discord.gg/PwM6NYtccQ) 

This repo, named SkyReels-A1, contains the official PyTorch implementation of our paper SkyReels-A1: Expressive Portrait Animation in Video Diffusion Transformers.

🔥🔥🔥 News!!

  • Jun 1, 2025: 🎉 We published the technical report, SkyReels-Audio: Omni Audio-Conditioned Talking Portraits in Video Diffusion Transformers.
  • Apr 3, 2025: 🔥 We release SkyReels-A2. This is an open-sourced controllable video generation framework capable of assembling arbitrary visual elements.
  • Mar 4, 2025: 🔥 We release audio-driven portrait image animation pipeline. Try out on Huggingface Spaces Demo !
  • Feb 18, 2025: 👋 We release the inference code and model weights of SkyReels-A1. Download
  • Feb 18, 2025: 🎉 We have made our technical report available as open source. Read
  • Feb 18, 2025: 🔥 Our online demo of LipSync is available on SkyReels now! Try out on LipSync .
  • Feb 18, 2025: 🔥 We have open-sourced I2V video generation model SkyReels-V1. This is the first and most advanced open-source human-centric video foundation model.

📑 TODO List

  • [x] Checkpoints
  • [x] Inference Code
  • [x] Web Demo (Gradio)
  • [x] Audio-driven Portrait Image Animation Pipeline
  • [x] Inference Code for Long Videos
  • [ ] User-Level GPU Inference on RTX4090
  • [ ] ComfyUI

Getting Started 🏁

1. Clone the code and prepare the environment 🛠️

First git clone the repository with code:

git clone https://github.com/SkyworkAI/SkyReels-A1.git
cd SkyReels-A1

# create env using conda
conda create -n skyreels-a1 python=3.10
conda activate skyreels-a1

Then, install the remaining dependencies:

pip install -r requirements.txt

2. Download pretrained weights 📥

You can download the pretrained weights is from HuggingFace:

# !pip install -U "huggingface_hub[cli]"
huggingface-cli download Skywork/SkyReels-A1 --local-dir local_path --exclude "*.git*" "README.md" "docs"

The FLAME, mediapipe, and smirk models are located in the SkyReels-A1/extra_models folder.

The directory structure of our SkyReels-A1 code is formulated as:

pretrained_models
├── FLAME
├── SkyReels-A1-5B
│   ├── pose_guider
│   ├── scheduler
│   ├── tokenizer
│   ├── siglip-so400m-patch14-384
│   ├── transformer
│   ├── vae
│   └── text_encoder
├── mediapipe
└── smirk

Download DiffposeTalk assets and pretrained weights (For Audio-driven)

  • We use diffposetalk to generate flame coefficients from audio, thereby constructing motion signals.

  • Download the diffposetalk code and follow its README to download the weights and related data.

  • Then place them in the specified directory.

cp -r ${diffposetalk_root}/style pretrained_models/diffposetalk
cp ${diffposetalk_root}/experiments/DPT/head-SA-hubert-WM/checkpoints/iter_0110000.pt pretrained_models/diffposetalk
cp ${diffposetalk_root}/datasets/HDTF_TFHP/lmdb/stats_train.npz pretrained_models/diffposetalk
  • Or you can download style files from link and stats_train.npz from link.
pretrained_models
├── FLAME
├── SkyReels-A1-5B
├── mediapipe
├── diffposetalk
│   ├── style
│   ├── iter_0110000.pt
│   ├── stats_train.npz
└── smirk

Download Frame interpolation Model pretrained weights (For Long Video Inference and Dynamic Resolution)

  • We use FILM to generate transition frames, making the video transitions smoother (Set use_interpolation to True).

  • Download film_net_fp16.pt, and place it in the specified directory.

pretrained_models
├── FLAME
├── SkyReels-A1-5B
├── mediapipe
├── diffposetalk
├── film_net
│   ├── film_net_fp16.pt
└── smirk

3. Inference 🚀

You can simply run the inference scripts as:

python inference.py

# inference audio to video
python inference_audio.py

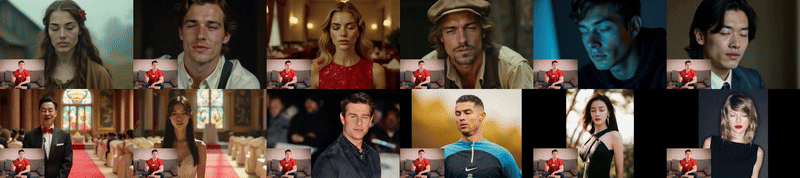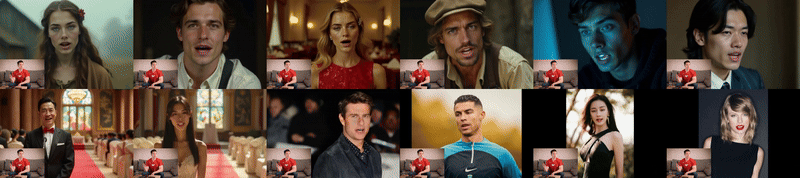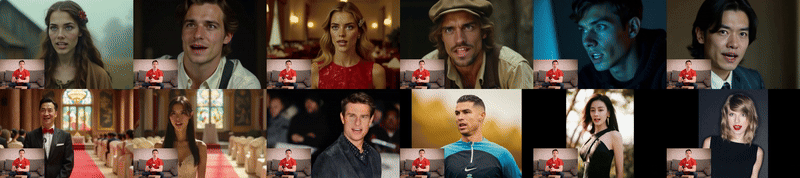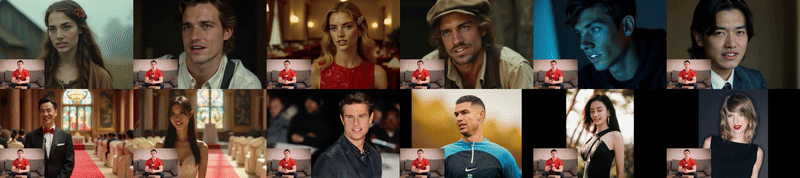
If the script runs successfully, you will get an output mp4 file. This file includes the following results: driving video, input image or video, and generated result.

Long Video Inference

Now, you can run the long video inference scripts to obtain portrait animation of any length:

python inference_long_video.py

# inference audio to video
python inference_audio_long_video.py

Dynamic Resolution

All inference scripts now support dynamic resolution, simply set target_fps to any desired fps, recommended fps include: 12fps (Native), 24fps, 48fps, 60fps, other settings such as 25fps and 30fps may cause unstable frame rates.

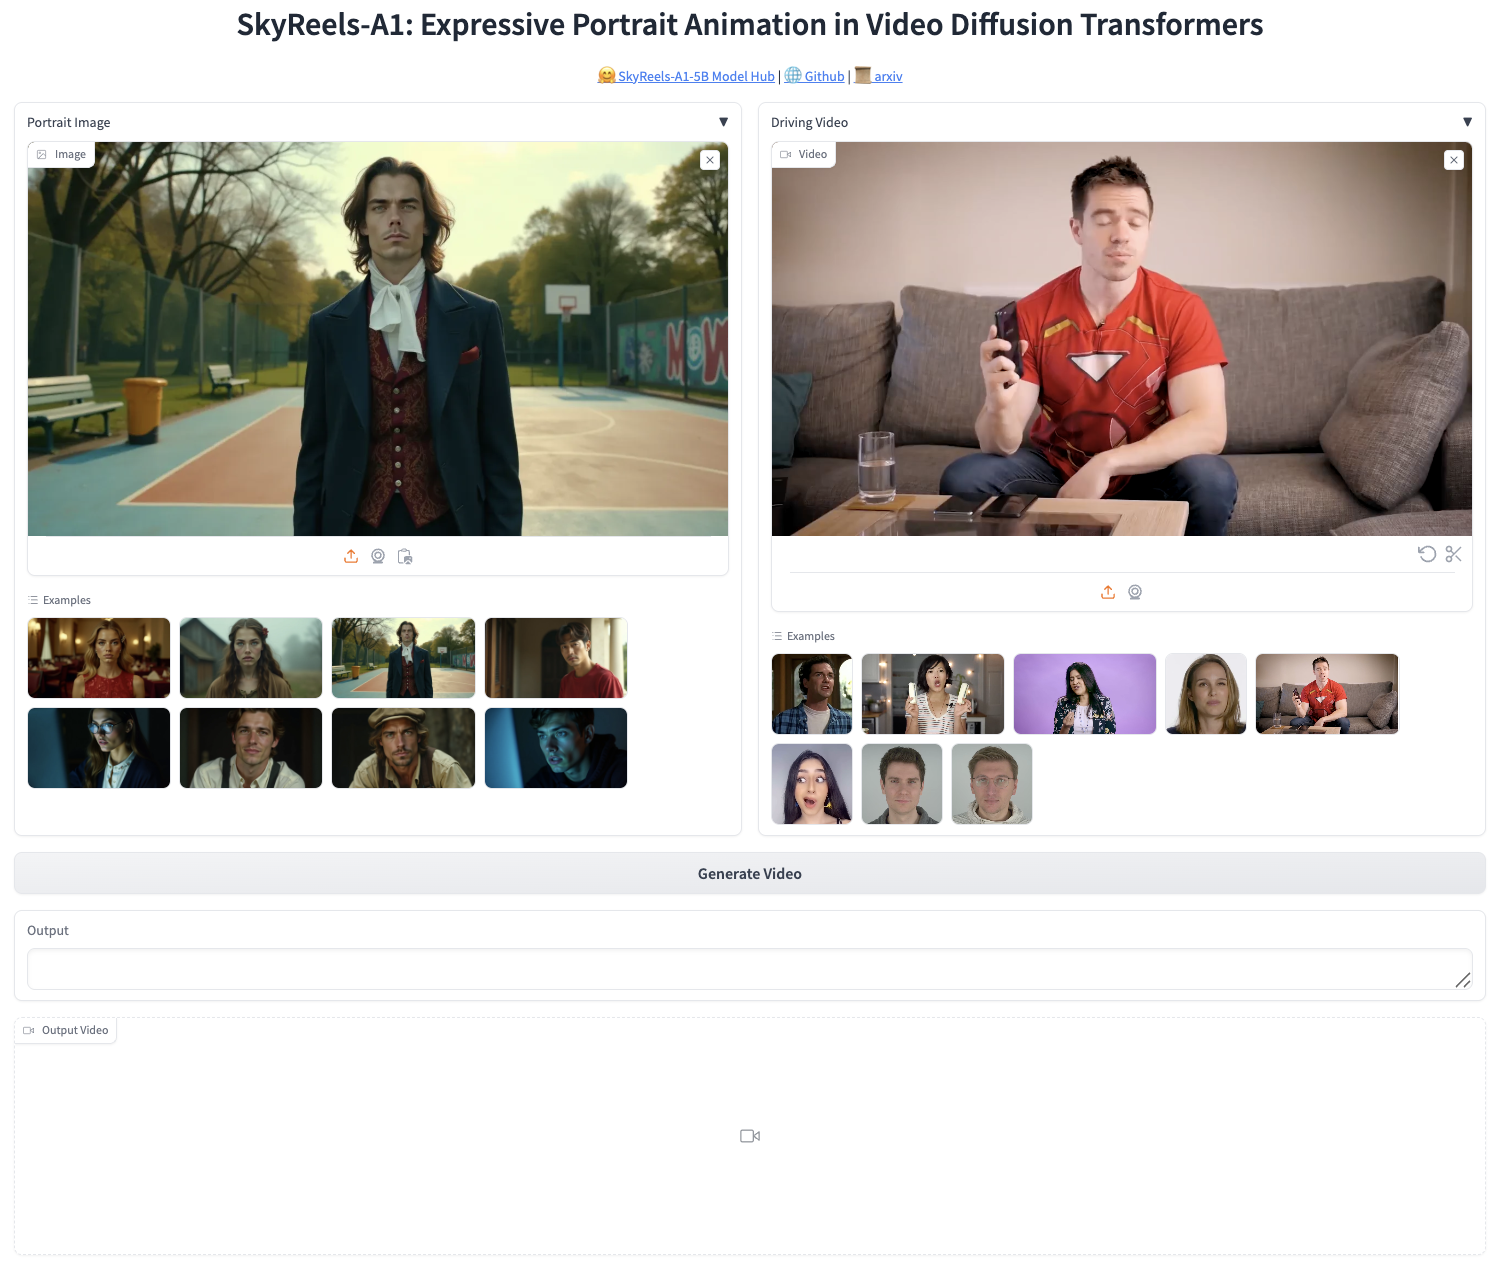
Gradio Interface 🤗

We provide a Gradio interface for a better experience, just run by:

python app.py

The graphical interactive interface is shown as below:
Metric Evaluation 👓

We also provide all scripts for automatically calculating the metrics, including SimFace, FID, and L1 distance between expression and motion, reported in the paper.

All codes can be found in the eval folder. After setting the video result path, run the following commands in sequence:

python arc_score.py
python expression_score.py
python pose_score.py

Acknowledgements 💐

We would like to thank the contributors of CogvideoX, finetrainers and DiffPoseTalkrepositories, for their open research and contributions.

Citation 💖

If you find SkyReels-A1 useful for your research, welcome to 🌟 this repo and cite our work using the following BibTeX:

@article{qiu2025skyreels,
  title={Skyreels-a1: Expressive portrait animation in video diffusion transformers},
  author={Qiu, Di and Fei, Zhengcong and Wang, Rui and Bai, Jialin and Yu, Changqian and Fan, Mingyuan and Chen, Guibin and Wen, Xiang},
  journal={arXiv preprint arXiv:2502.10841},
  year={2025}
}

Star History

Nearby in the ranking
Similar items