Segment and Track Anything (SAM-Track)
Online Demo:  Technical Report:
Tutorial: tutorial-v1.6(audio),tutorial-v1.5 (Text), tutorial-v1.0 (Click & Brush)
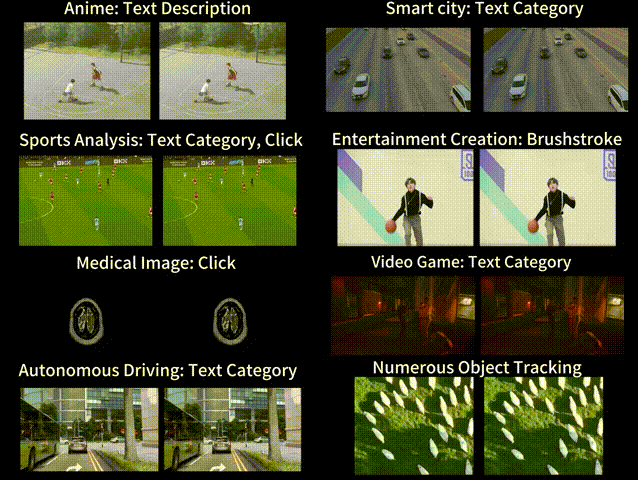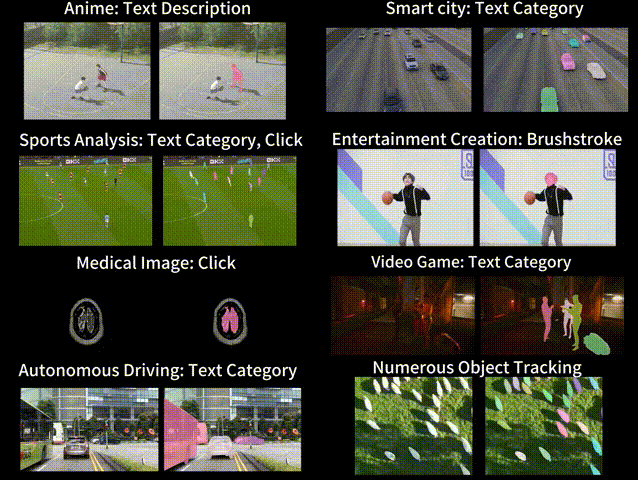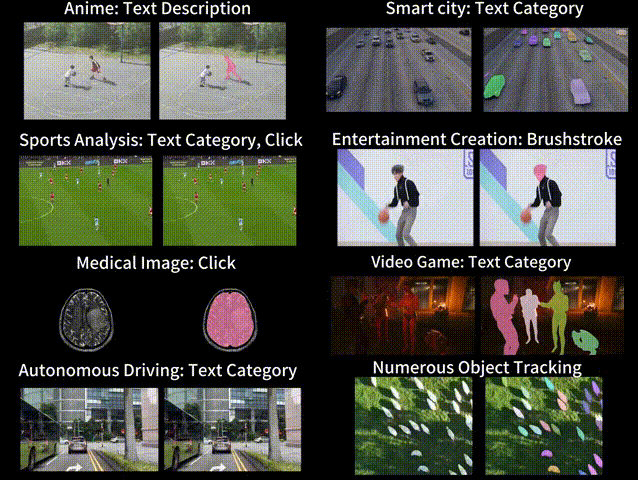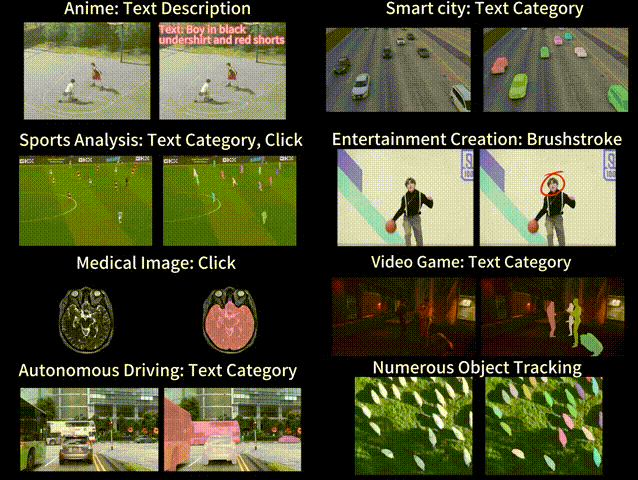
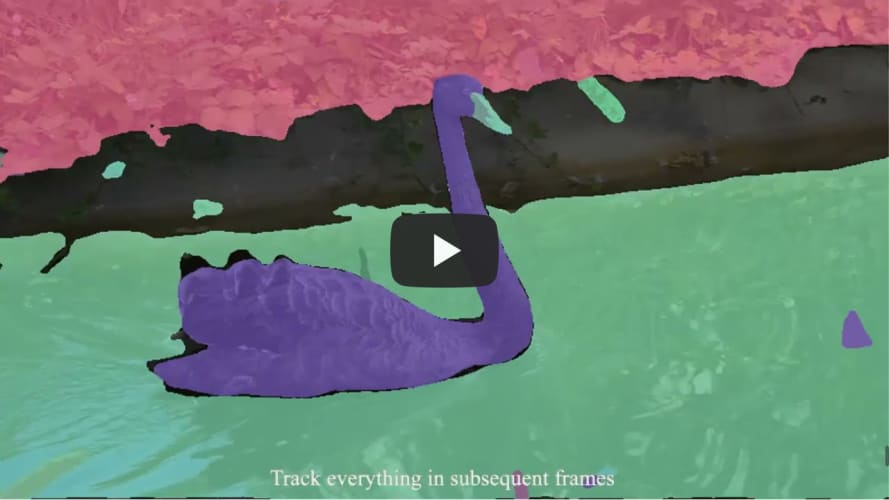
Segment and Track Anything is an open-source project that focuses on the segmentation and tracking of any objects in videos, utilizing both automatic and interactive methods. The primary algorithms utilized include the SAM (Segment Anything Models) for automatic/interactive key-frame segmentation and the DeAOT (Decoupling features in Associating Objects with Transformers) (NeurIPS2022) for efficient multi-object tracking and propagation. The SAM-Track pipeline enables dynamic and automatic detection and segmentation of new objects by SAM, while DeAOT is responsible for tracking all identified objects.
Impact
Segment and Track anything has been adopted as core infrastructure in published robotics research from MIT CSAIL and Harvard SEAS:
| Project | Institutions | Venue | Details |
|---|---|---|---|
| Follow Anything (FAn) | MIT CSAIL · Harvard SEAS · Project CETI | IEEE RA-L | Open-vocabulary real-time drone tracking system. |
:loudspeaker:New Features
-
[2024/4/23] We have added an audio-grounding feature that tracks the sound-making object within the video's soundtrack.
-
[2023/5/12] We have authored a technical report for SAM-Track.
-
[2023/5/7] We have added
demo_instseg.ipynb, which uses Grounding-DINO to detect new objects in the key frames of a video. It can be applied in the fields of smart cities and autonomous driving. -
[2023/4/29] We have added advanced arguments for AOT-L:
long_term_memory_gapandmax_len_long_term.long_term_memory_gapcontrols the frequency at which the AOT model adds new reference frames to its long-term memory. During mask propagation, AOT matches the current frame with the reference frames stored in the long-term memory.- Setting the gap value to a proper value helps to obtain better performance. To avoid memory explosion in long videos, we set a
max_len_long_termvalue for the long-term memory storage, i.e. when the number of memory frames reaches themax_len_long_term value, the oldest memory frame will be discarded and a new frame will be added.
-
[2023/4/26] Interactive WebUI 1.5-Version: We have added new features based on Interactive WebUI-1.0 Version.
- We have added a new form of interactivity—text prompts—to SAMTrack.
- From now on, multiple objects that need to be tracked can be interactively added.
- Check out tutorial for Interactive WebUI 1.5-Version. More demos will be released in the next few days.
-
[2023/4/26] Image-Sequence input: The WebUI now has a new feature that allows for input of image sequences, which can be used to test video segmentation datasets. Get started with the tutorial for Image-Sequence input.
-
[2023/4/25] Online Demo: You can easily use SAMTrack in Colab for visual tracking tasks.
-
[2023/4/23] Interactive WebUI: We have introduced a new WebUI that allows interactive user segmentation through strokes and clicks. Feel free to explore and have fun with the tutorial!
- [2023/4/24] Tutorial V1.0: Check out our new video tutorials!
- YouTube-Link: Tutorial for Interactively modify single-object mask for first frame of video、Tutorial for Interactively add object by click、Tutorial for Interactively add object by stroke.
- Bilibili Video Link:Tutorial for Interactively modify single-object mask for first frame of video、Tutorial for Interactively add object by click、Tutorial for Interactively add object by stroke.
- 1.0-Version is a developer version, please feel free to contact us if you encounter any bugs :bug:.
- [2023/4/24] Tutorial V1.0: Check out our new video tutorials!
-
[2023/4/17] SAMTrack: Automatically segment and track anything in video!
:fire:Demos
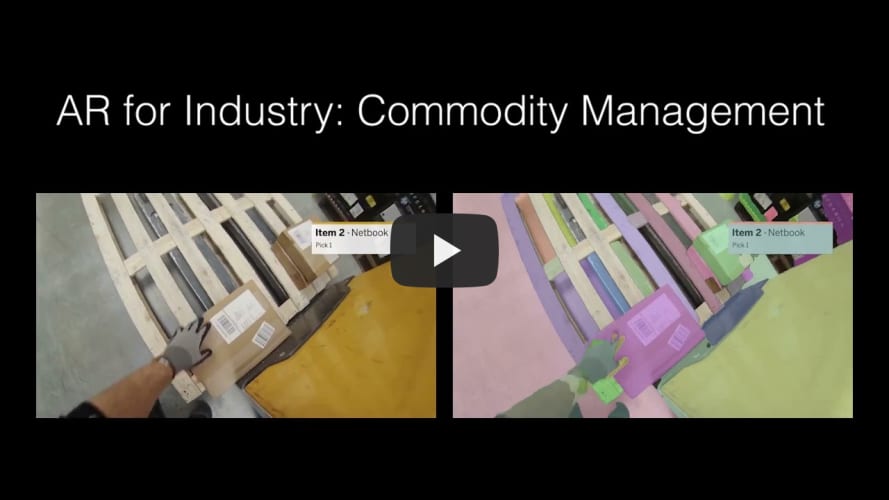
This video showcases the segmentation and tracking capabilities of SAM-Track in various scenarios, such as street views, AR, cells, animations, aerial shots, and more.
:calendar:TODO
- [x] Colab notebook: Completed on April 25th, 2023.
- [x] 1.0-Version Interactive WebUI: Completed on April 23rd, 2023.
- [x] 1.5-Version Interactive WebUI: Completed on April 26th, 2023.
- We will develop a function that allows interactive modification of multi-object masks for the first frame of a video. This function will be based on Version 1.0. YouTube: Demo4, Demo5; Bilibili: Demo4, Demo5
- Furthermore, we plan to include text prompts as an additional form of interaction. YouTube: Demo1, Demo2; Bilibili: Demo1, Demo2
- [ ] 2.x-Version Interactive WebUI
- In version 2.x, the segmentation model will offer two options: SAM and SEEM.
- We will develop a new function where the fixed-category object detection result can be displayed as a prompt.
- We will enable SAM-Track to add and modify objects during tracking. YouTube: Demo6, Demo7; Bilibili: Demo6, Demo7
Demo1 showcases SAM-Track's ability to take the class of objects as prompt. The user gives the category text 'panda' to enable instance-level segmentation and tracking of all objects belonging to this category.

Demo2 showcases SAM-Track's ability to take the text description as prompt. SAM-Track could segment and track target objects given the input that 'panda on the far left'.
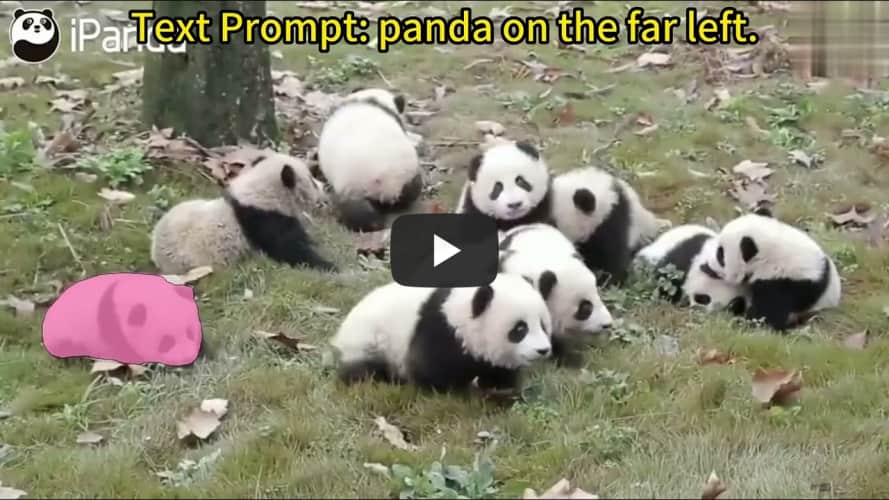
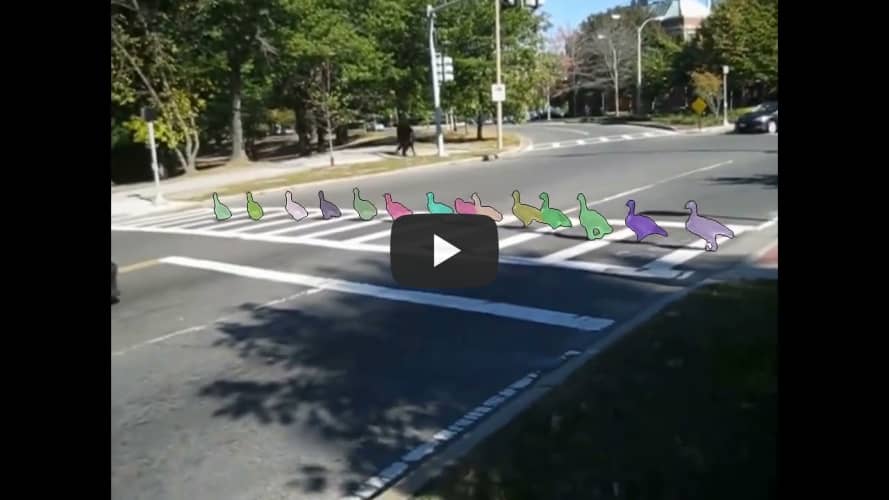
Demo3 showcases SAM-Track's ability to track numerous objects at the same time. SAM-Track is capable of automatically detecting newly appearing objects.
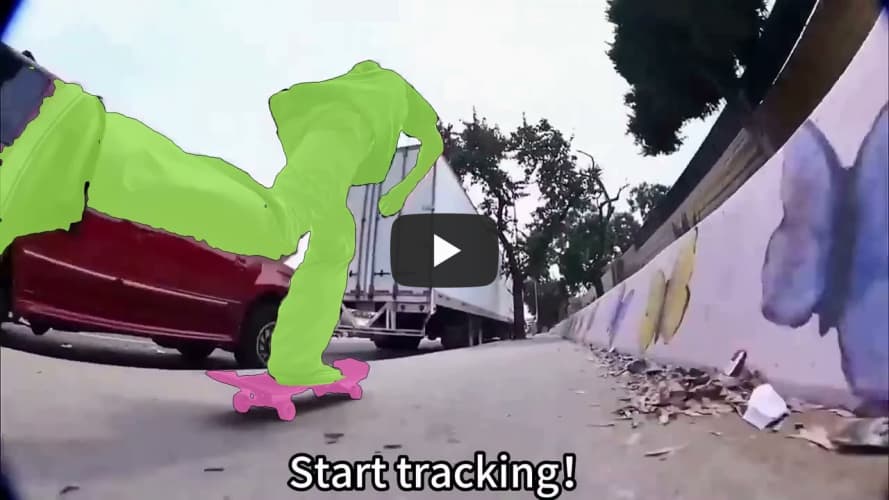
Demo4 showcases SAM-Track's ability to take multiple modes of interactions as prompt. The user specified human and skateboard with click and brushstroke, respectively.
Demo5 showcases SAM-Track's ability to refine the results of segment-everything. The user merges the tram as a whole with a single click.
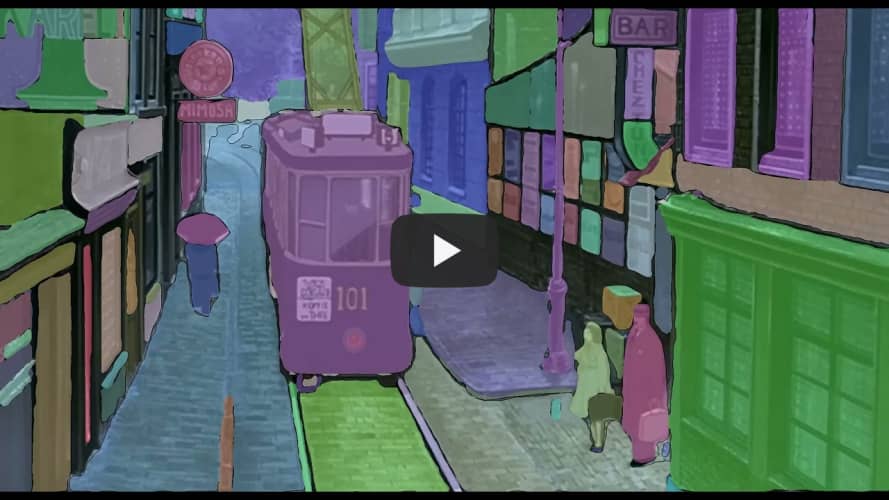
Demo6 showcases SAM-Track's ability to add new objects during tracking. The user annotates another car by rolling back to an intermediate frame.
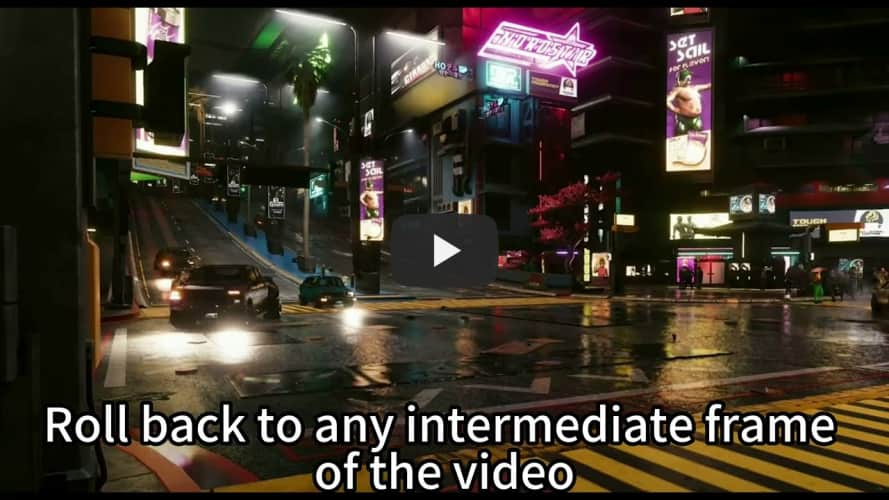
Demo7 showcases SAM-Track's ability to refine the prediction during tracking. This feature is highly advantageous for segmentation and tracking under complex environments.
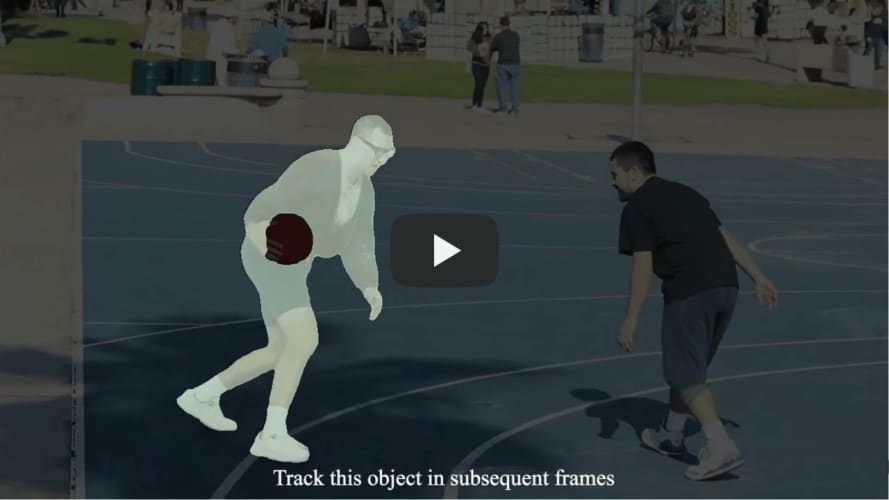
Demo8 showcases SAM-Track's ability to interactively segment and track individual objects. The user specified that SAM-Track tracked a man playing street basketball.
Demo9 showcases SAM-Track's ability to interactively add specified objects for tracking.The user customized the addition of objects to be tracked on top of the segmentation of everything in the scene using SAM-Track.
:computer:Getting Started
:bookmark_tabs:Requirements
The Segment-Anything repository has been cloned and renamed as sam, and the aot-benchmark repository has been cloned and renamed as aot.
Please check the dependency requirements in SAM and DeAOT.
The implementation is tested under python 3.9, as well as pytorch 1.10 and torchvision 0.11. We recommend equivalent or higher pytorch version.
Use the install.sh to install the necessary libs for SAM-Track
bash script/install.sh
FFmpeg Requirement
This project requires FFmpeg (used by MoviePy).
Setup (for Windows) Download: https://www.gyan.dev/ffmpeg/builds/ffmpeg-release-essentials.zip Extract to: C:\ffmpeg Add to PATH: C:\ffmpeg\bin Restart terminal and verify: ffmpeg -version
Setup (for linux): sudo apt update sudo apt install ffmpeg ffmpeg -version
Setup (for macOS): brew install ffmpeg ffmpeg -version
:star:Model Preparation
- Download the SAM model to ckpt folder for running the code
-
SAM vit_b (default) : https://dl.fbaipublicfiles.com/segment_anything/sam_vit_b_01ec64.pth
-
SAM vit_l: https://dl.fbaipublicfiles.com/segment_anything/sam_vit_l_0b3195.pth
-
SAM vit_h: https://dl.fbaipublicfiles.com/segment_anything/sam_vit_h_4b8939.pth
- Download DEAOT model to ckpt folder for running the code
| Model | Param (M) | PRE_YTB_DAV |
|---|---|---|
| DeAOTT | 7.2 | gdrive |
| DeAOTS | 10.2 | gdrive |
| DeAOTB | 13.2 | gdrive |
| DeAOTL | 13.2 | gdrive |
| R50-DeAOTL | 19.8 | gdrive |
| SwinB-DeAOTL | 70.3 | gdrive |
Download Grounding-DINO model to ckpt folder
| Name | Backbone | Training Data | Box AP (COCO) | Checkpoint |
|---|---|---|---|---|
| GroundingDINO-T | Swin-T | O365, GoldG, Cap4M | 48.4 (zero-shot) / 57.2 (fine-tuned) | Download |
| GroundingDINO-B | Swin-B | COCO, O365, GoldG, Cap4M, OpenImages, ODinW-35, RefCOCO | 56.7 | Download |
Download AST model to ast_master/pretrained_models, after cloning the AST repository
-
Full AudioSet, 10 tstride, 10 fstride, with Weight Averaging (0.459 mAP)
-
Full AudioSet, 10 tstride, 10 fstride, without Weight Averaging, Model 1 (0.450 mAP)
-
Full AudioSet, 10 tstride, 10 fstride, without Weight Averaging, Model 2 (0.448 mAP)
-
Full AudioSet, 10 tstride, 10 fstride, without Weight Averaging, Model 3 (0.448 mAP)
-
Full AudioSet, 12 tstride, 12 fstride, without Weight Averaging, Model (0.447 mAP)
-
Full AudioSet, 14 tstride, 14 fstride, without Weight Averaging, Model (0.443 mAP)
-
Full AudioSet, 16 tstride, 16 fstride, without Weight Averaging, Model (0.442 mAP)
-
Speechcommands V2-35, 10 tstride, 10 fstride, without Weight Averaging, Model (98.12% accuracy on evaluation set) the default model is audioset_0.4593 (audioset_0.4593.pth).
You can download the default weights using the command line as shown below. $$ bash script/download_ckpt.sh $$
Running docker file
- docker build -f Dockerfile -t myimage .
- docker run myimage
:heart:Run Demo
- The video to be processed can be put in ./assets.
- Then run demo.ipynb step by step to generate results.
- The results will be saved as masks for each frame and a gif file for visualization.
The arguments for SAM-Track, DeAOT and SAM can be manually modified in model_args.py for purpose of using other models or controling the behavior of each model.
:muscle:WebUI App
Our user-friendly visual interface allows you to easily obtain the results of your experiments. Simply initiate it using the command line.
python app.py
Users can upload the video directly on the UI and use SegTracker to automatically/interactively track objects within that video. We use a video of a man playing basketball as an example.

SegTracker-Parameters:
- aot_model: used to select which version of DeAOT/AOT to use for tracking and propagation.
- sam_gap: used to control how often SAM is used to add newly appearing objects at specified frame intervals. Increase to decrease the frequency of discovering new targets, but significantly improve speed of inference.
Common issue: – Unexpected new object detections after ~100 frames
If you observe that only a subset of objects (e.g., 32 fish) were initially selected, but after around frame 100 the tracker suddenly detects many additional objects (e.g., 96 fish, including false positives in the background), this is expected behavior rather than a bug.
By default, SAM is re-invoked every sam_gap = 100 frames to discover newly appearing objects. During this re-segmentation step, SAM may automatically detect additional objects or background regions, increasing the number of tracked instances.
Solution: Increase the sam_gap value to a number larger than the total number of frames you intend to process (or larger than the frame index where this occurs). This prevents automatic SAM re-segmentation and keeps tracking only the objects that were initially selected.
For example:
Tracking a 150-frame video with fixed objects? Set sam_gap = 1000. Want SAM to discover genuinely new objects during tracking? Keep sam_gap at a smaller value.
- points_per_side: used to control the number of points per side used for generating masks by sampling a grid over the image. Increasing the size enhances the ability to detect small objects, but larger targets may be segmented into finer granularity.
- max_obj_num: used to limit the maximum number of objects that SAM-Track can detect and track. A larger number of objects necessitates a greater utilization of memory, with approximately 16GB of memory capable of processing a maximum of 255 objects.
Usage: To see the details, please refer to the tutorial for 1.0-Version WebUI.
:school:About us
Thank you for your interest in this project. The project is supervised by the ReLER Lab at Zhejiang University’s College of Computer Science and Technology. ReLER was established by Yang Yi, a Qiu Shi Distinguished Professor at Zhejiang University. Our dedicated team of contributors includes Yangming Cheng, Jiyuan Hu, Yuanyou Xu, Liulei Li, Xiaodi Li, Zongxin Yang, Wenguan Wang and Yi Yang.
:full_moon_with_face:Credits
Licenses for borrowed code can be found in licenses.md file.
- DeAOT/AOT - https://github.com/yoxu515/aot-benchmark
- SAM - https://github.com/facebookresearch/segment-anything
- Gradio (for building WebUI) - https://github.com/gradio-app/gradio
- Grounding-Dino - https://github.com/yamy-cheng/GroundingDINO
- AST - https://github.com/YuanGongND/ast
License
The project is licensed under the AGPL-3.0 license. To utilize or further develop this project for commercial purposes through proprietary means, permission must be granted by us (as well as the owners of any borrowed code).
Citations
Please consider citing the related paper(s) in your publications if it helps your research.
@article{cheng2023segment,
  title={Segment and Track Anything},
  author={Cheng, Yangming and Li, Liulei and Xu, Yuanyou and Li, Xiaodi and Yang, Zongxin and Wang, Wenguan and Yang, Yi},
  journal={arXiv preprint arXiv:2305.06558},
  year={2023}
}
@article{kirillov2023segment,
  title={Segment anything},
  author={Kirillov, Alexander and Mintun, Eric and Ravi, Nikhila and Mao, Hanzi and Rolland, Chloe and Gustafson, Laura and Xiao, Tete and Whitehead, Spencer and Berg, Alexander C and Lo, Wan-Yen and others},
  journal={arXiv preprint arXiv:2304.02643},
  year={2023}
}
@inproceedings{yang2022deaot,
  title={Decoupling Features in Hierarchical Propagation for Video Object Segmentation},
  author={Yang, Zongxin and Yang, Yi},
  booktitle={Advances in Neural Information Processing Systems (NeurIPS)},
  year={2022}
}
@inproceedings{yang2021aot,
  title={Associating Objects with Transformers for Video Object Segmentation},
  author={Yang, Zongxin and Wei, Yunchao and Yang, Yi},
  booktitle={Advances in Neural Information Processing Systems (NeurIPS)},
  year={2021}
}
@article{yang2024scalable,
  title={Scalable video object segmentation with identification mechanism},
  author={Yang, Zongxin and Miao, Jiaxu and Wei, Yunchao and Wang, Wenguan and Wang, Xiaohan and Yang, Yi},
  journal={IEEE Transactions on Pattern Analysis and Machine Intelligence},
  volume={46},
  number={9},
  pages={6247--6262},
  year={2024},
  publisher={IEEE}
}
@article{liu2023grounding,
  title={Grounding dino: Marrying dino with grounded pre-training for open-set object detection},
  author={Liu, Shilong and Zeng, Zhaoyang and Ren, Tianhe and Li, Feng and Zhang, Hao and Yang, Jie and Li, Chunyuan and Yang, Jianwei and Su, Hang and Zhu, Jun and others},
  journal={arXiv preprint arXiv:2303.05499},
  year={2023}
}
@inproceedings{gong21b_interspeech,
  author={Yuan Gong and Yu-An Chung and James Glass},
  title={AST: Audio Spectrogram Transformer},
  booktitle={Proc. Interspeech 2021},
  pages={571--575},
  doi={10.21437/Interspeech.2021-698}
  year={2021}
}