yvann-ba/ComfyUI_Yvann-Nodes 排名第 14,657,有 714 个星标。
同类别比较
yvann-ba/ComfyUI_Yvann-Nodes 排名第 14,657,此处有 8 个同类条目;chujiezheng/chat_templates 排名第 14,650。
同类别比较| 名称 | 排名 | 指标 |
|---|
| MISTLab/Swarm-SLAM | 14,630 | - 语言:
- Shell
- 星标数:
- 715
- 分叉数:
- 82
- 简介:
- Sparse Decentralized Collaborative Simultaneous Localization and Mapping Framework for Multi-Robot Systems
|
|---|
| OpenClaudia/openclaudia-skills | 14,632 | - 语言:
- JavaScript
- 星标数:
- 715
- 分叉数:
- 59
- 简介:
- 77 open-source marketing skills for Claude Code, Codex, and other AI coding agents. SEO, content, email, ads, analytics, and growth.
|
|---|
| Picovoice/rhino | 14,647 | - 语言:
- Python
- 星标数:
- 714
- 分叉数:
- 97
- 简介:
- On-device Speech-to-Intent engine powered by deep learning
|
|---|
| chujiezheng/chat_templates | 14,650 | - 语言:
- Jinja
- 星标数:
- 714
- 分叉数:
- 64
- 简介:
- Chat Templates for 🤗 HuggingFace Large Language Models
|
|---|
| mckaywrigley/ai-brainstore | 14,665 | - 语言:
- TypeScript
- 星标数:
- 713
- 分叉数:
- 97
- 简介:
- An experiment concept for an AI brain.
|
|---|
| SeanJ1ang/design-judge-skills | 14,671 | - 语言:
- Python
- 星标数:
- 712
- 分叉数:
- 102
- 简介:
- Evidence-driven Agent Skills for design award research, evaluation, award matching, entry writing, and submission readiness.
|
|---|
| easylink-ai-open/tiri-agent | 14,688 | - 语言:
- TypeScript
- 星标数:
- 711
- 分叉数:
- 121
- 简介:
- Tiri local agent backend and web shell built on agent-runtime.
|
|---|
| runesleo/claude-code-workflow | 14,722 | - 语言:
- Shell
- 星标数:
- 709
- 分叉数:
- 88
- 简介:
- QuietHarness:Claude Code、Codex、Cursor 共用的轻量 AI 工作系统
|
|---|
关键参数与规格
关键参数与规格| 参数 | 值 |
|---|
| 语言 | Python |
|---|
| 类别 | AI Engineering |
|---|
| 子类别 | Build agent workflow (visual) |
|---|
| 关键词 | Image production, Music |
|---|
| 星标数 | 714 |
|---|
| 分叉数 | 30 |
|---|
| 贡献者 | 4 |
|---|
| 创建日期 | 2024-08-26 |
|---|
| 更新日期 | 2026-10-09 |
|---|
| 1 天星标数 | 0 |
|---|
| 7 天星标数 | -1 |
|---|
| 排名 | 14,657 |
|---|
| 上次排名 | 14,506 |
|---|
| 排名变化 | -151 |
|---|
| 7 天星标排名 | 17,686 |
|---|
| 上次 7 天星标排名 | 17,639 |
|---|
| 7 天星标排名变化 | -47 |
|---|
| 总星标排名 | 14,667 |
|---|
| 上次总星标排名 | 14,641 |
|---|
| 总星标排名变化 | -26 |
|---|
| 国家 | France |
|---|
README 摘录
**Create** Audio Reactive AI videos, enable controls over AI generations styles, content and composition with any audio **Simple**: Just Drop one of our Workflows in ComfyUI and specify your audio and visuals input **Flexible**: Works with existing ComfyUI AI tech and nodes (eg: IPAdapter, AnimateDiff, ControlNet, etc. Install ComfyUI (Works on Mac, Windows, Linux) 2. **Drop** the downloaded file into the ComfyUI window 2. **Set your inputs** (images/video/text + audio) 4. **Download the models** listed on the note 5
. **Click Queue** to generate your audio-reactive animation! Node Parameters **audio_sep_model**: Model from "Load Audio Separation Model" **audio**: Input audio file **batch_size**: Frames to associate with audio weights **fps**: Frame rate for the analysis **Parameters**: **analysis_mode**: e. , Drums Only, Vocals, Full Audio **threshold**: Minimum weight pass-through **multiply**: Amplification factor **Outputs**: **graph_audio** (image preview), **processed_audio**, **original_audio**, **audio_weights** (list of values). Node Parameters **model**: Choose between HybridDemucs / OpenUnmix. **Outputs**: **audio_sep_model** (connect
to Audio Analysis or Remixer). Node Parameters **peaks_threshold**: Sensitivity. **min_peaks_distance**: Minimum gap in frames between peaks. **Outputs**: Binary peak list, alternate list, peak indices/count, graph. Node Parameters **images**: Batch of images. **peaks_weights**: From "Audio Peaks Detection". **blend_mode**, **transitions_length**, **min_IPA_weight**, etc. Node Parameters **peaks_index**: Indices from peaks detection. Node Parameters **drums_volume**, **vocals_volume**, **bass_volume**, **others_volume** **Outputs**: single merged audio track. Node Parameters **floats**: list of floats. Node Parameters
**floats** (and optional second/third). " Node Parameters **floats**: list of floats. **Outputs**: dictionary with strategy info.
常见问题
记录了多少星标和分叉?
yvann-ba/ComfyUI_Yvann-Nodes 有 714 个星标和 30 个分叉。
仓库排名是多少?
yvann-ba/ComfyUI_Yvann-Nodes 排名第 14,657。
记录的语言和类别是什么?
yvann-ba/ComfyUI_Yvann-Nodes 有 714 个星标,语言为 Python,类别为 AI Engineering。
哪个仓库排名最接近?
yvann-ba/ComfyUI_Yvann-Nodes 与 chujiezheng/chat_templates 比较,后者排名第 14,650,有 714 个星标。
A pack of custom nodes that enable audio reactivity within ComfyUI, allowing you to generate AI-driven animations that sync with music
What Does This Do?
- Create Audio Reactive AI videos, enable controls over AI generations styles, content and composition with any audio
- Simple: Just Drop one of our Workflows in ComfyUI and specify your audio and visuals input
- Flexible: Works with existing ComfyUI AI tech and nodes (eg: IPAdapter, AnimateDiff, ControlNet, etc.)
Quick Setup
1. Install ComfyUI (Works on Mac, Windows, Linux)
2. Pick a Workflow ⬇️
🖼️ Images to Video
Takes a set of images + audio
Results:
[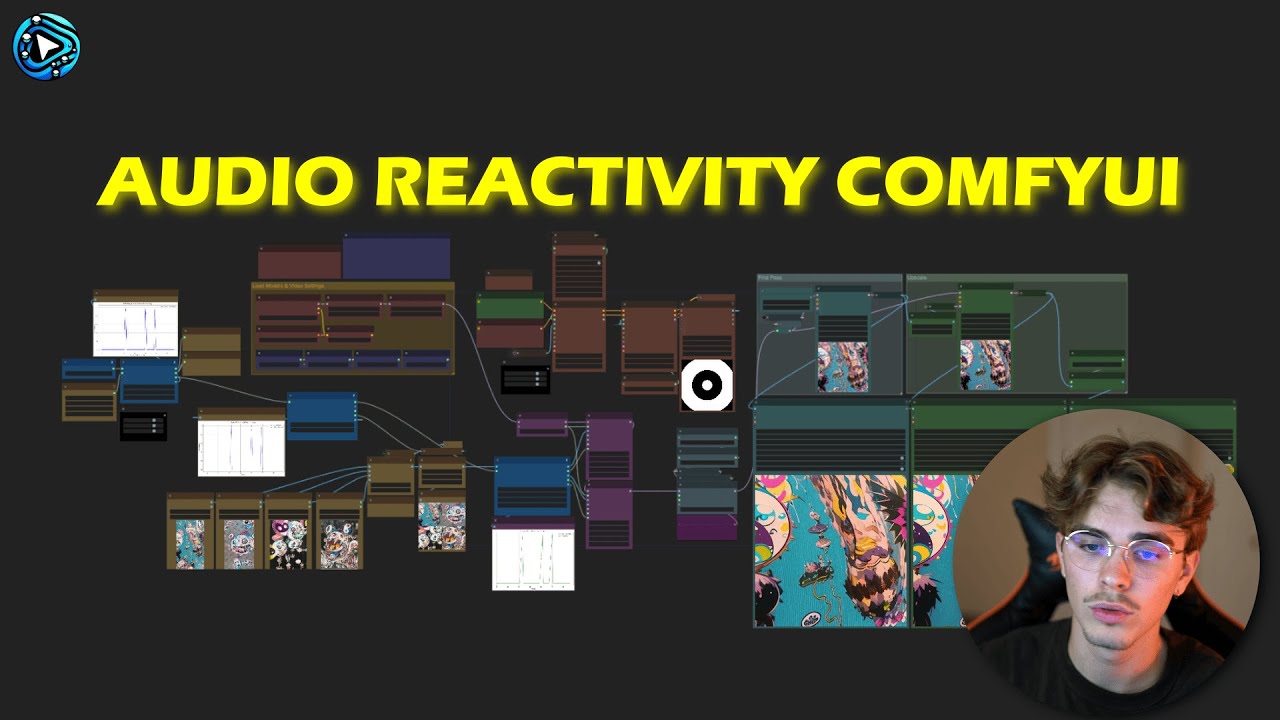](https://www.youtube.com/watch?v=O2s6NseXlMc)
📺 Watch Tutorial
📥 Download ImagesToVideo Workflow
🎬 Video to Video
Takes a source video + audio
Results:
[](https://www.youtube.com/watch?v=BiQHWKP3q0c)
📺 Watch Tutorial
📥 Download VideoToVideo Workflow
✍️ Text to Video
Takes a text prompt + audio
Results:
📥 Download TextToVideo Workflow
3. Load & Run
- Drop the downloaded
.json file into the ComfyUI window
- Click "Install All" on the popup
- Set your inputs (images/video/text + audio)
- Download the models listed on the note
- Click Queue to generate your audio-reactive animation!
That's it! Have fun !!
That's it! Have fun !!
Nodes Details
Click to Expand: Node-by-Node Reference
Audio Analysis 🔍
Analyzes audio to generate reactive weights for each frame.
Node Parameters
- audio_sep_model: Model from "Load Audio Separation Model"
- audio: Input audio file
- batch_size: Frames to associate with audio weights
- fps: Frame rate for the analysis
Parameters:
- analysis_mode: e.g., Drums Only, Vocals, Full Audio
- threshold: Minimum weight pass-through
- multiply: Amplification factor
Outputs:
- graph_audio (image preview),
- processed_audio, original_audio,
- audio_weights (list of values).
Load Audio Separation Model 🎧
Loads or downloads an audio separation model (e.g., HybridDemucs, OpenUnmix).
Node Parameters
- model: Choose between HybridDemucs / OpenUnmix.
- Outputs: audio_sep_model (connect to Audio Analysis or Remixer).
Audio Peaks Detection 📈
Identifies peaks in the audio weights to trigger transitions or events.
Node Parameters
- peaks_threshold: Sensitivity.
- min_peaks_distance: Minimum gap in frames between peaks.
- Outputs: Binary peak list, alternate list, peak indices/count, graph.
Audio IP Adapter Transitions 🔄
Manages transitions between images based on peaks. Great for stable or style transitions.
Node Parameters
- images: Batch of images.
- peaks_weights: From "Audio Peaks Detection".
- blend_mode, transitions_length, min_IPA_weight, etc.
Audio Prompt Schedule 📝
Links text prompts to peak indices.
Node Parameters
- peaks_index: Indices from peaks detection.
- prompts: multiline string.
- Outputs: mapped schedule string.
Audio Remixer 🎛️
Adjusts volume levels (drums, vocals, bass, others) in a track.
Node Parameters
- drums_volume, vocals_volume, bass_volume, others_volume
- Outputs: single merged audio track.
Repeat Image To Count 🔁
Repeats a set of images N times.
Node Parameters
- mask: Mask input.
- Outputs: Repeated images.
Invert Floats 🔄
Flips sign of float values.
Node Parameters
- floats: list of floats.
- Outputs: inverted list.
Floats Visualizer 📈
Plots float values as a graph.
Node Parameters
- floats (and optional second/third).
- Outputs: visual graph image.
Mask To Float 🎭
Converts a mask into a single float value.
Node Parameters
- mask: input.
- Outputs: float.
Floats To Weights Strategy 🏋️
Transforms float lists into an IPAdapter "weight strategy."
Node Parameters
- floats: list of floats.
- Outputs: dictionary with strategy info.
Please give a ⭐ on GitHub it helps us enhance our Tool and it's Free !! (:
Made with the help of Lilien 😎