Language Models are Super Mario: Absorbing Abilities from Homologous Models as a Free Lunch

This repository is built for the paper Language Models are Super Mario: Absorbing Abilities from Homologous Models as a Free Lunch. 🔔 If you have any questions or suggestions, please feel free to let us know. You can directly email Le Yu using the email address yule@buaa.edu.cn or post an issue on this repository.
💥 News 💥
- 🔥🔥🔥[May 2, 2024] Our paper is accepted at ICML 2024! The camera ready version is coming soon.
- 🔥🔥🔥[February 9, 2024] Special thanks to Sourab Mangrulkar for integrating our work into the huggingface/peft Project!
- 🔥🔥🔥[January 28, 2024] Our merged model supermario_v2 ranks first among 7B models on the Open LLM Leaderboard!
- 🔥🔥🔥[December 4, 2023] We appreciate Minhajul Hoque for sharing our work on Medium!
- 🔥🔥🔥[November 29, 2023] Special thanks to papersread.ai for sharing our work!
- 🔥🔥🔥[November 29, 2023] We appreciate martyn for extending our work to Stable Diffusion models!
- 🔥🔥🔥[November 27, 2023] Special thanks to brucethemoose for applying our work on the model on Hugging Face!
- 🔥🔥🔥[November 26, 2023] We appreciate cg123 for integrating our work into the mergekit Project!
- 🔥🔥🔥[November 25, 2023] Special thanks to fly51fly for sharing our work on Twitter!
- 🔥🔥🔥[November 24, 2023] We appreciate uukuguy for integrating our work into the Multi-LoRAs Project!
- 🔥🔥🔥[November 23, 2023] Special thanks to WizardLM for sharing our work on Twitter!
- 🔥🔥🔥[November 21, 2023] We appreciate PaperWeekly for sharing our work on WeChat and Zhihu!
- 🔥🔥🔥[November 11, 2023] Special thanks to 夕小瑶 for sharing our work on WeChat and Zhihu!
- 🔥🔥🔥[November 6, 2023] Our paper is available on arXiv, Papers With Code, and Hugging Face.
Overview
In this work, we uncover that Language Models (LMs), either encoder- or decoder-based, can obtain new capabilities by assimilating the parameters of homologous models without the need for retraining or GPUs.
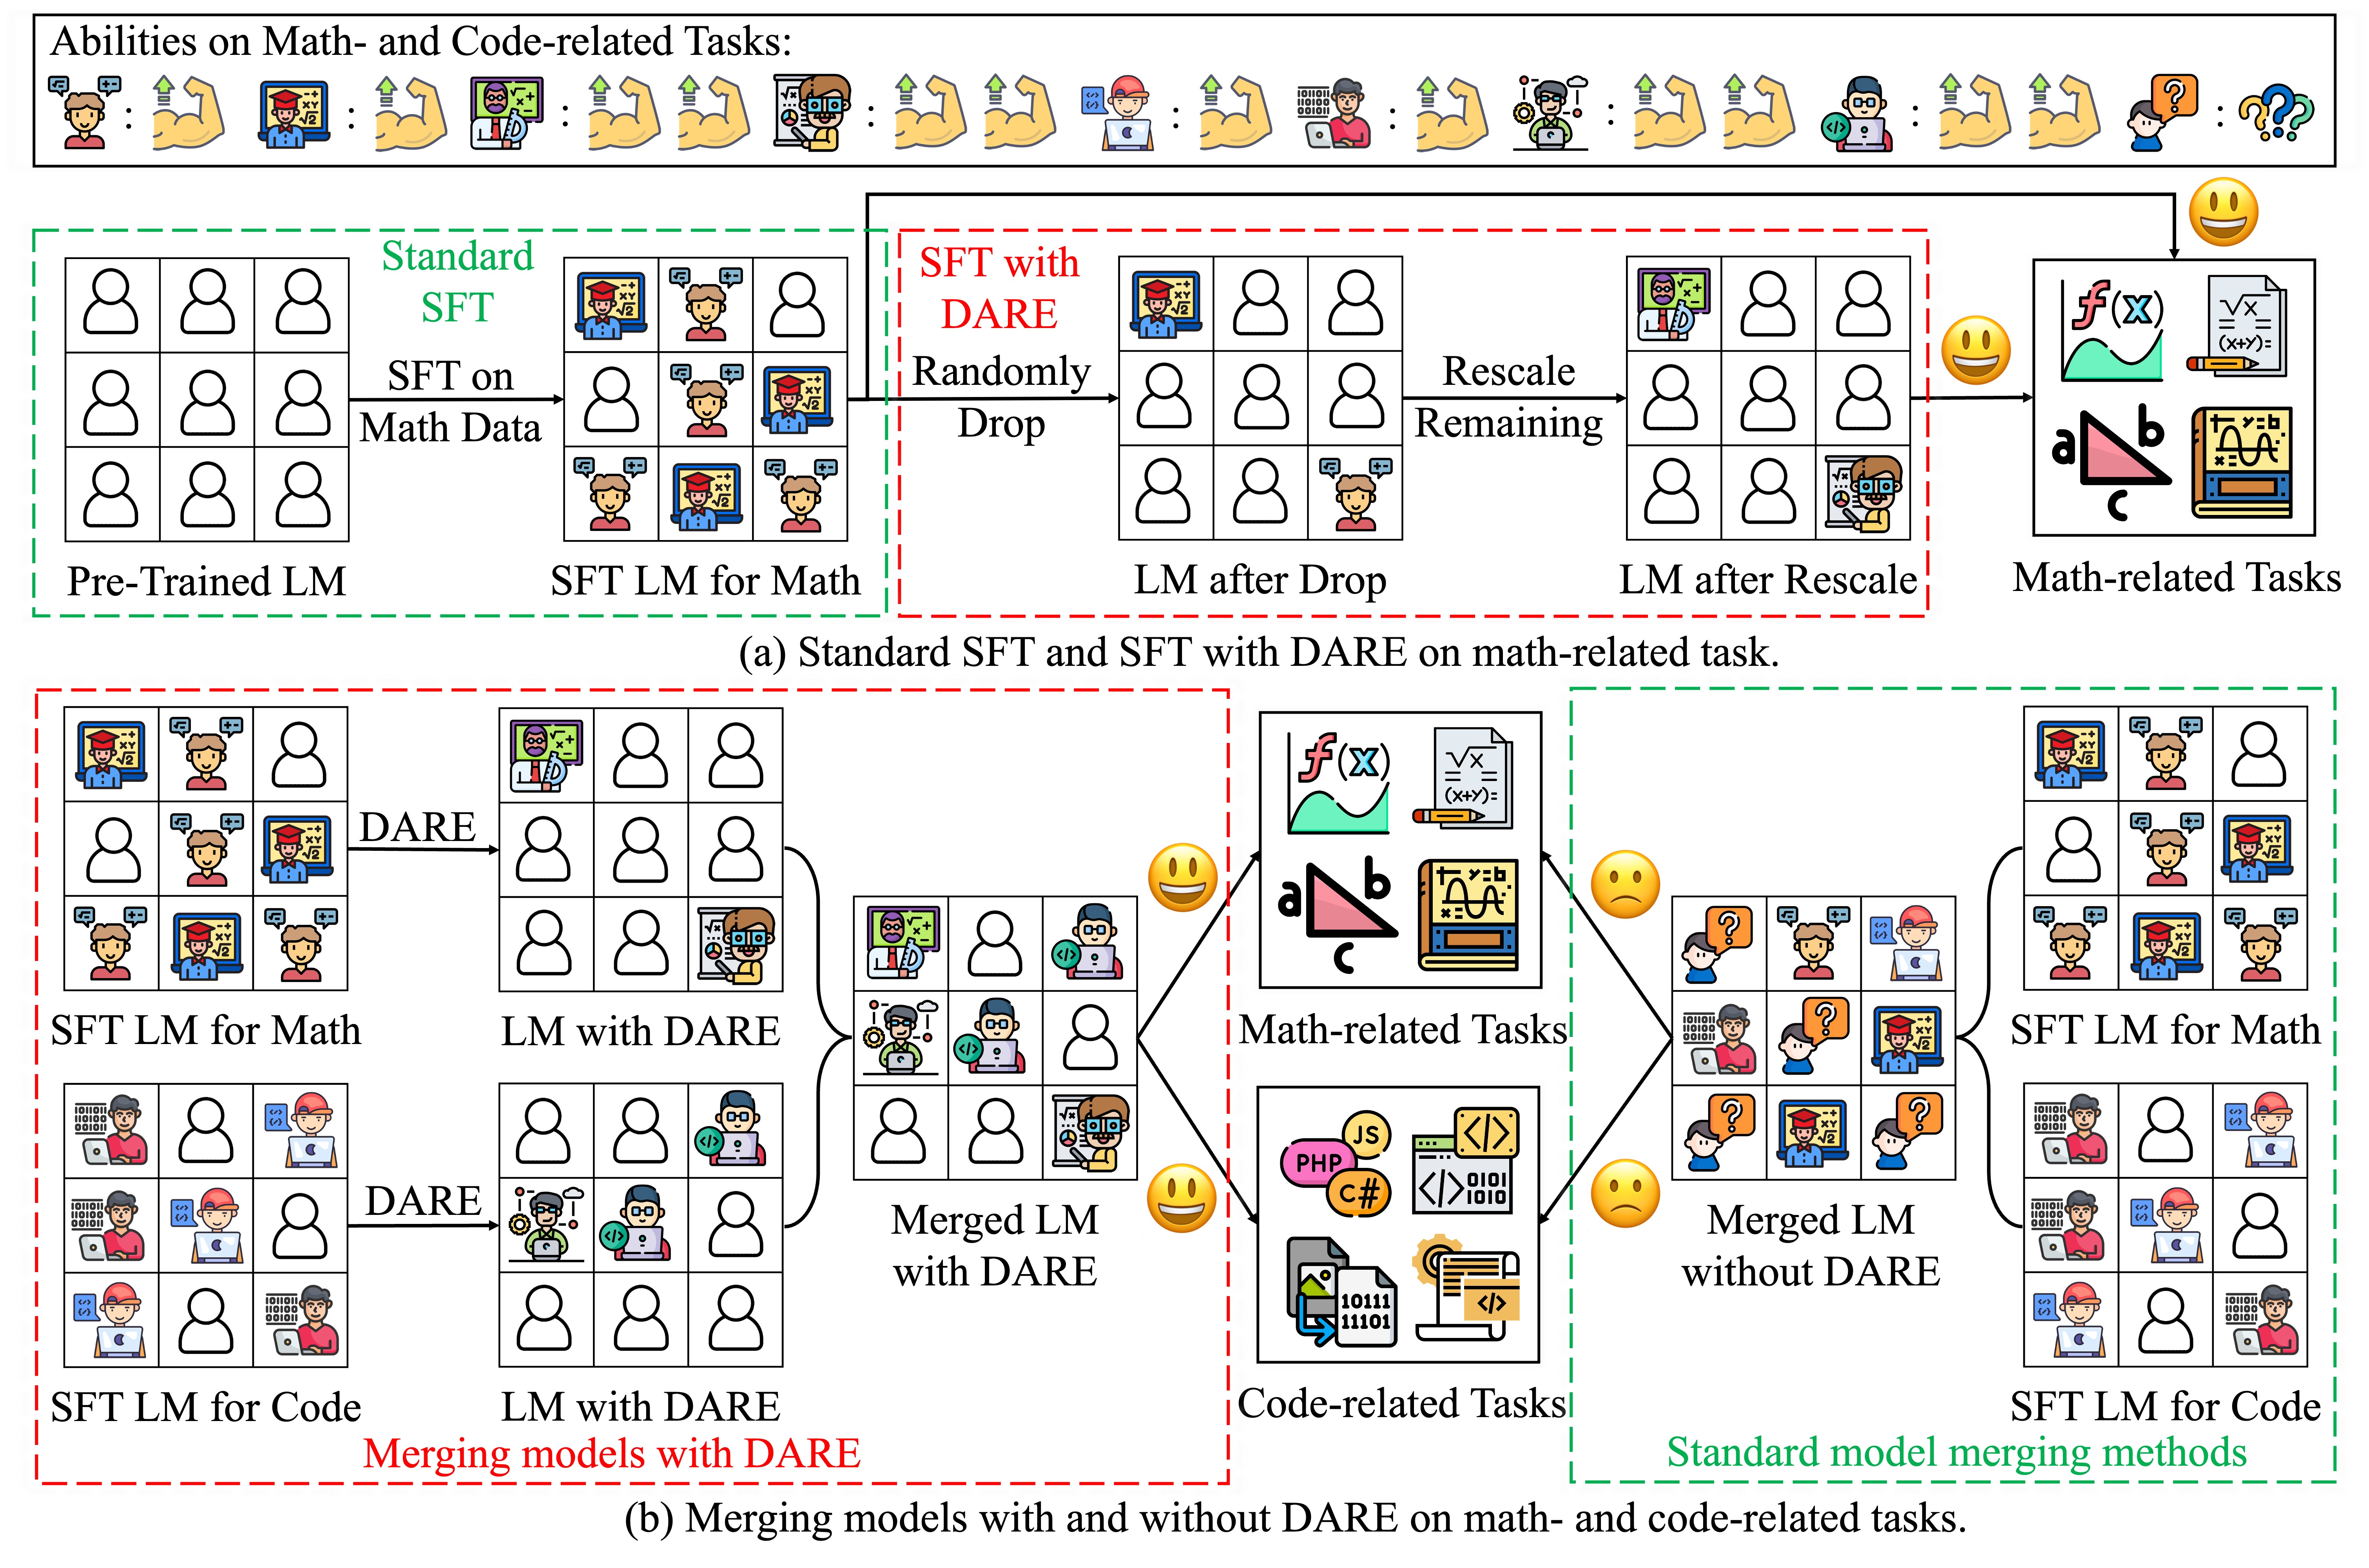
- We introduce a novel operation called DARE to directly set most of (90% or even 99%) the delta parameters to zeros without affecting the capabilities of SFT LMs.
- We sparsify delta parameters of multiple SFT homologous models with DARE as a general preprocessing technique and subsequently merge them into a single model by parameter averaging.
The workflow is shown as follows,
By conducting extensive experiments, we find that:
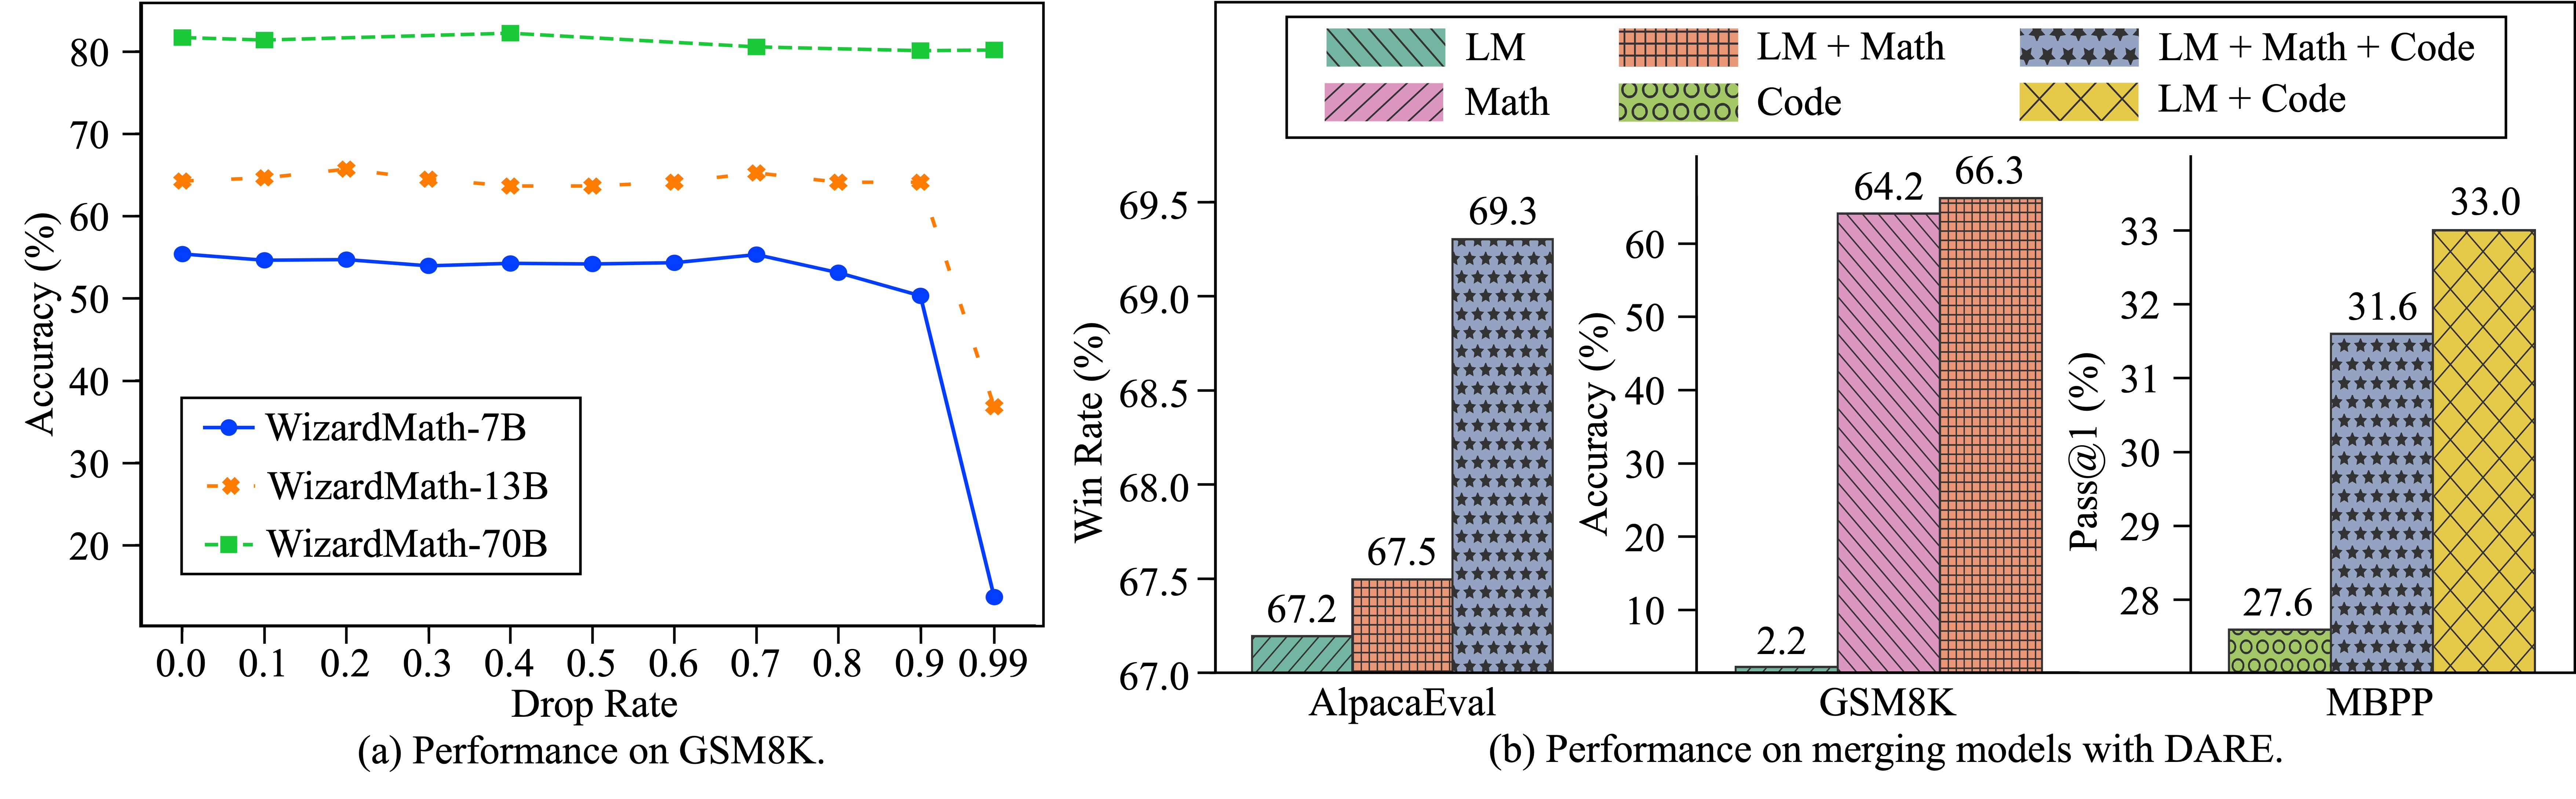
- DARE is effective for SFT models whose delta parameter value ranges are relatively small (e.g., within 0.005), being able to eliminate even 99% delta parameters. Larger models can tolerate a higher proportion of discarded parameters, indicating that SFT naturally learns an extremely sparse set of delta parameters, and nearly all abilities originate from the pre-trained LMs. See (a) in the figure below.
- DARE can merge multiple task-specific LMs into one LM with diverse abilities, which is able to possess the functionalities of all SFT models. For instance, the merger of WizardLM and WizardMath increases the GSM8K accuracy of WizardLM from 2.2 to 66.3, maintaining its instruction-following capabilities while surpassing WizardMath's original 64.2 performance. See (b) in the figure below.
Language Models and Datasets
We conduct experiments on both encoder- and decoder-based LMs.
- For encoder-based LMs, we choose bert-base-uncased and roberta-base as pre-trained backbones. Eight datasets from the GLUE benchmark are used, including CoLA, SST-2, MRPC, STS-B, QQP, MNLI, QNLI, and RTE.
- For decoder-based LMs, we choose LLaMA, Llama 2, and Code Llama as pre-trained backbones. WizardLM, WizardMath, WizardCoder-Python, and Code Alpaca are used as fine-tuned models. We evaluate three tasks on five datasets: AlpacaEval (instruction-following), GSM8K and MATH (mathematical reasoning), and HumanEval and MBPP (code-generating).
Note that we provide GSM8K, MATH, and MBPP datasets in math_code_data/ folder, which are obtained from WizardLM repository.
Other datasets can be automatically downloaded by our codes. For language models, you can download them either manually or by our codes.
You can also modify the cache_dir in the utils/load_config.py file to specify your own path to save datasets and models.
Model Merging Methods
We provide a well-coded implementation of five model merging methods in this repository, including Average Merging, Task Arithmetic, Fisher Merging, RegMean, and TIES-Merging. We also combine the proposed DARE with the above methods to facilitate the merging performance.
Environments
PyTorch 2.0.1, transformers 4.33.1, datasets 2.13.1, vllm 0.1.4, human_eval, numpy, and tqdm.
Executing Scripts for Encoder-based LMs
For encoder-based LMs, we first fine-tune them on the GLUE benchmark (support both single-task and multi-task settings), and then inference with them. We also provide scripts to merge encoder-based LMs with five model merging methods.
Scripts for Fine-Tuning on GLUE
- Example of fine-tuning roberta-base on CoLA dataset under single-task setting:
python train_plms_glue.py --language_model_name roberta-base --dataset_name cola --learning_rate 1e-5 --num_runs 5
- Example of fine-tuning roberta-base on CoLA and RTE datasets under multi-task setting:
python train_plms_glue.py --language_model_name roberta-base --dataset_name cola --multitask_training --auxiliary_dataset_name rte --learning_rate 1e-5 --num_runs 5
Scripts for Inference with DARE and Other Variants
- Example of direct inference on roberta-base (drop rate 0.0):
python inference_plms_glue.py --language_model_name roberta-base --weight_mask_rate 0.0
- Example of inference on roberta-base with DARE (drop rate 0.9):
python inference_plms_glue.py --language_model_name roberta-base --weight_mask_rate 0.9 --use_weight_rescale
- Example of inference on roberta-base with DropOnly (drop rate 0.9):
python inference_plms_glue.py --language_model_name roberta-base --weight_mask_rate 0.9
- Example of inference on roberta-base with magnitude-based pruning (drop rate 0.9):
python inference_plms_glue.py --language_model_name roberta-base --weight_mask_rate 0.9 --mask_strategy magnitude
- Example of inference on roberta-base with masking fine-tuned parameters (drop rate 0.9):
python inference_plms_glue.py --language_model_name roberta-base --weight_mask_rate 0.9 --use_weight_rescale --weight_format finetuned_weight
Scripts for Merging Models
- Example of merging pairwise fine-tuned roberta-base with Average Merging:
python merge_plms_glue.py --merging_method_name average_merging --language_model_name roberta-base
- Example of merging pairwise fine-tuned roberta-base with Fisher Merging:
python merge_plms_glue.py --merging_method_name fisher_merging --normalize_fisher_weight --language_model_name roberta-base
- Example of merging pairwise fine-tuned roberta-base with Average Merging and DARE:
python merge_plms_glue.py --merging_method_name mask_merging --use_weight_rescale --language_model_name roberta-base --mask_apply_method average_merging
Executing Scripts for Decoder-based LMs
Since the decoder-based LMs we use have already been fine-tuned, they can be directly utilized for inference. We also provide scripts to merge decoder-based LMs with two model merging methods (Average Merging and Task Arithmetic).
Scripts for Inference with DARE and Other Variants
- Example of direct inference on WizardMath-7B-V1.0 on GSM8K (drop rate 0.0):
python inference_llms_instruct_math_code.py --dataset_name gsm8k --finetuned_model_name WizardMath-7B-V1.0 --tensor_parallel_size 1 --weight_mask_rate 0.0
- Example of inference on WizardMath-7B-V1.0 on GSM8K with DARE (drop rate 0.9):
python inference_llms_instruct_math_code.py --dataset_name gsm8k --finetuned_model_name WizardMath-7B-V1.0 --tensor_parallel_size 1 --weight_mask_rate 0.9 --use_weight_rescale
- Example of inference on WizardMath-7B-V1.0 on GSM8K with DropOnly (drop rate 0.9):
python inference_llms_instruct_math_code.py --dataset_name gsm8k --finetuned_model_name WizardMath-7B-V1.0 --tensor_parallel_size 1 --weight_mask_rate 0.9
- Example of inference on WizardMath-7B-V1.0 on GSM8K with magnitude-based pruning (drop rate 0.9):
python inference_llms_instruct_math_code.py --dataset_name gsm8k --finetuned_model_name WizardMath-7B-V1.0 --tensor_parallel_size 1 --weight_mask_rate 0.9 --mask_strategy magnitude
- Example of inference on WizardMath-7B-V1.0 on GSM8K with masking fine-tuned parameters (drop rate 0.9):
python inference_llms_instruct_math_code.py --dataset_name gsm8k --finetuned_model_name WizardMath-7B-V1.0 --tensor_parallel_size 1 --weight_mask_rate 0.9 --use_weight_rescale --weight_format finetuned_weight
Scripts for Merging Models
- Example of merging WizardLM-13B-V1.2 and WizardMath-13B-V1.0 with Average Merging:
python merge_llms_instruct_math_code.py --merge_instruct --merge_math --merging_method_name average_merging --tensor_parallel_size 1
- Example of merging WizardLM-13B-V1.2 and WizardMath-13B-V1.0 with Task Arithmetic:
python merge_llms_instruct_math_code.py --merge_instruct --merge_math --merging_method_name task_arithmetic --scaling_coefficient 1.0 --tensor_parallel_size 1
- Example of merging WizardLM-13B-V1.2 and WizardMath-13B-V1.0 with Average Merging and DARE (drop rate 0.2):
python merge_llms_instruct_math_code.py --merge_instruct --merge_math --merging_method_name mask_merging --use_weight_rescale --weight_mask_rate 0.2 --mask_apply_method average_merging --tensor_parallel_size 1
❗Note 1: When merging decoder-based LMs, the number of GPUs we should allocate is equals to num_models_to_merge * tensor_parallel_size. For example, if we want to merge WizardLM-13B-V1.2 and WizardMath-13B-V1.0 with tensor_parallel_size == 1, then we should allocate 2 * 1 = 2 GPUs.
❗Note 2: If "AssertionError: data parallel group is already initialized" error is raised by vllm on your device, please try to run direct_inference_merged_llms_instruct_math_code.py with the corresponding setting.
For example, if this error occurs when merging WizardLM-13B-V1.2 and WizardMath-13B-V1.0 with Average Merging and DARE (drop rate 0.2), please run the following command to evaluate on instruct- or math-related task
python direct_inference_merged_llms_instruct_math_code.py --merge_instruct --merge_math --merging_method_name mask_merging --use_weight_rescale --weight_mask_rate 0.2 --mask_apply_method average_merging --tensor_parallel_size 1 --evaluate_task instruct
python direct_inference_merged_llms_instruct_math_code.py --merge_instruct --merge_math --merging_method_name mask_merging --use_weight_rescale --weight_mask_rate 0.2 --mask_apply_method average_merging --tensor_parallel_size 1 --evaluate_task math
Evaluation Process for AlpacaEval, HumanEval and MBPP
For AlpacaEval, HumanEval and MBPP, our codes will store the generated files and please additionally run the following evaluation commands to get the final metrics.
- For AlpacaEval:
We use
chatgpt_fnin alpaca_eval repository to compute the win rate. Firstly, please see alpaca_eval repository to install the environment. Then, if you want to evaluate the generated WizardLM-13B-V1.2_inference_mask_0.2_rescale_True.json file, please run
alpaca_eval --model_outputs ./save_gen_instruct_responses_results/alpaca_eval/WizardLM-13B-V1.2_inference_mask_0.2_rescale_True.json --annotators_config chatgpt_fn --name WizardLM-13B-V1.2_inference_mask_0.2_rescale_True
- For HumanEval: Firstly, please see human-eval repository to install the environment. Then, if you want to evaluate the generated WizardCoder-Python-13B-V1.0_inference_mask_0.2_rescale_True.jsonl file, please run
evaluate_functional_correctness ./save_gen_codes_results/human_eval/WizardCoder-Python-13B-V1.0_inference_mask_0.2_rescale_True.jsonl
- For MBPP: Firstly, please see bigcode-evaluation-harness repository to install the environment. Then, if you want to evaluate the generated WizardCoder-Python-13B-V1.0_inference_mask_0.2_rescale_True.jsonl file, please run
accelerate launch ./bigcode-evaluation-harness/main.py --tasks mbpp --allow_code_execution --load_generations_path ./save_gen_codes_results/mbpp/WizardCoder-Python-13B-V1.0_inference_mask_0.2_rescale_True.jsonl
Acknowledgments
We are grateful to the authors of WizardLM for making their project codes publicly available.
Citation
Please consider citing our paper when using this project.
@inproceedings{yu2024language,
  title={Language Models are Super Mario: Absorbing Abilities from Homologous Models as a Free Lunch},
  author={Yu, Le and Yu, Bowen and Yu, Haiyang and Huang, Fei and Li, Yongbin},
  booktitle={International Conference on Machine Learning},
  year={2024},
  organization={PMLR}
}