AOT Series Frameworks in PyTorch
News
2024/03: AOST - AOST, the journal extension of AOT, has been accepted by TPAMI. AOST is the first scalable VOS framework supporting run-time speed-accuracy trade-offs, from real-time efficiency to SOTA performance.2023/07: Pyramid/Panoptic AOT - The code of PAOT has been released in paot branch of this repository. We propose a benchmark VIPOSeg for panoptic VOS, and PAOT is designed to tackle the challenges in panoptic VOS and achieves SOTA performance. PAOT consists of a multi-scale architecture of LSTT (same as MS-AOT in VOT2022) and panoptic ID banks for thing and stuff. Please refer to the paper for more details.2023/07: WINNER - DeAOT-based Tracker ranked 1st in the VOTS 2023 challenge (leaderboard). In detail, our DMAOT improves DeAOT by storing object-wise long-term memories instead of frame-wise long-term memories. This avoids the memory growth problem when processing long video sequences and produces better results when handling multiple objects.2023/06: WINNER - DeAOT-based Tracker ranked 1st in two tracks of EPIC-Kitchens challenges (leaderboard). In detail, our MS-DeAOT is a multi-scale version of DeAOT and is the winner of Semi-Supervised Video Object Segmentation (segmentation-based tracking) and TREK-150 Object Tracking (BBox-based tracking). Technical reports are coming soon.2023/04: SAM-Track - We are pleased to announce the release of our latest project, Segment and Track Anything (SAM-Track). This innovative project merges two kinds of models, SAM and our DeAOT, to achieve seamless segmentation and efficient tracking of any objects in videos.2022/10: WINNER - AOT-based Tracker ranked 1st in four tracks of the VOT 2022 challenge (presentation of results). In detail, our MS-AOT is the winner of two segmentation tracks, VOT-STs2022 and VOT-RTs2022 (real-time). In addition, the bounding box results of MS-AOT (initialized by AlphaRef, and output is bounding box fitted to mask prediction) surpass the winners of two bounding box tracks, VOT-STb2022 and VOT-RTb2022 (real-time). The bounding box results were required by the organizers after the competition deadline but were highlighted in the workshop presentation (ECCV 2022).
Intro
A modular reference PyTorch implementation of AOT series frameworks:
-
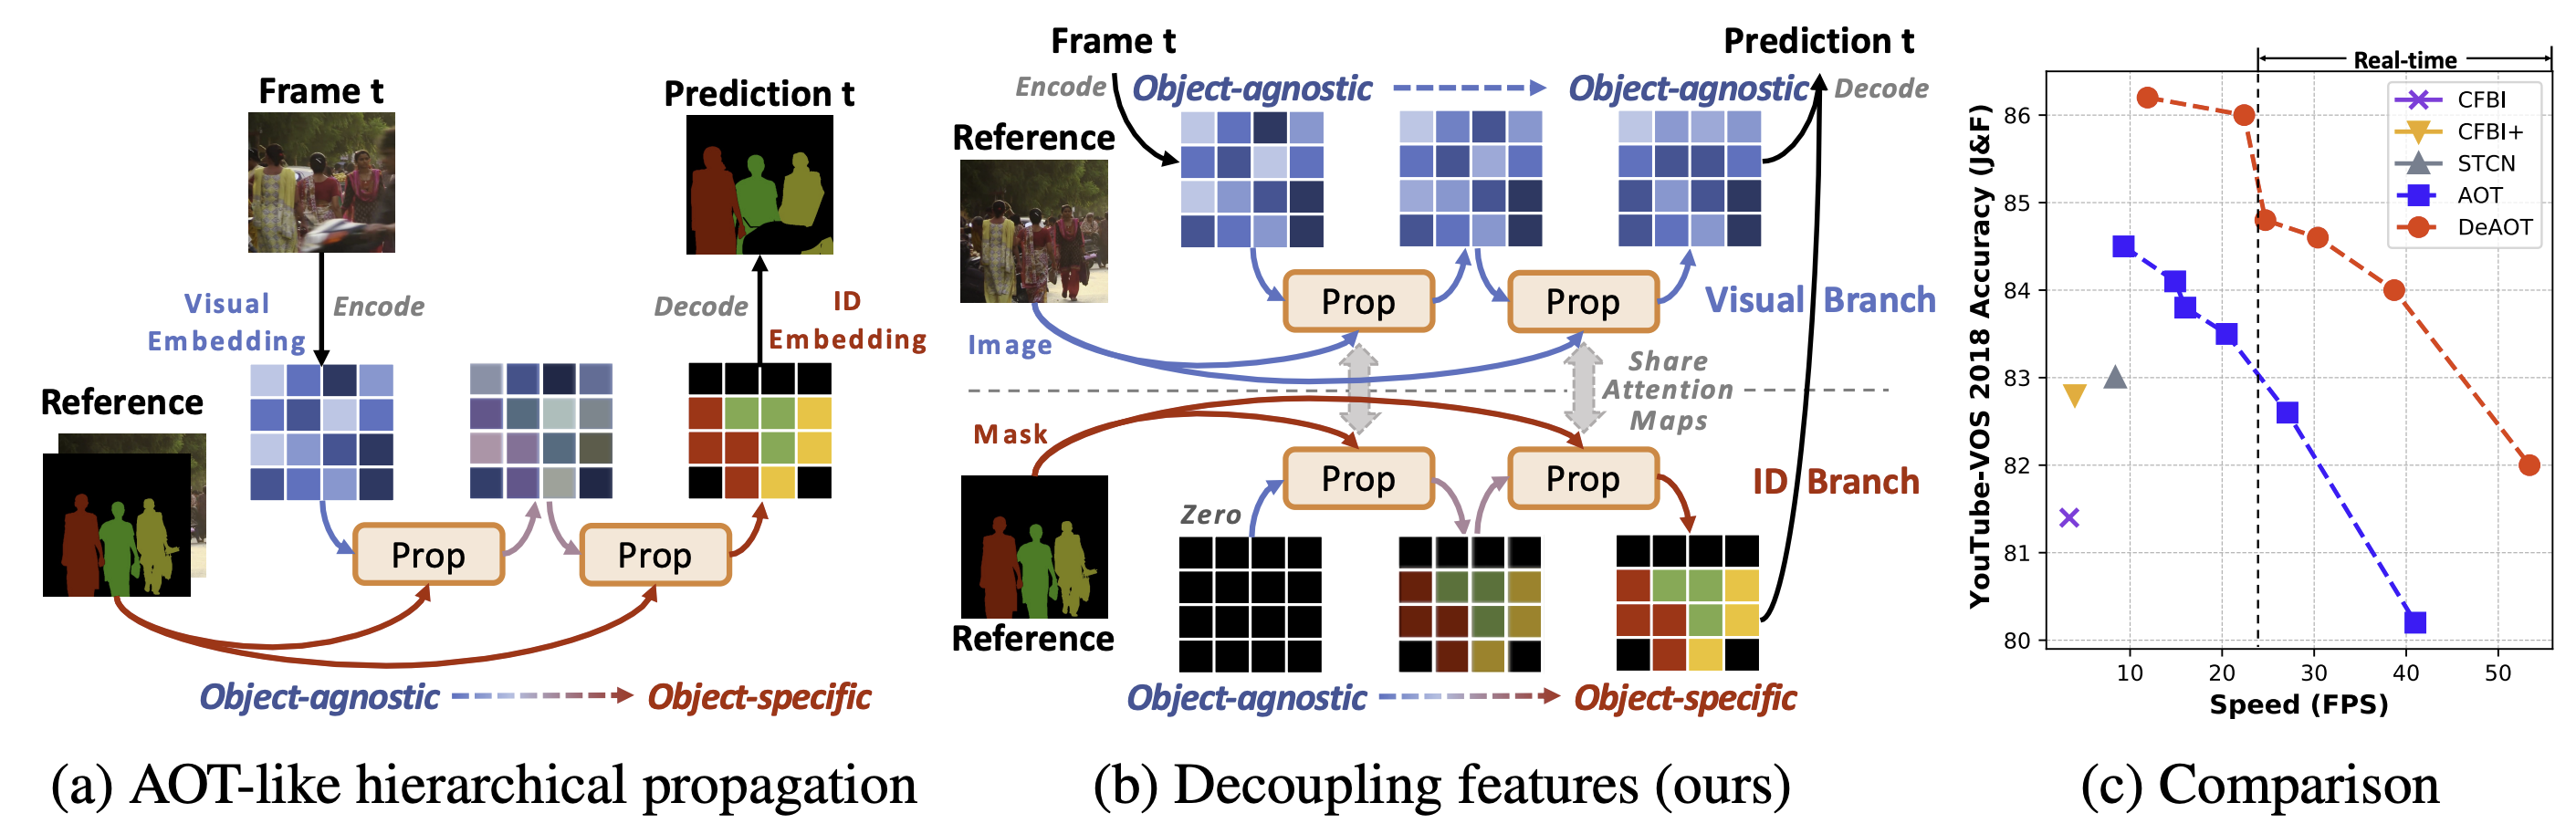
DeAOT: Decoupling Features in Hierarchical Propagation for Video Object Segmentation (NeurIPS 2022, Spotlight) [OpenReview][PDF]
-
AOT: Associating Objects with Transformers for Video Object Segmentation (NeurIPS 2021, Score 8/8/7/8) [OpenReview][PDF]
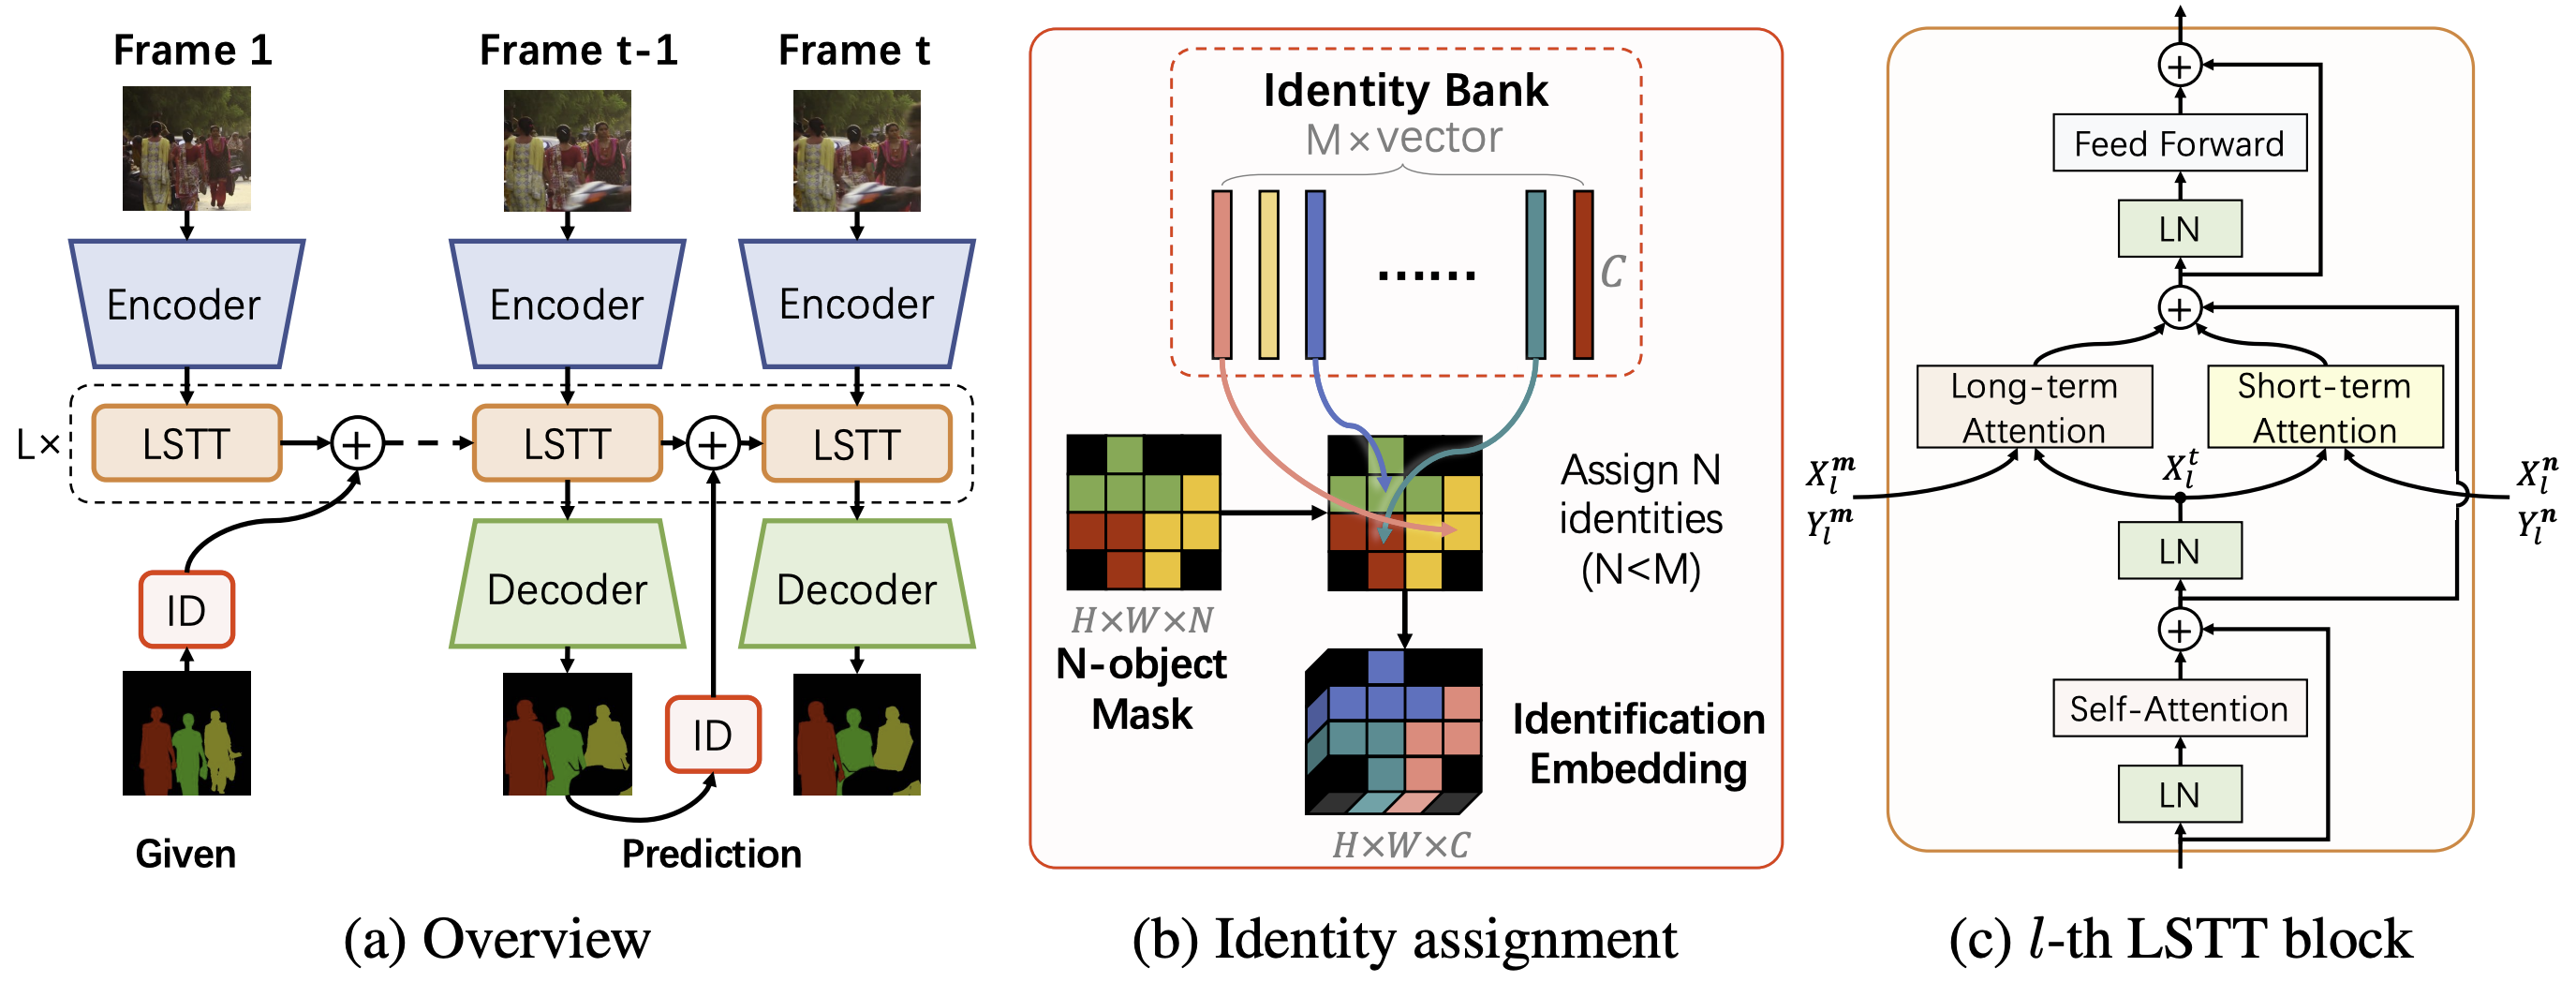
An extension of AOT, AOST (under review), is available now. AOST is a more robust and flexible framework, supporting run-time speed-accuracy trade-offs.
Examples
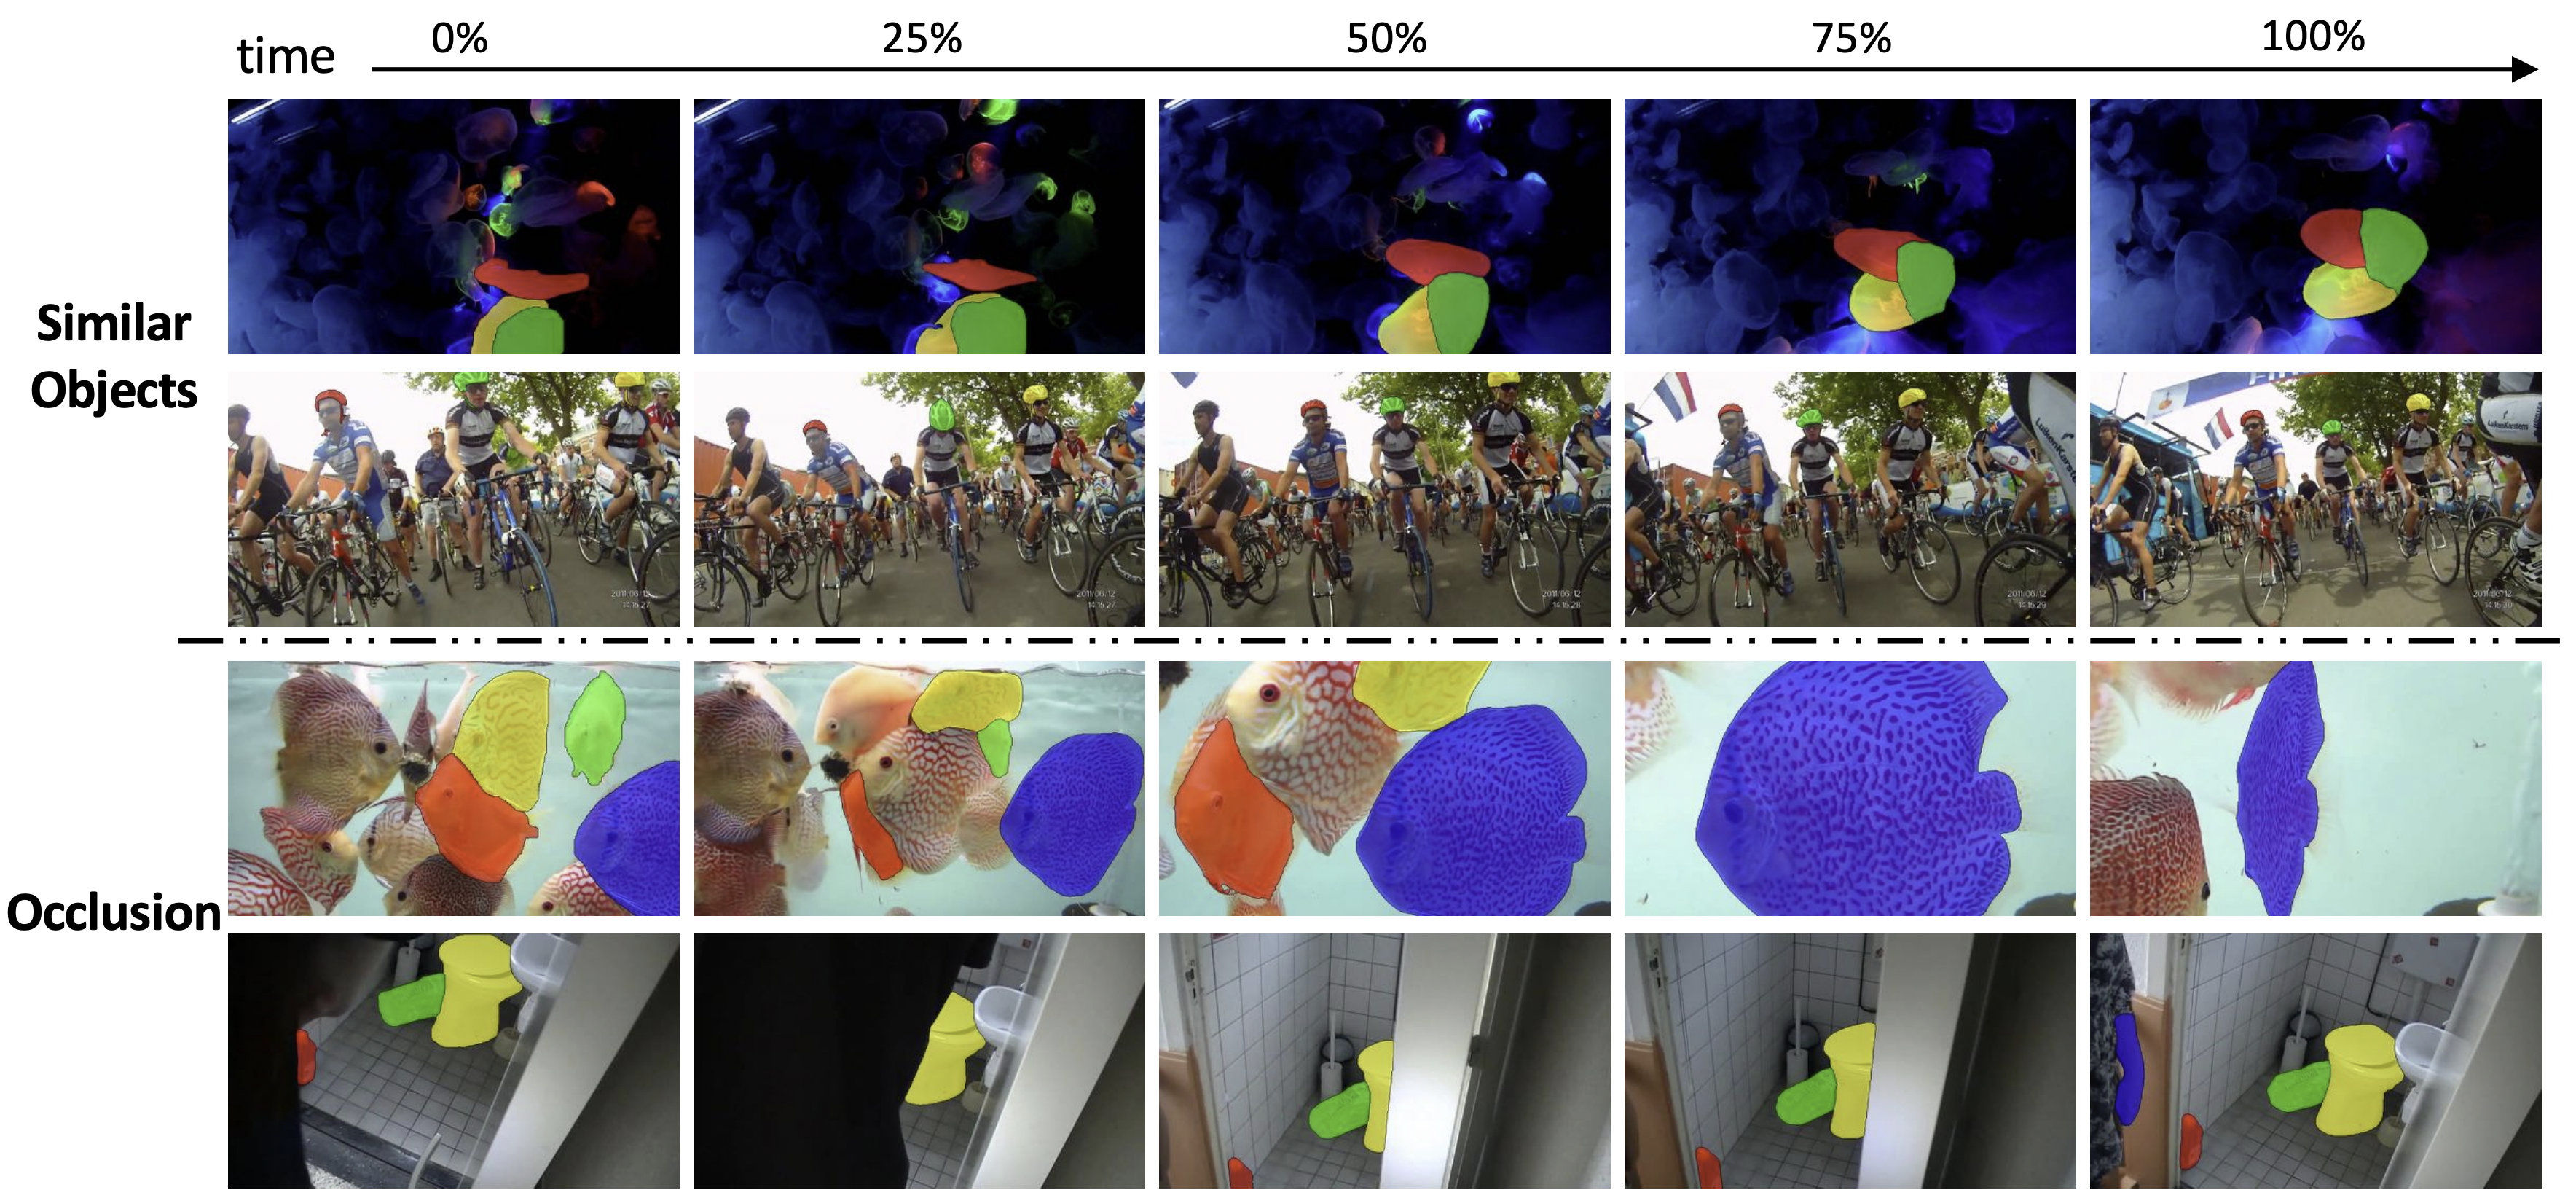
Benchmark examples:
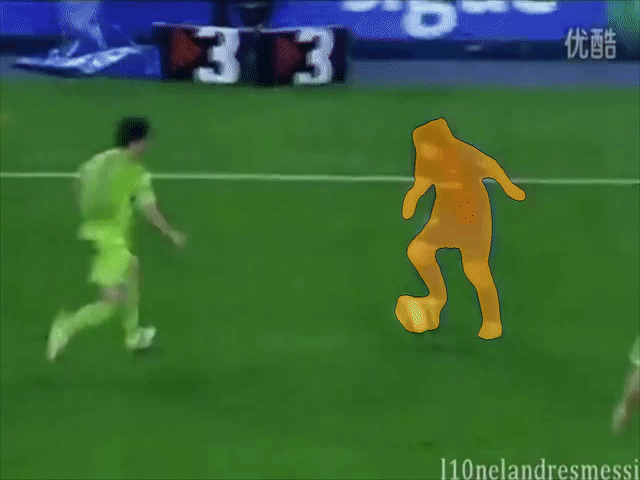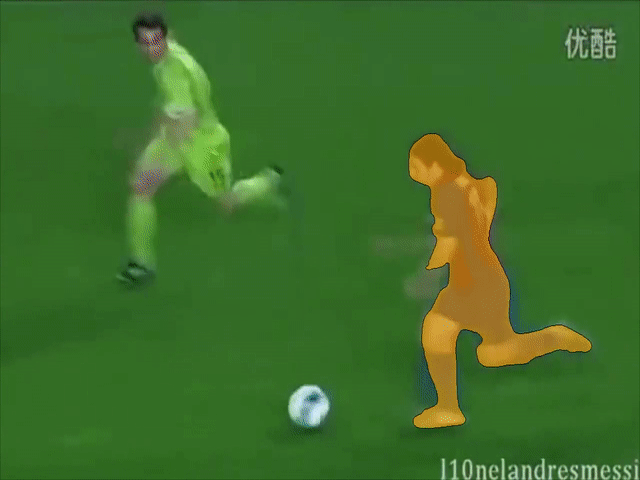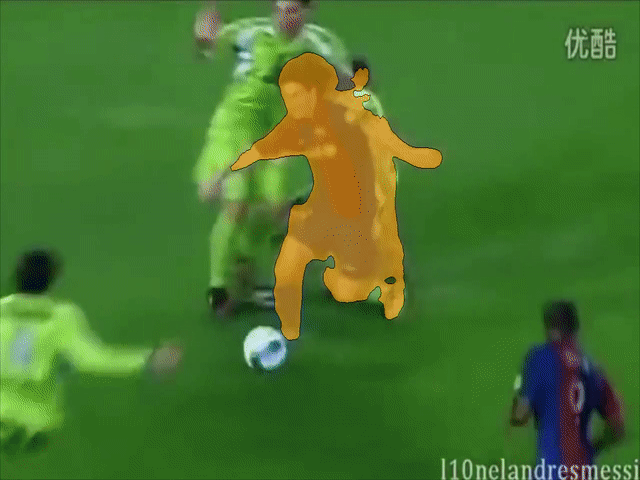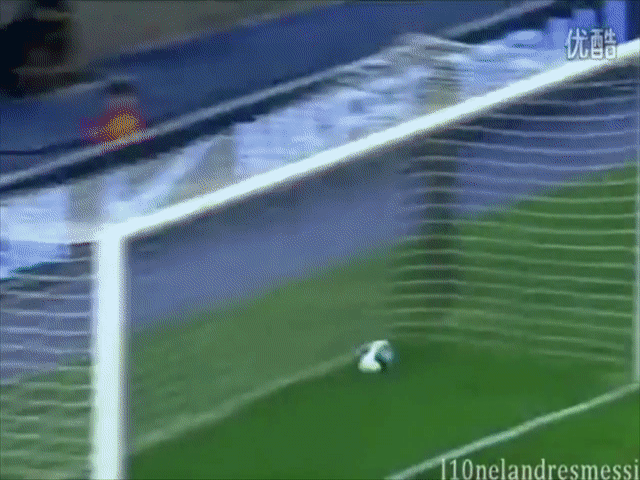
General examples (Messi and Kobe):
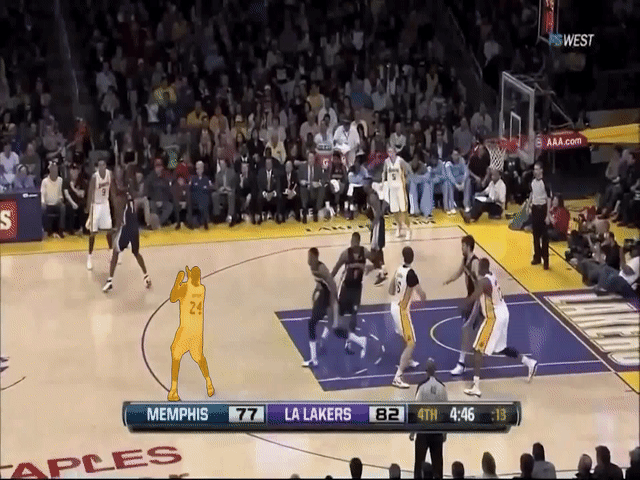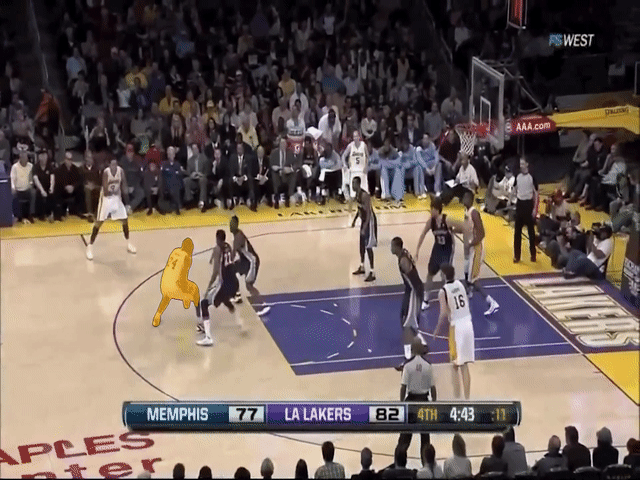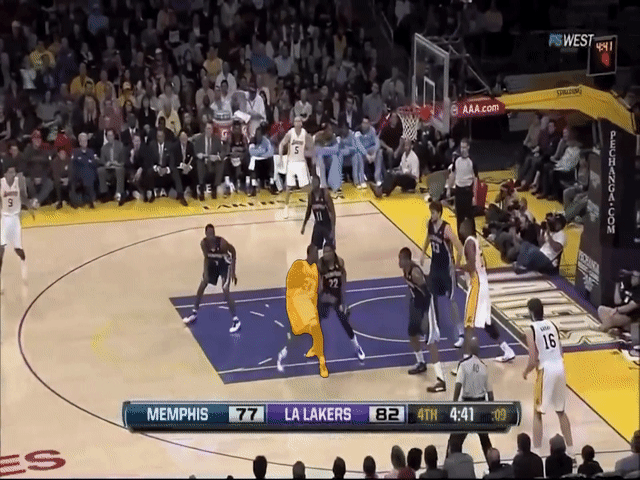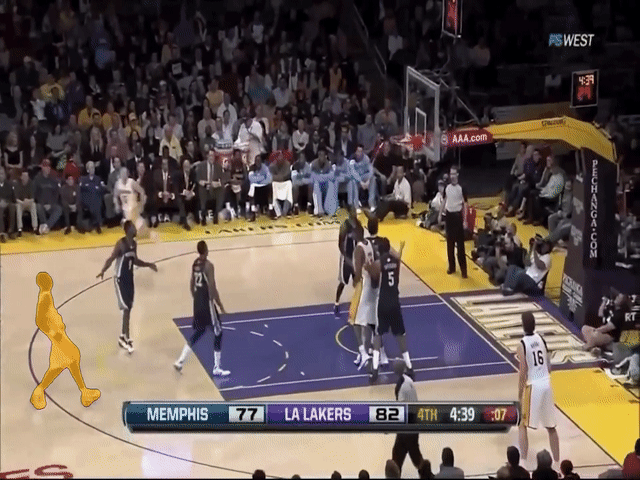
Highlights
- High performance: up to 85.5% (R50-AOTL) on YouTube-VOS 2018 and 82.1% (SwinB-AOTL) on DAVIS-2017 Test-dev under standard settings (without any test-time augmentation and post processing).
- High efficiency: up to 51fps (AOTT) on DAVIS-2017 (480p) even with 10 objects and 41fps on YouTube-VOS (1.3x480p). AOT can process multiple objects (less than a pre-defined number, 10 is the default) as efficiently as processing a single object. This project also supports inferring any number of objects together within a video by automatic separation and aggregation.
- Multi-GPU training and inference
- Mixed precision training and inference
- Test-time augmentation: multi-scale and flipping augmentations are supported.
Requirements
- Python3
- pytorch >= 1.7.0 and torchvision
- opencv-python
- Pillow
- Pytorch Correlation. Recommend to install from source:
git clone https://github.com/ClementPinard/Pytorch-Correlation-extension.git
cd Pytorch-Correlation-extension
pip install .
cd ..
Optional:
- scikit-image (if you want to run our Demo, please install)
Model Zoo and Results
Pre-trained models, benckmark scores, and pre-computed results reproduced by this project can be found in MODEL_ZOO.md.
Demo - Panoptic Propagation
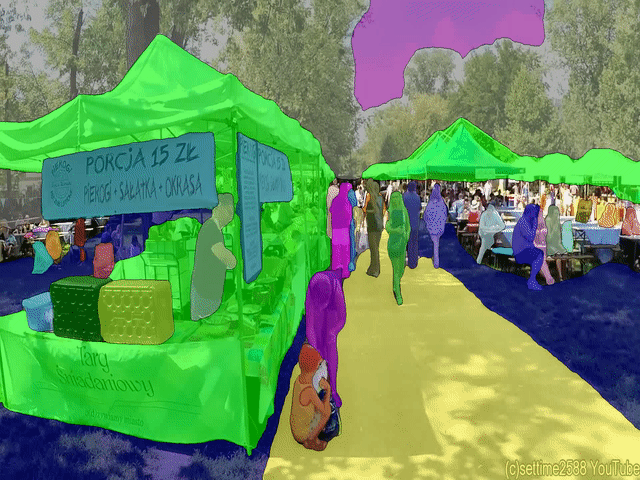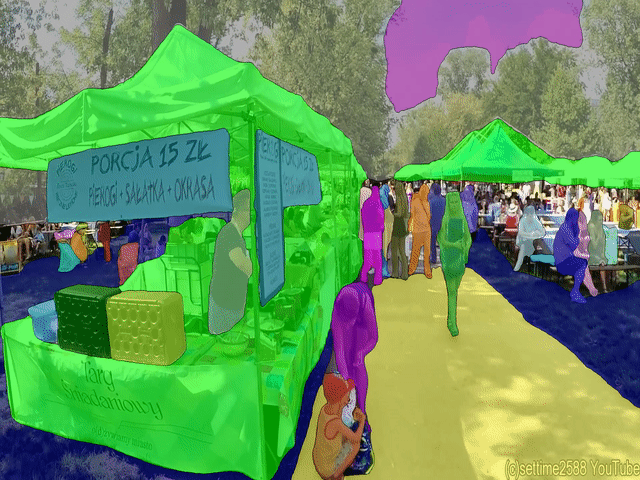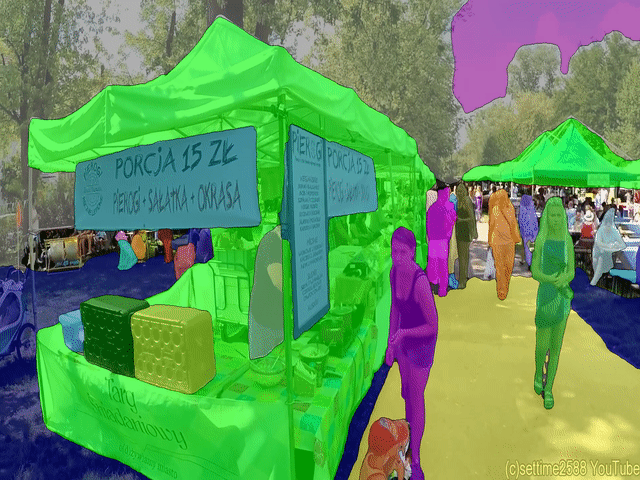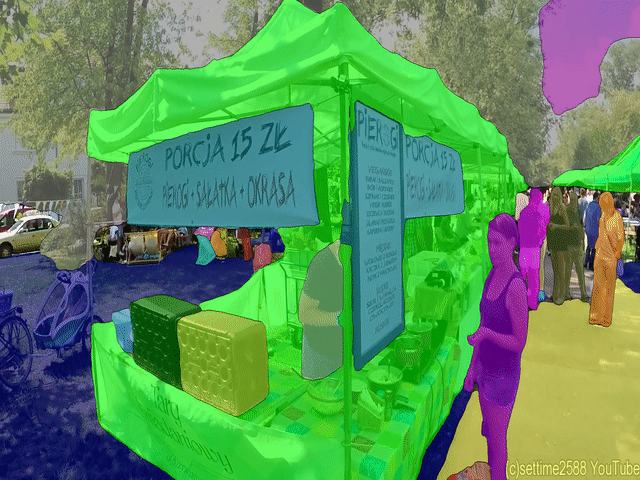
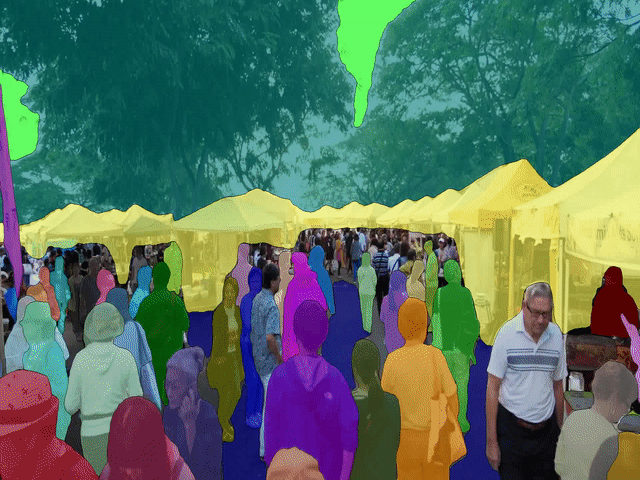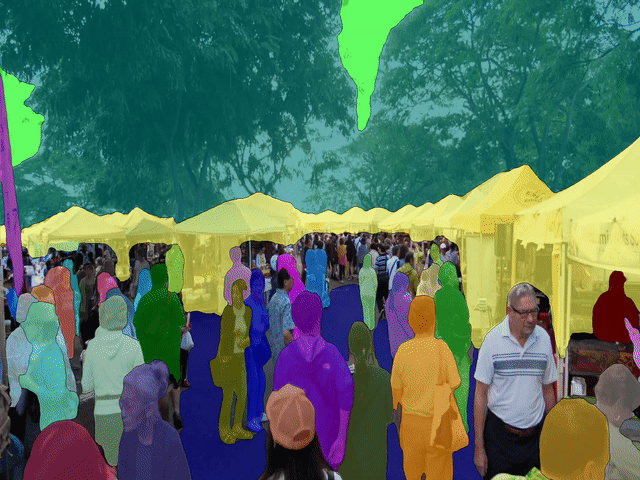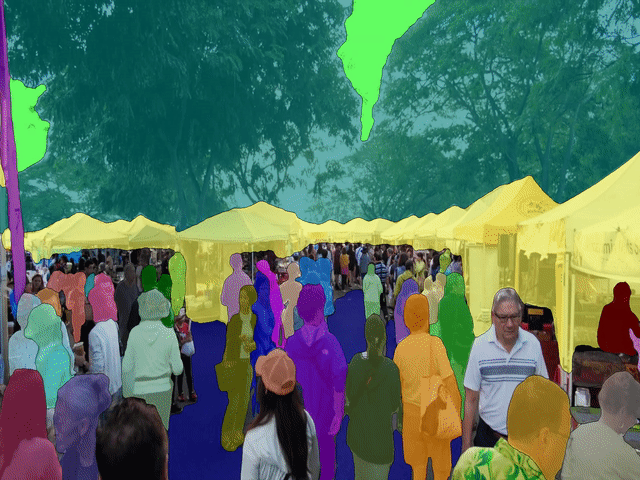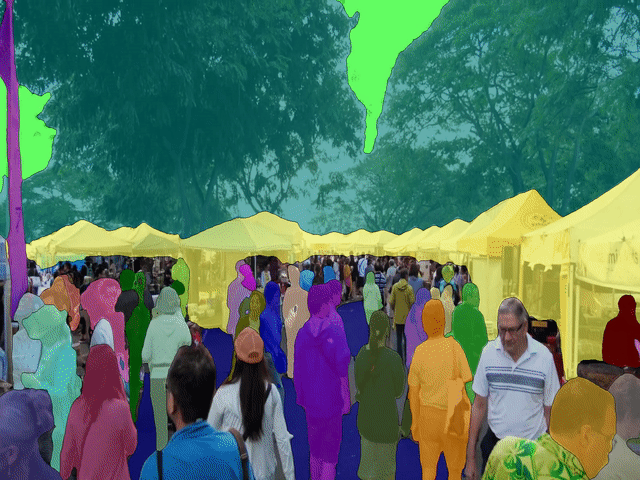
We provide a simple demo to demonstrate AOT's effectiveness. The demo will propagate more than 40 objects, including semantic regions (like sky) and instances (like person), together within a single complex scenario and predict its video panoptic segmentation.
To run the demo, download the checkpoint of R50-AOTL into pretrain_models, and then run:
python tools/demo.py
which will predict the given scenarios in the resolution of 1.3x480p. You can also run this demo with other AOTs (MODEL_ZOO.md) by setting --model (model type) and --ckpt_path (checkpoint path).
Two scenarios from VSPW are supplied in datasets/Demo:
- 1001_3iEIq5HBY1s: 44 objects. 1080P.
- 1007_YCTBBdbKSSg: 43 objects. 1080P.
Results:
Getting Started
-
Prepare a valid environment follow the requirements.
-
Prepare datasets:
Please follow the below instruction to prepare datasets in each corresponding folder.
-
Static
datasets/Static: pre-training dataset with static images. Guidance can be found in AFB-URR, which we referred to in the implementation of the pre-training.
-
YouTube-VOS
A commonly-used large-scale VOS dataset.
datasets/YTB/2019: version 2019, download link.
trainis required for training.valid(6fps) andvalid_all_frames(30fps, optional) are used for evaluation.datasets/YTB/2018: version 2018, download link. Only
valid(6fps) andvalid_all_frames(30fps, optional) are required for this project and used for evaluation. -
DAVIS
A commonly-used small-scale VOS dataset.
datasets/DAVIS: TrainVal (480p) contains both the training and validation split. Test-Dev (480p) contains the Test-dev split. The full-resolution version is also supported for training and evaluation but not required.
-
-
Prepare ImageNet pre-trained encoders
Select and download below checkpoints into pretrain_models:
- MobileNet-V2 (default encoder)
- MobileNet-V3
- ResNet-50
- ResNet-101
- ResNeSt-50
- ResNeSt-101
- Swin-Base
The current default training configs are not optimized for encoders larger than ResNet-50. If you want to use larger encoders, we recommend early stopping the main-training stage at 80,000 iterations (100,000 in default) to avoid over-fitting on the seen classes of YouTube-VOS.
-
Training and Evaluation
The example script will train AOTT with 2 stages using 4 GPUs and auto-mixed precision (
--amp). The first stage is a pre-training stage usingStaticdataset, and the second stage is a main-training stage, which uses bothYouTube-VOS 2019 trainandDAVIS-2017 trainfor training, resulting in a model that can generalize to different domains (YouTube-VOS and DAVIS) and different frame rates (6fps, 24fps, and 30fps).Notably, you can use only the
YouTube-VOS 2019 trainsplit in the second stage by changingpre_ytb_davtopre_ytb, which leads to better YouTube-VOS performance on unseen classes. Besides, if you don't want to do the first stage, you can start the training from stageytb, but the performance will drop about 1~2% absolutely.After the training is finished (about 0.6 days for each stage with 4 Tesla V100 GPUs), the example script will evaluate the model on YouTube-VOS and DAVIS, and the results will be packed into Zip files. For calculating scores, please use official YouTube-VOS servers (2018 server and 2019 server), official DAVIS toolkit (for Val), and official DAVIS server (for Test-dev).
Adding your own dataset
Coming
Troubleshooting
Waiting
TODO
- [ ] Code documentation
- [ ] Adding your own dataset
- [ ] Results with test-time augmentations in Model Zoo
- [ ] Support gradient accumulation
- [x] Demo tool
Citations
Please consider citing the related paper(s) in your publications if it helps your research.
@article{yang2021aost,
  title={Scalable Video Object Segmentation with Identification Mechanism},
  author={Yang, Zongxin and Miao, Jiaxu and Wei, Yunchao and Wang, Wenguan and Wang, Xiaohan and Yang, Yi},
  journal={TPAMI},
  year={2024}
}
@inproceedings{xu2023video,
  title={Video object segmentation in panoptic wild scenes},
  author={Xu, Yuanyou and Yang, Zongxin and Yang, Yi},
  booktitle={IJCAI},
  year={2023}
}
@inproceedings{yang2022deaot,
  title={Decoupling Features in Hierarchical Propagation for Video Object Segmentation},
  author={Yang, Zongxin and Yang, Yi},
  booktitle={Advances in Neural Information Processing Systems (NeurIPS)},
  year={2022}
}
@inproceedings{yang2021aot,
  title={Associating Objects with Transformers for Video Object Segmentation},
  author={Yang, Zongxin and Wei, Yunchao and Yang, Yi},
  booktitle={Advances in Neural Information Processing Systems (NeurIPS)},
  year={2021}
}
License
This project is released under the BSD-3-Clause license. See LICENSE for additional details.