English | 简体中文
Segment Any Point Cloud Sequences by Distilling Vision Foundation Models
[Youquan Liu](https://github.com/youquanl)1,*
[Lingdong Kong](https://ldkong.com)1,2,*
[Jun Cen](http://cen-jun.com)3
[Runnan Chen](https://scholar.google.com/citations?user=Uq2DuzkAAAAJ)4
[Wenwei Zhang](http://zhangwenwei.cn)1,5

[Liang Pan](https://scholar.google.com/citations?user=lSDISOcAAAAJ)5
[Kai Chen](http://chenkai.site)1
[Ziwei Liu](https://liuziwei7.github.io)5


1Shanghai AI Laboratory
2National University of Singapore
3The Hong Kong University of Science and Technology
4The University of Hong Kong
5S-Lab, Nanyang Technological University
Seal :seal:
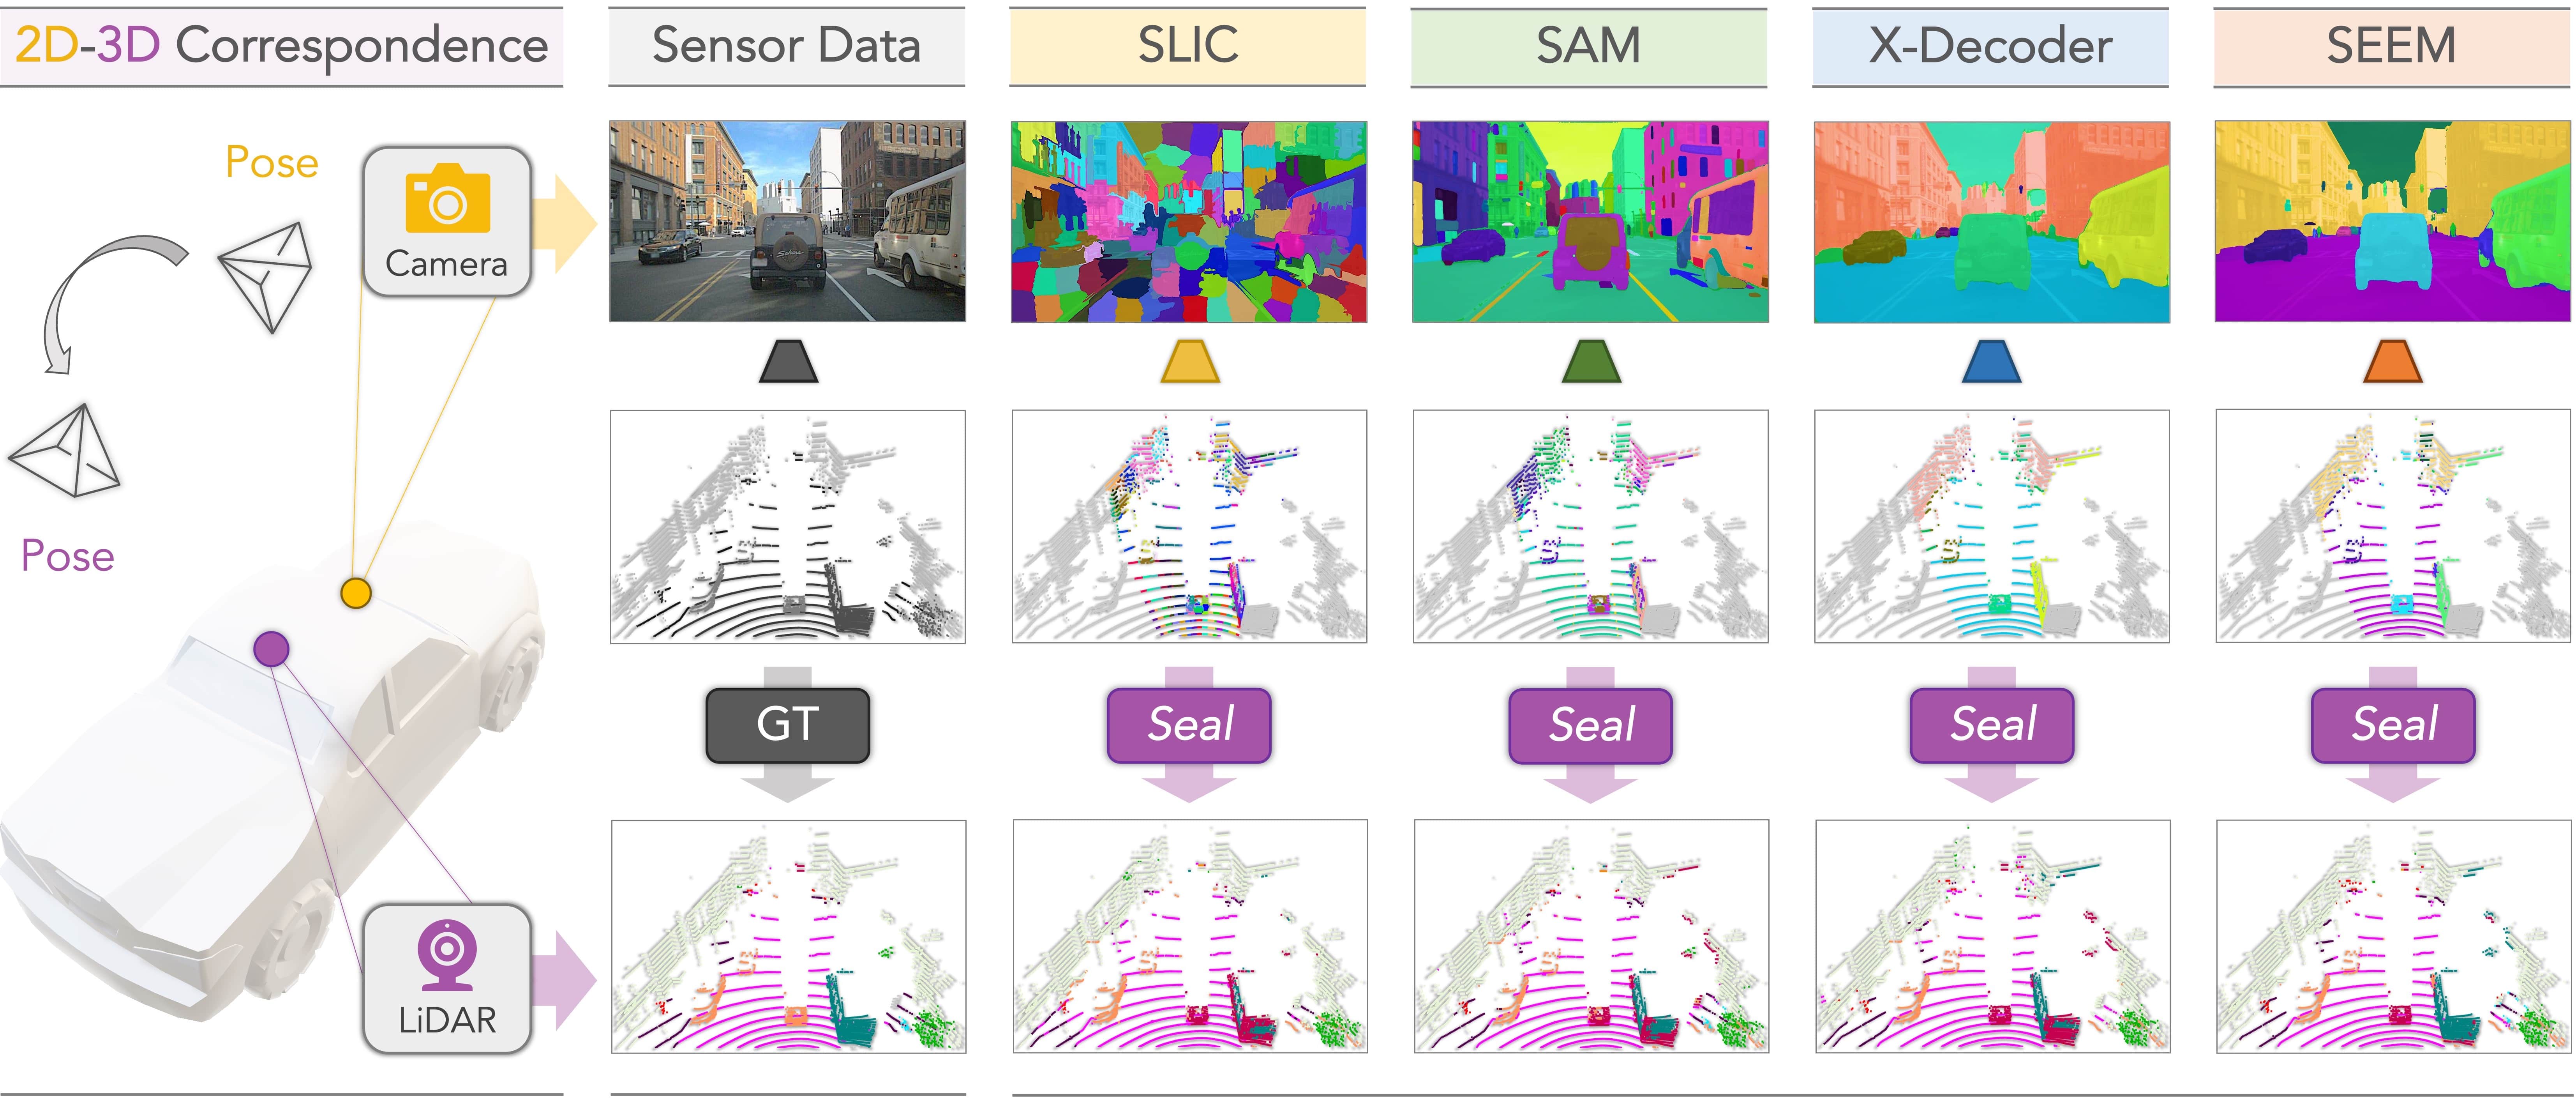
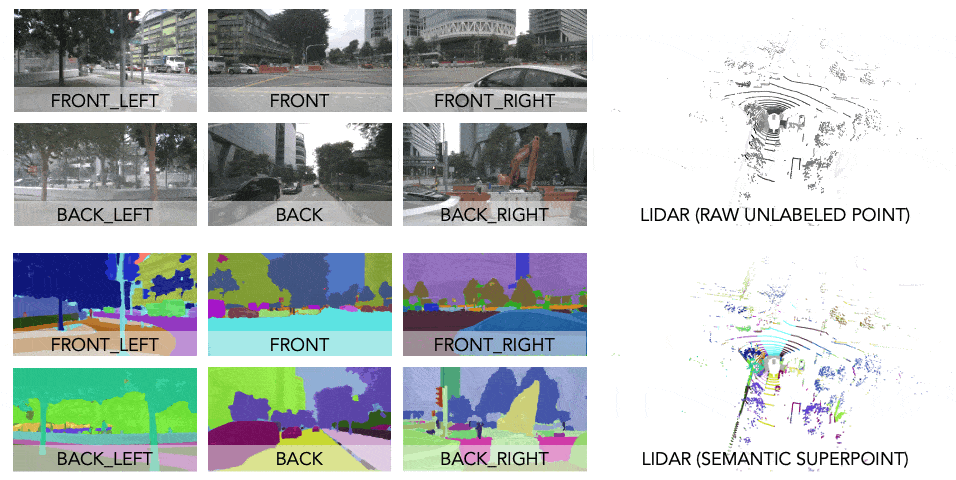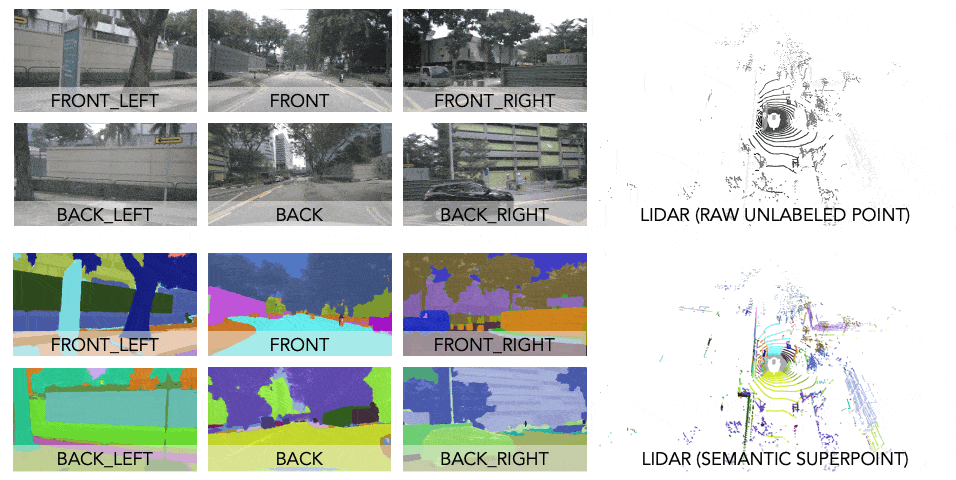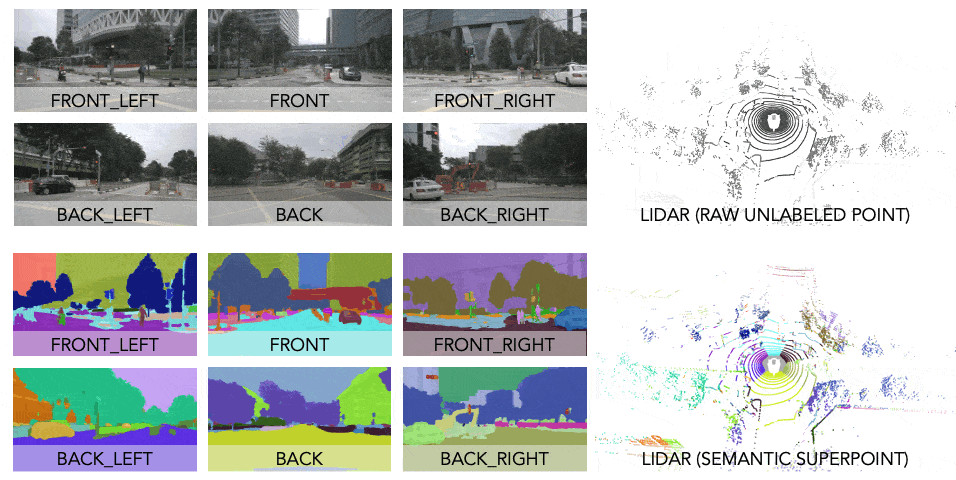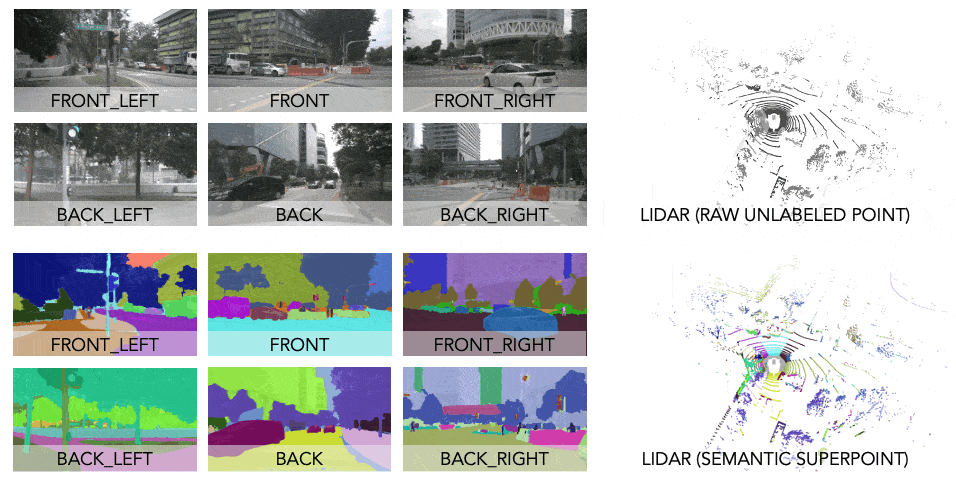
Seal is a versatile self-supervised learning framework capable of segmenting any automotive point clouds by leveraging off-the-shelf knowledge from vision foundation models (VFMs) and encouraging spatial and temporal consistency from such knowledge during the representation learning stage.
:sparkles: Highlight
- :rocket: Scalability:
Sealdirectly distills the knowledge from VFMs into point clouds, eliminating the need for annotations in either 2D or 3D during pretraining. - :balance_scale: Consistency:
Sealenforces the spatial and temporal relationships at both the camera-to-LiDAR and point-to-segment stages, facilitating cross-modal representation learning. - :rainbow: Generalizability:
Sealenables knowledge transfer in an off-the-shelf manner to downstream tasks involving diverse point clouds, including those from real/synthetic, low/high-resolution, large/small-scale, and clean/corrupted datasets.
:oncoming_automobile: 2D-3D Correspondence
:movie_camera: Video Demo
| Demo 1 | Demo 2 | Demo 3 |
|---|---|---|
 |
 |
 |
| Link :arrow_heading_up: | Link :arrow_heading_up: | Link :arrow_heading_up: |
Updates
- [2023.12] - We are hosting The RoboDrive Challenge at ICRA 2024. :blue_car:
- [2023.09] -
Sealwas selected as a :sparkles: spotlight :sparkles: at NeurIPS 2023. - [2023.09] -
Sealwas accepted to NeurIPS 2023! :tada: - [2023.07] - We release the code for generating semantic superpixel & superpoint by SLIC, SAM, and SEEM. More VFMs coming on the way!
- [2023.06] - Our paper is available on arXiv, click here to check it out. Code will be available later!
Outline
- Installation
- Data Preparation
- Superpoint Generation
- Getting Started
- Main Result
- TODO List
- License
- Acknowledgement
- Citation
Installation
Please refer to INSTALL.md for the installation details.
Data Preparation
| nuScenes | SemanticKITTI | Waymo Open | ScribbleKITTI |
|---|---|---|---|
 |
 |
 |
 |
| RELLIS-3D | SemanticPOSS | SemanticSTF | DAPS-3D |
 |
 |
 |
 |
| SynLiDAR | Synth4D | nuScenes-C | |
 |
 |
 |
Please refer to DATA_PREPARE.md for the details to prepare these datasets.
Superpoint Generation
| Raw Point Cloud | Semantic Superpoint | Groundtruth |
|---|---|---|
 |
 |
 |
 |
 |
 |
 |
 |
 |
 |
 |
 |
Kindly refer to SUPERPOINT.md for the details to generate the semantic superpixels & superpoints with vision foundation models.
Getting Started
Kindly refer to GET_STARTED.md to learn more usage of this codebase.
Main Result
:unicorn: Framework Overview
 |
|---|
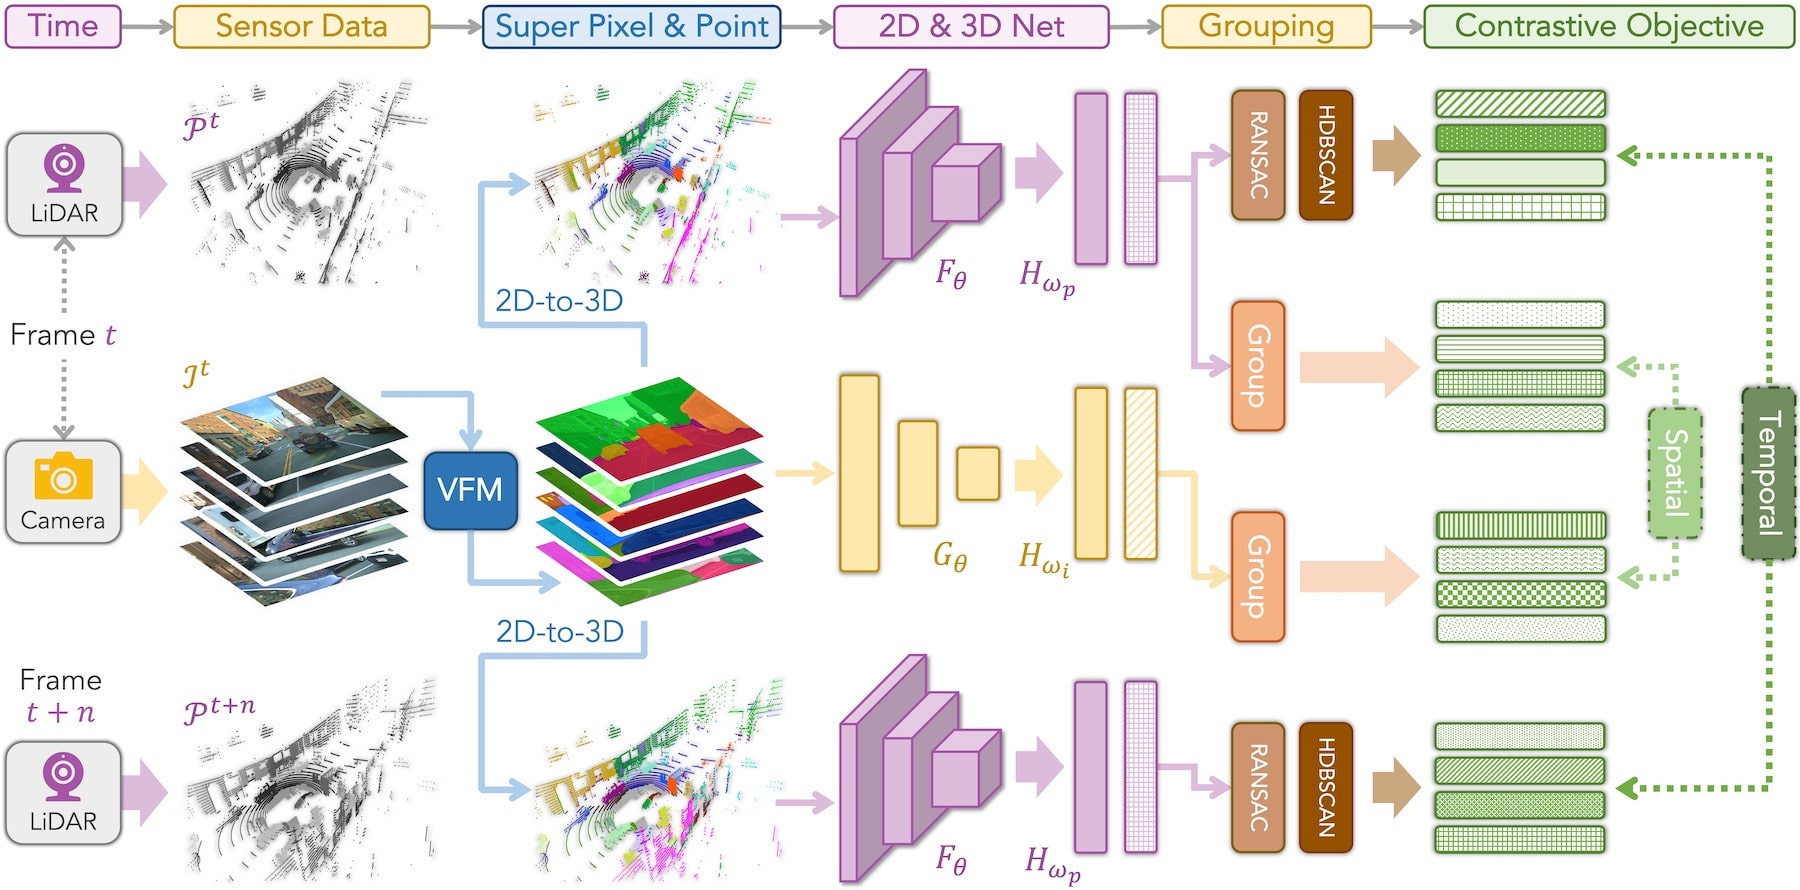
| Overview of the Seal :seal: framework. We generate, for each {LiDAR, camera} pair at timestamp t and another LiDAR frame at timestamp t + n, the semantic superpixel and superpoint by VFMs. Two pertaining objectives are then formed, including spatial contrastive learning between paired LiDAR and camera features and temporal consistency regularization between segments at different timestamps. |
:car: Cosine Similarity
 |
|---|
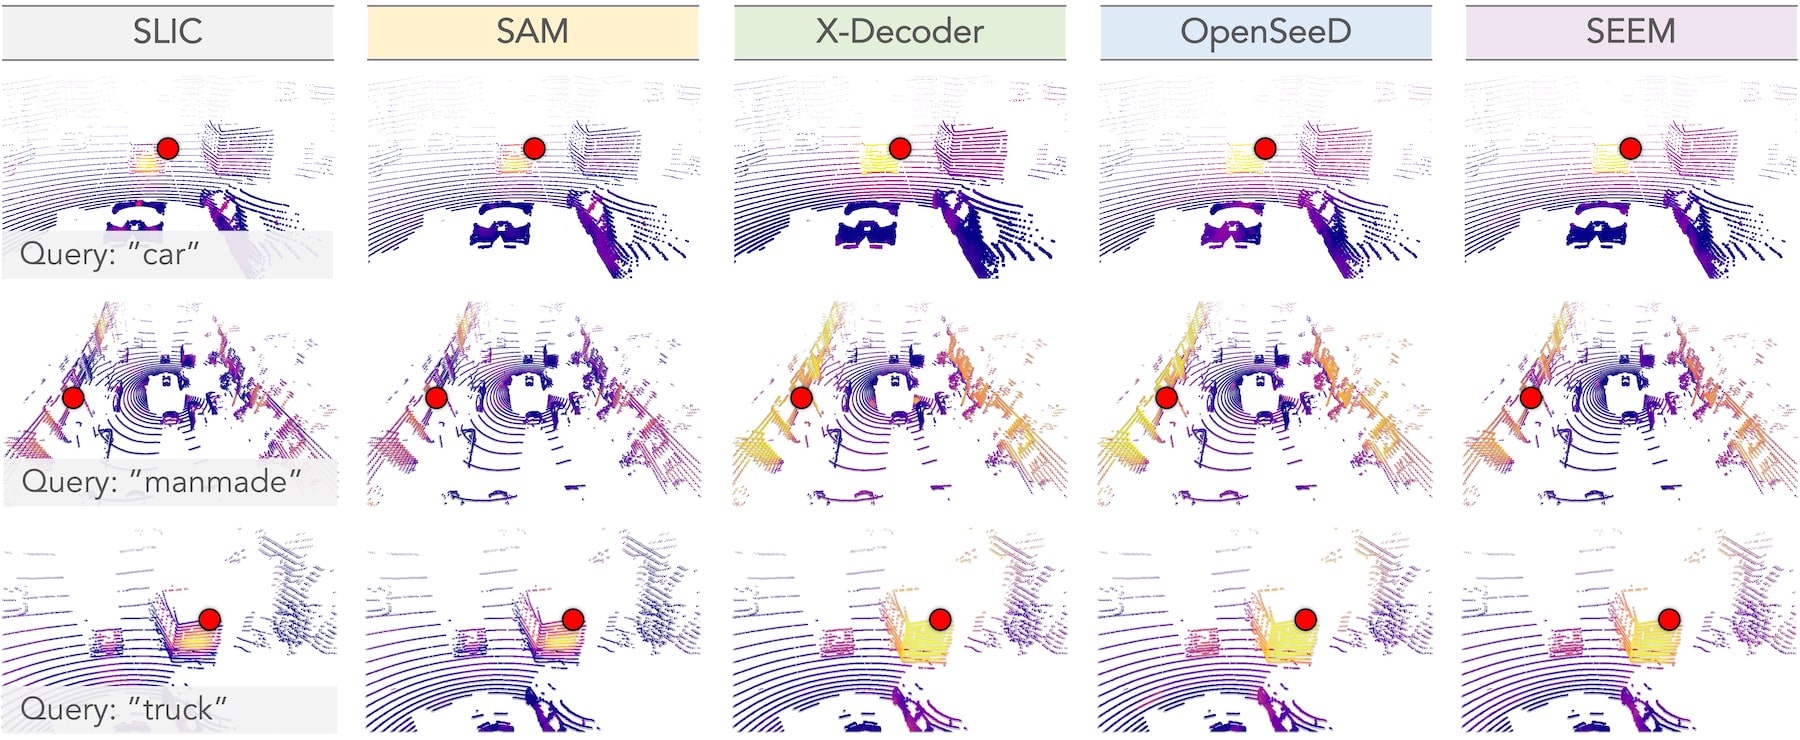
| The cosine similarity between a query point (red dot) and the feature learned with SLIC and different VFMs in our Seal :seal: framework. The queried semantic classes from top to bottom examples are: “car”, “manmade”, and “truck”. The color goes from violet to yellow denoting low and high similarity scores, respectively. |
:blue_car: Benchmark
Method
nuScenes
KITTI
Waymo
Synth4D
LP
1%
5%
10%
25%
Full
1%
1%
1%
Random
8.10
30.30
47.84
56.15
65.48
74.66
39.50
39.41
20.22
PointContrast
21.90
32.50
41.10
DepthContrast
22.10
31.70
41.50
PPKT
35.90
37.80
53.74
60.25
67.14
74.52
44.00
47.60
61.10
SLidR
38.80
38.30
52.49
59.84
66.91
74.79
44.60
47.12
63.10
ST-SLidR
40.48
40.75
54.69
60.75
67.70
75.14
44.72
44.93
Seal :seal:
44.95
45.84
55.64
62.97
68.41
75.60
46.63
49.34
64.50
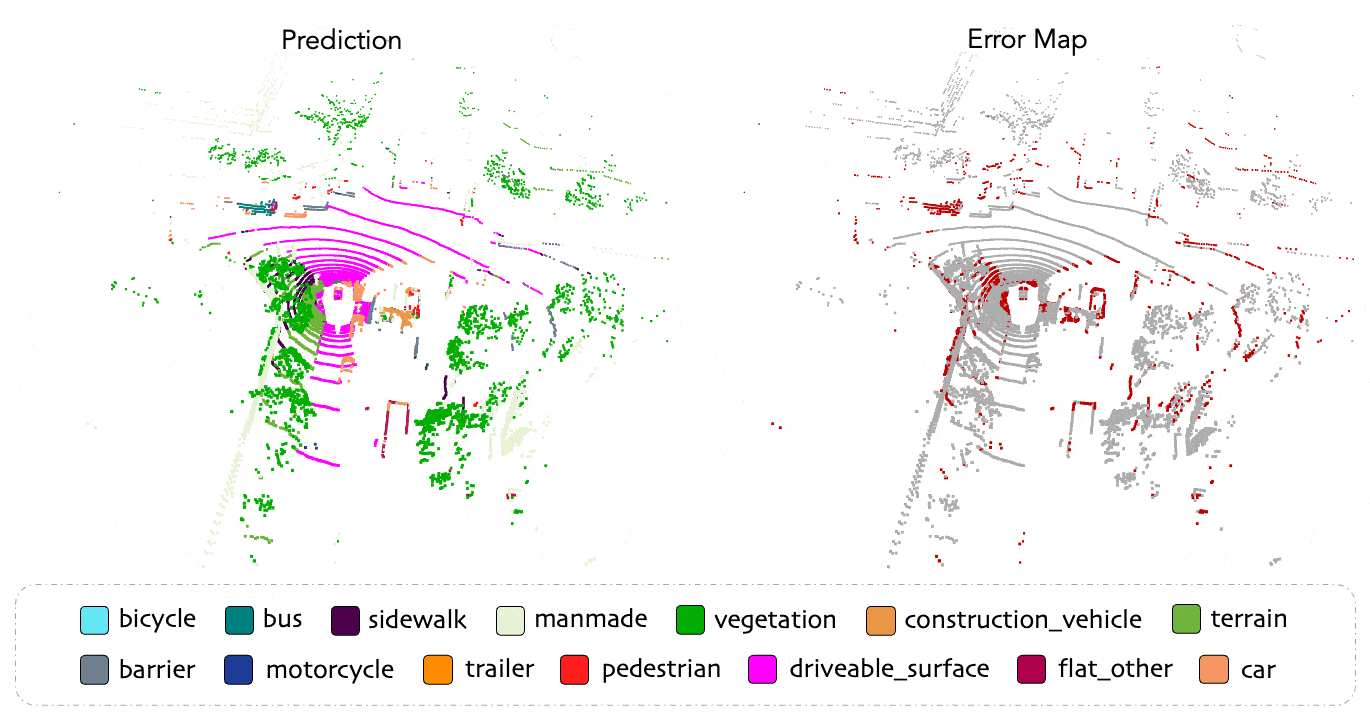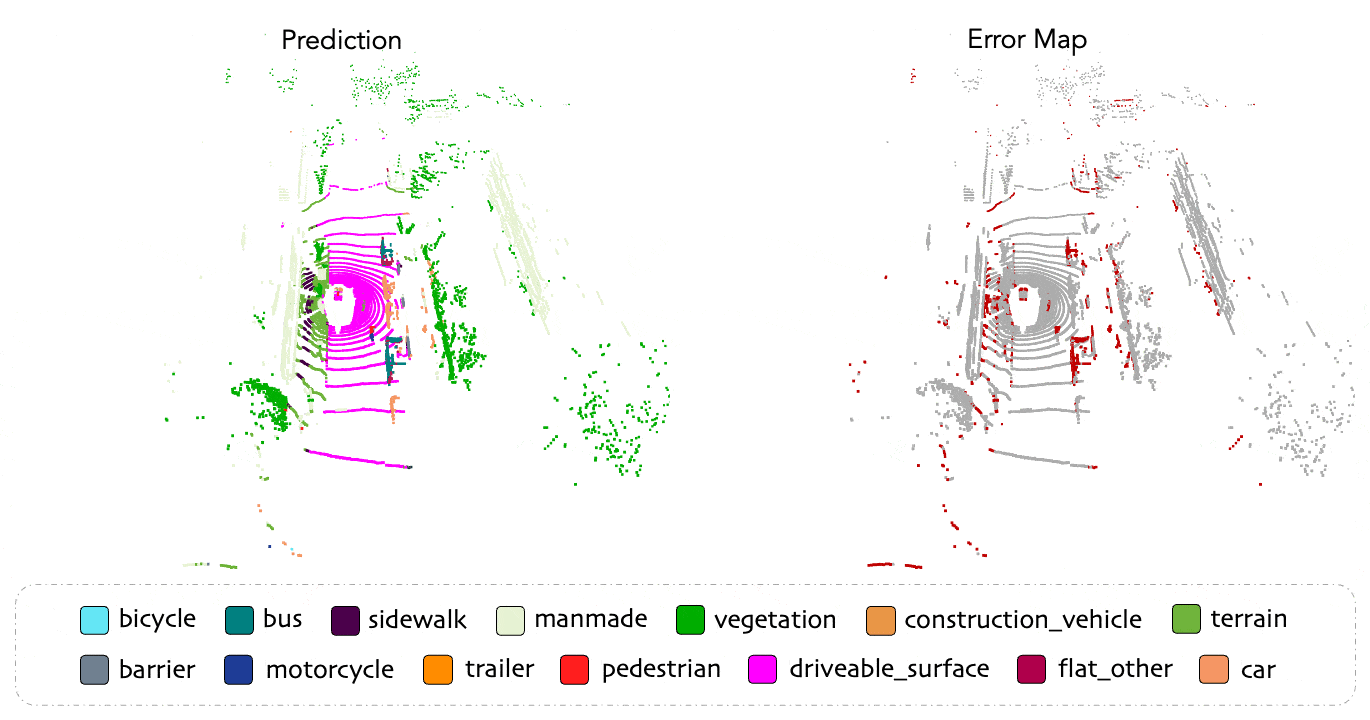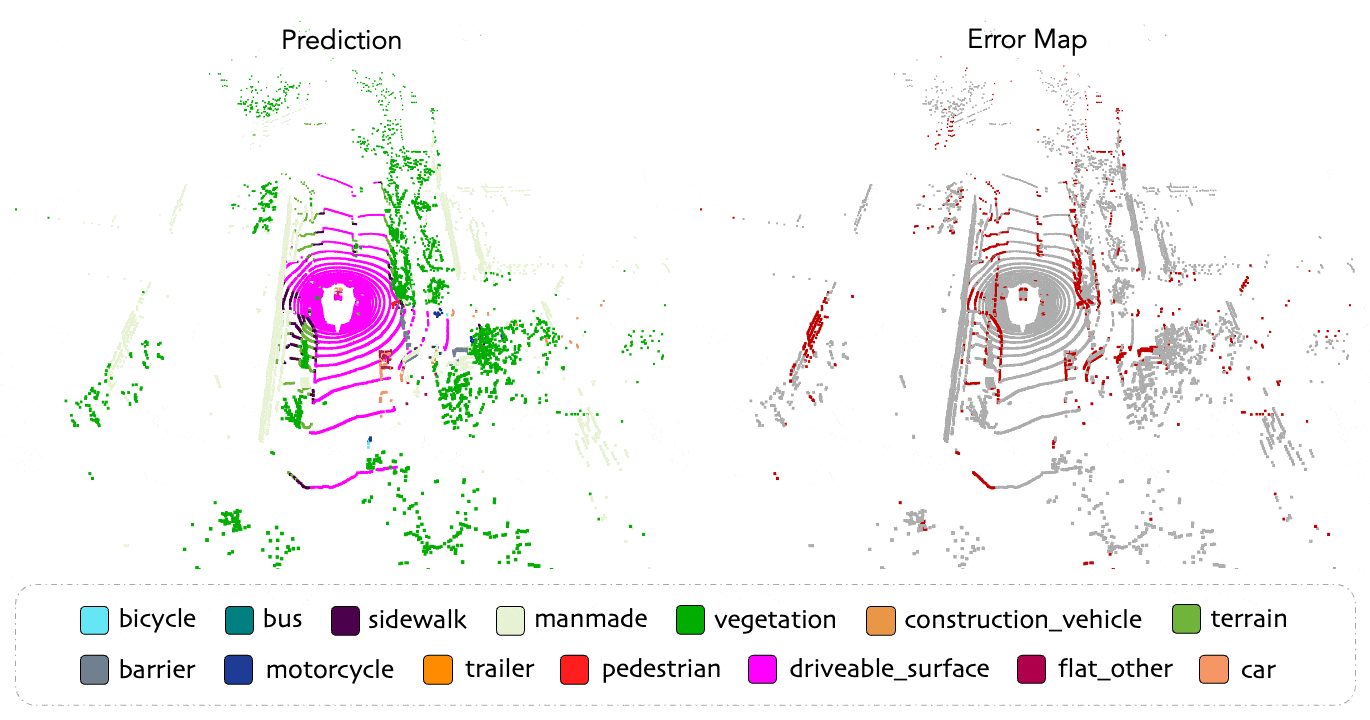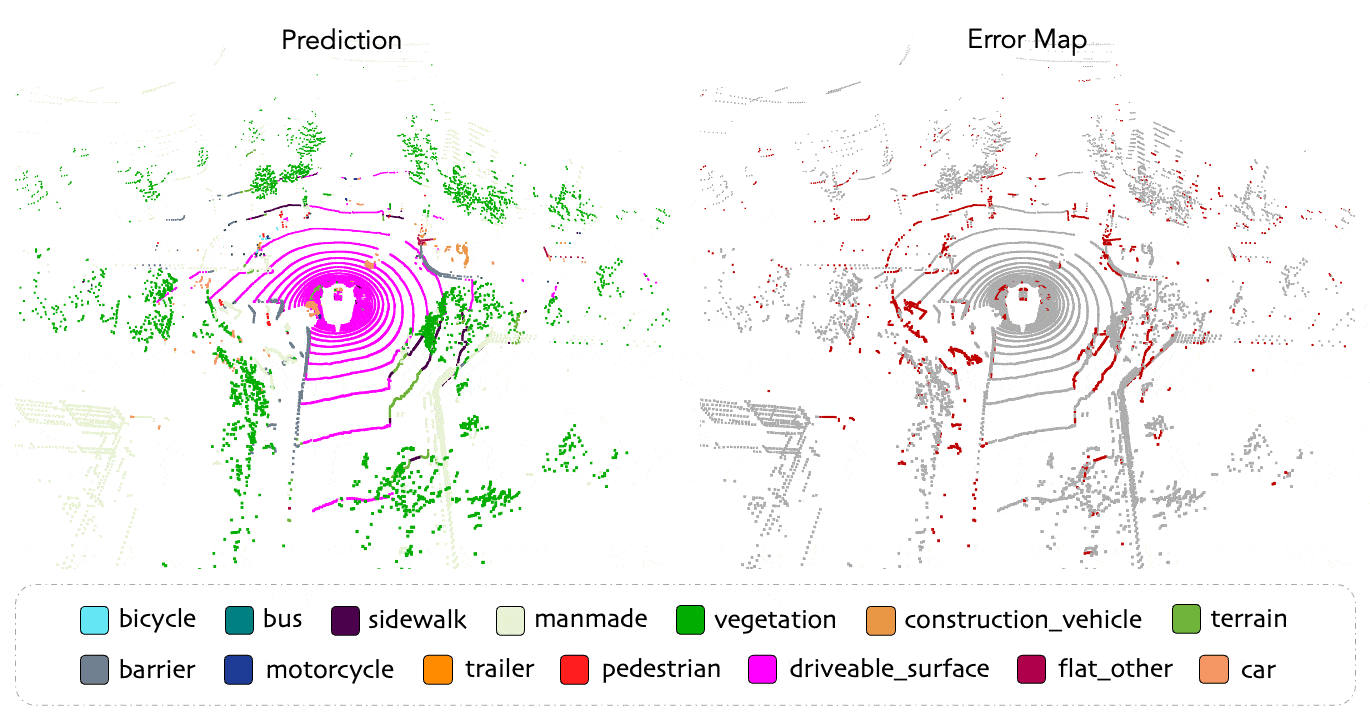
:bus: Linear Probing
 |
|---|
| The qualitative results of our Seal :seal: framework pretrained on nuScenes (without using groundtruth labels) and linear probed with a frozen backbone and a linear classification head. To highlight the differences, the correct / incorrect predictions are painted in gray / red, respectively. |
:articulated_lorry: Downstream Generalization
Method
ScribbleKITTI
RELLIS-3D
SemanticPOSS
SemanticSTF
SynLiDAR
DAPS-3D
1%
10%
1%
10%
Half
Full
Half
Full
1%
10%
Half
Full
Random
23.81
47.60
38.46
53.60
46.26
54.12
48.03
48.15
19.89
44.74
74.32
79.38
PPKT
36.50
51.67
49.71
54.33
50.18
56.00
50.92
54.69
37.57
46.48
78.90
84.00
SLidR
39.60
50.45
49.75
54.57
51.56
55.36
52.01
54.35
42.05
47.84
81.00
85.40
Seal :seal:
40.64
52.77
51.09
55.03
53.26
56.89
53.46
55.36
43.58
49.26
81.88
85.90
:truck: Robustness Probing
| Init | Backbone | mCE | mRR | Fog | Wet | Snow | Motion | Beam | Cross | Echo | Sensor |
|---|---|---|---|---|---|---|---|---|---|---|---|
| Random | PolarNet | 115.09 | 76.34 | 58.23 | 69.91 | 64.82 | 44.60 | 61.91 | 40.77 | 53.64 | 42.01 |
| Random | CENet | 112.79 | 76.04 | 67.01 | 69.87 | 61.64 | 58.31 | 49.97 | 60.89 | 53.31 | 24.78 |
| Random | WaffleIron | 106.73 | 72.78 | 56.07 | 73.93 | 49.59 | 59.46 | 65.19 | 33.12 | 61.51 | 44.01 |
| Random | Cylinder3D | 105.56 | 78.08 | 61.42 | 71.02 | 58.40 | 56.02 | 64.15 | 45.36 | 59.97 | 43.03 |
| Random | SPVCNN | 106.65 | 74.70 | 59.01 | 72.46 | 41.08 | 58.36 | 65.36 | 36.83 | 62.29 | 49.21 |
| Random | MinkUNet | 112.20 | 72.57 | 62.96 | 70.65 | 55.48 | 51.71 | 62.01 | 31.56 | 59.64 | 39.41 |
| PPKT | MinkUNet | 105.64 | 76.06 | 64.01 | 72.18 | 59.08 | 57.17 | 63.88 | 36.34 | 60.59 | 39.57 |
| SLidR | MinkUNet | 106.08 | 75.99 | 65.41 | 72.31 | 56.01 | 56.07 | 62.87 | 41.94 | 61.16 | 38.90 |
| Seal :seal: | MinkUNet | 92.63 | 83.08 | 72.66 | 74.31 | 66.22 | 66.14 | 65.96 | 57.44 | 59.87 | 39.85 |
:tractor: Qualitative Assessment
 |
|---|
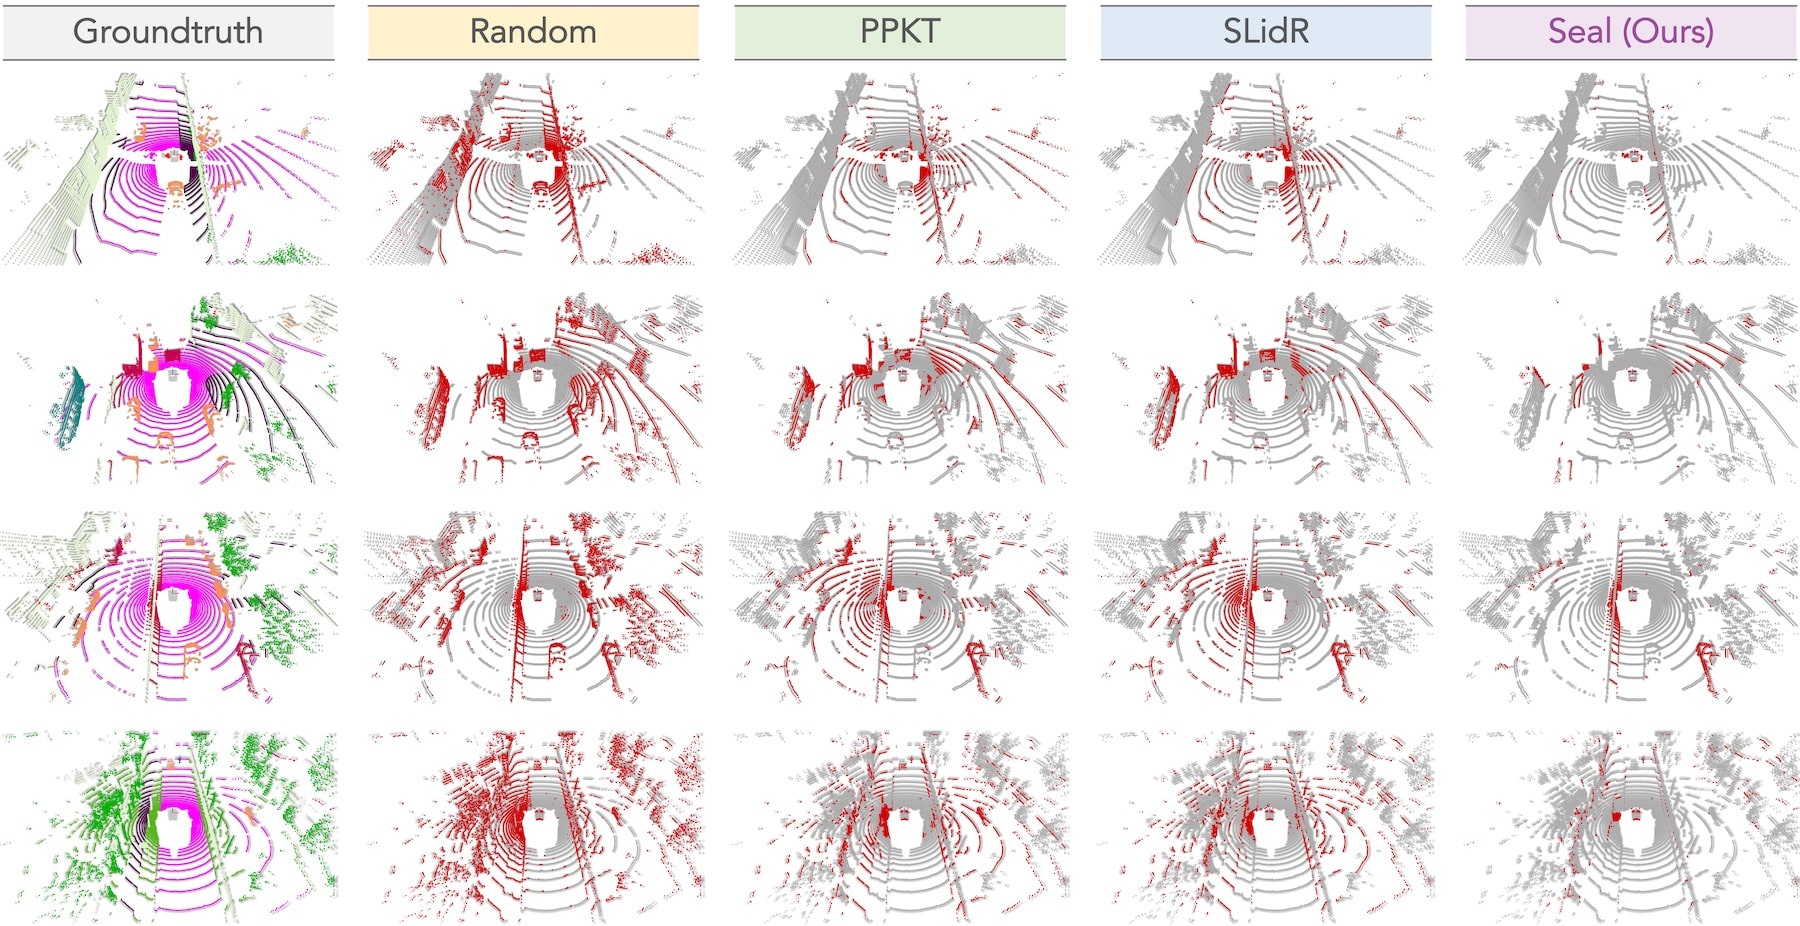
| The qualitative results of Seal :seal: and prior methods pretrained on nuScenes (without using groundtruth labels) and fine-tuned with 1% labeled data. To highlight the differences, the correct / incorrect predictions are painted in gray / red, respectively. |
TODO List
- [x] Initial release. :rocket:
- [x] Add license. See here for more details.
- [x] Add video demos :movie_camera:
- [x] Add installation details.
- [x] Add data preparation details.
- [x] Support semantic superpixel generation.
- [x] Support semantic superpoint generation.
- [ ] Add evaluation details.
- [ ] Add training details.
Citation
If you find this work helpful, please kindly consider citing our paper:
@inproceedings{liu2023segment,
  title = {Segment Any Point Cloud Sequences by Distilling Vision Foundation Models},
  author = {Liu, Youquan and Kong, Lingdong and Cen, Jun and Chen, Runnan and Zhang, Wenwei and Pan, Liang and Chen, Kai and Liu, Ziwei},
  booktitle = {Advances in Neural Information Processing Systems},
  year = {2023},
}
@misc{liu2023segment_any_point_cloud,
  title = {The Segment Any Point Cloud Codebase},
  author = {Liu, Youquan and Kong, Lingdong and Cen, Jun and Chen, Runnan and Zhang, Wenwei and Pan, Liang and Chen, Kai and Liu, Ziwei},
  howpublished = {\url{https://github.com/youquanl/Segment-Any-Point-Cloud}},
  year = {2023},
}
License

This work is under the Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License.
Acknowledgement
This work is developed based on the MMDetection3D codebase.
MMDetection3D is an open-source object detection toolbox based on PyTorch, towards the next-generation platform for general 3D detection. It is a part of the OpenMMLab project developed by MMLab.
Part of this codebase has been adapted from SLidR, Segment Anything, X-Decoder, OpenSeeD, Segment Everything Everywhere All at Once, LaserMix, and Robo3D.
:heart: We thank the exceptional contributions from the above open-source repositories!