
ClawProBench
Transparent live-first benchmark harness for evaluating model capability inside the OpenClaw runtime.
102 active scenarios, 164 catalog scenarios, deterministic grading, and OpenClaw-native coverage.
Paper now on arXiv: ClawProBench: Trace-Aware Evaluation of AI Agents with Runtime Coverage and Frozen Workplace-Style Holdouts.
Dataset available on Hugging Face: xyh110sym/clawprobench.
ClawProBench focuses on real OpenClaw execution with deterministic grading, structured reports, and benchmark-profile selection. The default ranking path is the core profile; broader active coverage remains available through intelligence, coverage, native, and full.
The current worktree inventory reports 102 active scenarios and 164 total catalog scenarios (62 incubating) via python3 run.py inventory --json and python3 run.py inventory --benchmark-status all --json.
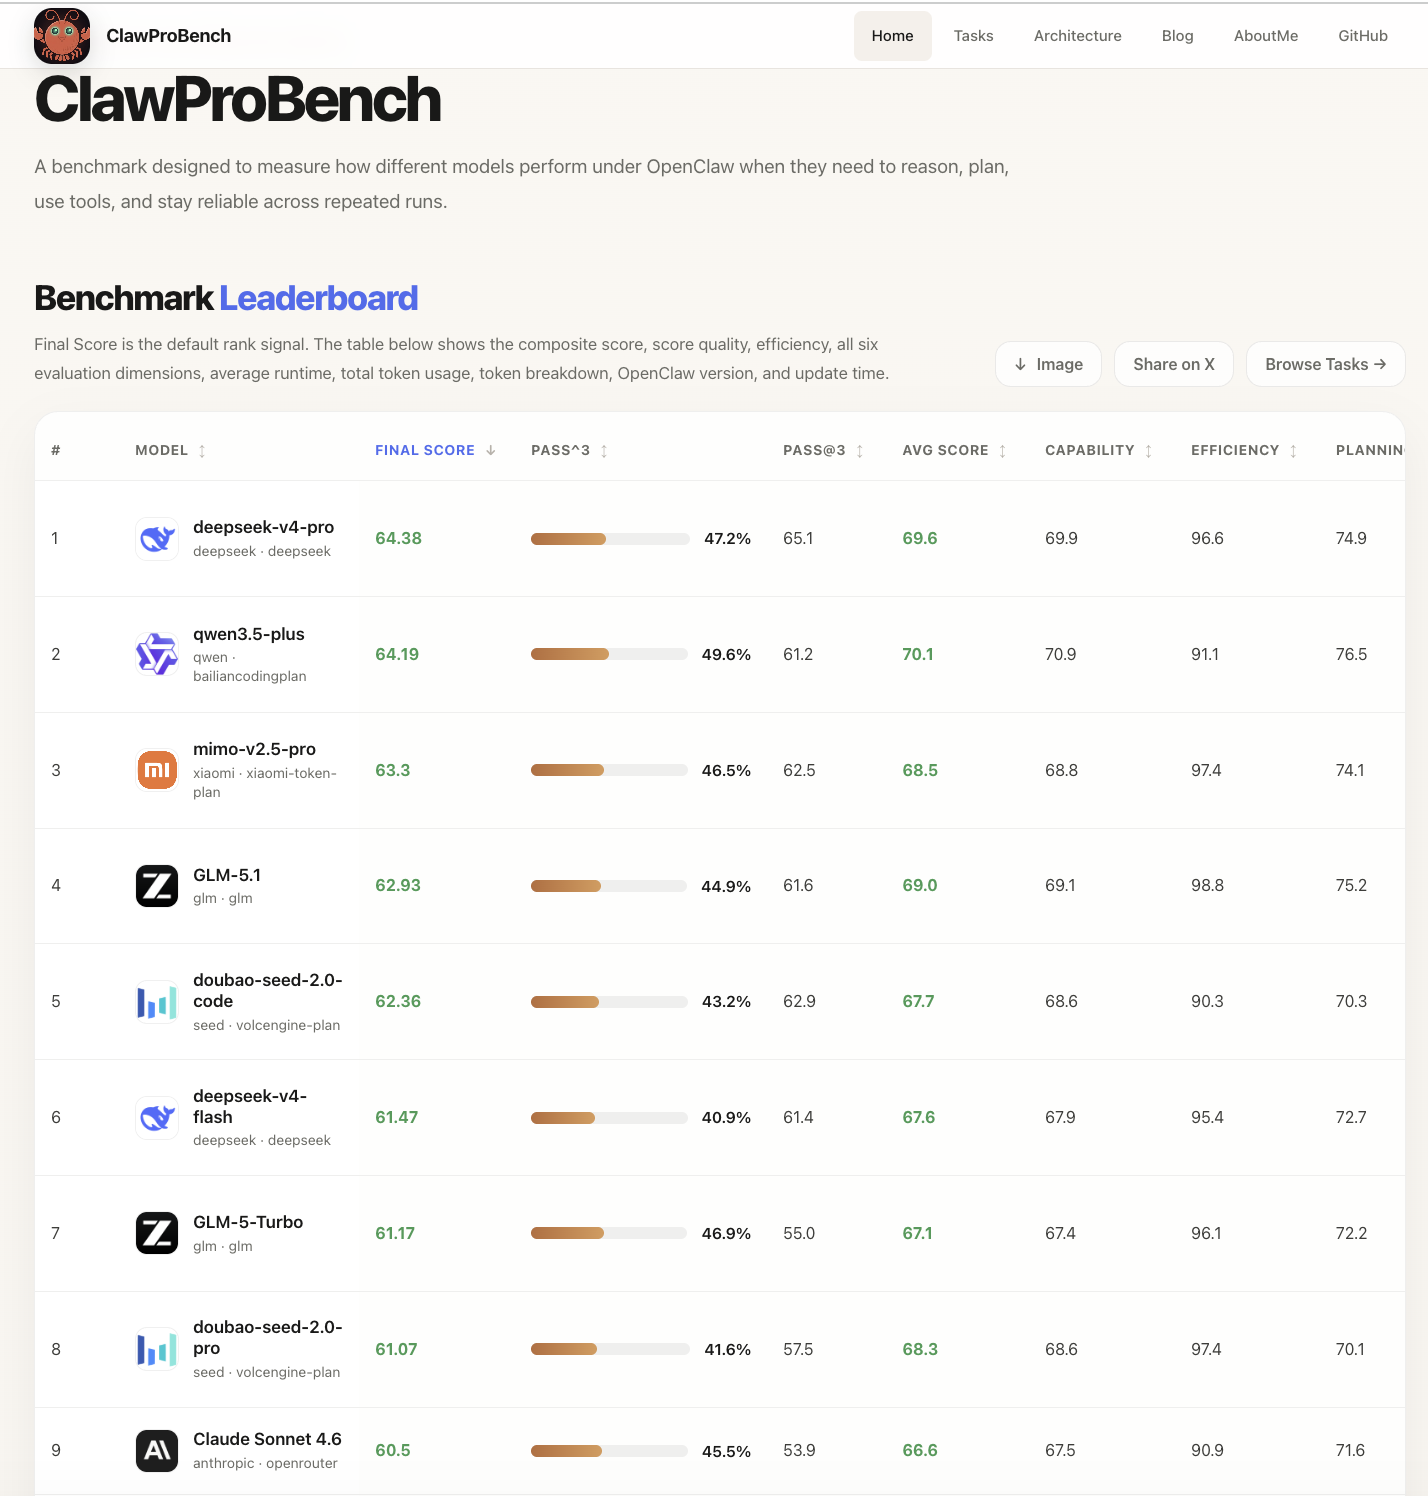
Leaderboard
Browse the public leaderboard and benchmark cases at suyoumo.github.io/bench.
Get Involved
We sincerely thank friends from Kimi and Qwen for their helpful feedback and improvement suggestions for the ClawProBench leaderboard.
We also thank LongCat, Kimi, Ant Ling, and MiMo for providing model access support, trial access, or platform resources. This support helped reduce evaluation costs and made it possible to cover more frontier and preview models in a transparent live-runtime setting.
If domestic third-party API gateway providers would like their served models, such as Claude 4.7 Opus or GPT-5.5, to appear on the leaderboard, please contact us. We can run the benchmark and publish reproducible results when the evaluation setup is stable.
To run ClawProBench, submit results, or discuss model evaluation for the leaderboard, contact: xyh920691910@outlook.com.
LLMLeadBoard
LLMLeadBoard is the report-sourced model-score board in the same leaderboard family as ClawProBench. It aggregates benchmark scores by model and inference mode from public model reports, making it easier to compare reported capability signals across benchmark families.
The current LLMLeadBoard covers 63 models, 55 source reports, and 444
benchmarks. It supports benchmark filtering, stacked cells when different
reports give different scores for the same model and benchmark, trend charts for
benchmark progress within a model family, and iteration-speed charts for model
release cadence.
Blog
- ClawProBench Close DataSet LeadBoard Release:ClawProBench Closed Dataset Release and Analysis
- Safety Under Live Agent Work: What the ClawProBench Leaderboard Shows
- My Feelings During the Development of ClawProBench
- Open-sourcing ClawProBench: Bringing Agent Benchmarks Back to the Real Runtime
📢 Updates
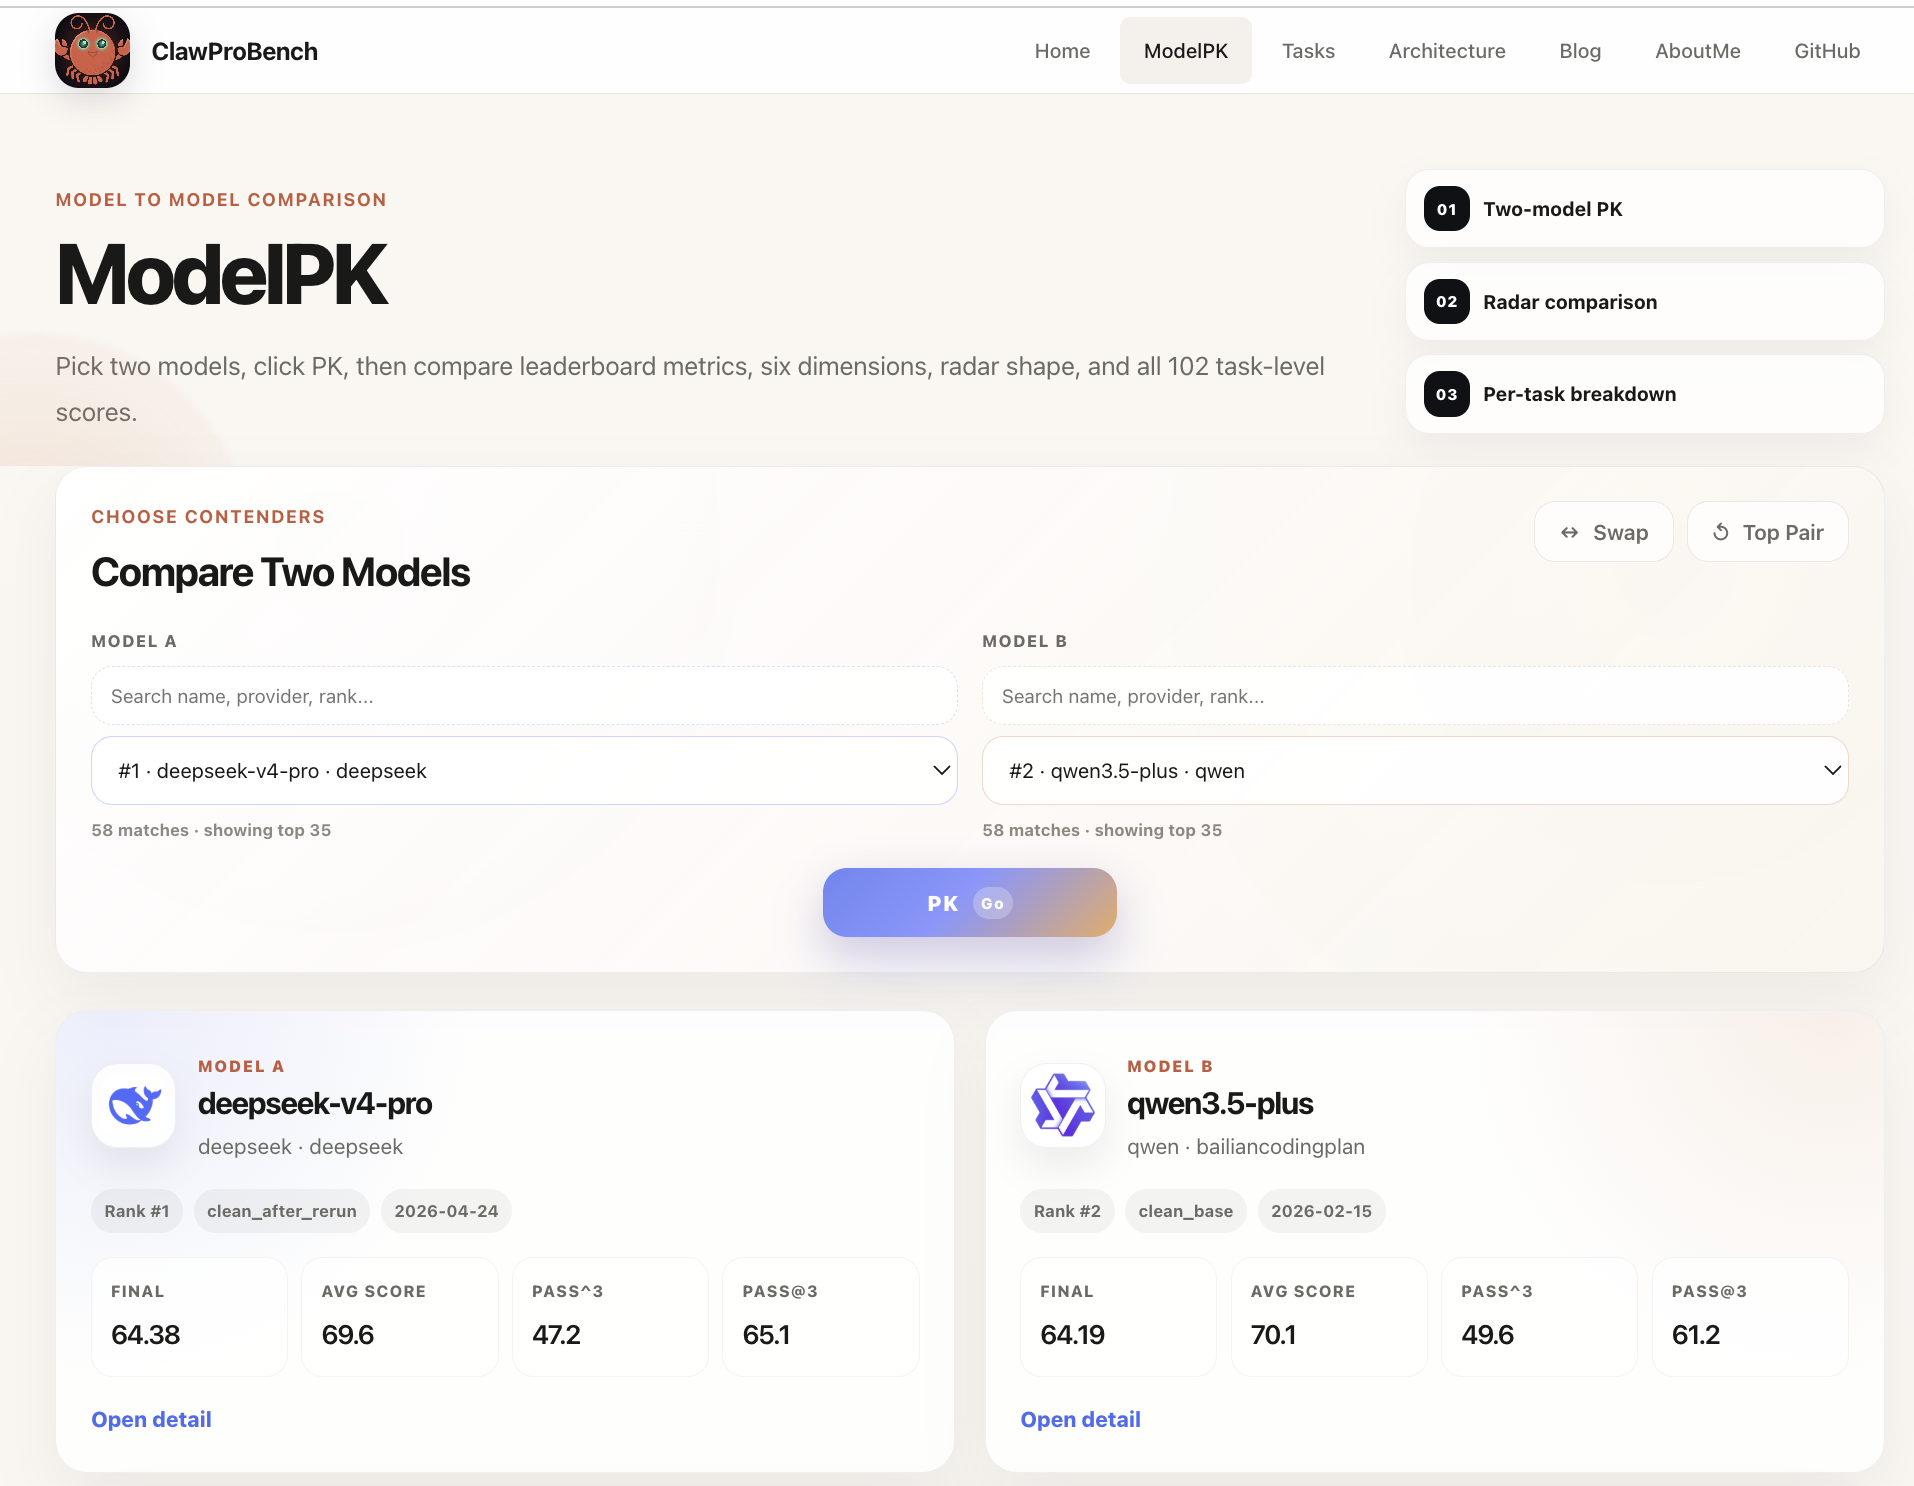
v2.0.4- Released the full 102 active scenarios dataset on Hugging Face, including prompts, fixtures, and scenario configurations for all benchmark-active tasks.v2.0.3- Published the ClawProBench paper on arXiv (2608.22510) and updated the citation block; addedkimi-k3leaderboard scores; synced harness code updates (resume model-alias preservation fix); hardened multiple custom checkers with deterministic order-insensitive matchers; and vendored the IronClaw and NanoClaw harness sources to support cross-harness evaluation.v2.0.2- Addedagnes-2.0-flashresults to both the ClawProBench open-source and closed-dataset leaderboards. CodeAgentBench also added results forGLM-5.2,Qwen3.7-Max,Qwen3.7-Plus,MiniMax-M3, andstep-3.7-flash.v2.0.1- Added closed-dataset scores forQwen3.7-Max,Gemini 3.1 Pro,MiniMax-M3, andstep-3.7-flash; added open-source dataset scores forMiniMax-M3andstep-3.7-flash; and introduced the LLMLeadBoard section for the report-sourced benchmark-score leaderboard.v2.0.0- Released the closed-dataset leaderboard with33model results; added clickable closed-dataset model detail pages, closed-dataset visualization charts, and closed-dataset task browsing inTasks.v1.1.6- Added Shanghai AI Labintern-s2-previewto the open-source model leaderboard.v1.1.5- Added thering-2.6-1T-xhighleaderboard result; the leaderboard now includes65models.v1.1.4- Added leaderboard results for BaiduERNIE 5.1and SenseTimeSensenova 6.7 Flash Lite. (We are glad to see ClawProBench attracting growing attention. Because the benchmark is fully open source, it cannot fully avoid vendors optimizing specifically for the public benchmark; a leaderboard based on a closed ClawProBench dataset will be released soon. The open-source dataset portion and evaluation harness for my coding benchmark are also expected to be open-sourced within the next 1-2 weeks. Stay tuned.)v1.1.3- Added OpenAIgpt-5.5,gpt-5.4, andgpt-5.3-codexleaderboard results, which now rank 1-3; also addedDeepSeek-R1andkimi-for-coding-k2.6, and synced the latest live-runtime, custom-check loading, and scenario-grading fixes.v1.1.2- Added leaderboard data forqwen3.5-397b-a17b, fixed pricing and release-date metadata for several models, and added ModelPK for detailed model-to-model comparison.v1.1.1- Added leaderboard results forkimi-k2.6; the leaderboard now includes57models.v1.1.0- Added leaderboard results forqwen3.6-27b,qwen3.6-35b-a3b, andqwen3.6-flash.v1.0.9- Verified model-detail data across the leaderboard, fixed several data errors, addedDeepSeeK-V4-Pro,DeepSeek-V4-Flash,LongCat-2.0-Preview, andLing-2.6-1T, and introduced the newFinalScoremetric based onpass^3,pass@3, andaverage_score.v1.0.8- Added 6 new leaderboard models:qwen3.6-max-preview,mimo-v2.5,mimo-v2.5-pro,hunyuan-t1,hy3-preview, andLing-2.6-Flash.v1.0.7- Synced benchmark bug fixes from the latest harness line, including--exclude-scenariofiltering, isolated live-run runtime hardening, and trace-argument compatibility fixes for custom scoring.v1.0.6- Fixed the leaderboard sticky-header sync bug that could appear when dragging the horizontal scrollbar with a mouse. Added theqwen3.6-plusToken Plan result to the leaderboard.v1.0.5- Fixed theqwen3.6-plusmodel detail bug where the Bailian and Qwen Coding Plan entries incorrectly showed duplicated per-task scores.v1.0.4- Fixed isolated live-run log pollution that could cause false execution failures. Addedkimi-k2.6-code-preview; the leaderboard now includes43model results.v1.0.3- Reviewed leaderboard, detail, and raw-result consistency across 40+ benchmark models; fixed confirmed data mismatches fordoubao-seed-code,qwen3.6-plus,qwen3-max-2026-01-23,astron-code-latest, andERNIE-4.5-Turbo.v1.0.2- Addedkimi-for-coding,gemma4-31b, andkimi-k2-thinking; improved image download flows for easier mobile-device browsing.v1.0.1- Addedqwen3-coder-next,doubao-seed-code,qwen3-max-2026-01-23, andqwen3.6plusrerun withbailiancodingplan; added model image download and benchmark sharing to Twitter; fixed completed-report resume overwrite,tool_use_14graceful fallback on skills inventory load failure,tool_use_17invalid JSON and missing-file tolerance, andaudit_scenario_quality.pycompatibility.v1.0.0- ClawProBench released with 102 tasks across 6 domains, with 3-try runs, checkpoint resume, and cross-environment resume support.
Evaluation Logic
- Default ranking path:
core - Extended active capability suite:
intelligence - Native-only slice:
native - Multi-trial runs are supported via
--trials N - Key leaderboard metrics now include
pass^3,pass@3,average_score, andFinalScore FinalScore = 100 × S^0.40 × r_all^0.45 × r_any^0.15, whereS = average_score,r_all = (pass^3)^(1/3), andr_any = 1 - (1 - pass@3)^(1/3)- This is intended to weight stable repeated success most heavily, while still preserving overall quality and upside from best-of-3 performance
- Reports expose
avg_score,max_score, coverage-aware summaries, cost, latency, and resume metadata - Interrupted runs can continue with
--continueor--resume-from, and execution failures can be re-queued with--rerun-execution-failures
Quick Start
We recommend using uv for fast, reliable Python environment setup:
pip install uv
uv venv --python 3.11
source .venv/bin/activate
uv pip install -r requirements.txt
Before running the benchmark, make sure your local OpenClaw runtime is available:
openclaw --help
openclaw agents list --json
Inspect the benchmark catalog and validate the scenario set:
python3 run.py inventory
python3 run.py inventory --json
python3 run.py dry
Run a one-trial smoke on the default ranking benchmark:
python3 run.py run \
  --model '' \
  --execution-mode live \
  --benchmark-profile core \
  --trials 1 \
  --cleanup-agents
Run the full default benchmark:
python3 run.py run \
  --model '' \
  --execution-mode live \
  --benchmark-profile core \
  --trials 3 \
  --cleanup-agents
Compare generated reports:
python3 run.py compare --results-dir results
For isolated same-host runs, the harness also supports:
--openclaw-profile--openclaw-state-dir--openclaw-config-path--openclaw-gateway-port--openclaw-binary
Benchmark Profiles
| Profile | Active scenarios | Purpose |
|---|---|---|
core |
26 | Default ranking suite |
intelligence |
95 | Extended active capability benchmark |
coverage |
7 | Lower-stakes breadth and regression slice |
native |
36 | Active OpenClaw-native slice only |
full |
102 | Union of all active scenarios |
The benchmark catalog also includes 62 incubating scenarios that can be inspected with --benchmark-status all.
OpenClaw Runtime
Live runs expect a working local openclaw CLI plus the auth and config required by the surfaces exercised by the selected scenarios. If your binary is not on PATH, set OPENCLAW_BINARY or pass --openclaw-binary.
config/openclaw.json.template is provided as a reference template for local OpenClaw configuration and isolated-run setups.
Repo Map
run.py: CLI entrypoint forinventory,dry,run, andcompareharness/: loader, runner, scoring, reporting, and live OpenClaw bridgescenarios/: benchmark tasks in YAMLdatasets/: seeded live-task data and optional setup / teardown scriptscustom_checks/: scenario-specific grading logictests/: regression coverage for loader, runner, scoring, and reportingdocs/: public assets plus evaluation validation and benchmark-profile policy
Generated Output
Benchmark reports are written to results/. They are generated runtime artifacts and are intentionally ignored by version control in this repo layout.
Usage Statistics
Tracking started: 2026-08-25
| Metric | Total | Unique |
|---|---|---|
| Clones | 459 | 82 |
| Views | 129 | 61 |
Clones and views are accumulated daily from the GitHub Traffic API. Raw daily data lives in traffic/traffic.json.
Run python3 scripts/update_traffic.py to refresh the statistics.
Citation
If you use ClawProBench in your research, please cite:
@misc{clawprobench2026,
  title={ClawProBench: Trace-Aware Evaluation of AI Agents with Runtime Coverage and Frozen Workplace-Style Holdouts},
  author={YuanHang, Xiao},
  year={2026},
  eprint={2608.22510},
  archivePrefix={arXiv},
  primaryClass={cs.AI},
  url={https://arxiv.org/abs/2608.22510},
  doi={10.48550/arXiv.2608.22510}
}
Contribution
We welcome issues, documentation fixes, scenario improvements, grader hardening, and benchmark-engine contributions. See CONTRIBUTING.md for setup and validation guidance.
Acknowledgements
This project was informed by prior open-source work on agent evaluation, benchmark design, and real-world task assessment.
We drew ideas from projects such as PinchBench, Claw-Eval, AgencyBench, and related agent-benchmark efforts, especially in areas like task design, evaluation methodology, harness structure, and public benchmark presentation.
Some tasks in this repository are adapted and reworked from earlier public benchmark-style task sets into the OpenClaw runtime and grading framework.