 VideoLLM-online: Online Video Large Language Model for Streaming Video
Updates
2025-09-03
I made some updates to make sure this repo can be inference with the latest transformers==4.55.4 and pytorch==2.7.1+cu128. Similar versions should be okay. If you want to obtain a strong VLM-online model, I highly recommend you to finetune Qwen2.5VL-Instruct with the streaming EOS loss here. No need to use the weak text-only Llama3 again.
2025-04-24
Updates! Our new paper: LiveCC: Learning Video LLM with Streaming Speech Transcription at Scale. All resources, including the training video data, have been released at LiveCC Webpage
TLDR
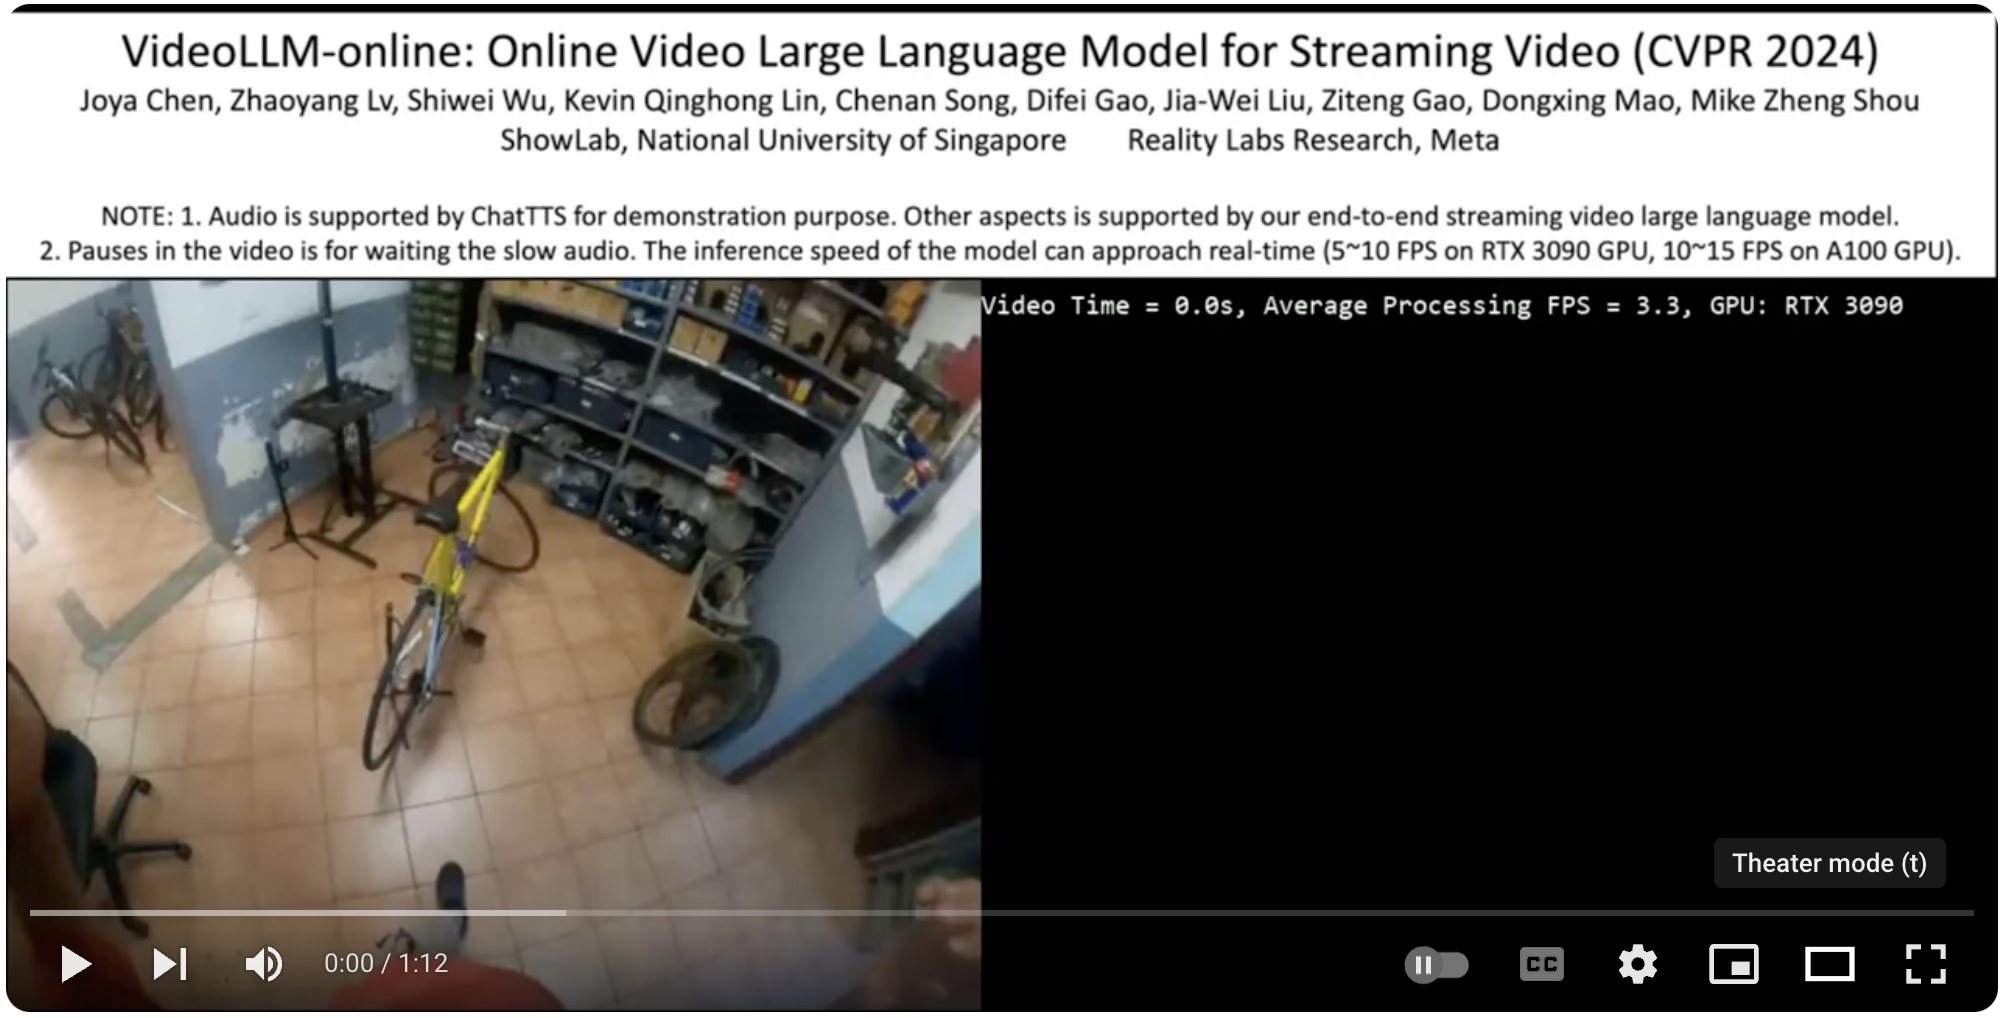
The first streaming video LLM, high speed (5 ~ 10 FPS on NVIDIA 3090 GPU, 10 ~ 15 FPS on A100GPU) on long-form videos (10 minutes), with SOTA performance on online/offline settings.
Introduction
This is the official implementation of VideoLLM-online: Online Video Large Language Model for Streaming Video, CVPR 2024. Our paper introduces several interesting stuffs compared to popular image/video/multimodal models:
-
Online Video Streaming: Unlike previous models that serve as offline mode (querying/responding to a full video), our model supports online interaction within a video stream. It can proactively update responses during a stream, such as recording activity changes or helping with the next steps in real time. Even GPT-4o, which is audio-driven, requires user voice interaction with the visual scene, not actual video streaming.
-
Cheap and Scalable Streaming Data Synthesis: Current video datasets for training multimodal LLMs are mostly offline and unsuitable for training an online video language model. Our method transforms any offline annotation into streaming dialogue data by prompting open-source LLM. The model is entirely trained on Llama synthesized data.
-
Parallelized Real-Time Inference: Our inference method parallelizes video encoding, LLM forwarding for video frames, and LLM response generation, arranging them asynchronously. This significantly enhances real-time performance, achieving 10-15 FPS on an A100 GPU.
Quick Start
- (Recommended) Launch the gradio demo locally with:
python -m demo.app --resume_from_checkpoint chenjoya/videollm-online-8b-v1plus
But if there are some bugs with flash-attn, try to use
python -m demo.app --resume_from_checkpoint chenjoya/videollm-online-8b-v1plus --attn_implementation sdpa
- (Recommended) Launch the CLI locally with:
python -m demo.cli --resume_from_checkpoint chenjoya/videollm-online-8b-v1plus
- (Deprecated, HF Spaces too slow) Try demo at 
By passing --resume_from_checkpoint chenjoya/videollm-online-8b-v1plus, the PEFT checkpoint will be automatically downloaded and applied to meta-llama/Meta-Llama-3-8B-Instruct.
Installation
Ensure you have Miniconda and Python version >= 3.10 installed, then run:
conda install -y pytorch torchvision torchaudio pytorch-cuda=12.1 -c pytorch -c nvidia
pip install transformers accelerate deepspeed peft editdistance Levenshtein tensorboard gradio moviepy submitit
pip install flash-attn --no-build-isolation
PyTorch source will make ffmpeg installed, but it is an old version and usually make very low quality preprocessing. Please install newest ffmpeg following:
wget https://johnvansickle.com/ffmpeg/releases/ffmpeg-release-amd64-static.tar.xz
tar xvf ffmpeg-release-amd64-static.tar.xz
rm ffmpeg-release-amd64-static.tar.xz
mv ffmpeg-7.0.2-amd64-static ffmpeg
If you want to try our model with the audio in real-time streaming, please also clone ChatTTS.
pip install omegaconf vocos vector_quantize_pytorch cython
git clone git+https://github.com/2noise/ChatTTS
mv ChatTTS demo/rendering/
Training and Evaluation
-
Download streaming dialogue data from 
-
Distributed preprocess video frames: 2 FPS and 384 resolution, then using
google/siglip-large-patch16-384to extract CLS with avg pooled 3x3 spatial tokens. Please refer to instructions under data/preprocess/. -
Refer to the examples under scripts/
-
If you are interested in our streaming dialogue data generation, please see data/livechat/
Model Zoo
VideoLLM-online-8B-v1+
- LLM: meta-llama/Meta-Llama-3-8B-Instruct
- Vision Strategy:
- Frame Encoder: google/siglip-large-patch16-384
- Frame Tokens: CLS token + 3x3 average pooled spatial tokens
- Frame FPS: 2 for training, 2~10 for inference
- Frame Resolution: max resolution 384, with zero-padding to keep aspect ratio
- Video Length: 10 minutes
- Training Data: Ego4D Narration Stream 113K + Ego4D GoalStep Stream 21K
VideoLLM-online-8B-v1
- LLM: meta-llama/Meta-Llama-3-8B-Instruct
- Vision Strategy:
- Frame Encoder: google/siglip-large-patch16-384
- Frame Tokens: CLS token
- Frame FPS: 2 for training, 2~10 for inference
- Frame Resolution: max resolution 384, with zero-padding to keep aspect ratio
- Video Length: 60 minutes
- Training Data: Ego4D Narration Stream 113K + Ego4D GoalStep Stream 21K
VideoLLM-online beyond Llama
This codebase has a very simple and clean implementation. You only need to change the inherited class from Llama to Mistral to achieve the Mistral version of VideoLLM-online. Please refer to the examples in models/live_llama.
Citation
@inproceedings{videollm-online,
  author       = {Joya Chen and Zhaoyang Lv and Shiwei Wu and Kevin Qinghong Lin and Chenan Song and Difei Gao and Jia-Wei Liu and Ziteng Gao and Dongxing Mao and Mike Zheng Shou},
  title        = {VideoLLM-online: Online Video Large Language Model for Streaming Video},
  booktitle    = {CVPR},
  year         = {2024},
}