word2vec, sentence2vec, machine reading comprehension, dialog system, text classification, pretrained language model (i.e., XLNet, BERT, ELMo, GPT), sequence labeling, information retrieval, information extraction (i.e., entity, relation and event extraction), knowledge graph, text generation, network embedding
Building and Embedding Machine Learning Model into a Web App(With Flask,Streamlit,etc)
关键参数与规格
关键参数与规格
参数
值
语言
Jupyter Notebook
类别
Tutorials
子类别
ML/AI fundamentals
关键词
Audio production
星标数
586
分叉数
191
贡献者
2
创建日期
2018-10-20
更新日期
2026-08-30
1 天星标数
0
7 天星标数
0
排名
16,540
上次排名
16,325
排名变化
-215
7 天星标排名
15,583
上次 7 天星标排名
15,594
7 天星标排名变化
11
总星标排名
17,099
上次总星标排名
17,080
总星标排名变化
-19
README 摘录
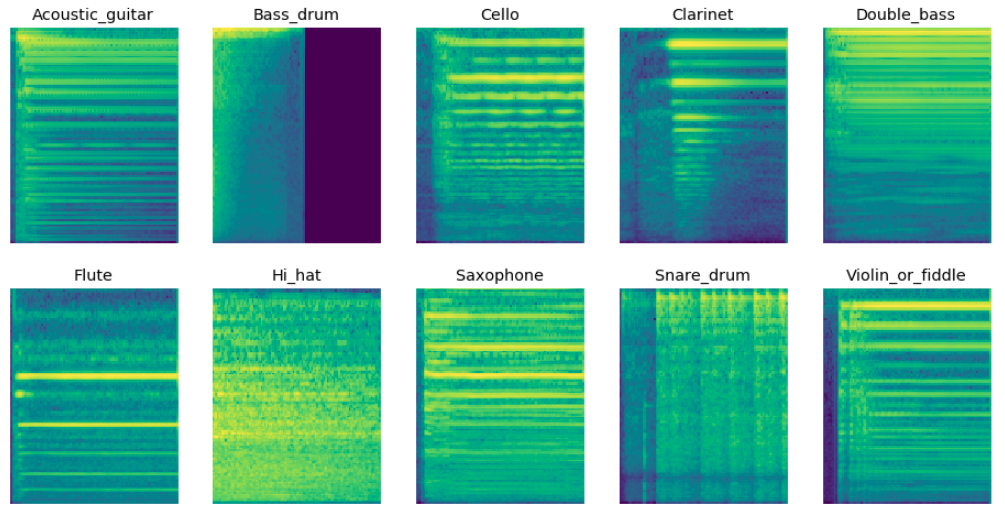
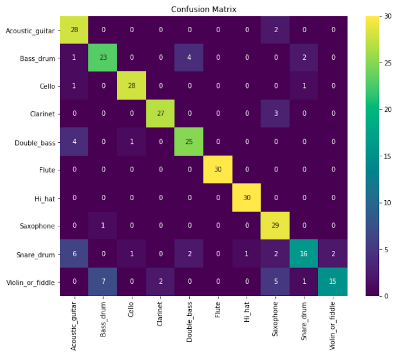
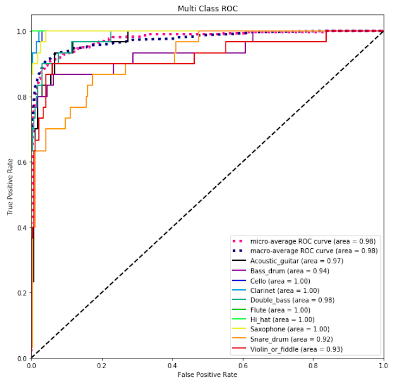
Audio-Classification (Kapre Version) Pipeline for prototyping audio classification algorithms with TF 2. 3 YouTube Environment Jupyter Notebooks Audio Preprocessing Training Plot History Confusion Matrix Receiver Operating Characteristic Kapre YouTube This series has been re-worked. There are new videos to support this repository. It is recommended to follow the new series. If you want to follow the old videos, restore to a previous commit. Environment Jupyter Notebooks Assuming you have ipykernel installed from your conda environment Audio Preprocessing clean
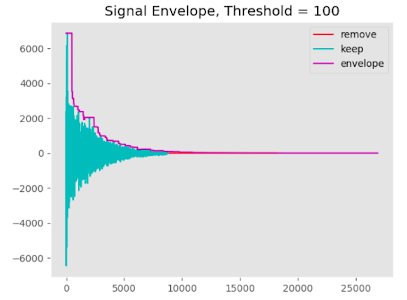
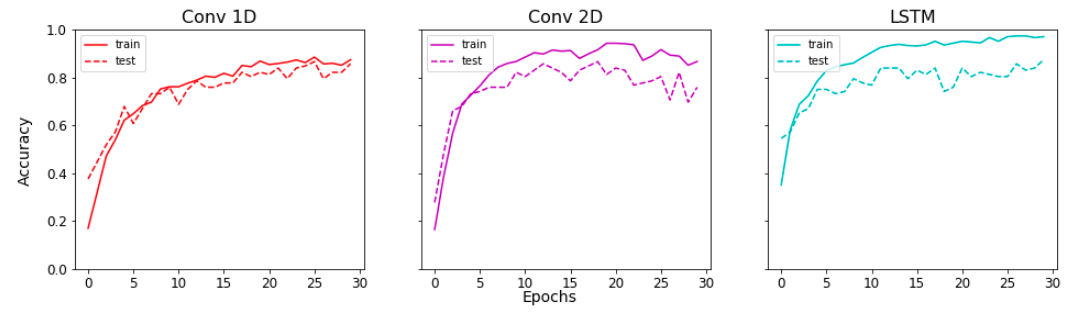
. py can be used to preview the signal envelope at a threshold to remove low magnitude data When you uncomment split_wavs, a clean directory will be created with downsampled mono audio split by delta time Training Change model_type to: conv1d, conv2d, lstm Sample rate and delta time should be the same from clean. py Plot History Assuming you have ran all 3 models and saved the images into logs, check Confusion Matrix Receiver Operating Characteristic Kapre For computation
of audio transforms from time to frequency domain on the fly