MoCoGAN: Decomposing Motion and Content for Video Generation
This repository contains an implementation and further details of MoCoGAN: Decomposing Motion and Content for Video Generation by Sergey Tulyakov, Ming-Yu Liu, Xiaodong Yang, Jan Kautz.
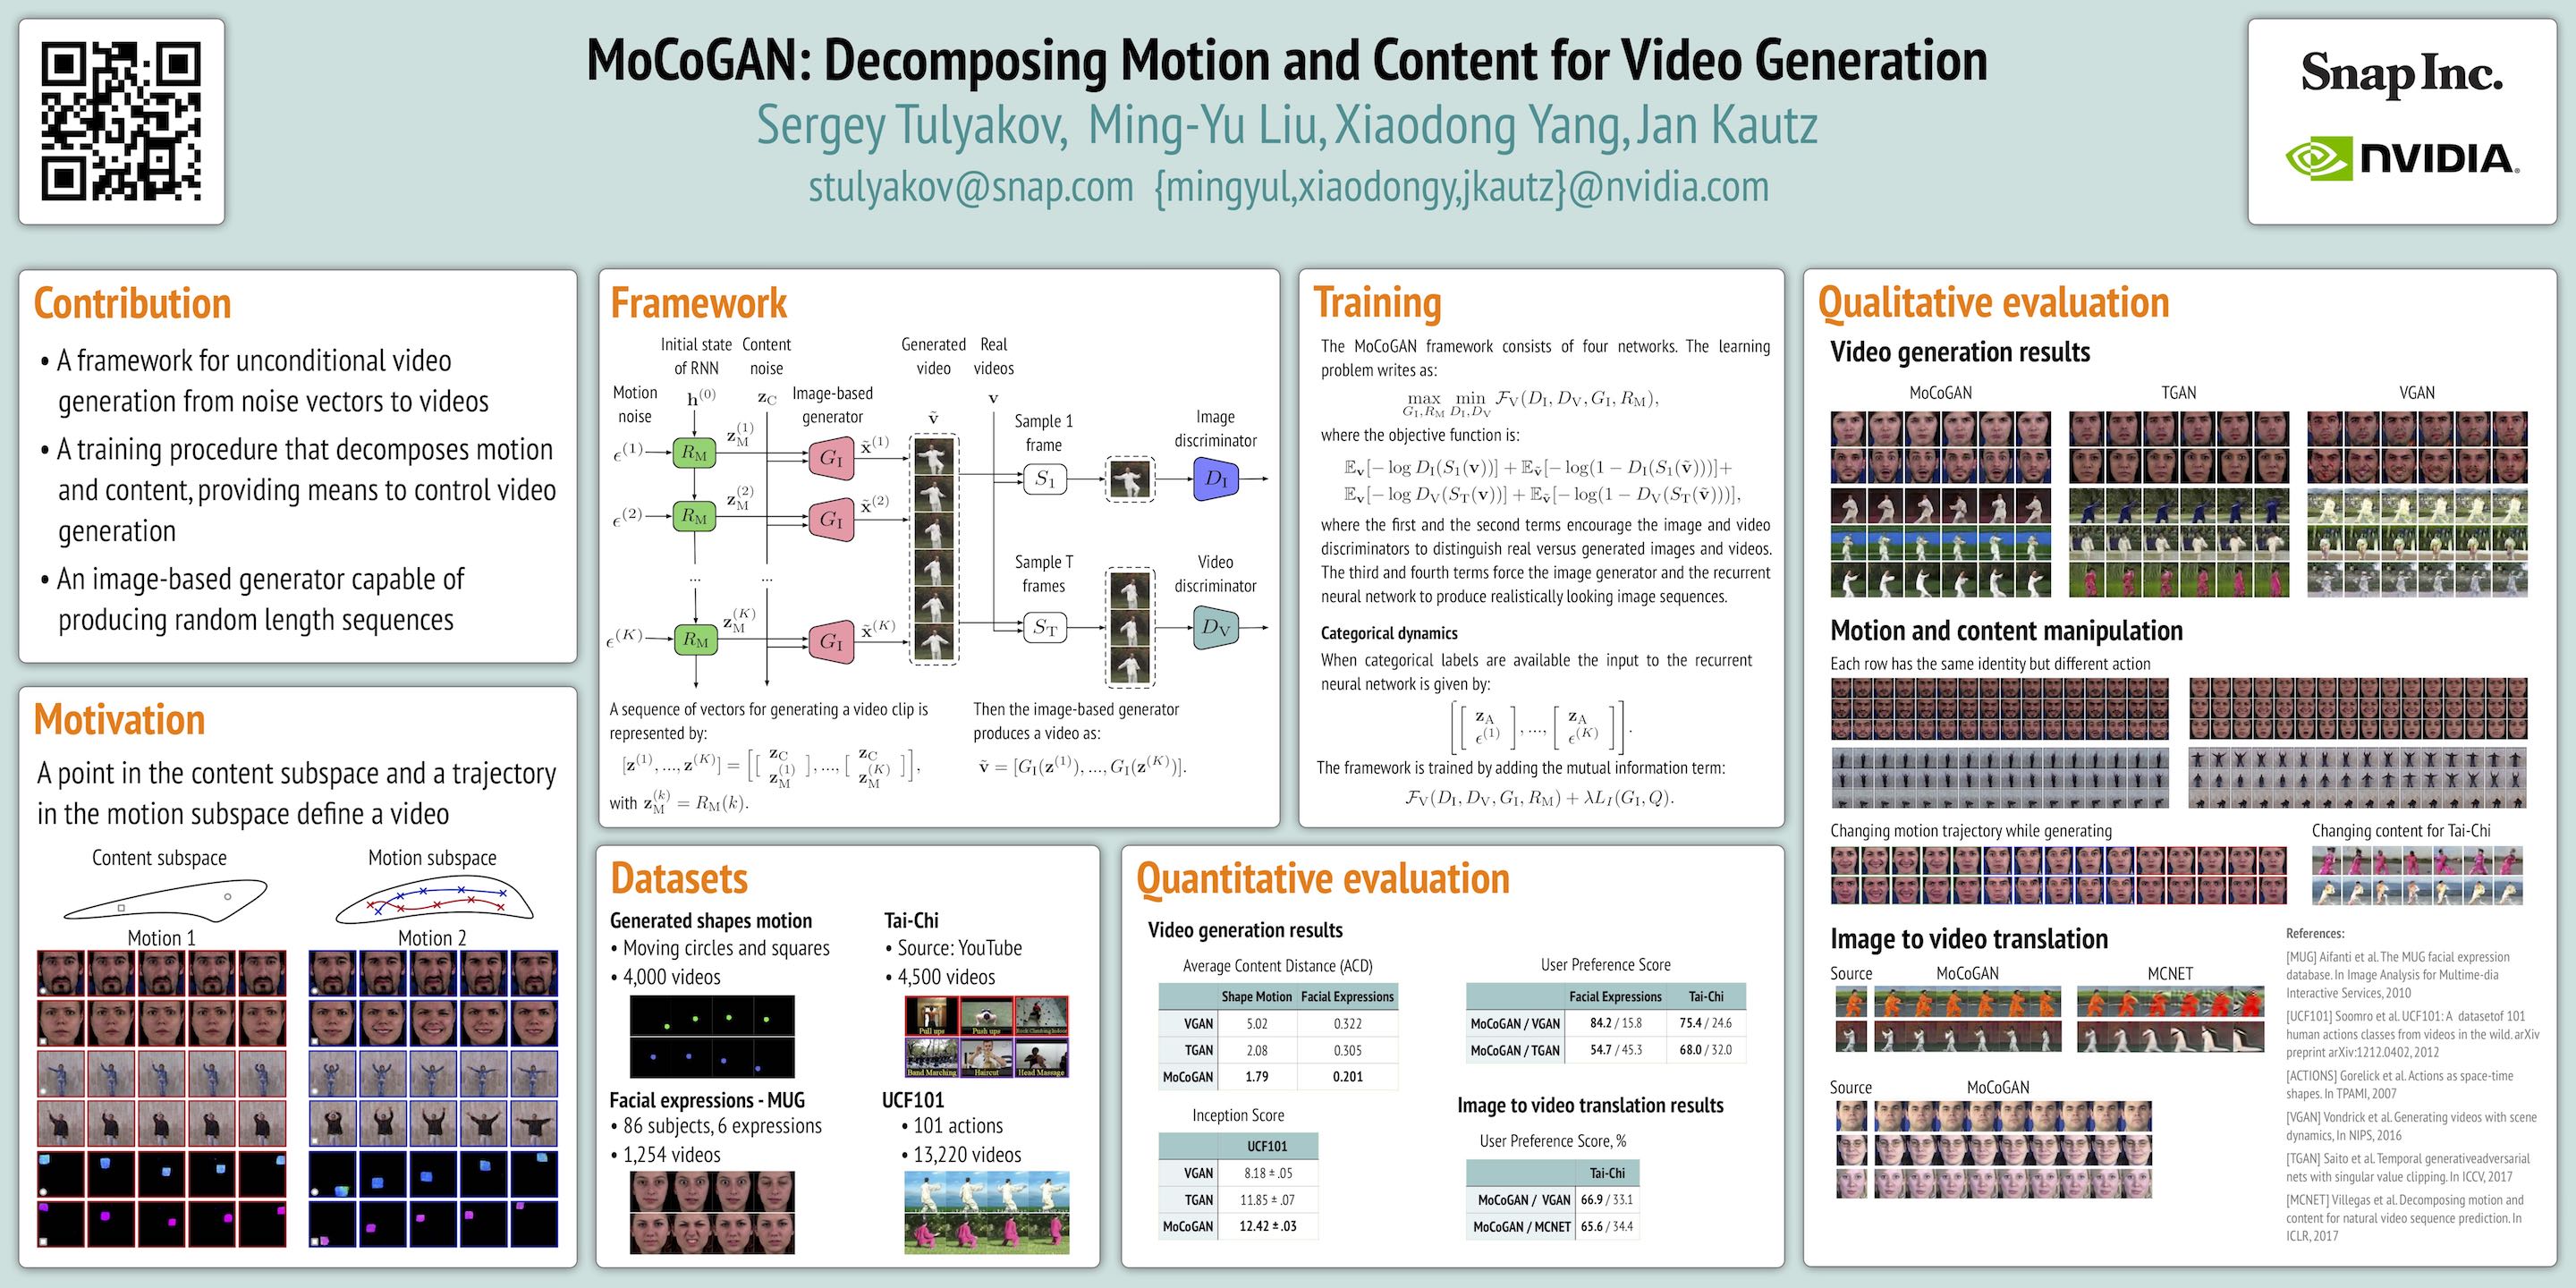
CVPR Poster:
Representation
MoCoGAN is a generative model for videos, which generates videos from random inputs. It features separated representations of motion and content, offering control over what is generated. For example, MoCoGAN can generate the same object performing different actions, as well as the same action performed by different objects

Examples of generated videos
We trained MoCoGAN on the MUG Facial Expression Database to generate facial expressions. When fixing the content code and changing the motion code, it generated the same person performs different expressions. When fixing the motion code and changing the content code, it generated different people performs the same expression. In the figure shown below, each column has fixed identity, each row shows the same action:
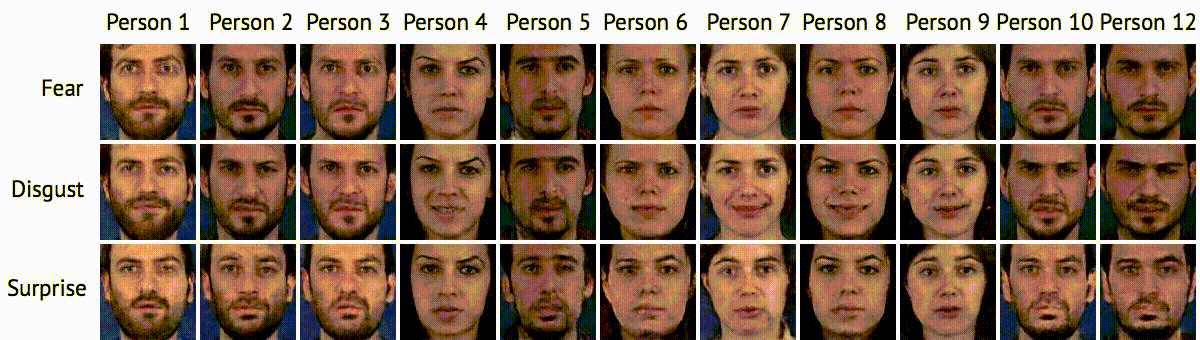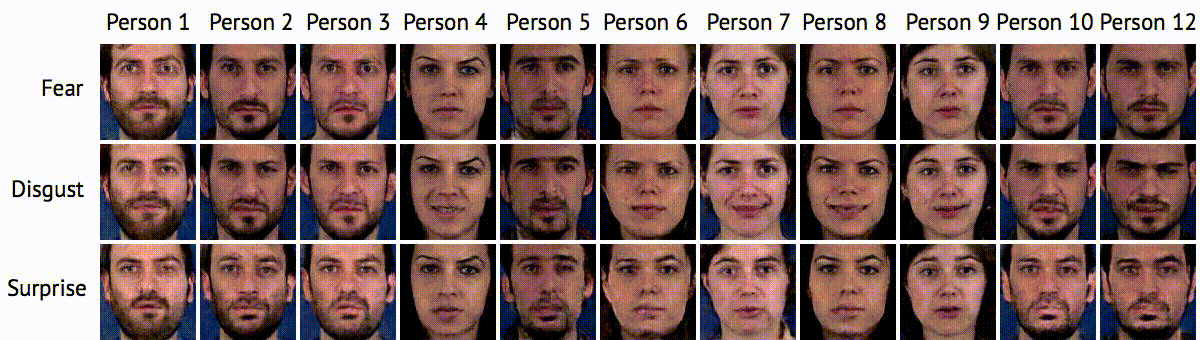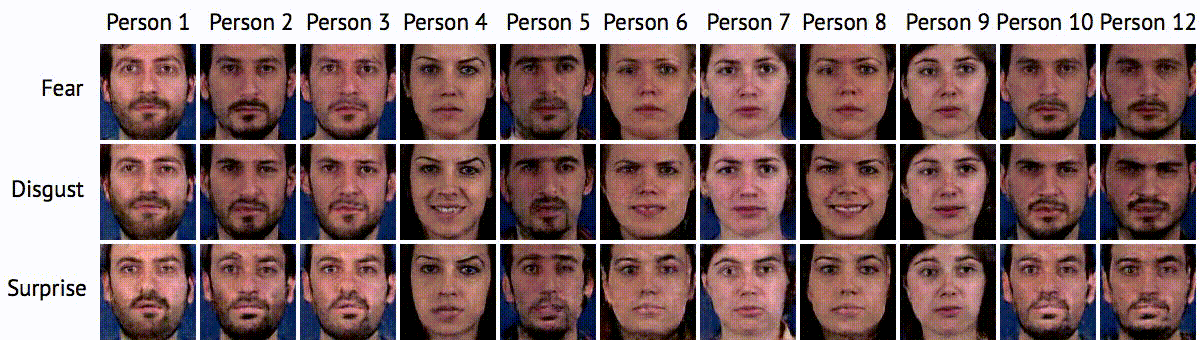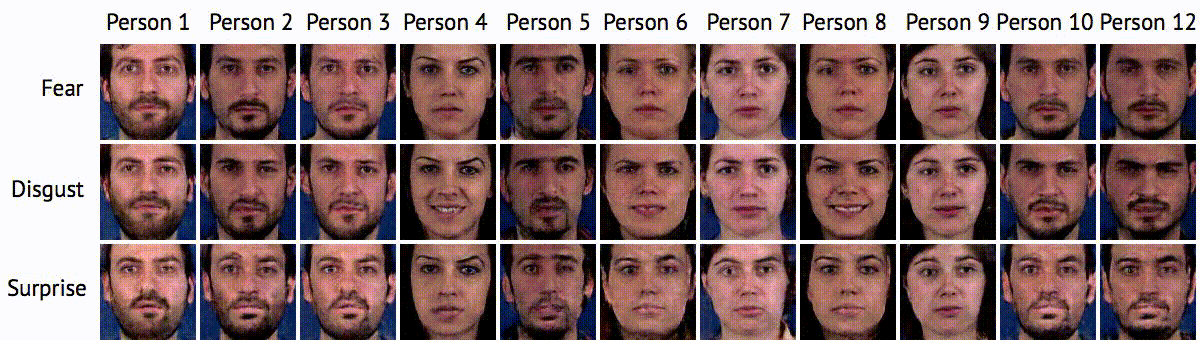
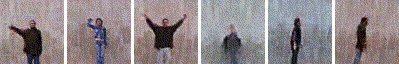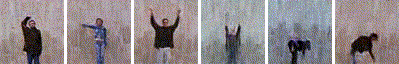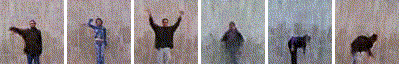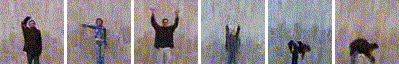
We trained MoCoGAN on a human action dataset where content is represented by the performer, executing several actions. When fixing the content code and changing the motion code, it generated the same person performs different actions. When fixing the motion code and changing the content code, it generated different people performs the same action. Each pair of images represents the same action executed by different people:
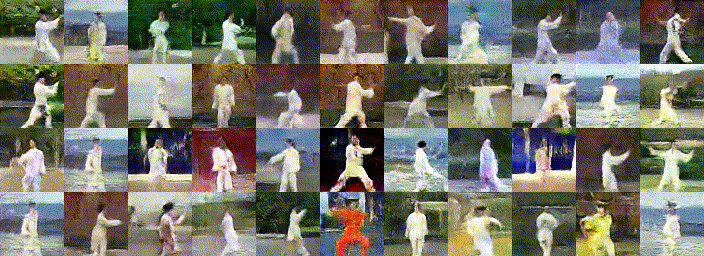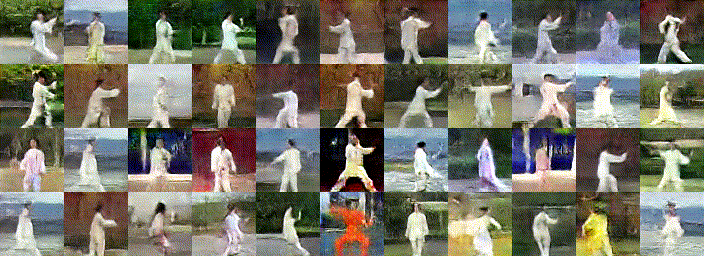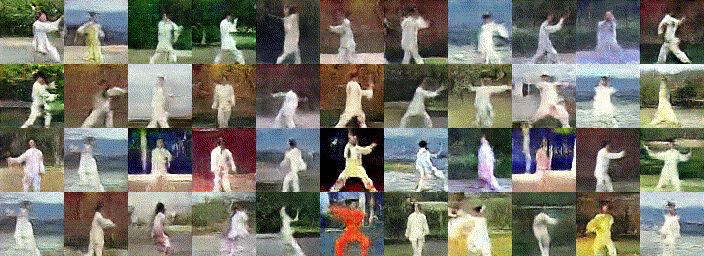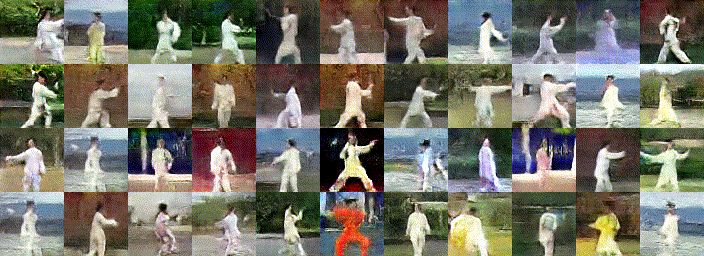
We have collected a large-scale TaiChi dataset including 4.5K videos of TaiChi performers. Below are videos generated by MoCoGAN.
Training MoCoGAN
Please refer to a wiki page
Citation
If you use MoCoGAN in your research please cite our paper:
@inproceedings{Tulyakov:2018:MoCoGAN,
 title={{MoCoGAN}: Decomposing motion and content for video generation},
 author={Tulyakov, Sergey and Liu, Ming-Yu and Yang, Xiaodong and Kautz, Jan},
 booktitle={IEEE Conference on Computer Vision and Pattern Recognition (CVPR)},
 pages = {1526--1535},
 year={2018}
}