Datumbox is an open-source Machine Learning framework written in Java which allows the rapid development of Machine Learning and Statistical applications.
PyTorch code for CVPR 2018 paper: Learning to Compare: Relation Network for Few-Shot Learning (Few-Shot Learning part)
关键参数与规格
关键参数与规格
参数
值
语言
Jupyter Notebook
类别
Model Development
子类别
Architecture
星标数
1,081
分叉数
187
贡献者
1
创建日期
2019-09-09
更新日期
2026-09-19
1 天星标数
0
7 天星标数
0
排名
11,709
上次排名
11,638
排名变化
-71
7 天星标排名
13,110
上次 7 天星标排名
13,131
7 天星标排名变化
21
总星标排名
10,507
上次总星标排名
10,494
总星标排名变化
-13
国家
South Korea
README 摘录
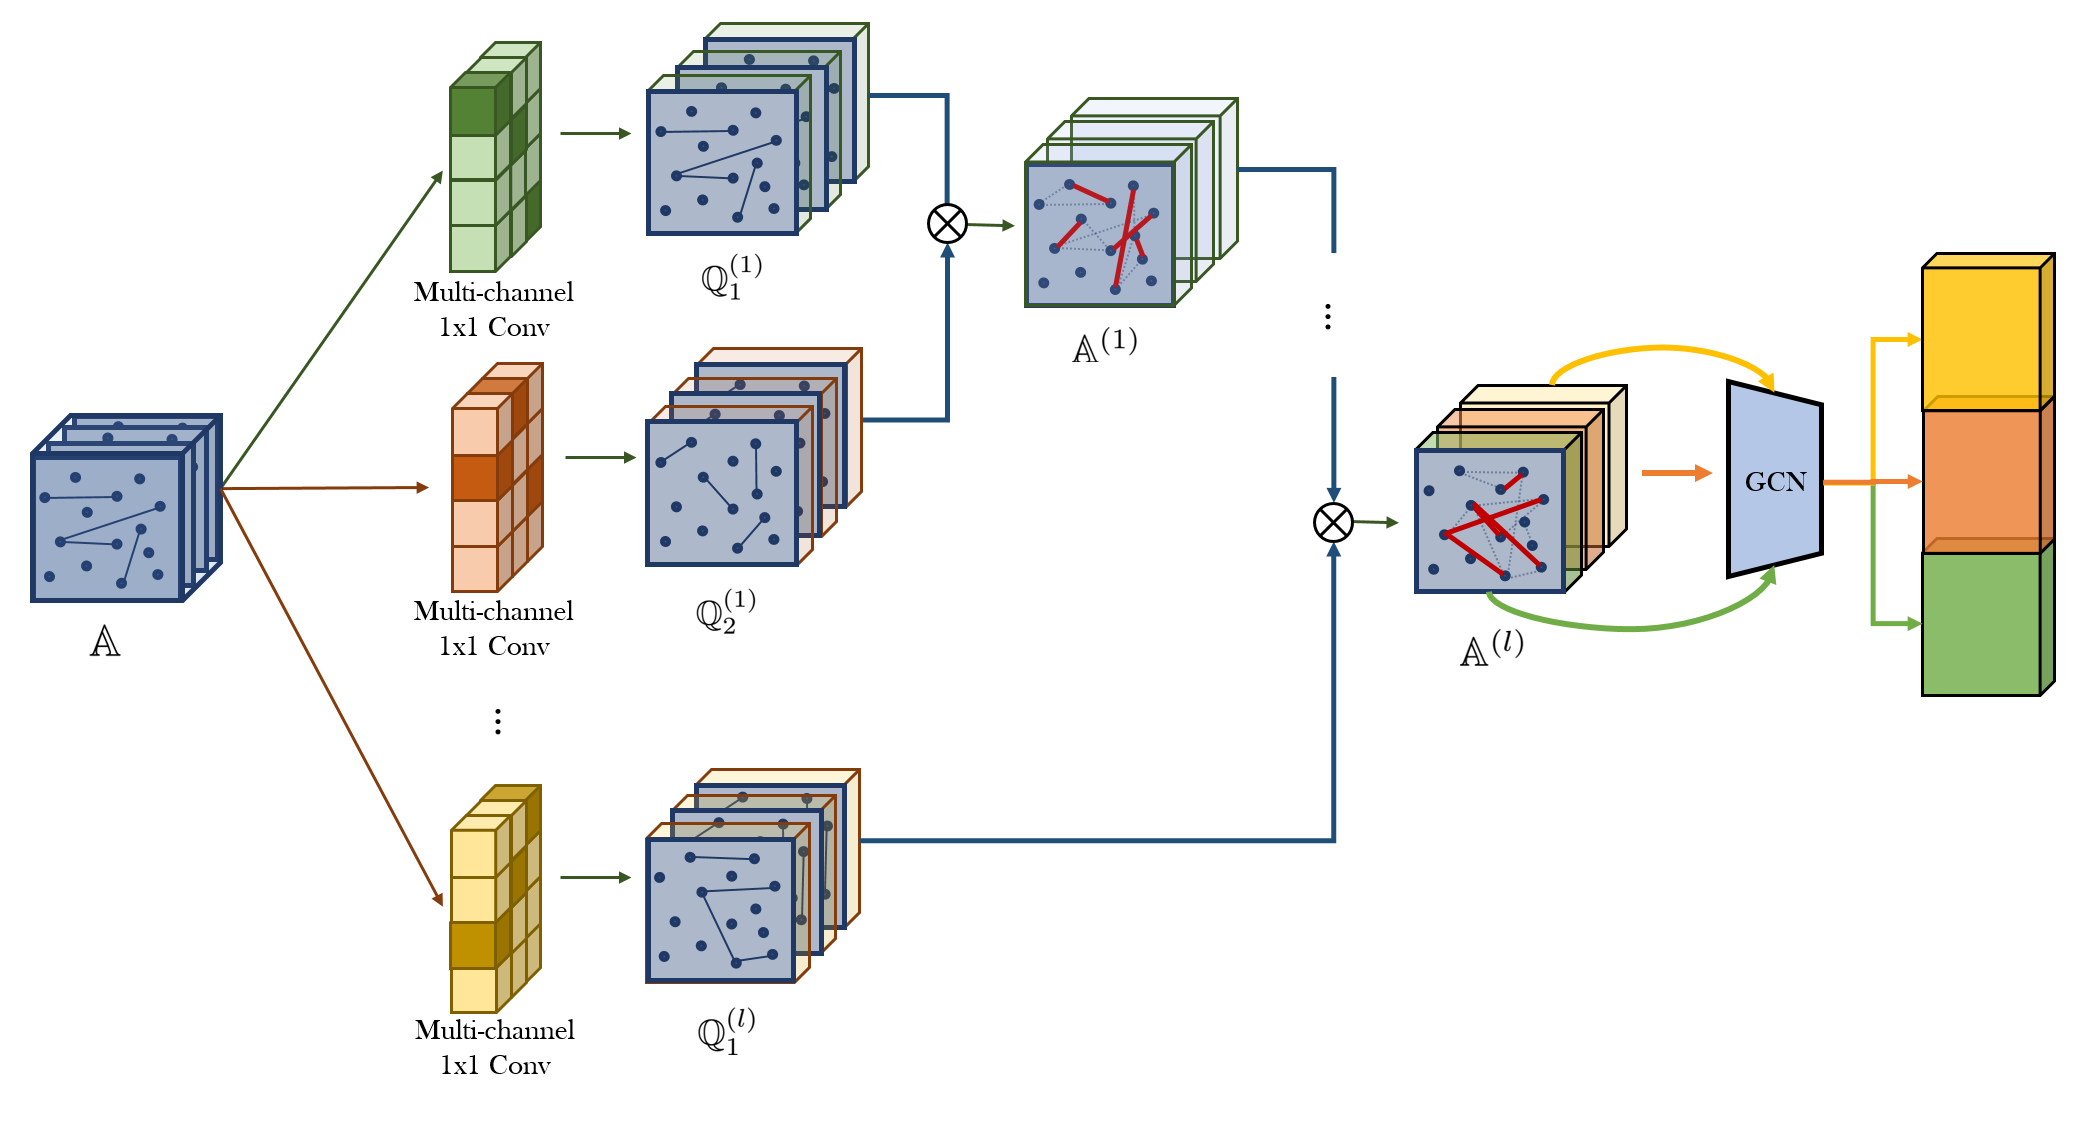
Graph Transformer Networks This repository is the implementation of Graph Transformer Networks(GTN) and Fast Graph Transformer Networks with Non-local Operations (FastGTN). Seongjun Yun, Minbyul Jeong, Raehyun Kim, Jaewoo Kang, Hyunwoo J. Kim, Graph Transformer Networks, In Advances in Neural Information Processing Systems (NeurIPS 2019). Seongjun Yun, Minbyul Jeong, Sungdong Yoo, Seunghun Lee, Sean S, Yi, Raehyun Kim, Jaewoo Kang, Hyunwoo J. Kim, Graph Transformer Networks: Learning meta-path graphs to improve GNNs, Neural Networks 2022. Updates \[**Sep 19
, 2022**\] We released the source code of our FastGTN with non-local operations), which improves GTN's scalability (Fast) and performance (non-local operations). \[**Sep 19, 2022**\] We updated the source code of our GTNs to address the issue where the latest version of torch_geometric removed the backward() of the multiplication of sparse matrices (spspmm). To be specific, we implemented the multiplication of sparse matrices using pytorch. Installation Install pytorch Install torch_geometric To run the previous version of GTN
(in prev_GTN folder), ** The latest version of torch_geometric removed the backward() of the multiplication of sparse matrices (spspmm), so to solve the problem, we uploaded the old version of torch-sparse with backward() on pip under the name torch-sparse-old. Data Preprocessing We used datasets from Heterogeneous Graph Attention Networks (Xiao Wang et al. ) and uploaded the preprocessing code of acm data as an example. Running the code *** To check the best performance of GTN in DBLP
and ACM datasets, we recommend running the GTN in OpenHGNN implemented with the DGL library. sparsemm requires more memory than the existing torch_sparse. spspmm, it was not possible to run the best case with num_layer > 1 in DBLP and ACM datasets. Download datasets (DBLP, ACM, IMDB) from this link and extract data. DBLP ACM IMDB Citation If this work is useful for your research, please cite our GTN and FastGTN:
Seongjun Yun, Minbyul Jeong, Raehyun Kim, Jaewoo Kang, Hyunwoo J. Kim, Graph Transformer Networks, In Advances in Neural Information Processing Systems (NeurIPS 2019).
Seongjun Yun, Minbyul Jeong, Sungdong Yoo, Seunghun Lee, Sean S, Yi, Raehyun Kim, Jaewoo Kang, Hyunwoo J. Kim, Graph Transformer Networks: Learning meta-path graphs to improve
GNNs, Neural Networks 2022.
Updates
[Sep 19, 2022] We released the source code of our FastGTN with non-local operations, which improves GTN's scalability (Fast) and performance (non-local operations).
[Sep 19, 2022] We updated the source code of our GTNs to address the issue where the latest version of torch_geometric removed the backward() of the multiplication of sparse matrices (spspmm). To be specific, we implemented the multiplication of sparse matrices using pytorch.sparse.mm that includes backward() operation.
To run the previous version of GTN (in prev_GTN folder),
$ pip install torch-sparse-old
** The latest version of torch_geometric removed the backward() of the multiplication of sparse matrices (spspmm), so to solve the problem, we uploaded the old version of torch-sparse with backward() on pip under the name torch-sparse-old.
*** To check the best performance of GTN in DBLP and ACM datasets, we recommend running the GTN in OpenHGNN implemented with the DGL library. Since the newly used torch.sparsemm requires more memory than the existing torch_sparse.spspmm, it was not possible to run the best case with num_layer > 1 in DBLP and ACM datasets.
$ mkdir data
$ cd data
Download datasets (DBLP, ACM, IMDB) from this link and extract data.zip into data folder.
If this work is useful for your research, please cite our GTN and FastGTN:
@inproceedings{yun2019GTN,
  title={Graph Transformer Networks},
  author={Yun, Seongjun and Jeong, Minbyul and Kim, Raehyun and Kang, Jaewoo and Kim, Hyunwoo J},
  booktitle={Advances in Neural Information Processing Systems},
  pages={11960--11970},
  year={2019}
}
@article{yun2022FastGTN,
title = {Graph Transformer Networks: Learning meta-path graphs to improve GNNs},
journal = {Neural Networks},
volume = {153},
pages = {104-119},
year = {2022},
}