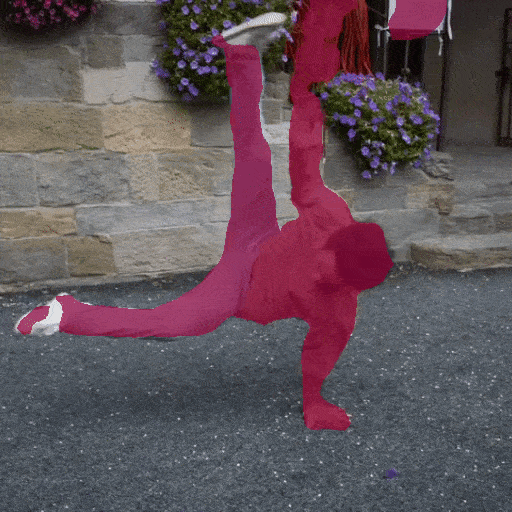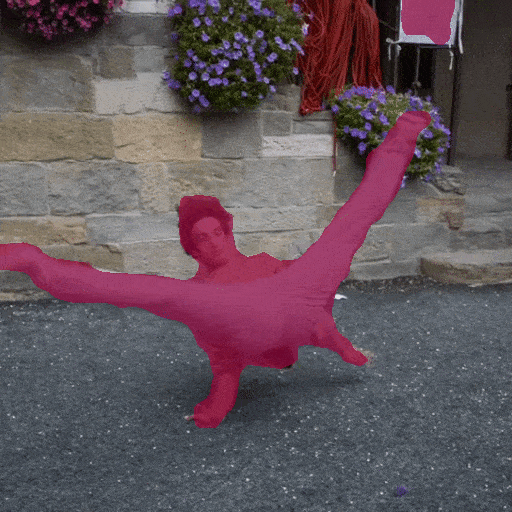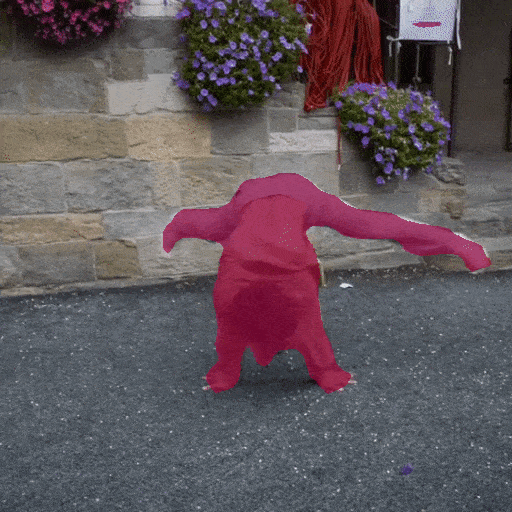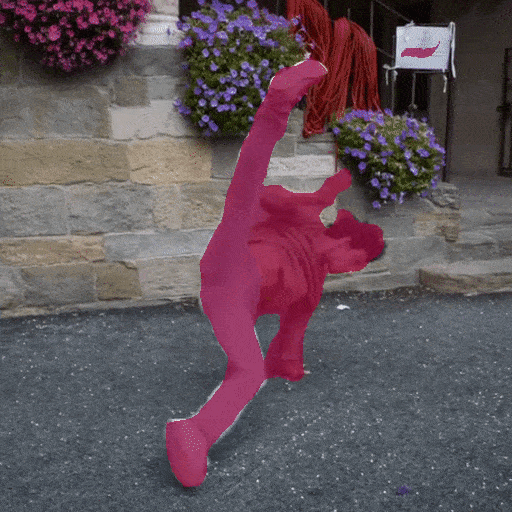← 开源
rstrudel

segmenter

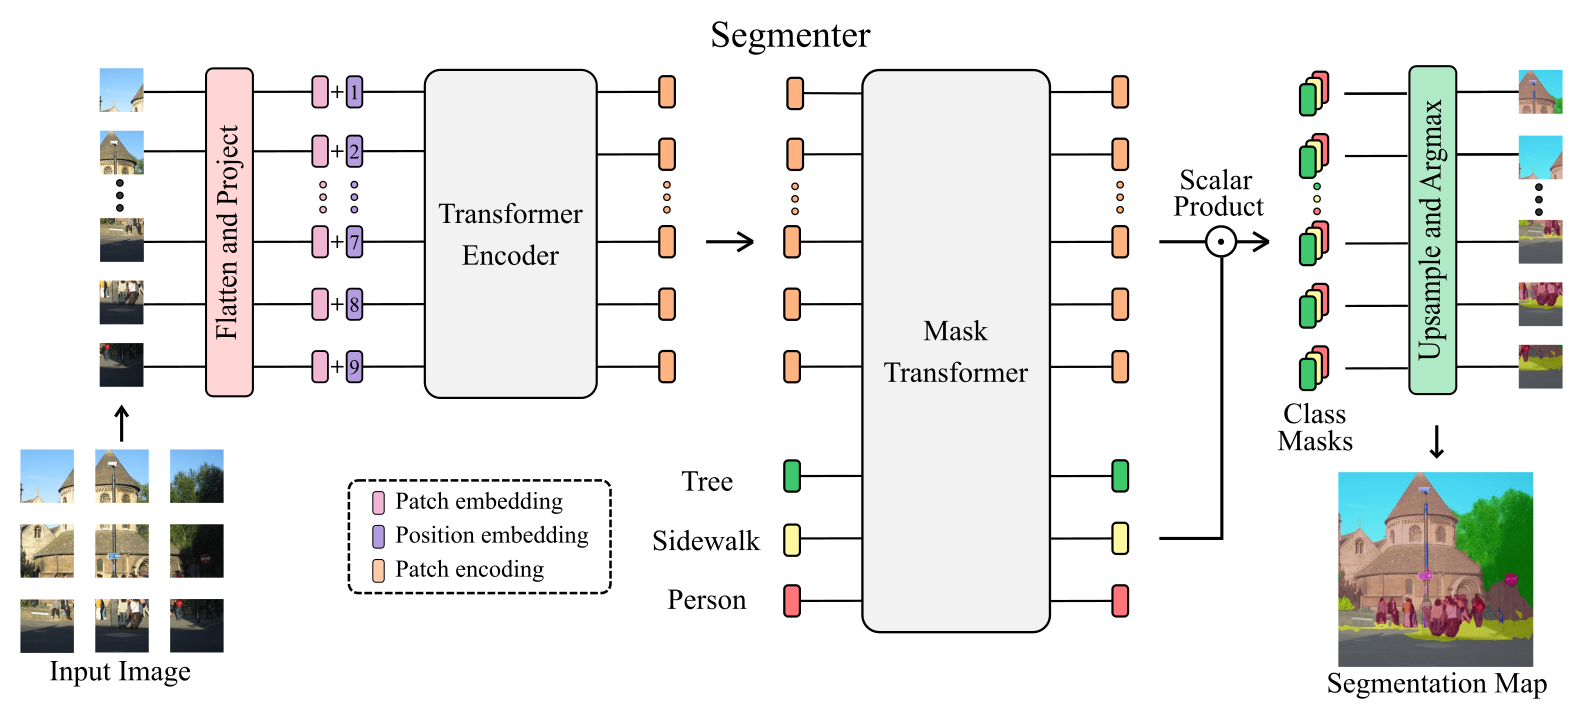
[ICCV2021] Official PyTorch implementation of Segmenter: Transformer for Semantic Segmentation
ModelsVision modelsPython
在 GitHub 打开
增长势头
+024 小时新增 Star0.0%
906
Star
182
Fork
+0
本周
3
贡献者
创建于 2021-05-11 · 更新于 2026-10-02 · 今日第 12740 名
主要开发者
rstrudelrjgpinelacairncross

rstrudel/segmenter 排名第 12,740,有 906 个星标。

同类别比较

rstrudel/segmenter 排名第 12,740,此处有 8 个同类条目;google-deepmind/alphagenome_research 排名第 12,747。

同类别比较
名称排名指标
facebookresearch/cwm12,697
语言:
Python
星标数:
910
分叉数:
74
简介:
Research code artifacts for Code World Model (CWM) including inference tools, reproducibility, and documentation.
reedscot/icml201612,704
语言:
Lua
星标数:
910
分叉数:
216
简介:
Generative Adversarial Text-to-Image Synthesis
OpenDriveLab/Vista12,719
语言:
Python
星标数:
908
分叉数:
63
简介:
[NeurIPS 2024] A Generalizable World Model for Autonomous Driving
facebookresearch/SpanBERT12,727
语言:
Python
星标数:
907
分叉数:
176
简介:
Code for using and evaluating SpanBERT.
google-deepmind/alphagenome_research12,747
语言:
Python
星标数:
905
分叉数:
159
简介:
Research code accompanying AlphaGenome
hustvl/YOLOS12,772
语言:
Jupyter Notebook
星标数:
903
分叉数:
125
简介:
[NeurIPS 2021] You Only Look at One Sequence
EvolvingLMMs-Lab/NEO12,786
语言:
Python
星标数:
901
分叉数:
33
简介:
NEO Series: Native Vision-Language Models from First Principles
FudanDISC/DISC-FinLLM12,819
语言:
Python
星标数:
896
分叉数:
97
简介:
DISC-FinLLM,中文金融大语言模型(LLM),旨在为用户提供金融场景下专业、智能、全面的金融咨询服务。DISC-FinLLM, a Chinese financial large language model (LLM) designed to provide users with professional, intelligent, and comprehensive financial consulting services in financial scenarios.
关键参数与规格
关键参数与规格
参数值
语言Python
类别Models
子类别Vision models
星标数906
分叉数182
贡献者3
创建日期2021-05-11
更新日期2026-10-02
1 天星标数0
7 天星标数0
排名12,740
上次排名12,647
排名变化-93
7 天星标排名13,585
上次 7 天星标排名13,598
7 天星标排名变化13
总星标排名12,016
上次总星标排名11,994
总星标排名变化-22
国家France
README 摘录

Segmenter: Transformer for Semantic Segmentation Segmenter: Transformer for Semantic Segmentation by Robin Strudel*, Ricardo Garcia*, Ivan Laptev and Cordelia Schmid, ICCV 2021. *Equal Contribution 🔥 **Segmenter is now available on MMSegmentation. ** Installation Define os environment variables pointing to your checkpoint and dataset directory, put in your : Install PyTorch 1. To download ADE20K, use the following command: Model Zoo We release models with a Vision Transformer backbone initialized from the improved ViT models. ADE20K Segmenter models with ViT backbone: Segmenter models with

DeiT backbone: Pascal Context Cityscapes Inference Download one checkpoint with its configuration in a common folder, for example . You can generate segmentation maps from your own data with: To evaluate on ADE20K, run the command: Train Train on ADE20K on a single GPU: To train , simply set as backbone and launch the above command using a minimum of 4 V100 GPUs (~12 minutes per epoch) and up to 8 V100 GPUs (~7 minutes per epoch). The code uses SLURM environment

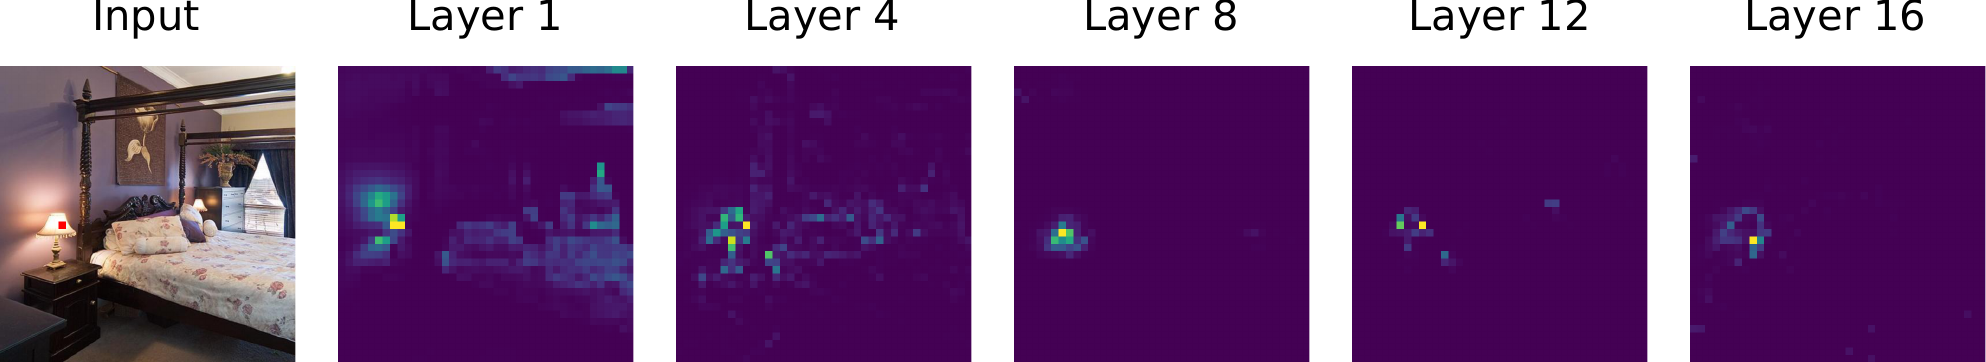
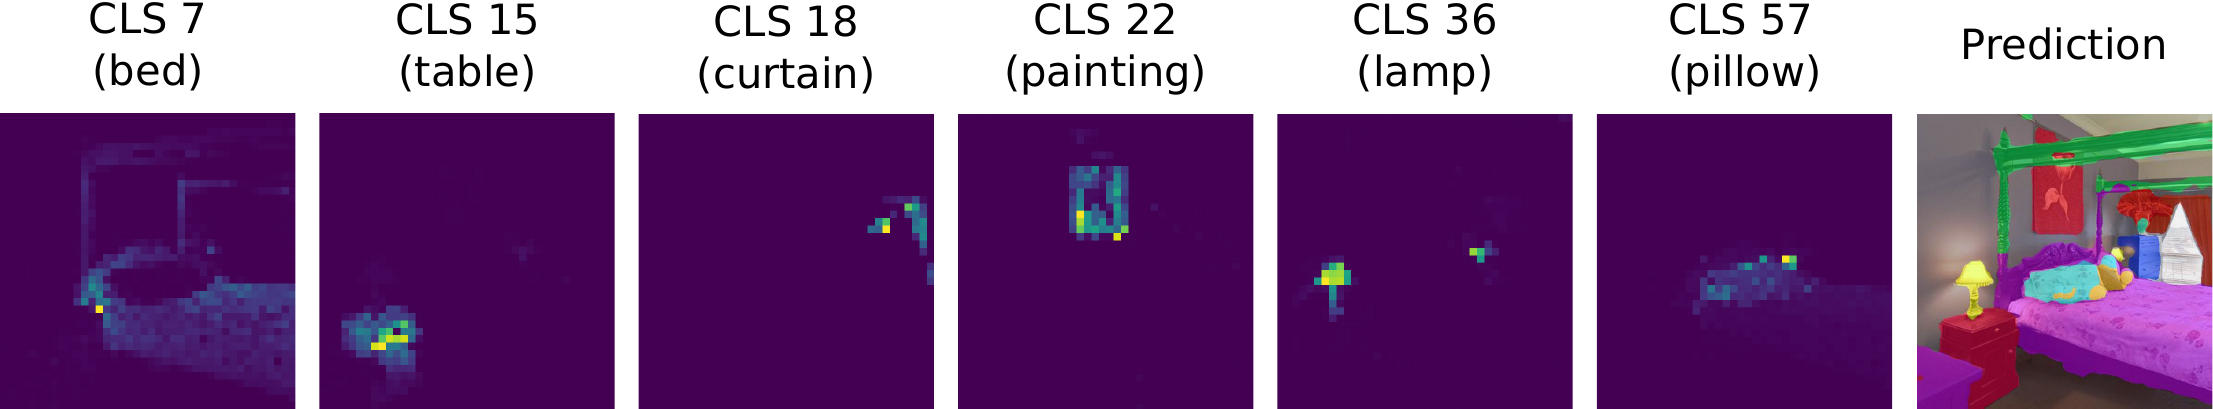
variables. Logs To plot the logs of your experiments, you can use with located in with the path to your experiments logs: Attention Maps To visualize the attention maps for encoder layer 0 and patch , you can use: Different options are provided to select the generated attention maps: or : Select encoder or decoder attention maps respectively. or : generates attention maps for the patch with coordinates . combined with generates attention maps for the CLS token of the encoder. combined with generates

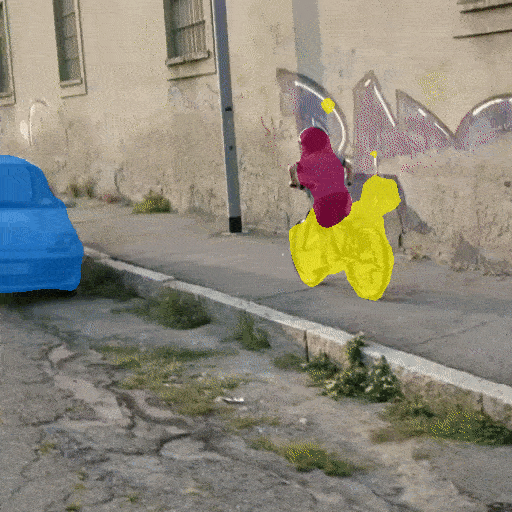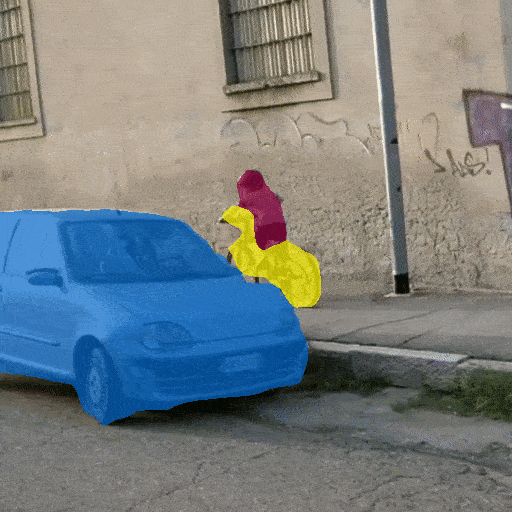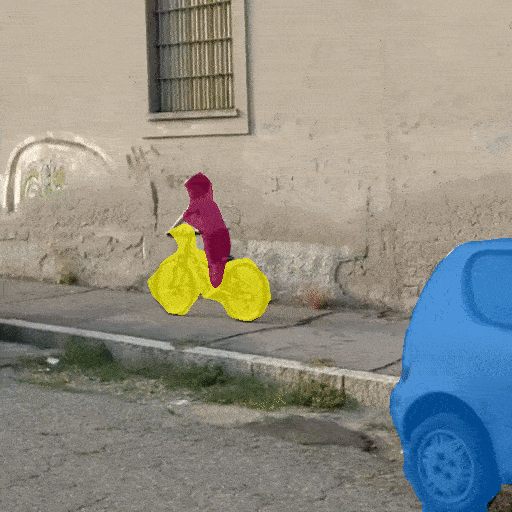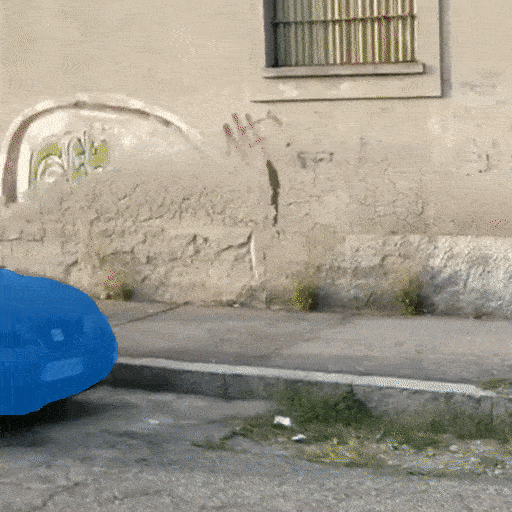
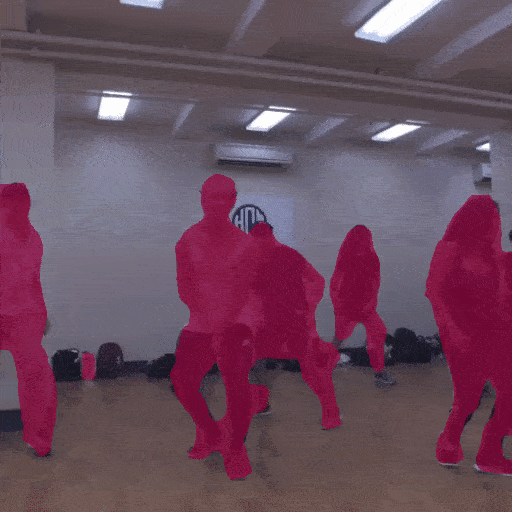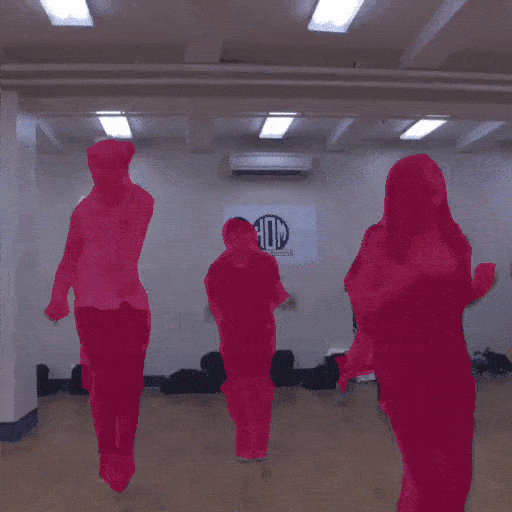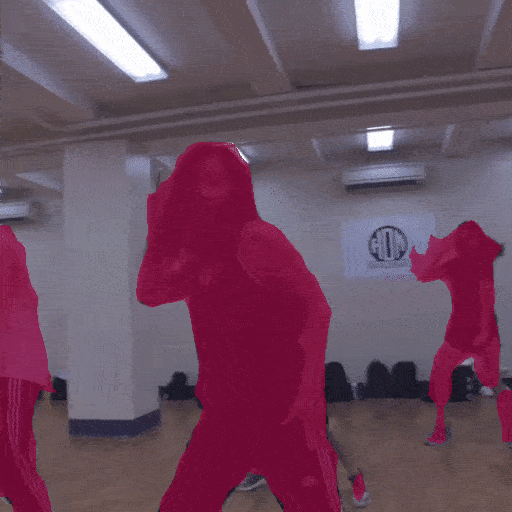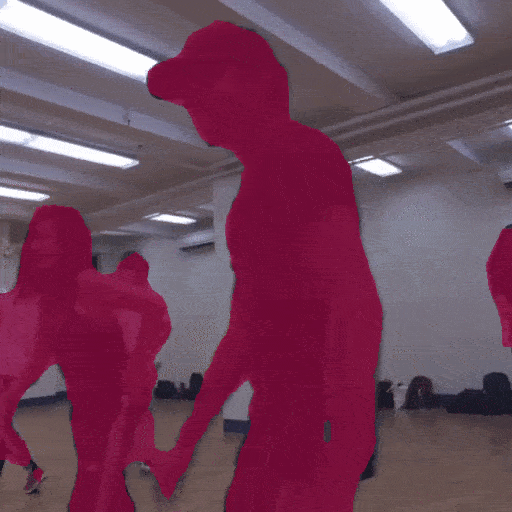
maps for each class embedding of the decoder. and : Coordinates of the patch to draw attention maps from. : Select the layer for which the attention maps are generated. For example, to generate attention maps for the decoder class embeddings, you can use: Attention maps for patch in encoder layers 1, 4, 8, 12 and 16: Attention maps for the class embeddings in decoder layer 0: Video Segmentation Zero shot video segmentation on DAVIS video dataset with Seg-B-Mask/16

model trained on ADE20K. BibTex Acknowledgements The Vision Transformer code is based on timm library and the semantic segmentation training and evaluation pipeline is using mmsegmentation.

常见问题

记录了多少星标和分叉?

rstrudel/segmenter 有 906 个星标和 182 个分叉。

仓库排名是多少?

rstrudel/segmenter 排名第 12,740。

记录的语言和类别是什么?

rstrudel/segmenter 有 906 个星标,语言为 Python,类别为 Models。

哪个仓库排名最接近?

rstrudel/segmenter 与 google-deepmind/alphagenome_research 比较,后者排名第 12,747,有 905 个星标。

README

Segmenter: Transformer for Semantic Segmentation

Segmenter: Transformer for Semantic Segmentation by Robin Strudel*, Ricardo Garcia*, Ivan Laptev and Cordelia Schmid, ICCV 2021.

*Equal Contribution

🔥 Segmenter is now available on MMSegmentation.

Installation

Define os environment variables pointing to your checkpoint and dataset directory, put in your .bashrc:

export DATASET=/path/to/dataset/dir

Install PyTorch 1.9 then pip install . at the root of this repository.

To download ADE20K, use the following command:

python -m segm.scripts.prepare_ade20k $DATASET

Model Zoo

We release models with a Vision Transformer backbone initialized from the improved ViT models.

ADE20K

Segmenter models with ViT backbone:

Name

mIoU (SS/MS)

params

Resolution

FPS

Download

Seg-T-Mask/16

38.1 / 38.8

7M

512x512

52.4

model

config

log

Seg-S-Mask/16

45.3 / 46.9

27M

512x512

34.8

model

config

log

Seg-B-Mask/16

48.5 / 50.0

106M

512x512

24.1

model

config

log

Seg-B/8

49.5 / 50.5

89M

512x512

4.2

model

config

log

Seg-L-Mask/16

51.8 / 53.6

334M

640x640

model

config

log

Segmenter models with DeiT backbone:

Name

mIoU (SS/MS)

params

Resolution

FPS

Download

Seg-B†/16

47.1 / 48.1

87M

512x512

27.3

model

config

log

Seg-B†-Mask/16

48.7 / 50.1

106M

512x512

24.1

model

config

log

Pascal Context

Name

mIoU (SS/MS)

params

Resolution

FPS

Download

Seg-L-Mask/16

58.1 / 59.0

334M

480x480

model

config

log

Cityscapes

Name

mIoU (SS/MS)

params

Resolution

FPS

Download

Seg-L-Mask/16

79.1 / 81.3

322M

768x768

model

config

log

Inference

Download one checkpoint with its configuration in a common folder, for example seg_tiny_mask.

You can generate segmentation maps from your own data with:

python -m segm.inference --model-path seg_tiny_mask/checkpoint.pth -i images/ -o segmaps/ 

To evaluate on ADE20K, run the command:

# single-scale evaluation:
python -m segm.eval.miou seg_tiny_mask/checkpoint.pth ade20k --singlescale
# multi-scale evaluation:
python -m segm.eval.miou seg_tiny_mask/checkpoint.pth ade20k --multiscale

Train

Train Seg-T-Mask/16 on ADE20K on a single GPU:

python -m segm.train --log-dir seg_tiny_mask --dataset ade20k \
  --backbone vit_tiny_patch16_384 --decoder mask_transformer

To train Seg-B-Mask/16, simply set vit_base_patch16_384 as backbone and launch the above command using a minimum of 4 V100 GPUs (~12 minutes per epoch) and up to 8 V100 GPUs (~7 minutes per epoch). The code uses SLURM environment variables.

Logs

To plot the logs of your experiments, you can use

python -m segm.utils.logs logs.yml

with logs.yml located in utils/ with the path to your experiments logs:

root: /path/to/checkpoints/
logs:
  seg-t: seg_tiny_mask/log.txt
  seg-b: seg_base_mask/log.txt

Attention Maps

To visualize the attention maps for Seg-T-Mask/16 encoder layer 0 and patch (0, 21), you can use:

python -m segm.scripts.show_attn_map seg_tiny_mask/checkpoint.pth \ 
images/im0.jpg output_dir/ --layer-id 0 --x-patch 0 --y-patch 21 --enc

Different options are provided to select the generated attention maps:

  • --enc or --dec: Select encoder or decoder attention maps respectively.
  • --patch or --cls: --patch generates attention maps for the patch with coordinates (x_patch, y_patch). --cls combined with --enc generates attention maps for the CLS token of the encoder. --cls combined with --dec generates maps for each class embedding of the decoder.
  • --x-patch and --y-patch: Coordinates of the patch to draw attention maps from. This flag is ignored when --cls is used.
  • --layer-id: Select the layer for which the attention maps are generated.

For example, to generate attention maps for the decoder class embeddings, you can use:

python -m segm.scripts.show_attn_map seg_tiny_mask/checkpoint.pth \
images/im0.jpg output_dir/ --layer-id 0 --dec --cls

Attention maps for patch (0, 21) in Seg-L-Mask/16 encoder layers 1, 4, 8, 12 and 16:
Attention maps for the class embeddings in Seg-L-Mask/16 decoder layer 0:
Video Segmentation

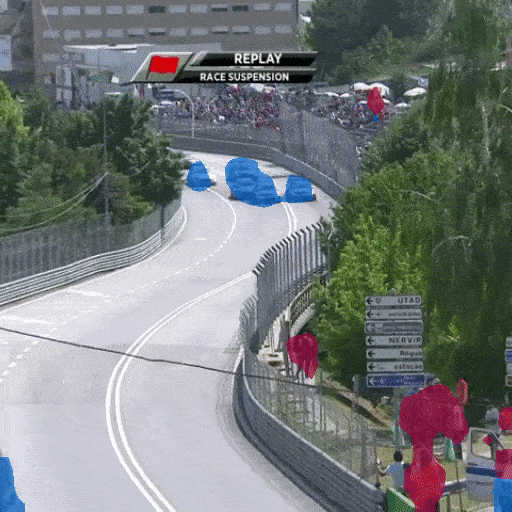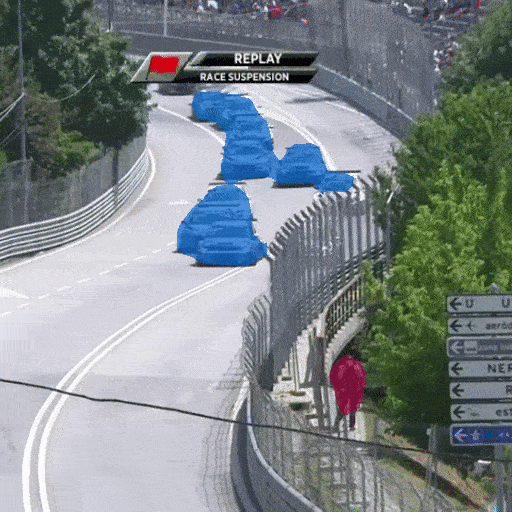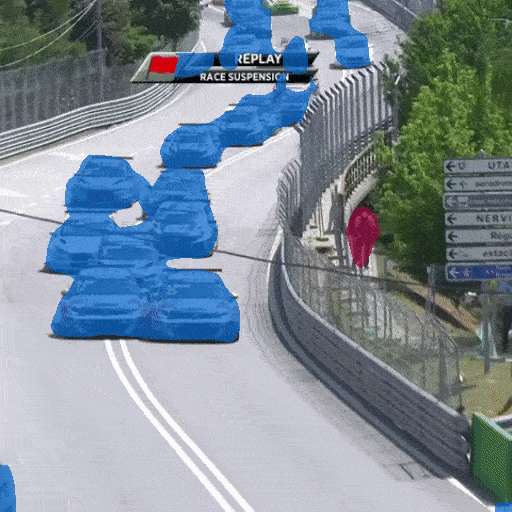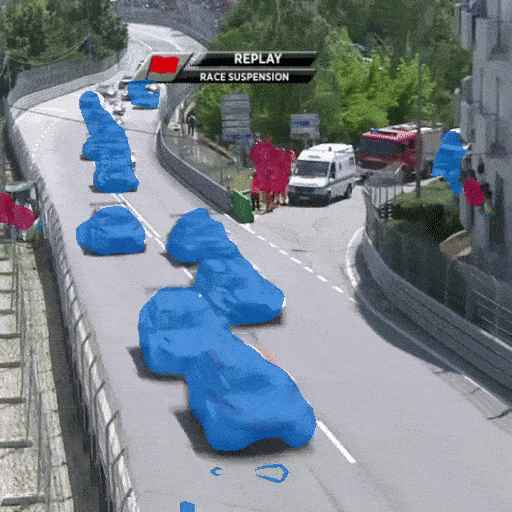
Zero shot video segmentation on DAVIS video dataset with Seg-B-Mask/16 model trained on ADE20K.
BibTex

@article{strudel2021,
  title={Segmenter: Transformer for Semantic Segmentation},
  author={Strudel, Robin and Garcia, Ricardo and Laptev, Ivan and Schmid, Cordelia},
  journal={arXiv preprint arXiv:2105.05633},
  year={2021}
}

Acknowledgements

The Vision Transformer code is based on timm library and the semantic segmentation training and evaluation pipeline is using mmsegmentation.

排名相邻
同类项目