← 开源
reriiasu

speech-to-text

Real-time transcription using faster-whisper
ApplicationsPersonalHTML
在 GitHub 打开
增长势头
+024 小时新增 Star0.0%
613
Star
99
Fork
+0
本周
1
贡献者
创建于 2023-03-30 · 更新于 2026-09-30 · 今日第 16075 名
主要开发者

reriiasu/speech-to-text 排名第 16,075,有 613 个星标。

同类别比较

reriiasu/speech-to-text 排名第 16,075,此处有 8 个同类条目;sdcb/chats 排名第 16,076。

同类别比较
名称排名指标
hofstadter-io/hof16,056
语言:
Go
星标数:
614
分叉数:
47
简介:
A developer experience centered on CUE. Unifies schemas, data models, deterministic and agentic code generation, workflow and task engine, dagger powered environments, coding assistant, and vscode extension; woven together on the CUE lattice. Squint harder if you can't see the cube :]
timmyy123/LLM-Hub16,060
语言:
C
星标数:
614
分叉数:
137
简介:
Local LLM, image&video&music generator, run codex with local models on your phone
abielzulio/chatgpt-raycast16,066
语言:
TypeScript
星标数:
613
分叉数:
50
简介:
ChatGPT raycast extension
mololab/json-translator16,071
语言:
TypeScript
星标数:
613
分叉数:
81
简介:
jsontt 💡 - AI JSON Translator with GPT / Gemma / Mixtral / llama + other FREE translation modules to translate your json/yaml files into other languages ✅ Check Readme ✌ Supports GPT / Gemma / Mixtral / llama / DeepL / Google / Bing / Libre / Argos
sdcb/chats16,076
语言:
C#
星标数:
613
分叉数:
110
简介:
A powerful and flexible frontend & AI gateway for large language models, supporting 21+ mainstream AI model providers.
bradleyboyuyang/ML-HFT16,090
语言:
Jupyter Notebook
星标数:
612
分叉数:
144
简介:
High frequency trading (HFT) framework built for futures using machine learning and deep learning techniques
cpaczek/any-buddy16,091
语言:
TypeScript
星标数:
612
分叉数:
54
简介:
Hack Claude Code to get any buddy you want
criptogus/HermesOffice16,092
语言:
TypeScript
星标数:
612
分叉数:
83
关键参数与规格
关键参数与规格
参数值
语言HTML
类别Applications
子类别Personal
关键词Speech-to-text
星标数613
分叉数99
贡献者1
创建日期2023-03-30
更新日期2026-09-30
1 天星标数0
7 天星标数0
排名16,075
上次排名15,874
排名变化-201
7 天星标排名15,331
上次 7 天星标排名15,340
7 天星标排名变化9
总星标排名16,500
上次总星标排名16,472
总星标排名变化-28
README 摘录

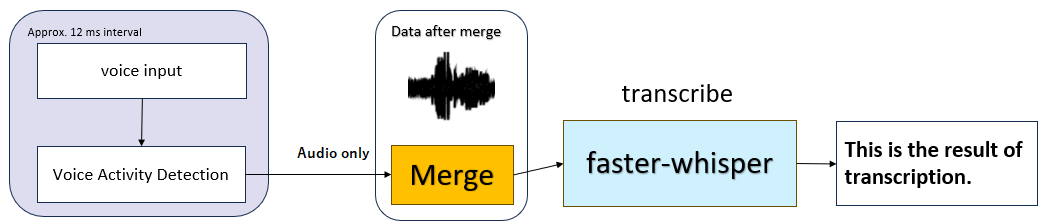
speech-to-text Real-time transcription using faster-whisper Accepts audio input from a microphone using a Sounddevice. By using Silero VAD(Voice Activity Detection), silent parts are detected and recognized as one voice data. This audio data is converted to text using Faster-Whisper. The HTML-based GUI allows you to check the transcription results and make detailed settings for the faster-whisper. Transcription speed If the sentences are well separated, the transcription takes less than a second. " It
will perform the following actions: 1. Select "App Settings" and configure the settings. Select "Model Settings" and configure the settings. Select "Transcribe Settings" and configure the settings. Select "VAD Settings" and configure the settings. Start Transcription If you use the OpenAI API for text proofreading, set OPENAI_API_KEY as an environment variable. Notes If you select local_model in "Model size or path", the model with the same name in the local folder will be referenced. Demo News 2023
-06-26 Add generate audio files from input sound. Add synchronize audio files with transcription. 2023-06-29 Add transcription from audio files. (only wav format) 2023-07-03 Add Send transcription results from a WebSocket server to a WebSocket client. Example of use: Display subtitles in live streaming. 2023-07-05 Add generate SRT files from transcription result. 2023-07-08 Add support for mp3, ogg, and other audio files. Add setting to include non-speech data in buffer

. While this will increase memory usage, it will improve transcription accuracy. 2023-07-09 Add non-speech threshold setting. 2023-07-11 Add Text proofreading option via OpenAI API. 2023-07-12 Add feature where audio and word highlighting are synchronized. 2023-10-01 Support for repetition_penalty and no_repeat_ngram_size in transcribe_settings. Update faster-whisper requirement to include the latest version "0. 2024-07-23 Support "Faster Distil-Whisper" model. Update faster-whisper requirement to include

the latest version "1. [x] Use Silero VAD [x] Allow local parameters to be set from the GUI. [x] Supports additional options in faster-whisper 0.

常见问题

记录了多少星标和分叉?

reriiasu/speech-to-text 有 613 个星标和 99 个分叉。

仓库排名是多少?

reriiasu/speech-to-text 排名第 16,075。

记录的语言和类别是什么?

reriiasu/speech-to-text 有 613 个星标,语言为 HTML,类别为 Applications。

哪个仓库排名最接近?

reriiasu/speech-to-text 与 sdcb/chats 比较,后者排名第 16,076,有 613 个星标。

README

speech-to-text

Real-time transcription using faster-whisper

Accepts audio input from a microphone using a Sounddevice. By using Silero VAD(Voice Activity Detection), silent parts are detected and recognized as one voice data. This audio data is converted to text using Faster-Whisper.

The HTML-based GUI allows you to check the transcription results and make detailed settings for the faster-whisper.

Transcription speed

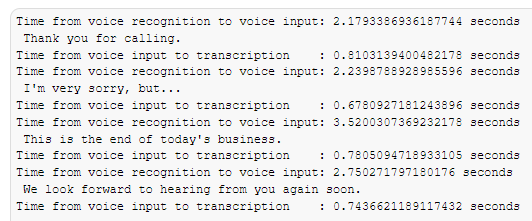
If the sentences are well separated, the transcription takes less than a second.

Large-v2 model
Executed with CUDA 11.7 on a NVIDIA GeForce RTX 3060 12GB.

Installation

  1. pip install .

for Windows

Please execute "run.bat." It will perform the following actions:

  1. Create a Python virtual environment.
  2. Install pip packages.
  3. Run speech_to_text.

Usage

  1. python -m speech_to_text
  2. Select "App Settings" and configure the settings.
  3. Select "Model Settings" and configure the settings.
  4. Select "Transcribe Settings" and configure the settings.
  5. Select "VAD Settings" and configure the settings.
  6. Start Transcription

If you use the OpenAI API for text proofreading, set OPENAI_API_KEY as an environment variable.

Notes

  • If you select local_model in "Model size or path", the model with the same name in the local folder will be referenced.

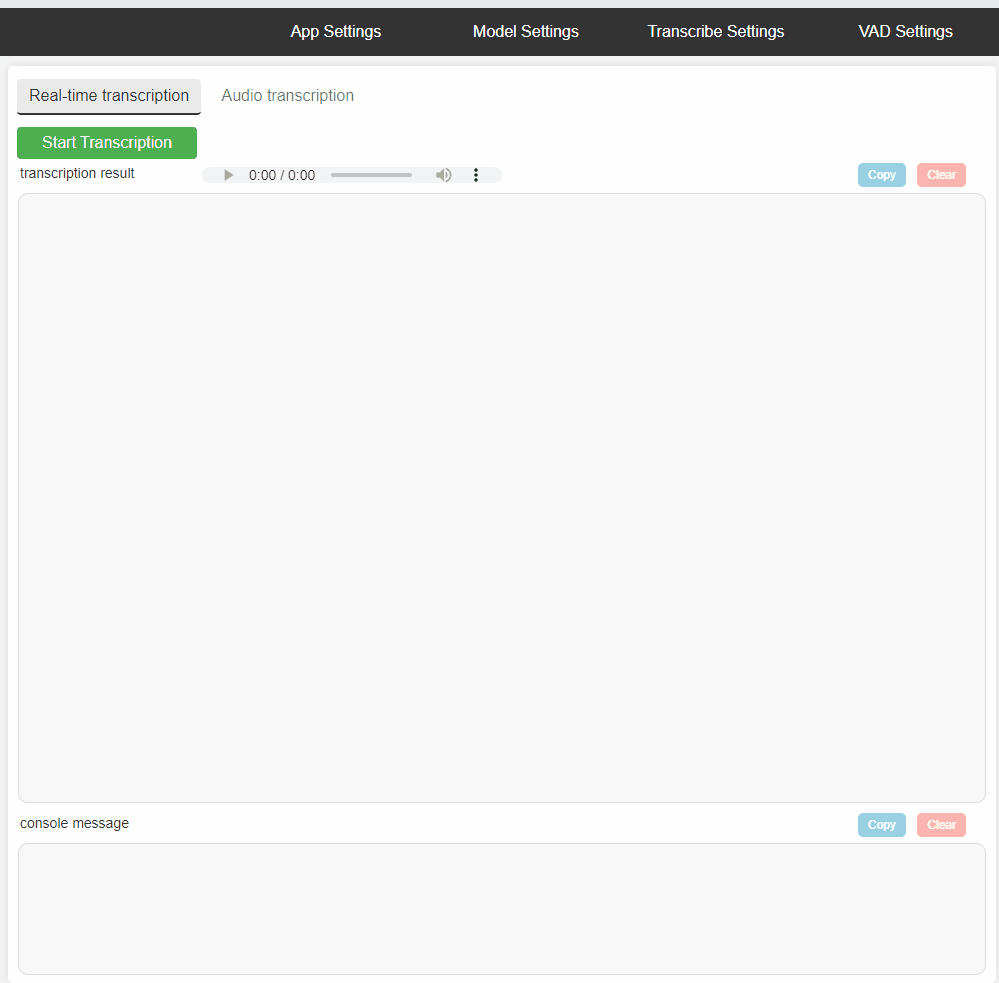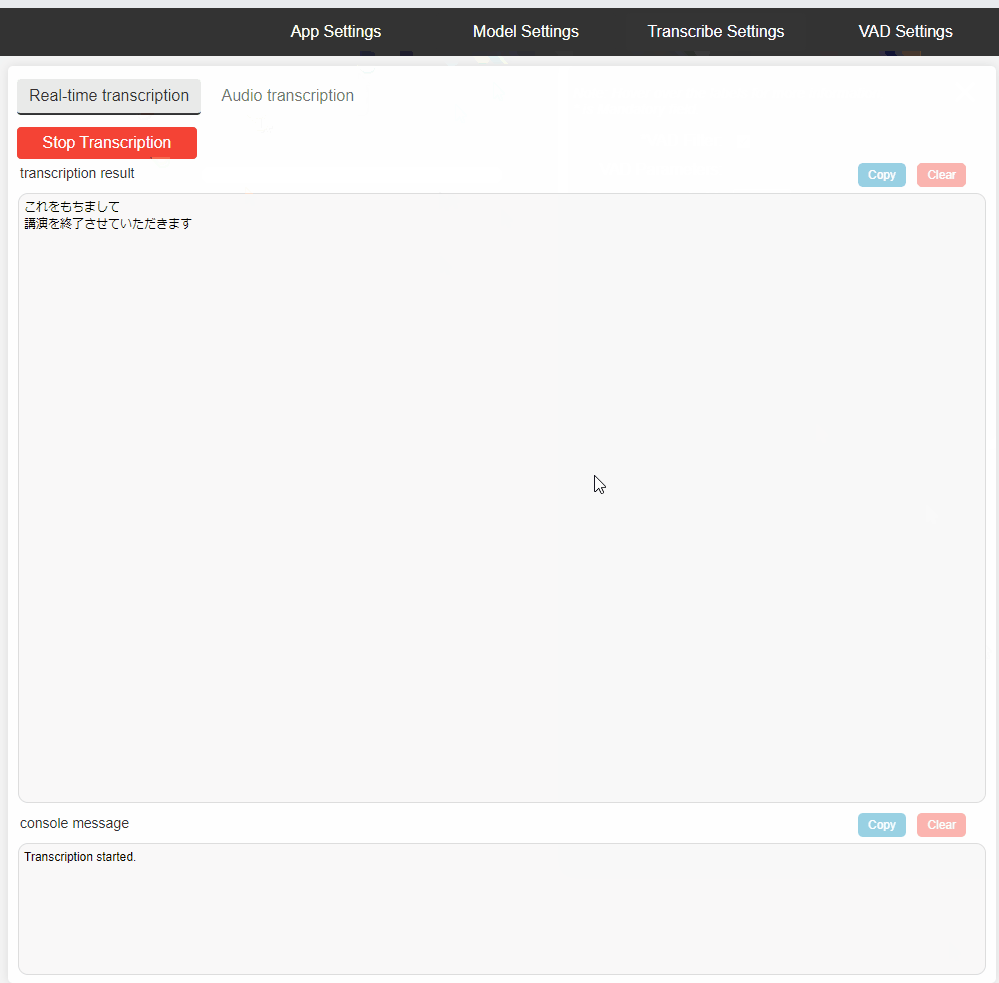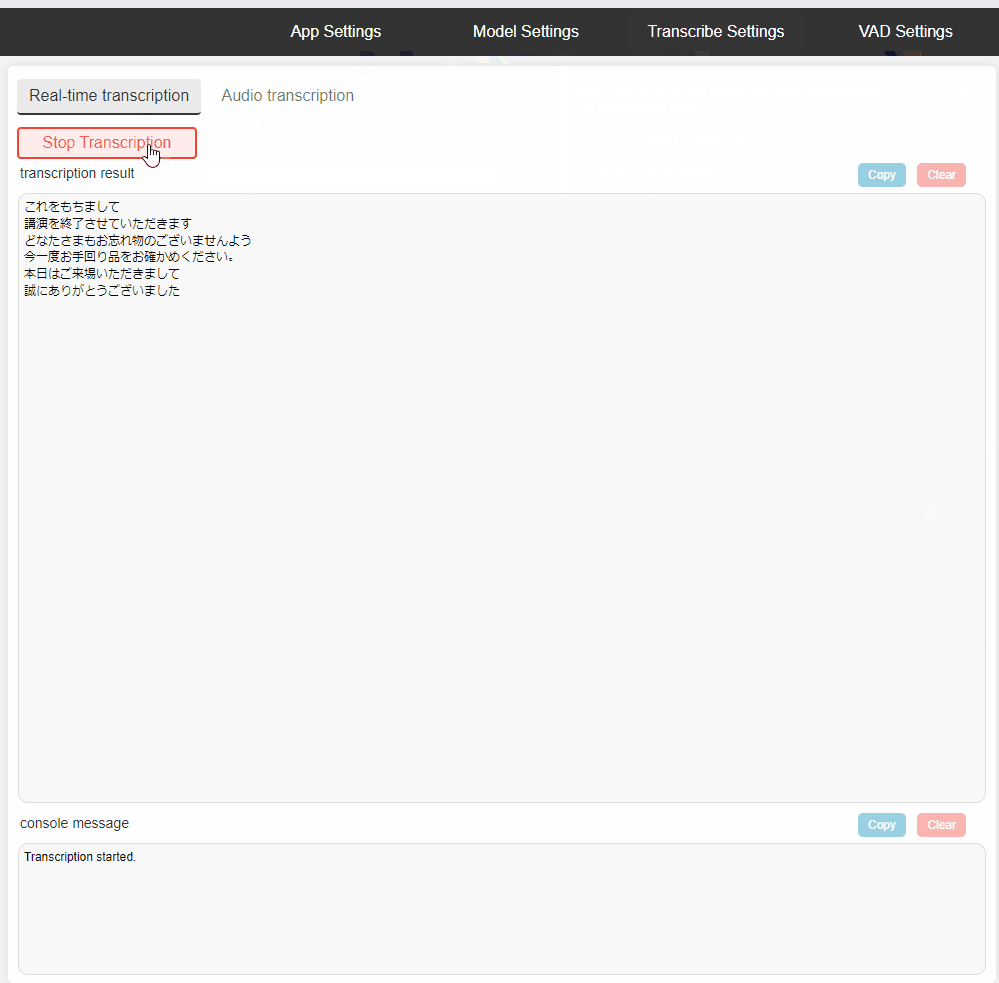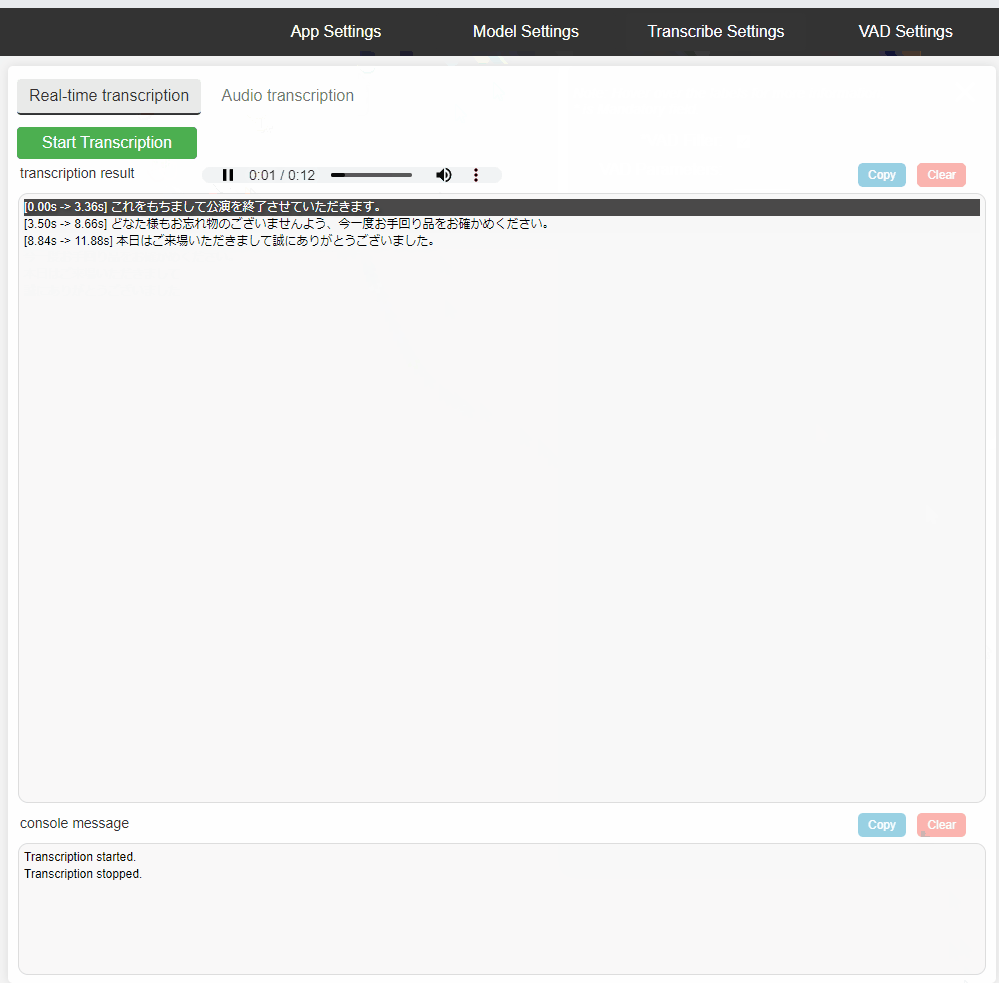
Demo

News

2023-06-26

  • Add generate audio files from input sound.
  • Add synchronize audio files with transcription.
    Audio and text highlighting are linked.

2023-06-29

  • Add transcription from audio files.(only wav format)

2023-07-03

  • Add Send transcription results from a WebSocket server to a WebSocket client.
    Example of use: Display subtitles in live streaming.

2023-07-05

  • Add generate SRT files from transcription result.

2023-07-08

  • Add support for mp3, ogg, and other audio files.
    Depends on Soundfile support.
  • Add setting to include non-speech data in buffer.
    While this will increase memory usage, it will improve transcription accuracy.

2023-07-09

  • Add non-speech threshold setting.

2023-07-11

  • Add Text proofreading option via OpenAI API.
    Transcription results can be proofread.

2023-07-12

  • Add feature where audio and word highlighting are synchronized.
    if Word Timestamps is true.

2023-10-01

  • Support for repetition_penalty and no_repeat_ngram_size in transcribe_settings.
  • Updating packages.

2023-11-27

  • Support "large-v3" model.
  • Update faster-whisper requirement to include the latest version "0.10.0".

2024-07-23

  • Support "Faster Distil-Whisper" model.
  • Update faster-whisper requirement to include the latest version "1.0.3".
  • Updating packages.
  • Add run.bat for Windows.

Todo

  • [x] Save and load previous settings.

  • [x] Use Silero VAD

  • [x] Allow local parameters to be set from the GUI.

  • [x] Supports additional options in faster-whisper 0.8.0

排名相邻
同类项目