← 开源
penghao-wu

vstar

PyTorch Implementation of "V* : Guided Visual Search as a Core Mechanism in Multimodal LLMs"

Model DevelopmentArchitecturePython
在 GitHub 打开
增长势头
+024 小时新增 Star0.0%
715
Star
43
Fork
+0
本周
2
贡献者
创建于 2023-12-15 · 更新于 2026-10-08 · 今日第 14642 名
主要开发者
penghao-wueltociear

penghao-wu/vstar 排名第 14,642,有 715 个星标。

同类别比较

penghao-wu/vstar 排名第 14,642,此处有 8 个同类条目;lich99/ChatGLM-finetune-LoRA 排名第 14,640。

同类别比较
名称排名指标
EndlessSora/focal-frequency-loss14,629
语言:
Python
星标数:
715
分叉数:
61
简介:
[ICCV 2021] Focal Frequency Loss for Image Reconstruction and Synthesis
SalesforceAIResearch/DiffusionDPO14,633
语言:
Python
星标数:
715
分叉数:
53
简介:
Code for "Diffusion Model Alignment Using Direct Preference Optimization"
labmlai/inspectus14,638
语言:
TypeScript
星标数:
715
分叉数:
34
简介:
LLM Analytics
lich99/ChatGLM-finetune-LoRA14,640
语言:
Jupyter Notebook
星标数:
715
分叉数:
62
简介:
Code for fintune ChatGLM-6b using low-rank adaptation (LoRA)
JulesBelveze/time-series-autoencoder14,645
语言:
Python
星标数:
714
分叉数:
69
简介:
PyTorch Dual-Attention LSTM-Autoencoder For Multivariate Time Series
MingyuJ666/Stockagent14,646
语言:
Python
星标数:
714
分叉数:
171
简介:
[TIST] Large Language Model-based Stock Trading in Simulated Real-world Environments
openspeech-team/openspeech14,656
语言:
Python
星标数:
714
分叉数:
115
简介:
Open-Source Toolkit for End-to-End Speech Recognition leveraging PyTorch-Lightning and Hydra.
LC1332/Chinese-alpaca-lora14,658
语言:
Jupyter Notebook
星标数:
713
分叉数:
81
简介:
骆驼:A Chinese finetuned instruction LLaMA. Developed by 陈启源 @ 华中师范大学 & 李鲁鲁 @ 商汤科技 & 冷子昂 @ 商汤科技
关键参数与规格
关键参数与规格
参数值
语言Python
类别Model Development
子类别Architecture
关键词Computer vision, Multimodal
星标数715
分叉数43
贡献者2
创建日期2023-12-15
更新日期2026-10-08
1 天星标数0
7 天星标数0
排名14,642
上次排名14,496
排名变化-146
7 天星标排名14,579
上次 7 天星标排名10,918
7 天星标排名变化-3,661
总星标排名14,645
上次总星标排名14,625
总星标排名变化-20
README 摘录

*V*\*: Guided Visual Search as a Core Mechanism in Multimodal LLMs Paper | Project Page | Online Demo Contents: 1. Acknowledgement Getting Started Installation Pre-trained Model The VQA LLM can be downloaded here. The visual search model can be downloaded here. Training Dataset The alignment stage of the VQA LLM uses the 558K subset of the LAION-CC-SBU dataset used by LLaVA which can be downloaded here. The instruction tuning stage requires several instruction tuning subsets which can be found

here. The instruction tuning data requires images from COCO-2014, COCO-2017, and GQA. After downloading them, organize the data following the structure below Demo You can launch a local Gradio demo after the installation by running . Note that the pre-trained model weights will be automatically downloaded if you have not downloaded them before. You are expected to see the web page below: Benchmark Our *V*\*Bench is available here. The benchmark contains folders for different subtasks. Within each

folder is a list of image files and annotation JSON files. The image and annotations files are paired according to the filename. The format of the annotation files is: Evaluation To evaluate our model on the *V*\*Bench benchmark, run To evaluate our visual search mechanism on the annotated targets from the *V*\*Bench benchmark, run The detailed evaluation results of our model can be found here. Training The training of the VQA LLM model includes two stages. For the

pre-training stage, enter the LLaVA folder and run For the instruction tuning stage, enter the LLaVA folder and run For the training data preparation and training procedures of our visual search model, please check this doc. License This project is under the MIT license. Citation Please consider citing our paper if you find this project helpful for your research: Acknowledgement This work is built upon the LLaVA and LISA.

常见问题

记录了多少星标和分叉?

penghao-wu/vstar 有 715 个星标和 43 个分叉。

仓库排名是多少?

penghao-wu/vstar 排名第 14,642。

记录的语言和类别是什么?

penghao-wu/vstar 有 715 个星标,语言为 Python,类别为 Model Development。

哪个仓库排名最接近?

penghao-wu/vstar 与 lich99/ChatGLM-finetune-LoRA 比较,后者排名第 14,640,有 715 个星标。

README

V*: Guided Visual Search as a Core Mechanism in Multimodal LLMs

Paper | Project Page | Online Demo
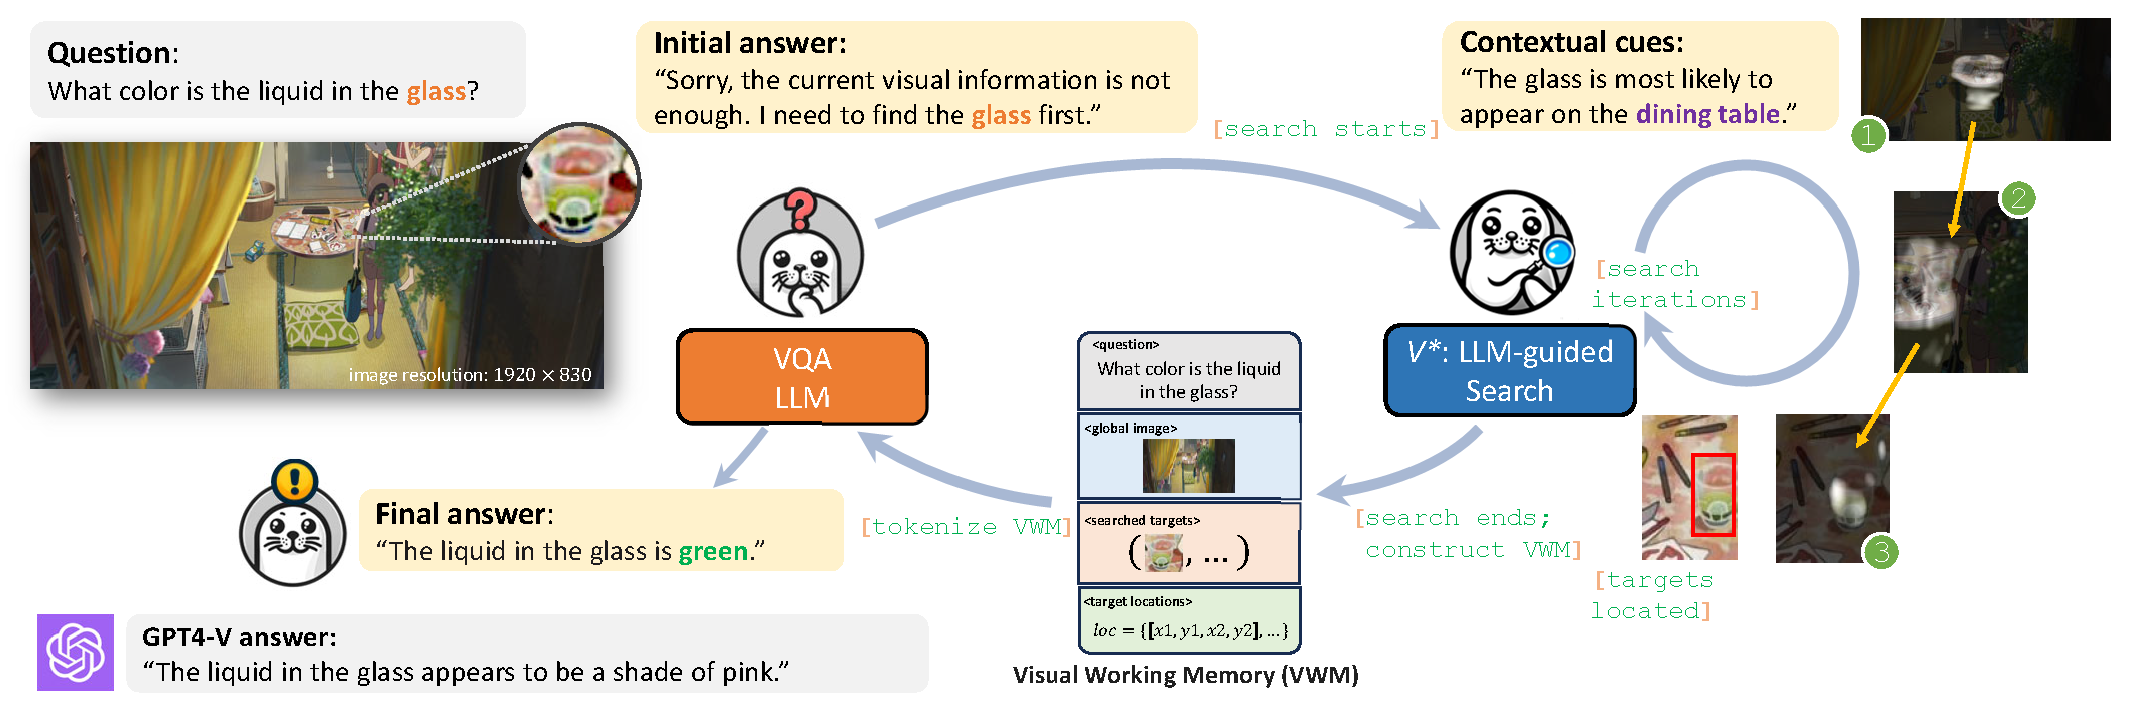
Contents:

  1. Getting Started
  2. Demo
  3. Benchmark
  4. Evaluation
  5. Training
  6. License
  7. Citation
  8. Acknowledgement

Getting Started

Installation

conda create -n vstar python=3.10 -y
conda activate vstar
pip install -r requirements.txt
pip install flash-attn --no-build-isolation
export PYTHONPATH=$PYTHONPATH:path_to_vstar_repo

Pre-trained Model

The VQA LLM can be downloaded here.
The visual search model can be downloaded here.

Training Dataset

The alignment stage of the VQA LLM uses the 558K subset of the LAION-CC-SBU dataset used by LLaVA which can be downloaded here.

The instruction tuning stage requires several instruction tuning subsets which can be found here.

The instruction tuning data requires images from COCO-2014, COCO-2017, and GQA. After downloading them, organize the data following the structure below

├── coco2014
│   └── train2014
├── coco2017
│   └── train2017
└── gqa
     └── images

Demo

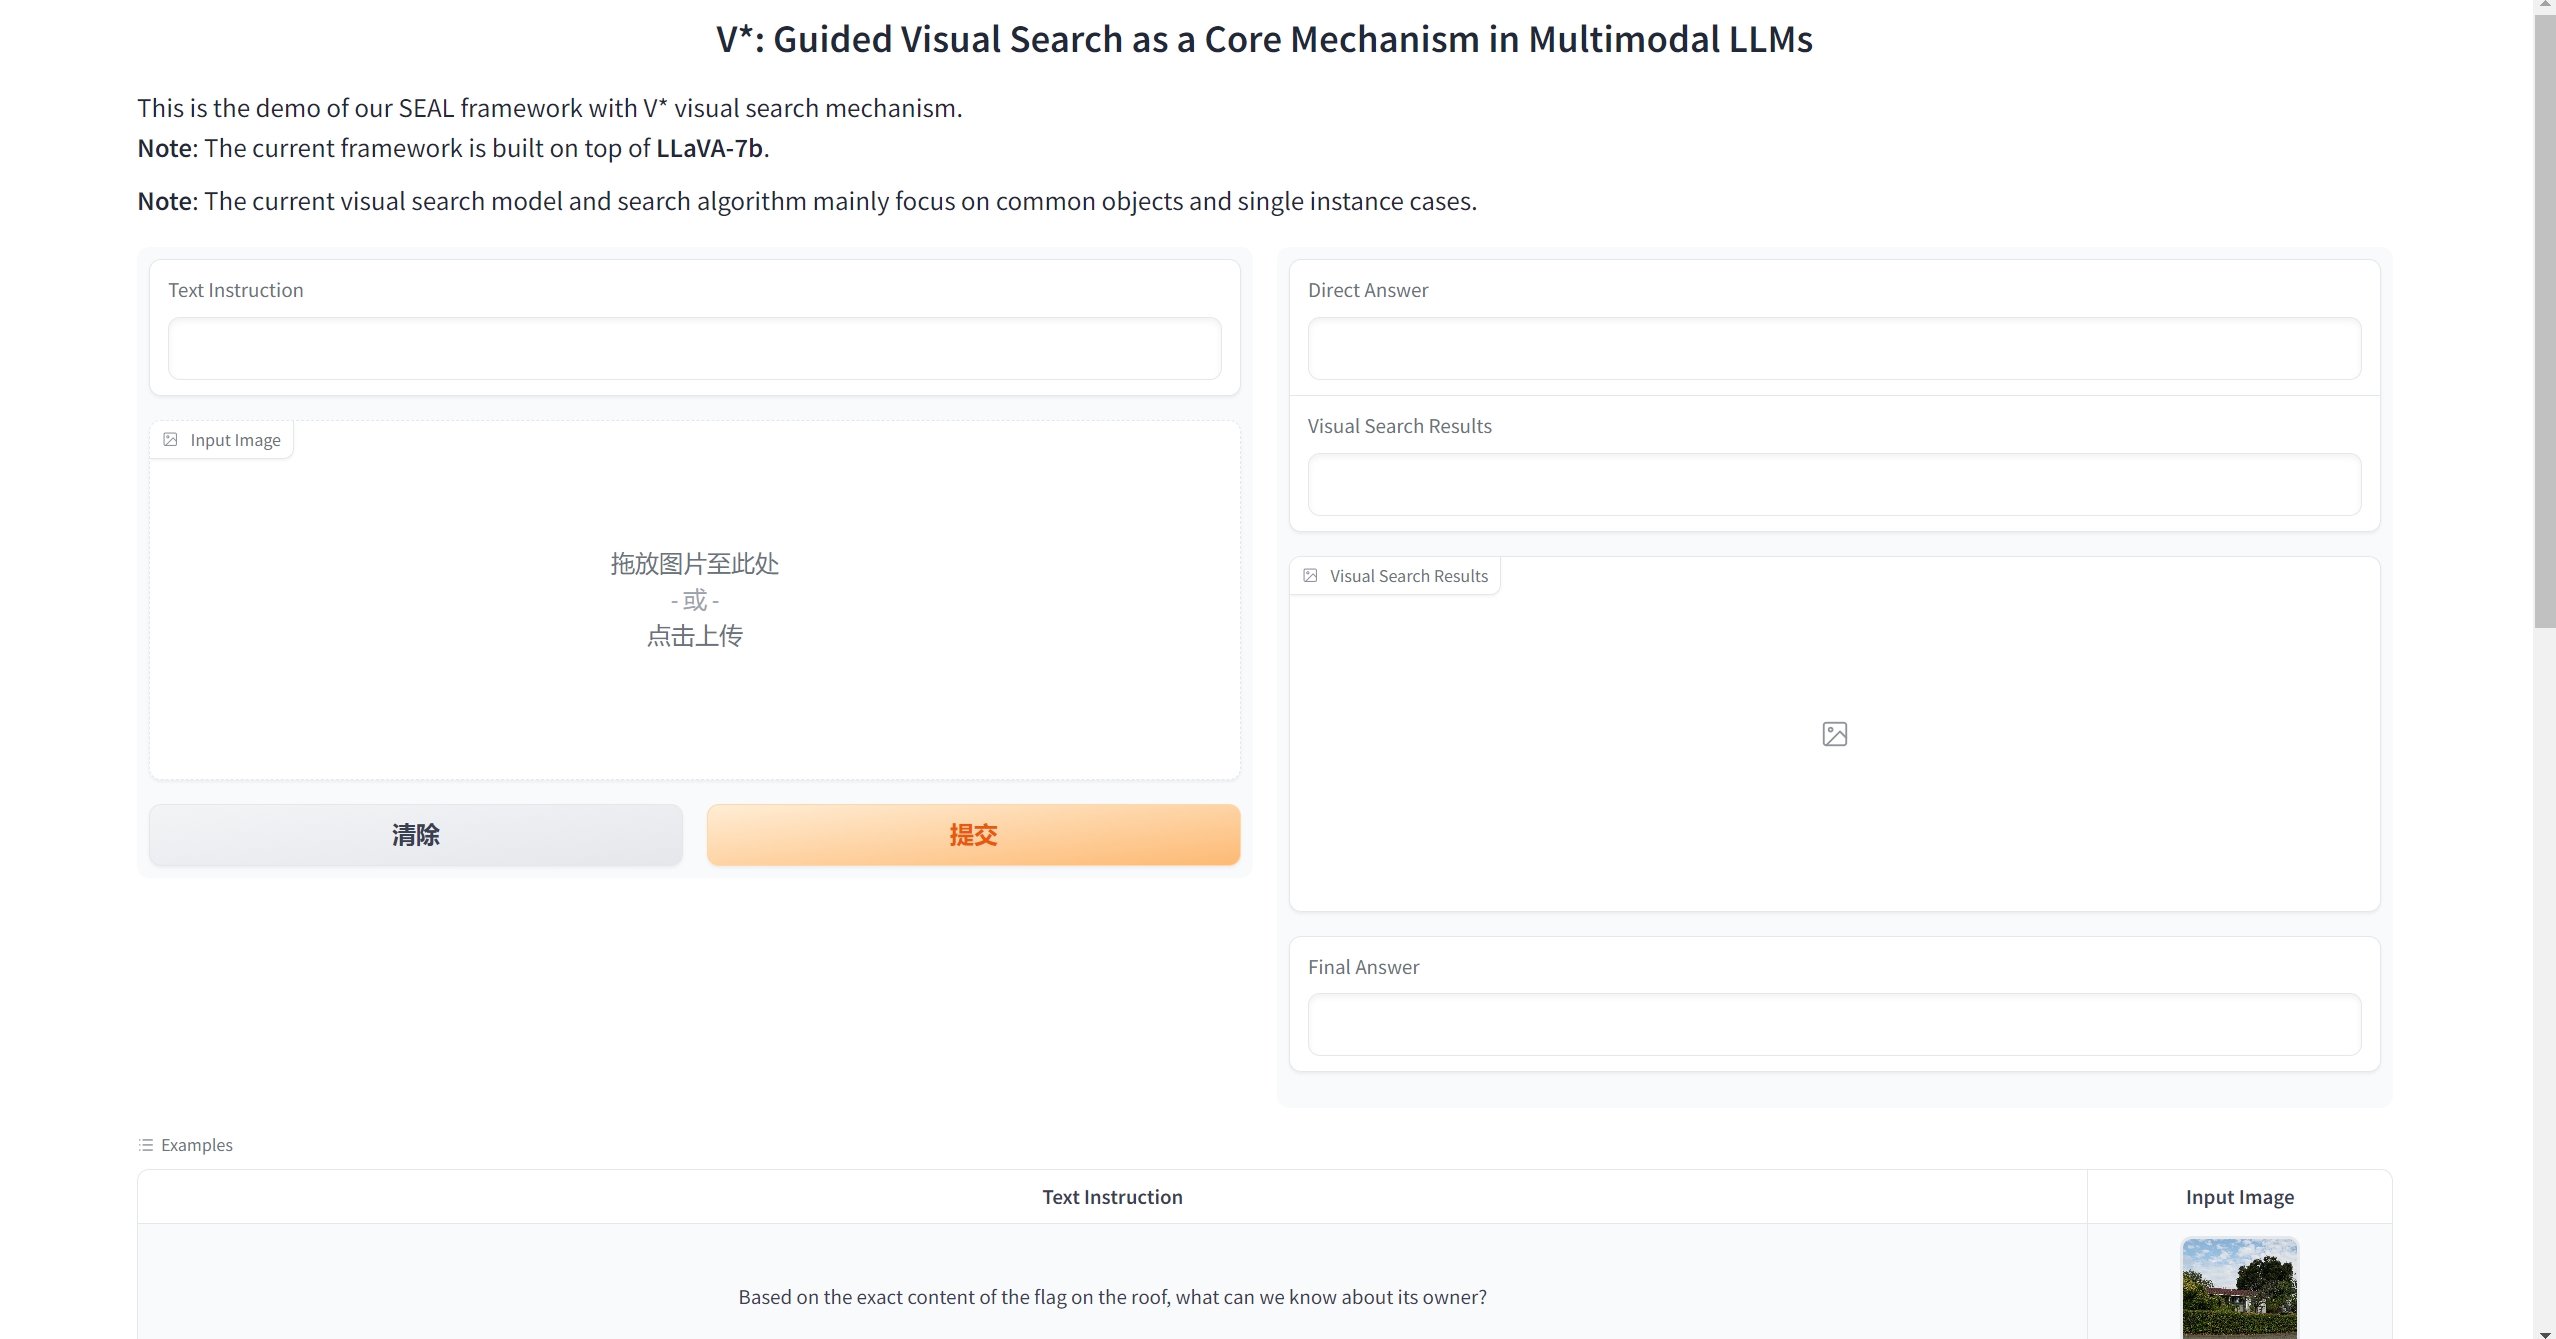
You can launch a local Gradio demo after the installation by running python app.py. Note that the pre-trained model weights will be automatically downloaded if you have not downloaded them before.

You are expected to see the web page below:
Benchmark

Our V*Bench is available here. The benchmark contains folders for different subtasks. Within each folder is a list of image files and annotation JSON files. The image and annotations files are paired according to the filename. The format of the annotation files is:

{
  "target_object": [] // A list of target object names
  ,
  "bbox": [] // A list of target object coordinates in 
  ,
  "question": "",
  "options": [] // A list of options, the first one is the correct option by default
}

Evaluation

To evaluate our model on the V*Bench benchmark, run

python vstar_bench_eval.py --benchmark-folder PATH_TO_BENCHMARK_FOLDER

To evaluate our visual search mechanism on the annotated targets from the V*Bench benchmark, run

python visual_search.py --benchmark-folder PATH_TO_BENCHMARK_FOLDER

The detailed evaluation results of our model can be found here.

Training

The training of the VQA LLM model includes two stages.

For the pre-training stage, enter the LLaVA folder and run

sh pretrain.sh

For the instruction tuning stage, enter the LLaVA folder and run

sh finetune.sh

For the training data preparation and training procedures of our visual search model, please check this doc.

License

This project is under the MIT license. See LICENSE for details.

Citation

Please consider citing our paper if you find this project helpful for your research:

@article{vstar,
  title={V*: Guided Visual Search as a Core Mechanism in Multimodal LLMs},
  author={Penghao Wu and Saining Xie},
  journal={arXiv preprint arXiv:2312.14135},
  year={2023}
}

Acknowledgement

  • This work is built upon the LLaVA and LISA.
排名相邻
同类项目