← 开源
nikhilbarhate99

PPO-PyTorch

Minimal implementation of clipped objective Proximal Policy Optimization (PPO) in PyTorch

TutorialsML/AI fundamentalsPython
在 GitHub 打开
增长势头
+024 小时新增 Star0.0%
2.38k
Star
419
Fork
+0
本周
6
贡献者
创建于 2018-09-27 · 更新于 2026-10-13 · 今日第 8663 名
主要开发者
nikhilbarhate99Aakarshan-chauhanAlpoGIT

nikhilbarhate99/PPO-PyTorch 排名第 8,663,有 2,385 个星标。

同类别比较

nikhilbarhate99/PPO-PyTorch 排名第 8,663,此处有 8 个同类条目;hamzafarooq/building-llm-applications-from-scratch 排名第 8,655。

同类别比较
名称排名指标
jostmey/NakedTensor8,644
语言:
Python
星标数:
2,404
分叉数:
144
简介:
Bare bone examples of machine learning in TensorFlow
pbharrin/machinelearninginaction8,647
语言:
HTML
星标数:
2,402
分叉数:
1,776
简介:
Source Code for the book: Machine Learning in Action published by Manning
dipanjanS/practical-machine-learning-with-python8,653
语言:
Jupyter Notebook
星标数:
2,396
分叉数:
1,654
简介:
Master the essential skills needed to recognize and solve complex real-world problems with Machine Learning and Deep Learning by leveraging the highly popular Python Machine Learning Eco-system.
hamzafarooq/building-llm-applications-from-scratch8,655
语言:
Jupyter Notebook
星标数:
2,392
分叉数:
650
简介:
Code and Slides
boost-devs/ai-tech-interview8,671
星标数:
2,380
分叉数:
512
简介:
👩‍💻👨‍💻 AI 엔지니어 기술 면접 스터디 (⭐️ 2k+)
hesamsheikh/ml-retreat8,673
语言:
Jupyter Notebook
星标数:
2,378
分叉数:
251
简介:
Machine Learning Journal for Intermediate to Advanced Topics.
fengdu78/machine_learning_beginner8,682
语言:
Jupyter Notebook
星标数:
2,365
分叉数:
910
简介:
机器学习初学者公众号作品
ErickWendel/semana-javascript-expert078,690
语言:
JavaScript
星标数:
2,359
分叉数:
506
简介:
JS Expert Week 7.0 - 🙅🤏🏻 Controlling Streaming Platforms using Eye and Hand Detection 👁🖐
关键参数与规格
关键参数与规格
参数值
语言Python
类别Tutorials
子类别ML/AI fundamentals
关键词Alignment, RL
星标数2,385
分叉数419
贡献者6
创建日期2018-09-27
更新日期2026-10-13
1 天星标数0
7 天星标数0
排名8,663
上次排名8,730
排名变化67
7 天星标排名12,052
上次 7 天星标排名12,111
7 天星标排名变化59
总星标排名5,482
上次总星标排名5,474
总星标排名变化-8
README 摘录

PPO-PyTorch UPDATE [April 2021] : merged discrete and continuous algorithms added linear decaying for the continuous action space ; to make training more stable for complex environments added different learning rates for actor and critic episodes, timesteps and rewards are now logged in files utils to plot graphs from log files utils to test and make gifs from preTrained networks combining all the files to train / test / plot graphs / make gifs on google colab in a convenient jupyter-notebook Introduction This

repository provides a Minimal PyTorch implementation of Proximal Policy Optimization (PPO) with clipped objective for OpenAI gym environments. It is primarily intended for beginners in Reinforcement Learning for understanding the PPO algorithm. It can still be used for complex environments but may require some hyperparameter-tuning or changes in the code. A concise explaination of PPO algorithm can be found here and a thorough explaination of all the details for implementing best performing PPO can be found here (All are

not implemented in this repo yet). To keep the training procedure simple : It has a **constant standard deviation** for the output action distribution (**multivariate normal with diagonal covariance matrix**) for the continuous environments, i. it is a hyperparameter and NOT a trainable parameter. (action_std significantly affects performance) It uses simple **monte-carlo estimate** for calculating advantages and NOT Generalized Advantage Estimate (check out the OpenAI spinning up implementation for that). It is a **single threaded implementation**, i. One of

the older forks of this repository has been modified to have Parallel workers Usage To train a new network : run To test a preTrained network : run To plot graphs using log files : run To save images for gif and make gif using a preTrained network : run All parameters and hyperparamters to control training / testing / graphs / gifs are in their respective file combines all the files in a jupyter-notebook All the **hyperparameters used for training (preTrained) policies are listed** in

the in PPO_preTrained directory Note : if the environment runs on CPU, use CPU as device for faster training.

常见问题

记录了多少星标和分叉?

nikhilbarhate99/PPO-PyTorch 有 2,385 个星标和 419 个分叉。

仓库排名是多少?

nikhilbarhate99/PPO-PyTorch 排名第 8,663。

记录的语言和类别是什么?

nikhilbarhate99/PPO-PyTorch 有 2,385 个星标,语言为 Python,类别为 Tutorials。

哪个仓库排名最接近?

nikhilbarhate99/PPO-PyTorch 与 hamzafarooq/building-llm-applications-from-scratch 比较,后者排名第 8,655,有 2,392 个星标。

README

PPO-PyTorch

UPDATE [April 2021] :

  • merged discrete and continuous algorithms
  • added linear decaying for the continuous action space action_std; to make training more stable for complex environments
  • added different learning rates for actor and critic
  • episodes, timesteps and rewards are now logged in .csv files
  • utils to plot graphs from log files
  • utils to test and make gifs from preTrained networks
  • PPO_colab.ipynb combining all the files to train / test / plot graphs / make gifs on google colab in a convenient jupyter-notebook

Open PPO_colab.ipynb in Google Colab

Introduction

This repository provides a Minimal PyTorch implementation of Proximal Policy Optimization (PPO) with clipped objective for OpenAI gym environments. It is primarily intended for beginners in Reinforcement Learning for understanding the PPO algorithm. It can still be used for complex environments but may require some hyperparameter-tuning or changes in the code. A concise explaination of PPO algorithm can be found here and a thorough explaination of all the details for implementing best performing PPO can be found here (All are not implemented in this repo yet).

To keep the training procedure simple :

  • It has a constant standard deviation for the output action distribution (multivariate normal with diagonal covariance matrix) for the continuous environments, i.e. it is a hyperparameter and NOT a trainable parameter. However, it is linearly decayed. (action_std significantly affects performance)
  • It uses simple monte-carlo estimate for calculating advantages and NOT Generalized Advantage Estimate (check out the OpenAI spinning up implementation for that).
  • It is a single threaded implementation, i.e. only one worker collects experience. One of the older forks of this repository has been modified to have Parallel workers

Usage

  • To train a new network : run train.py
  • To test a preTrained network : run test.py
  • To plot graphs using log files : run plot_graph.py
  • To save images for gif and make gif using a preTrained network : run make_gif.py
  • All parameters and hyperparamters to control training / testing / graphs / gifs are in their respective .py file
  • PPO_colab.ipynb combines all the files in a jupyter-notebook
  • All the hyperparameters used for training (preTrained) policies are listed in the README.md in PPO_preTrained directory

Note :

  • if the environment runs on CPU, use CPU as device for faster training. Box-2d and Roboschool run on CPU and training them on GPU device will be significantly slower because the data will be moved between CPU and GPU often

Citing

Please use this bibtex if you want to cite this repository in your publications :

@misc{pytorch_minimal_ppo,
    author = {Barhate, Nikhil},
    title = {Minimal PyTorch Implementation of Proximal Policy Optimization},
    year = {2021},
    publisher = {GitHub},
    journal = {GitHub repository},
    howpublished = {\url{https://github.com/nikhilbarhate99/PPO-PyTorch}},
}

Results

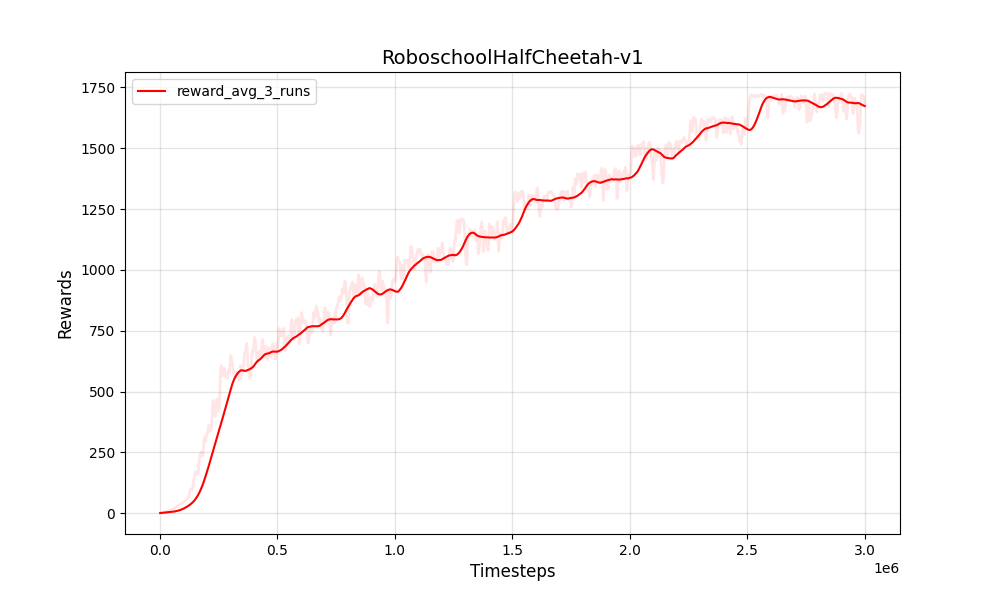
PPO Continuous RoboschoolHalfCheetah-v1 PPO Continuous RoboschoolHalfCheetah-v1
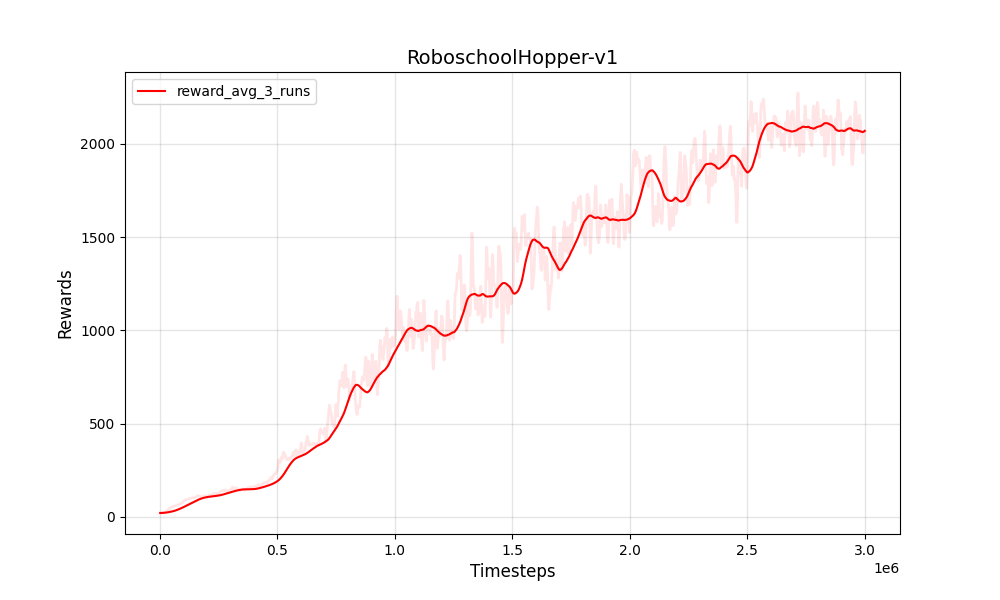
PPO Continuous RoboschoolHopper-v1 PPO Continuous RoboschoolHopper-v1
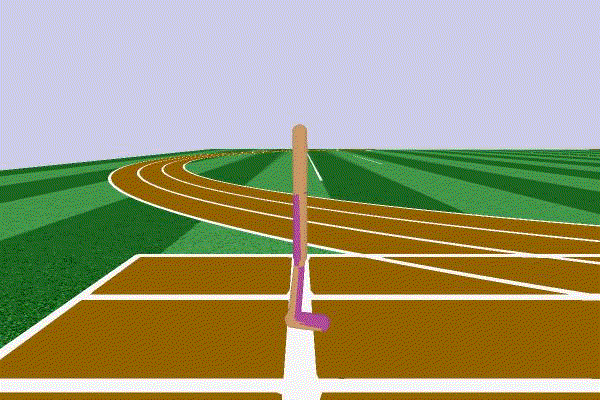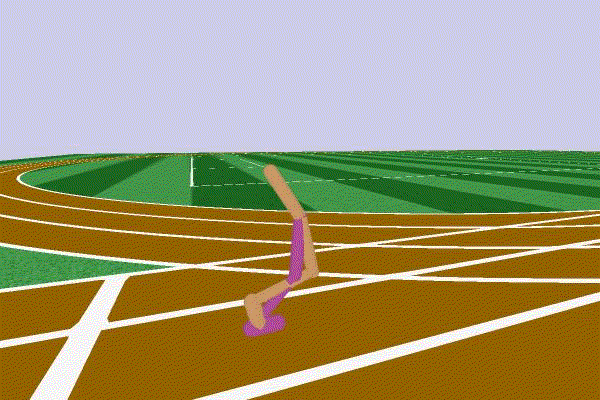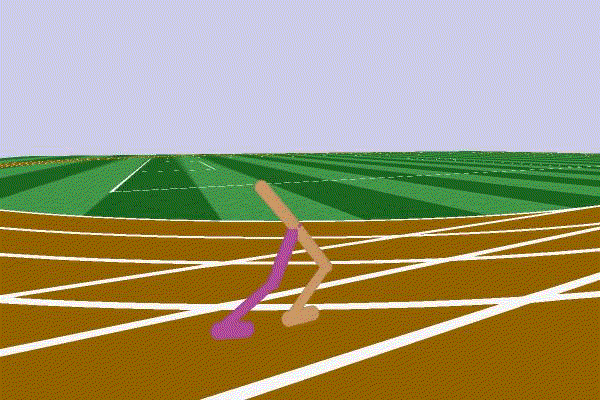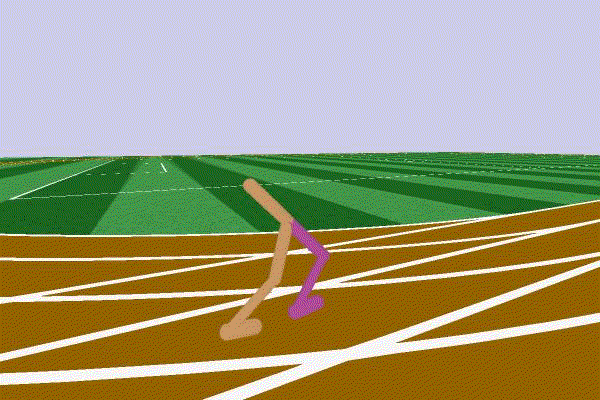
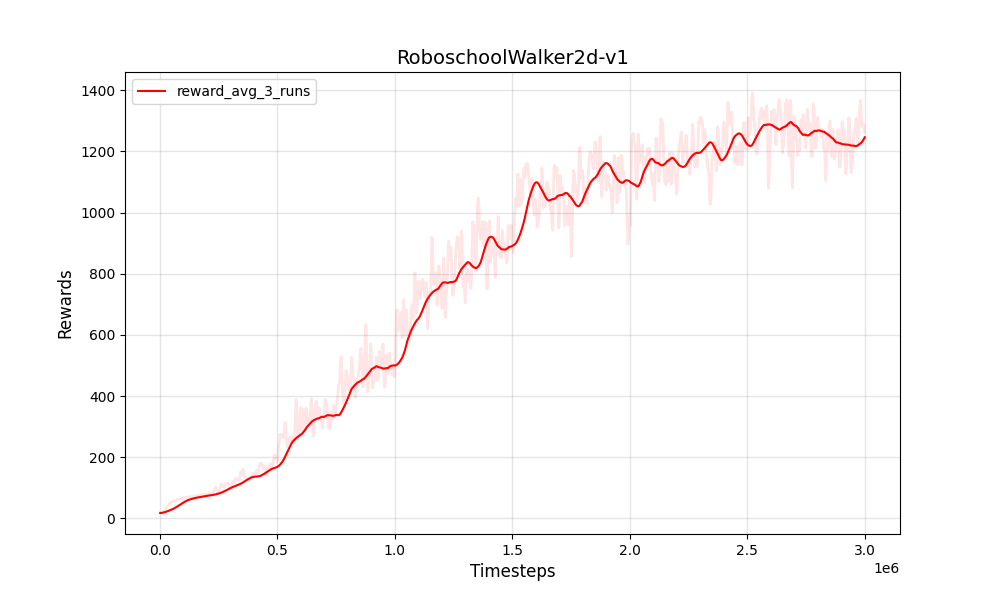
PPO Continuous RoboschoolWalker2d-v1 PPO Continuous RoboschoolWalker2d-v1
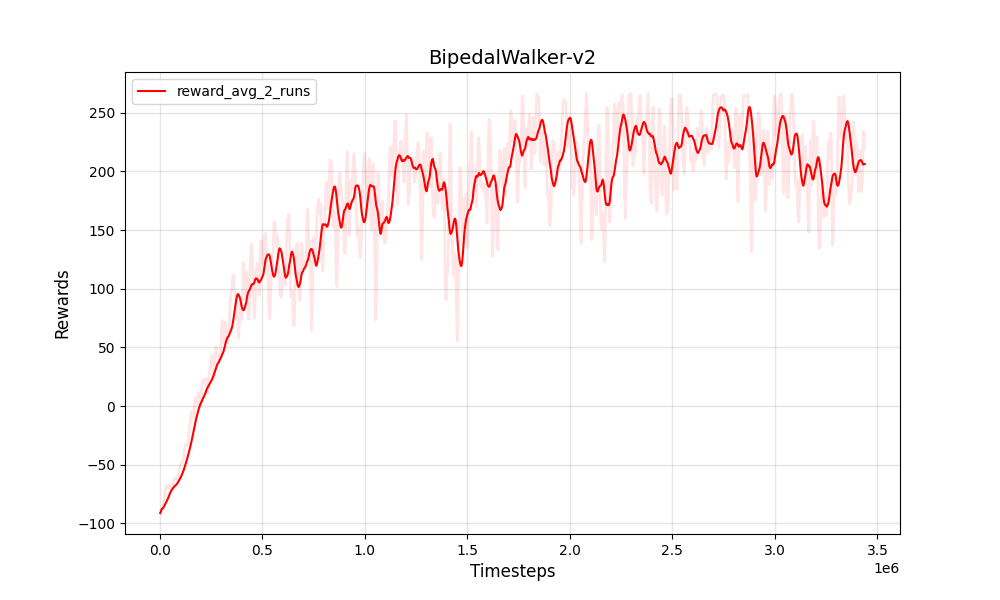
PPO Continuous BipedalWalker-v2 PPO Continuous BipedalWalker-v2
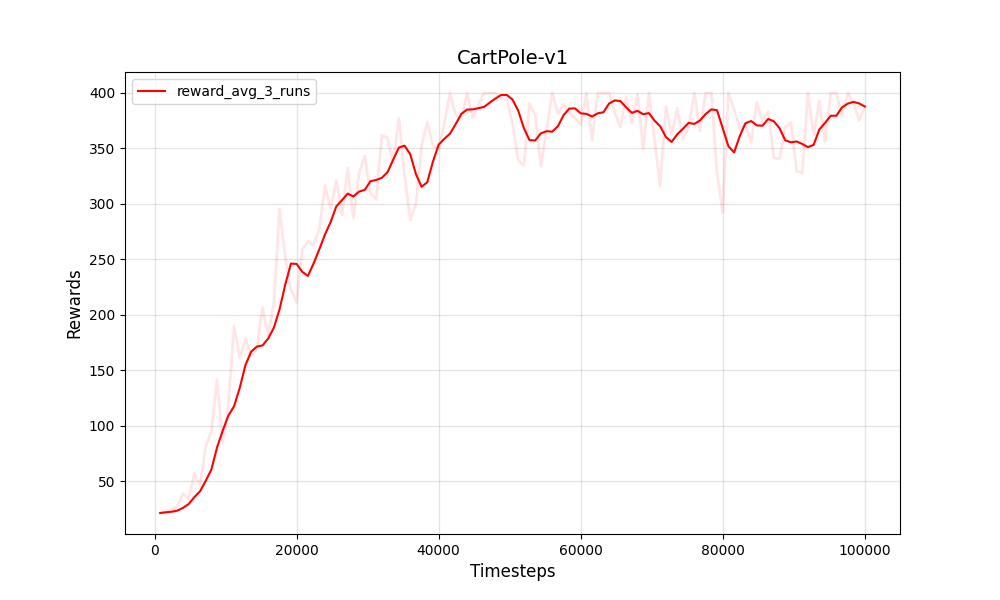
PPO Discrete CartPole-v1 PPO Discrete CartPole-v1
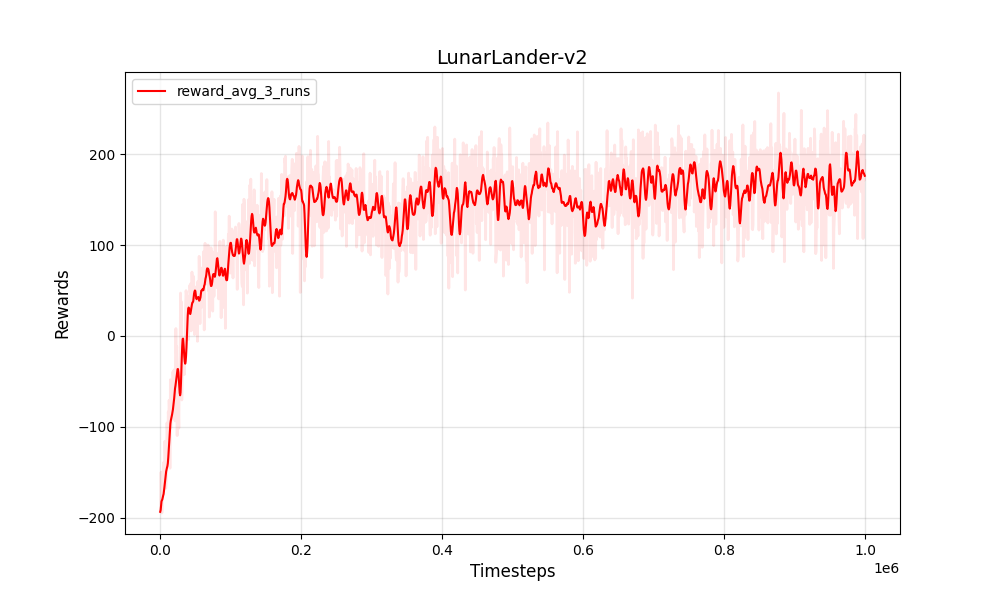
PPO Discrete LunarLander-v2 PPO Discrete LunarLander-v2

Dependencies

Trained and Tested on:

Python 3
PyTorch
NumPy
gym

Training Environments

Box-2d
Roboschool
pybullet

Graphs and gifs

pandas
matplotlib
Pillow

References

排名相邻
同类项目