All-In-One Music Structure Analyzer


This package provides models for music structure analysis, predicting:
- Tempo (BPM)
- Beats
- Downbeats
- Functional segment boundaries
- Functional segment labels (e.g., intro, verse, chorus, bridge, outro)
Table of Contents
- Installation
- Usage for CLI
- Usage for Python
- Visualization & Sonification
- Available Models
- Speed
- Advanced Usage for Research
- Concerning MP3 Files
- Training
- Citation
Installation
1. Install PyTorch
Visit PyTorch and install the appropriate version for your system.
2. Install NATTEN (Required for Linux and Windows; macOS will auto-install)
- Linux: Download from NATTEN website
- macOS: Auto-installs with
allin1. - Windows: Build from source:
pip install ninja # Recommended, not required
git clone https://github.com/SHI-Labs/NATTEN
cd NATTEN
make
3. Install the package
pip install git+https://github.com/CPJKU/madmom  # install the latest madmom directly from GitHub
pip install allin1  # install this package
4. (Optional) Install FFmpeg for MP3 support
For ubuntu:
sudo apt install ffmpeg
For macOS:
brew install ffmpeg
Usage for CLI
To analyze audio files:
allin1 your_audio_file1.wav your_audio_file2.mp3
Results will be saved in the ./struct directory by default:
./struct
└── your_audio_file1.json
└── your_audio_file2.json
The analysis results will be saved in JSON format:
{
  "path": "/path/to/your_audio_file.wav",
  "bpm": 100,
  "beats": [ 0.33, 0.75, 1.14, ... ],
  "downbeats": [ 0.33, 1.94, 3.53, ... ],
  "beat_positions": [ 1, 2, 3, 4, 1, 2, 3, 4, 1, ... ],
  "segments": [
    {
      "start": 0.0,
      "end": 0.33,
      "label": "start"
    },
    {
      "start": 0.33,
      "end": 13.13,
      "label": "intro"
    },
    {
      "start": 13.13,
      "end": 37.53,
      "label": "chorus"
    },
    {
      "start": 37.53,
      "end": 51.53,
      "label": "verse"
    },
    ...
  ]
}
All available options are as follows:
$ allin1 -h

usage: allin1 [-h] [-o OUT_DIR] [-v] [--viz-dir VIZ_DIR] [-s] [--sonif-dir SONIF_DIR] [-a] [-e] [-m MODEL] [-d DEVICE] [-k]
              [--demix-dir DEMIX_DIR] [--spec-dir SPEC_DIR]
              paths [paths ...]

positional arguments:
  paths                 Path to tracks

options:
  -h, --help            show this help message and exit
  -o OUT_DIR, --out-dir OUT_DIR
                        Path to a directory to store analysis results (default: ./struct)
  -v, --visualize       Save visualizations (default: False)
  --viz-dir VIZ_DIR     Directory to save visualizations if -v is provided (default: ./viz)
  -s, --sonify          Save sonifications (default: False)
  --sonif-dir SONIF_DIR
                        Directory to save sonifications if -s is provided (default: ./sonif)
  -a, --activ           Save frame-level raw activations from sigmoid and softmax (default: False)
  -e, --embed           Save frame-level embeddings (default: False)
  -m MODEL, --model MODEL
                        Name of the pretrained model to use (default: harmonix-all)
  -d DEVICE, --device DEVICE
                        Device to use (default: cuda if available else cpu)
  -k, --keep-byproducts
                        Keep demixed audio files and spectrograms (default: False)
  --demix-dir DEMIX_DIR
                        Path to a directory to store demixed tracks (default: ./demix)
  --spec-dir SPEC_DIR   Path to a directory to store spectrograms (default: ./spec)
Usage for Python
Available functions:
analyze()
Analyzes the provided audio files and returns the analysis results.
import allin1

# You can analyze a single file:
result = allin1.analyze('your_audio_file.wav')

# Or multiple files:
results = allin1.analyze(['your_audio_file1.wav', 'your_audio_file2.mp3'])
A result is a dataclass instance containing:
AnalysisResult(
  path='/path/to/your_audio_file.wav',
  bpm=100,
  beats=[0.33, 0.75, 1.14, ...],
  beat_positions=[1, 2, 3, 4, 1, 2, 3, 4, 1, ...],
  downbeats=[0.33, 1.94, 3.53, ...],
  segments=[
    Segment(start=0.0, end=0.33, label='start'),
    Segment(start=0.33, end=13.13, label='intro'),
    Segment(start=13.13, end=37.53, label='chorus'),
    Segment(start=37.53, end=51.53, label='verse'),
    Segment(start=51.53, end=64.34, label='verse'),
    Segment(start=64.34, end=89.93, label='chorus'),
    Segment(start=89.93, end=105.93, label='bridge'),
    Segment(start=105.93, end=134.74, label='chorus'),
    Segment(start=134.74, end=153.95, label='chorus'),
    Segment(start=153.95, end=154.67, label='end'),
  ]),
Unlike CLI, it does not save the results to disk by default. You can save them as follows:
result = allin1.analyze(
  'your_audio_file.wav',
  out_dir='./struct',
)
Parameters:
-
paths:Union[PathLike, List[PathLike]]
List of paths or a single path to the audio files to be analyzed. -
out_dir:PathLike(optional)
Path to the directory where the analysis results will be saved. By default, the results will not be saved. -
visualize:Union[bool, PathLike](optional)
Whether to visualize the analysis results or not. If a path is provided, the visualizations will be saved in that directory. Default is False. If True, the visualizations will be saved in './viz'. -
sonify:Union[bool, PathLike](optional)
Whether to sonify the analysis results or not. If a path is provided, the sonifications will be saved in that directory. Default is False. If True, the sonifications will be saved in './sonif'. -
model:str(optional)
Name of the pre-trained model to be used for the analysis. Default is 'harmonix-all'. Please refer to the documentation for the available models. -
device:str(optional)
Device to be used for computation. Default is 'cuda' if available, otherwise 'cpu'. -
include_activations:bool(optional)
Whether to include activations in the analysis results or not. -
include_embeddings:bool(optional)
Whether to include embeddings in the analysis results or not. -
demix_dir:PathLike(optional)
Path to the directory where the source-separated audio will be saved. Default is './demix'. -
spec_dir:PathLike(optional)
Path to the directory where the spectrograms will be saved. Default is './spec'. -
keep_byproducts:bool(optional)
Whether to keep the source-separated audio and spectrograms or not. Default is False. -
multiprocess:bool(optional)
Whether to use multiprocessing for extracting spectrograms. Default is True.
Returns:
Union[AnalysisResult, List[AnalysisResult]]
Analysis results for the provided audio files.
load_result()
Loads the analysis results from the disk.
result = allin1.load_result('./struct/24k_Magic.json')
visualize()
Visualizes the analysis results.
fig = allin1.visualize(result)
fig.show()
Parameters:
-
result:Union[AnalysisResult, List[AnalysisResult]]
List of analysis results or a single analysis result to be visualized. -
out_dir:PathLike(optional)
Path to the directory where the visualizations will be saved. By default, the visualizations will not be saved.
Returns:
Union[Figure, List[Figure]]List of figures or a single figure containing the visualizations.Figureis a class frommatplotlib.pyplot.
sonify()
Sonifies the analysis results. It will mix metronome clicks for beats and downbeats, and event sounds for segment boundaries to the original audio file.
y, sr = allin1.sonify(result)
# y: sonified audio with shape (channels=2, samples)
# sr: sampling rate (=44100)
Parameters:
result:Union[AnalysisResult, List[AnalysisResult]]
List of analysis results or a single analysis result to be sonified.out_dir:PathLike(optional)
Path to the directory where the sonifications will be saved. By default, the sonifications will not be saved.
Returns:
Union[Tuple[NDArray, float], List[Tuple[NDArray, float]]]
List of tuples or a single tuple containing the sonified audio and the sampling rate.
Visualization & Sonification
This package provides a simple visualization (-v or --visualize) and sonification (-s or --sonify) function for the analysis results.
allin1 -v -s your_audio_file.wav
The visualizations will be saved in the ./viz directory by default:
./viz
└── your_audio_file.pdf
The sonifications will be saved in the ./sonif directory by default:
./sonif
└── your_audio_file.sonif.wav
For example, a visualization looks like this:
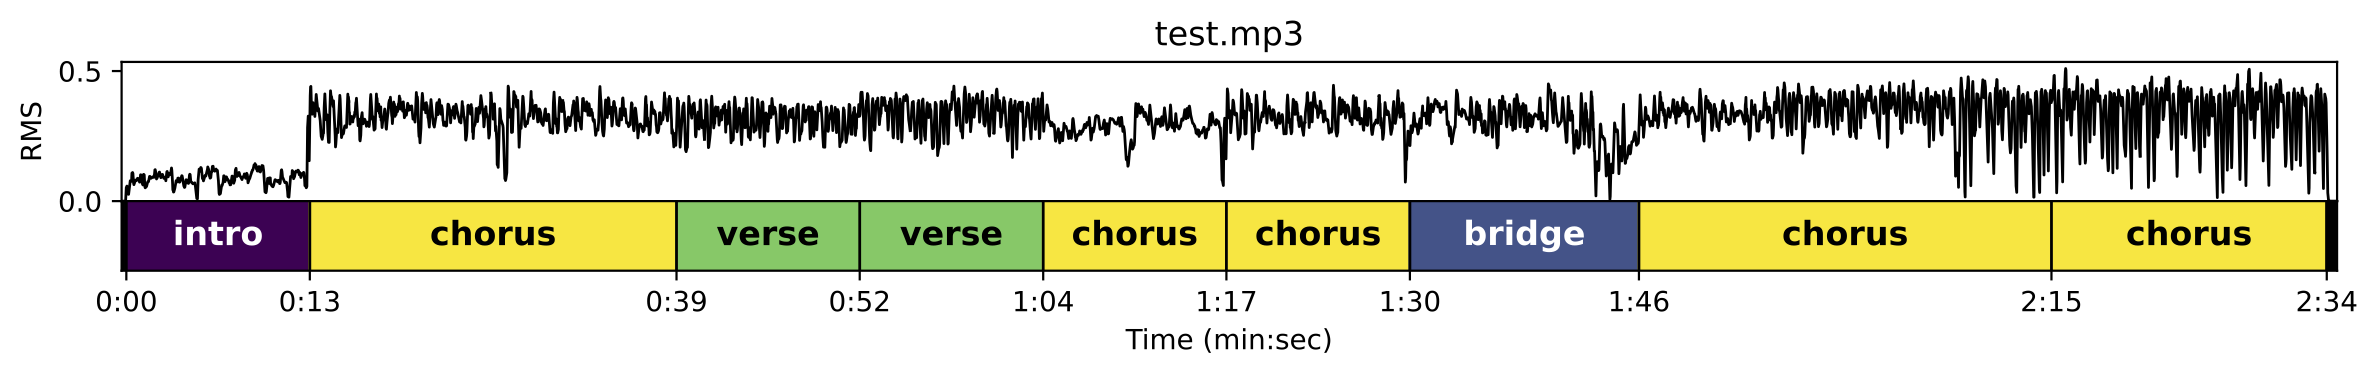
You can try it at Hugging Face Space.
Available Models
The models are trained on the Harmonix Set with 8-fold cross-validation. For more details, please refer to the paper.
harmonix-all: (Default) An ensemble model averaging the predictions of 8 models trained on each fold.harmonix-foldN: A model trained on fold N (0~7). For example,harmonix-fold0is trained on fold 0.
By default, the harmonix-all model is used. To use a different model, use the --model option:
allin1 --model harmonix-fold0 your_audio_file.wav
Speed
With an RTX 4090 GPU and Intel i9-10940X CPU (14 cores, 28 threads, 3.30 GHz),
the harmonix-all model processed 10 songs (33 minutes) in 73 seconds.
Advanced Usage for Research
This package provides researchers with advanced options to extract frame-level raw activations and embeddings without post-processing. These have a resolution of 100 FPS, equivalent to 0.01 seconds per frame.
CLI
Activations
The --activ option also saves frame-level raw activations from sigmoid and softmax:
$ allin1 --activ your_audio_file.wav
You can find the activations in the .npz file:
./struct
└── your_audio_file1.json
└── your_audio_file1.activ.npz
To load the activations in Python:
>>> import numpy as np
>>> activ = np.load('./struct/your_audio_file1.activ.npz')
>>> activ.files
['beat', 'downbeat', 'segment', 'label']
>>> beat_activations = activ['beat']
>>> downbeat_activations = activ['downbeat']
>>> segment_boundary_activations = activ['segment']
>>> segment_label_activations = activ['label']
Details of the activations are as follows:
beat: Raw activations from the sigmoid layer for beat tracking (shape:[time_steps])downbeat: Raw activations from the sigmoid layer for downbeat tracking (shape:[time_steps])segment: Raw activations from the sigmoid layer for segment boundary detection (shape:[time_steps])label: Raw activations from the softmax layer for segment labeling (shape:[label_class=10, time_steps])
You can access the label names as follows:
>>> allin1.HARMONIX_LABELS
['start',
 'end',
 'intro',
 'outro',
 'break',
 'bridge',
 'inst',
 'solo',
 'verse',
 'chorus']
Embeddings
This package also provides an option to extract raw embeddings from the model.
$ allin1 --embed your_audio_file.wav
You can find the embeddings in the .npy file:
./struct
└── your_audio_file1.json
└── your_audio_file1.embed.npy
To load the embeddings in Python:
>>> import numpy as np
>>> embed = np.load('your_audio_file1.embed.npy')
Each model embeds for every source-separated stem per time step,
resulting in embeddings shaped as [stems=4, time_steps, embedding_size=24]:
- The number of source-separated stems (the order is bass, drums, other, vocals).
- The number of time steps (frames). The time step is 0.01 seconds (100 FPS).
- The embedding size of 24.
Using the --embed option with the harmonix-all ensemble model will stack the embeddings,
saving them with the shape [stems=4, time_steps, embedding_size=24, models=8].
Python
The Python API allin1.analyze() offers the same options as the CLI:
>>> allin1.analyze(
      paths='your_audio_file.wav',
      include_activations=True,
      include_embeddings=True,
    )

AnalysisResult(
  path='/path/to/your_audio_file.wav',
  bpm=100,
  beats=[...],
  downbeats=[...],
  segments=[...],
  activations={
    'beat': array(...),
    'downbeat': array(...),
    'segment': array(...),
    'label': array(...)
  },
  embeddings=array(...),
)
Concerning MP3 Files
Due to variations in decoders, MP3 files can have slight offset differences. I recommend you to first convert your audio files to WAV format using FFmpeg (as shown below), and use the WAV files for all your data processing pipelines.
ffmpeg -i your_audio_file.mp3 your_audio_file.wav
In this package, audio files are read using Demucs. To my understanding, Demucs converts MP3 files to WAV using FFmpeg before reading them. However, using a different MP3 decoder can yield different offsets. I've observed variations of about 20~40ms, which is problematic for tasks requiring precise timing like beat tracking, where the conventional tolerance is just 70ms. Hence, I advise standardizing inputs to the WAV format for all data processing, ensuring straightforward decoding.
Training
Please refer to TRAINING.md.
Citation
If you use this package for your research, please cite the following paper:
@inproceedings{taejun2023allinone,
  title={All-In-One Metrical And Functional Structure Analysis With Neighborhood Attentions on Demixed Audio},
  author={Kim, Taejun and Nam, Juhan},
  booktitle={IEEE Workshop on Applications of Signal Processing to Audio and Acoustics (WASPAA)},
  year={2023}
}