treehouse
Manage worktrees without managing worktrees.
Are you still only working on one task at a time? Are you manually juggling between a few clones of the same repo?
Or... are you starting a new worktree for every agent session, losing all your installed dependencies and build cache each time, and wondering why your agents are slow?
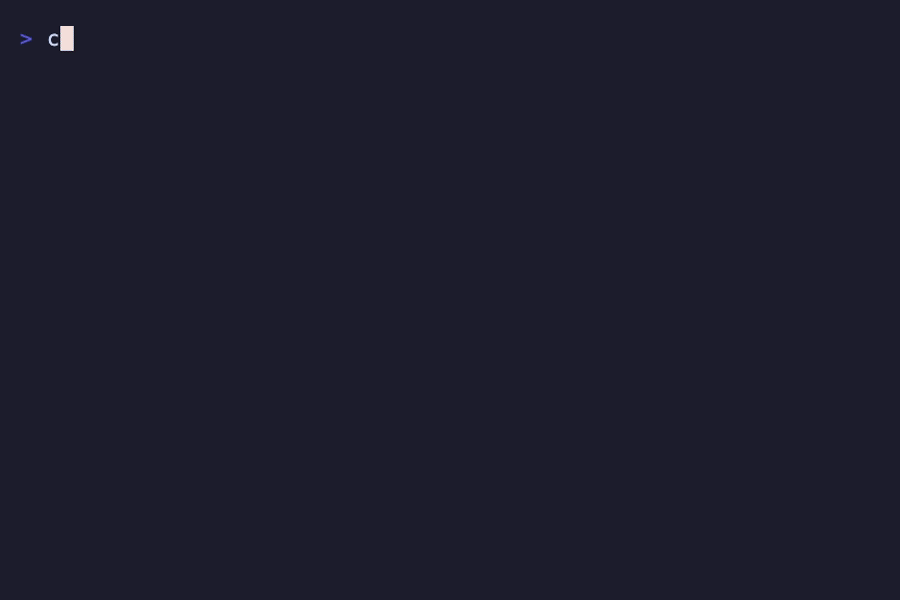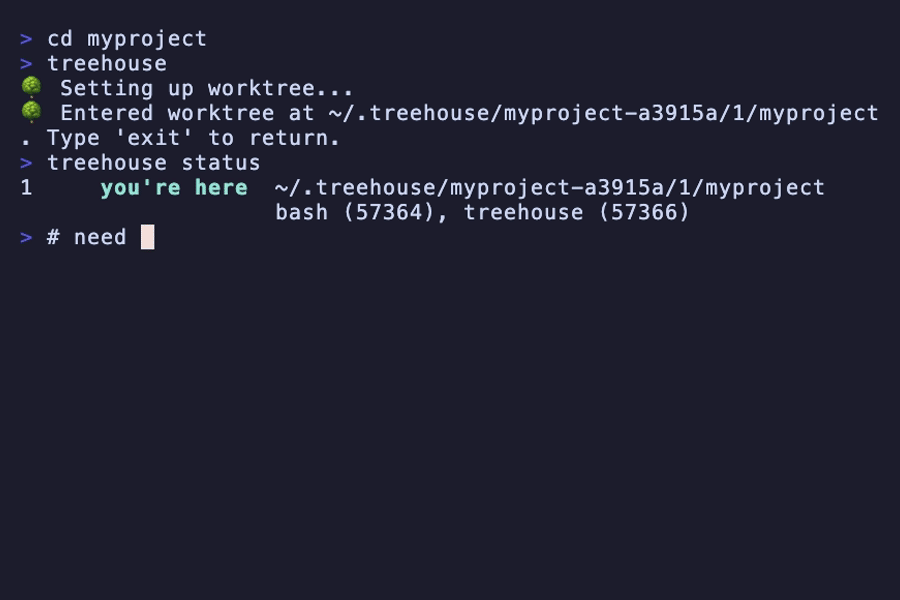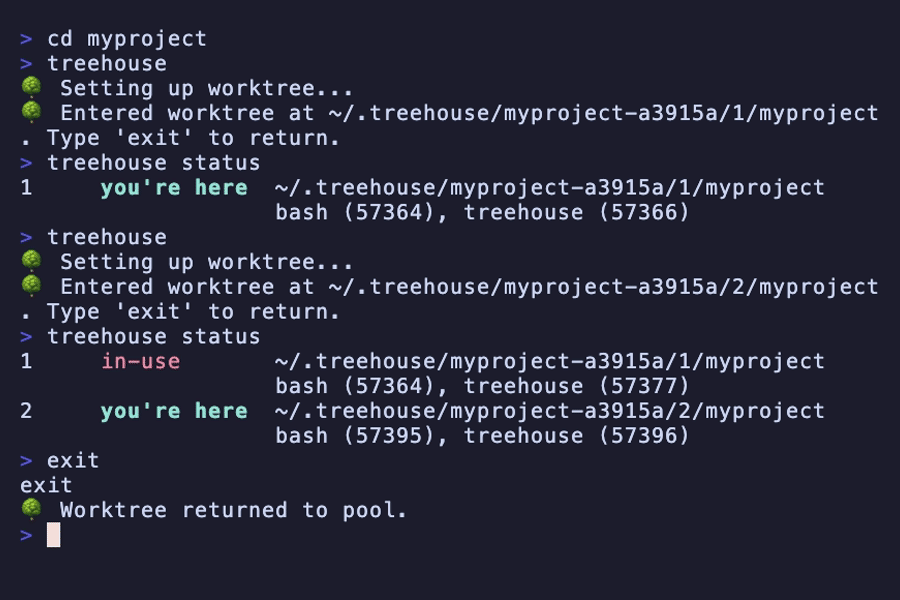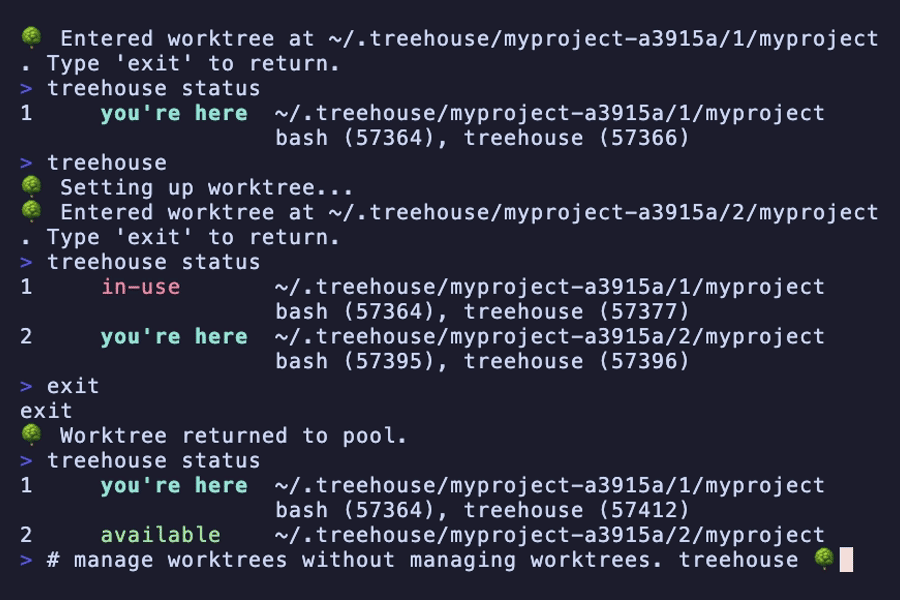
Treehouse helps you manage a pool of reusable, isolated worktrees so each of your agents gets its own environment instantly — no cloning, no conflicts, no coordination overhead.
- Instant isolation —
treehouseputs you into a clean worktree with zero hassel. - Reusable worktrees — worktrees are preserved in a pool when you're done, with dependencies and build cache intact, ready for the next agent.
- Conflict-free — automatic detection of in-use worktrees and your agents never step on each other's toes.
Quick Start
$ cd myproject                 # start in your repo as usual
$ treehouse                    # get a worktree and drop into a subshell
🌳 Entered worktree at ~/.treehouse/myproject-a1b2c3/1/myproject. Type 'exit' to return.

# You're now in an isolated worktree.
# Run your AI agent, make changes, do whatever you need.

$ exit                         # exit the subshell when you're done
🌳 Terminated lingering processes: opencode (pid 12345)
🌳 Worktree returned to pool.
Install
macOS / Linux
curl -fsSL https://kunchenguid.github.io/treehouse/install.sh | sh
Windows (PowerShell)
irm https://kunchenguid.github.io/treehouse/install.ps1 | iex
Nix
nix run github:kunchenguid/treehouse
# or pin a specific release tag:
nix run github:kunchenguid/treehouse/v2.3.0
Install into your Nix profile:
nix profile add github:kunchenguid/treehouse
Or add to your flake inputs:
treehouse = {
  url = "github:kunchenguid/treehouse";
  inputs.nixpkgs.follows = "nixpkgs";
};
The flake exposes #default and #treehouse package outputs, plus apps for nix run.
Go
go install github.com/kunchenguid/treehouse/v3@latest
From source
git clone https://github.com/kunchenguid/treehouse.git
cd treehouse
make install
How It Works
Treehouse manages a pool of git worktrees per repository, stored under the configured treehouse root.
The default treehouse root is ~/.treehouse/.
You can instead keep the pool inside the project with --root ., so it lives next to the code and is removed with the project.
  treehouse
      │
      ▼
  Find repo root
      │
      ▼
  git fetch origin
      │
      ▼
  ┌──────────────────────────────────────────────────────┐
  │  Scan pool for a safely reusable worktree            │
  │  (this clone's, idle, unleased, clean, and HEAD      │
  │  merged into the exact reset target; skip if safety  │
  │  or clone ownership is unprovable)                   │
  └──────────┬───────────────────────────────────────────┘
             │
        ┌────┴────┐
        │  Found? │
        └────┬────┘
         yes/ \no
           /   \
          ▼     ▼
   Reset to   Create new worktree
   latest     (detached HEAD at
   default    latest default
   branch     branch)
              & add to pool
          \   /
           \ /
            ▼
  Spawn subshell in worktree
  (agent works here)
           │
           ▼
     exit subshell
           │
           ▼
  Terminate lingering worktree
  processes and verify none remain
           │
           ▼
  Reset worktree & return to pool
  (ready for next agent)
- Detached HEAD by default — without
-b/--branch, worktrees use detached HEAD mode and reset to whichever of the local or remote default branch is further ahead. Passtreehouse get -bto create and check out a new local Git branch at the acquired commit. See Base branch for base selection and branch-creation details. - Choosable base branch — set
base_branchintreehouse.toml, or passtreehouse get --base, to cut worktrees from a branch other than the repository default. Opt-in; unset keeps today's inference. This composes with--branch: the new branch starts at the selected base. - Unique worktree directory names — pass
treehouse get --unique-leaf(or setunique_leafintreehouse.toml) to name new slots-instead of ``, so tooling that derives per-checkout identity from the directory name tells the slots apart. Opt-in; off keeps today's layout, and existing worktrees are never moved. - Choosable worktree path — set
worktree_pathintreehouse.toml, or passtreehouse get --worktree-path '', to place new worktrees somewhere a tool requires instead of{pool}/{slot}/{repo}. Opt-in, and creation-only: worktrees already in the pool keep their recorded paths. See Worktree path. - Clone-correct reuse — two local clones of the same remote share one pool, but a worktree is only ever reused by the clone it belongs to, judged by its physical Git common directory (symlinked or, on a case-insensitive filesystem, differently cased paths to one clone count as that clone). Another clone's idle worktree is skipped and left intact; if nothing reusable is left,
getcreates a new worktree up tomax_treesand otherwise fails with a message counting the foreign and unverifiable worktrees. A worktree whose owning clone cannot be proven is never reused, and neither is any worktree when the requesting clone's own identity cannot be proven. Non-colocated jj repositories have no Git common directory, so their worktrees are never reused;getcreates a new one each time untilmax_treesis reached. - Opt-in APFS sharing - share identical large tracked files with the main checkout using independent copy-on-write clones. Default off, macOS/APFS and fresh Git slots only; existing slots and ignored output are never swept. See APFS copy-on-write sharing.
- No daemon - all operations are inline CLI commands. Pool state is a small on-disk file, written under a lock by each command.
- Interactive shell setup — when opening a subshell on macOS or Linux,
treehouse,treehouse get, andtreehouse enterstart$SHELLas an interactive login shell when it resolves tobash,fish, orzsh. Other shells, fallback shells, and Windows use their default invocation. A regular executable that is merely named like a supported shell but does not accept-i -l(for example a wrapper script at/opt/tools/bash) is an accepted limitation: the resolved basename is the contract, and PATH-identity probing would reject genuine second installs of the same shell. - In-use detection — treehouse scans running processes and short-lived owner reservations to determine which worktrees are in-use. Reservations are persisted only while
get,destroy, andprunelifecycle work is running. - Durable leases -
treehouse get --leasereserves a worktree as a persistent home without keeping a process inside it. Each acquisition gets an immutable random lease identity, and the lease is recorded in treehouse's own state. An ordinary lease keeps the worktree out of latergetandpruneuntil you release it withtreehouse return. Unlike process-based in-use detection, it survives with zero processes running inside the worktree; recovered leases follow the state recovery policy. - State recovery - treehouse writes pool state atomically via a temp file and replacement. If an existing state file is empty, truncated, or omits an on-disk worktree, treehouse rebuilds the missing entries. See Recovering missing pool state for automatic recovery and handling slots that remain quarantined.
- Gitignored file seeding — commit a
.worktreeincludefile for the default selection, or passget --include-filefor a personal manifest. Selected local files are copied from the main checkout on each acquire. See Seeding gitignored files. - Dirty detection - treehouse treats tracked changes and untracked files as dirty, even when repository config hides untracked files from normal
git statusoutput. - Safe pruning - By default,
treehouse pruneremoves only clean, idle managed worktrees with landed HEAD commits. See Base branch for the merge rule.treehouse prune --allapplies the same safety checks across every managed pool under the user-level treehouse root. Backing-repository-missing orphans are reported by default;--prune-orphansincludes them as unverified prune candidates, and--yesis required before deletion. It is a dry run unless you pass--yes. - Self-healing get -
treehouse getprunes stale git worktree bookkeeping (e.g. left behind by a crashed or forcibly removed worktree) before adding a new worktree, so a prunable registration never wedges the pool with a "missing but already registered worktree" error.
CLI Reference
| Command | Description |
|---|---|
treehouse |
Get a worktree and open a subshell (alias for get) |
treehouse get |
Acquire a worktree from the pool |
treehouse get --lease |
Durably lease a worktree without a subshell; print its path |
treehouse lease |
Durably lease an existing pool worktree in place, without touching its files or git state |
treehouse enter |
Open a subshell in an existing worktree by name (the number from status), even if it is in use; pool state is left untouched |
treehouse status |
Show pool status (highlights leased and current worktrees) |
treehouse return [path|name] |
Release any lease and return a worktree only after verifying foreign processes stopped; the name is the number from status |
treehouse return --all |
Return every held worktree in the current repo pool |
treehouse prune |
Dry-run removal of stale idle worktrees in the current repo pool |
treehouse prune --all |
Dry-run removal of stale idle worktrees across every managed pool |
treehouse destroy |
Dry-run removal of one worktree (safe by default; --yes to execute) |
treehouse destroy --all |
Dry-run removal of every disposable worktree in that pool |
treehouse init |
Create a default treehouse.toml config file |
treehouse update |
Update treehouse to the latest version |
Flags
| Command | Flag | Description |
|---|---|---|
get |
--lease |
Durably lease the worktree without opening a subshell; print only its path to stdout |
get |
--lease-holder |
Optional label recorded as the lease holder (defaults to $TREEHOUSE_LEASE_HOLDER) |
get |
--json |
Print path, lease_id, lease_holder, leased_at, and base_branch as JSON (requires --lease) |
get |
-b, --branch |
Create and check out a new Git branch at the acquired commit; fails if it already exists or its name is invalid |
get |
--base |
Branch to cut this worktree from, overriding base_branch in config |
get |
--include-file |
Replace committed .worktreeinclude for this acquisition with the supplied manifest |
get |
--unique-leaf |
Name a newly created worktree directory - instead of ``, overriding unique_leaf in config |
get |
--worktree-path |
Template for a newly created worktree's directory, overriding worktree_path in config |
get |
--apfs-sharing |
fresh opts in to tracked-file sharing for new Git slots on macOS/APFS; off opts out (default) |
lease |
--lease-holder |
Optional label recorded as the lease holder (defaults to $TREEHOUSE_LEASE_HOLDER) |
lease |
--json |
Print path, lease_id, lease_holder, leased_at, and base_branch as JSON (base_branch is best-effort: empty when the slot records no explicit base and its own worktree cannot resolve a default) |
enter |
--print-path |
Print only the worktree's absolute path to stdout instead of opening a subshell (for cd "$(treehouse enter --print-path 1)") |
status |
--json |
Print worktree status and lease metadata as JSON |
return |
--force |
Clean, reset, and return without prompting |
return |
--all |
Return every held worktree in this repository's pool; leaves alone slots status reports available or damaged, and a you're here slot nobody else holds |
return |
--if-lease-id |
Return only if the current lease has the expected per-acquisition identity |
return |
--if-lease-holder |
Return only if the current lease has the expected holder |
prune |
--yes |
Delete listed prune candidates instead of doing a dry run |
prune |
--all |
Sweep every managed pool under the user-level treehouse root |
prune |
--global |
Alias for --all |
prune |
--prune-orphans |
Include backing-repository-missing orphans in prune candidates |
prune |
--verbose, -v |
Show detailed skip diagnostics |
destroy |
--all |
Remove all worktrees in the named pool (requires a pool path) |
destroy |
--yes |
Execute the removal instead of doing a dry run |
destroy |
--include-unlanded |
Also remove dirty, unmerged, or unverified worktrees (irreversible data loss) |
destroy |
--include-in-use |
Also remove worktrees with a running process or owner reservation (processes are terminated cleanly first) |
destroy |
--include-leased |
Also remove a leased worktree; only when the exact path is named, never via --all |
APFS copy-on-write sharing
Git worktrees already share Git's object database, but checked-out file data can still occupy separate blocks. On macOS/APFS, Treehouse can replace identical tracked files with independent copy-on-write clones of the same path in the owning main checkout. Editing either file does not change the other; deleting the source does not invalidate the clone. These are not hardlinks.
Opt in for one acquisition:
treehouse get --lease --apfs-sharing fresh
Or set apfs_sharing = "fresh" in treehouse.toml or ~/.config/treehouse/config.toml. Precedence is --apfs-sharing > TREEHOUSE_APFS_SHARING > repo/user config > off. The only values are off and fresh; invalid values fail before allocation. Override a configured opt-in with --apfs-sharing off or TREEHOUSE_APFS_SHARING=off.
Fresh Git slots only. The pass runs after normal checkout, seeding and optional branch creation, before the slot is marked acquired, Treehouse's post_create hooks run, or its path is published. Reused slots, return, existing worktrees, and jj workspaces are never swept. Only tracked regular files at least 64 KiB are candidates. It does not copy or share ignored node_modules, build directories, caches, Git metadata, or seeded files. Different source bytes are left alone; different branches are fine. Files rewritten by later builds or resets may lose sharing.
Exclusive destination ownership is required. Do not enable this when another editor, build, Git operation, or external watcher can write into the destination during setup. Pool leases and final stat checks are not filesystem writer locks. Treehouse conservatively skips sharing when Git post-checkout/reference-transaction hooks, custom fsmonitor hooks, or checkout filter attributes could already have started a writer. This also skips LFS-filtered checkouts. Treehouse's own hooks still run afterward as usual. The pass does not write source file content or metadata, though reading may update source access times.
The native implementation hashes the original destination and source, clones into destination-local staging, verifies the staged bytes, restores destination permissions/timestamps/xattrs and verifies them along with owner/group, hashes again, and atomically replaces the destination. Inode and ctime change; creation time is not preserved. Symlinked paths, ACLs, hardlinks, special mode/flag bits, sparse/compressed representations, different owners, and unsupported metadata are skipped. Other operating systems, non-APFS filesystems and cross-volume pairs keep ordinary copies, with the reason on stderr. No Python helper or daemon is required.
Diagnostics stay on stderr, including for get --lease --json; stdout retains its path/lease contract. logical_bytes is the payload cloned. private_data_reduced_bytes is a separate before/after APFS allocation measurement, not an immediate increase in volume free space: snapshots, shared extents and filesystem metadata matter. The initial checkout still needs its full allocation, and later writes need free space for private blocks. The pass adds synchronous hashing/metadata work while the pool is locked; opt-in does not guarantee a speedup.
A safe per-file clone, metadata or ENOSPC failure leaves the original in place and reports a skip/error. Detected destination/status/index/HEAD changes, cancellation, or incomplete staging cleanup fail acquisition and retain the provisional lease as quarantine, without publishing a path. Inspect the slot before returning or destroying it. SIGINT/SIGTERM unwind staging; SIGKILL can leave .treehouse-sharing-* directories, but the unpublished slot remains leased. Do not treat such a slot as ready for use or delete similarly named files in other worktrees.
Measured benefit
The pre-implementation scout measured real APFS private data on an arm64 Mac running macOS 26.6.2, using the reference algorithm on two independently created Git worktrees per public repository:
| Public corpus | Pre-pass tracked private data | Private data removed per worktree | Reduction |
|---|---|---|---|
| Godot demo projects | 324.57 MB | 301.39 MB | 92.86% |
| Google Fonts | 3,059.27 MB | 2,919.83 MB | 95.44% |
MB are decimal. The denominator includes all tracked regular-file private data, not just candidates; shared Git administration and inode/directory metadata are excluded. These fresh worktrees had no build/dependency output, so their whole-worktree regular-file denominators were the same. Benefits can be much smaller as a fraction of a populated worktree: another measured corpus fell from 87.97% of tracked data to 6.78% of whole regular-file data when its installed dependencies and build output were included. Multiply per-worktree savings by your retained slot count, but account for branch differences, writes and existing sharing.
The reference pass added 7.95-8.55 seconds for Godot and 96.58-98.92 seconds for Fonts. A single native-metadata prototype trial reduced these to 2.28 and 19.18 seconds. Those are scout prototype timings, not benchmarks or promises for the shipped Go implementation; cold caches, metadata and workload shape matter. Default-on behavior and automatic ignored-file sharing are intentionally out of scope.
Seeding gitignored files
Commit a .worktreeinclude file to seed selected gitignored files from the main checkout into each acquired Git worktree or jj workspace. This is useful for local configuration or generated files that every worktree needs but Git should not track. By default, only the committed file at the worktree's HEAD is used; a dirty or untracked .worktreeinclude in the main checkout is ignored, and a missing committed file is a no-op.
Manifests use .gitignore pattern syntax. A file must be ignored by the repository and selected by the manifest; tracked files and unignored untracked files are never copied. Use ! to exclude a broader match:
.env*
!.env.local
local-config/
For a personal selection that does not need to be committed, pass an explicit manifest:
treehouse get --include-file ./personal.include
treehouse get --lease --include-file ./personal.include
The supplied manifest replaces, rather than extends, committed .worktreeinclude for this acquisition, on both new and reused slots. The manifest may be tracked, untracked, or ignored. Relative manifest paths resolve from your current directory; patterns inside the file always select files relative to the main checkout root, not the manifest's directory. There is no config setting or environment variable for this override.
Treehouse reads the supplied file once before acquisition. A missing or unreadable file is an error before any slot is created or reset, with no fallback to the committed manifest. An empty file seeds nothing. Later acquisitions without the flag use the committed default again. Return and reuse remove previously seeded files using Treehouse's recorded inventory, even if the local manifest has changed or been deleted.
Treehouse refreshes selected files whenever it creates or reuses a worktree. On Unix-like systems, it preserves regular-file permissions, including executable bits. A source symlink becomes a regular file containing the symlink target text; Treehouse never follows it or creates a destination symlink. Rooted filesystem operations prevent selected paths and existing destination symlinks from escaping either checkout.
If seeding fails, acquisition fails too. A newly created worktree is removed; if cleanup fails, or if a reused worktree was only partly refreshed, Treehouse records it as leased and quarantined so a later get cannot hand it out silently. Inspect it with treehouse status. If Treehouse reports it as recovered, its seeded-file inventory is unknown: remove it with treehouse destroy --include-leased --yes, or return it by name as described in Recovering missing pool state, knowing that seeded ignored files stay in it. Other quarantined worktrees can be returned after they are safe to reuse.
Leasing a worktree (no subshell)
treehouse get normally opens an interactive subshell whose lifetime is the hold: when the shell exits, the worktree returns to the pool.
That is awkward for callers that need a worktree to persist as a permanent home with no long-lived process inside it.
treehouse get --lease is the non-interactive, durable alternative:
path=$(treehouse get --lease)
# $path is the leased worktree's absolute path; all banners went to stderr.
It acquires a worktree exactly like get, but instead of opening a subshell it marks the worktree leased in treehouse's persistent state. By default it prints only the worktree's absolute path to stdout; --json prints the lease allocation instead. Every human-facing message goes to stderr, so either output mode stays clean.
An ordinary lease keeps a worktree out of later get and prune, regardless of whether any process runs inside it, until the lease is explicitly released. Recovered leases have a separate, conservative automatic release path described in Recovering missing pool state.
A bulk treehouse destroy --all never removes it either; only naming its exact path with treehouse destroy --include-leased --yes will.
Pass --lease-holder (or set $TREEHOUSE_LEASE_HOLDER) to record who holds the lease; treehouse status then shows it next to the leased state.
get --lease can only protect a worktree it acquires itself. To give a worktree that already exists - a long-lived home acquired with plain get, or any registered slot that predates leases - the same protection after the fact, lease it in place:
treehouse lease 3 --lease-holder secondmate-home
lease is state-only: it never resets, fetches, cleans, or checks out the worktree, so it is safe on a slot holding live work. It refuses when the name is unknown, when the registered worktree's directory no longer exists, when the slot is being destroyed, or when it is already leased (naming the holder). Leasing a worktree whose treehouse get shell is still running is safe: when that shell exits, get sees the slot is no longer its own and leaves it untouched. treehouse return releases an in-place lease exactly like an acquired one.
Every acquisition receives a new random lease_id, including reacquiring the same path with the same holder. Automation can request a stable machine-readable allocation:
treehouse get --lease --lease-holder automation-A --json
# {"path":"...","lease_id":"...","lease_holder":"automation-A","leased_at":"...","base_branch":"main"}
Callers that already fetched the required refs can avoid another network operation with --no-fetch:
git fetch origin main refs/pull/123/head
treehouse get --lease --no-fetch --json
With --no-fetch, Treehouse resets or creates the worktree from existing local refs and never contacts origin. The caller is responsible for ensuring those refs and objects are current.
treehouse status --json returns an array with name, path, status, branch, detached, branch_error, recovery_reason, recovery_backup, flavor, lease_id, lease_holder, leased_at, and processes. recovery_reason is set when an unsafe recovered lease remains quarantined. recovery_backup is the slot's recovery backup folder, set while that folder holds anything. branch names the checked-out branch of a git slot on a branch; it is empty for a detached HEAD, a jj slot, and a markerless (damaged) slot. detached is true only for a git slot on a detached HEAD (the state treehouse get leaves by default) and is omitted when false; branch_error is set when a slot's branch could not be read, so a read failure is never mistaken for a detached HEAD or an empty branch. processes is what treehouse return would terminate in that worktree, not every process whose working directory is inside it: the calling process and its ancestors are excluded, so running status from inside a pooled worktree reports what is resident in the slot instead of the shell you typed the command into. When the process table itself cannot be read, status is unverified and processes is empty: whether anything is running there is unknown, so the slot is not reported available, dirty, or in-use, and the error is printed as a warning on stderr. A lease, an owner reservation, or the slot you are standing in is still reported as such, because those facts do not depend on the scan. flavor is the backend the worktree's own marker identifies ("git" or "jj") and is omitted when no marker is found. Non-leased entries use empty lease strings and a null timestamp. State files written before lease identities remain readable; their existing leases have an empty lease_id until released and acquired again.
Release a lease with treehouse return , which terminates lingering processes and verifies that no foreign process remains before it resets the worktree, clears the lease, and returns the worktree to the pool.
If process termination or that verification fails, the command exits nonzero and leaves the worktree and lease in place instead of recycling a slot that may still be in use.
A non-interactive dirty return aborts without cleaning: prune will not reclaim that slot. Retry by pasting the printed treehouse return --force hint (shell-quoted so copy-paste does not expand metacharacters). --force with no path only works from inside a repository.
When you pass an explicit path, treehouse return can run from outside the repository because it resolves the managed pool from that worktree path.
Naming the worktree
treehouse return accepts the same worktree name treehouse status prints in its first column, and treehouse lease and treehouse enter already take - so what you read off status can be returned without transcribing a path:
treehouse status
# 1     leased       ~/.treehouse/myrepo-a1b2c3/1/myrepo  (held by agent-a)
# 3     available    ~/.treehouse/myrepo-a1b2c3/3/myrepo
treehouse return 1
A name is the slot's own identity and belongs to it for its whole lifetime; it is not a position in the listing, so it does not move when another slot is created or destroyed. Because a name means nothing outside the pool that issued it, it is resolved against the pool of the repository you are standing in - unlike a path, which finds its own pool and works from anywhere.
An argument is read as a path first and only then as a name, so every argument that resolves today keeps resolving to exactly the same worktree. An argument holding a path separator is a path and only a path: its failure keeps reporting the path diagnosis rather than a misleading "no worktree named".
Returning everything at once
treehouse return --all returns every held worktree in the current repository's pool:
treehouse return --all
# 🌳 Returning 1 (leased) at ~/.treehouse/myrepo-a1b2c3/1/myrepo
# 🌳 Returning 2 (in-use) at ~/.treehouse/myrepo-a1b2c3/2/myrepo
# 🌳 Returned 2 of 2 held worktree(s); 0 skipped; 1 not held.
Held means somebody has the slot: leased, in-use, dirty, unverified, and you're here when the slot is any of those underneath. Three kinds of slot are left alone. An available slot has nothing to return. A damaged slot's marker is missing or unreadable, so neither the detach nor the reset a return performs can be judged safe - treehouse destroy, which status spells out for such a slot, is what removes it. And a slot reported you're here that is otherwise parked, clean and quiet is held by nobody: your own shell standing in it is the only reason status does not call it available, and treehouse enter is documented to leave pool state untouched, so --all must not reset it either.
Naming any of them explicitly still returns it, including a bare treehouse return from inside the slot you are standing in: the narrow target is a deliberate act, while the bulk one must not surprise.
This target set is deliberately wider than the other bulk verbs. prune never touches a leased slot, and destroy removes one only when its exact path is named with --include-leased; --all clears leased and in-use slots. Those verbs delete a worktree, while a return keeps it in the pool, and reclaiming a whole pool whose agents are gone is what the verb is for. Terminate the agents first if they are still working.
Two outcomes are reported as skipped, count against neither the returns nor the failures, and leave the slot exactly as it was:
- No longer the acquisition the listing saw.
--alllists the pool once and then works through it, so an earlier confirmation can hold the run open while a later slot changes state. Each release is pinned to the lease the listing saw: a slot that was leased is refused unless that same lease is still on it - whether it was handed to someone else or simply returned in the meantime - and a slot that was not leased is refused if it has been leased since. The report says only that the slot is no longer the acquisition the run listed, because the lease identity is all that was compared. That is also the whole guarantee: a slot handed to another plaintreehouse getcarries no lease to compare, so it is returned like any other in-use slot, which is what--alldoes to in-use slots by design. - Still recovered. A slot that remains quarantined after the automatic recovery check is skipped by
--all. A missing or invalid state key can relabel a whole pool at once. The check runs again under the state lock at each release, so a slot recovered after the listing is skipped too, before the dirty confirmation. The run namestreehouse returnfor each remaining slot: after inspecting it, that named return releases it, confirming first if it has uncommitted changes, and warns that any ignored files treehouse seeded into it are not cleaned up.treehouse destroy --include-leased --yesremoves it instead.
Each worktree is returned exactly as naming it would be, including the confirmation before uncommitted changes are discarded. Declining one - or failing to return one - never stops the worktrees after it, and the summary names every slot that was left behind. --all takes no path or name, and cannot be combined with --if-lease-id or --if-lease-holder, which identify a single acquisition.
treehouse return exits 0 only when the worktree was actually returned:
| Exit | Meaning |
|---|---|
0 |
The worktree was returned and any lease on it was released |
1 |
The return failed: unmet lease conditions, process termination, or reset |
3 |
The worktree was not returned, and is exactly as it was found: it has uncommitted changes and cleaning was declined, or the confirmation could not be answered |
--all reports the same statuses for the whole run: 0 when every held worktree was returned or skipped, 3 when the only thing that stopped a return was an abort, and 1 when any worktree failed. A skip is never a failure: nothing went wrong, so a retry would only report it again. A run in which every held slot was skipped still exits 0 and leaves the pool exactly as it was - nothing it set out to return was still there to return. A failure outranks an abort because the two need opposite responses - retry one, clean or --force the other.
treehouse get uses the same exit 3 when its subshell exits and leaves the worktree dirty, because it leaks the slot the same way: the worktree stays dirty, so a later get skips it and prune will not reclaim it. Exiting a get subshell while another session holds a durable lease on that slot is not this case and still exits 0, because a leased slot was never that session's to return.
Exit 3 is separate from 1 because the two need different handling. A failure is worth retrying; an unreturned dirty worktree stays unreturned until someone cleans it or passes --force, so a caller that retries on it will loop.
For retry-safe automation, condition the return on the identity from allocation or status:
treehouse return --force \
  --if-lease-id "$lease_id" \
  --if-lease-holder "$lease_holder" \
  "$path"
Treehouse compares supplied conditions while holding the pool state lock. A missing lease or mismatch exits nonzero before process termination, worktree reset, or state clearing. The same lock fences a matching return through the final clear, so the identity succeeds once and cannot release a later acquisition of the same path. --if-lease-holder is optional; use --if-lease-id for ABA protection when a holder may be reused.
For backward compatibility, treehouse return without either condition keeps its original unconditional path-only behavior. Existing path-only scripts and treehouse get --lease stdout are unchanged.
Recovering missing pool state
Treehouse writes treehouse-state.json atomically, so a crash mid-write should leave the previous state file intact.
If an existing state file is empty, truncated, or otherwise invalid, commands do not fail just because the JSON cannot be parsed.
They print a warning and rebuild the pool entries from worktree directories still on disk.
Commands also restore an on-disk worktree that is missing from an otherwise valid state file, covering the narrow case where worktree creation succeeded but recording its quarantine failed.
Every restored entry is marked leased because treehouse cannot know whether it was idle, in-use, or durably leased.
Both routes scan the pool directory, so a worktree that worktree_path placed outside it is not rebuilt — see Worktree path for how to remove one.
Run treehouse status to inspect recovered entries.
State from 3.0 or later whose pool-local treehouse-state.key is missing, or whose seed inventory fails to verify, is handled the same way, and so is any state beside an invalid key.
State from a release before 3.0 is the exception: it never seeded ignored files, so treehouse adopts it as is.
treehouse 3.0.0 got that wrong and quarantined every entry of pre-3.0 state as recovered; those entries read like any other recovered entry, because nothing left in the state file can tell a slot that was idle from one that was durably leased.
Unversioned state is adopted the same way when a still-running 2.x binary rewrites it after 3.0 has already run in the pool, for example when an agent session outlives the upgrade.
This is a known limitation: such a rewrite drops the record of ignored files that 3.0 seeded from .worktreeinclude, so a later reset of that slot does not remove them and they stay in it when the slot is reused.
Treehouse 3.0.2 automatically frees a recovered Git slot on the next command that examines pool state only when it proves no process is using it, tracked files are unchanged, and HEAD is contained in a remote-tracking ref or the slot's base branch. On Unix, untracked files do not block recovery: treehouse moves them, without deleting them, into that slot's fixed backup folder before freeing the slot. The folder sits beside the pool, in the treehouse root, and is named treehouse-recovered-backup--: slot 1 of the pool ~/.treehouse/myrepo-a1b2c3 is backed up to ~/.treehouse/treehouse-recovered-backup-myrepo-a1b2c3-1. Treehouse keeps that folder owner-only (0700), tightening an existing folder you own; it refuses to move files into the folder if it belongs to another user, cannot be tightened, or it or a destination folder inside it is a symlink, and keeps the slot leased instead. On Windows, where a new folder inherits its parent's access rules, treehouse never moves untracked files: a recovered slot with untracked files stays leased. Preserve them and return the slot by name, or remove them and let the next pool command recheck it; a recovered slot without untracked files can still be freed automatically. A retry after a failed move reuses the same folder and never overwrites a file already there (a name taken by an earlier attempt gets a numeric suffix such as notes.txt.1). While the folder holds anything, treehouse status shows it next to the slot. Keep and inspect that backup folder; it is never automatically removed.
Recovered jj slots cannot be automatically verified and stay leased until returned by name. Any slot that fails a check stays leased. treehouse status reports the specific reason and tells you to inspect the slot, resolve the issue, and run treehouse return by name. This includes active processes, tracked edits, an unpushed HEAD, and anything treehouse cannot verify. treehouse return --all continues to skip slots that remain recovered after the automatic check. To remove one instead, name its exact path with treehouse destroy --include-leased --yes; bulk destroy --all and prune leave recovered entries alone.
Recovery cannot reconstruct the inventory of ignored files treehouse seeded into the worktree. Such files are not included in the untracked-file backup and can remain in the slot when it is reused; inspect and preserve any seeded ignored files yourself before returning or reusing a recovered slot. This known limitation is unchanged.
Pruning stale worktrees and orphans
treehouse prune is a dry run by default.
By default, it lists stale idle managed worktrees that would be deleted and shows the reclaimable disk space.
Pass treehouse prune --yes to delete those worktrees.
By default, prune only inspects the current repository's pool and must be run inside a repository.
Pass treehouse prune --all or treehouse prune --global to inspect every managed pool under the user-level treehouse root from any directory.
Global prune reads the user-level config and hooks.
Both forms derive each worktree's owning repository from its own version-control metadata, then fetch and check merge safety against that repository, so a pool shared by two clones of the same remote is pruned from either clone.
Without --prune-orphans, pass treehouse prune --all --yes to delete only the globally safe stale candidates.
Prune ignores worktrees that are currently in use, leased, or reserved by another lifecycle operation.
It skips idle worktrees that are unsafe to remove and prints the skip reason, such as uncommitted tracked or untracked changes, or an unlanded HEAD commit (see Base branch for the merge rule).
Skip output is grouped by reason so large global sweeps stay scannable.
When origin exists, prune fetches it and checks the current remote default branch tracking ref first.
Without origin, prune checks the local default branch ref first.
If origin cannot be reached, prune reports origin unreachable (cannot verify) and leaves the worktree untouched, even when --prune-orphans is set.
If a linked worktree points at a missing backing repository, prune reports orphaned (backing repository missing).
Plain treehouse prune and treehouse prune --all never delete those orphans.
Pass --prune-orphans to include true backing-repository-missing orphans in the dry run, then add --yes to delete them.
Treehouse cannot verify orphan contents after the backing version-control metadata is gone, so each orphan candidate is marked content could not be verified.
Use --verbose to show the underlying version-control diagnostic details for skipped worktrees.
Destroying worktrees
treehouse destroy is the deliberate tool for removing a worktree even though it still has unlanded work, but it is safe by default and holds itself to the same bar as prune.
Targets are narrow and explicit:
treehouse destroytargets exactly one worktree.treehouse destroy --alltargets worktrees in THAT pool only. The pool path can be the pool directory, a worktree inside it, or the repository (.works from inside a repo).
Like prune, destroy judges and removes each worktree through its own owning repository, so either clone sharing a pool can destroy the other clone's worktrees.
There is no cross-pool or global destroy: --all without a pool path is an error, so a stray command can never reach beyond the pool you named.
Destroy is a dry run by default.
It prints a risk-revealing preview - one or more status labels ([disposable], [leased], [in-use:], [unmerged], [dirty], [unverified], or a comma-separated combination such as [leased,dirty]), the path, and the size of each target - and removes nothing.
Pass --yes to execute.
It never prints a blind "all worktrees destroyed"; the summary always reports exactly what was destroyed and what was skipped.
A bare treehouse destroy --all --yes removes only the genuinely disposable set (merged, clean, idle, unleased - the same set prune would take) and SKIPS everything else, telling you which flag would include it.
Each risky class is its own opt-in, so removing risky worktrees can never be a reflexive --yes:
--include-unlandedalso removes worktrees with uncommitted changes, a HEAD not merged into the default branch, or contents treehouse cannot verify, such as a missing backing repository (irreversible data loss).--include-in-usealso removes worktrees with a running process or owner reservation; their processes are terminated cleanly first and their pids are shown in the preview.--include-leasedalso removes a leased worktree, but only when you name the exact worktree path. Leased worktrees are NEVER removed by--all; combining--include-leasedwith--allis rejected.
A single named worktree that is skipped for lack of a flag makes the command exit non-zero, so scripts notice that nothing happened.
Bulk --all skips are normal and exit zero; inspect the summary to see what remains.
Migrating from --force
The old blunt treehouse destroy --force flag has been removed.
It overrode every protection at once - in-use, unmerged, dirty, and leased - which is what made it dangerous.
Replace it with the specific --include-* flag(s) for the risk you actually intend to override, plus --yes:
| Old | New |
|---|---|
treehouse destroy --force |
treehouse destroy --yes (add --include-unlanded / --include-in-use / --include-leased as needed) |
treehouse destroy --all --force |
treehouse destroy --all --yes (add --include-unlanded for dirty, unmerged, or unverified targets, and --include-in-use for in-use targets; leased homes are never included) |
Configuration
Create a repo config file with treehouse init, or add one manually:
Repo-level: treehouse.toml in the repository root
User-level: ~/.config/treehouse/config.toml
# Maximum number of worktrees in the pool
max_trees = 16

# Optional worktree root directory.
# Empty uses $HOME/.treehouse.
# Relative paths are resolved from the repo root for repo-scoped commands.
# Use "." to keep the pool inside the project (see "In-project storage" below).
# Use an absolute user-level root for treehouse prune --all.
# root = "$HOME/worktrees"

# Optional base branch worktrees are cut from.
# Unset infers it from the repository (see "Base branch" below).
# base_branch = "develop"

# Optional unique worktree directory names.
# Names new slots - instead of  (see "Unique worktree
# directory names" below).
# unique_leaf = true
# Optional path for newly created worktrees.
# Unset uses {pool}/{slot}/{repo} (see "Worktree path" below).
# worktree_path = "{repo_parent}/{repo}-{slot}"

# Optional tracked-file sharing (see "APFS copy-on-write sharing" above).
# apfs_sharing = "fresh"

# Optional version-control backend. Git is the default everywhere; set "jj"
# to opt in to the experimental Jujutsu backend
# (see "Version-control backend" below).
# vcs = "jj"
The repo-level config takes precedence for repo-safe settings.
treehouse prune --all can run without a repository, so it uses only the user-level config and does not read per-repo treehouse.toml files while sweeping.
If no config is found, the default pool size is 16.
Base branch
By default Treehouse infers the branch worktrees are cut from: origin/HEAD, then the checked-out branch, then init.defaultBranch.
That inference is invisible and can drift — origin/HEAD is only set at clone time, and some clones never have it at all.
Set it explicitly for the whole pool:
base_branch = "develop"
or for a single acquisition:
treehouse get --base develop
treehouse get --lease --base release/2.x --json
--base wins over base_branch, and both are opt-in: with neither set, the inference is unchanged.
A few things worth knowing:
- Worktrees stay in detached HEAD by default.
--baseselects only the starting commit; it does not itself create or check out a branch. Add-b/--branchto create and check out a new local Git branch at that commit, including withget --leasefor non-interactive use.--branchdoes not change base selection; existing or invalid branch names fail instead of selecting another name or commit. The jj backend rejects--branch. - Returning a worktree leaves its named branch intact.
treehouse returndetaches and resets the slot for reuse; it does not delete the branch. - Failed branch checkout keeps the branch and worktree. If Git creates the branch but checkout fails or a checkout hook moves it away from the acquired commit,
getfails without handing off the slot. Treehouse quarantines the worktree for inspection, preserving files the hook may have written; the slot remains unavailable until you resolve it. The branch is also left in place because another worktree may have checked it out. If a checkout hook exits nonzero but leaves the requested branch at the acquired commit, acquisition succeeds and its diagnostic goes to stderr, not--leasestdout. - A concurrent branch-name collision can leave a slot quarantined. Known collisions fail before a slot is reset or created. If the name is taken after that check and a reference-transaction hook could have written files, or the new worktree contains files beyond Treehouse's known seed copies, Treehouse preserves the worktree for inspection rather than deleting its contents. A post-checkout hook alone does not cause quarantine when checkout never ran.
- Base branch names only. For
--base, usedevelop, notorigin/develop, a tag, or a commit SHA. Whichever ofdevelopandorigin/developis further ahead wins, preferringoriginwhen they have diverged — exactly how the inferred default behaves. A tag sharing a branch's name never wins: refs are resolved fully qualified. - It fails closed. A base that resolves to neither a local branch nor
origin/is an error; Treehouse never falls back to the inferred default, which would hand you a worktree cut from the wrong branch and report success.treehouse statusshows the resolved base, and flags a configured one it cannot resolve. - Returned worktrees are parked on the base they were cut from, so the pool keeps recycling.
base_branchwins when it is set; otherwise a slot acquired with--baseis parked back on that branch. A slot parked elsewhere could not be reused whenever the base is not a descendant of it. Prune and destroy also accept a clean slot whose HEAD is merged into its recorded explicit base even when it is not merged into the default branch; slots without an explicit base must pass the default-branch check. - Existing pools migrate on their own. A slot is recycled onto a newly requested base as long as it carries nothing beyond the base it was cut from; the two bases need no ancestry relation, so a
developslot rejoins a plaintreehouse getand vice versa. A slot holding commits the new base does not contain is still refused, as always. - Git backend only for now. Under the jj backend an explicit base fails with a clear error rather than silently using the default bookmark.
Unique worktree directory names
Every pool slot lives at //, so the directory a worktree is checked out in is named after the repository and is the same for every slot:
~/.treehouse/myproject-a1b2c3/1/myproject
~/.treehouse/myproject-a1b2c3/2/myproject
The parent directory (1, 2) already distinguishes them, but tooling that derives per-checkout identity from the last path segment cannot see it — a test-harness database name, a Compose project name, a cache key. Two agents working in two slots collide on one identity.
Opt in to a leaf that is unique within the pool:
treehouse get --unique-leaf
export TREEHOUSE_UNIQUE_LEAF=1   # for a shell session
or for the whole pool in treehouse.toml:
unique_leaf = true
~/.treehouse/myproject-a1b2c3/1/myproject-1
~/.treehouse/myproject-a1b2c3/2/myproject-2
The resolved value follows the same precedence as --root (highest first):
- The
--unique-leafflag (--unique-leaf=falseturns it off for one acquisition) - The
TREEHOUSE_UNIQUE_LEAFenvironment variable unique_leafin the repo-leveltreehouse.tomlunique_leafin the user-level~/.config/treehouse/config.toml- The default, off
A few things worth knowing:
- It is off by default, and with it off nothing about the layout changes.
- It only names slots treehouse creates from now on. A worktree already in the pool keeps the path recorded in pool state: turning the option on never moves, renames, or invalidates one. To convert an existing pool,
treehouse destroyits slots and re-acquire. - The name is stable. The slot number is part of the leaf, so a slot recycled by a later
gethands back the same path it had before. - Both layouts coexist in one pool. Status, prune, destroy, and lease handling read paths from pool state and never assume the leaf, so slots created before and after the opt-in live side by side.
Worktree path
New pool slots are created at {pool}/{slot}/{repo}, for example ~/.treehouse/myapp-a1b2c3/1/myapp.
Some tooling only works when a checkout sits at a particular location relative to something else — build systems that find a project root by walking up a fixed number of directories from the package directory are the common case, and a pool three levels deeper silently resolves the wrong root.
Set worktree_path to place new slots yourself:
# worktrees become siblings of the repository: /myapp-1, /myapp-2
worktree_path = "{repo_parent}/{repo}-{slot}"
or for a single acquisition:
treehouse get --lease --worktree-path '{repo_parent}/{repo}-{slot}'
or for every acquisition in one shell session:
export TREEHOUSE_WORKTREE_PATH='{repo_parent}/{repo}-{slot}'
| Placeholder | Expands to |
|---|---|
{slot} |
The slot name (1, 2, …). Required — without it every slot resolves to one directory. |
{repo} |
The repository directory's name |
{repo_parent} |
The directory holding the repository |
{pool} |
This repository's pool directory |
One of {pool} or {repo} is also required, because slot names are allocated per pool: a user-level $HOME/trees/{slot} would send the first slot of every repository to $HOME/trees/1. {repo_parent} does not count — two repositories side by side expand it to the same directory, so {repo_parent}/{slot} collides exactly the same way. It stays available as a placeholder; it just has to be paired, as in {repo_parent}/{repo}-{slot}.
The template must resolve to an absolute path, so anchor it on {pool}, {repo_parent}, or an absolute prefix of your own: a bare {repo}-{slot} is rejected rather than resolved against whichever directory you happened to run get from.
$VAR and ${VAR} expand as well, exactly like root, and they expand before the placeholders are read — so ${HOME}/trees/{repo}-{slot} works, and ${slot} is an environment variable rather than the slot placeholder.
A variable the environment leaves empty is an error rather than an empty path segment, because dropping a directory would place worktrees somewhere the template does not name, and differently depending on whether the invoking shell, cron job, or CI runner exports it. ${} and a ${ with no closing brace are errors for the same reason. A value that ends in a separator is fine — path cleaning collapses the doubled separator and the worktree lands where the template names.
The resolved value follows the same precedence as --root (highest first): the --worktree-path flag, the TREEHOUSE_WORKTREE_PATH environment variable, worktree_path in the repo-level treehouse.toml, then in the user-level config.
A few things worth knowing:
- It is off by default. With nothing set, the layout is unchanged.
- It supersedes
unique_leaf. A template names every segment of the path, including the leaf, so there is nothing left forunique_leafto rename; write{repo}-{slot}in the template for the same effect. Setting both warns once on stderr rather than silently picking one. - It applies only to slots created from now on. Worktrees already in the pool keep the path recorded in state — nothing is moved, renamed, or invalidated — so both layouts coexist in a pool until the old slots are destroyed and re-acquired. Recycling, leases,
status,return,prune, anddestroyall key off the recorded path, so they behave the same wherever a slot lives. - A template that would corrupt the pool is rejected before anything is created: a missing
{slot}or repository-scoping placeholder, a misspelled placeholder, a template that resolves to the same directory for every slot (path cleaning cancels..against the segment before it, so{slot}/../sharedwould send every slot to one directory; a..that only walks up inside a variable's value is fine), a path that is or contains the repository or the pool directory, and a path inside the repository working tree (where the worktree would show up as untracked content). Inside the pool directory a template must stay at{pool}/{slot}/, because that is the depth pool-state recovery scans, and it must be spelled through the pool directory itself rather than through a symlink into it, so pool state and recovery name that worktree the same way. A path inside another repository's pool directory is rejected too: that pool's recovery would register the worktree as a slot of its own, which consumes one of its slots for good and leaves the owning repository unable to return it. A worktree beside the pools, under the Treehouse root, is fine — the root holds pools without being one. Placement is judged on canonicalized paths, so a symlink pointing back into the repository or the pool is caught rather than followed. Every one of these checks runs on everyget, including the acquisitions that recycle a slot and so never use the template, so what a template is rejected for never depends on how full the pool is. - An existing directory is never adopted, and never wedges the pool.
{repo}alone still collides between two repositories that share a directory name, and no template can rule every collision out, so a templated path that already exists is never quietly turned into a second pool's worktree.getwarns on stderr, skips that slot name and tries the next one instead, up tomax_treescandidates, so a stray directory — which is what a lost state file leaves behind, since recovery only scans the pool directory — costs a slot name rather than every acquisition. Only when every candidate path is occupied doesgetfail; it names them, says treehouse never adopts an existing directory, and points atgit worktree listand Recovering missing pool state so you can decide what the occupants are, rather than prescribing a command whose preconditions it cannot check. The built-in layout is untouched by this check. - Only the worktree is deleted. Under the built-in layout
pruneanddestroyalso remove the numbered slot directory, which exists solely to hold the worktree. A worktree placed elsewhere has a parent Treehouse does not own, so its parent is left alone. - Recovering a lost state file is pool-local.
ReadStatereconstructs missing entries by scanning the pool directory, so worktrees placed outside it cannot be recovered that way; the pool keeps working — latergets skip the names those worktrees occupy — but remove such a worktree withgit worktree remove(orjj workspace forget) to get its slot name back. - Under the jj backend, seeding leaves an empty directory behind. With a
.worktreeincludemanifest, a worktree placed outside the pool leaves an empty hidden.treehouse-jj-seed-authdirectory in the parent the template chose. Its entries are removed with the worktree; the directory itself stays, because removing it safely would need a lock across every pool that shares that parent.
Version-control backend (git or Jujutsu)
Treehouse works in git and Jujutsu (jj) repositories. The jj backend is experimental: it is newer than the git backend and has seen far less production use, so treat it accordingly and report issues. In a jj repository, pooled worktrees are jj workspaces instead of git worktrees; the pool, lease, and safety machinery is identical.
Git is the default backend everywhere, including in colocated repositories (both .jj and .git) and .jj-only repositories.
Opt in to the jj backend with vcs = "jj", resolved in this precedence (highest first): the TREEHOUSE_VCS environment variable, the repo-level treehouse.toml, the user-level ~/.config/treehouse/config.toml.
The jj opt-in only applies where a .jj directory actually exists; in a plain git repository it is silently ignored and git is used, so a shell-wide TREEHOUSE_VCS=jj never breaks git-only repositories.
A vcs value other than "git" or "jj" (e.g. "Jujutsu") is ignored the same way, but warns once on stderr naming the value and where it came from, so a typo keeps commands working without silently leaving you on the wrong backend.
Pooled jj workspaces inherit the opt-in from their main repository root, so an untracked treehouse.toml there is enough.
The backend is resolved on every command, and existing pool slots keep the flavor they were created with: changing the opt-in does not convert worktrees already in the pool.
destroy and prune handle each slot by its own flavor (its .git or .jj marker), so a git worktree is still cleanly deregistered from git even after opting the repository into jj, and vice versa.
A slot whose marker is missing entirely (a damaged slot) is never reused, reset, or detached; treehouse status reports it as damaged even when you are standing in it, treehouse return only clears its lease (and --all leaves it alone), treehouse lease still protects it but reports an empty base_branch rather than reading one through a fallback backend, prune reports it as unverifiable, and treehouse destroy --include-unlanded removes it.
treehouse get is flavor-aware too: it only reuses slots matching the backend the repository currently selects, and creates new slots with that backend, so a caller who opted in to jj is never handed a git worktree (or vice versa).
Old-flavor slots stay in the pool untouched — treehouse status marks them and they count toward max_trees — until you migrate them: treehouse destroy the old slots and re-acquire with treehouse get.
jj-backend notes:
- Pooled worktrees are jj workspaces and are not colocated: they contain
.jjbut no.git, so run jj commands (not git) inside them. - A worktree is considered dirty when its working-copy commit
@is non-empty or has a description. - Resets abandon only the working-copy commit and are recoverable with
jj op restore. - Merge detection uses ancestry; squash-merged work is treated as unmerged, so lifecycle commands err on the side of keeping it.
- The default branch resolves to the
main/master/trunkbookmark, preferring origin. - A pooled jj workspace whose backing repository was deleted is classified as an orphan just like a git worktree:
prunereports it, andprune --prune-orphans --yesreclaims it.
Worktree root
The worktree root can also be set without a config file, and the resolved value follows this precedence (highest first):
- The
--rootflag (e.g.treehouse get --root .) - The
TREEHOUSE_ROOTenvironment variable rootin the repo-leveltreehouse.tomlrootin the user-level~/.config/treehouse/config.toml- The default,
~/.treehouse
A relative value (including .) is resolved from the repo root, exactly like a relative root in config; treehouse is always appended, so --root . places the pool at /.treehouse/.
In-project storage
By default the pool lives in the global ~/.treehouse store. Set the root to . to keep it inside the project instead:
treehouse get --root .          # one-off
export TREEHOUSE_ROOT=.         # for a shell session
or commit it for the whole repo in treehouse.toml:
root = "."
This is opt-in; the default global store is unchanged. In-project mode:
- Places the pool at
/.treehouse/, so worktrees sit next to the code and are removed with the project (rm -rfleaves no global orphan). - Git-ignores the pool directory automatically, so it stays out of
git add. - Is not reached by
treehouse prune --all, which only sweeps the global root; in-project pools are removed with the project instead.
Hooks
You can run commands automatically at worktree lifecycle points by adding a [hooks] section to the user-level config at ~/.config/treehouse/config.toml.
Hooks in repo-level treehouse.toml are ignored for safety, so that running treehouse in an untrusted clone cannot execute checked-in shell.
During a command, treehouse warns once per repo-level treehouse.toml on stderr, naming the file and any ignored lifecycle hook keys declared under [hooks] rather than dropping them silently.
treehouse destroy always reads pre_destroy from the user-level config because it can target a pool by path.
[hooks]
post_create = ["./scripts/setup-venv.sh"]
pre_destroy = ["./scripts/teardown.sh"]
post_createruns after a worktree is provisioned or reset and right beforetreehouse gethands it to you. Fortreehouse get --lease, stdout frompost_createis routed to stderr so stdout remains the leased path.pre_destroyruns before a worktree is removed bytreehouse destroy --yes,treehouse destroy --all --yes, or prune deletion commands such astreehouse prune --yesandtreehouse prune --prune-orphans --yes.
Commands in each list run sequentially in the worktree directory, via the OS shell (/bin/sh -c on Linux/macOS, %COMSPEC% /c on Windows).
If a command exits non-zero, treehouse logs the command, exit code, and stderr, then continues with the remaining commands.
A failing hook does not fail the overall get, destroy, or prune operation.
Development
make build          # Build the binary
make test           # Run tests
make lint           # Run gofmt + go vet
make dist           # Cross-compile for all platforms
make install        # Install to $GOPATH/bin or /usr/local/bin
make clean          # Remove build artifacts