← 开源
konpatp

diffae

Official implementation of Diffusion Autoencoders

Model DevelopmentArchitectureJupyter Notebook
在 GitHub 打开
增长势头
+024 小时新增 Star0.0%
974
Star
159
Fork
+0
本周
3
贡献者
创建于 2022-01-11 · 更新于 2026-10-06 · 今日第 12294 名
主要开发者
konpatpnessessencechenxwh

konpatp/diffae 排名第 12,294,有 974 个星标。

同类别比较

konpatp/diffae 排名第 12,294,此处有 8 个同类条目;salesforce/OmniXAI 排名第 12,296。

同类别比较
名称排名指标
microsoft/Samba12,268
语言:
Python
星标数:
978
分叉数:
52
简介:
[ICLR 2025] Samba: Simple Hybrid State Space Models for Efficient Unlimited Context Language Modeling
timqian/bambot12,270
语言:
TypeScript
星标数:
978
分叉数:
96
简介:
Play with open source, low-cost AI robots with ease 🤖
jacobgil/keras-dcgan12,273
语言:
Python
星标数:
977
分叉数:
402
简介:
Keras implementation of Deep Convolutional Generative Adversarial Networks
facebookresearch/localrf12,279
语言:
Python
星标数:
976
分叉数:
60
简介:
An algorithm for reconstructing the radiance field of a large-scale scene from a single casually captured video.
salesforce/OmniXAI12,296
语言:
Jupyter Notebook
星标数:
974
分叉数:
108
简介:
OmniXAI: A Library for eXplainable AI
PlexPt/chatgpt-corpus12,298
星标数:
973
分叉数:
146
简介:
ChatGPT 中文语料库 对话语料 小说语料 客服语料 用于训练大模型
ProHiryu/bert-chinese-ner12,301
语言:
Python
星标数:
972
分叉数:
274
简介:
使用预训练语言模型BERT做中文NER
YehLi/xmodaler12,302
语言:
Python
星标数:
972
分叉数:
104
简介:
X-modaler is a versatile and high-performance codebase for cross-modal analytics(e.g., image captioning, video captioning, vision-language pre-training, visual question answering, visual commonsense reasoning, and cross-modal retrieval).
关键参数与规格
关键参数与规格
参数值
语言Jupyter Notebook
类别Model Development
子类别Architecture
关键词Diffusion
星标数974
分叉数159
贡献者3
创建日期2022-01-11
更新日期2026-10-06
1 天星标数0
7 天星标数0
排名12,294
上次排名12,222
排名变化-72
7 天星标排名13,352
上次 7 天星标排名13,364
7 天星标排名变化12
总星标排名11,382
上次总星标排名11,366
总星标排名变化-16
国家USA
README 摘录

Official implementation of Diffusion Autoencoders A CVPR 2022 (ORAL) paper (paper, site, 5-min video): Usage Note: Since we expect a lot of changes on the codebase, please fork the repo before using. Prerequisites See Quick start A jupyter notebook. For unconditional generation: For manipulation: For interpolation: For autoencoding: Aligning your own images: 1. Result images will be available in directory Original in directory Aligned with Using Checkpoints We provide checkpoints for the following models: 1. DDIM: **FFHQ128** (72M, 130M

), **Bedroom128**, **Horse128** 2. DiffAE (autoencoding only): **FFHQ256**, **FFHQ128** (72M, 130M), **Bedroom128**, **Horse128** 3. DiffAE (with latent DPM, can sample): **FFHQ256**, **FFHQ128**, **Bedroom128**, **Horse128** 4. DiffAE's classifiers (for manipulation): **FFHQ256's latent on CelebAHQ**, **FFHQ128's latent on CelebAHQ** Checkpoints ought to be put into a separate directory . Download the checkpoints and put them into directory. It should look like this: LMDB Datasets We do not own any of the following datasets. We provide the LMDB ready-to-use dataset for the sake

of convenience. FFHQ CelebAHQ **Broken links** Note: I'm trying to recover the following links. CelebA LSUN Bedroom LSUN Horse The directory tree should be: You can also download from the original sources, and use our provided codes to package them as LMDB files. Original sources for each dataset is as follows: FFHQ ( CelebAHQ ( CelebA ( LSUN ( The conversion codes are provided as: Google drive: Training We provide scripts for training & evaluate DDIM and DiffAE (including latent DPM) on the following datasets

: FFHQ128, FFHQ256, Bedroom128, Horse128, Celeba64 (D2C's crop). Usually, the evaluation results (FID's) will be available in directory. Note: Most experiment requires at least 4x V100s during training the DPM models while requiring 1x 2080Ti during training the accompanying latent DPM. **FFHQ128** A classifier (for manipulation) can be trained using: **FFHQ256** We only trained the DiffAE due to high computation cost. After the task is done, you need to train the latent DPM (requiring only 1x 2080Ti) A classifier (for manipulation

) can be trained using: **Bedroom128** **Horse128** **Celeba64** This experiment can be run on 2080Ti's.

常见问题

记录了多少星标和分叉?

konpatp/diffae 有 974 个星标和 159 个分叉。

仓库排名是多少?

konpatp/diffae 排名第 12,294。

记录的语言和类别是什么?

konpatp/diffae 有 974 个星标,语言为 Jupyter Notebook,类别为 Model Development。

哪个仓库排名最接近?

konpatp/diffae 与 salesforce/OmniXAI 比较,后者排名第 12,296,有 974 个星标。

README

Official implementation of Diffusion Autoencoders

A CVPR 2022 (ORAL) paper (paper, site, 5-min video):

@inproceedings{preechakul2021diffusion,
      title={Diffusion Autoencoders: Toward a Meaningful and Decodable Representation}, 
      author={Preechakul, Konpat and Chatthee, Nattanat and Wizadwongsa, Suttisak and Suwajanakorn, Supasorn},
      booktitle={IEEE Conference on Computer Vision and Pattern Recognition (CVPR)}, 
      year={2022},
}

Usage

⚙️ Try a Colab walkthrough:

🤗 Try a web demo:

Note: Since we expect a lot of changes on the codebase, please fork the repo before using.

Prerequisites

See requirements.txt

pip install -r requirements.txt

Quick start

A jupyter notebook.

For unconditional generation: sample.ipynb

For manipulation: manipulate.ipynb

For interpolation: interpolate.ipynb

For autoencoding: autoencoding.ipynb

Aligning your own images:

  1. Put images into the imgs directory
  2. Run align.py (need to pip install dlib requests)
  3. Result images will be available in imgs_align directory

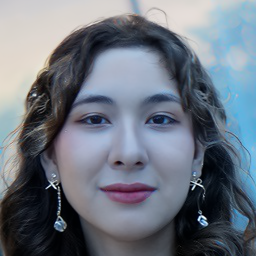
Original in imgs directory

Aligned with align.py
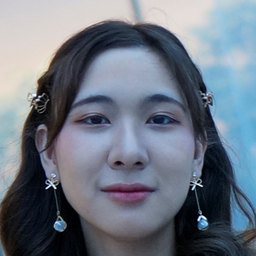
Using manipulate.ipynb
Checkpoints

We provide checkpoints for the following models:

  1. DDIM: FFHQ128 (72M, 130M), Bedroom128, Horse128
  2. DiffAE (autoencoding only): FFHQ256, FFHQ128 (72M, 130M), Bedroom128, Horse128
  3. DiffAE (with latent DPM, can sample): FFHQ256, FFHQ128, Bedroom128, Horse128
  4. DiffAE's classifiers (for manipulation): FFHQ256's latent on CelebAHQ, FFHQ128's latent on CelebAHQ

Checkpoints ought to be put into a separate directory checkpoints. Download the checkpoints and put them into checkpoints directory. It should look like this:

checkpoints/
- bedroom128_autoenc
    - last.ckpt # diffae checkpoint
    - latent.ckpt # predicted z_sem on the dataset
- bedroom128_autoenc_latent
    - last.ckpt # diffae + latent DPM checkpoint
- bedroom128_ddpm
- ...

LMDB Datasets

We do not own any of the following datasets. We provide the LMDB ready-to-use dataset for the sake of convenience.

Broken links

Note: I'm trying to recover the following links.

The directory tree should be:

datasets/
- bedroom256.lmdb
- celebahq256.lmdb
- celeba.lmdb
- ffhq256.lmdb
- horse256.lmdb

You can also download from the original sources, and use our provided codes to package them as LMDB files. Original sources for each dataset is as follows:

The conversion codes are provided as:

data_resize_bedroom.py
data_resize_celebhq.py
data_resize_celeba.py
data_resize_ffhq.py
data_resize_horse.py

Google drive: https://drive.google.com/drive/folders/1abNP4QKGbNnymjn8607BF0cwxX2L23jh?usp=sharing

Training

We provide scripts for training & evaluate DDIM and DiffAE (including latent DPM) on the following datasets: FFHQ128, FFHQ256, Bedroom128, Horse128, Celeba64 (D2C's crop). Usually, the evaluation results (FID's) will be available in eval directory.

Note: Most experiment requires at least 4x V100s during training the DPM models while requiring 1x 2080Ti during training the accompanying latent DPM.

FFHQ128

# diffae
python run_ffhq128.py
# ddim
python run_ffhq128_ddim.py

A classifier (for manipulation) can be trained using:

python run_ffhq128_cls.py

FFHQ256

We only trained the DiffAE due to high computation cost. This requires 8x V100s.

sbatch run_ffhq256.py

After the task is done, you need to train the latent DPM (requiring only 1x 2080Ti)

python run_ffhq256_latent.py

A classifier (for manipulation) can be trained using:

python run_ffhq256_cls.py

Bedroom128

# diffae
python run_bedroom128.py
# ddim
python run_bedroom128_ddim.py

Horse128

# diffae
python run_horse128.py
# ddim
python run_horse128_ddim.py

Celeba64

This experiment can be run on 2080Ti's.

# diffae
python run_celeba64.py
排名相邻
同类项目