PyEPO: A PyTorch/JAX-based End-to-End Predict-then-Optimize Tool


Learning Framework
Publication
This repository is the official implementation of the paper: PyEPO: A PyTorch-based End-to-End Predict-then-Optimize Library for Linear and Integer Programming (Mathematical Programming Computation, 2024)
Citation:
@article{tang2024,
  title={PyEPO: a PyTorch-based end-to-end predict-then-optimize library for linear and integer programming},
  author={Tang, Bo and Khalil, Elias B},
  journal={Mathematical Programming Computation},
  issn={1867-2957},
  doi={10.1007/s12532-024-00255-x},
  year={2024},
  month={July},
  publisher={Springer}
}
If you use the CaVE loss, please also cite:
@inproceedings{tang2024cave,
  title={CaVE: A Cone-Aligned Approach for Fast Predict-then-Optimize with Binary Linear Programs},
  author={Tang, Bo and Khalil, Elias B},
  booktitle={Integration of Constraint Programming, Artificial Intelligence, and Operations Research},
  pages={193--210},
  year={2024},
  publisher={Springer}
}
Introduction
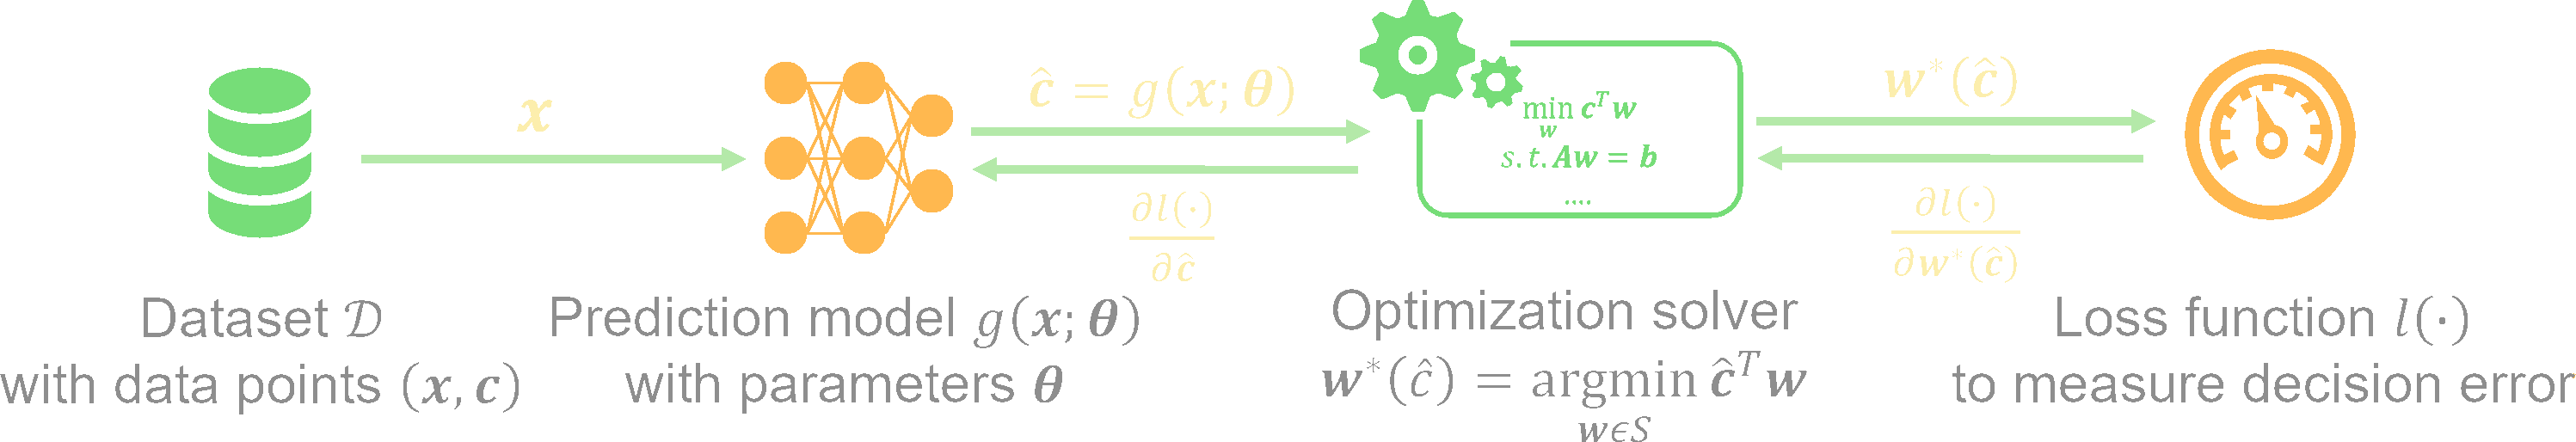
PyEPO is a Python library for predict-then-optimize. It focuses on problems where a model predicts objective coefficients and the feasible region is fixed, then trains the predictor against downstream decision quality rather than prediction error alone.
PyEPO models optimization problems with GurobiPy, COPT, Pyomo, Google OR-Tools, or MPAX, and exposes the optimization layer through PyTorch and JAX training frontends. The symbolic pyepo.dsl frontend can define LPs, MIPs, and supported fixed-quadratic objective terms, then compile the same model to a PyEPO backend.
For end-to-end learning on binary linear programs (TSP, CVRP, knapsack, ...), PyEPO includes CaVE [13], a cone-alignment loss that uses binding-constraint normals at the true optimum. CaVE requires optDatasetConstrs and a Gurobi-backed optModel for extracting binding constraints. In the CVRP-20 setup from notebook 04 (num_data=1000, 10 epochs, single process), CaVE+ trains 8.2x faster than SPO+; CaVE-Hybrid with solve_ratio=0.3 trains 10.5x faster with higher final regret.
PyEPO also integrates MPAX, a JAX-based solver for GPU batch solving of linear and quadratic programs.
Documentation
The official PyEPO docs can be found at https://khalil-research.github.io/PyEPO.
Slides
A PyEPO tutorial was presented at the ACC 2024 conference. The talk slides are available here.
Notebooks
 01 Optimization Model: Build an optimization solver
- 02 Optimization Dataset: Generate synthetic data and use optDataset
- 03 Training and Testing: Train method families on a shortest-path dataset
- 04 CaVE for Binary Linear Programs: Train with the cone-aligned CaVE loss on TSP
- 05 2D Knapsack Solution Visualization: Visualize solutions for the knapsack problem
- 06 Warcraft Shortest Path: Train shortest path models on the Warcraft terrains dataset
- 07 Real-World Energy Scheduling: Apply PyEPO to an energy scheduling dataset
- 08 kNN Robust Losses: Use optDatasetKNN for robust losses
- 09 Solving on MPAX with PDHG: Use MPAX for GPU-accelerated batch solving
- 10 JAX Frontend: Train PyEPO losses in JAX/Flax with
jax.grad
Experiments
To reproduce the experiments in the original paper, use the code and instructions in the MPC branch. That branch reflects an early PyEPO version and is intended for reproduction rather than current development.
Features
- End-to-end gradient surrogates for predict-then-optimize, covering the seven families in the docs:
- Surrogate losses: convex upper bound on regret (SPO+ [1]) and finite-difference directional gradient (PG [11]).
- Perturbed methods: Monte Carlo gradients over random cost perturbations: DPO and PFYL [5] [6], I-MLE [9], AI-MLE [10].
- Regularized methods: L2-regularized Frank-Wolfe over the convex hull of feasible solutions: RFWO and RFYL [6].
- Black-box methods: surrogate backward rules for discrete solvers: DBB [3] (interpolation) and NID [4] (signed identity).
- Cone-aligned estimation: project the predicted cost onto binding-constraint normals at the true optimum; binary linear programs only: CaVE [13].
- Contrastive methods: margin against a cached pool of non-optimal solutions: NCE and CMAP [7].
- Learning to rank: rank the true optimum highest among the pool: pointwise / pairwise / listwise LTR [8].
- Multi-solver backend under a unified
optModelAPI: Gurobi, COPT, Pyomo, Google OR-Tools, and the GPU-native MPAX PDHG solver. - Symbolic modeling with
pyepo.dsl: define an LP, MIP, or supported fixed-quadratic objective once withVariable,Parameter, and constraints, then compile it to a PyEPO backend. The compiled model is anoptModeland works with PyEPO training methods. - Parallel solving via a Pathos worker pool to amortize per-instance ILP solves across a mini-batch.
- Solution caching [7] reuses previously computed optima to skip redundant solver calls in contrastive and ranking training.
- kNN-smoothed targets [12] replace each label with a neighborhood aggregate for noise-robust regret.
Installation
Pip Install
Install the PyPI release with:
pip install pyepo
Conda Install
Install the Anaconda Cloud package with:
conda install -c pyepo pyepo
Install from Source
Clone PyEPO from GitHub.
git clone -b main --depth 1 https://github.com/khalil-research/PyEPO.git
Install the package from the local checkout.
pip install ./PyEPO/pkg
Solver Backends
PyEPO compiles optimization models onto a solver backend. A bare pip install pyepo does not install one; each backend has a pip extra that installs its package alongside PyEPO, e.g. pip install pyepo[gurobi] (also copt, pyomo, ortools, mpax, cave for the Clarabel-based CaVE loss, or all). The default backend is Gurobi; for a license-free setup, use Pyomo or OR-Tools with an open solver.
Dependencies
Core dependencies include:
Solver and frontend packages depend on the backend you use: GurobiPy, COPT, Pyomo, OR-Tools, MPAX, JAX, Flax, and optax are installed as needed.
Sample Code
An end-to-end predict-then-optimize example. The optimization model is defined with pyepo.dsl and compiled to Gurobi; change backend to use another PyEPO backend such as COPT, Pyomo, OR-Tools, or MPAX.
import pyepo
from pyepo import EPO, dsl
import torch
from torch import nn
from torch.utils.data import DataLoader

# generate knapsack data
num_item = 10
weights, feat, costs = pyepo.data.knapsack.genData(
    1000, 5, num_item, 3, deg=4, noise_width=0.5, seed=135,
)
capacity = (weights.sum(axis=1) * 0.5).astype(int)

# define the optimization problem
x = dsl.Variable(num_item, vtype=EPO.BINARY)
c = dsl.Parameter(num_item)
optmodel = dsl.Problem(dsl.Maximize(c @ x), [weights @ x <= capacity]).compile(backend="gurobi")

# build dataset
dataset = pyepo.data.dataset.optDataset(optmodel, feat, costs)
dataloader = DataLoader(dataset, batch_size=32, shuffle=True)

# train a linear predictor with SPO+
predmodel = nn.Linear(5, num_item)
spo = pyepo.func.SPOPlus(optmodel, processes=1)
optimizer = torch.optim.Adam(predmodel.parameters(), lr=1e-3)

for epoch in range(10):
    for xb, cb, wb, zb in dataloader:
        loss = spo(predmodel(xb), cb, wb, zb)
        optimizer.zero_grad()
        loss.backward()
        optimizer.step()

print("Training regret:", pyepo.metric.regret(predmodel, optmodel, dataloader))
JAX frontend (pyepo.func.jax)
End-to-end training of a shortest-path predictor on a 5x5 grid with the SPO+ loss (Flax + optax):
import jax
import jax.numpy as jnp
import optax
from flax import linen as nn

import pyepo
from pyepo.data.dataset import optDataset
from pyepo.func.jax import SPOPlus

# optimization model: 5x5 grid shortest path
grid = (5, 5)
optmodel = pyepo.model.shortestPathModel(grid)

# synthetic data
x, c = pyepo.data.shortestpath.genData(
    num_data=1000, num_features=5, grid=grid, deg=4, noise_width=0.5, seed=135,
)
ds = optDataset(optmodel, x, c)
xj = jnp.asarray(x, jnp.float32)
cj, wj, zj = (jnp.asarray(a, jnp.float32) for a in (ds.costs, ds.sols, ds.objs))

# linear predictor and SPO+ loss
predmodel = nn.Dense(optmodel.num_cost)
params = predmodel.init(jax.random.PRNGKey(0), xj[:1])
spo = SPOPlus(optmodel, reduction="mean")
optimizer = optax.adam(1e-2)
opt_state = optimizer.init(params)

# end-to-end training
for epoch in range(10):
    grads = jax.grad(lambda p: spo(predmodel.apply(p, xj), cj, wj, zj))(params)
    updates, opt_state = optimizer.update(grads, opt_state)
    params = optax.apply_updates(params, updates)
Reference
- [1] Elmachtoub, A. N., & Grigas, P. (2021). Smart "predict, then optimize". Management Science.
- [2] Mandi, J., Stuckey, P. J., & Guns, T. (2020). Smart predict-and-optimize for hard combinatorial optimization problems. In Proceedings of the AAAI Conference on Artificial Intelligence.
- [3] Vlastelica, M., Paulus, A., Musil, V., Martius, G., & Rolinek, M. (2020). Differentiation of blackbox combinatorial solvers. In International Conference on Learning Representations.
- [4] Sahoo, S. S., Paulus, A., Vlastelica, M., Musil, V., Kuleshov, V., & Martius, G. (2023). Backpropagation through combinatorial algorithms: Identity with projection works. In International Conference on Learning Representations.
- [5] Berthet, Q., Blondel, M., Teboul, O., Cuturi, M., Vert, J. P., & Bach, F. (2020). Learning with differentiable perturbed optimizers. Advances in neural information processing systems, 33, 9508-9519.
- [6] Dalle, G., Baty, L., Bouvier, L., & Parmentier, A. (2022). Learning with Combinatorial Optimization Layers: a Probabilistic Approach. arXiv:2207.13513.
- [7] Mulamba, M., Mandi, J., Diligenti, M., Lombardi, M., Bucarey, V., & Guns, T. (2021). Contrastive losses and solution caching for predict-and-optimize. Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence.
- [8] Mandi, J., Bucarey, V., Mulamba, M., & Guns, T. (2022). Decision-focused learning: through the lens of learning to rank. Proceedings of the 39th International Conference on Machine Learning.
- [9] Niepert, M., Minervini, P., & Franceschi, L. (2021). Implicit MLE: backpropagating through discrete exponential family distributions. Advances in Neural Information Processing Systems, 34, 14567-14579.
- [10] Minervini, P., Franceschi, L., & Niepert, M. (2023, June). Adaptive perturbation-based gradient estimation for discrete latent variable models. In Proceedings of the AAAI Conference on Artificial Intelligence (Vol. 37, No. 8, pp. 9200-9208).
- [11] Gupta, V., & Huang, M. (2024). Decision-Focused Learning with Directional Gradients. Advances in Neural Information Processing Systems, 37.
- [12] Schutte, N., Postek, K., & Yorke-Smith, N. (2024). Robust Losses for Decision-Focused Learning. Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence.
- [13] Tang, B., & Khalil, E. B. (2024). CaVE: A Cone-Aligned Approach for Fast Predict-then-Optimize with Binary Linear Programs. In Integration of Constraint Programming, Artificial Intelligence, and Operations Research (pp. 193-210).