← 开源
jamesturk

scrapeghost

👻 Experimental library for scraping websites using OpenAI's GPT API.

AI EngineeringGive agent toolsPython
在 GitHub 打开
增长势头
+024 小时新增 Star0.0%
1.44k
Star
86
Fork
+0
本周
2
贡献者
创建于 2023-03-18 · 更新于 2026-10-15 · 今日第 10316 名
主要开发者
jamesturkDieterHolvoet

jamesturk/scrapeghost 排名第 10,316,有 1,440 个星标。

同类别比较

jamesturk/scrapeghost 排名第 10,316,此处有 8 个同类条目;6551Team/opentwitter-mcp 排名第 10,321。

同类别比较
名称排名指标
vitalops/openvibe10,289
语言:
Python
星标数:
1,452
分叉数:
131
简介:
Python Imeplementation of Opencode
dmmiller612/bert-extractive-summarizer10,292
语言:
Python
星标数:
1,451
分叉数:
304
简介:
Easy to use extractive text summarization with BERT
writer/writer-framework10,295
语言:
Python
星标数:
1,451
分叉数:
102
简介:
No-code in the front, Python in the back. An open-source framework for creating data apps.
dleemiller/WordLlama10,298
语言:
Python
星标数:
1,450
分叉数:
49
简介:
Things you can do with the token embeddings of an LLM
6551Team/opentwitter-mcp10,321
语言:
Python
星标数:
1,439
分叉数:
102
简介:
Twitter/X Data · User Profiles · Tweet Search · Follower Events · KOL Tracking
eumemic/ai-legion10,324
语言:
TypeScript
星标数:
1,438
分叉数:
172
简介:
An LLM-powered autonomous agent platform
hollance/CoreMLHelpers10,337
语言:
Swift
星标数:
1,434
分叉数:
188
简介:
Types and functions that make it a little easier to work with Core ML in Swift.
alan345/AI-Fullstack-SaaS-Boilerplate10,341
语言:
TypeScript
星标数:
1,433
分叉数:
223
简介:
Fullstack SaaS Boilerplate built with tRPC, Fastify and React
关键参数与规格
关键参数与规格
参数值
语言Python
类别AI Engineering
子类别Give agent tools
关键词Data scraping
星标数1,440
分叉数86
贡献者2
创建日期2023-03-18
更新日期2026-10-15
1 天星标数0
7 天星标数0
排名10,316
上次排名5,688
排名变化-4,628
7 天星标排名12,583
上次 7 天星标排名12,620
7 天星标排名变化37
总星标排名8,353
上次总星标排名8,344
总星标排名变化-9
国家USA
README 摘录

scrapeghost **This project from 2023 is no longer maintained or recommended, the author has no interest in working with commercial LLMs. ** **was** an experimental library for scraping websites using OpenAI's GPT. Source: Documentation: Issues: **Use at your own risk. This library makes considerably expensive calls ($0. 36 for a GPT-4 call on a moderately sized page. ) Cost estimates are based on the OpenAI pricing page and not guaranteed to be accurate. ** Features The purpose of this library is to

provide a convenient interface for exploring web scraping with GPT. While the bulk of the work is done by the GPT model, provides a number of features to make it easier to use. **Python-based schema definition** - Define the shape of the data you want to extract as any Python object, with as much or little detail as you want. **Preprocessing** **HTML cleaning** - Remove unnecessary HTML to reduce the size and cost of API requests. **CSS and XPath selectors** - Pre

-filter HTML by writing a single CSS or XPath selector. **Auto-splitting** - Optionally split the HTML into multiple calls to the model, allowing for larger pages to be scraped. **Postprocessing** **JSON validation** - Ensure that the response is valid JSON. (With the option to kick it back to GPT for fixes if it's not. ) **Schema validation** - Go a step further, use a schema to validate the response. **Hallucination check** - Does the data in the response truly exist on the page? **Cost

Controls** Scrapers keep running totals of how many tokens have been sent and received, so costs can be tracked. 5-Turbo by default, fall back to GPT-4 if needed. ) Allows setting a budget and stops the scraper if the budget is exceeded.

常见问题

记录了多少星标和分叉?

jamesturk/scrapeghost 有 1,440 个星标和 86 个分叉。

仓库排名是多少?

jamesturk/scrapeghost 排名第 10,316。

记录的语言和类别是什么?

jamesturk/scrapeghost 有 1,440 个星标,语言为 Python,类别为 AI Engineering。

哪个仓库排名最接近?

jamesturk/scrapeghost 与 6551Team/opentwitter-mcp 比较,后者排名第 10,321,有 1,439 个星标。

README

scrapeghost

This project from 2023 is no longer maintained or recommended, the author has no interest in working with commercial LLMs.

scrapeghost was an experimental library for scraping websites using OpenAI's GPT.

Source: https://codeberg.org/jpt/scrapeghost

Documentation: https://jamesturk.github.io/scrapeghost/

Issues: https://codeberg.org/jpt/scrapeghost/issues

Use at your own risk. This library makes considerably expensive calls ($0.36 for a GPT-4 call on a moderately sized page.) Cost estimates are based on the OpenAI pricing page and not guaranteed to be accurate.
Features

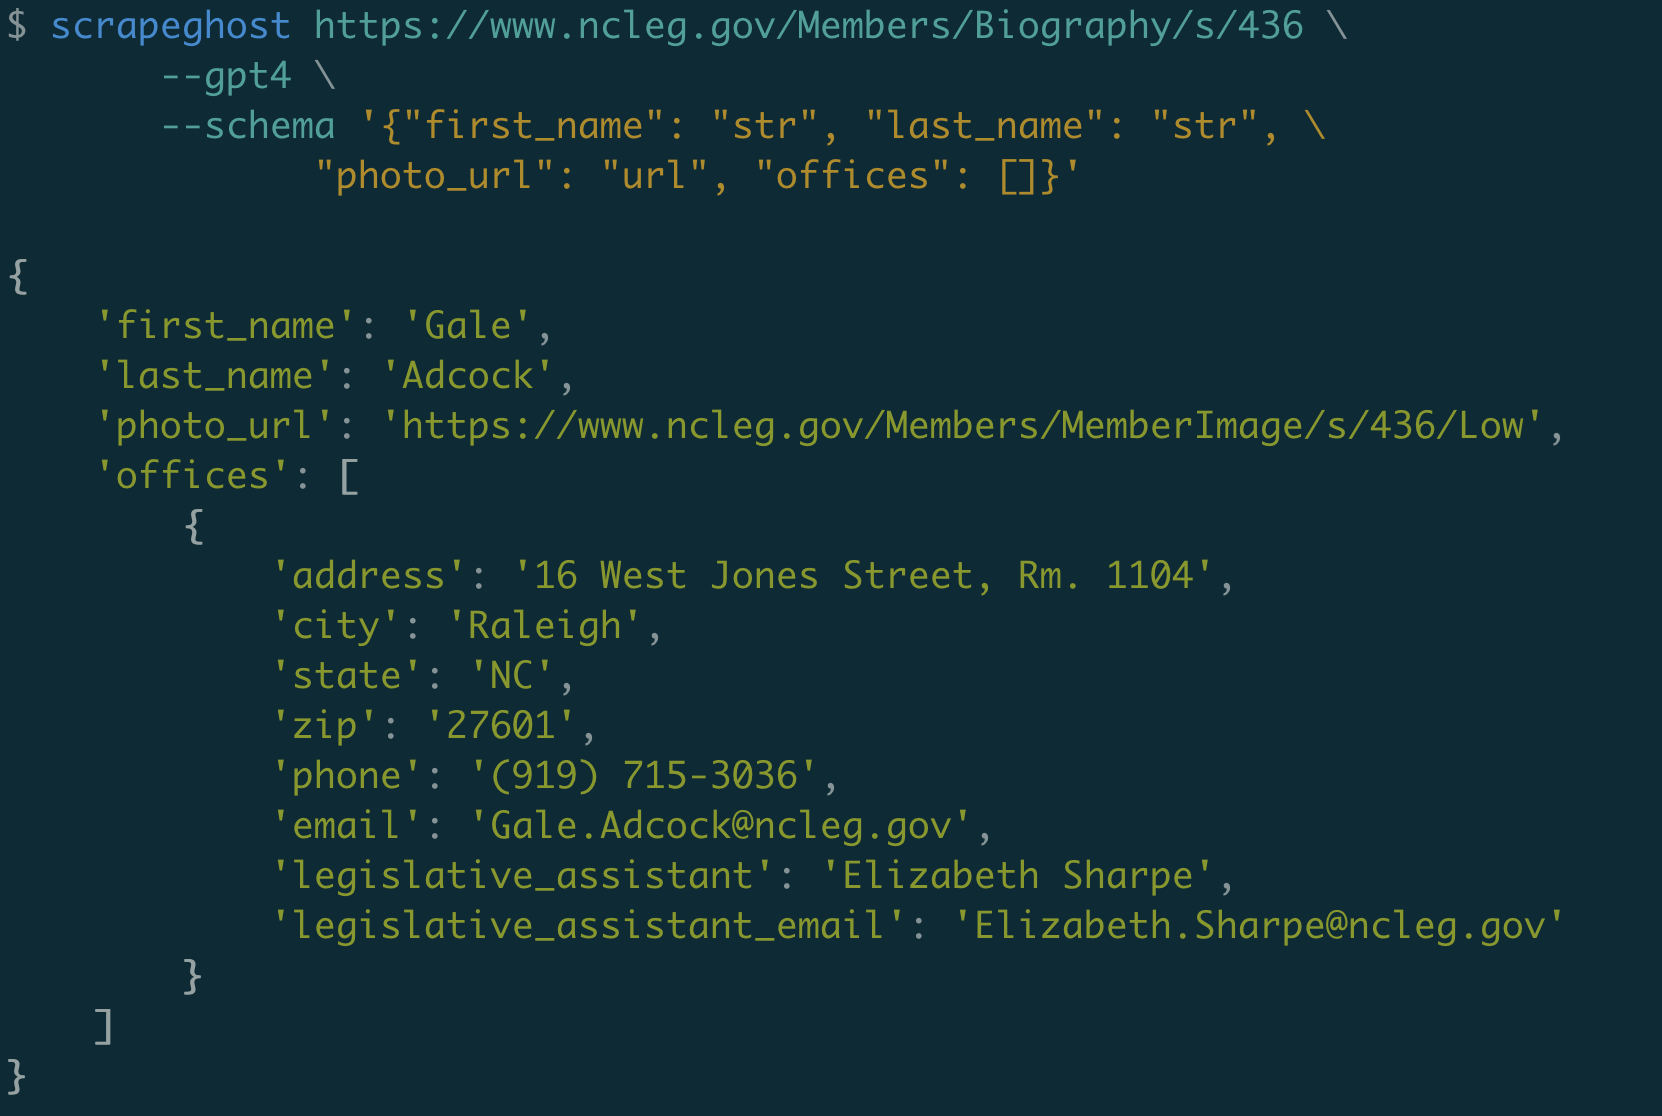
The purpose of this library is to provide a convenient interface for exploring web scraping with GPT.

While the bulk of the work is done by the GPT model, scrapeghost provides a number of features to make it easier to use.

Python-based schema definition - Define the shape of the data you want to extract as any Python object, with as much or little detail as you want.

Preprocessing

  • HTML cleaning - Remove unnecessary HTML to reduce the size and cost of API requests.
  • CSS and XPath selectors - Pre-filter HTML by writing a single CSS or XPath selector.
  • Auto-splitting - Optionally split the HTML into multiple calls to the model, allowing for larger pages to be scraped.

Postprocessing

  • JSON validation - Ensure that the response is valid JSON. (With the option to kick it back to GPT for fixes if it's not.)
  • Schema validation - Go a step further, use a pydantic schema to validate the response.
  • Hallucination check - Does the data in the response truly exist on the page?

Cost Controls

  • Scrapers keep running totals of how many tokens have been sent and received, so costs can be tracked.
  • Support for automatic fallbacks (e.g. use cost-saving GPT-3.5-Turbo by default, fall back to GPT-4 if needed.)
  • Allows setting a budget and stops the scraper if the budget is exceeded.
排名相邻
同类项目