AdderNet: Do We Really Need Multiplications in Deep Learning?
This code is a demo of CVPR 2020 paper AdderNet: Do We Really Need Multiplications in Deep Learning?
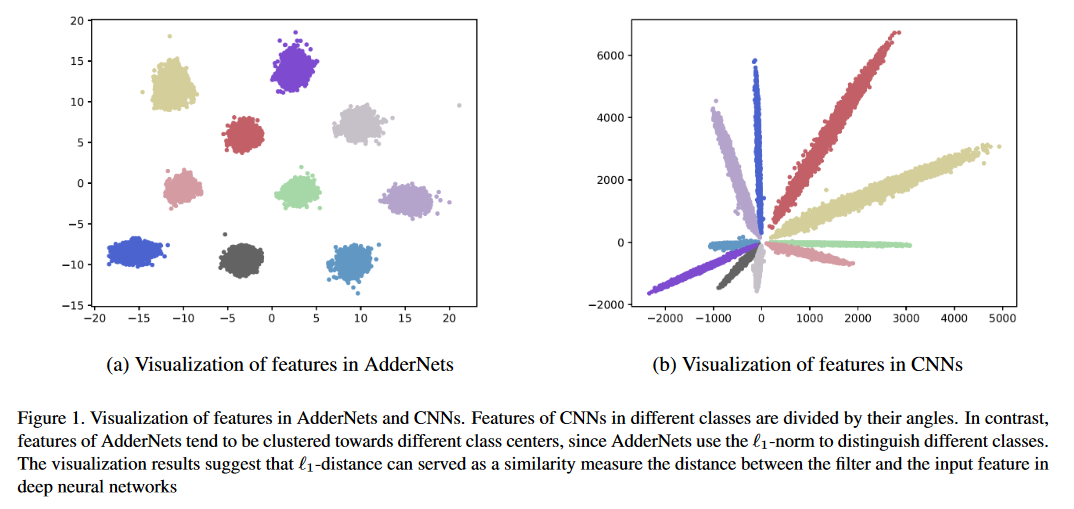
We present adder networks (AdderNets) to trade massive multiplications in deep neural networks, especially convolutional neural networks (CNNs), for much cheaper additions to reduce computation costs. In AdderNets, we take the L1-norm distance between filters and input feature as the output response. As a result, the proposed AdderNets can achieve 74.9% Top-1 accuracy 91.7% Top-5 accuracy using ResNet-50 on the ImageNet dataset without any multiplication in convolution layer.
Run python main.py to train on CIFAR-10.
Classification results on CIFAR-10 and CIFAR-100 datasets.
| Model | Method | CIFAR-10 | CIFAR-100 |
|---|---|---|---|
| VGG-small | ANN | 93.72% | 72.64% |
| PKKD ANN | 95.03% | 76.94% | |
| SLAC ANN | 93.96% | 73.63% | |
| ResNet-20 | ANN | 92.02% | 67.60% |
| PKKD ANN | 92.96% | 69.93% | |
| SLAC ANN | 92.29% | 68.31% | |
| ShiftAddNet* | 89.32%(160epoch) | - | |
| ResNet-32 | ANN | 93.01% | 69.17% |
| PKKD ANN | 93.62% | 72.41% | |
| SLAC ANN | 93.24% | 69.83% |
Classification results on ImageNet dataset.
| Model | Method | Top-1 Acc | Top-5 Acc |
|---|---|---|---|
| ResNet-18 | CNN | 69.8% | 89.1% |
| ANN | 67.0% | 87.6% | |
| PKKD ANN | 68.8% | 88.6% | |
| SLAC ANN | 67.7% | 87.9% | |
| ResNet-50 | CNN | 76.2% | 92.9% |
| ANN | 74.9% | 91.7% | |
| PKKD ANN | 76.8% | 93.3% | |
| SLAC ANN | 75.3% | 92.6% |
*ShiftAddNet used different training setting.
Super-Resolution results on several SR datasets.
| Scale | Model | Method | Set5 (PSNR/SSIM) | Set14 (PSNR/SSIM) | B100 (PSNR/SSIM) | Urban100 (PSNR/SSIM) |
|---|---|---|---|---|---|---|
| ×2 | VDSR | CNN | 37.53/0.9587 | 33.03/0.9124 | 31.90/0.8960 | 30.76/0.9140 |
| ANN | 37.37/0.9575 | 32.91/0.9112 | 31.82/0.8947 | 30.48/0.9099 | ||
| EDSR | CNN | 38.11/0.9601 | 33.92/0.9195 | 32.32/0.9013 | 32.93/0.9351 | |
| ANN | 37.92/0.9589 | 33.82/0.9183 | 32.23/0.9000 | 32.63/0.9309 | ||
| ×3 | VDSR | CNN | 33.66/0.9213 | 29.77/0.8314 | 28.82/0.7976 | 27.14/0.8279 |
| ANN | 33.47/0.9151 | 29.62/0.8276 | 28.72/0.7953 | 26.95/0.8189 | ||
| EDSR | CNN | 34.65/0.9282 | 30.52/0.8462 | 29.25/0.8093 | 28.80/0.8653 | |
| ANN | 34.35/0.9212 | 30.33/0.8420 | 29.13/0.8068 | 28.54/0.8555 | ||
| ×4 | VDSR | CNN | 31.35/0.8838 | 28.01/0.7674 | 27.29/0.7251 | 25.18/0.7524 |
| ANN | 31.27/0.8762 | 27.93/0.7630 | 27.25/0.7229 | 25.09/0.7445 | ||
| EDSR | CNN | 32.46/0.8968 | 28.80/0.7876 | 27.71/0.7420 | 26.64/0.8033 | |
| ANN | 32.13/0.8864 | 28.57/0.7800 | 27.58/0.7368 | 26.33/0.7874 |
Adversarial robustness on CIFAR-10 under white-box attacks without adversarial training.
| Model | Method | Clean | FGSM | BIM7 | PGD7 | MIM5 | RFGSM5 |
|---|---|---|---|---|---|---|---|
| ResNet-20 | CNN | 92.68 | 16.33 | 0.00 | 0.00 | 0.01 | 0.00 |
| ANN | 91.72 | 18.42 | 0.00 | 0.00 | 0.04 | 0.00 | |
| CNN-R | 90.62 | 17.23 | 3.46 | 3.67 | 4.23 | 0.06 | |
| ANN-R | 90.95 | 29.93 | 29.30 | 29.72 | 32.25 | 3.38 | |
| ANN-R-AWN | 90.55 | 45.93 | 42.62 | 43.39 | 46.52 | 18.36 | |
| ResNet-32 | CNN | 92.78 | 23.55 | 0.00 | 0.01 | 0.10 | 0.00 |
| ANN | 92.48 | 35.85 | 0.03 | 0.11 | 1.04 | 0.02 | |
| CNN-R | 91.32 | 20.41 | 5.15 | 5.27 | 6.09 | 0.07 | |
| ANN-R | 91.68 | 19.74 | 15.96 | 16.08 | 17.48 | 0.07 | |
| ANN-R-AWN | 91.25 | 61.30 | 59.41 | 59.74 | 61.54 | 39.79 |
Comparisons of mAP on PASCAL VOC.
| Model | Backbone | Neck | mAP |
|---|---|---|---|
| Faster R-CNN | Conv R50 | Conv | 79.5 |
| FCOS | Conv R50 | Conv | 79.1 |
| RetinaNet | Conv R50 | Conv | 77.3 |
| FoveaBox | Conv R50 | Conv | 76.6 |
| Adder-FCOS | Adder R50 | Adder | 76.5 |
Requirements
- python 3
- pytorch >= 1.1.0
- torchvision
Preparation
You can follow pytorch/examples to prepare the ImageNet data.
The pretrained models are available in google drive or baidu cloud (access code:126b)
Usage
Run python main.py to train on CIFAR-10.
Run python test.py --data_dir 'path/to/imagenet_root/' to evaluate on ImageNet val set. You will achieve 74.9% Top accuracy and 91.7% Top-5 accuracy on the ImageNet dataset using ResNet-50.
Run python test.py --dataset cifar10 --model_dir models/ResNet20-AdderNet.pth --data_dir 'path/to/cifar10_root/' to evaluate on CIFAR-10. You will achieve 91.8% accuracy on the CIFAR-10 dataset using ResNet-20.
The inference and training of AdderNets is slow since the adder filters is implemented without cuda acceleration. You can write cuda to achieve higher inference speed.
Citation
@article{AdderNet,
	title={AdderNet: Do We Really Need Multiplications in Deep Learning?},
	author={Chen, Hanting and Wang, Yunhe and Xu, Chunjing and Shi, Boxin and Xu, Chao and Tian, Qi and Xu, Chang},
	journal={CVPR},
	year={2020}
}
Contributing
We appreciate all contributions. If you are planning to contribute back bug-fixes, please do so without any further discussion.
If you plan to contribute new features, utility functions or extensions to the core, please first open an issue and discuss the feature with us. Sending a PR without discussion might end up resulting in a rejected PR, because we might be taking the core in a different direction than you might be aware of.