🌐 Language
English | 简体中文 | 繁體中文 | 日本語 | 한국어 | हिन्दी | ไทย | Français | Deutsch | Español | Italiano | Русский | Português | Nederlands | Polski | العربية | فارسی | Türkçe | Tiếng Việt | Bahasa Indonesia | অসমীয়া
TimeCapsule LLM
A language model trained from scratch exclusively on data from certain places and time periods to reduce modern bias and emulate the voice, vocabulary, and worldview of the era.
Imagine if an AI model didnt just pretend to be historical but actually was.
v0 and v0.5 built on nanoGPT by Andrej Karpathy Core training scripts and model architecture are his work.
v1 built on Phi 1.5 by Microsoft
v2 built on llamaforcausallm
Research Status
This project was initiated and developed independently.
It is currently conducted under academic supervision, with an affiliated research collaboration at Muhlenberg College & Georgia State University.
Citation
If you use this dataset or model in academic work, please cite:
@misc{london_llm_1800,
  author = {Grigorian, Hayk and Yaghoobian, Hamed},
  title = {Historic London English (1800–1875)},
  year = {2025},
  publisher = {Hugging Face},
  howpublished = {\url{https://huggingface.co/datasets/postgrammar/london-llm-1800}}
}
Join the Vintage LLM Discord
If you're interested in historical language models, time-specific datasets, or the future of projects like TimeCapsuleLLM, Violet-1.4B, Mr. Chatterbox come join the community.
We use the server to discuss ideas, share progress, and connect with others building in this space.
Sponsors
Model Behavior & Limitations
v0
Early prompts show the model responding with 1800's language and behavior. Example: Prompt: "Who art Henry?" and it replied "I know that man, I have did not a black, the storm."

- No mention of modern concepts
- Mostly era-accurate vocabulary
- Sentences are mostly incoherent (expected for ~187MB training data)
v0.5-london
A significant improvement over v0.
- Victorian writing style, proper punctuation, mostly grammatical sentences
- Still high factual hallucination rate
- OCR noise (“Digitized by Google”) still present in outputs

v1-london
First model to recall and connect a real historical event with an actual figure from the dataset.
Example: Prompt: "It was the year of our Lord 1834"
The output: "It was the year of our Lord 1834 and the streets of London were filled with protest and petition. The cause, as many re counted, was not bound in the way of private, but having taken up the same day in the day of Lord Palmerston, the public will receive a short statement of the difficulties under which the day of law has reached us. It is a matter of deep regret, that the present events in the history of the world are clear, and consequently will be'known. It is not true that the very men who first settled in the Gospel at Jerusalem should have so extensive and so interesting a record of the prosperity and prosperity"
At first I assumed that a protest might have coincidentally taken place the same year but take a look at this: 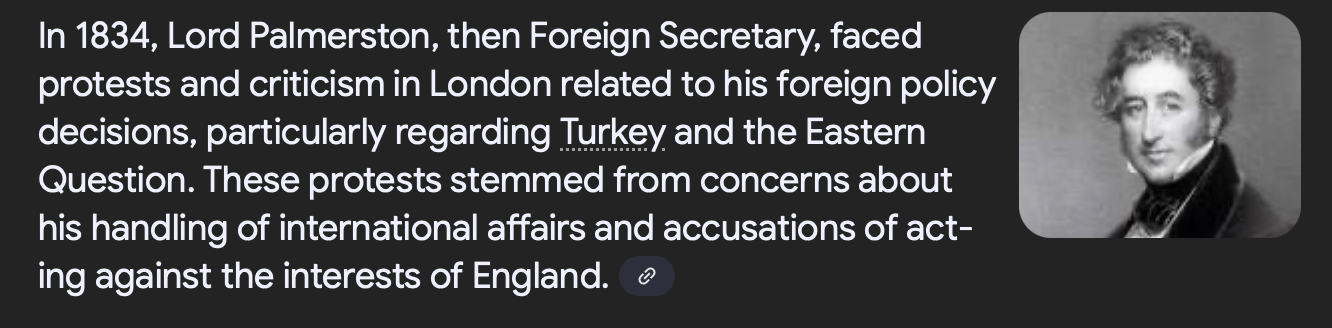
v2mini-eval1-london
Trained using a 15GB sample from v2's 90GB dataset. Model trained to 10K steps only.
There was an issue with tokenization that causes output to look like this:
PROMPT: Who is Charles Dickens?
W ho is Charles D ic ens ? D oes that work more of h ise x cell ent st ir ring , in his pl ays , int he G reat C omp any 's f arm ? What I have y et to qu ote from J ack P ick ett ? D oy oun ot know th att hey were as pe cies of g all oping , ors aw ing oft heir bre asts , or what w ast ob ed one about the t im ew hen J acks on was looking ont hew ind ow ? What ist hes uccess of an English man , and which h isson has not be end is cover ing t ome , where by to acc omp lish such a we ight ? D idy ou ever m ake ap ass age int othe old road way , ort o an anch or - b ree ze att he foot of our boat , which you m ust le ave us ? The fact is , that whe ther the wind would rise up from the pl ain on S atur day night orn o ont ide , ort ill then orth , or other wise , wes hall be com pelled t od esc ribe af orm idable bar rier , with t hes ame e ffect s ast he p resent . In th iss itu ation , at le ast , itis not to omuch t os ay that we have le ft that room . I bel ieve there are three c op ies int he " F ive H undred - fold ," to bere fer red to , ast he first n umber of our read ers wh ow is ht
Corrected:
"Who is Charles Dickens? Does that work more of his excellent stirring, in his plays, in the Great Company's farm? What I have yet to quote from Jack Pickett? Do you not know that they were a species of galloping, or sawing of their breasts, or what was to be done about the time when Jackson was looking on the window? What is the success of an Englishman, and which his son has not been discovering to me, whereby to accomplish such a weight? Did you ever make a passage into the old roadway, or to an anchor-breeze at the foot of our boat, which you must leave us? The fact is, that whether the wind would rise up from the plain on Saturday night or noontide, or till the north, or otherwise, we shall be compelled to describe a formidable barrier, with the same effects as the present. In this situation, at least, it is not too much to say that we have left that room. I believe there are three copies in the 'Five Hundred-fold,' to be referred to, as the first number of our readers who wish t[o]...”
v2mini-eval2-london
Trained using the same 15GB sample used for training eval1. Model is again trained to 10K steps only.
PROMPT:Charles Darwin
Charles DarwinECCEMACY. Sir, — The following case is interesting to me : — I was in London a fortnight, and was much affected with an attack of rheumatism. The first attack of rheumatism was a week before I saw you, and the second when I saw you, and the third when I saw you, and the third in the same time. The second attack of gout, however, was not accompanied by any febrile symptoms, but was accompanied with an increased flow of urine, and with a more copious discharge of urine. The third attack was an hour after I saw you, and was succeeded by a return of a paroxysm of gout, and a more rapid return of the gout. The fourth attack was also accompanied by a fever, but was not always accompanied by any febrile symptoms. The third attack of gout was a fortnight after you had been ill, and the fourth was followed by a paroxysm of gout. The fourth attack was a fortnight after you were attacked, and was accompanied by a sense
v2-london
Trained using a 90GB (112GB tokenized) dataset Trained to 182K steps
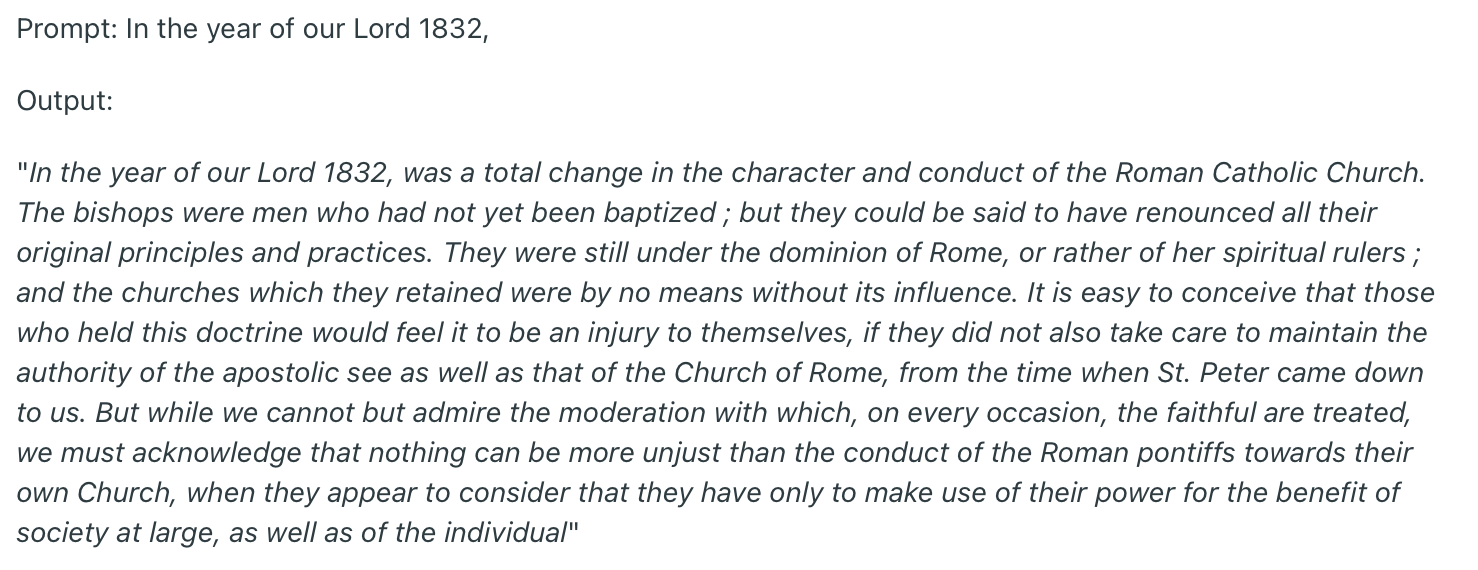
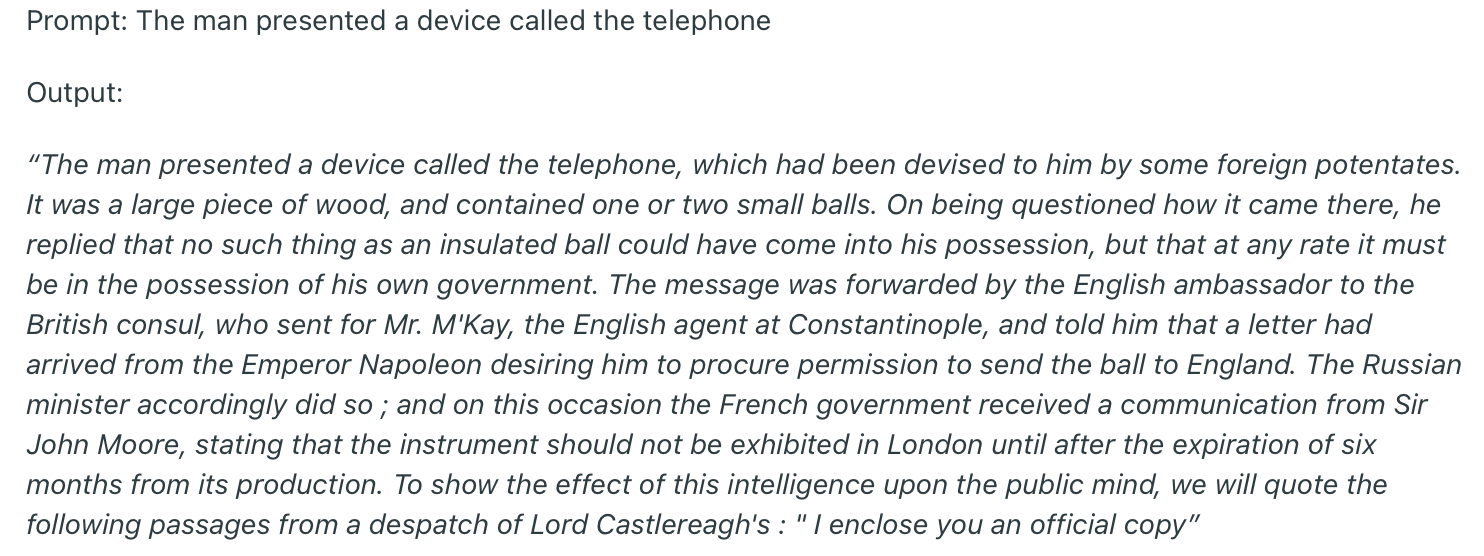
Whats next?
- Development has begun on TimeCapsuleLLM v3
- Scaling dataset size and geographic coverage
- Expanding beyond London to additional cities
The work is being carried out in collaboration with researchers from Muhlenberg College & Georgia State University.
Datasets
v2
- 90GB(raw) of 1800-1875 London texts
- 136,344 documents
- The full tokenized dataset is now available here: https://huggingface.co/datasets/postgrammar/london-llm-1800
Bias Stats
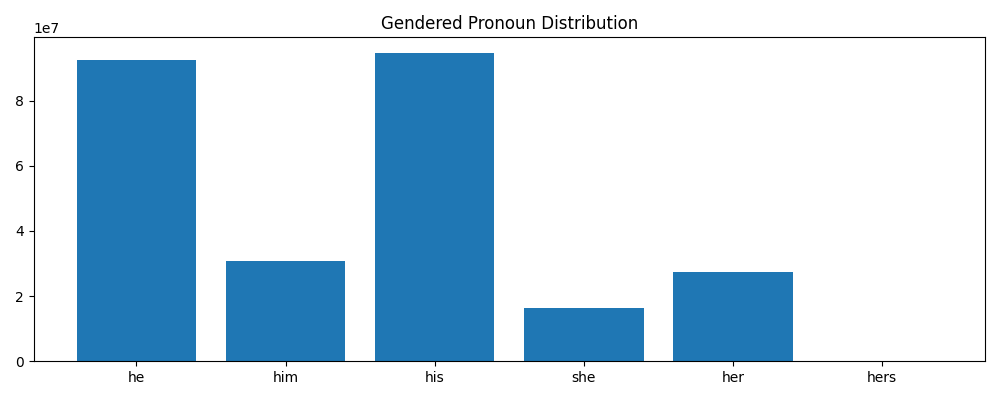

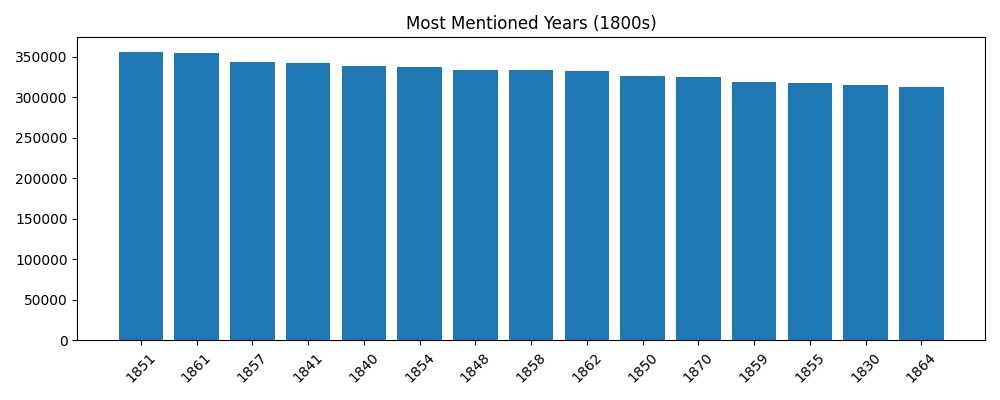
Refer to v2 bias report for more info.
How to Use
This project focuses mostly on curating historical data, preparing it for training and building a tokenizer. I am not going to cover the full LLM training process, for that refer to nanoGPT by Andrej Karpathy.
Step 1: Gather and Prepare Historical Texts
- Collect .txt files of public domain books, documents, etc from your chosen time period (e.g., London 1800-1875)
- Keep them within your chosen time/place window
- Clean the text files using a script or manually remove headers/footer from Project Gutenberg, Modern annotations or things like OCR errors.
Step 2: Build a Custom Tokenizer
- Run train_tokenizer.py or train_tokenizer_hf.py on the cleaned data.
- This will give you vocab.json and merges.txt
- Thes files define vocab and merge rules for your model
Step 3: Train Your Model
- Refer to nanoGPT by Andrej Karpathy for the training process or your chosen architecture’s docs.
FAQ
What is Selective Temporal Training ?
Selective Temporal Training (STT) is a machine learning methodology where all training data is specifically curated to fall within a specific historical time period. It's done in order to model the language and knowledge of that era without influence from modern concepts. For example, the current model I have now (v0.5) is trained on data exclusively from 1800-1875, it's not fine tuned but trained from scratch resulting in output that reflects the linguistic style and historical context of that time period.
Why not just use fine-tuning or LoRA?
For this project I'm trying to create a language model that is unclouded from modern bias. If I fine-tune something like GPT-2, it's already pre-trained and that information won't go away. If I train from scratch the language model won't pretend to be old, it just will be. The Goal for this project right now is to create something can reason exclusively using knowledge from London books published between 1800 and 1875.
What kind of data did you use for training?
I'm using books, legal documents, newspapers, and other writings from 1800–1875 London. The list I linked (for v0) has like 200 but for the first training I just used 50 files about ~187 MB. You can view a list of the documents: https://github.com/haykgrigo3/TimeCapsuleLLM/blob/main/Copy of London Documents for Time Capsule LLM.txt
Dataset sizes:
- v0: ~187MB
- v0.5: ~435MB
- v1: ~6.25GB
- v2mini-eval1: 15GB(sample from v2's 90GB)
- v2: 90GB
How large are the models ?
v0: 16M Parameters
v0.5 123M Parameters
v1: 700M Parameters
v2mini-eval1: 300M Parameters
v2mini-eval2: 200M Parameters
v2: 1.2B Parameters
Training Specs ?
v0/v0.5
GPU: Geforce rtx 4060 CPU: i5-13400F Ram: 16GB DDR5.
v1
GPU: A100 SXM rented
v2mini-eval1/eval2
GPU: A100 SXM rented
v2
GPU: H100 SXM rented
Related Work
-
- 13B parameter LLM trained on 260B tokens of text prior to 1930 with Q&A. There is also a base version.
-
- 1.4B parameter LLM trained on 1800-1899 texts with Q&A. There is also a 160M version.
-
- 340M parameter LLM trained on over 28,000 texts between 1837-1899 with Q&A.
-
- a family of 4B parameter LLMs based on the Qwen3 architecture trained from scratch on 80B tokens of historical data up to knowledge-cutoffs 1913,1929,1933,1939,1946.
-
- a 7.24B History language model (LM) pretrained exclusively on English text predating 1913. Created by researchers from University of Waterloo, Adelaide University, University of Oxford, and University College London. Link to paper
-
- MonadGPT is a finetune of Mistral-Hermes 2 on 11,000 early modern texts in English, French and Latin, mostly coming from EEBO and Gallica.
Acknowledgements
I would like to thank Dr. Hamed Yaghoobian for academic supervision, guidance on research framing and evaluation, and for assistance with tokenizer training and dataset preparation for the v2 release. His feedback and experience were instrumental in refining the presentation of this work.