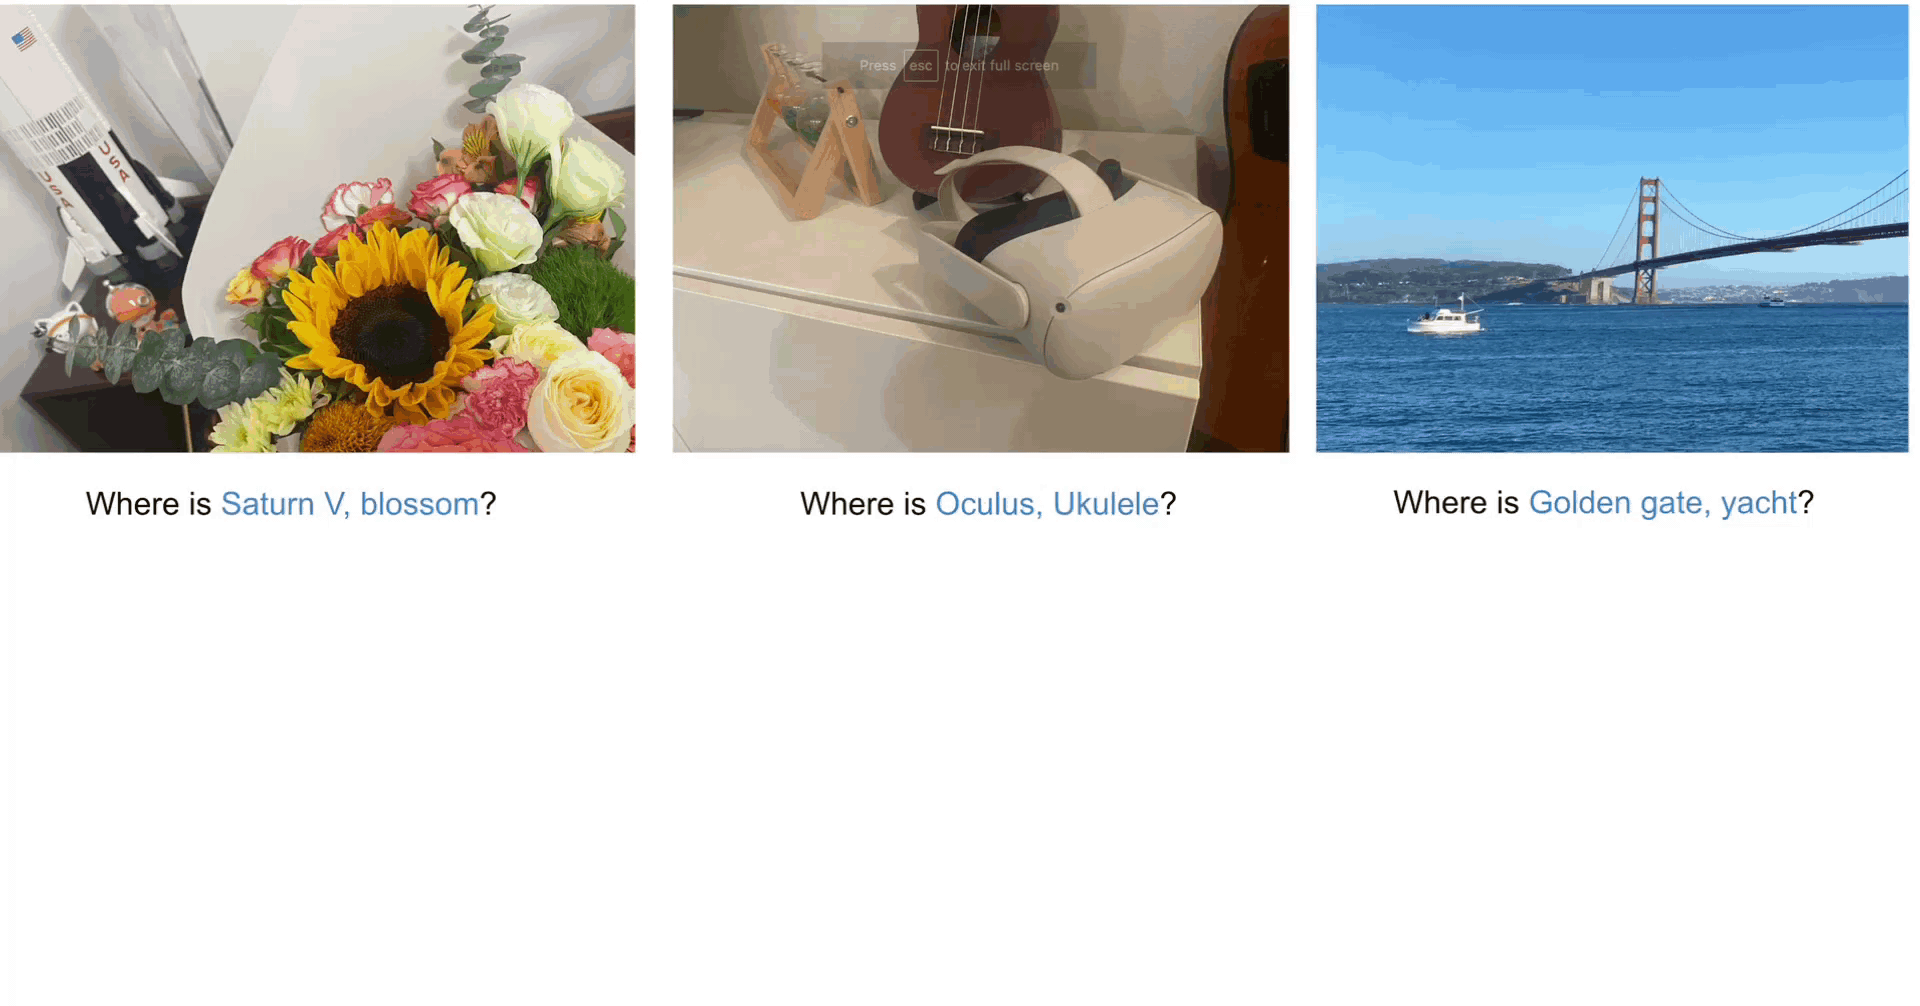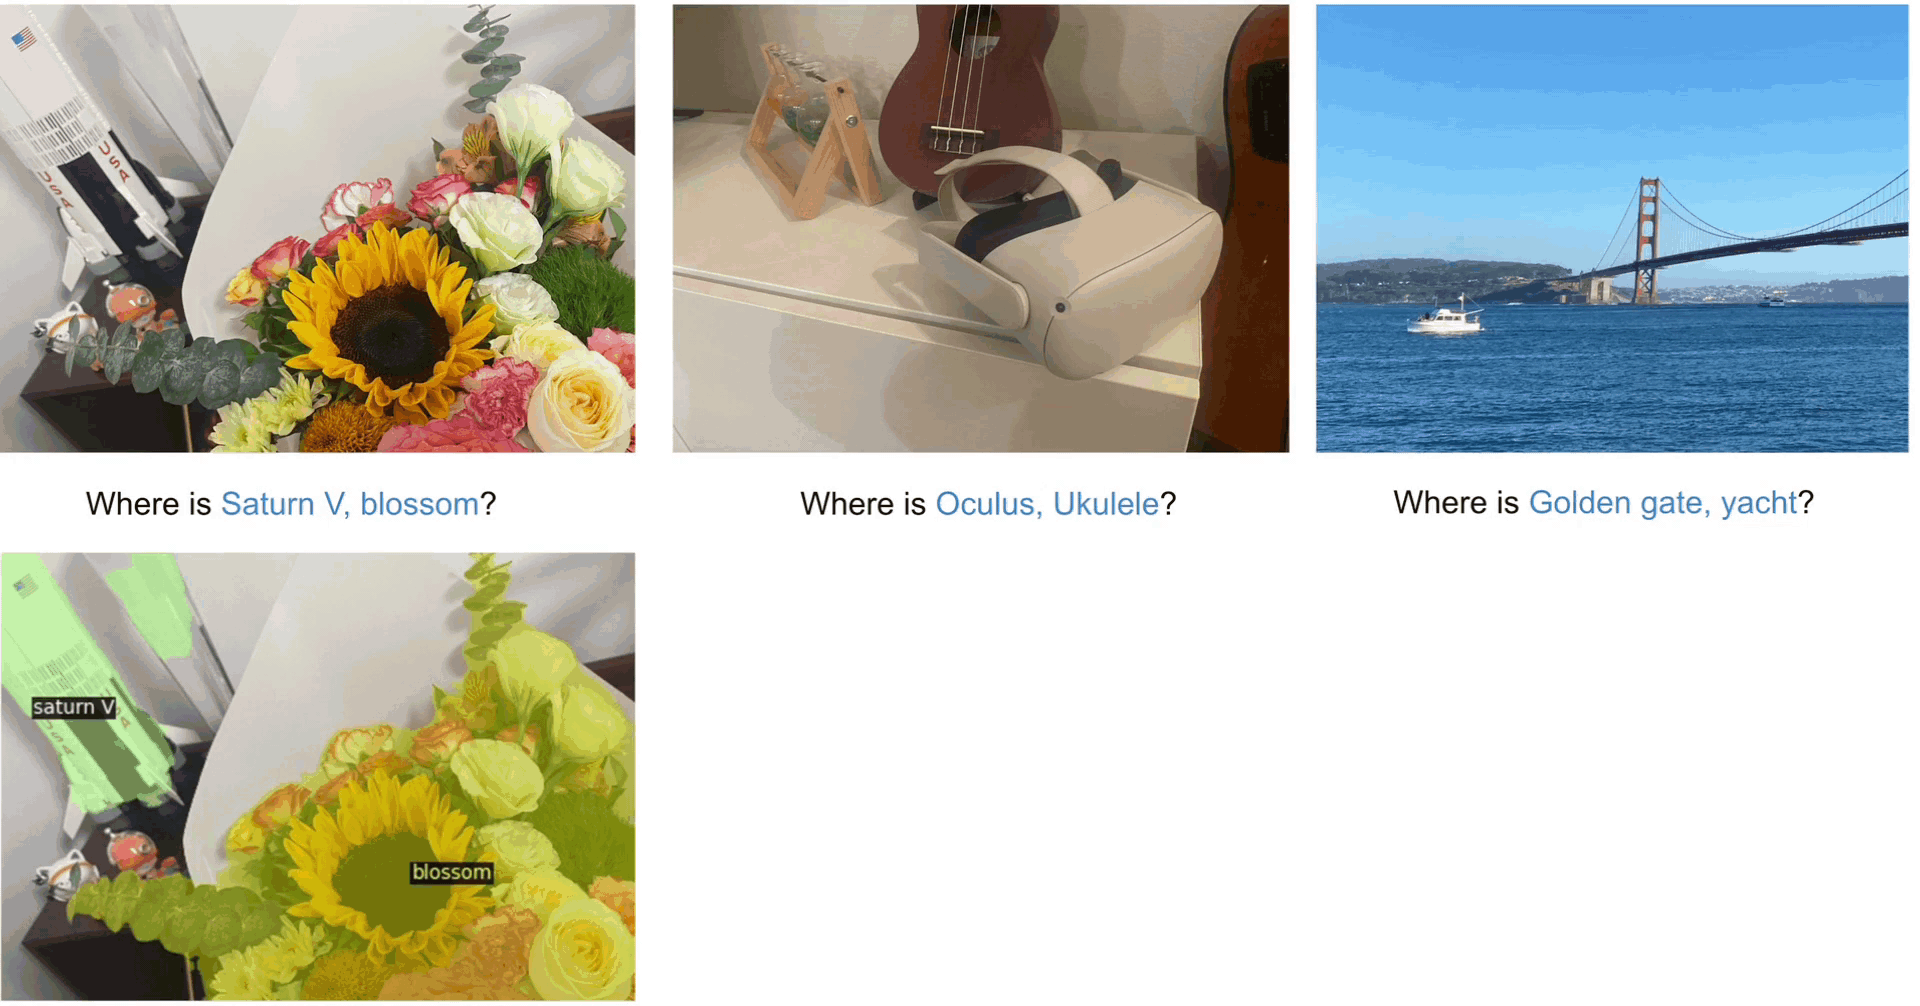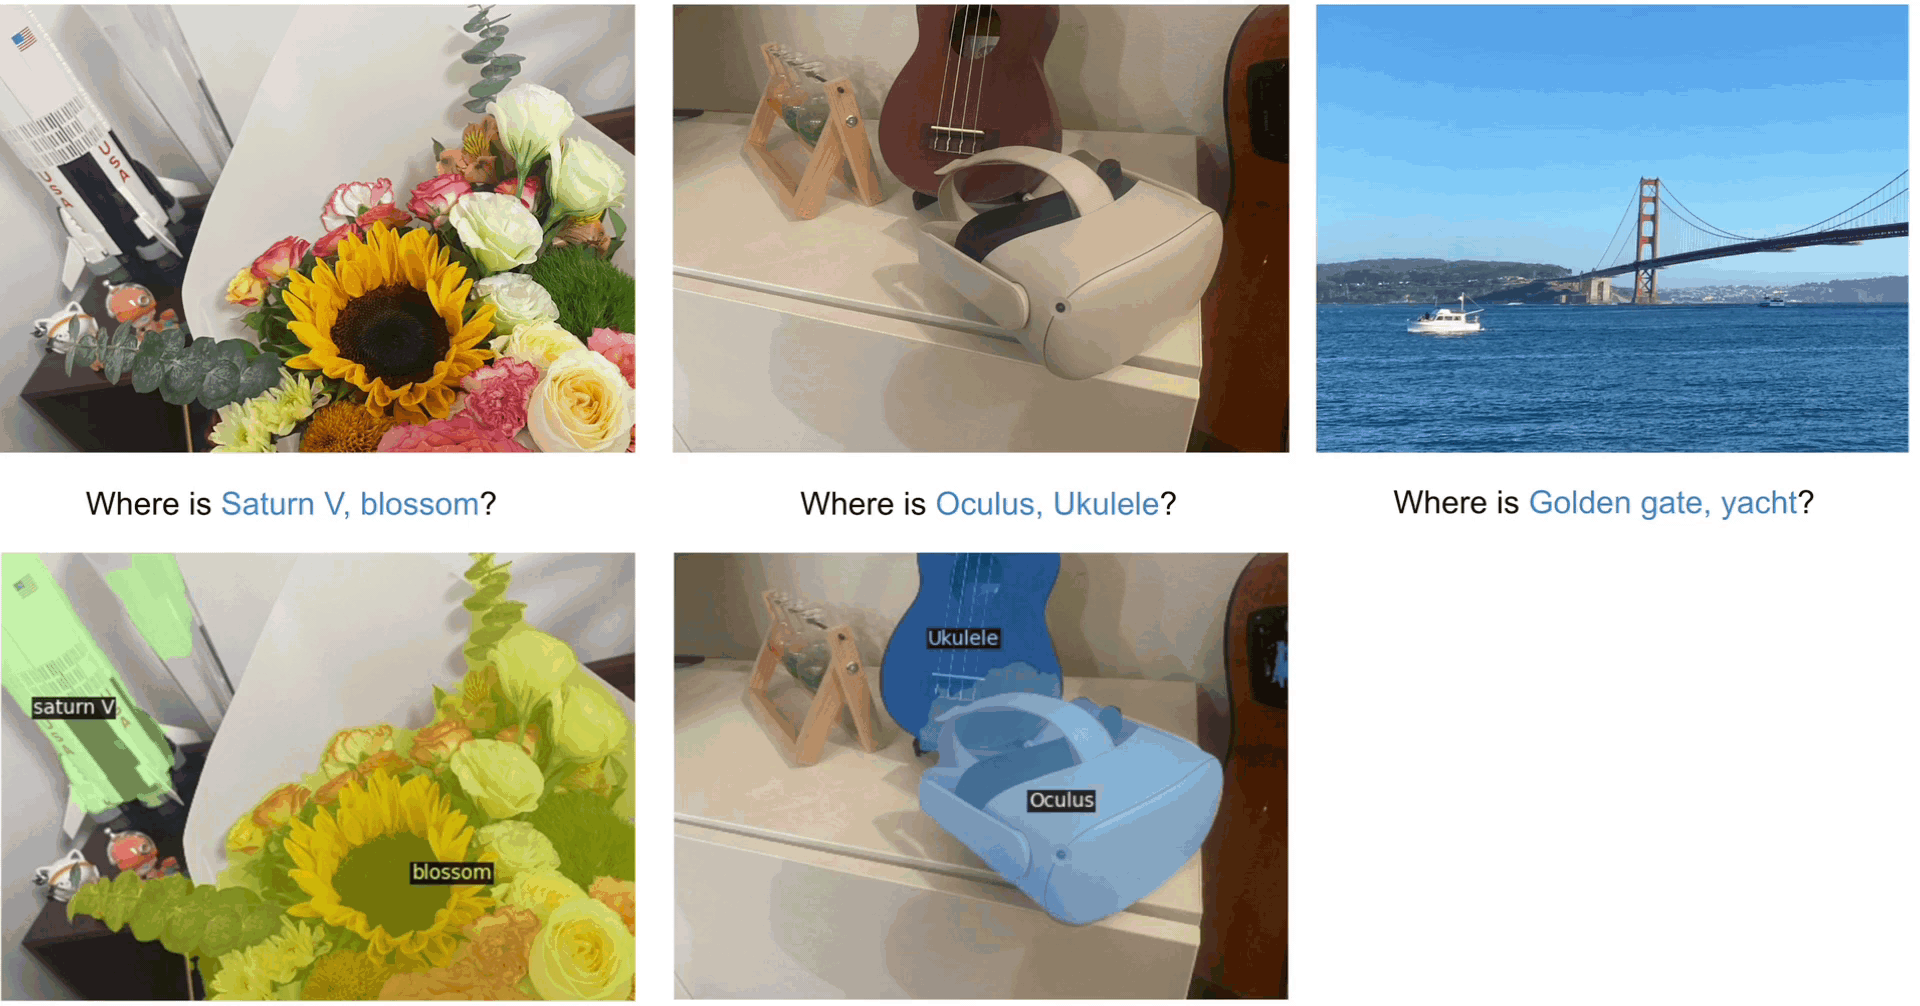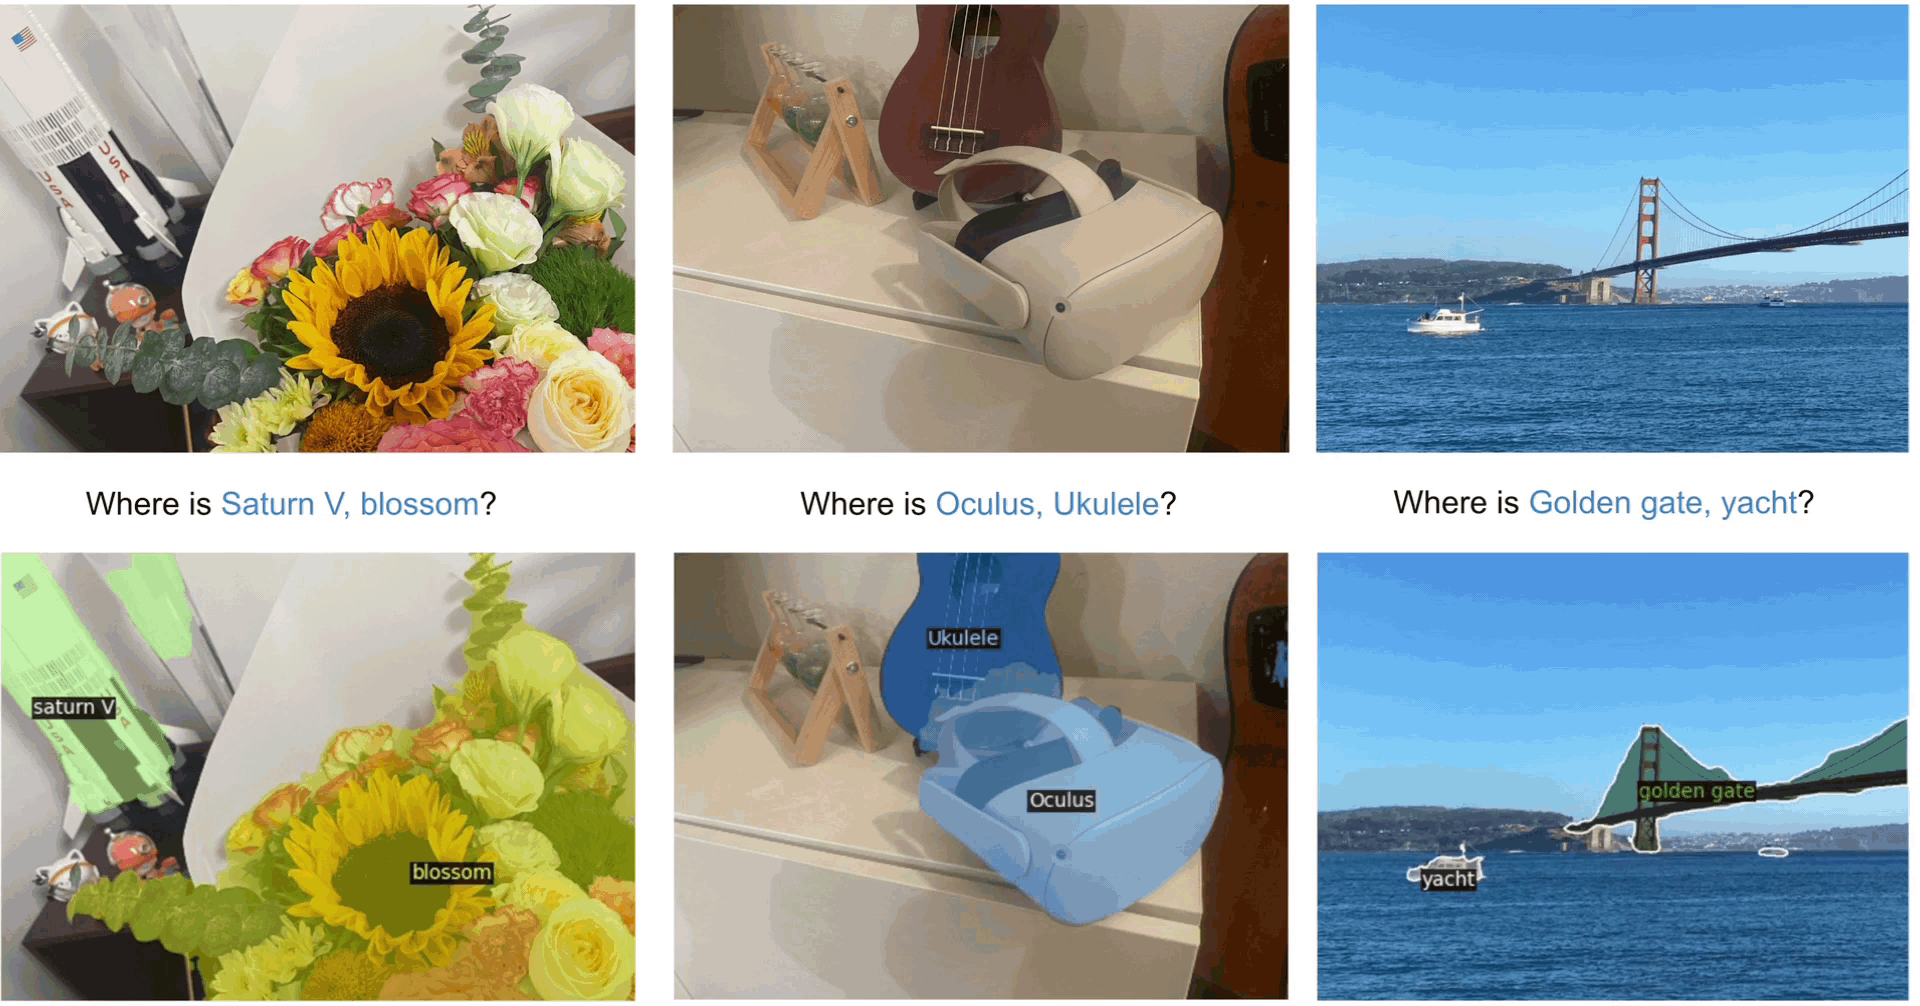
[OVSeg] Open-Vocabulary Semantic Segmentation with Mask-adapted CLIP
This is the official PyTorch implementation of our paper:
Open-Vocabulary Semantic Segmentation with Mask-adapted CLIP
Feng Liang, Bichen Wu, Xiaoliang Dai, Kunpeng Li, Yinan Zhao, Hang Zhang, Peizhao Zhang, Peter Vajda, Diana Marculescu
Computer Vision and Pattern Recognition Conference (CVPR), 2023
[arXiv] [Project] [huggingface demo]
Installation
Please see installation guide.
Data Preparation
Please see datasets preparation.
Getting started
Please see getting started instruction.
Finetuning CLIP
Please see open clip training.
LICENSE
Shield: 
The majority of OVSeg is licensed under a Creative Commons Attribution-NonCommercial 4.0 International License.

However portions of the project are under separate license terms: CLIP and ZSSEG are licensed under the MIT license; MaskFormer is licensed under the CC-BY-NC; openclip is licensed under the license at its repo.
Citing OVSeg :pray:
If you use OVSeg in your research or wish to refer to the baseline results published in the paper, please use the following BibTeX entry.
@inproceedings{liang2023open,
  title={Open-vocabulary semantic segmentation with mask-adapted clip},
  author={Liang, Feng and Wu, Bichen and Dai, Xiaoliang and Li, Kunpeng and Zhao, Yinan and Zhang, Hang and Zhang, Peizhao and Vajda, Peter and Marculescu, Diana},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
  pages={7061--7070},
  year={2023}
}