👽 Terraform Orchestration Tool for DevOps. Keep environment configuration DRY with hierarchical imports of configurations, inheritance, and WAY more. Native support for Terraform and Helmfile.
An OpenCL-based FPGA Accelerator for Convolutional Neural Networks
关键参数与规格
关键参数与规格
参数
值
语言
Python
类别
Infrastructure
子类别
Inference service optimization
关键词
Distributed training
星标数
1,447
分叉数
211
贡献者
3
创建日期
2025-02-26
更新日期
2026-10-14
1 天星标数
0
7 天星标数
4
排名
10,309
上次排名
10,314
排名变化
5
7 天星标排名
6,158
上次 7 天星标排名
6,155
7 天星标排名变化
-3
总星标排名
8,335
上次总星标排名
8,326
总星标排名变化
-9
国家
China
README 摘录
Expert Parallelism Load Balancer (EPLB) When using expert parallelism (EP), different experts are assigned to different GPUs. Because the load of different experts may vary depending on the current workload, it is important to keep the load of different GPUs balanced. As described in the DeepSeek-V3 paper, we adopt a **redundant experts** strategy that duplicates heavy-loaded experts. Then, we heuristically pack the duplicated experts to GPUs to ensure load balancing across different GPUs. Moreover, thanks to the **group
-limited expert routing** used in DeepSeek-V3, we also attempt to place the experts of the same group to the same node to reduce inter-node data traffic, whenever possible. To facilitate reproduction and deployment, we open-source our deployed EP load balancing algorithm in . The algorithm computes a balanced expert replication and placement plan based on the estimated expert loads. Note that the exact method to predict the loads of experts is out of this repo's scope. A common
method is to use moving average of historical statistics. The Algorithm The load balancing algorithm comes with two policies used for different cases. Hierarchical Load Balancing When the number of server nodes divides the number of expert groups, we use the hierarchical load balancing policy to harness the group-limited expert routing. We first pack the expert groups to nodes evenly, ensuring the loads of different nodes are balanced. Then, we replicate the experts within each node. Finally, we pack
the replicated experts to individual GPUs to ensure different GPUs are load-balanced. The hierarchical load balancing policy can be used in prefilling stage with a smaller expert-parallel size. Global Load Balancing In other cases, we use the global load balancing policy that replicates the experts globally regardless of expert groups, and pack the replicated experts to individual GPUs. This policy can be adopted in decoding stage with a larger expert-parallel size. Interface and Example The main function
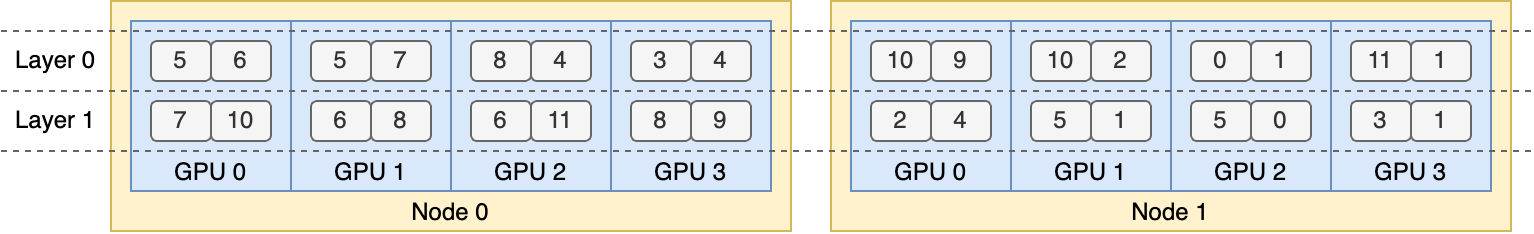
of the load balancer is . The following code illustrates an example of a two-layer MoE model, and each layer contains 12 experts. We introduce 4 redundant experts per layer, and the total 16 replicas are placed on 2 nodes, and each node contains 4 GPUs. The output, generated by the hierarchical load balancing policy, indicates the following expert replication and placement plan. License This code repository is released under the MIT License.
When using expert parallelism (EP), different experts are assigned to different GPUs. Because the load of different
experts may vary depending on the current workload, it is important to keep the load of different GPUs balanced.
As described in the DeepSeek-V3 paper, we adopt a redundant experts strategy that duplicates heavy-loaded experts.
Then, we heuristically pack the duplicated experts to GPUs to ensure load balancing across different GPUs. Moreover,
thanks to the group-limited expert routing used in DeepSeek-V3, we also attempt to place the experts of the same
group to the same node to reduce inter-node data traffic, whenever possible.
To facilitate reproduction and deployment, we open-source our deployed EP load balancing algorithm in eplb.py.
The algorithm computes a balanced expert replication and placement plan based on the estimated expert loads. Note
that the exact method to predict the loads of experts is out of this repo's scope. A common method is to use
moving average of historical statistics.
The Algorithm
The load balancing algorithm comes with two policies used for different cases.
Hierarchical Load Balancing
When the number of server nodes divides the number of expert groups, we use the hierarchical load balancing policy to
harness the group-limited expert routing. We first pack the expert groups to nodes evenly, ensuring the loads of
different nodes are balanced. Then, we replicate the experts within each node. Finally, we pack the replicated experts
to individual GPUs to ensure different GPUs are load-balanced. The hierarchical load balancing policy can be used in
prefilling stage with a smaller expert-parallel size.
Global Load Balancing
In other cases, we use the global load balancing policy that replicates the experts globally regardless of expert
groups, and pack the replicated experts to individual GPUs. This policy can be adopted in decoding stage with a larger
expert-parallel size.
Interface and Example
The main function of the load balancer is eplb.rebalance_experts.
The following code illustrates an example of a two-layer MoE model, and each layer contains 12 experts. We introduce 4 redundant experts per layer, and the total 16 replicas are placed on 2 nodes, and each node contains 4 GPUs.