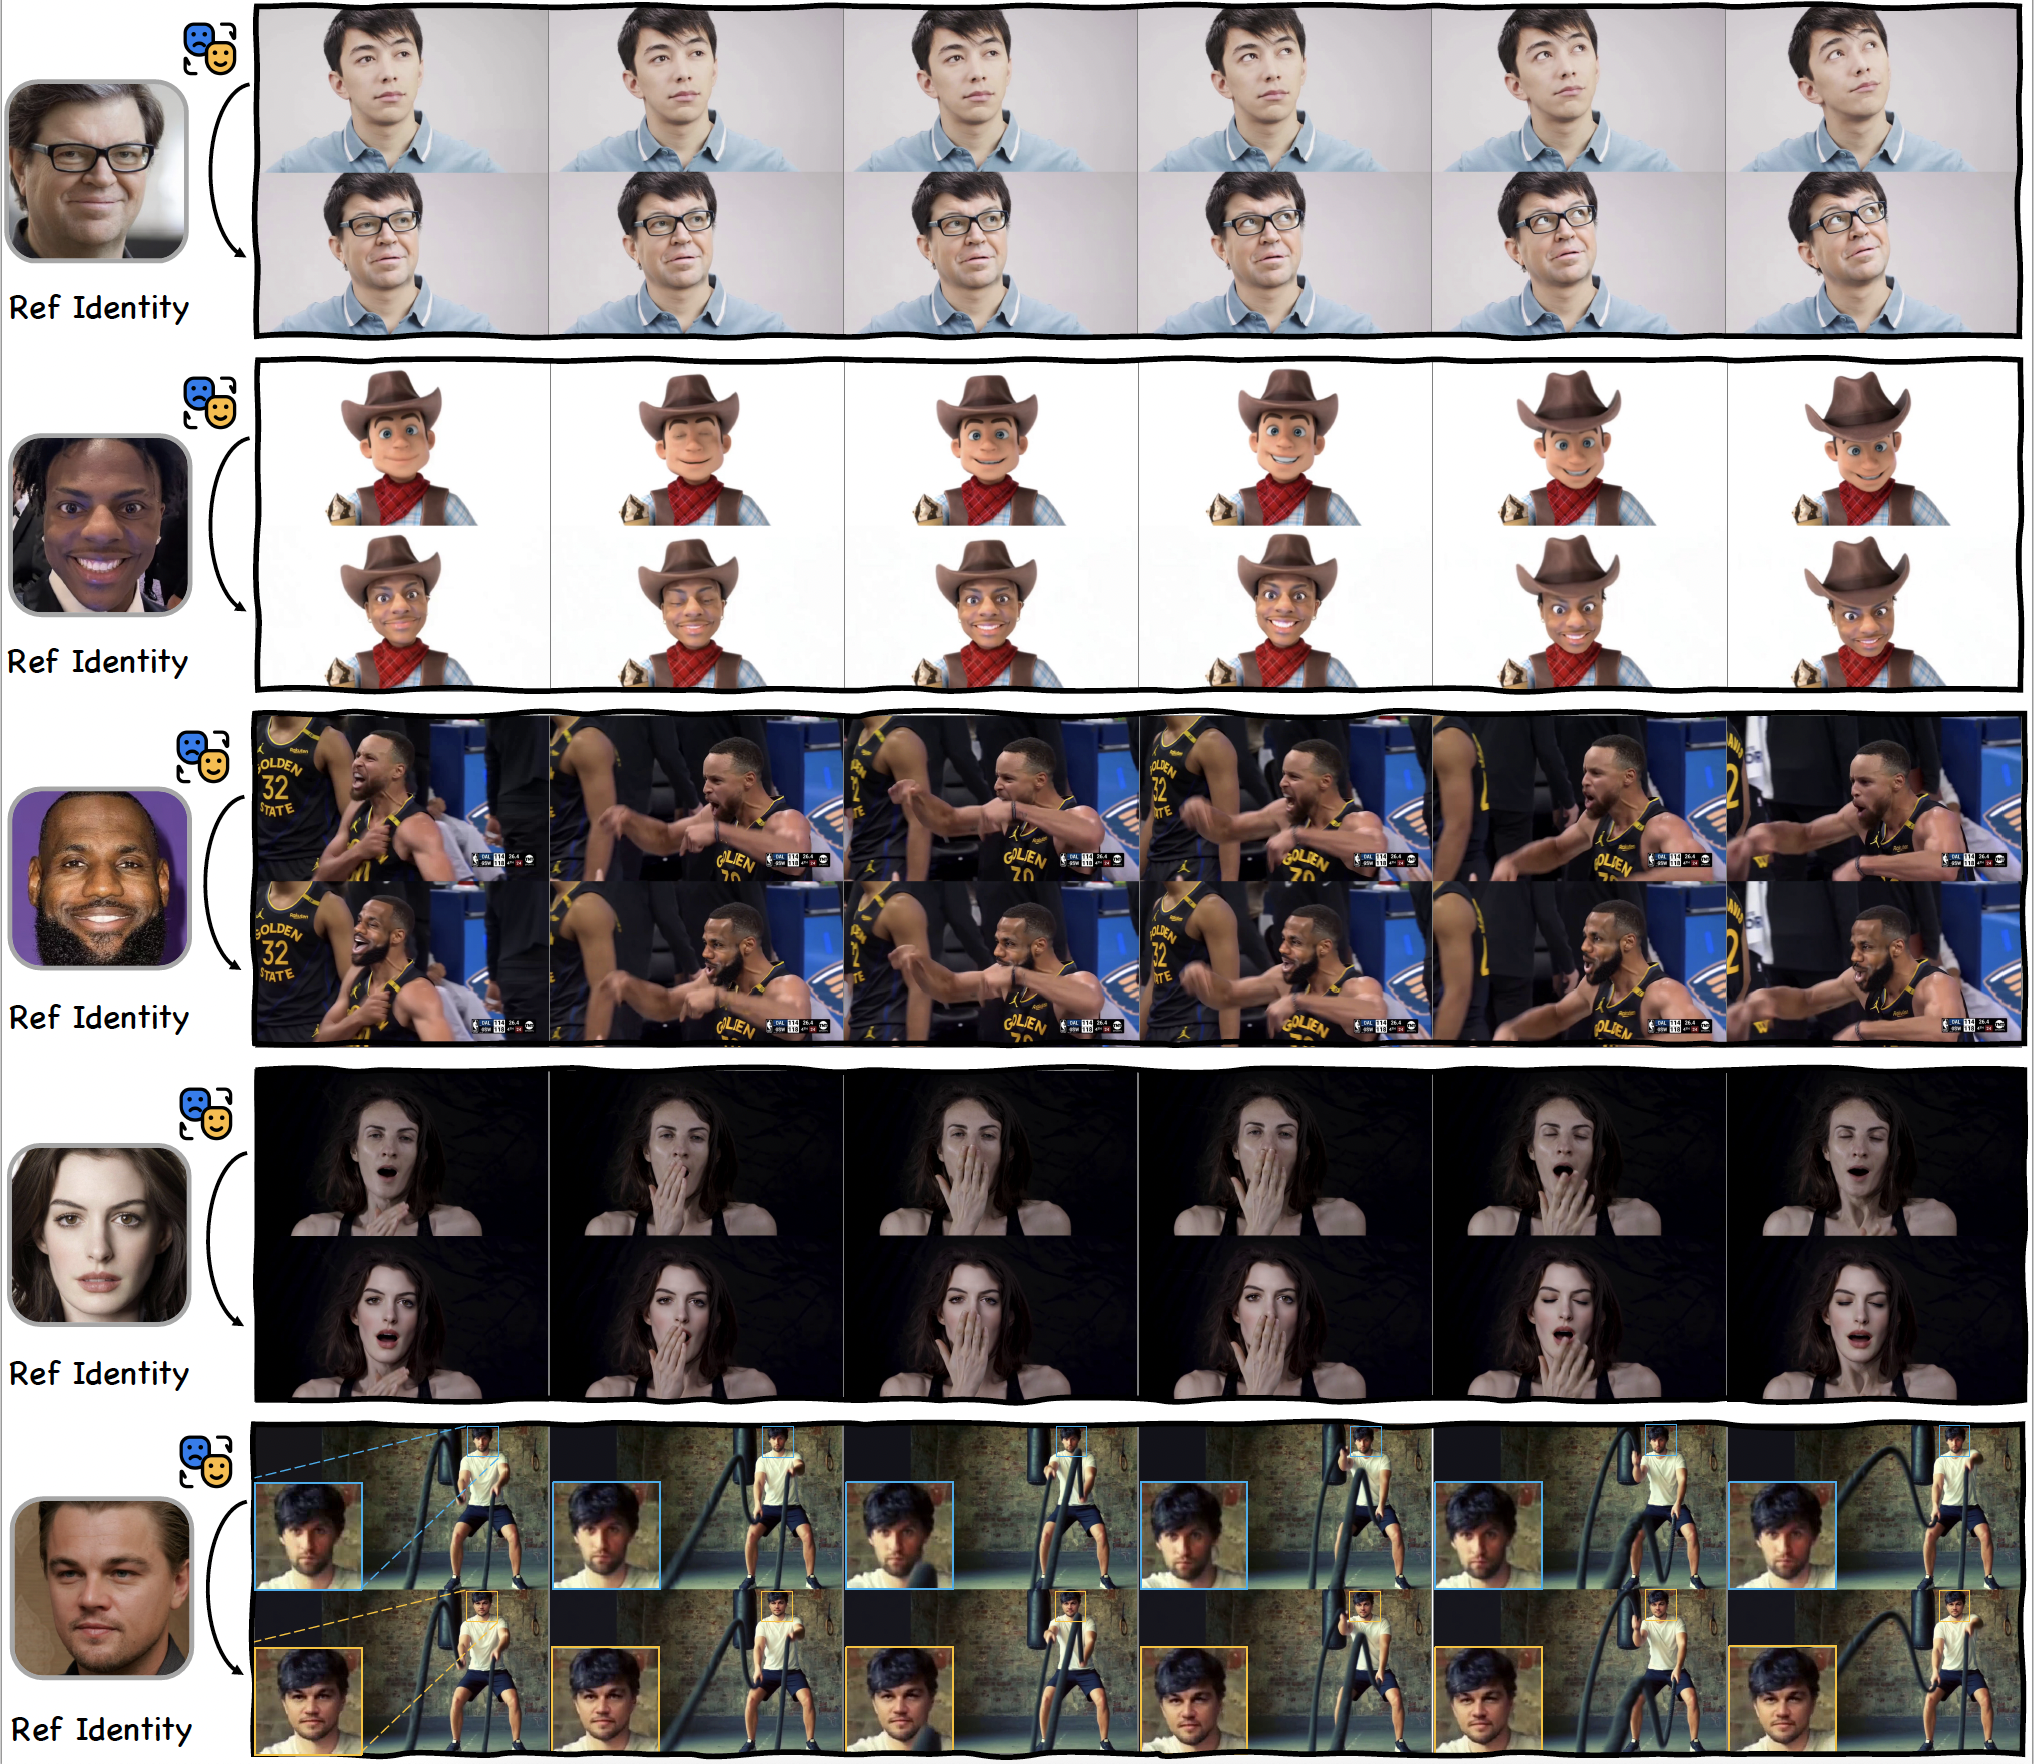
DreamID-V: Bridging the Image-to-Video Gap for High-Fidelity Face Swapping via Diffusion Transformer
🌐 Project Page | 📜 Arxiv | 🤗 Models | 🤗 IDBench-V(Comming) | 🤗 IDBench-Omni
DreamID-V: Bridging the Image-to-Video Gap for High-Fidelity Face Swapping via Diffusion Transformer
Xu Guo * , Fulong Ye * , Xinghui Li *, Pengqi Tu, Pengze Zhang, Qichao Sun, Songtao Zhao †, Xiangwang Hou † Qian He
- Equal contribution, † Corresponding author
Tsinghua University | Intelligent Creation Team, ByteDance
🔥 News
- [05/01/2026] 🎉 Our omni version DreamID-Omni is accepted by ICML 2026!
- [01/13/2026] 🔥 Thanks Goldlionren for supporting the DreamID-V Faster ComfyUI.
- [01/12/2026] 🔥 We released DreamID-V-Wan-1.3B-Faster, achieving a 1x inference speed boost with lower VRAM usage!
- [01/11/2026] 🔥 Thanks Goldlionren for supporting the 16GB VRAM GPUs version ComfyUI.
- [01/10/2026] 🔥 We released DreamID-V-Wan-1.3B-DWPose with enhanced pose detection stability!
- [01/08/2026] 🔥 Thanks HM-RunningHub for supporting ComfyUI.
- [01/06/2026] 🔥 Our paper is released!
- [01/05/2026] 🔥 Our code is released!
- [12/17/2025] 🔥 Our project is released!
- [08/11/2025] 🎉 Our image version DreamID is accepted by SIGGRAPH Asia 2025!
💡 Usage Tips
- Reference Image Preparation: Please upload cropped face images (recommended resolution: 512x512) as reference. Avoid using full-body photos to ensure optimal identity preservation.
- Inference Steps: For simple scenes, you can reduce the sampling steps to 20 to significantly decrease inference time.
Note: Our internal model based on Seedance1.0 achieves high quality in under 8 steps. Feel free to experience it at CapCut.
- Best Quality: For the highest fidelity results, we recommend using a resolution of 1280x720.
- Enhanced Pose Detection: We have resolved the previous pose detection issue by introducing DreamID-V-Wan-1.3B-DWPose. This significantly improves stability and robustness in pose extraction.
⚡️ Quickstart
Model Preparation
| Models | Download Link | Notes |
|---|---|---|
| DreamID-V | 🤗 Huggingface | Supports 480P & 720P |
| Wan-2.1 | 🤗 Huggingface | VAE & Text encoder |
Installation
Install dependencies:
# Ensure torch >= 2.4.0
pip install -r requirements.txt
DreamID-V-Wan-1.3B-Faster
Please ensure you have downloaded dreamidv_faster.pth and the DWPose estimation models are placed in the correct directory.
DreamID-V/
└── pose/
    └── models/
        ├── dw-ll_ucoco_384.onnx
        └── yolox_l.onnx
- Single-GPU inference
python generate_dreamidv_faster.py \
    --size 832*480 \
    --ckpt_dir wan2.1-1.3B path \
    --dreamidv_ckpt dreamidv_faster.pth path  \
    --sample_steps 16 \
    --base_seed 42
- Multi-GPU inference using FSDP + xDiT USP
pip install "xfuser>=0.4.1"
torchrun --nproc_per_node=2 generate_dreamidv_faster.py \
    --size 832*480 \
    --ckpt_dir wan2.1-1.3B path \
    --dreamidv_ckpt dreamidv_faster.pth path  \
    --sample_steps 16 \
    --dit_fsdp \
    --t5_fsdp \
    --ulysses_size 2 \
    --ring_size 1 \
    --base_seed 42
DreamID-V-Wan-1.3B-DWPose
Please ensure the pose estimation models are placed in the correct directory as follows:
DreamID-V/
└── pose/
    └── models/
        ├── dw-ll_ucoco_384.onnx
        └── yolox_l.onnx
- Single-GPU inference
python generate_dreamidv_dwpose.py \
    --size 832*480 \
    --ckpt_dir wan2.1-1.3B path \
    --dreamidv_ckpt dreamidv.pth path  \
    --sample_steps 20 \
    --base_seed 42
- Multi-GPU inference using FSDP + xDiT USP
pip install "xfuser>=0.4.1"
torchrun --nproc_per_node=2 generate_dreamidv_dwpose.py \
    --size 832*480 \
    --ckpt_dir wan2.1-1.3B path \
    --dreamidv_ckpt dreamidv.pth path  \
    --sample_steps 20 \
    --dit_fsdp \
    --t5_fsdp \
    --ulysses_size 2 \
    --ring_size 1 \
    --base_seed 42
DreamID-V-Wan-1.3B-MediaPipe
- Single-GPU inference
python generate_dreamidv.py \
    --size 832*480 \
    --ckpt_dir wan2.1-1.3B path \
    --dreamidv_ckpt dreamidv.pth path  \
    --sample_steps 20 \
    --base_seed 42
- Multi-GPU inference using FSDP + xDiT USP
pip install "xfuser>=0.4.1"
torchrun --nproc_per_node=2 generate_dreamidv.py \
    --size 832*480 \
    --ckpt_dir wan2.1-1.3B path \
    --dreamidv_ckpt dreamidv.pth path  \
    --sample_steps 20 \
    --dit_fsdp \
    --t5_fsdp \
    --ulysses_size 2 \
    --ring_size 1 \
    --base_seed 42
👍 Acknowledgements
Our work builds upon and is greatly inspired by several outstanding open-source projects, including Wan2.1, Phantom, OpenHumanVid, Follow-Your-Emoji, DWPose. We sincerely thank the authors and contributors of these projects for generously sharing their excellent codes and ideas.
📧 Contact
If you have any comments or questions regarding this open-source project, please open a new issue or contact Xu Guo and Fulong Ye.
⚠️ Ethics Statement
This project, DreamID-V, is intended for academic research and technical demonstration purposes only.
- Prohibited Use: Users are strictly prohibited from using this codebase to generate content that is illegal, defamatory, pornographic, harmful, or infringes upon the privacy and rights of others.
- Responsibility: Users bear full responsibility for the content they generate. The authors and contributors of this project assume no liability for any misuse or consequences arising from the use of this software.
- AI Labeling: We strongly recommend marking generated videos as "AI-Generated" to prevent misinformation. By using this software, you agree to adhere to these guidelines and applicable local laws.
⭐ Citation
If you find our work helpful, please consider citing our paper and leaving valuable stars
@article{guo2026dreamidv,
  title   = {DreamID-V: Bridging the Image-to-Video Gap for High-Fidelity Face Swapping via Diffusion Transformer},
  author  = {Guo, Xu and Ye, Fulong and Li, Xinghui and Tu, Pengqi and Zhang, Pengze and Sun, Qichao and Zhao, Songtao and Hou, Xiangwang and He, Qian},
  journal = {arXiv preprint arXiv:2601.01425},
  year    = {2026}
}