Dolphin: Document Image Parsing via Heterogeneous Anchor Prompting
Dolphin-v2 is an enhanced universal document parsing model that substantially improves upon the original Dolphin. It seamlessly handles any document type—whether digital-born or photographed—through a document-type-aware two-stage architecture with scalable anchor prompting.
📑 Overview
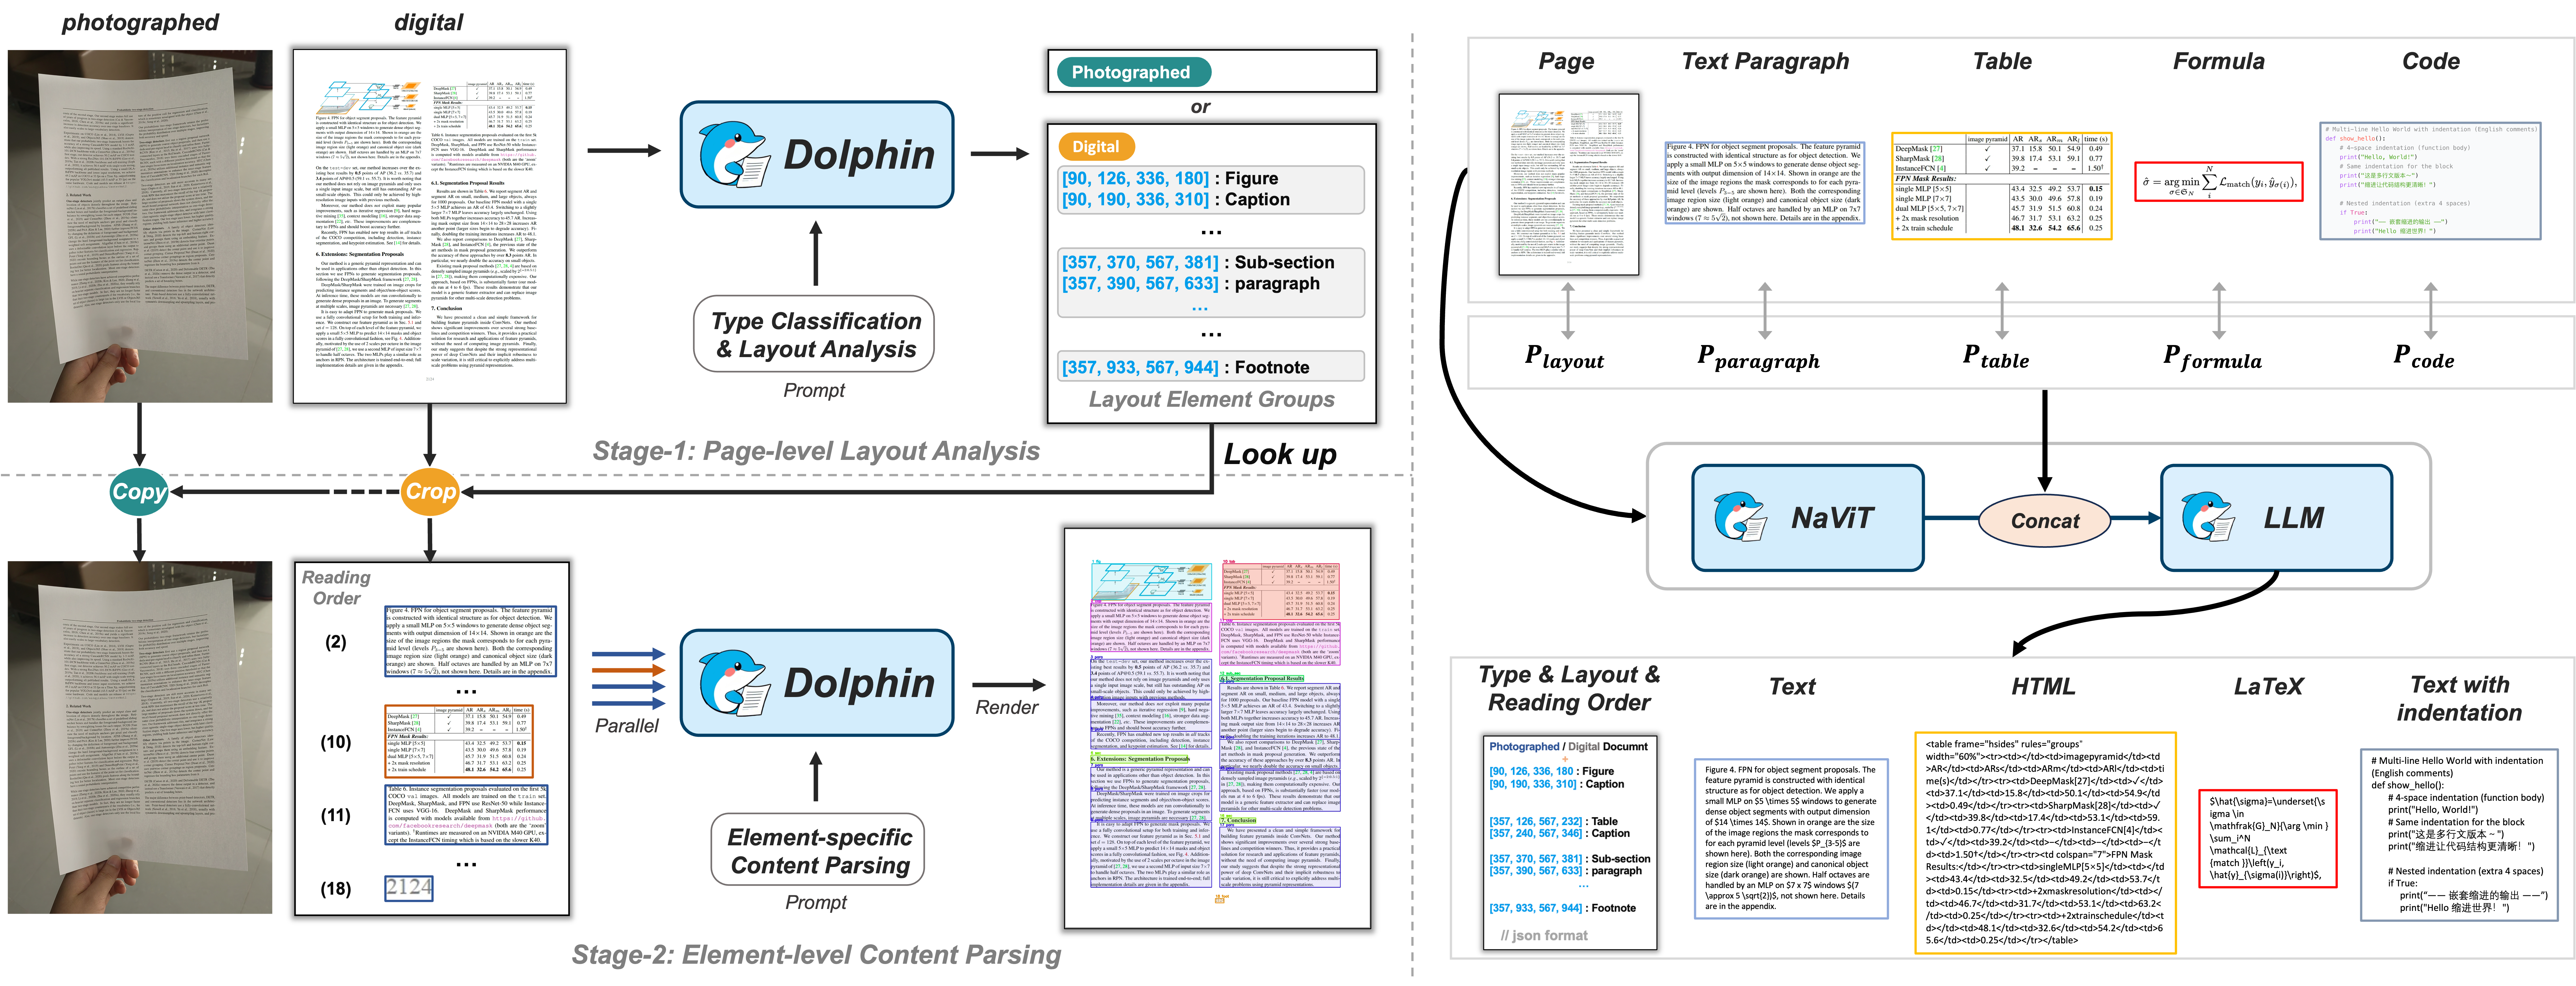
Document image parsing is challenging due to diverse document types and complexly intertwined elements such as text paragraphs, figures, formulas, tables, and code blocks. Dolphin-v2 addresses these challenges through a document-type-aware two-stage approach:
-
🔍 Stage 1: Document type classification (digital vs. photographed) + layout analysis with reading order prediction
-
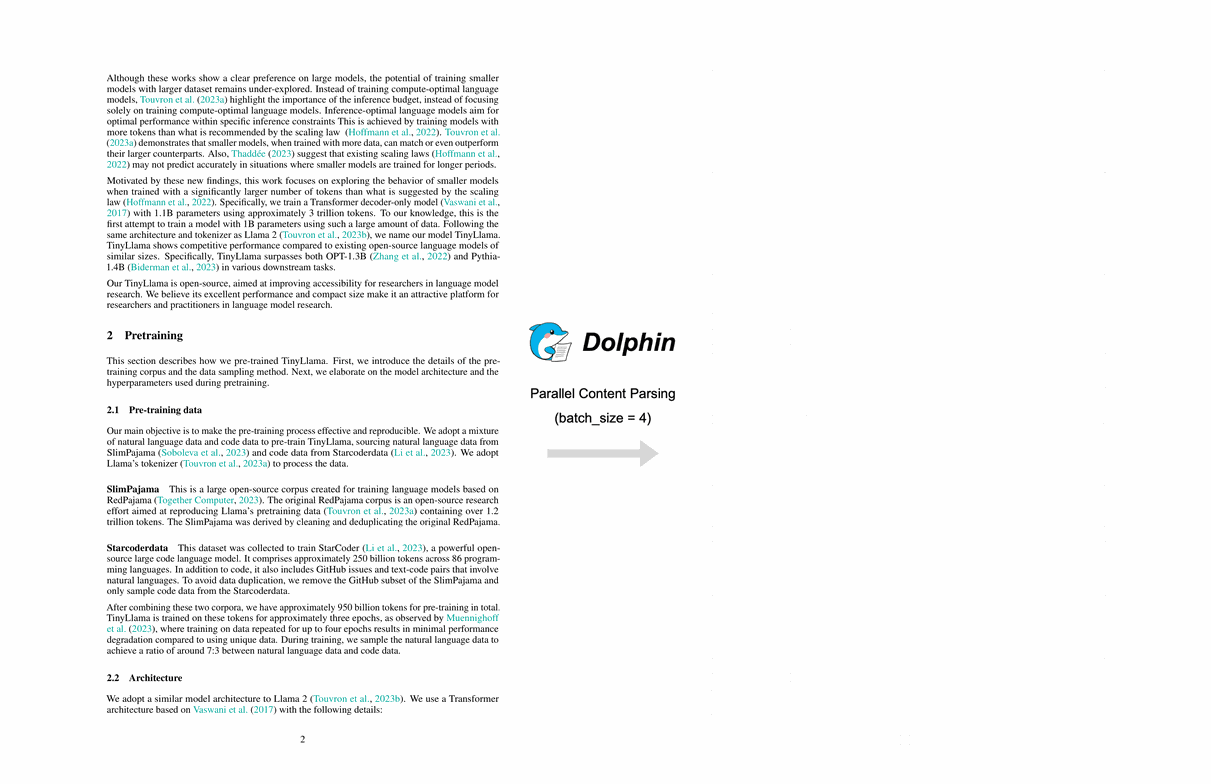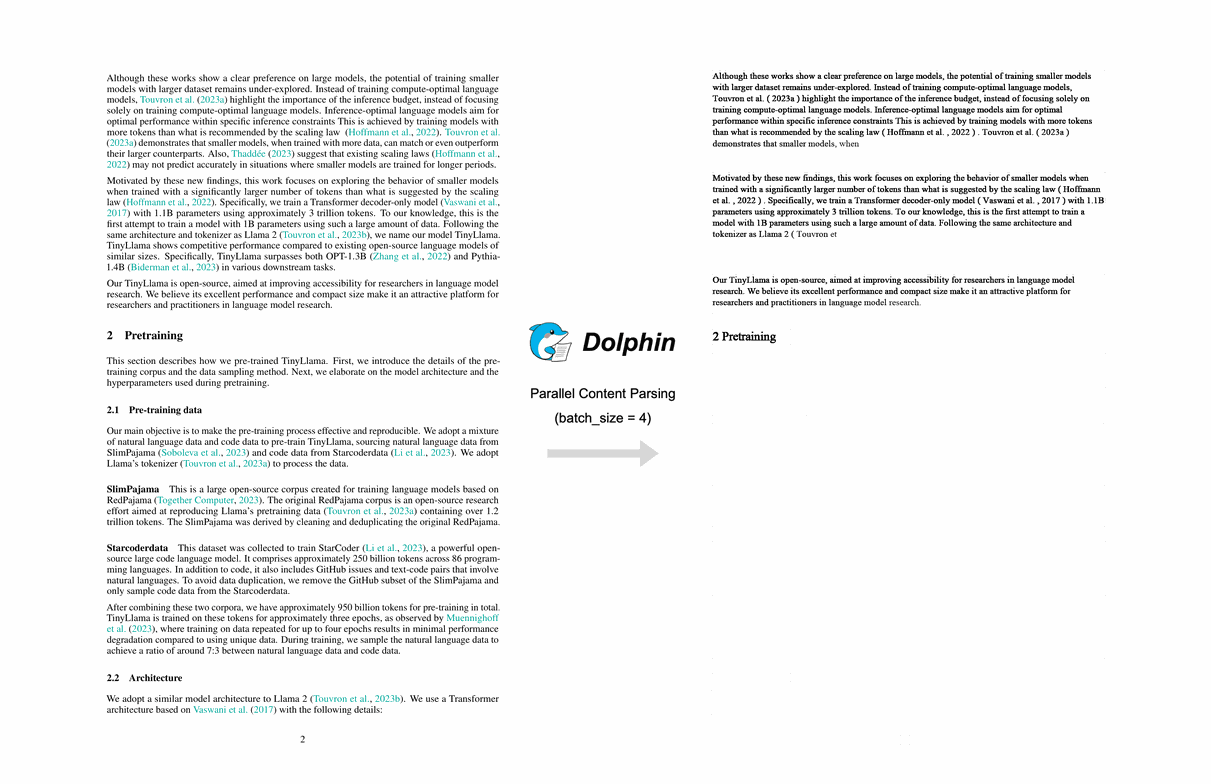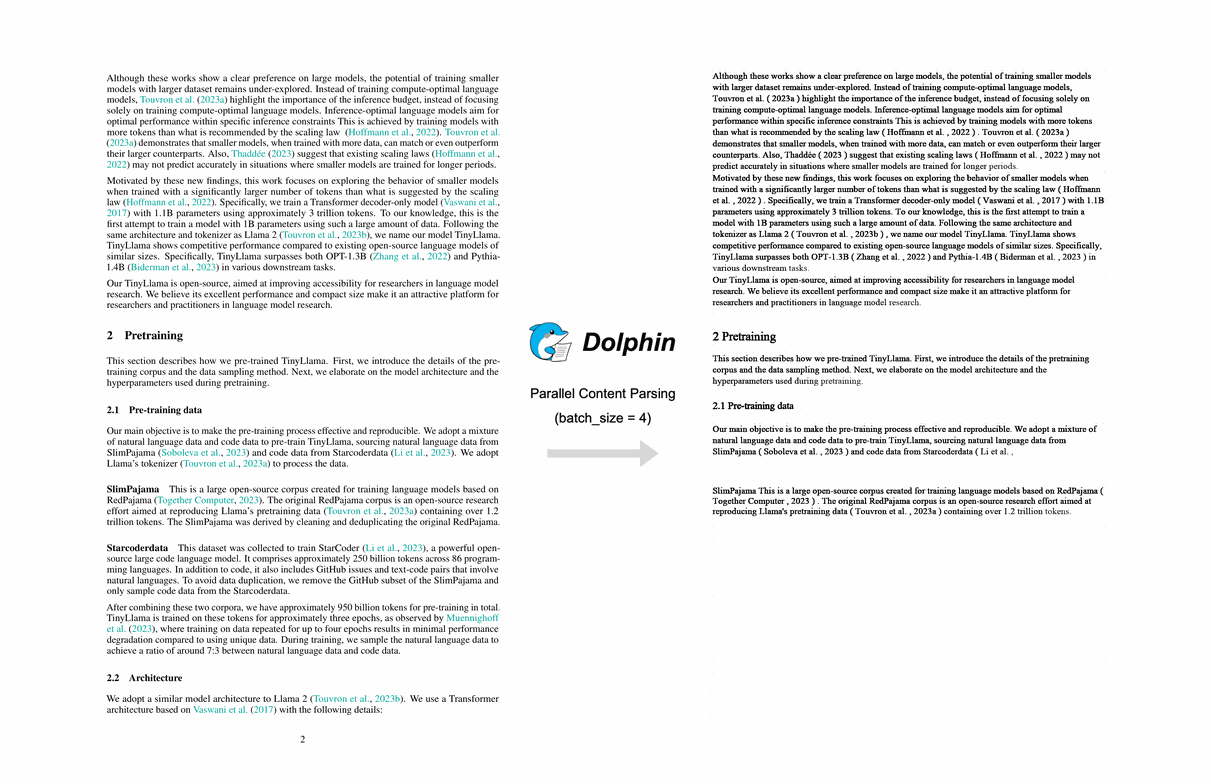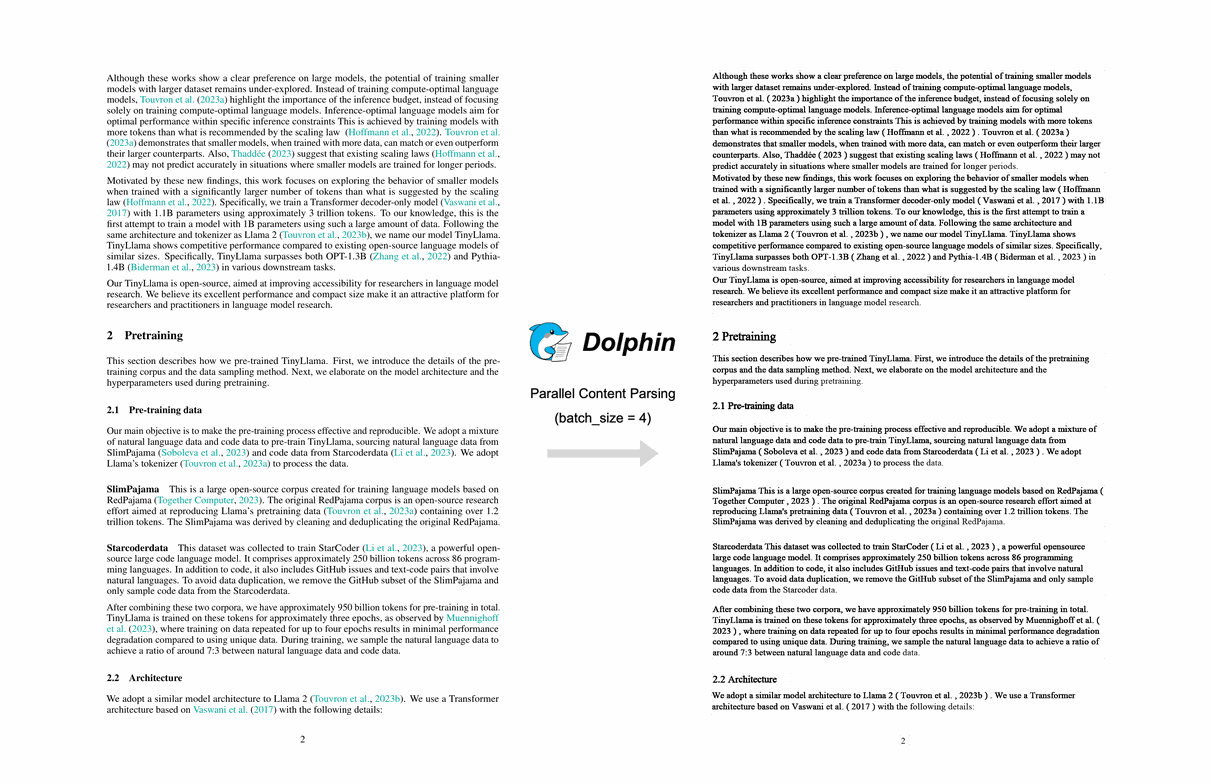
🧩 Stage 2: Hybrid parsing strategy - holistic parsing for photographed documents, parallel element-wise parsing for digital documents
Dolphin achieves promising performance across diverse page-level and element-level parsing tasks while ensuring superior efficiency through its lightweight architecture and parallel parsing mechanism.
📅 Changelog
- 🔥 2025.12.12 Released Dolphin-v2 model. Upgraded to 3B parameters with 21-element detection, attribute field extraction, dedicated formula/code parsing, and robust photographed document parsing. (Dolphin-1.5 moved to v1.5 branch)
- 🔥 2025.10.16 Released Dolphin-1.5 model. While maintaining the lightweight 0.3B architecture, this version achieves significant parsing improvements. (Dolphin 1.0 moved to v1.0 branch)
- 🔥 2025.07.10 Released the Fox-Page Benchmark, a manually refined subset of the original Fox dataset. Download via: Baidu Yun | Google Drive.
- 🔥 2025.06.30 Added TensorRT-LLM support for accelerated inference!
- 🔥 2025.06.27 Added vLLM support for accelerated inference!
- 🔥 2025.06.13 Added multi-page PDF document parsing capability.
- 🔥 2025.05.21 Our demo is released at link. Check it out!
- 🔥 2025.05.20 The pretrained model and inference code of Dolphin are released.
- 🔥 2025.05.16 Our paper has been accepted by ACL 2025. Paper link: arXiv.
📈 Performance
Comprehensive evaluation of document parsing on OmniDocBench (v1.5)
Model
Size
Overall↑
TextEdit↓
FormulaCDM↑
TableTEDS↑
TableTEDS-S↑
Read OrderEdit↓
Dolphin
0.3B
74.67
0.125
67.85
68.70
77.77
0.124
Dolphin-1.5
0.3B
85.06
0.085
79.44
84.25
88.06
0.071
Dolphin-v2
3B
89.78
0.054
87.63
87.02
90.48
0.054
🛠️ Installation
-
Clone the repository:
git clone https://github.com/ByteDance/Dolphin.git cd Dolphin -
Install the dependencies:
pip install -r requirements.txt -
Download the pre-trained models of Dolphin-v2:
Visit our Huggingface model card, or download model by:
# Download the model from Hugging Face Hub
git lfs install
git clone https://huggingface.co/ByteDance/Dolphin-v2 ./hf_model
# Or use the Hugging Face CLI
pip install huggingface_hub
huggingface-cli download ByteDance/Dolphin-v2 --local-dir ./hf_model
⚡ Inference
Dolphin provides two inference frameworks with support for two parsing granularities:
- Page-level Parsing: Parse the entire document page into a structured JSON and Markdown format
- Element-level Parsing: Parse individual document elements (text, table, formula)
📄 Page-level Parsing
# Process a single document image
python demo_page.py --model_path ./hf_model --save_dir ./results \
    --input_path ./demo/page_imgs/page_1.png

# Process a single document pdf
python demo_page.py --model_path ./hf_model --save_dir ./results \
    --input_path ./demo/page_imgs/page_6.pdf

# Process all documents in a directory
python demo_page.py --model_path ./hf_model --save_dir ./results \
    --input_path ./demo/page_imgs

# Process with custom batch size for parallel element decoding
python demo_page.py --model_path ./hf_model --save_dir ./results \
    --input_path ./demo/page_imgs \
    --max_batch_size 8
🧩 Element-level Parsing
# Process element images (specify element_type: table, formula, text, or code)
python demo_element.py --model_path ./hf_model --save_dir ./results \
    --input_path  \
    --element_type [table|formula|text|code]
🎨 Layout Parsing
# Process a single document image
python demo_layout.py --model_path ./hf_model --save_dir ./results \
    --input_path ./demo/page_imgs/page_1.png \

# Process a single PDF document
python demo_layout.py --model_path ./hf_model --save_dir ./results \
    --input_path ./demo/page_imgs/page_6.pdf \

# Process all documents in a directory
python demo_layout.py --model_path ./hf_model --save_dir ./results \
    --input_path ./demo/page_imgs
🌟 Key Features
- 🔄 Two-stage analyze-then-parse approach based on a single VLM
- 📊 Promising performance on document parsing tasks
- 🔍 Natural reading order element sequence generation
- 🧩 Heterogeneous anchor prompting for different document elements
- ⏱️ Efficient parallel parsing mechanism
- 🤗 Support for Hugging Face Transformers for easier integration
📮 Notice
Call for Bad Cases: If you have encountered any cases where the model performs poorly, we would greatly appreciate it if you could share them in the issue. We are continuously working to optimize and improve the model.
💖 Acknowledgement
We would like to acknowledge the following open-source projects that provided inspiration and reference for this work:
📝 Citation
If you find this code useful for your research, please use the following BibTeX entry.
@article{feng2025dolphin,
  title={Dolphin: Document Image Parsing via Heterogeneous Anchor Prompting},
  author={Feng, Hao and Wei, Shu and Fei, Xiang and Shi, Wei and Han, Yingdong and Liao, Lei and Lu, Jinghui and Wu, Binghong and Liu, Qi and Lin, Chunhui and others},
  journal={arXiv preprint arXiv:2505.14059},
  year={2025}
}