← 开源
benedekrozemberczki

graph2vec

A parallel implementation of "graph2vec: Learning Distributed Representations of Graphs" (MLGWorkshop 2017).

Model DevelopmentArchitecturePython
在 GitHub 打开
增长势头
+024 小时新增 Star0.0%
934
Star
165
Fork
+0
本周
3
贡献者
创建于 2018-07-10 · 更新于 2026-09-28 · 今日第 12541 名
主要开发者
benedekrozemberczkichamath-eka5teven1in

benedekrozemberczki/graph2vec 排名第 12,541,有 934 个星标。

同类别比较

benedekrozemberczki/graph2vec 排名第 12,541,此处有 8 个同类条目;ImprintLab/Medical-SAM2 排名第 12,540。

同类别比较
名称排名指标
mnicnc404/CartoonGan-tensorflow12,524
语言:
Python
星标数:
937
分叉数:
238
简介:
Generate your own cartoon-style images with CartoonGAN (CVPR 2018), powered by TensorFlow 2.0 Alpha.
acbull/pyHGT12,529
语言:
Python
星标数:
936
分叉数:
173
简介:
Code for "Heterogeneous Graph Transformer" (WWW'20), which is based on pytorch_geometric
baal-org/baal12,530
语言:
Python
星标数:
936
分叉数:
91
简介:
Bayesian active learning library for research and industrial usecases.
ImprintLab/Medical-SAM212,540
语言:
Python
星标数:
934
分叉数:
139
简介:
Medical SAM 2: Segment 3D Medical Images Via Segment Anything Model 2
eric-yyjau/pytorch-superpoint12,544
语言:
Jupyter Notebook
星标数:
934
分叉数:
194
简介:
Superpoint Implemented in PyTorch: https://arxiv.org/abs/1712.07629
dusty-nv/jetson-reinforcement12,546
语言:
C++
星标数:
933
分叉数:
224
简介:
Deep reinforcement learning GPU libraries for NVIDIA Jetson TX1/TX2 with PyTorch, OpenAI Gym, and Gazebo robotics simulator.
rusty1s/pytorch_cluster12,551
语言:
C++
星标数:
933
分叉数:
164
简介:
PyTorch Extension Library of Optimized Graph Cluster Algorithms
Mukosame/Zooming-Slow-Mo-CVPR-202012,566
语言:
Python
星标数:
930
分叉数:
163
简介:
Fast and Accurate One-Stage Space-Time Video Super-Resolution (accepted in CVPR 2020)
关键参数与规格
关键参数与规格
参数值
语言Python
类别Model Development
子类别Architecture
关键词Graph
星标数934
分叉数165
贡献者3
创建日期2018-07-10
更新日期2026-09-28
1 天星标数0
7 天星标数0
排名12,541
上次排名12,462
排名变化-79
7 天星标排名13,480
上次 7 天星标排名13,488
7 天星标排名变化8
总星标排名11,734
上次总星标排名11,717
总星标排名变化-17
国家UK
README 摘录

However, many graph analytics tasks such as graph classification and clustering require representing entire graphs as fixed length feature vectors. While the aforementioned approaches are naturally unequipped to learn such representations, graph kernels remain as the most effective way of obtaining them. However, these graph kernels use handcrafted features (e. ) and hence are hampered by problems such as poor generalization. To address this limitation, in this work, we propose a neural embedding framework named graph2vec to learn data-driven distributed

representations of arbitrary sized graphs. graph2vec's embeddings are learnt in an unsupervised manner and are task agnostic. Hence, they could be used for any downstream task such as graph classification, clustering and even seeding supervised representation learning approaches. Our experiments on several benchmark and large real-world datasets show that graph2vec achieves significant improvements in classification and clustering accuracies over substructure representation learning approaches and are competitive with state-of-the-art graph kernels. The model is now also available

in the Karate Club package. This repository provides an implementation for *graph2vec* as it is described in: graph2vec: Learning distributed representations of graphs. Narayanan, Annamalai and Chandramohan, Mahinthan and Venkatesan, Rajasekar and Chen, Lihui and Liu, Yang MLG 2017, 13th International Workshop on Mining and Learning with Graphs (MLGWorkshop 2017). The original TensorFlow implementation is available [[here]]( Requirements The codebase is implemented in Python 3. Package versions used for development are just below. Datasets The code takes an input folder

with json files. Every file is a graph and files have a numeric index as a name. The first key called "edges" corresponds to the edge list of the graph. The second key "features" corresponds to the node features. If the second key is not present the WL machine defaults to use the node degree as a feature. A sample graph dataset from NCI1 is included in the directory. Options Learning of the embedding is handled by the script which

provides the following command line arguments. Input and output options Model options Examples The following commands learn an embedding of the graphs and writes it to disk. The node representations are ordered by the ID. Creating a graph2vec embedding of the default dataset with the default hyperparameter settings. Saving the embedding at the default path. Creating an embedding of an other dataset. Creating an embedding of the default dataset in 32 dimensions.

常见问题

记录了多少星标和分叉?

benedekrozemberczki/graph2vec 有 934 个星标和 165 个分叉。

仓库排名是多少?

benedekrozemberczki/graph2vec 排名第 12,541。

记录的语言和类别是什么?

benedekrozemberczki/graph2vec 有 934 个星标,语言为 Python,类别为 Model Development。

哪个仓库排名最接近?

benedekrozemberczki/graph2vec 与 ImprintLab/Medical-SAM2 比较,后者排名第 12,540,有 934 个星标。

README

Graph2Vec

Abstract


Recent works on representation learning for graph structured data predominantly focus on learning distributed representations of graph substructures such as nodes and subgraphs. However, many graph analytics tasks such as graph classification and clustering require representing entire graphs as fixed length feature vectors. While the aforementioned approaches are naturally unequipped to learn such representations, graph kernels remain as the most effective way of obtaining them. However, these graph kernels use handcrafted features (e.g., shortest paths, graphlets, etc.) and hence are hampered by problems such as poor generalization. To address this limitation, in this work, we propose a neural embedding framework named graph2vec to learn data-driven distributed representations of arbitrary sized graphs. graph2vec's embeddings are learnt in an unsupervised manner and are task agnostic. Hence, they could be used for any downstream task such as graph classification, clustering and even seeding supervised representation learning approaches. Our experiments on several benchmark and large real-world datasets show that graph2vec achieves significant improvements in classification and clustering accuracies over substructure representation learning approaches and are competitive with state-of-the-art graph kernels.
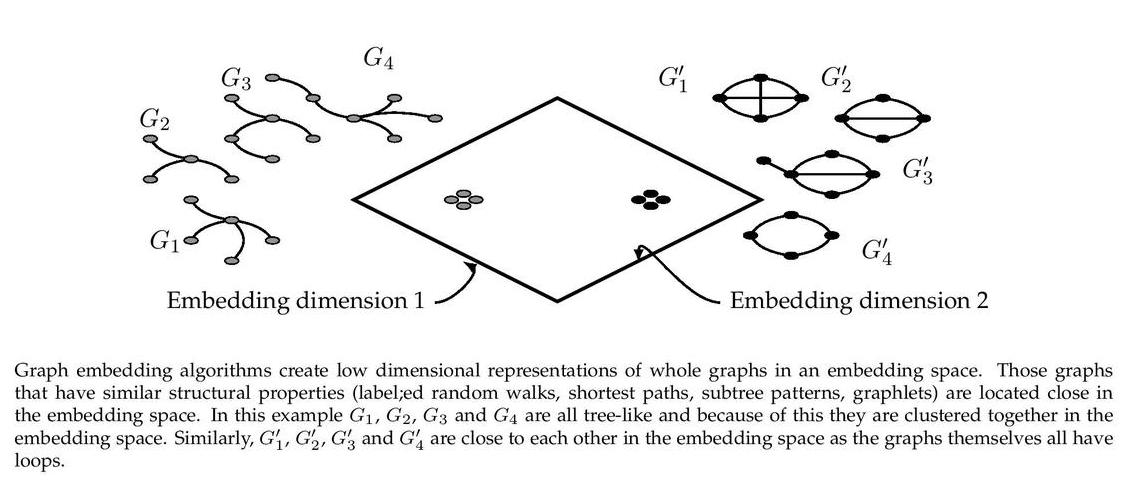
The model is now also available in the Karate Club package.

This repository provides an implementation for graph2vec as it is described in:

graph2vec: Learning distributed representations of graphs. Narayanan, Annamalai and Chandramohan, Mahinthan and Venkatesan, Rajasekar and Chen, Lihui and Liu, Yang MLG 2017, 13th International Workshop on Mining and Learning with Graphs (MLGWorkshop 2017).

The original TensorFlow implementation is available [here].

Requirements

The codebase is implemented in Python 3.5.2 | Anaconda 4.2.0 (64-bit). Package versions used for development are just below.

jsonschema        2.6.0
tqdm              4.28.1
numpy             1.15.4
pandas            0.23.4
texttable         1.5.0
gensim            3.6.0
networkx          2.4
joblib            0.13.0
logging           0.4.9.6  

Datasets

The code takes an input folder with json files. Every file is a graph and files have a numeric index as a name. The json files have two keys. The first key called "edges" corresponds to the edge list of the graph. The second key "features" corresponds to the node features. If the second key is not present the WL machine defaults to use the node degree as a feature. A sample graph dataset from NCI1 is included in the dataset/ directory.

Options

Learning of the embedding is handled by the src/graph2vec.py script which provides the following command line arguments.

Input and output options

  --input-path   STR    Input folder.           Default is `dataset/`.
  --output-path  STR    Embeddings path.        Default is `features/nci1.csv`.

Model options

  --dimensions     INT          Number of dimensions.                             Default is 128.
  --workers        INT          Number of workers.                                Default is 4.
  --epochs         INT          Number of training epochs.                        Default is 1.
  --min-count      INT          Minimal feature count to keep.                    Default is 5.
  --wl-iterations  INT          Number of feature extraction recursions.          Default is 2.
  --learning-rate  FLOAT        Initial learning rate.                            Default is 0.025.
  --down-sampling  FLOAT        Down sampling rate for frequent features.         Default is 0.0001.

Examples

The following commands learn an embedding of the graphs and writes it to disk. The node representations are ordered by the ID. Creating a graph2vec embedding of the default dataset with the default hyperparameter settings. Saving the embedding at the default path.

$ python src/graph2vec.py

Creating an embedding of an other dataset. Saving the output in a custom place.

$ python src/graph2vec.py --input-path new_data/ --output-path features/nci2.csv

Creating an embedding of the default dataset in 32 dimensions.

$ python src/graph2vec.py --dimensions 32

License

排名相邻
同类项目