LightNet
!!!New Repo.!!! ⇒ LightNet++: Boosted Light-weighted Networks for Real-time Semantic Segmentation
!!!New Repo.!!! ⇒ EfficientNet.PyTorch: Concise, Modular, Human-friendly PyTorch implementation of EfficientNet with Pre-trained Weights
!!!New Repo.!!! ⇒ MixNet-Pytorch: Concise, Modular, Human-friendly PyTorch implementation of MixNet with Pre-trained Weights
This repository contains the code (in PyTorch) for: "LightNet: Light-weight Networks for Semantic Image Segmentation " (underway) by Huijun Liu @ TU Braunschweig.
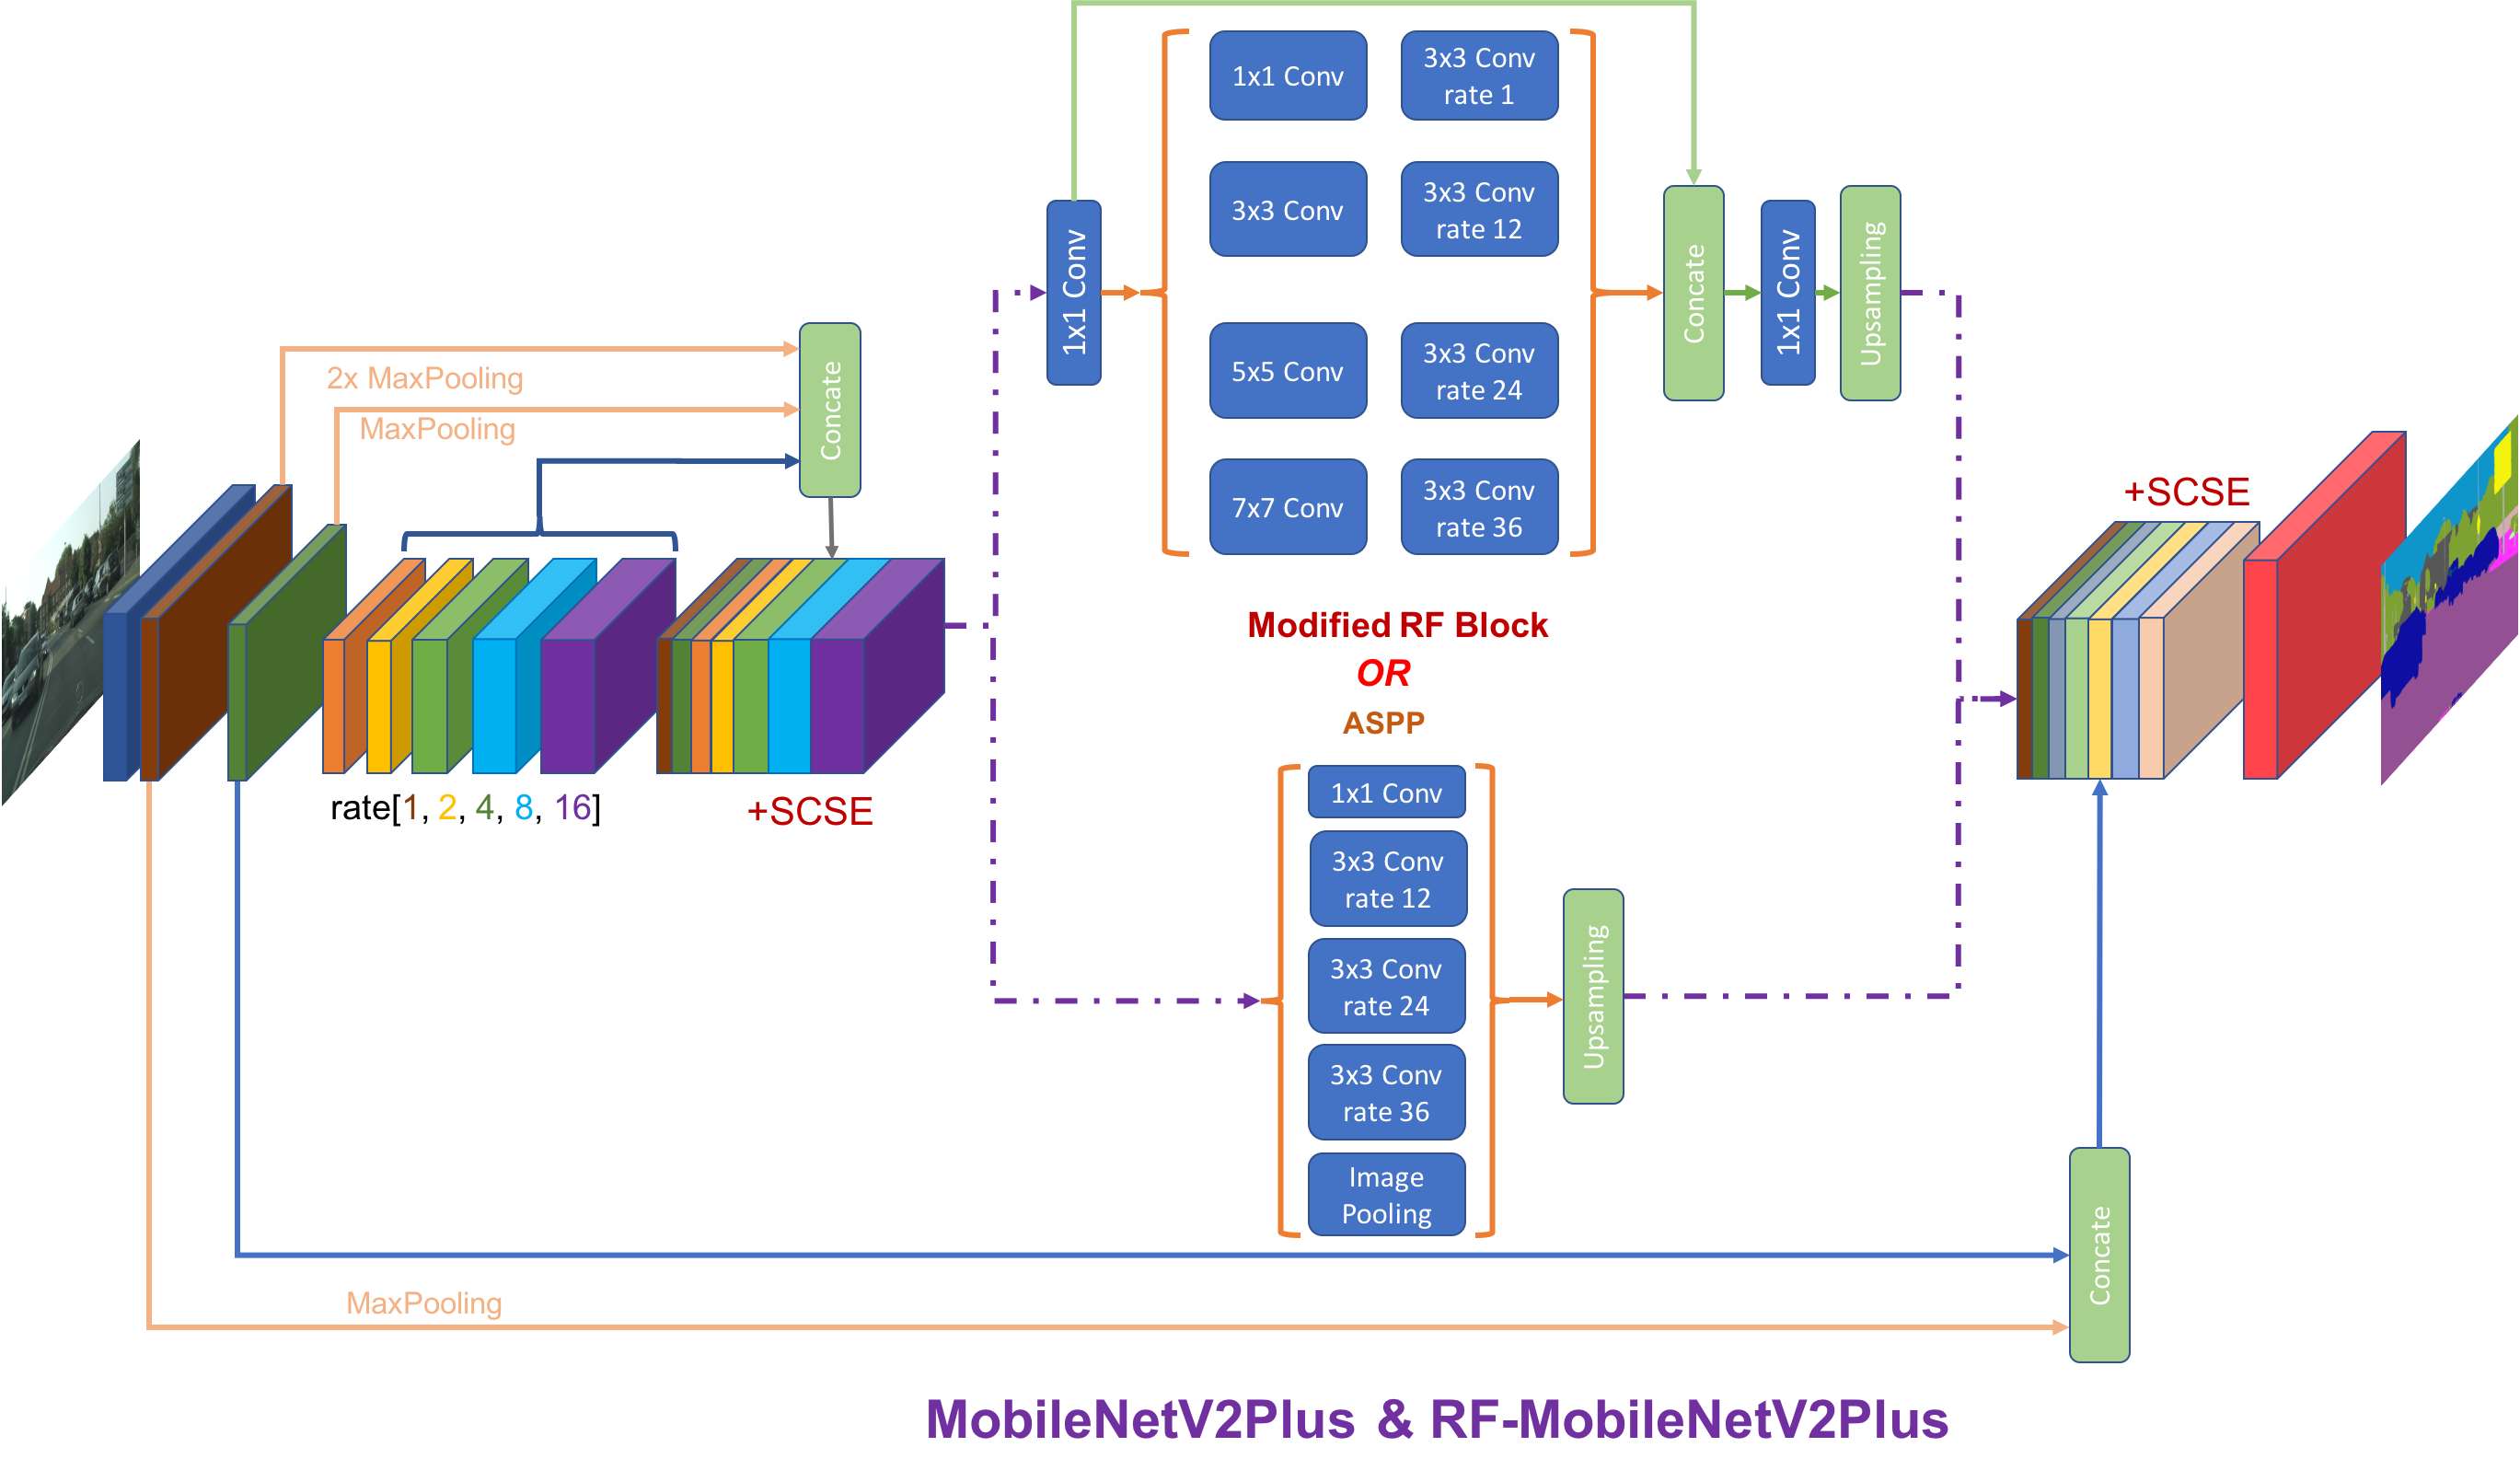
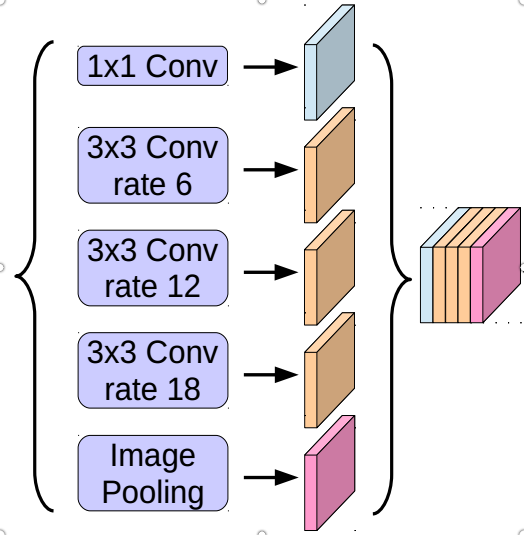
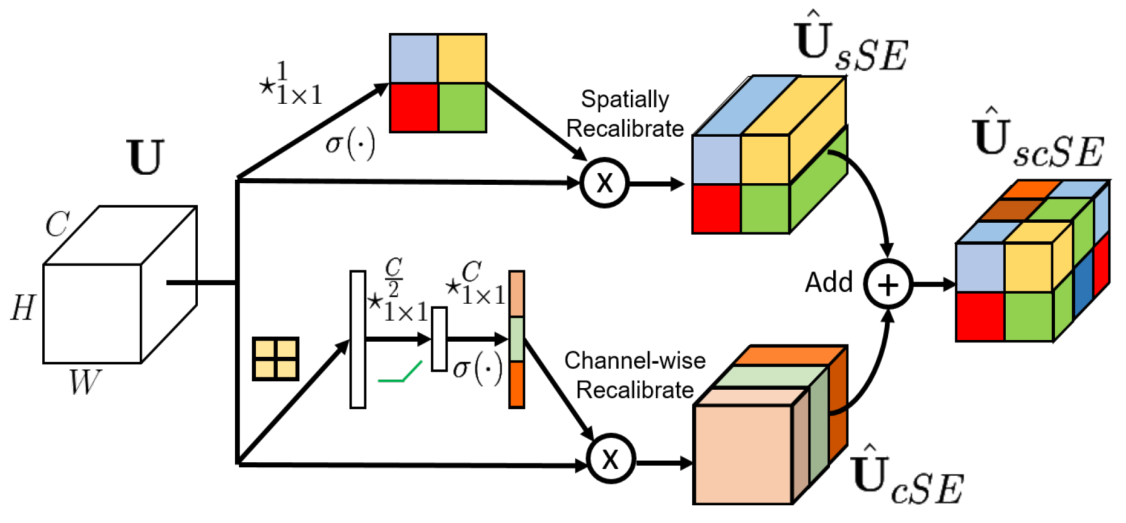
- MobileNetV2Plus: Modified MobileNetV2[1,8] + Spatial-Channel Sequeeze & Excitation (SCSE)[6] + ASPP[2,3] + Encoder-Decoder Arch.[3] + InplaceABN[4].
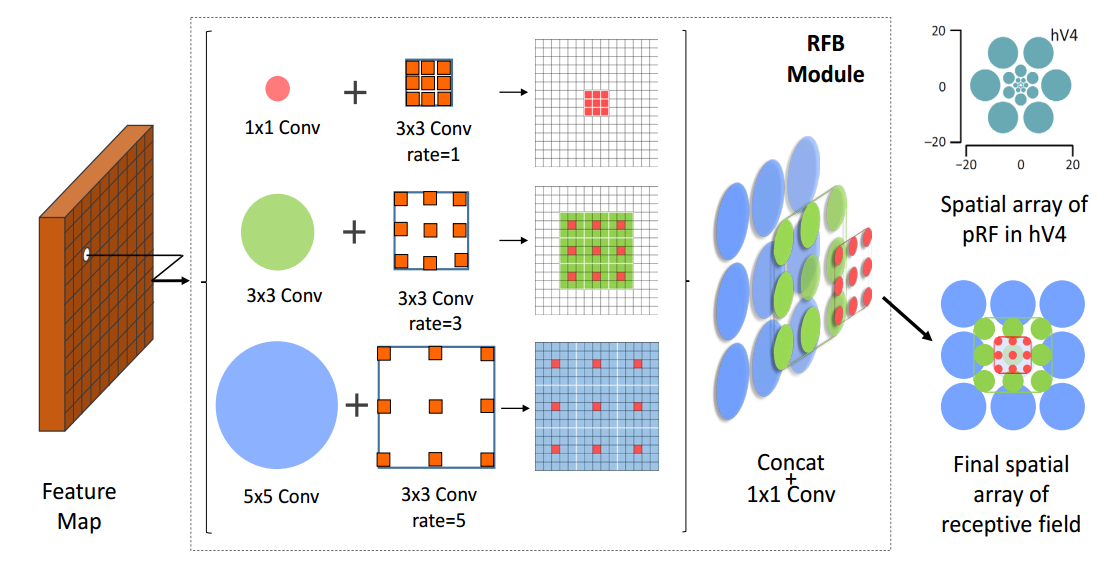
- RF-MobileNetV2Plus: Modified MobileNetV2 + SCSE + Receptive Field Block (RFB)[5] + Encoder-Decoder Arch. + InplaceABN.
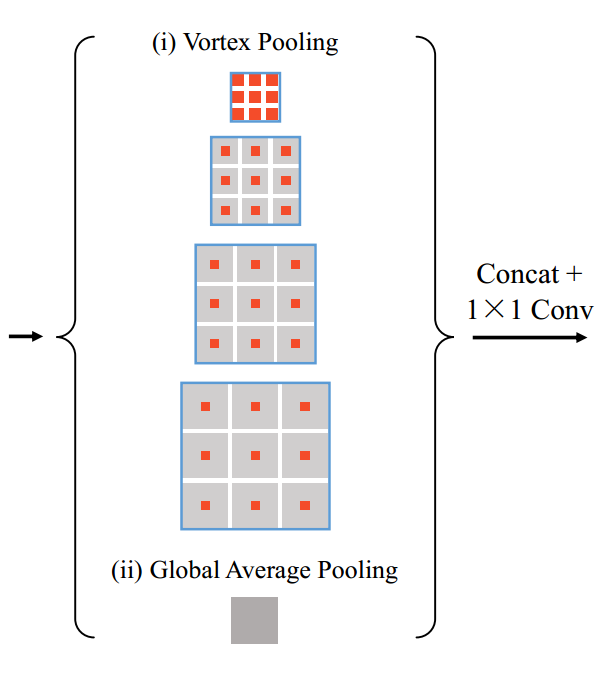
- MobileNetV2Vortex: Modified MobileNetV2 + SCSE + Vortex Pooling[24] + Encoder-Decoder Arch. + InplaceABN.
- MobileNetV2Share: Split Image & Concat Features + Modified MobileNetV2 + SCSE + ASPP/RFB + Encoder-Decoder Arch. + InplaceABN.
- Mixed-scale DenseNet: Modified Mixed-scale DenseNet[11] + SCSE + ASPP/RFB + InplaceABN.
- SE-WResNetV2: Modified WResNetV2 (InplaceABN & SCSE/SE)[4,6,7,13] + SCSE/SE + ASPP/RFB + Encoder-Decoder Arch. + InplaceABN.
- ShuffleNetPlus: Modified ShuffleNet[9] + SCSE + ASPP/RFB + Encoder-Decoder Arch. + InplaceABN.
!!!New!!!: add Vortex Pooling[24]
I no longer have GPUs to continue more experiments and model training (I borrowed 2 GPUs from the Institute for Computer Graphics @ TU Braunschweig to complete preliminary experiments, so thank them and Lukas Zhang here.), so if you like, welcome to experiment with other under-training models and my ideas!
Contents
Introduction
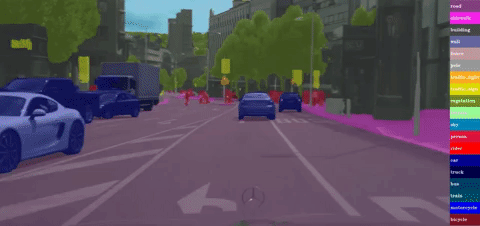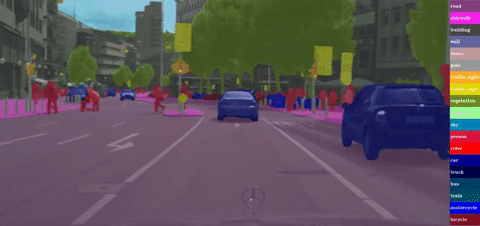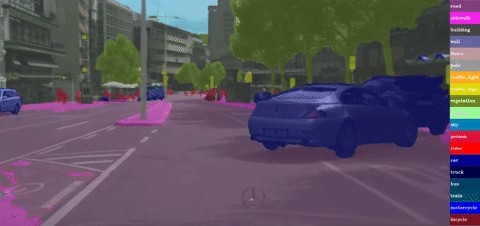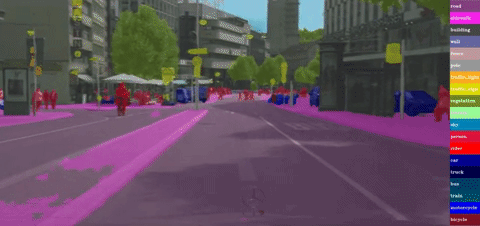
Semantic Segmentation is a significant part of the modern autonomous driving system, as exact understanding the surrounding scene is very important for the navigation and driving decision of the self-driving car. Nowadays, deep fully convolutional networks (FCNs) have a very significant effect on semantic segmentation, but most of the relevant researchs have focused on improving segmentation accuracy rather than model computation efficiency. However, the autonomous driving system is often based on embedded devices, where computing and storage resources are relatively limited. In this paper we describe several light-weight networks based on MobileNetV2, ShuffleNet and Mixed-scale DenseNet for semantic image segmentation task, Additionally, we introduce GAN for data augmentation[17] (pix2pixHD) concurrent Spatial-Channel Sequeeze & Excitation (SCSE) and Receptive Field Block (RFB) to the proposed network. We measure our performance on Cityscapes pixel-level segmentation, and achieve up to 70.72% class mIoU and 88.27% cat. mIoU. We evaluate the trade-offs between mIoU, and number of operations measured by multiply-add (MAdd), as well as the number of parameters.
Network Architecture
Usage
Dependencies
- Python3
- PyTorch(0.3.0+)
- tensorboard
- tensorboardX
- tqdm
- inplace_abn
- CityscapesScripts
- Cityscapes
- Mapillary Vistas Dataset
Train
As an example, use the following command to train a LightNet on Cityscapes or Mapillary Vistas Dataset:
> python3 train_mobile.py
> python3 train_mobile_mvd.py
> python3 train_share.py
> python3 train_mixscale.py
> python3 train_shuffle.py
> python3 train_inplace.py
Evaluation
We take the Cityscapes model trained above as an example.
To evaluate the trained model:
> python3 deploy_model.py
> python3 evaluation_cityscapes.py
> python3 demo_cityscapes.py
Other Options
We also include Mixed-scale DenseNet/RF-Mixed-scale DenseNet, ShuffleNetPlus/RFShuffleNetPlus, SE-DPShuffleNet, SE-Wide-ResNetV2 implementation in this repository.
Results
Mixed-scale DenseNet/RF-Mixed-scale DenseNet, ShuffleNetPlus/RFShuffleNetPlus, SE-DPShuffleNet, SE-Wide-ResNetV2 under-training (Ask a friend for help)
Results on Cityscapes (Pixel-level/Semantic Segmentation)
| Model | GFLOPs | Params | gtFine/gtCoarse/GAN | mIoU Classes(val./test S.S*) | mIoU Cat.(val./test S.S*) | Result(*.cvs) | Pytorch Model&Checkpoint |
|---|---|---|---|---|---|---|---|
| MobileNetV2Plus | 117.1? | 8.3M | Yes/No/No | 70.13/68.90 | 87.95/86.85 | GoogleDrive | / |
| MobileNetV2SDASPP | ? | ?M | Yes/No/Yes | 73.17/70.09 | 87.98/87.84 | GoogleDrive | GoogleDrive |
| MobileNetV2Plus | 117.1? | 8.3M | Yes/No/Yes | 73.89/70.72 | 88.72/87.64 | GoogleDrive | GoogleDrive |
| RF-MobileNetV2Plus | 87.6? | 8.6M | Yes/No/Yes | 72.37/70.68 | 88.31/88.27 | GoogleDrive | GoogleDrive |
| ShuffleNetPlus | 229.3? | 15.3M | Yes/No/Yes | * | * | * | * |
| Mixed-scale DenseNet | 49.9? | 0.80M | Yes/No/Yes | * | * | * | * |
| SE-WResNetV2 | ? | ?M | Yes/No/No | 80.13/77.15 | 90.87/90.59 | GoogleDrive | / |
- S.S.: Single Scale
Contact
ansleliu@gmail.com
h.liu@tu-braunschweig.de
Any discussions or concerns are welcomed!
References
[1]. Inverted Residuals and Linear Bottlenecks: Mobile Networks for Classification, Detection and Segmentation
[2]. Rethinking Atrous Convolution for Semantic Image Segmentation
[3]. Encoder-Decoder with Atrous Separable Convolution for Semantic Image Segmentation
[4]. In-Place Activated BatchNorm for Memory-Optimized Training of DNNs
[5]. Receptive Field Block Net for Accurate and Fast Object Detection
[6]. Concurrent Spatial and Channel Squeeze & Excitation in Fully Convolutional Networks
[7]. Squeeze-and-Excitation Networks
[8]. MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications
[9]. ShuffleNet: An Extremely Efficient Convolutional Neural Network for Mobile Devices
[10]. Averaging Weights Leads to Wider Optima and Better Generalization
[11]. A mixed-scale dense convolutional neural network for image analysis
[12]. Dual Path Networks
[13]. Wide Residual Networks
[14]. Densely Connected Convolutional Networks
[15]. CondenseNet: An Efficient DenseNet using Learned Group Convolutions
[16]. Full-Resolution Residual Networks for Semantic Segmentation in Street Scenes
[17]. High-Resolution Image Synthesis and Semantic Manipulation with Conditional GANs
[18]. SGDR: Stochastic Gradient Descent with Warm Restarts
[19]. Cyclical Learning Rates for Training Neural Networks
[20]. Group Normalization
[21]. Context Encoding for Semantic Segmentation
[22]. ExFuse: Enhancing Feature Fusion for Semantic Segmentation
[23]. The Lovász-Softmax loss: A tractable surrogate for the optimization of the intersection-over-union measure in neural networks
[24]. Vortex Pooling: Improving Context Representation in Semantic Segmentation
Acknowledgement
[0]. Lukas Zhang: Lend me GPUs.
[1]. meetshah1995: pytorch-semseg.
[2]. ruinmessi: RFBNet.
[3]. Jackson Huang: ShuffleNet.
[4]. Ji Lin: pytorch-mobilenet-v2.
[5]. ericsun99: MobileNet-V2-Pytorch.
[6]. Ross Wightman: pytorch-dpn-pretrained.
[7]. mapillary: inplace_abn.
[8]. Cadene: pretrained-models.pytorch.
[9]. Maxim Berman: LovaszSoftmax.