Fast & Lightweight License Plate OCR


Introduction
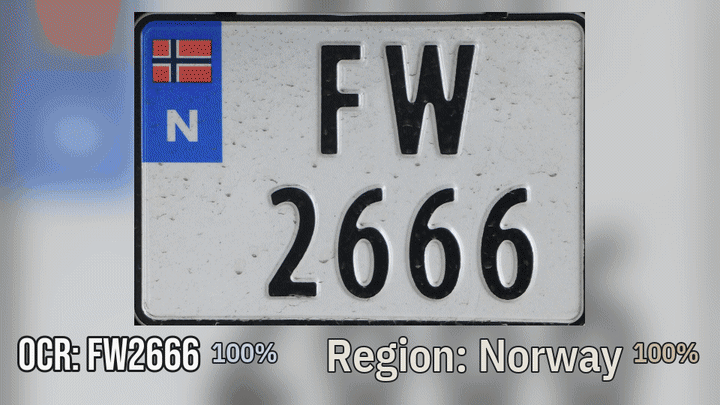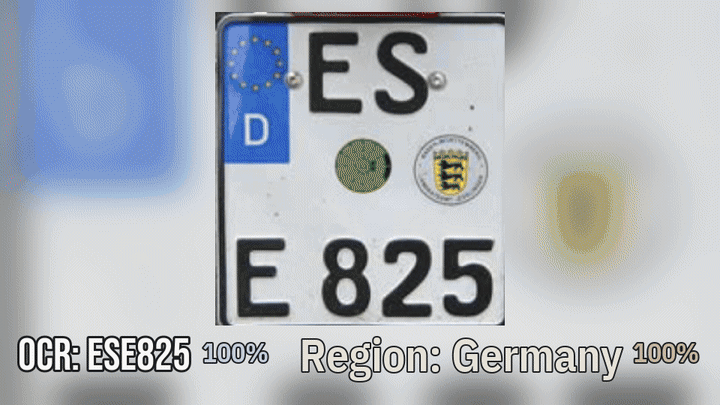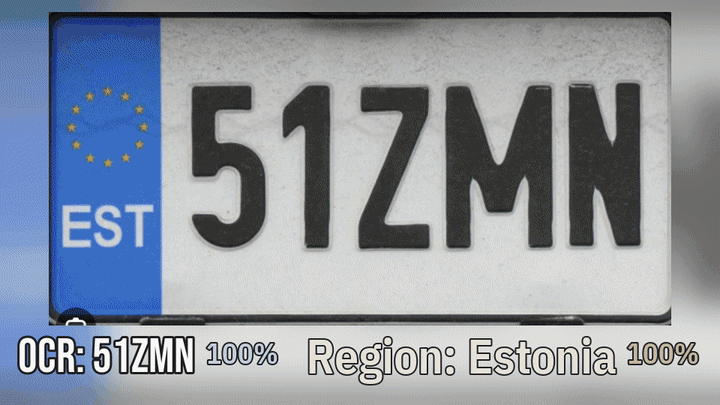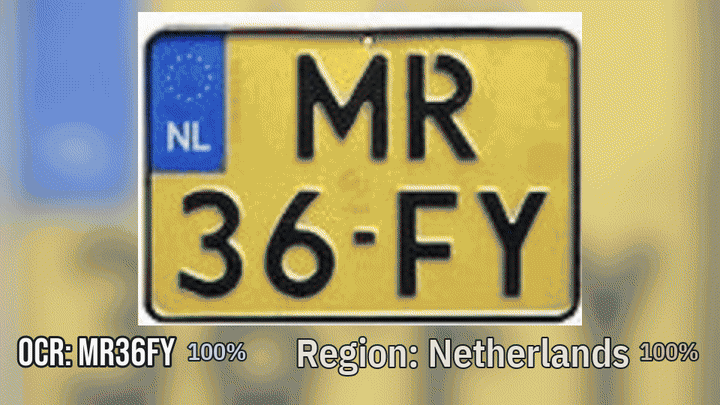
Lightweight and fast OCR models for license plate text recognition. You can train models from scratch or use the trained models for inference.
The idea is to use this after a plate object detector, since the OCR expects the cropped plates.
Features
- Keras 3 Backend Support: Train seamlessly using TensorFlow, JAX, or PyTorch backends 🧠
- Efficient Execution: Lightweight models that are cheap to run 💰
- ONNX Runtime Inference: Fast and optimized inference with ONNX runtime ⚡
- User-Friendly CLI: Simplified CLI for training and validating OCR models 🛠️
- Region Recognition (Optional): Predict region/country of the license plate 🌍
- Model HUB: Access to a collection of pre-trained models ready for inference 🌟
- Train/Fine-tune: Easily train or fine-tune your own models 🔧
- Export-Friendly: Export easily to CoreML, TFLite, or ONNX formats 📦
Available Models
Optimized, ready to use models with config files for inference or fine-tuning.
| Model Name | Size | Arch | b=1 Avg. Latency (ms) | Plates/sec (PPS) | Model Config | Plate Config | Val Results |
|---|---|---|---|---|---|---|---|
cct-s-v2-global-model |
S | CCT | 0.6758 | 1479.61 | model_config.yaml | plate_config.yaml | results |
cct-xs-v2-global-model |
XS | CCT | 0.4664 | 2144.14 | model_config.yaml | plate_config.yaml | results |
cct-s-v1-global-model |
S | CCT | 0.5877 | 1701.63 | model_config.yaml | plate_config.yaml | results |
cct-xs-v1-global-model |
XS | CCT | 0.3232 | 3094.21 | model_config.yaml | plate_config.yaml | results |
[!TIP] 🚀 Try the above models in Hugging Spaces.
[!NOTE] Benchmark Setup
These results were obtained with:
- Hardware: NVIDIA RTX 3090 GPU
- Execution Providers:
['TensorrtExecutionProvider', 'CUDAExecutionProvider', 'CPUExecutionProvider']- Install dependencies:
pip install fast-plate-ocr[onnx-gpu]
Explore the Model Zoo to see all available models.
Inference
For doing inference, install:
pip install fast-plate-ocr[onnx-gpu]
By default, no ONNX runtime is installed. To run inference, you must install at least one ONNX backend using an appropriate extra.
| Platform/Use Case | Install Command | Notes |
|---|---|---|
| CPU (default) | pip install fast-plate-ocr[onnx] |
Cross-platform |
| NVIDIA GPU (CUDA) | pip install fast-plate-ocr[onnx-gpu] |
Linux/Windows |
| Intel (OpenVINO) | pip install fast-plate-ocr[onnx-openvino] |
Best on Intel CPUs |
| Windows (DirectML) | pip install fast-plate-ocr[onnx-directml] |
For DirectML support |
| Qualcomm (QNN) | pip install fast-plate-ocr[onnx-qnn] |
Qualcomm chipsets |
Usage
To predict from disk image:
from fast_plate_ocr import LicensePlateRecognizer

m = LicensePlateRecognizer('cct-s-v2-global-model')
print(m.run('test_plate.png'))
If your model includes a region head (and plate_regions is defined in the plate config), predictions
also include region. The region_prob field is populated when return_confidence=True:
from fast_plate_ocr import LicensePlateRecognizer

m = LicensePlateRecognizer('cct-s-v2-global-model')
pred = m.run('test_plate.png', return_confidence=True)[0]
print(pred.region, pred.region_prob)
To run a model benchmark:
from fast_plate_ocr import LicensePlateRecognizer

m = LicensePlateRecognizer('cct-s-v2-global-model')
m.benchmark()
For more examples and the full API, see the Inference Guide and Reference.
Training
You can train models from scratch or fine-tune a pre-trained one using your own license plate dataset.
Install the training dependencies:
pip install fast-plate-ocr[train]
Fine-tuning Tutorial
A complete tutorial notebook is available for fine-tuning a license plate OCR model on your own dataset:
examples/fine_tune_workflow.ipynb. It covers the full workflow, from
preparing your dataset to training and exporting the model.
For full details on data preparation, model configs, fine-tuning, and training commands, check out the docs.
For region recognition and export-friendly activations, use the v2 models.
Contributing
Contributions to the repo are greatly appreciated. Whether it's bug fixes, feature enhancements, or new models, your contributions are warmly welcomed.
To start contributing or to begin development, you can follow these steps:
- Clone repo
git clone https://github.com/ankandrew/fast-plate-ocr.git - Install all dependencies (make sure you have uv installed):
make install - To ensure your changes pass linting and tests before submitting a PR:
make checks
Citations
@article{hassani2021escaping,
    title   = {Escaping the Big Data Paradigm with Compact Transformers},
    author  = {Ali Hassani and Steven Walton and Nikhil Shah and Abulikemu Abuduweili and Jiachen Li and Humphrey Shi},
    year    = 2021,
    url     = {https://arxiv.org/abs/2104.05704},
    eprint  = {2104.05704},
    archiveprefix = {arXiv},
    primaryclass = {cs.CV}
}