🚀 Metric3D Project 🚀
Official PyTorch implementation of Metric3Dv1 and Metric3Dv2:
[1] Metric3D: Towards Zero-shot Metric 3D Prediction from A Single Image


🏆 Champion in CVPR2023 Monocular Depth Estimation Challenge
News
[2024/8]Metric3Dv2 is accepted by TPAMI![2024/7/5]Our stable-diffusion alternative GeoWizard has now been accepted by ECCV 2024! Check NOW the repository and paper for the finest-grained geometry ever! 🎉🎉🎉[2024/6/25]Json files for KITTI datasets now available! Refer to Training for more details[2024/6/3]ONNX is supported! We appreciate @xenova for their remarkable efforts![2024/4/25]Weights for ViT-giant2 model released![2024/4/11]Training codes are released![2024/3/18]HuggingFace 🤗 GPU version updated![2024/3/18]Project page released![2024/3/18]Metric3D V2 models released, supporting metric depth and surface normal now![2023/8/10]Inference codes, pre-trained weights, and demo released.[2023/7]Metric3D accepted by ICCV 2023![2023/4]The Champion of 2nd Monocular Depth Estimation Challenge in CVPR 2023
🌼 Abstract
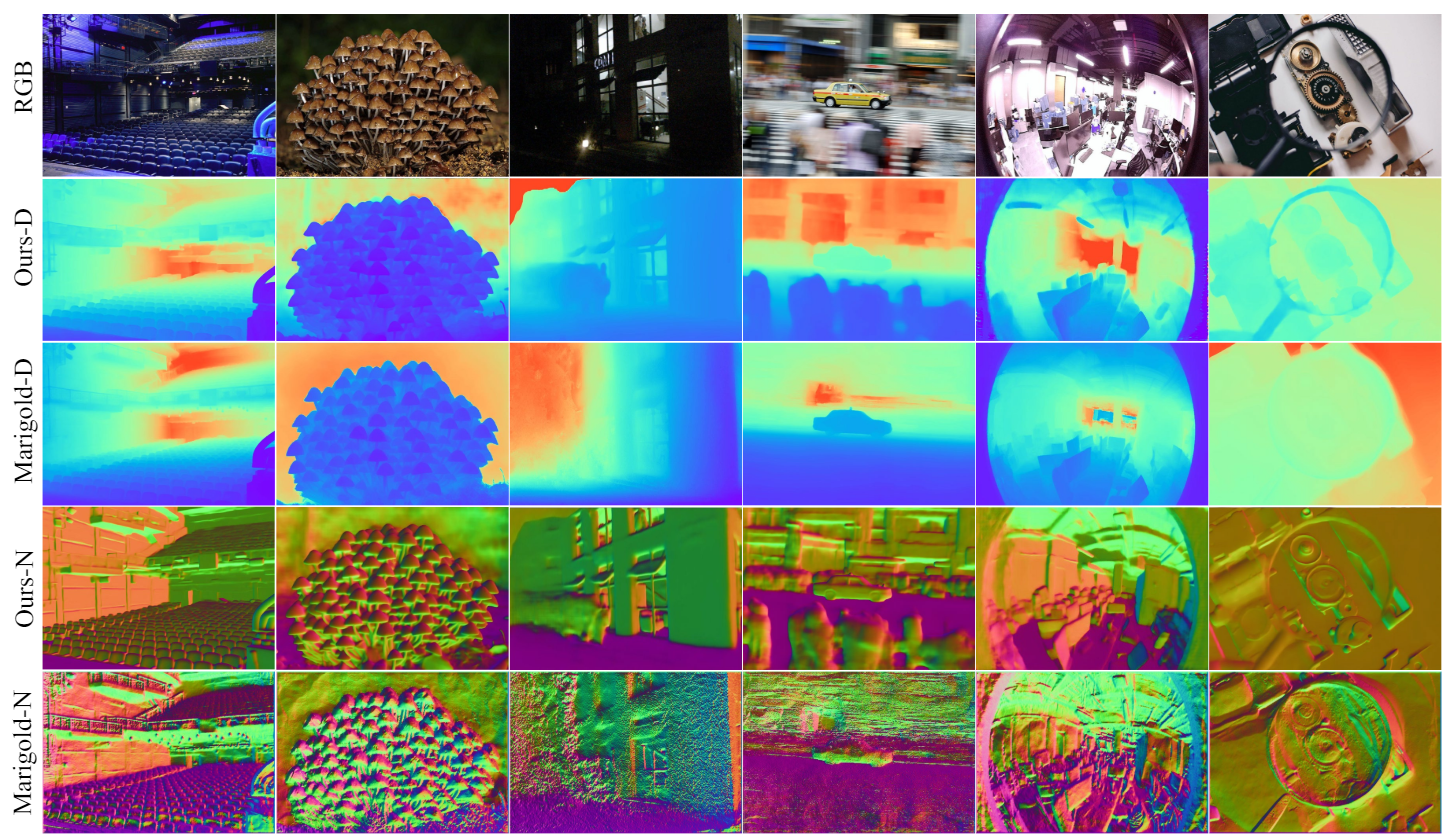
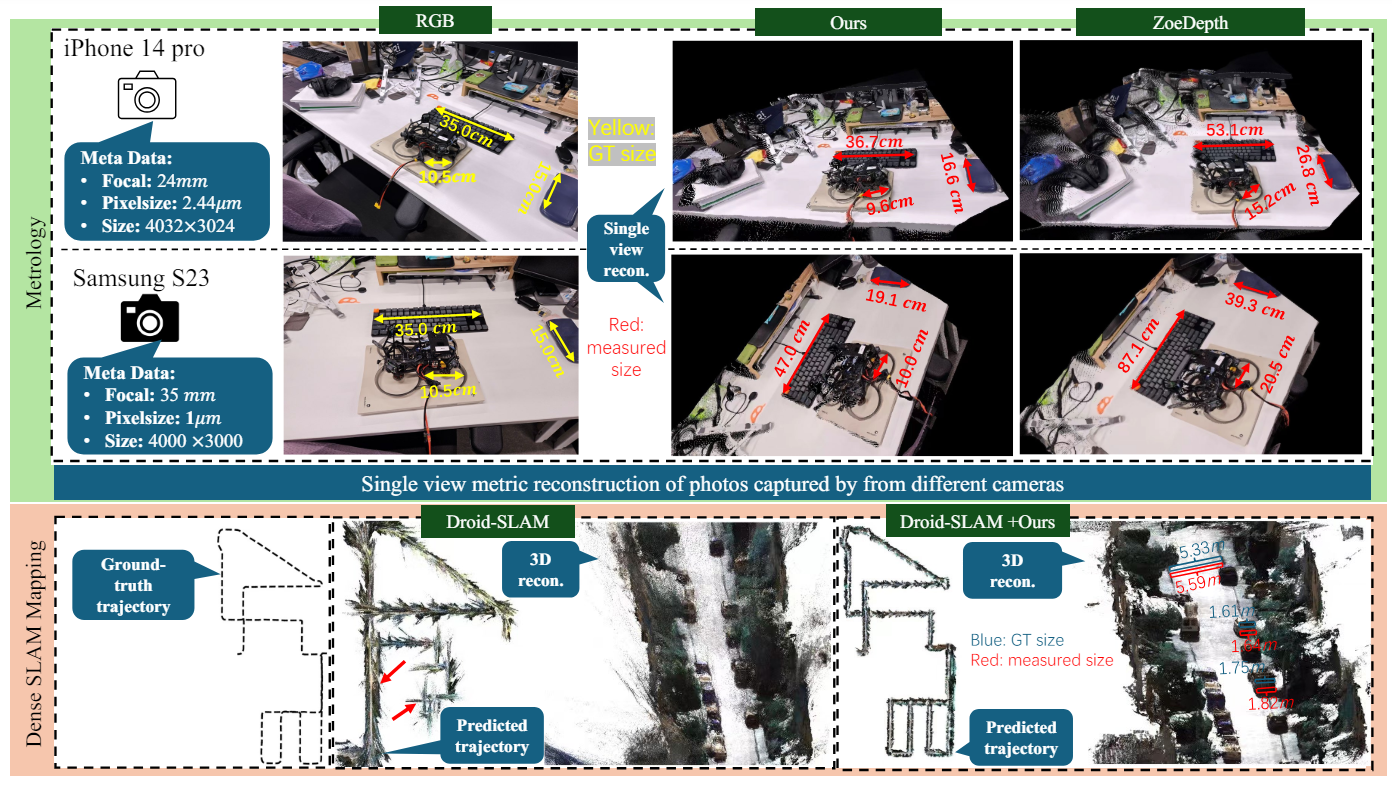
Metric3D is a strong and robust geometry foundation model for high-quality and zero-shot metric depth and surface normal estimation from a single image. It excels at solving in-the-wild scene reconstruction. It can directly help you measure the size of structures from a single image. Now it achieves SOTA performance on over 10 depth and normal benchmarks.
📝 Benchmarks
Metric Depth
Our models rank 1st on the routing KITTI and NYU benchmarks.
| Backbone | KITTI δ1 ↑ | KITTI δ2 ↑ | KITTI AbsRel ↓ | KITTI RMSE ↓ | KITTI RMS_log ↓ | NYU δ1 ↑ | NYU δ2 ↑ | NYU AbsRel ↓ | NYU RMSE ↓ | NYU log10 ↓ | |
|---|---|---|---|---|---|---|---|---|---|---|---|
| ZoeDepth | ViT-Large | 0.971 | 0.995 | 0.053 | 2.281 | 0.082 | 0.953 | 0.995 | 0.077 | 0.277 | 0.033 |
| ZeroDepth | ResNet-18 | 0.968 | 0.996 | 0.057 | 2.087 | 0.083 | 0.954 | 0.995 | 0.074 | 0.269 | 0.103 |
| IEBins | SwinT-Large | 0.978 | 0.998 | 0.050 | 2.011 | 0.075 | 0.936 | 0.992 | 0.087 | 0.314 | 0.031 |
| DepthAnything | ViT-Large | 0.982 | 0.998 | 0.046 | 1.985 | 0.069 | 0.984 | 0.998 | 0.056 | 0.206 | 0.024 |
| Ours | ViT-Large | 0.985 | 0.998 | 0.044 | 1.985 | 0.064 | 0.989 | 0.998 | 0.047 | 0.183 | 0.020 |
| Ours | ViT-giant2 | 0.989 | 0.998 | 0.039 | 1.766 | 0.060 | 0.987 | 0.997 | 0.045 | 0.187 | 0.015 |
Affine-invariant Depth
Even compared to recent affine-invariant depth methods (Marigold and Depth Anything), our metric-depth (and normal) models still show superior performance.
| #Data for Pretrain and Train | KITTI Absrel ↓ | KITTI δ1 ↑ | NYUv2 AbsRel ↓ | NYUv2 δ1 ↑ | DIODE-Full AbsRel ↓ | DIODE-Full δ1 ↑ | Eth3d AbsRel ↓ | Eth3d δ1 ↑ | |
|---|---|---|---|---|---|---|---|---|---|
| OmniData (v2, ViT-L) | 1.3M + 12.2M | 0.069 | 0.948 | 0.074 | 0.945 | 0.149 | 0.835 | 0.166 | 0.778 |
| MariGold (LDMv2) | 5B + 74K | 0.099 | 0.916 | 0.055 | 0.961 | 0.308 | 0.773 | 0.127 | 0.960 |
| DepthAnything (ViT-L) | 142M + 63M | 0.076 | 0.947 | 0.043 | 0.981 | 0.277 | 0.759 | 0.065 | 0.882 |
| Ours (ViT-L) | 142M + 16M | 0.042 | 0.979 | 0.042 | 0.980 | 0.141 | 0.882 | 0.042 | 0.987 |
| Ours (ViT-g) | 142M + 16M | 0.043 | 0.982 | 0.043 | 0.981 | 0.136 | 0.895 | 0.042 | 0.983 |
Surface Normal
Our models also show powerful performance on normal benchmarks.
| NYU 11.25° ↑ | NYU Mean ↓ | NYU RMS ↓ | ScanNet 11.25° ↑ | ScanNet Mean ↓ | ScanNet RMS ↓ | iBims 11.25° ↑ | iBims Mean ↓ | iBims RMS ↓ | |
|---|---|---|---|---|---|---|---|---|---|
| EESNU | 0.597 | 16.0 | 24.7 | 0.711 | 11.8 | 20.3 | 0.585 | 20.0 | - |
| IronDepth | - | - | - | - | - | - | 0.431 | 25.3 | 37.4 |
| PolyMax | 0.656 | 13.1 | 20.4 | - | - | - | - | - | - |
| Ours (ViT-L) | 0.688 | 12.0 | 19.2 | 0.760 | 9.9 | 16.4 | 0.694 | 19.4 | 34.9 |
| Ours (ViT-g) | 0.662 | 13.2 | 20.2 | 0.778 | 9.2 | 15.3 | 0.697 | 19.6 | 35.2 |
🌈 DEMOs
Zero-shot monocular metric depth & surface normal
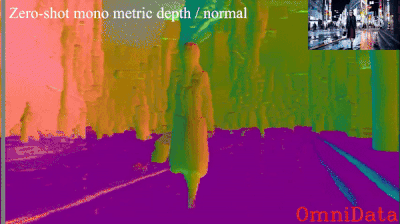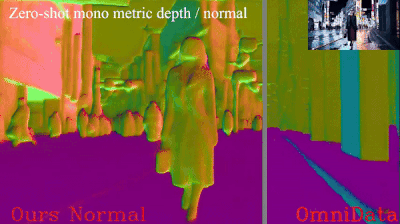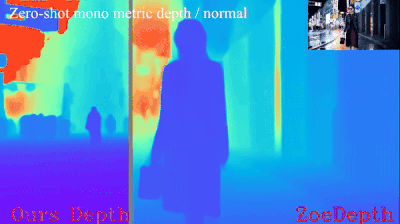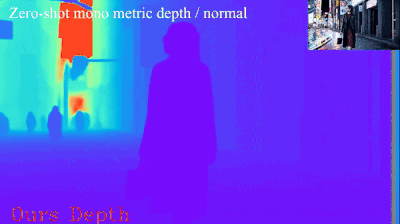
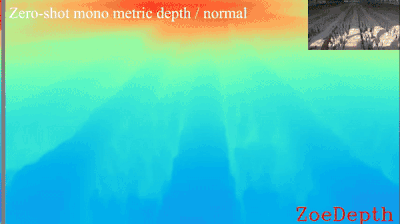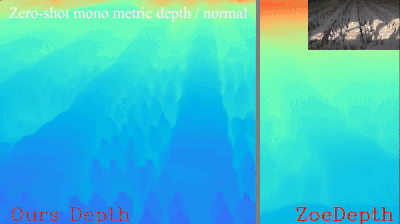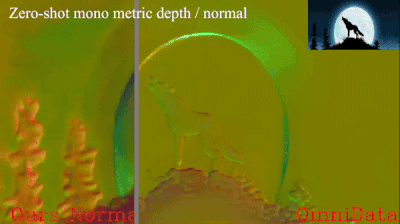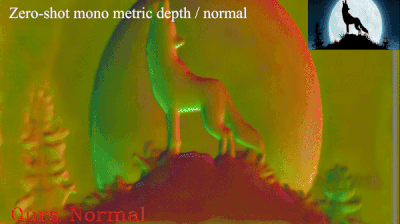
Zero-shot metric 3D recovery
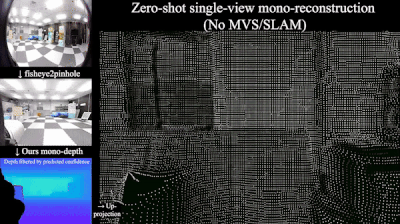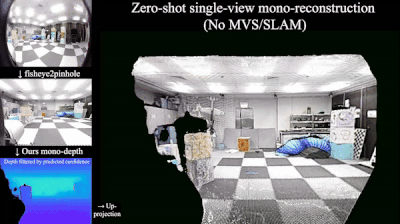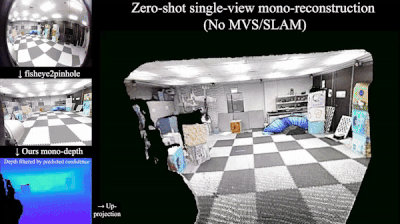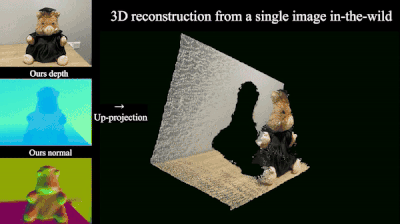
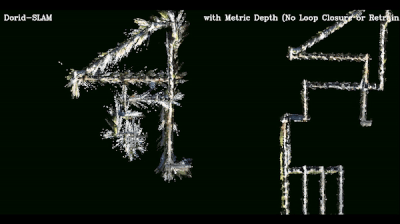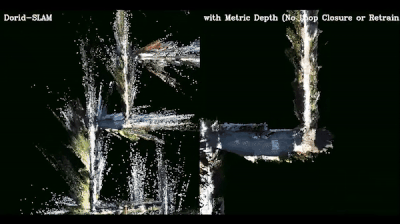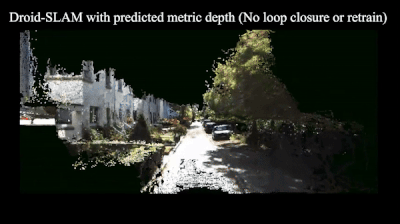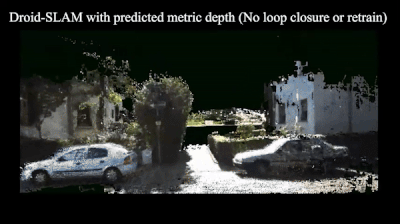
Improving monocular SLAM
//: # (| room |  |
 | [Download](https://drive.google.com/file/d/1P1izSegH2c4LUrXGiUksw037PVb0hjZr/view?usp=drive_link) |)
//: # (| Colosseum |  |
 | [Download](https://drive.google.com/file/d/1jJCXe5IpxBhHDr0TZtNZhjxKTRUz56Hg/view?usp=drive_link) |)
//: # (| chess |  |
 | [Download](https://drive.google.com/file/d/1oV_Foq25_p-tTDRTcyO2AzXEdFJQz-Wm/view?usp=drive_link) |)
//: # (  )
//: # (  )
🔨 Installation
One-line Installation
For the ViT models, use the following environment:
pip install -r requirements_v2.txt
For ConvNeXt-L, it is
pip install -r requirements_v1.txt
dataset annotation components
With off-the-shelf depth datasets, we need to generate json annotaions in compatible with this dataset, which is organized by:
dict(
	'files':list(
		dict(
			'rgb': 'data/kitti_demo/rgb/xxx.png',
			'depth': 'data/kitti_demo/depth/xxx.png',
			'depth_scale': 1000.0 # the depth scale of gt depth img.
			'cam_in': [fx, fy, cx, cy],
		),

		dict(
			...
		),

		...
	)
)
To generate such annotations, please refer to the "Inference" section.
configs
In mono/configs we provide different config setups.
Intrinsics of the canonical camera is set bellow:
    canonical_space = dict(
        img_size=(512, 960),
        focal_length=1000.0,
    ),
where cx and cy is set to be half of the image size.
Inference settings are defined as
    depth_range=(0, 1),
    depth_normalize=(0.3, 150),
    crop_size = (512, 1088),
where the images will be first resized as the crop_size and then fed into the model.
✈️ Training
Please refer to training/README.md. Now we provide complete json files for KITTI fine-tuning.
✈️ Inference
News: Improved ONNX support with dynamic shapes (Feature owned by @xenova. Appreciate for this outstanding contribution 🚩🚩🚩)
Now the onnx supports are availble for all three models with varying shapes. Refer to issue117 for more details.
Improved ONNX Checkpoints Available now
| Encoder | Decoder | Link | |
|---|---|---|---|
| v2-S-ONNX | DINO2reg-ViT-Small | RAFT-4iter | Download 🤗 |
| v2-L-ONNX | DINO2reg-ViT-Large | RAFT-8iter | Download 🤗 |
| v2-g-ONNX | DINO2reg-ViT-giant2 | RAFT-8iter | Download 🤗 |
One additional reminder for using these onnx models is reported by @norbertlink.
News: Pytorch Hub is supported
Now you can use Metric3D via Pytorch Hub with just few lines of code:
import torch
model = torch.hub.load('yvanyin/metric3d', 'metric3d_vit_small', pretrain=True)
pred_depth, confidence, output_dict = model.inference({'input': rgb})
pred_normal = output_dict['prediction_normal'][:, :3, :, :] # only available for Metric3Dv2 i.e., ViT models
normal_confidence = output_dict['prediction_normal'][:, 3, :, :] # see https://arxiv.org/abs/2109.09881 for details
Supported models: metric3d_convnext_tiny, metric3d_convnext_large, metric3d_vit_small, metric3d_vit_large, metric3d_vit_giant2.
We also provided a minimal working example in hubconf.py, which hopefully makes everything clearer.
News: ONNX Exportation and Inference are supported
We also provided a flexible working example in metric3d_onnx_export.py to export the Pytorch Hub model to ONNX format. We could test with the following commands:
# Export the model to ONNX model
python3 onnx/metric_3d_onnx_export.py metric3d_vit_small # metric3d_vit_large/metric3d_convnext_large

# Test the inference of the ONNX model
python3 onnx/test_onnx.py metric3d_vit_small.onnx
ros2_vision_inference provides a Python example, showcasing a pipeline from image to point clouds and integrated into ROS2 systems.
Download Checkpoint
| Encoder | Decoder | Link | |
|---|---|---|---|
| v1-T | ConvNeXt-Tiny | Hourglass-Decoder | Download 🤗 |
| v1-L | ConvNeXt-Large | Hourglass-Decoder | Download |
| v2-S | DINO2reg-ViT-Small | RAFT-4iter | Download |
| v2-L | DINO2reg-ViT-Large | RAFT-8iter | Download |
| v2-g | DINO2reg-ViT-giant2 | RAFT-8iter | Download 🤗 |
Dataset Mode
- put the trained ckpt file
model.pthinweight/. - generate data annotation by following the code
data/gene_annos_kitti_demo.py, which includes 'rgb', (optional) 'intrinsic', (optional) 'depth', (optional) 'depth_scale'. - change the 'test_data_path' in
test_*.shto the*.jsonpath. - run
source test_kitti.shorsource test_nyu.sh.
In-the-Wild Mode
- put the trained ckpt file
model.pthinweight/. - change the 'test_data_path' in
test.shto the image folder path. - run
source test_vit.shfor transformers andsource test.shfor convnets. As no intrinsics are provided, we provided by default 9 settings of focal length.
Metric3D and Droid-Slam
If you are interested in combining metric3D and monocular visual slam system to achieve the metric slam, you can refer to this repo.
❓ Q & A
Q1: Why depth maps look good but pointclouds are distorted?
Because the focal length is not properly set! Please find a proper focal length by modifying codes here yourself.
Q2: Why the point clouds are too slow to be generated?
Because the images are too large! Use smaller ones instead.
Q3: Why predicted depth maps are not satisfactory?
First be sure all black padding regions at image boundaries are cropped out. Then please try again. Besides, metric 3D is not almighty. Some objects (chandeliers, drones...) / camera views (aerial view, bev...) do not occur frequently in the training datasets. We will going deeper into this and release more powerful solutions.
📧 Citation
If you use this toolbox in your research or wish to refer to the baseline results published here, please use the following BibTeX entries:
@misc{Metric3D,
  author =       {Yin, Wei and Hu, Mu},
  title =        {OpenMetric3D: An Open Toolbox for Monocular Depth Estimation},
  howpublished = {\url{https://github.com/YvanYin/Metric3D}},
  year =         {2024}
}
Also please cite our papers if this help your research.
@article{hu2024metric3dv2,
  title={Metric3d v2: A versatile monocular geometric foundation model for zero-shot metric depth and surface normal estimation},
  author={Hu, Mu and Yin, Wei and Zhang, Chi and Cai, Zhipeng and Long, Xiaoxiao and Chen, Hao and Wang, Kaixuan and Yu, Gang and Shen, Chunhua and Shen, Shaojie},
  journal={IEEE Transactions on Pattern Analysis and Machine Intelligence},
  year={2024},
  publisher={IEEE}
}
@article{yin2023metric,
  title={Metric3D: Towards Zero-shot Metric 3D Prediction from A Single Image},
  author={Wei Yin, Chi Zhang, Hao Chen, Zhipeng Cai, Gang Yu, Kaixuan Wang, Xiaozhi Chen, Chunhua Shen},
  booktitle={ICCV},
  year={2023}
}
License and Contact
The Metric 3D code is under a 2-clause BSD License. For further commercial inquiries, please contact Dr. Wei Yin [yvanwy@outlook.com] and Mr. Mu Hu [mhuam@connect.ust.hk].