Clean, Robust, and Unified PyTorch implementation of popular DRL Algorithms
0.Star History
1.Dependencies
This repository uses the following python dependencies unless explicitly stated:
gymnasium==0.29.1
numpy==1.26.1
pytorch==2.1.0

python==3.11.5
2.How to use my code
Enter the folder of the algorithm that you want to use, and run the main.py to train from scratch:
python main.py
For more details, please check the README.md file in the corresponding algorithm folder.
3. Separate links of the code
- 1.Q-learning
- 2.1Duel Double DQN
- 2.2Noisy Duel DDQN on Atari Game
- 2.3Prioritized Experience Replay(PER) DQN/DDQN
- 2.4Categorical DQN (C51)
- 2.5NoisyNet DQN
- 3.1Proximal Policy Optimization(PPO) for Discrete Action Space
- 3.2Proximal Policy Optimization(PPO) for Continuous Action Space
- 4.1Deep Deternimistic Policy Gradient(DDPG)
- 4.2Twin Delayed Deep Deterministic Policy Gradient(TD3)
- 5.1Soft Actor Critic(SAC) for Discrete Action Space
- 5.2Soft Actor Critic(SAC) for Continuous Action Space
- 6.Actor-Sharer-Learner(ASL)
4. Recommended Resources for DRL
4.1 Simulation Environments:
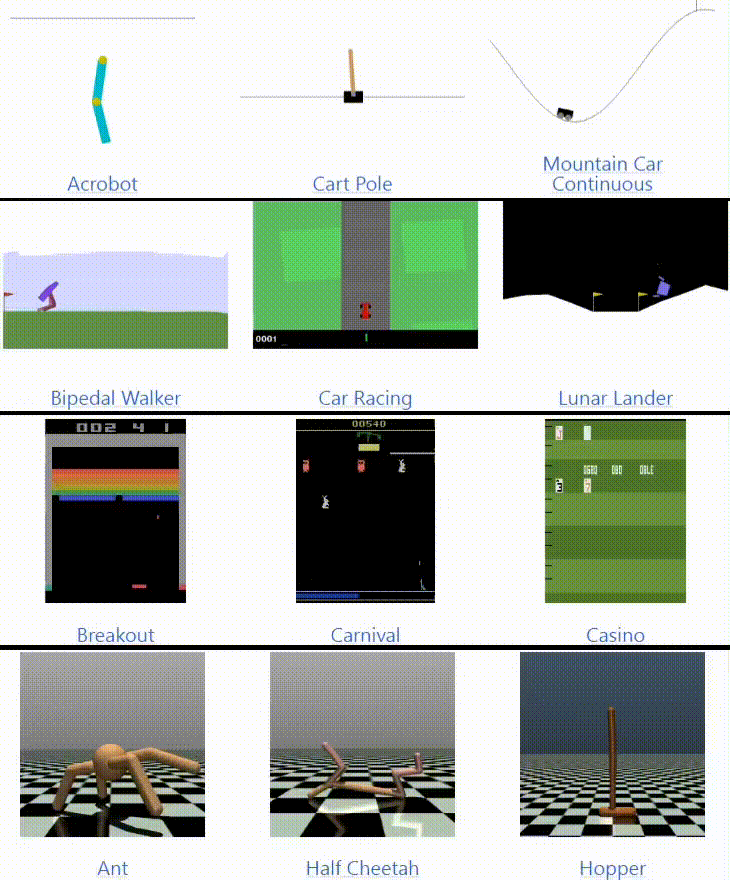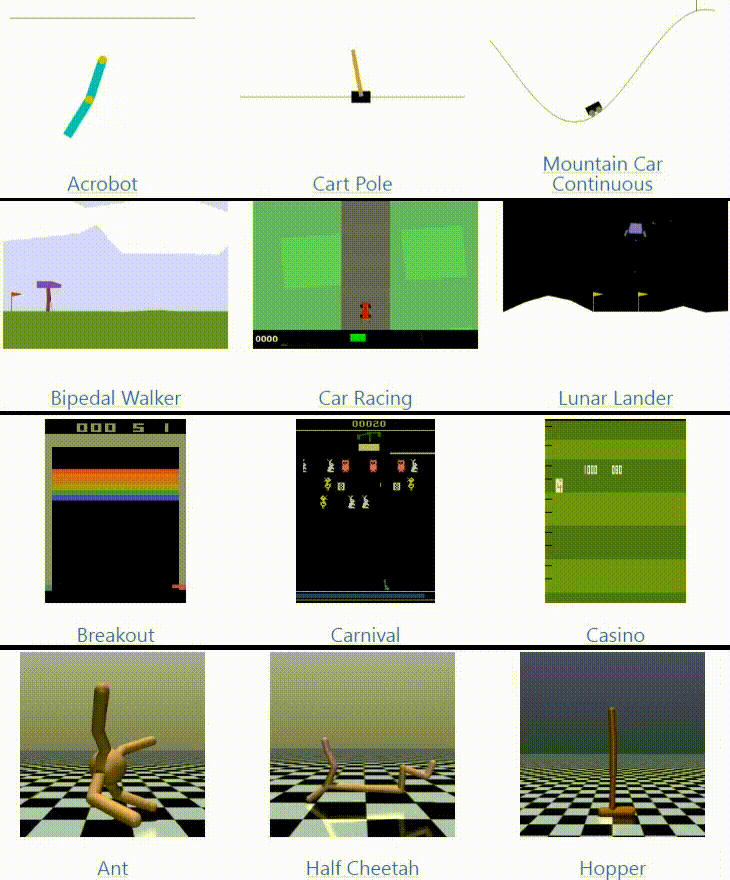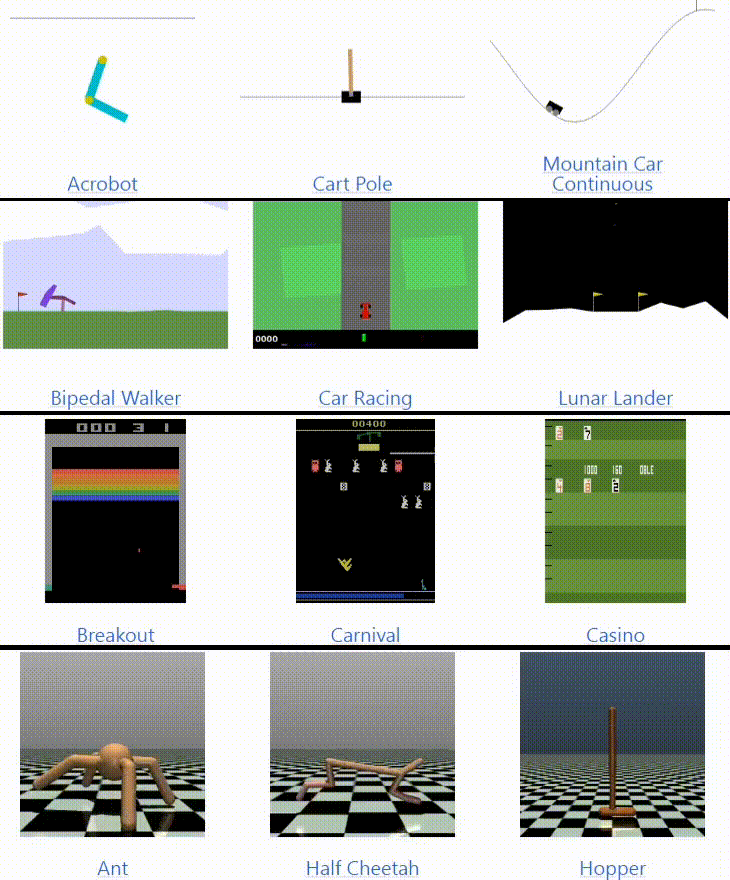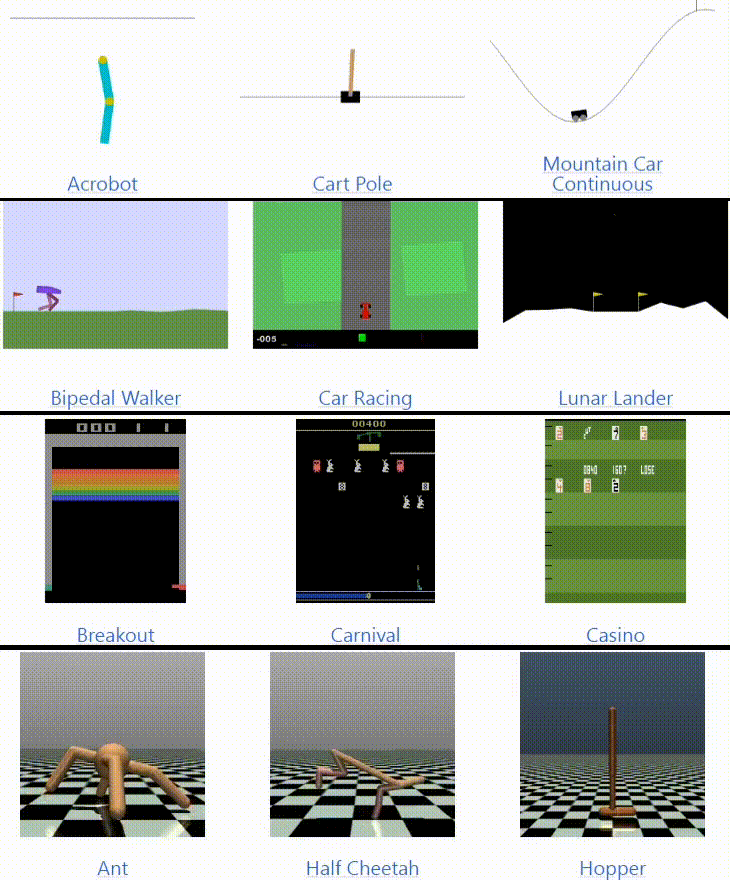
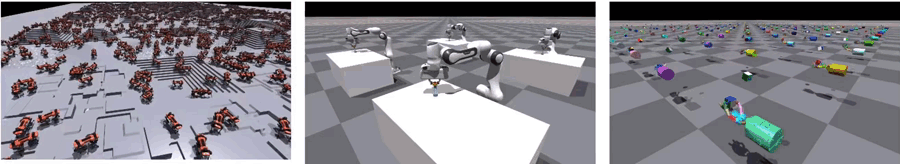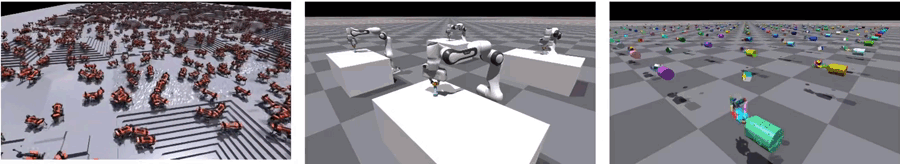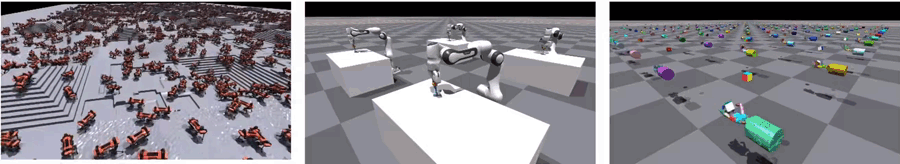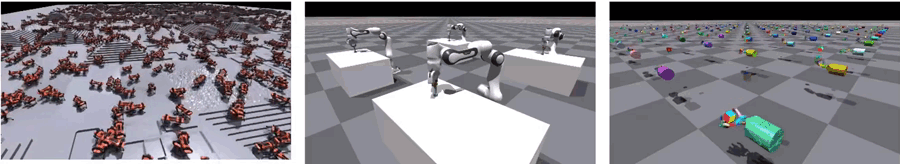
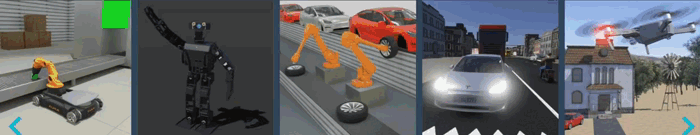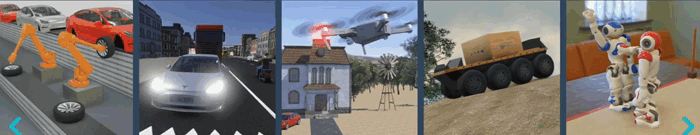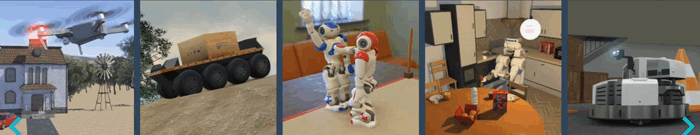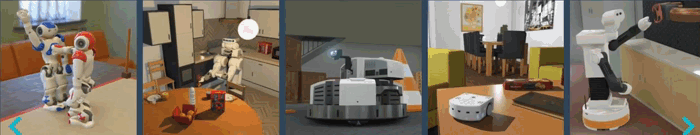
- Isaac Sim (NVIDIA’s physics simulation environment; GPU accelerated; Superfast):
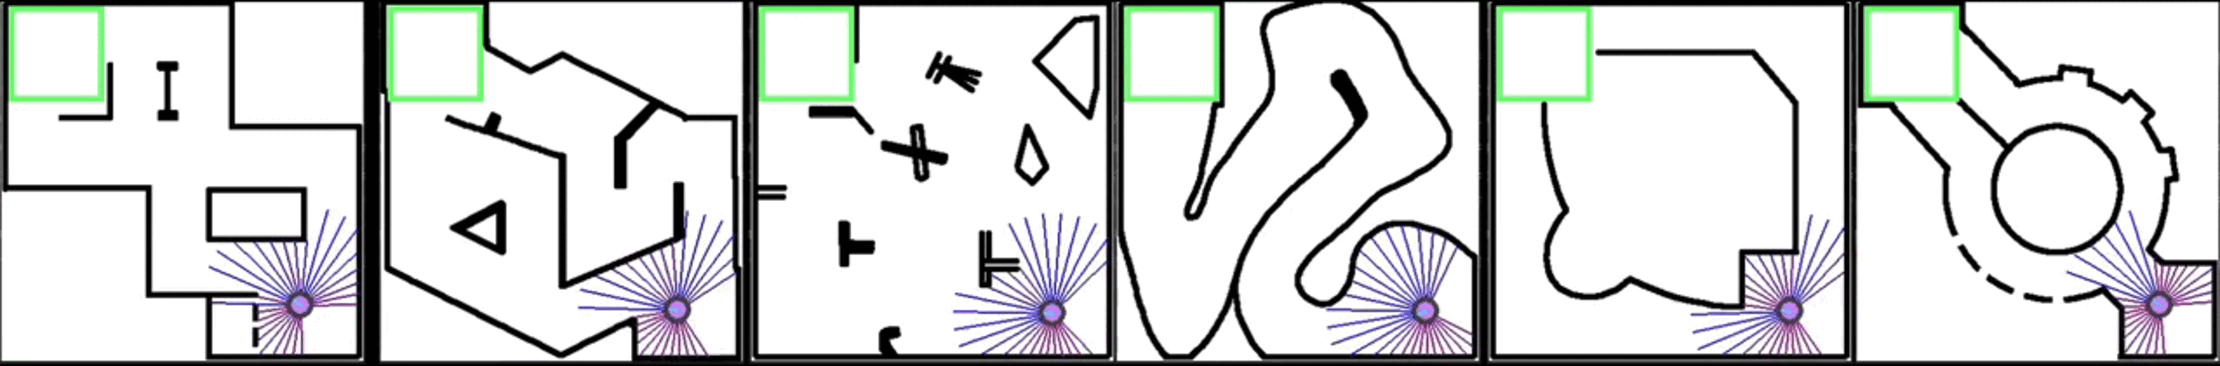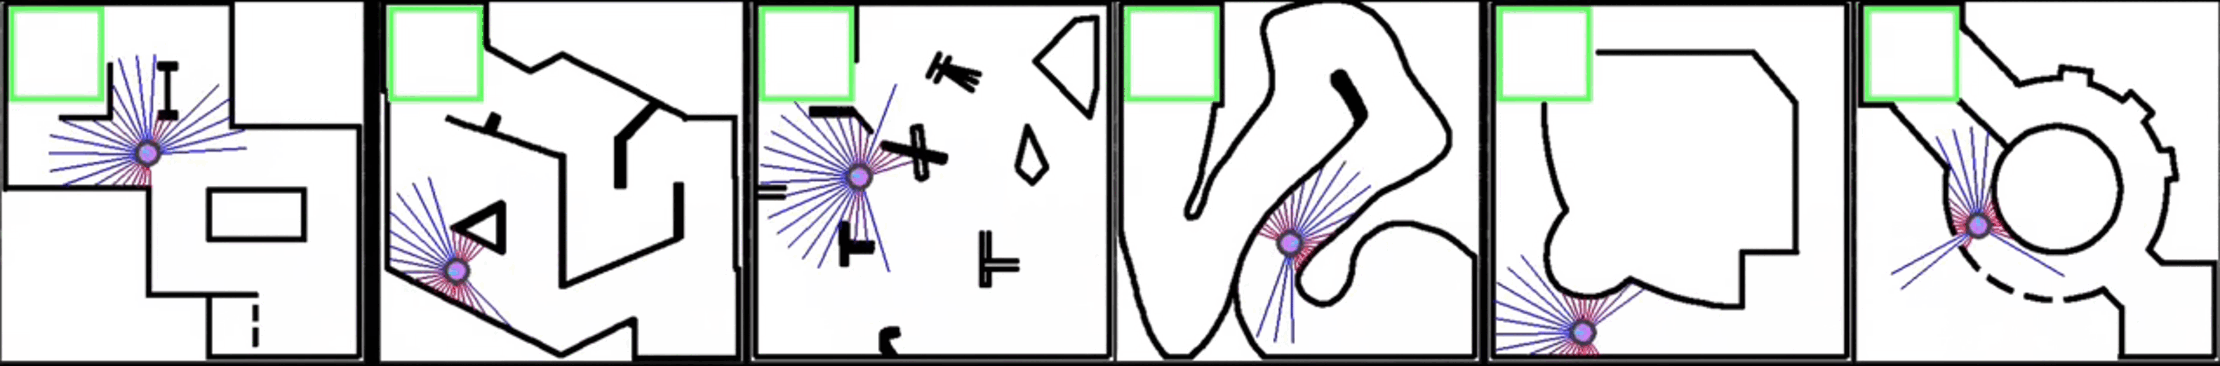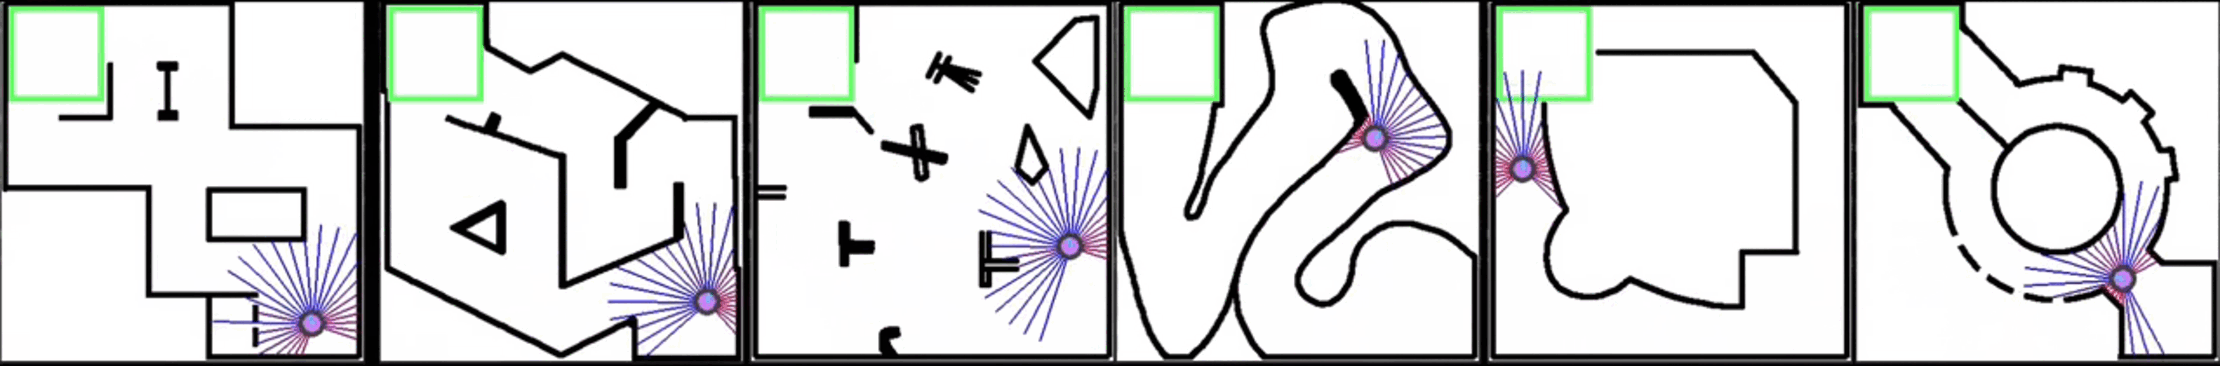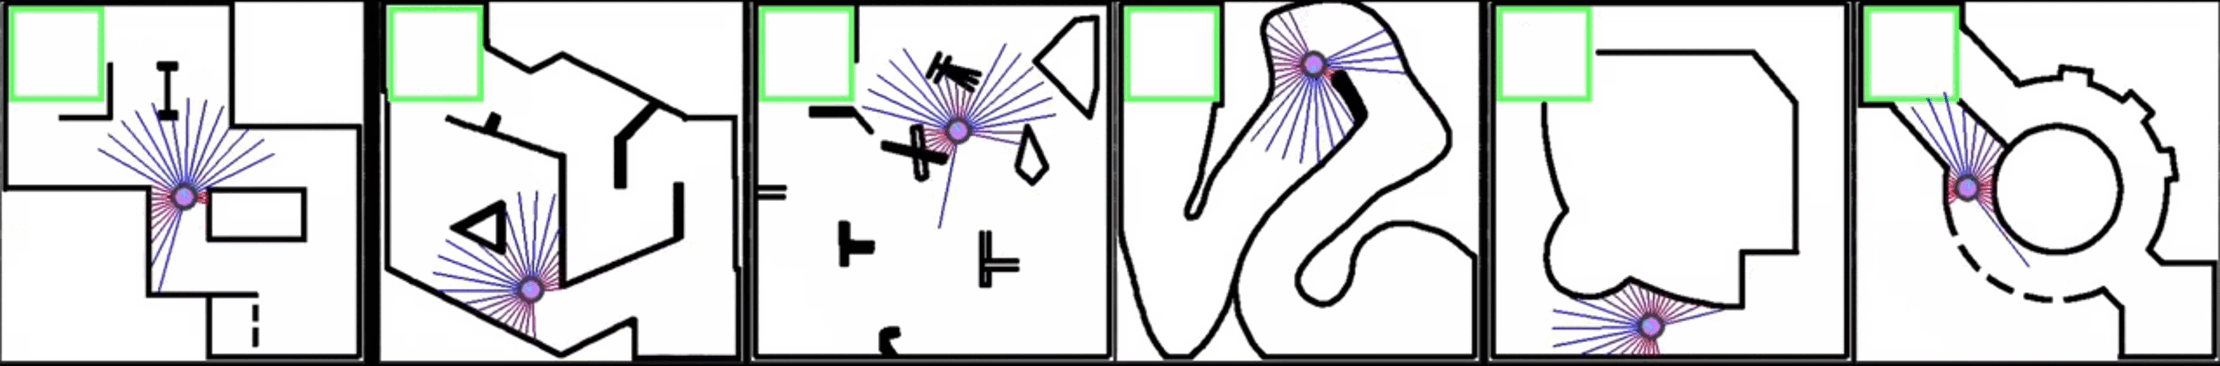
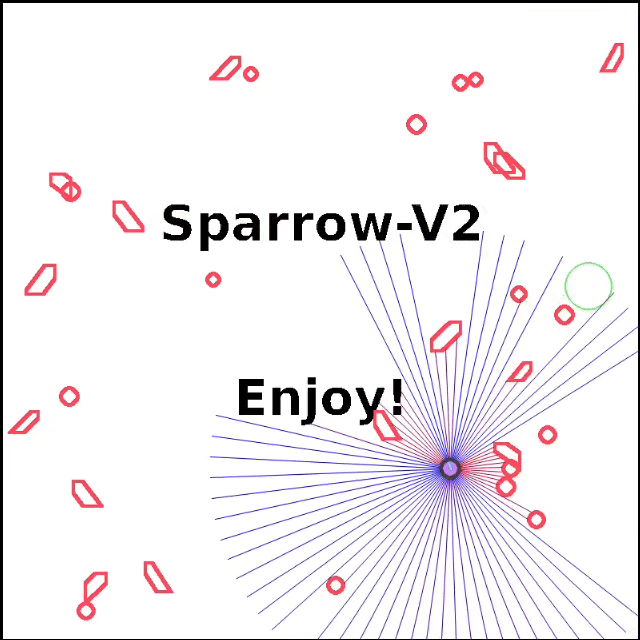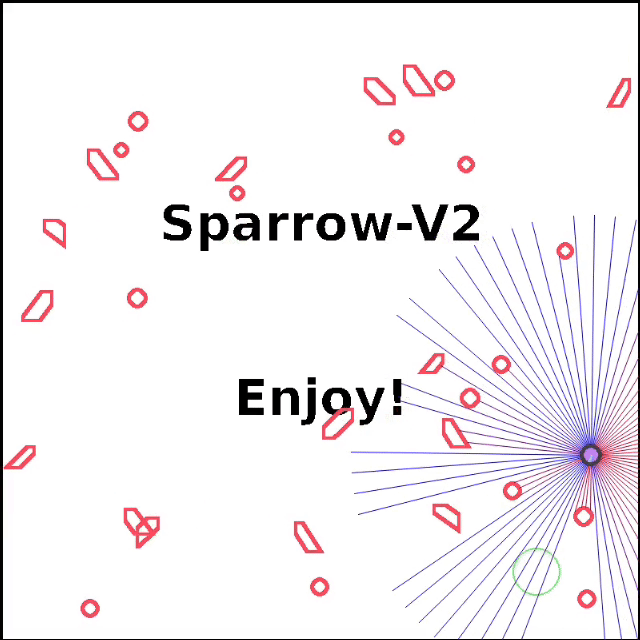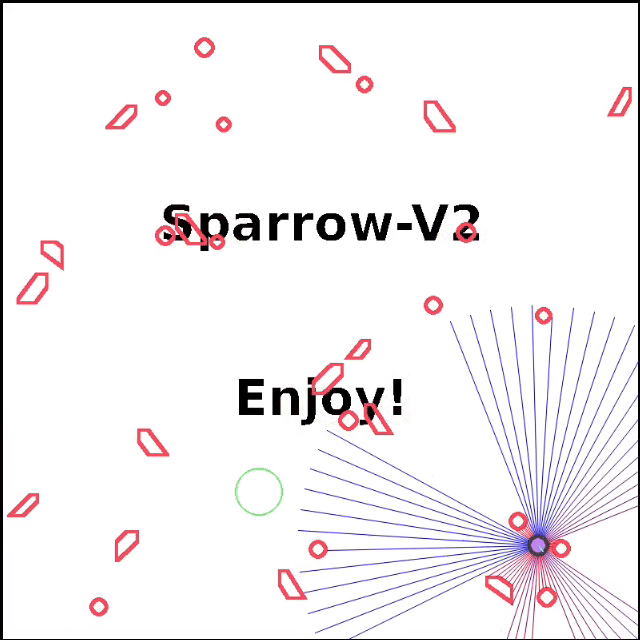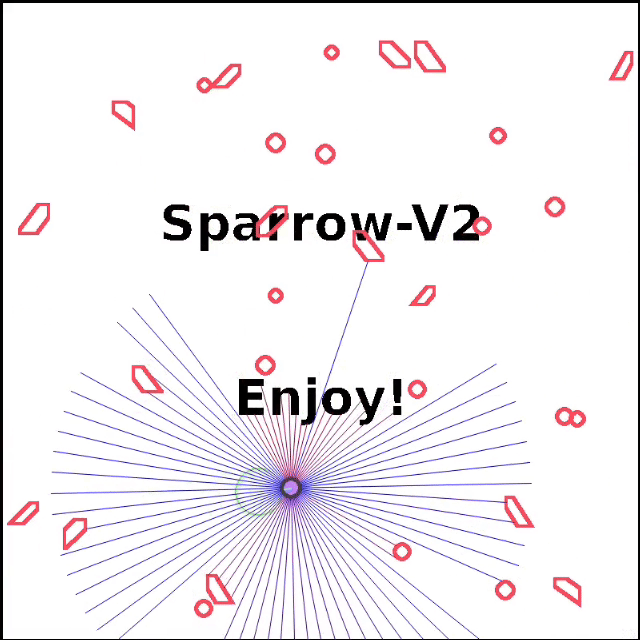
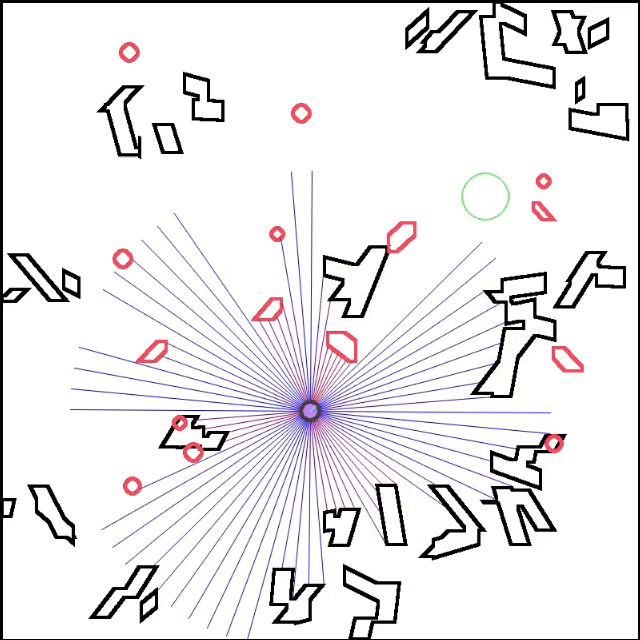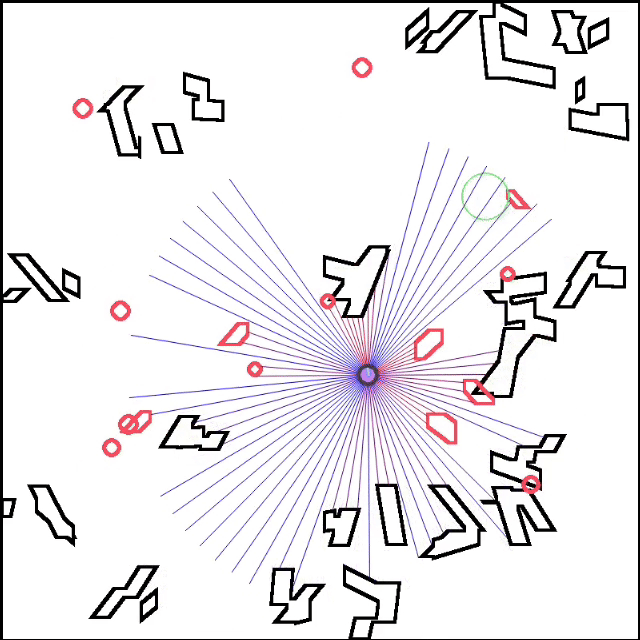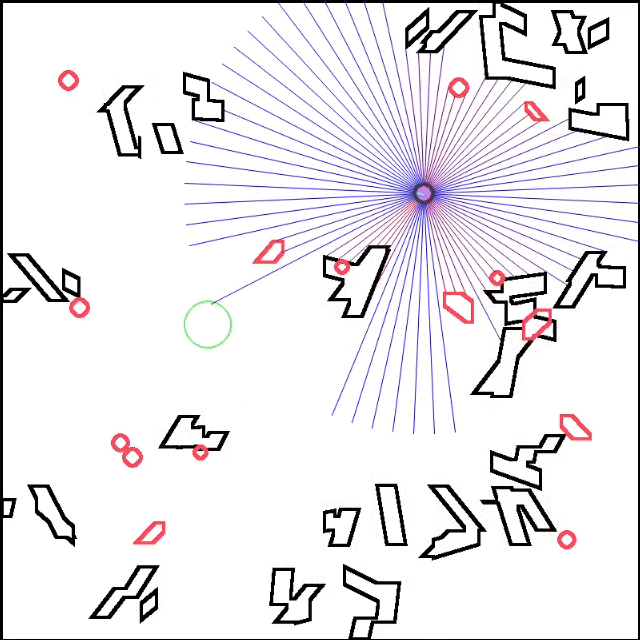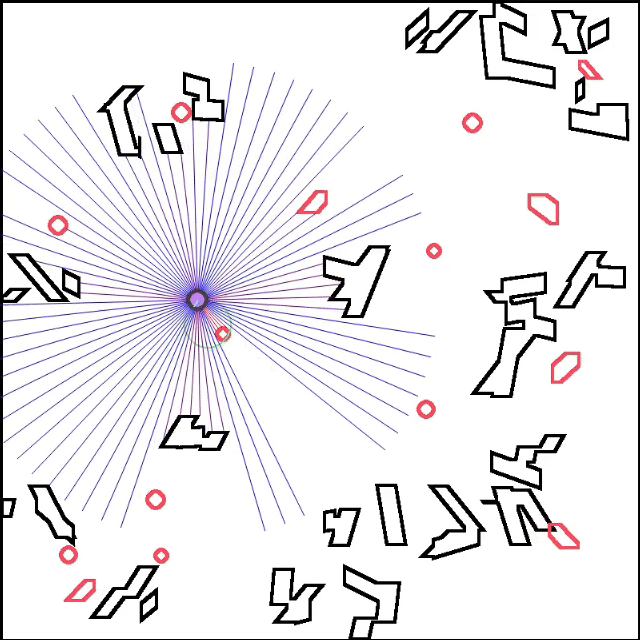
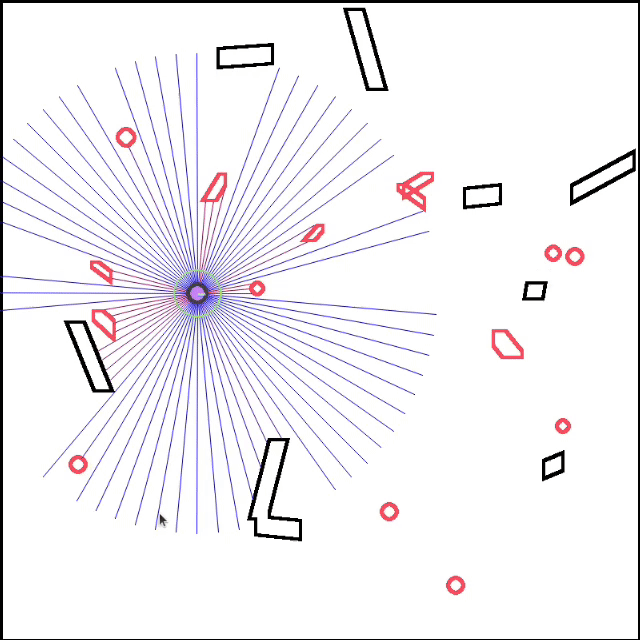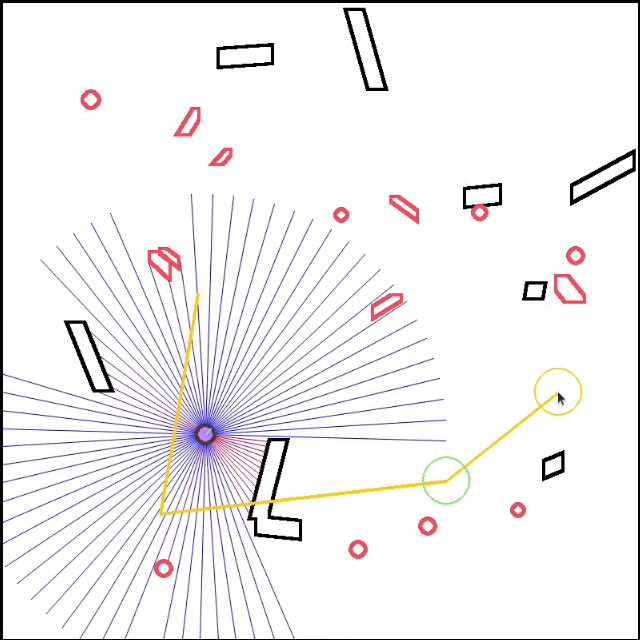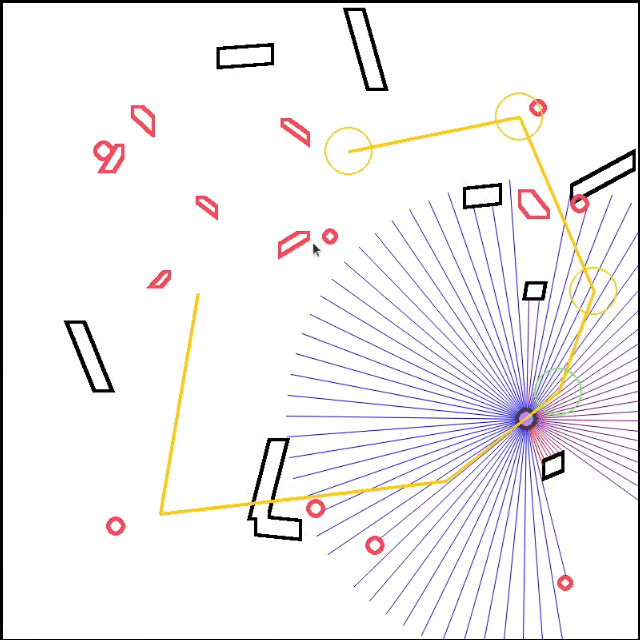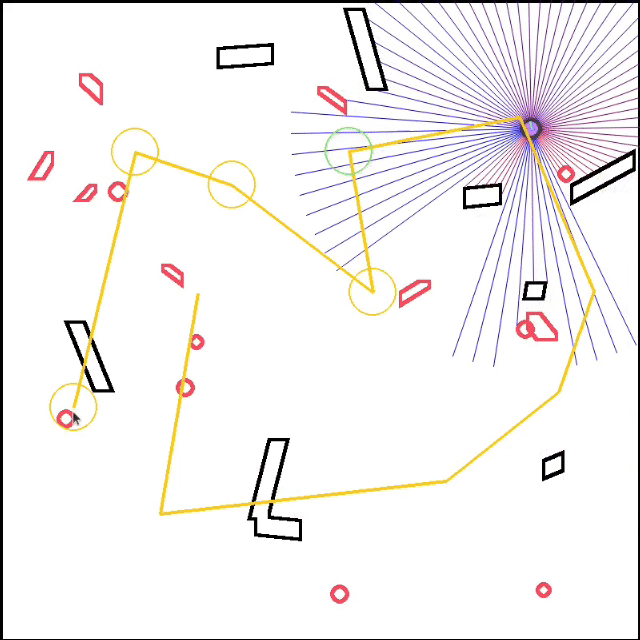
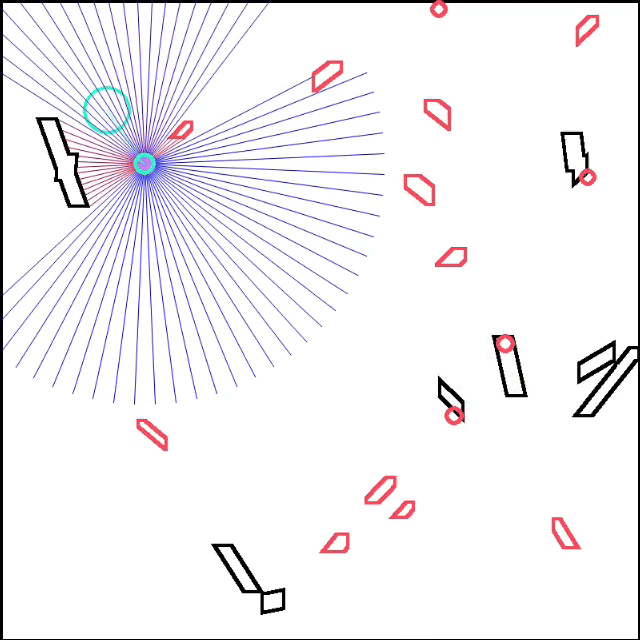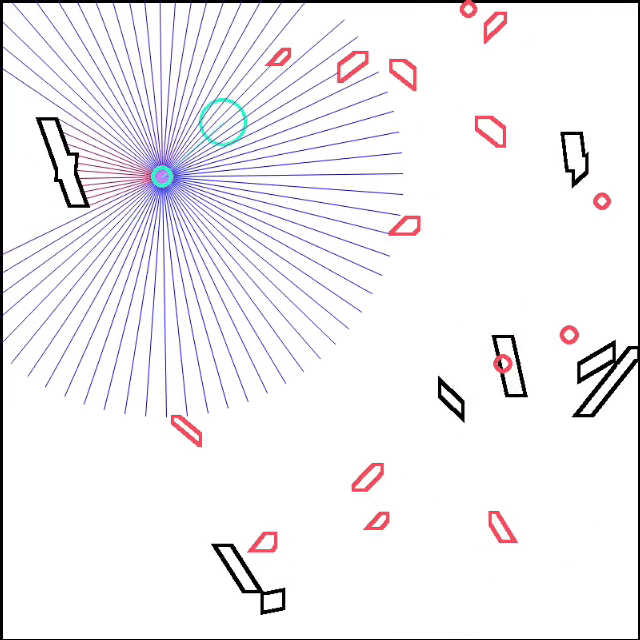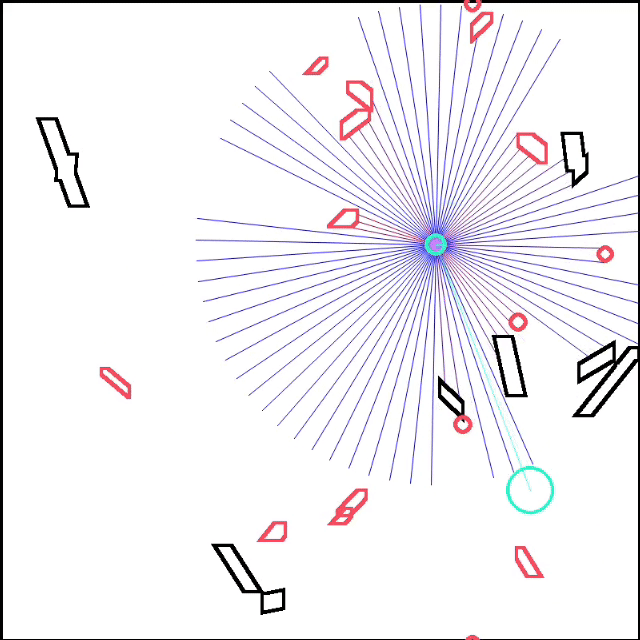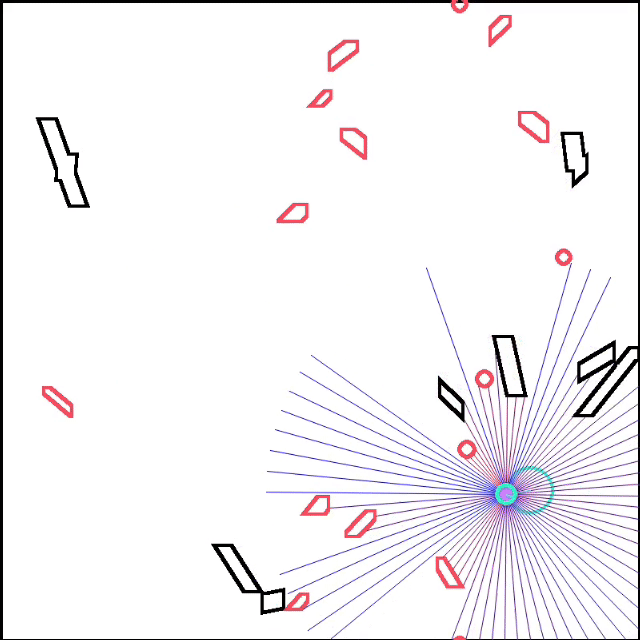
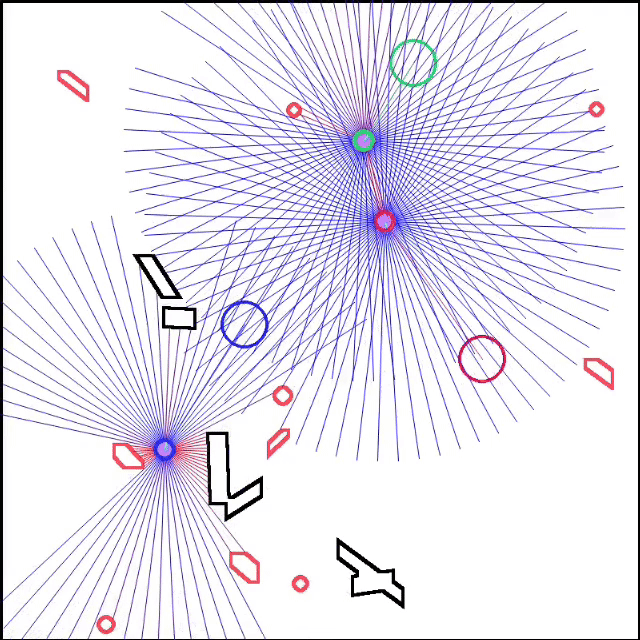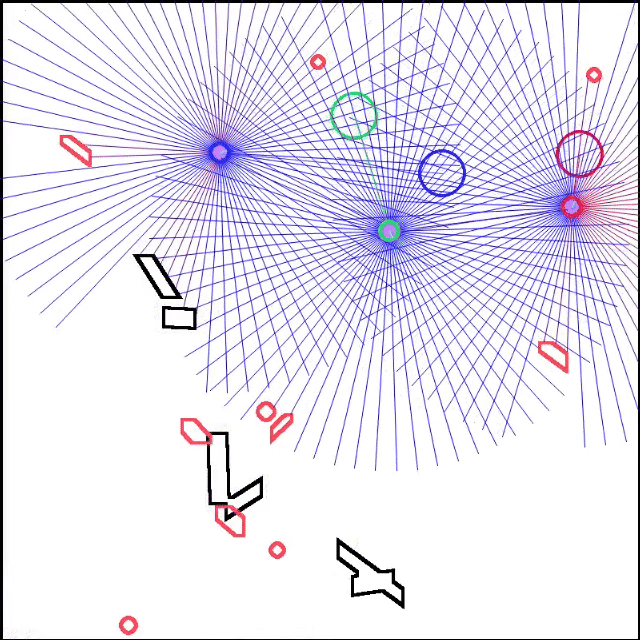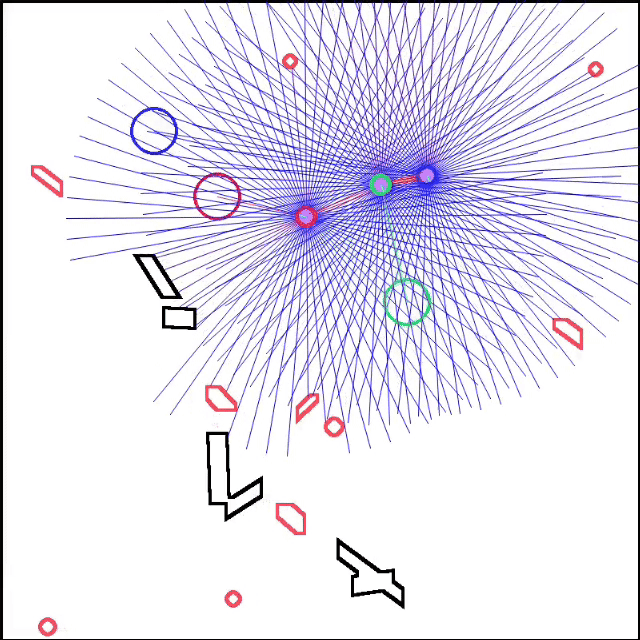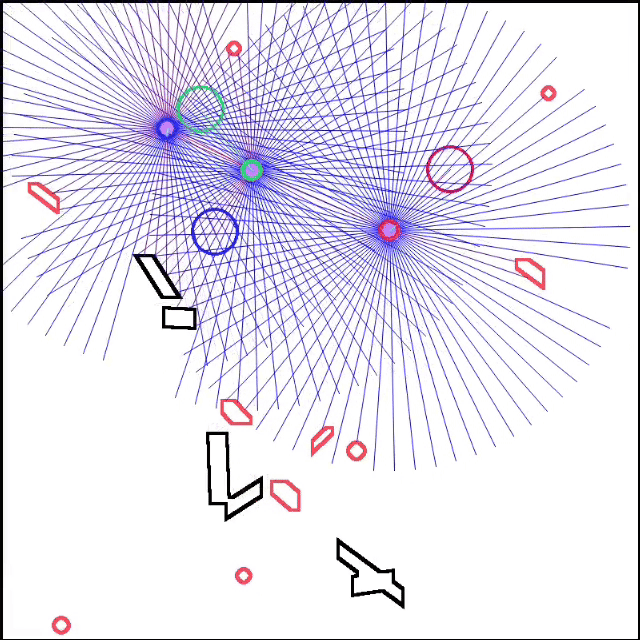
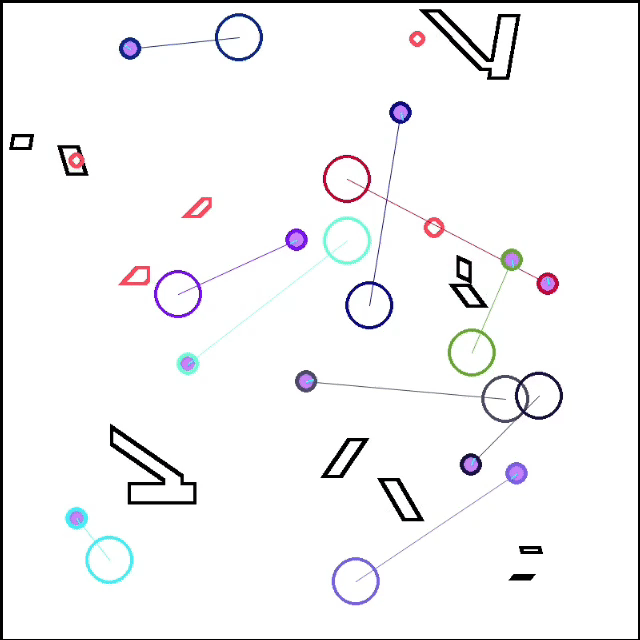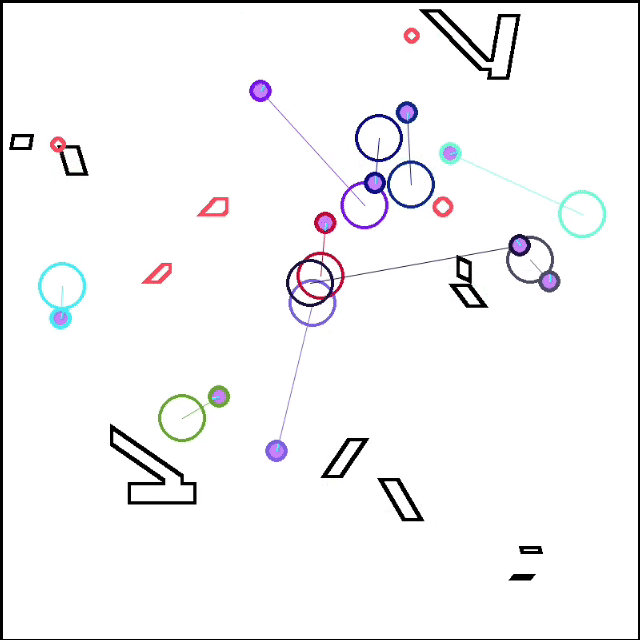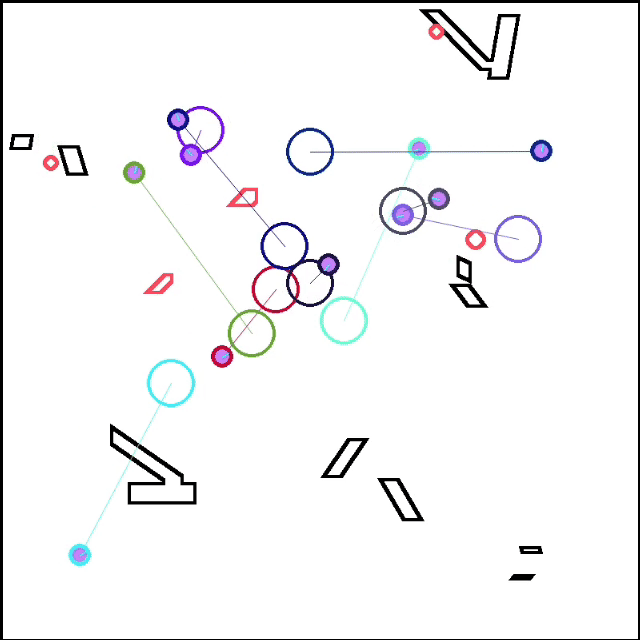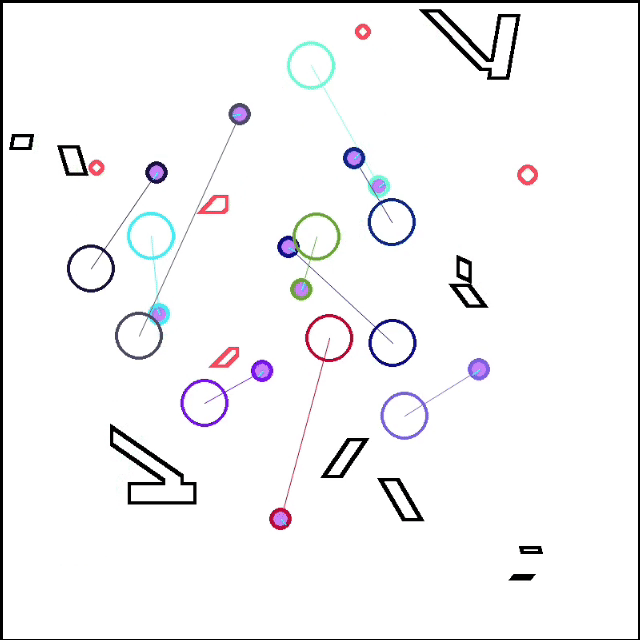
- Sparrow (Light Weight Simulator for Mobile Robot; DRL friendly):
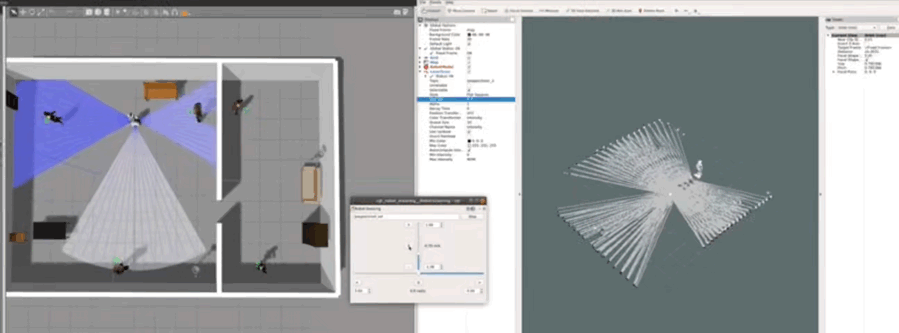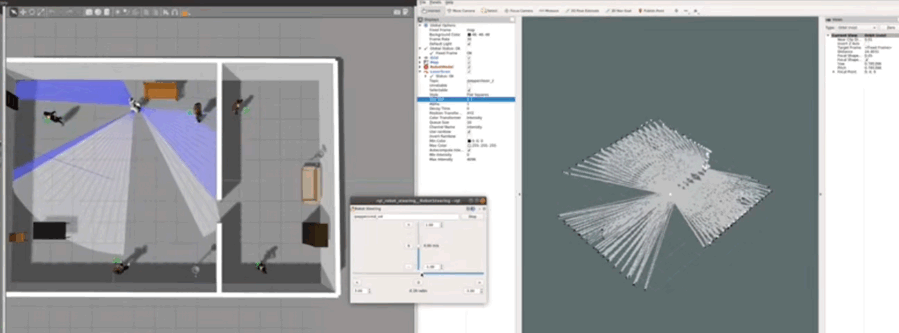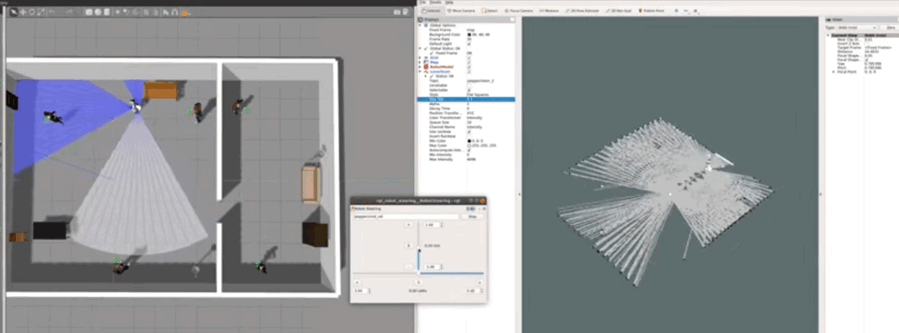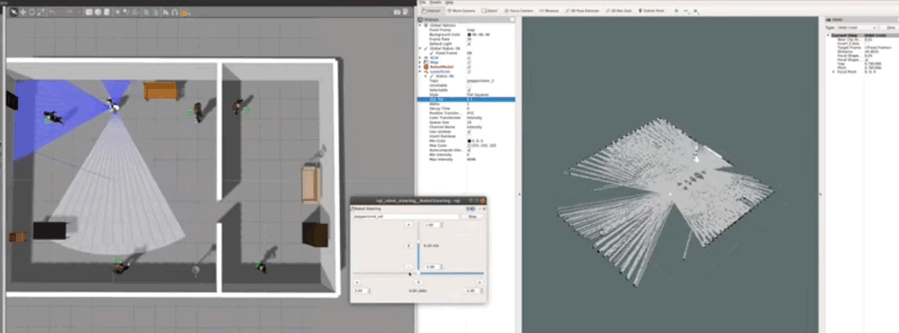
- ROS (Popular & Comprehensive physical simulator for robots; Heavy and Slow):
- Webots (Popular physical simulator for robots; Faster than ROS; Less realistic):
- Envpool (Fast Vectorized Env)
- Other Popular Envs
4.2 Books:
- 《Reinforcement learning: An introduction》--Richard S. Sutton
- 《深度学习入门:基于Python的理论与实现》--斋藤康毅
4.3 Online Courses:
- RL Courses(bilibili)--李宏毅(Hongyi Li)
- RL Courses(Youtube)--李宏毅(Hongyi Li)
- UCL Course on RL--David Silver
- 动手强化学习--上海交通大学
- DRL Courses--Shusen Wang
4.4 Blogs:
- OpenAI Spinning Up
- Policy Gradient Theorem --Cangxi
- Policy Gradient Algorithms --Lilian
- Theorem of PPO
- The 37 Implementation Details of Proximal Policy Optimization
- Prioritized Experience Replay
- Soft Actor Critic
- A (Long) Peek into Reinforcement Learning --Lilian
- Introduction to TD3
5. Important Papers
NoisyNet DQN: Fortunato M, Azar M G, Piot B, et al. Noisy networks for exploration[J]. arXiv preprint arXiv:1706.10295, 2017.
ColorDynamic: Generalizable, Scalable, Real-time, End-to-end Local Planner for Unstructured and Dynamic Environments
6. Citation
@misc{DRL-Pytorch,
  author = {Jinghao Xin},
  title = {DRL-Pytorch},
  year = {2022},
  publisher = {GitHub},
  journal = {GitHub Repository},
  howpublished = {\url{https://github.com/XinJingHao/DRL-Pytorch}},
}
7. Training Curves of my Code:
Q-learning:

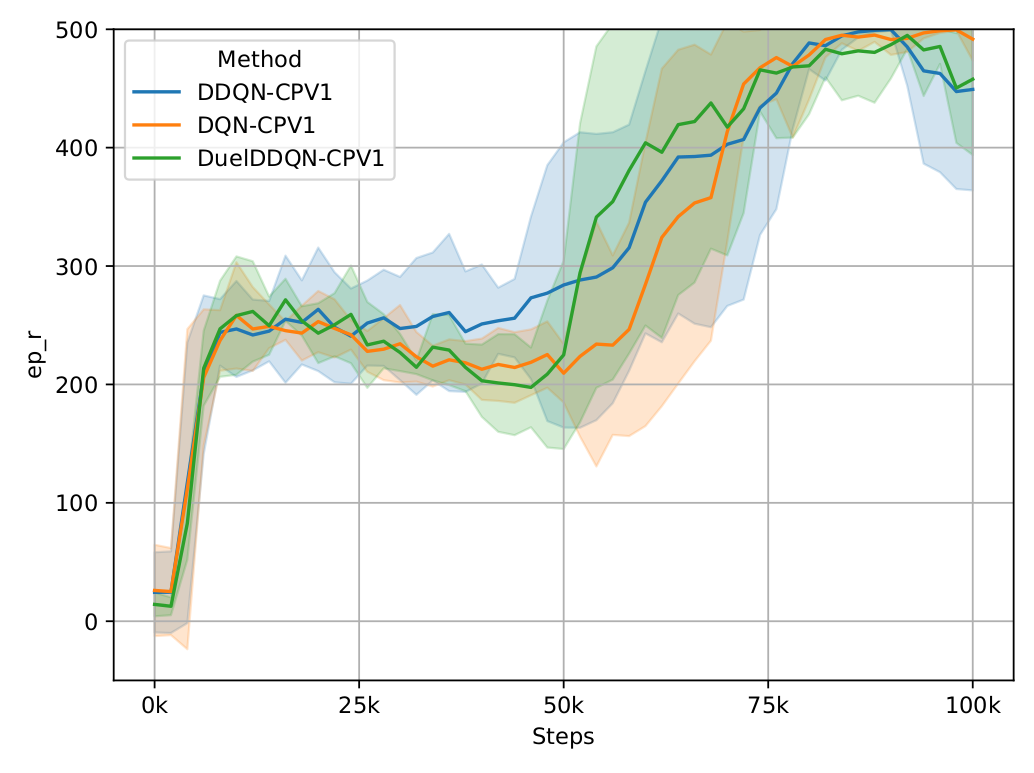
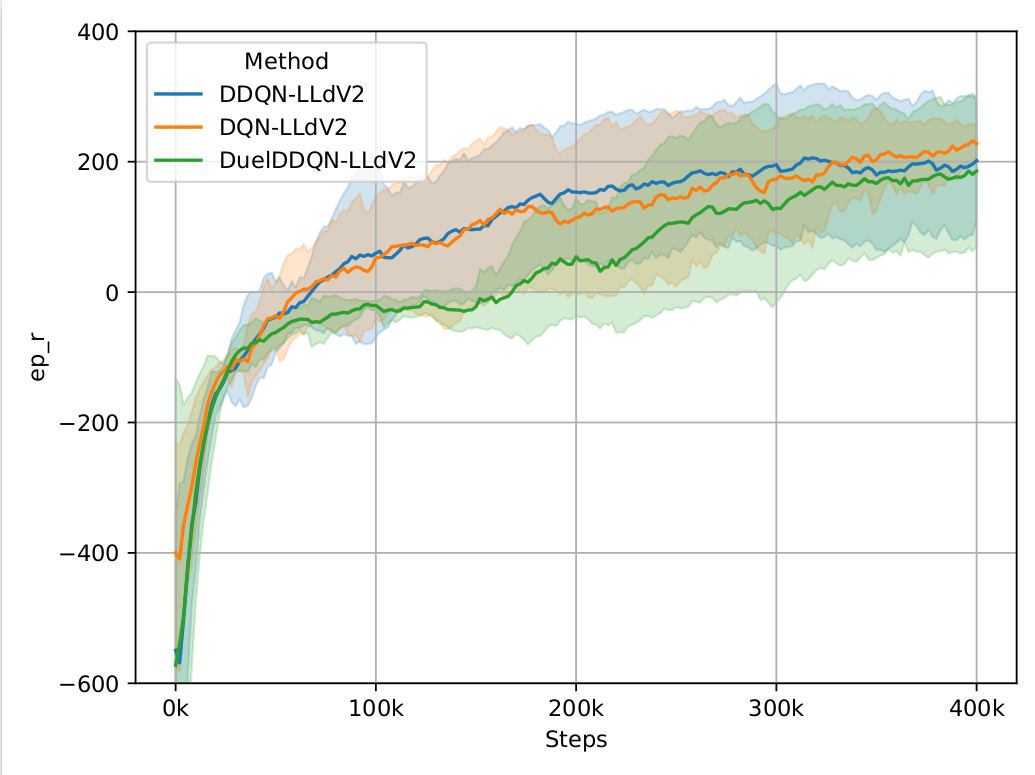
Duel Double DQN:
| CartPole | LunarLander |
|---|---|
 |
 |
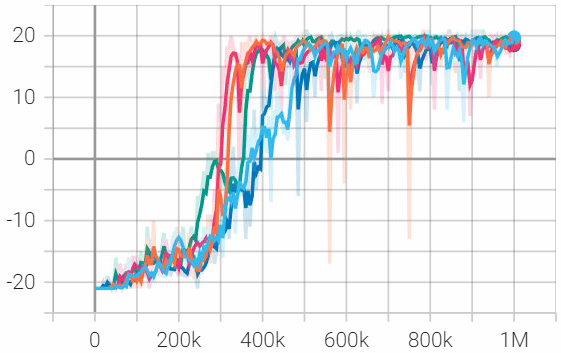
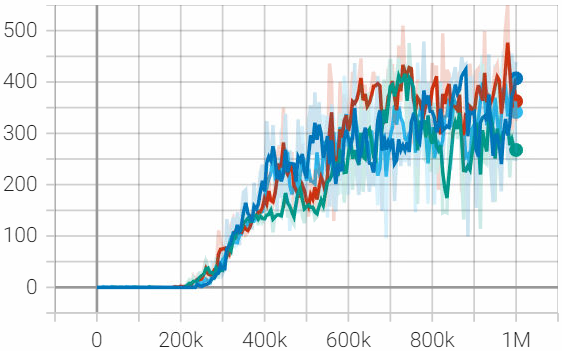
Noisy Duel DDQN on Atari Game:
| Pong | Enduro |
|---|---|
 |
 |
Prioritized DQN/DDQN:
| CartPole | LunarLander |
|---|---|
 |
 |
Categorical DQN:
| CartPole | LunarLander |
|---|---|
 |
 |
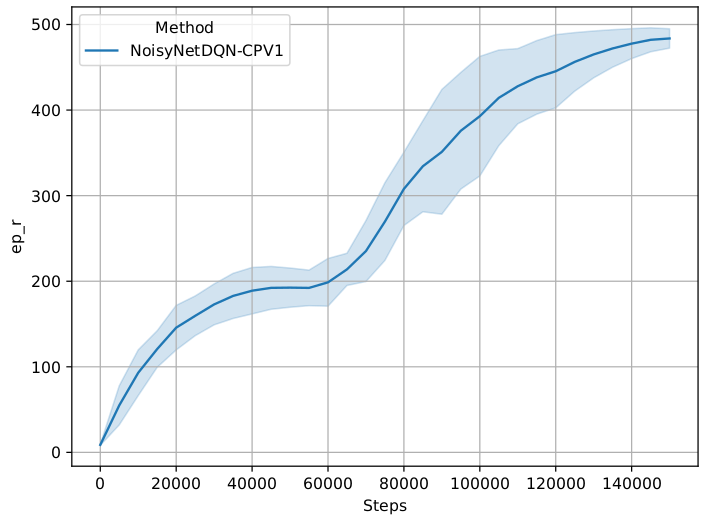
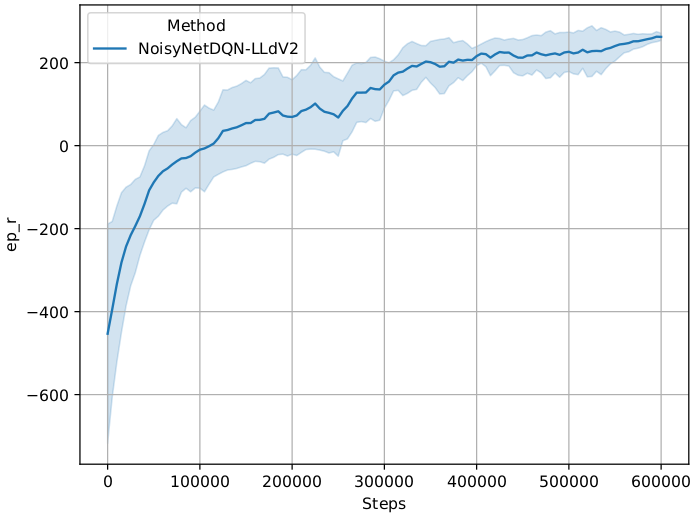
NoisyNet DQN:
| CartPole | LunarLander |
|---|---|
 |
 |
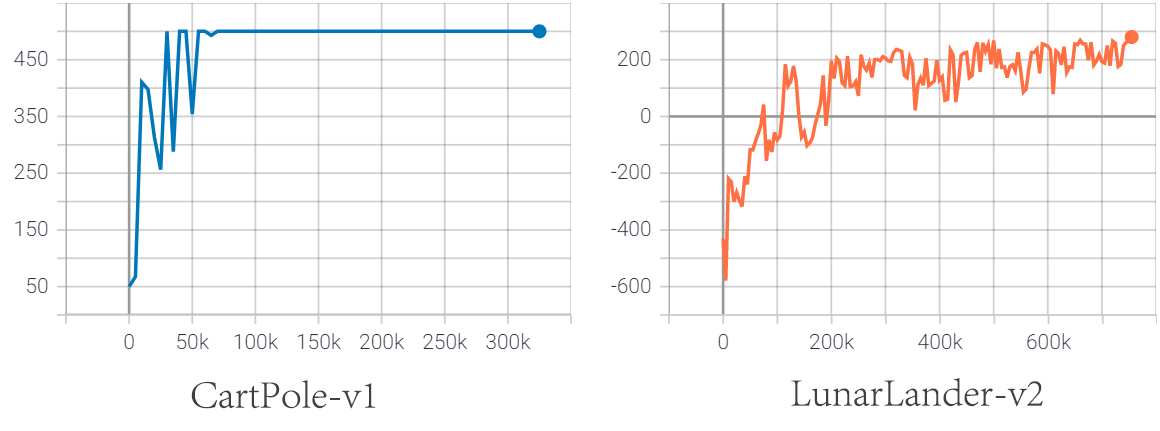
PPO Discrete:
PPO Continuous:
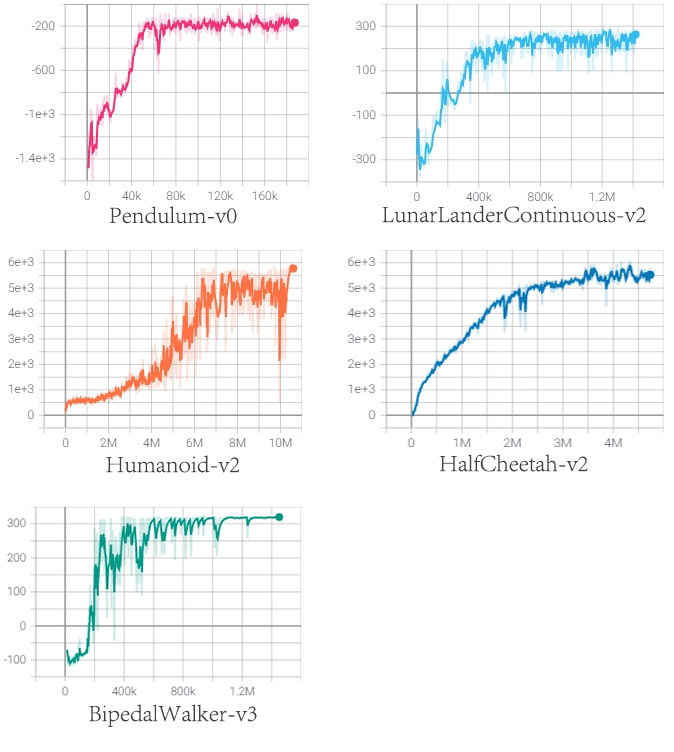
DDPG:
| Pendulum | LunarLanderContinuous |
|---|---|
 |
 |
TD3:
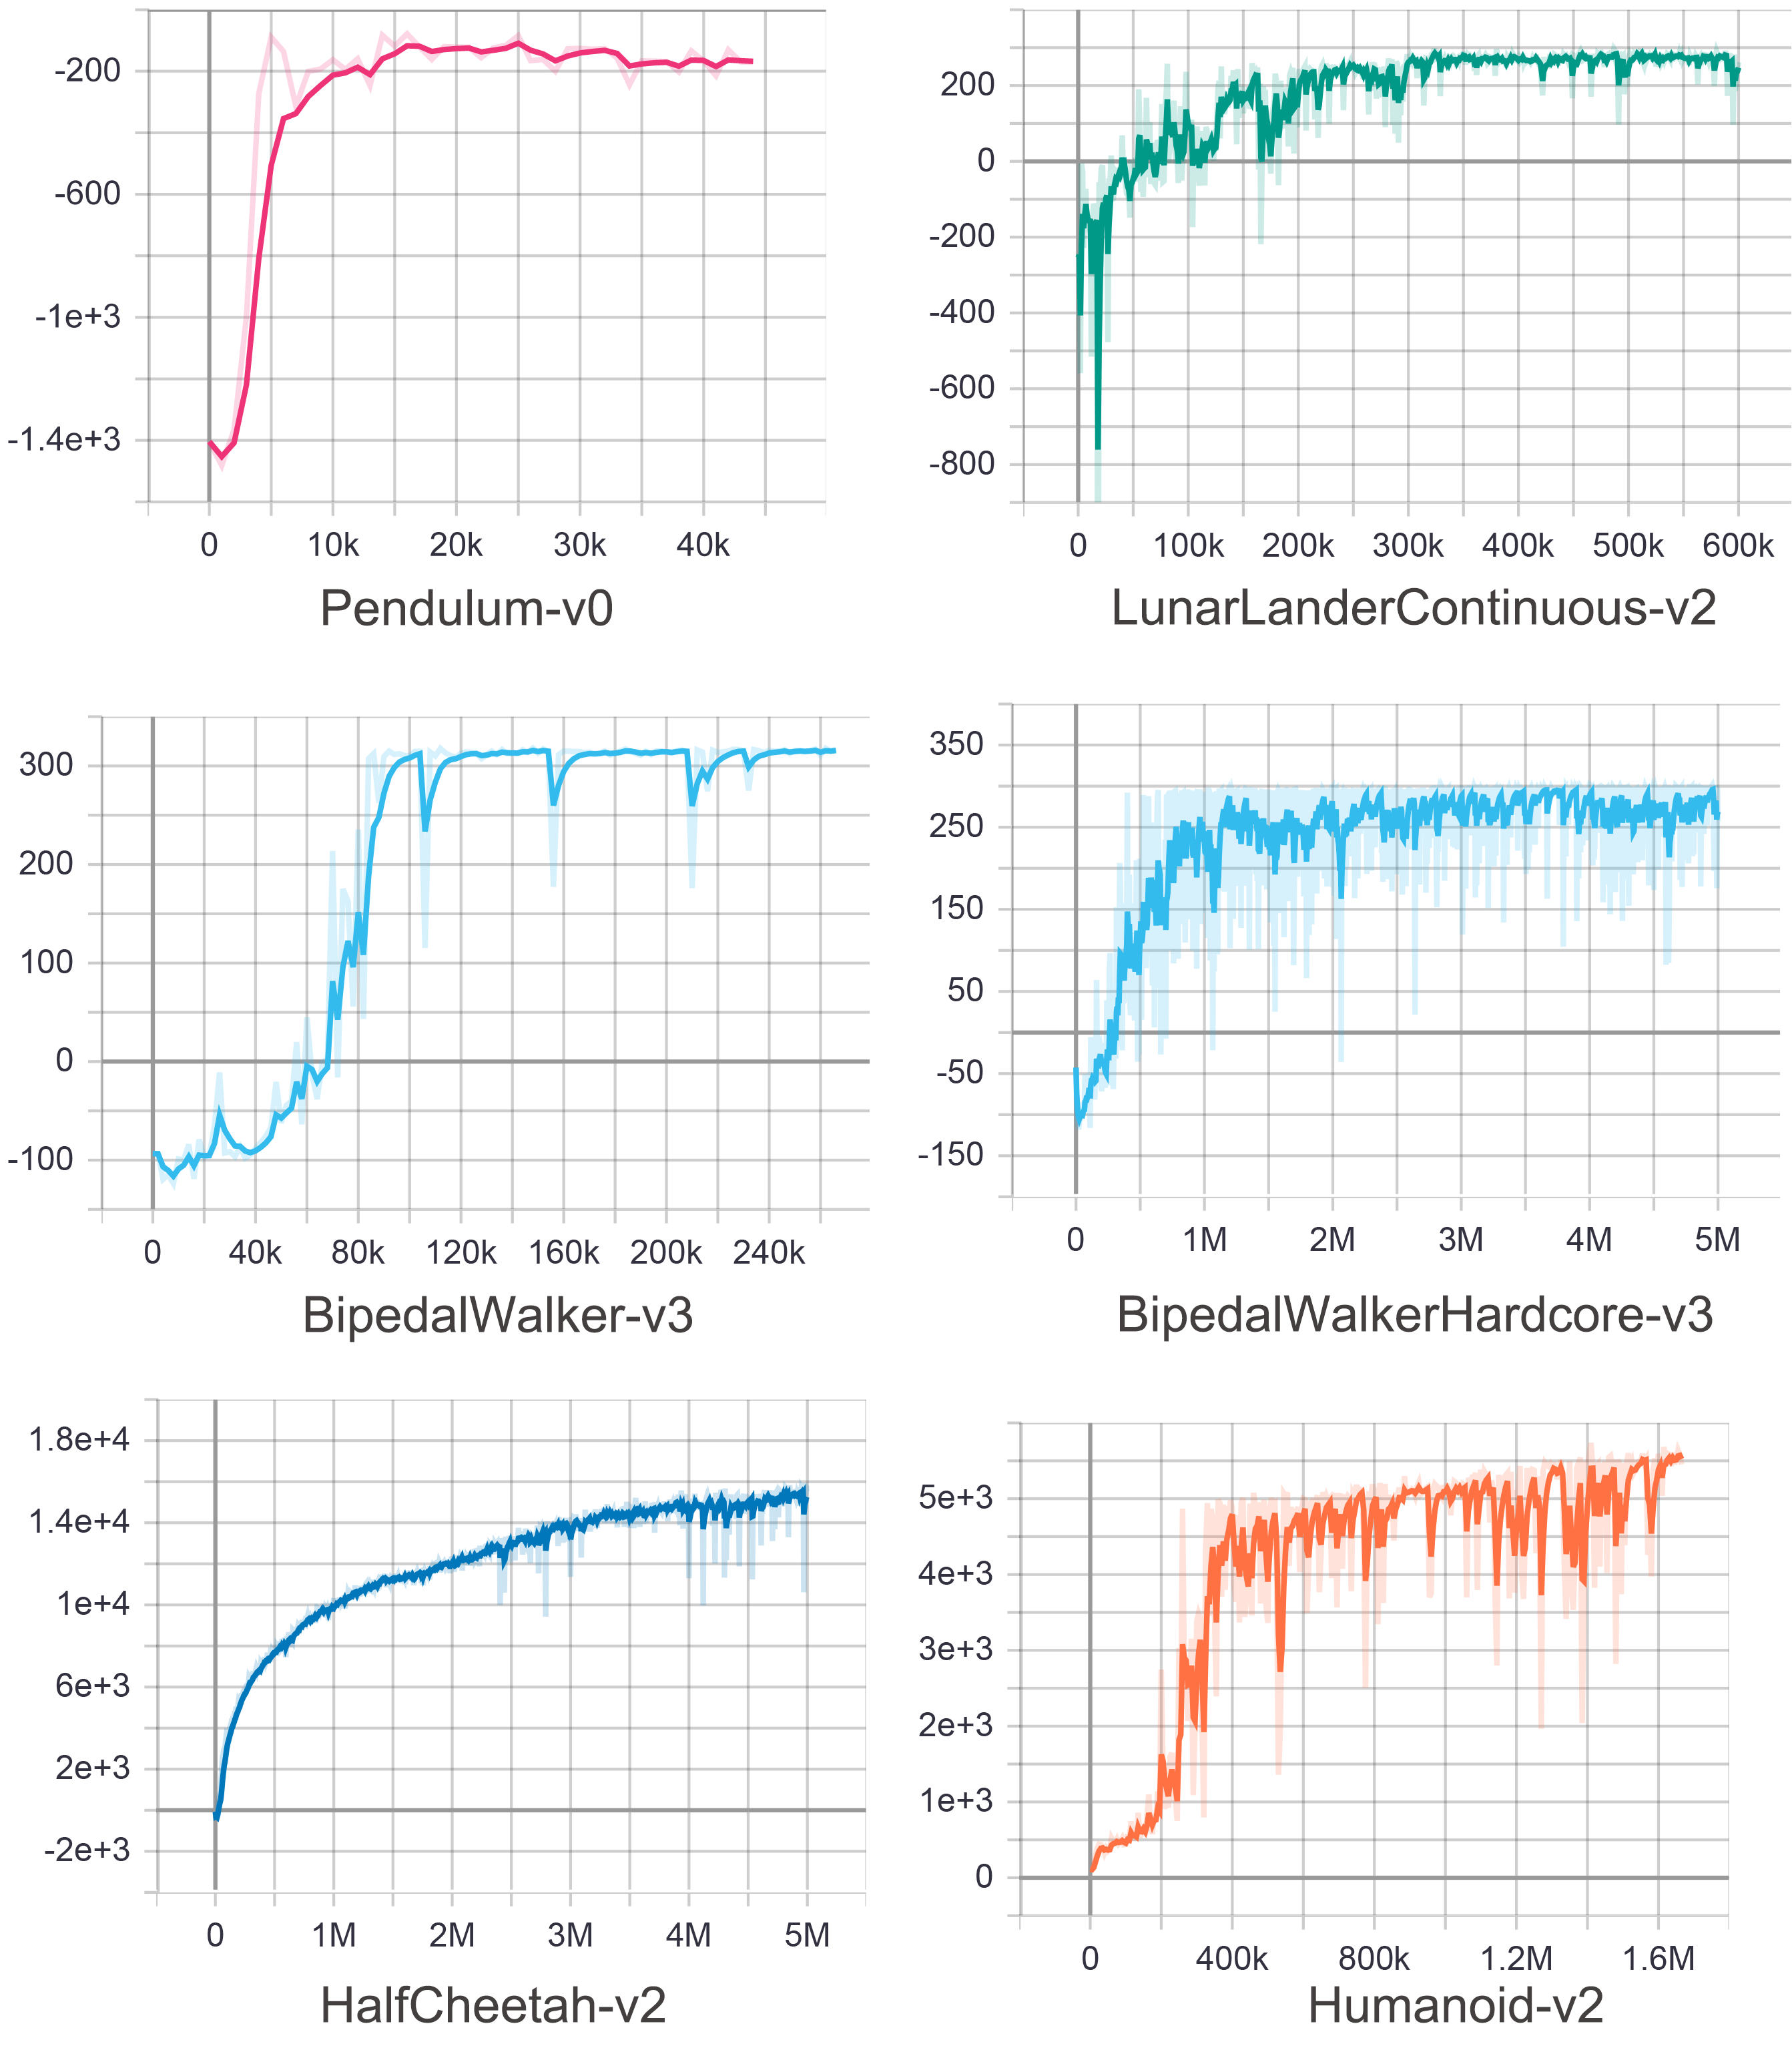
SAC Continuous:
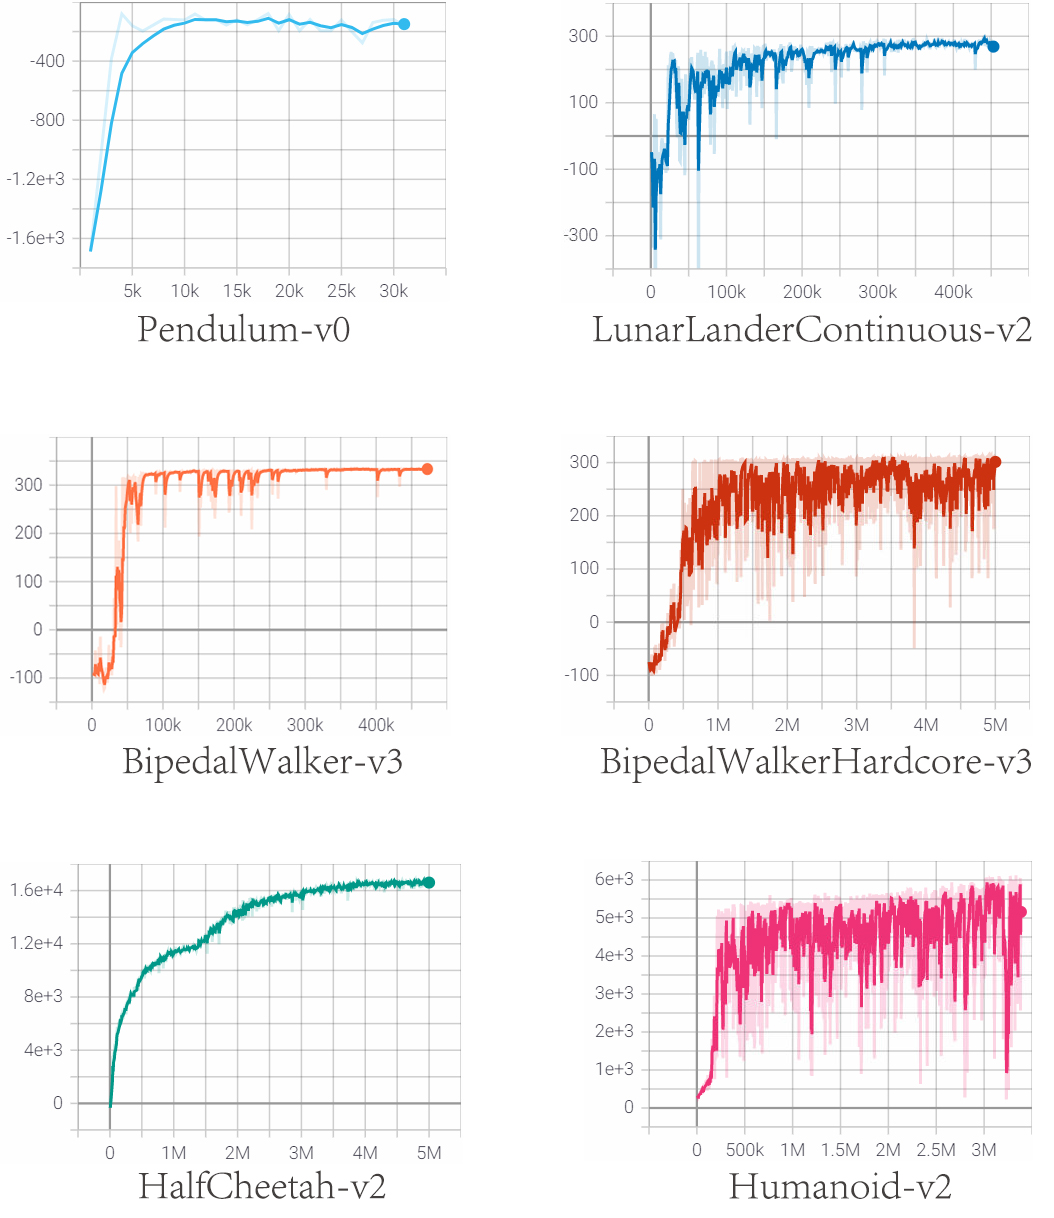
SAC Discrete:
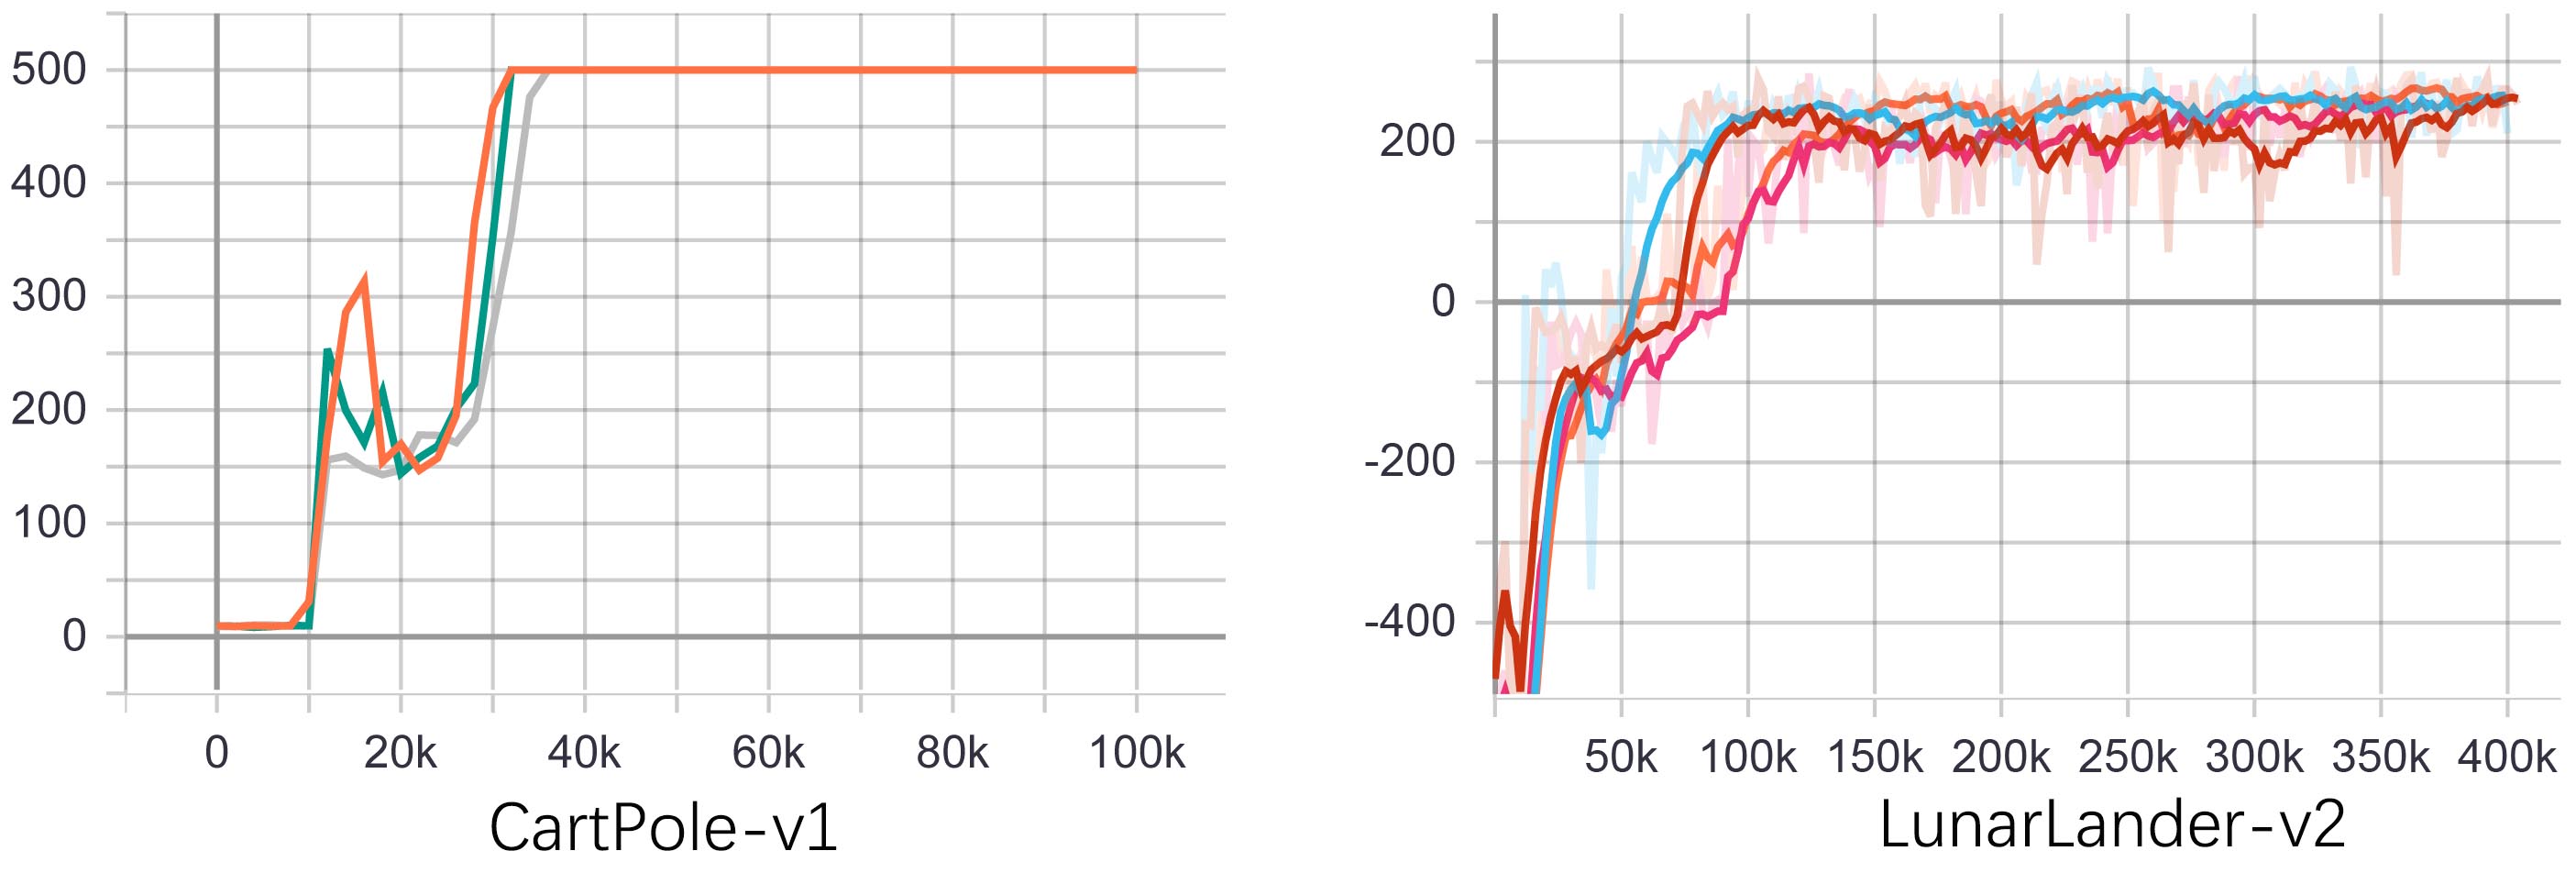
Actor-Sharer-Learner (ASL):
