← 开源
Walter0807

MotionBERT

[ICCV 2023] PyTorch Implementation of "MotionBERT: A Unified Perspective on Learning Human Motion Representations"

Model DevelopmentArchitecturePython
在 GitHub 打开
增长势头
+024 小时新增 Star0.0%
1.46k
Star
183
Fork
+1
本周
4
贡献者
创建于 2022-05-02 · 更新于 2026-10-14 · 今日第 10283 名
主要开发者
Walter0807ShirleyMaxxviewsetting

Walter0807/MotionBERT 排名第 10,283,有 1,455 个星标。

同类别比较

Walter0807/MotionBERT 排名第 10,283,此处有 8 个同类条目;microsoft/NeuronBlocks 排名第 10,282。

同类别比较
名称排名指标
aeon-toolkit/aeon10,272
语言:
Python
星标数:
1,458
分叉数:
355
简介:
A toolkit for time series machine learning and deep learning
nerfstudio-project/nerfacc10,278
语言:
Python
星标数:
1,457
分叉数:
121
简介:
A General NeRF Acceleration Toolbox in PyTorch.
zama-ai/concrete-ml10,279
语言:
Python
星标数:
1,457
分叉数:
202
简介:
Concrete ML: Privacy Preserving ML framework using Fully Homomorphic Encryption (FHE), built on top of Concrete, with bindings to traditional ML frameworks.
microsoft/NeuronBlocks10,282
语言:
Python
星标数:
1,456
分叉数:
191
简介:
NLP DNN Toolkit - Building Your NLP DNN Models Like Playing Lego
abreheret/PixelAnnotationTool10,284
语言:
C++
星标数:
1,455
分叉数:
308
简介:
Annotate quickly images.
xuannianz/EfficientDet10,291
语言:
Python
星标数:
1,452
分叉数:
388
简介:
EfficientDet (Scalable and Efficient Object Detection) implementation in Keras and Tensorflow
HuwCampbell/grenade10,296
语言:
Haskell
星标数:
1,450
分叉数:
81
简介:
Deep Learning in Haskell
microsoft/TextWorld10,299
语言:
Jupyter Notebook
星标数:
1,450
分叉数:
206
简介:
​TextWorld is a sandbox learning environment for the training and evaluation of reinforcement learning (RL) agents on text-based games.
关键参数与规格
关键参数与规格
参数值
语言Python
类别Model Development
子类别Architecture
关键词3D
星标数1,455
分叉数183
贡献者4
创建日期2022-05-02
更新日期2026-10-14
1 天星标数0
7 天星标数1
排名10,283
上次排名5,679
排名变化-4,604
7 天星标排名9,828
上次 7 天星标排名17,142
7 天星标排名变化7,314
总星标排名8,293
上次总星标排名8,285
总星标排名变化-8
国家China
README 摘录

MotionBERT: A Unified Perspective on Learning Human Motion Representations This is the official PyTorch implementation of the paper *"MotionBERT: A Unified Perspective on Learning Human Motion Representations"* (ICCV 2023). md | | 3D human pose estimation | docs/pose3d. md | | Skeleton-based action recognition | docs/action. md | Applications In-the-wild inference (for custom videos) Please refer to docs/inference. Using MotionBERT for *human-centric* video representations **Hints** 1. The model could handle different input lengths (no more than 243 frames). No need

to explicitly specify the input length elsewhere. The model uses 17 body keypoints (H36M format). If you are using other formats, please convert them before feeding to MotionBERT. py for examples of (easily) adapting MotionBERT to different downstream tasks. For RGB videos, you need to extract 2D poses (inference. md), convert the keypoint format (dataset_wild. py), and then feed to MotionBERT (infer_wild. yaml | - | | MotionBERT-Lite (61MB) | OneDrive | pretrain/MB_lite. yaml | - | | 3D Pose (H36M-SH, scratch) | OneDrive | pose3d

/MB_train_h36m. 2mm (MPJPE) | | 3D Pose (H36M-SH, ft) | OneDrive | pose3d/MB_ft_h36m. 2mm (MPJPE) | | Action Recognition (x-sub, ft) | OneDrive | action/MB_ft_NTU60_xsub. 2% (Top1 Acc) | | Action Recognition (x-view, ft) | OneDrive | action/MB_ft_NTU60_xview. 0% (Top1 Acc) | | Mesh (with 3DPW, ft) | OneDrive | mesh/MB_ft_pw3d. 1mm (MPVE) | In most use cases (especially with finetuning), gives a similar performance with lower computation overhead.

常见问题

记录了多少星标和分叉?

Walter0807/MotionBERT 有 1,455 个星标和 183 个分叉。

仓库排名是多少?

Walter0807/MotionBERT 排名第 10,283。

记录的语言和类别是什么?

Walter0807/MotionBERT 有 1,455 个星标,语言为 Python,类别为 Model Development。

哪个仓库排名最接近?

Walter0807/MotionBERT 与 microsoft/NeuronBlocks 比较,后者排名第 10,282,有 1,456 个星标。

README

MotionBERT: A Unified Perspective on Learning Human Motion Representations

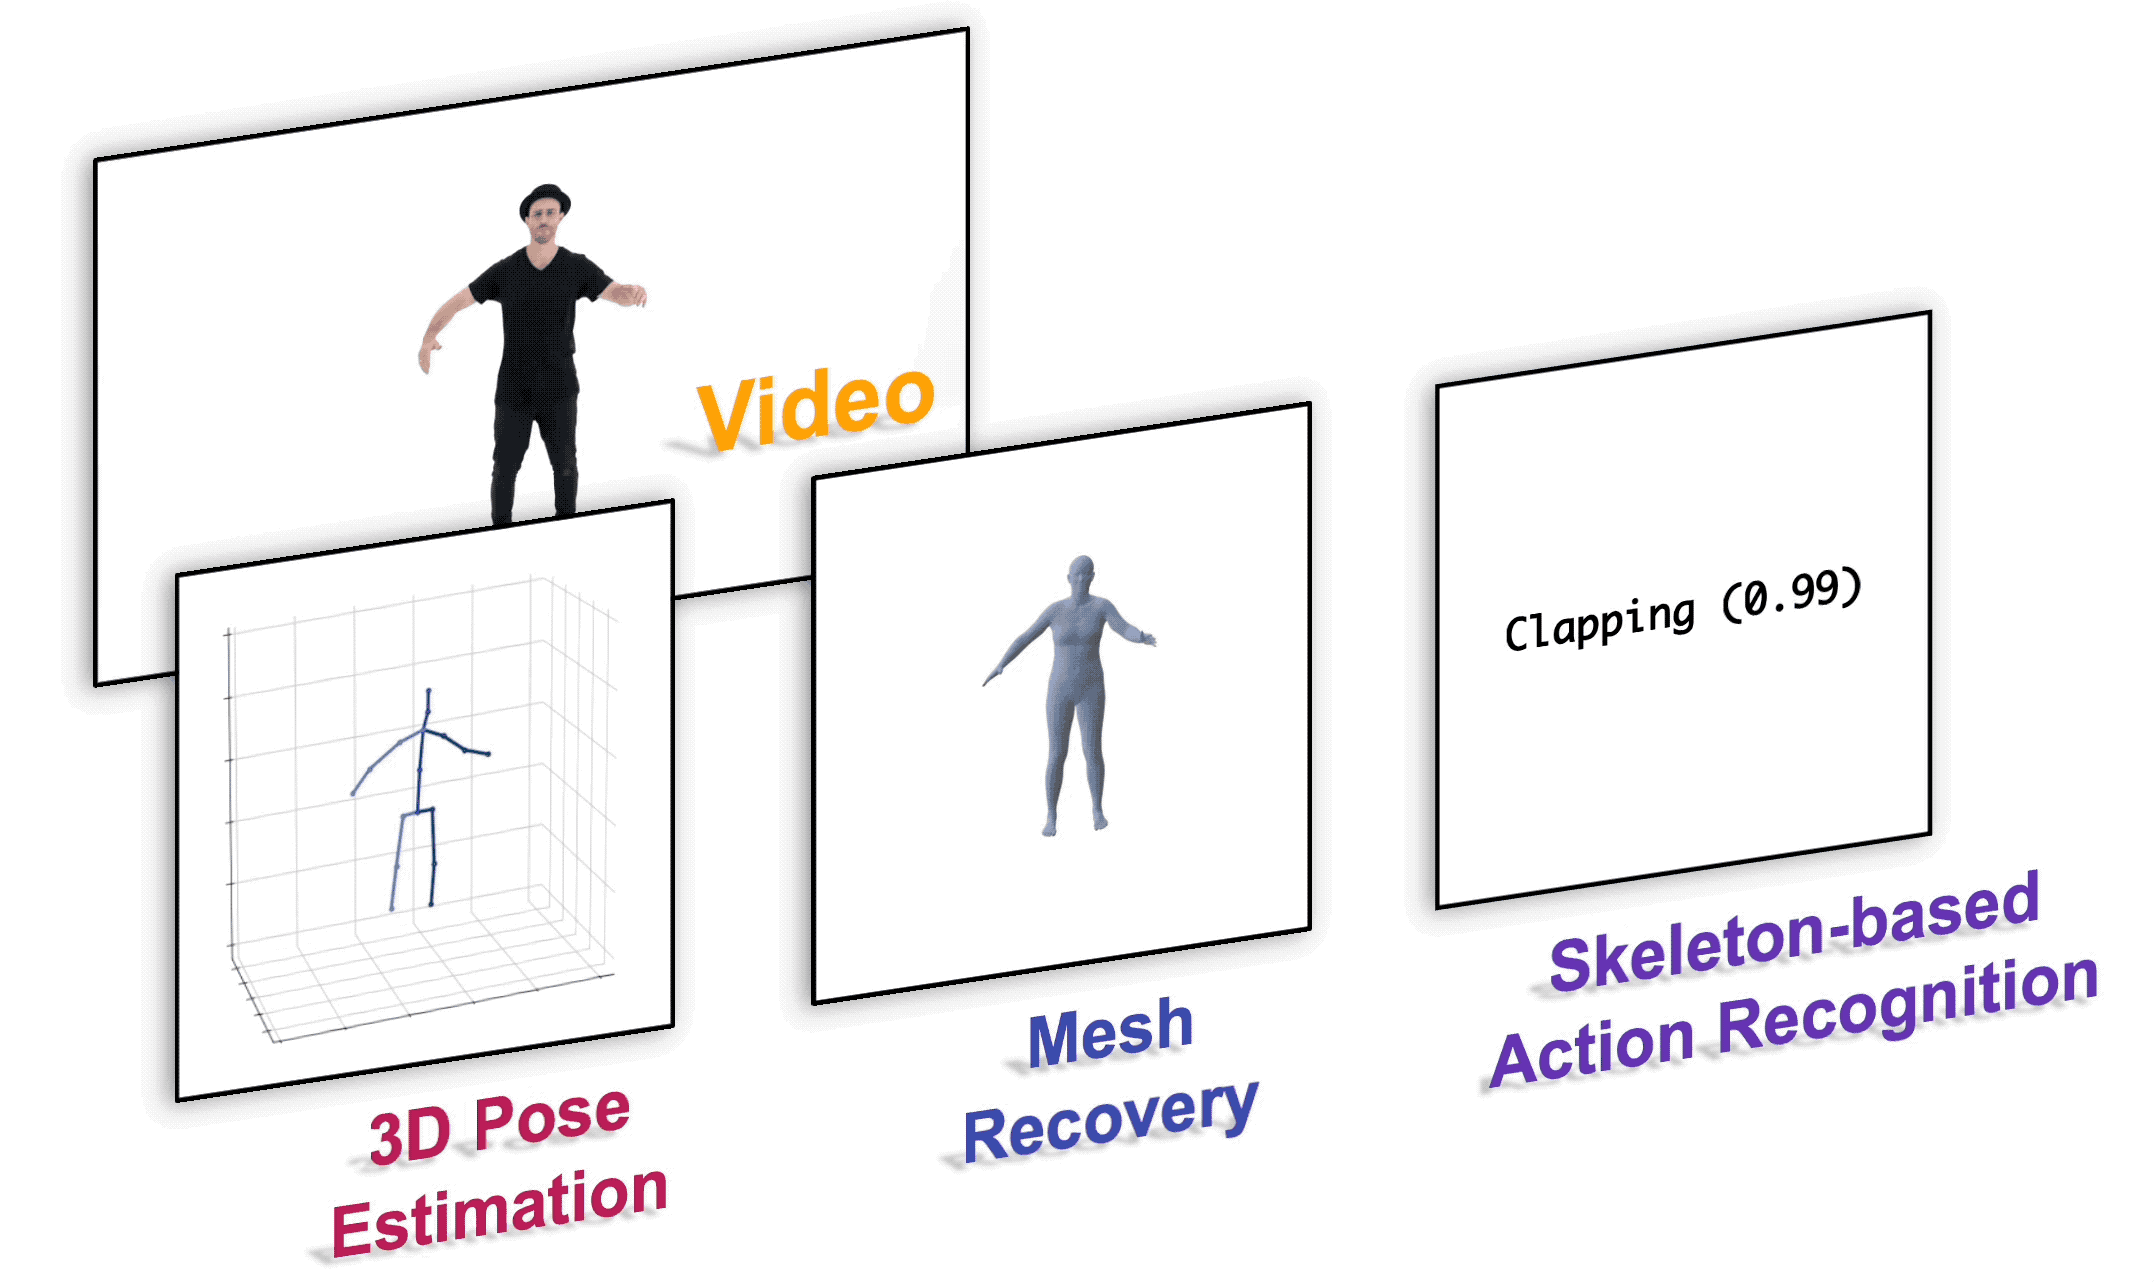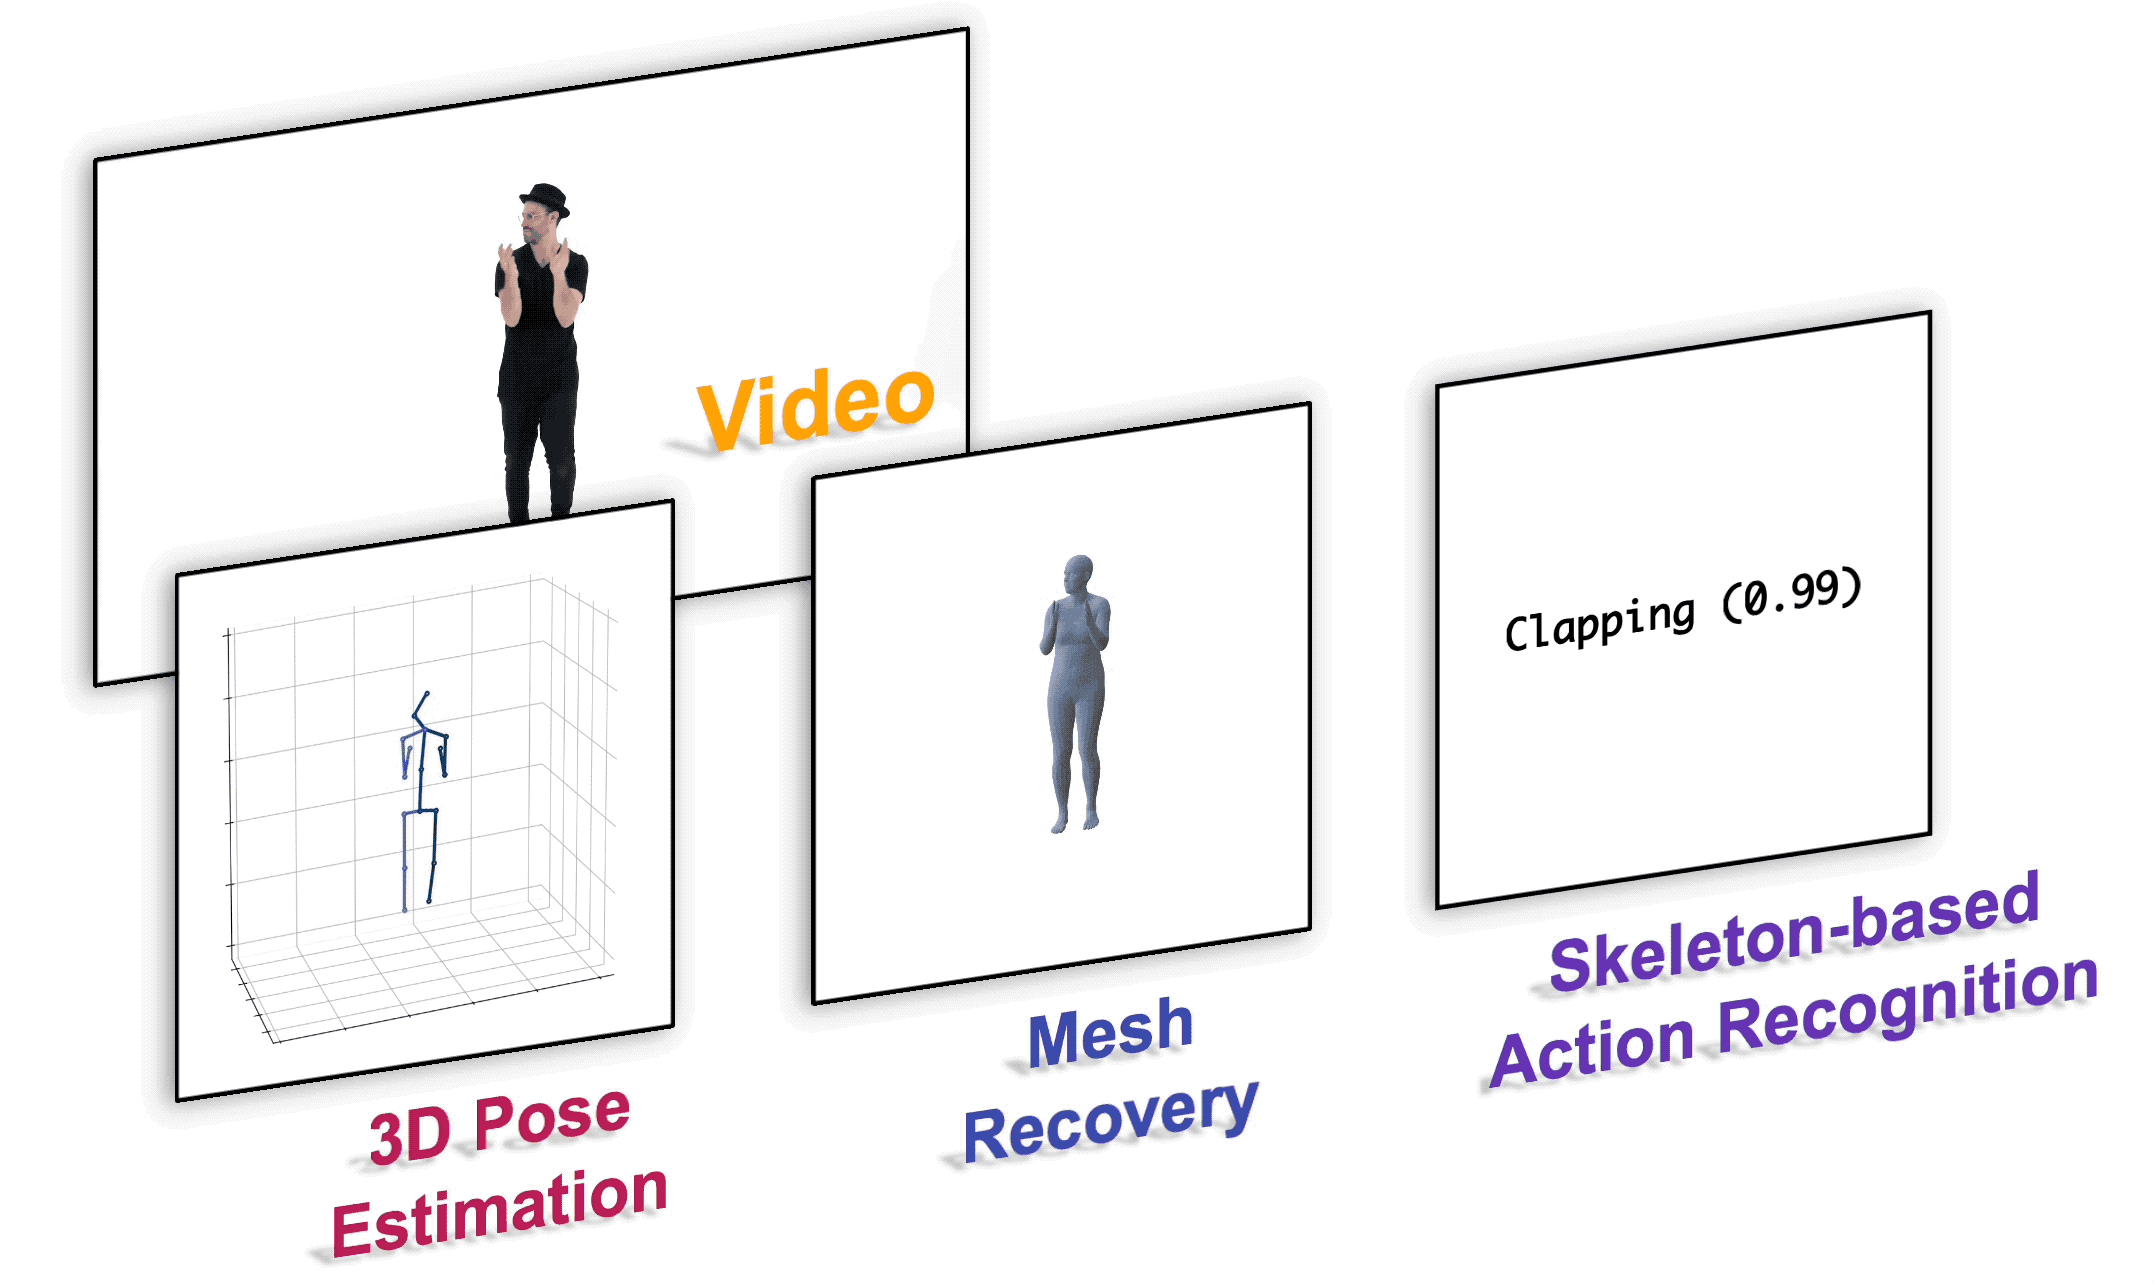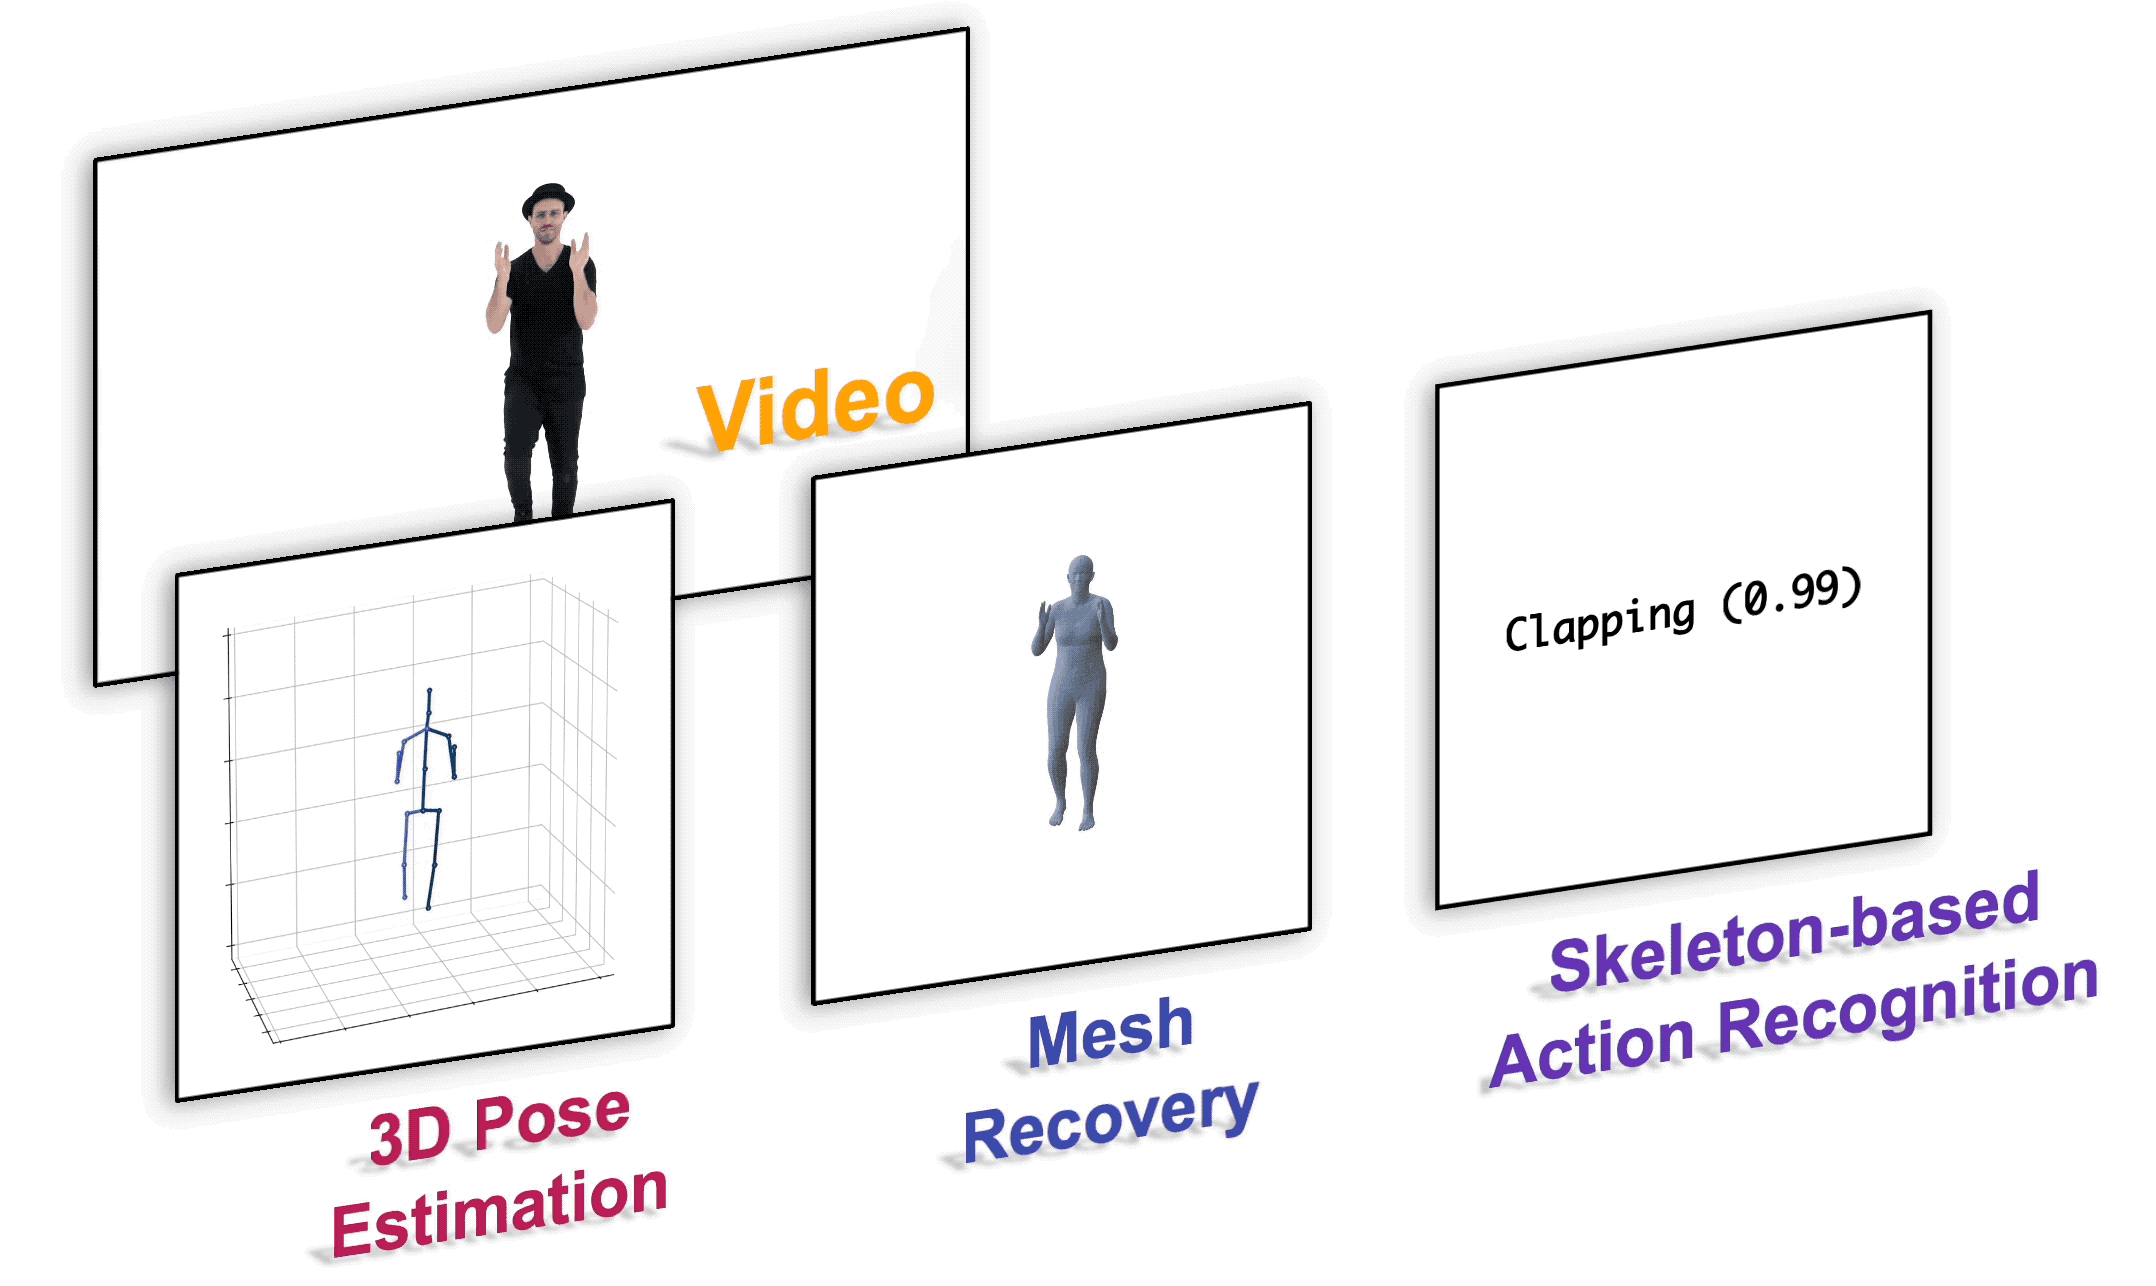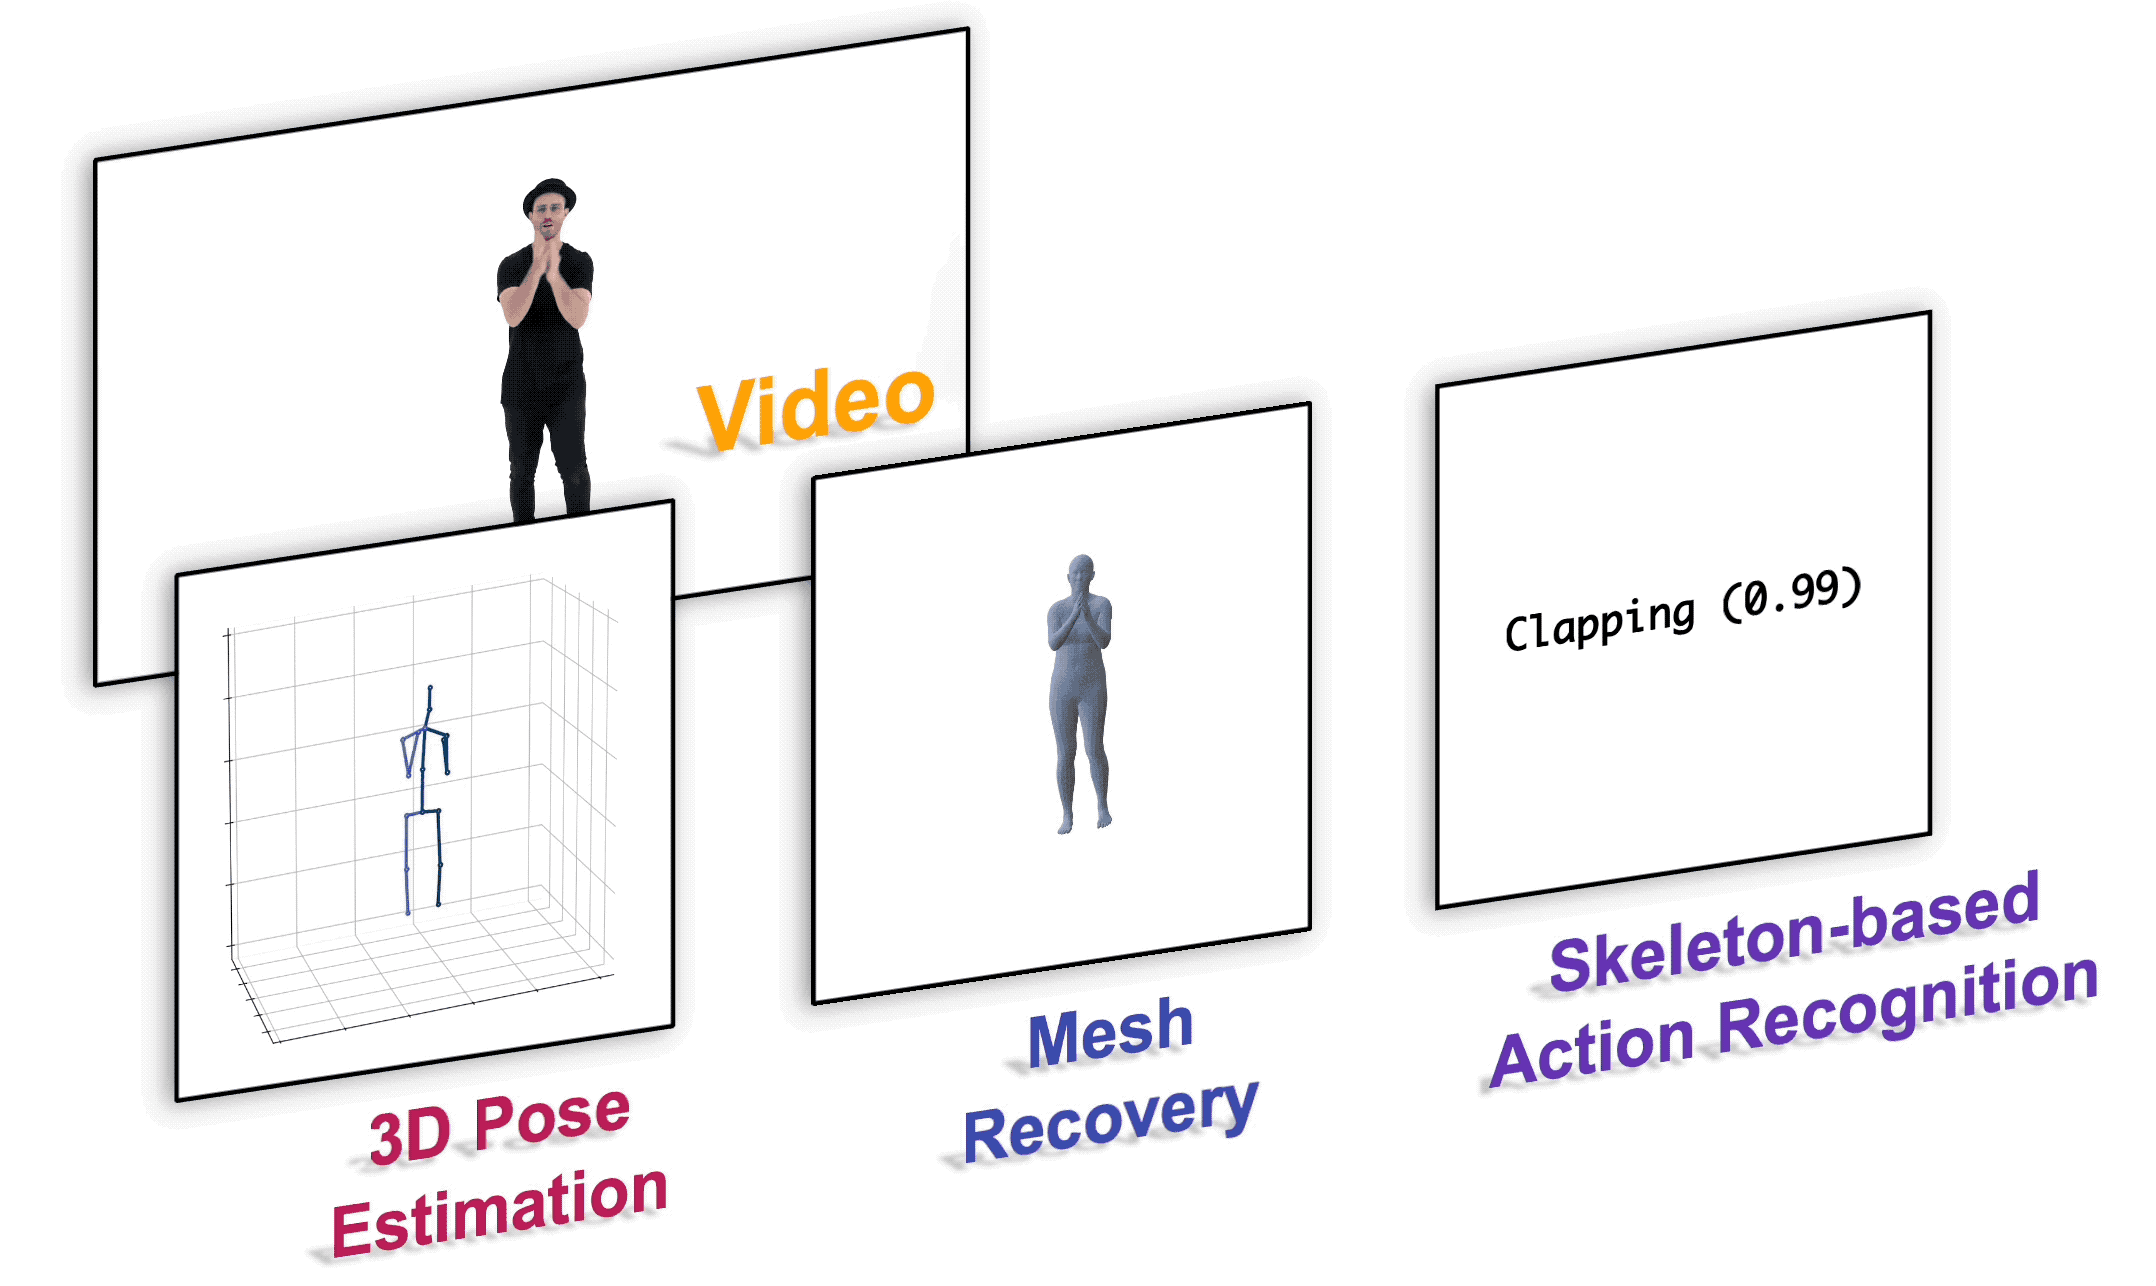
This is the official PyTorch implementation of the paper "MotionBERT: A Unified Perspective on Learning Human Motion Representations" (ICCV 2023).
Installation

conda create -n motionbert python=3.7 anaconda
conda activate motionbert
# Please install PyTorch according to your CUDA version.
conda install pytorch torchvision torchaudio pytorch-cuda=11.6 -c pytorch -c nvidia
pip install -r requirements.txt

Getting Started

Task Document
Pretrain docs/pretrain.md
3D human pose estimation docs/pose3d.md
Skeleton-based action recognition docs/action.md
Mesh recovery docs/mesh.md

Applications

In-the-wild inference (for custom videos)

Please refer to docs/inference.md.

Using MotionBERT for human-centric video representations

'''	    
  x: 2D skeletons 
    type = 
    shape = [batch size * frames * joints(17) * channels(3)]
    
  MotionBERT: pretrained human motion encoder
    type = 
    
  E: encoded motion representation
    type = 
    shape = [batch size * frames * joints(17) * channels(512)]
'''
E = MotionBERT.get_representation(x)

Hints

  1. The model could handle different input lengths (no more than 243 frames). No need to explicitly specify the input length elsewhere.
  2. The model uses 17 body keypoints (H36M format). If you are using other formats, please convert them before feeding to MotionBERT.
  3. Please refer to model_action.py and model_mesh.py for examples of (easily) adapting MotionBERT to different downstream tasks.
  4. For RGB videos, you need to extract 2D poses (inference.md), convert the keypoint format (dataset_wild.py), and then feed to MotionBERT (infer_wild.py).

Model Zoo
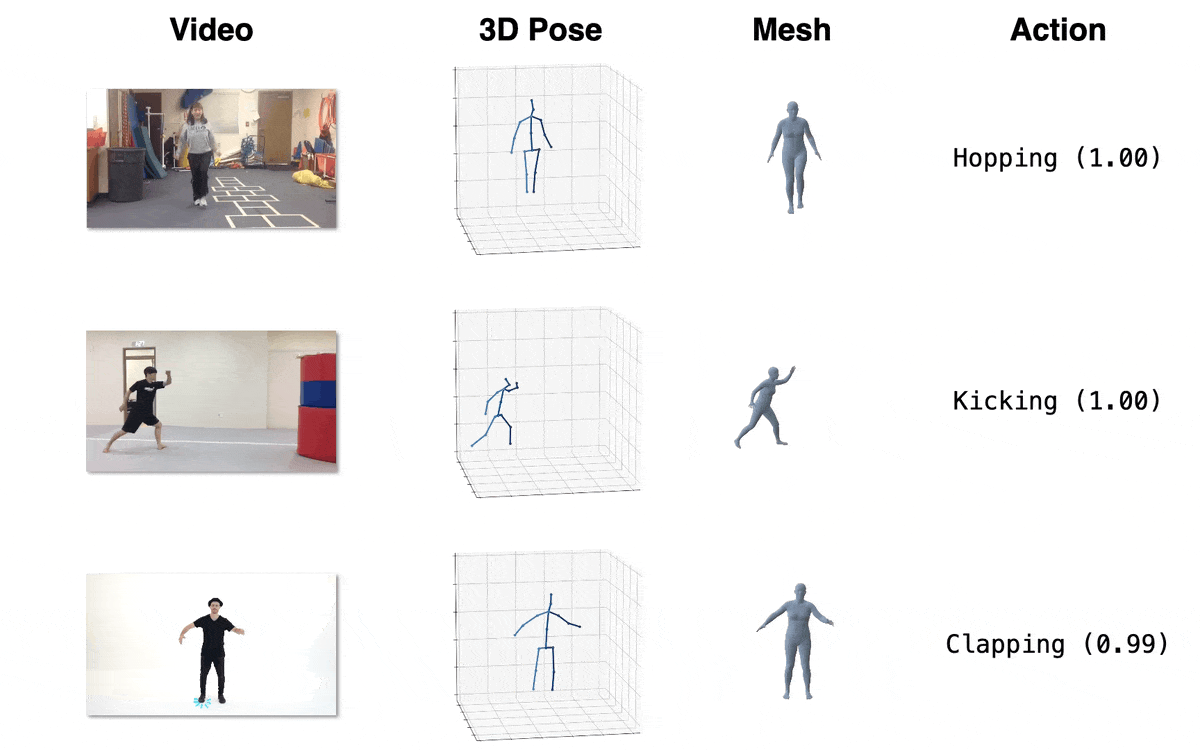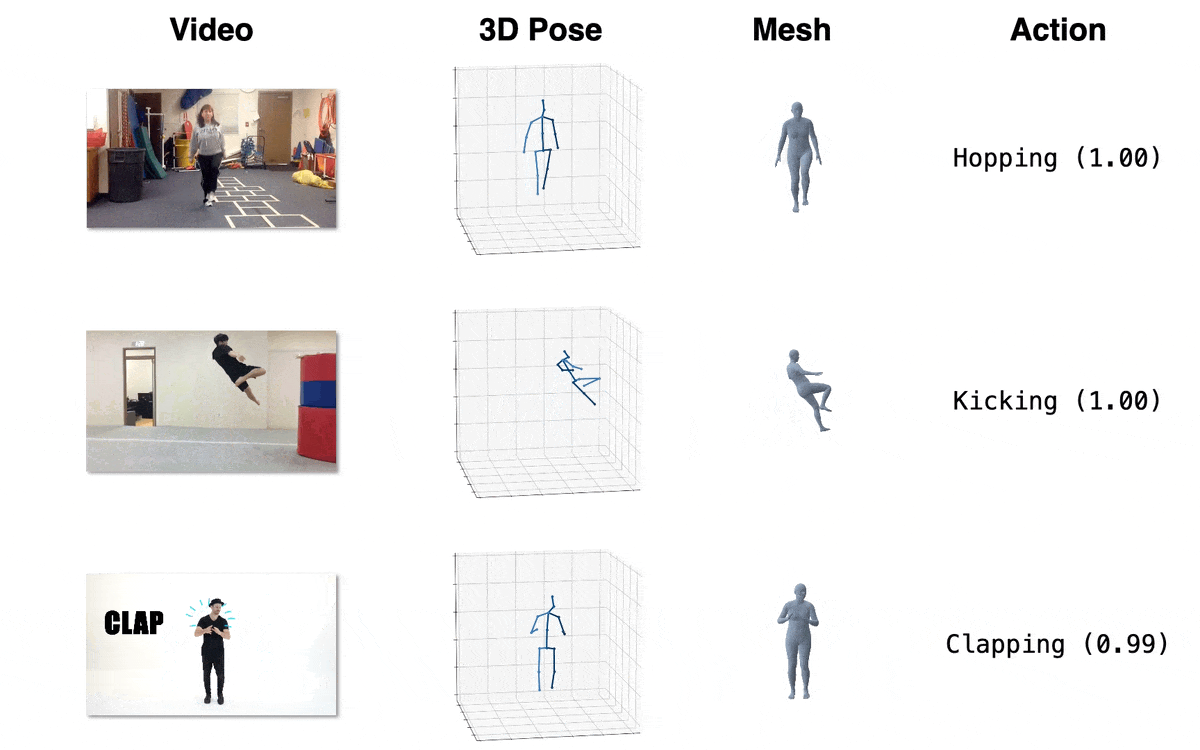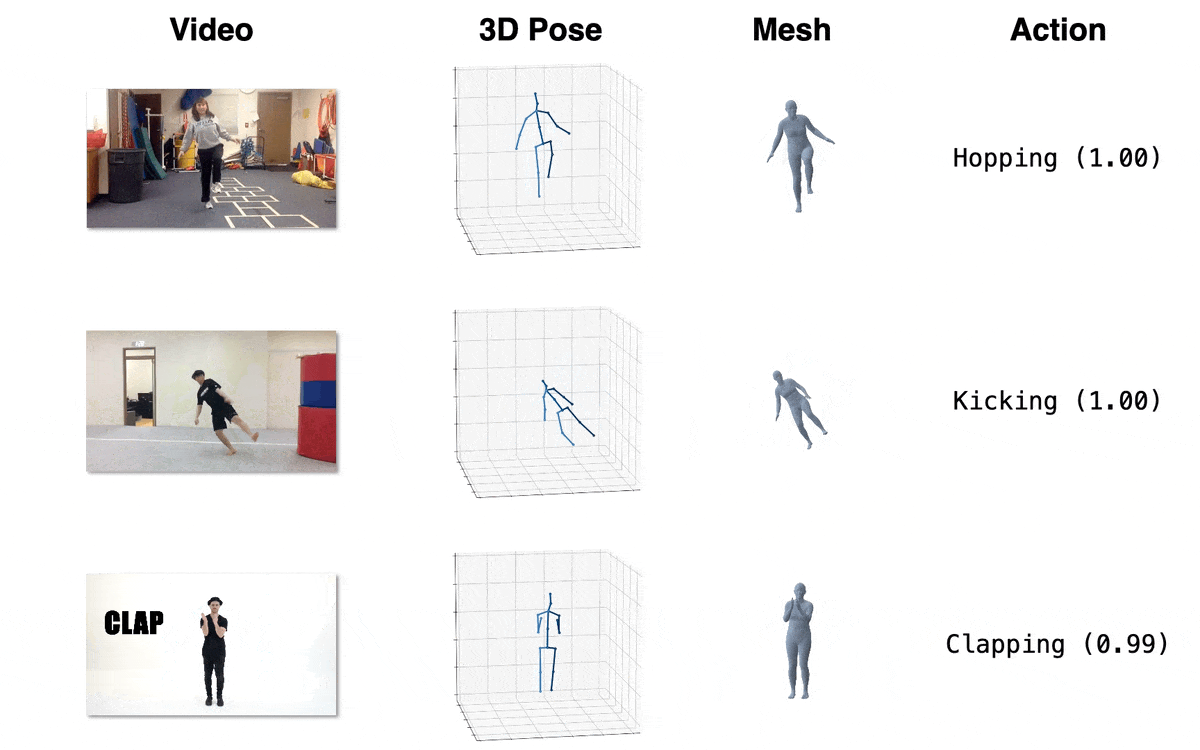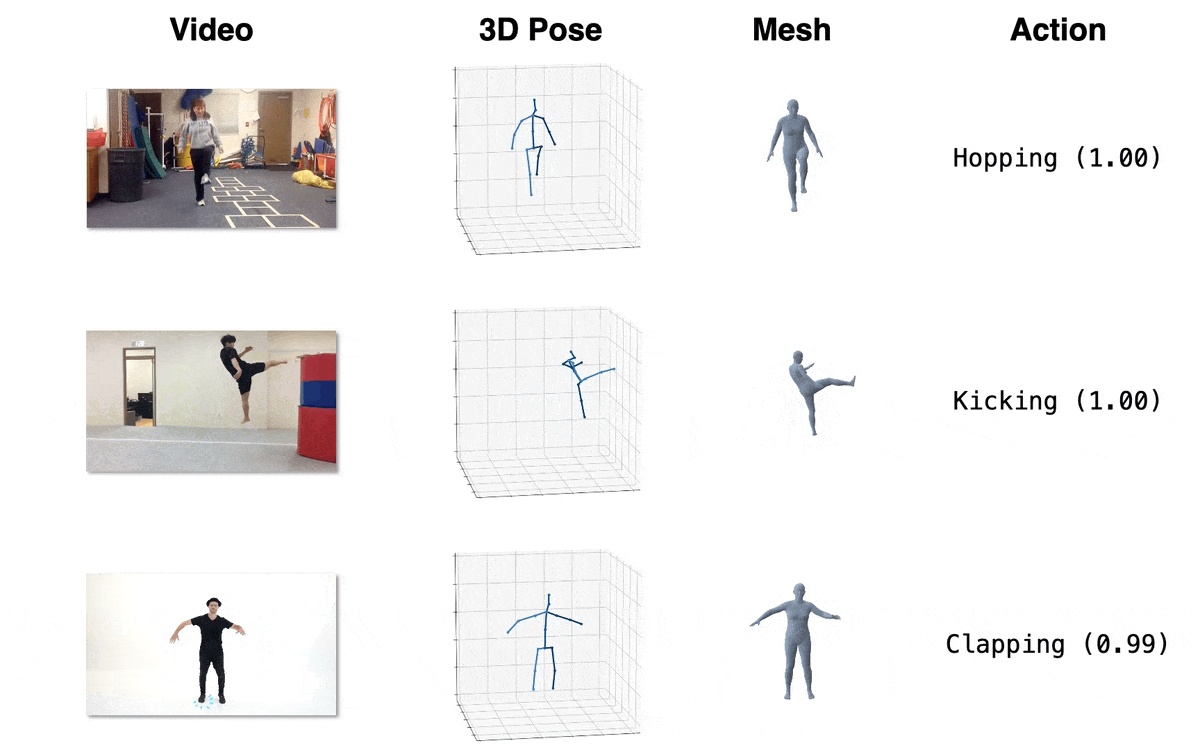
Model Download Link Config Performance
MotionBERT (162MB) OneDrive pretrain/MB_pretrain.yaml -
MotionBERT-Lite (61MB) OneDrive pretrain/MB_lite.yaml -
3D Pose (H36M-SH, scratch) OneDrive pose3d/MB_train_h36m.yaml 39.2mm (MPJPE)
3D Pose (H36M-SH, ft) OneDrive pose3d/MB_ft_h36m.yaml 37.2mm (MPJPE)
Action Recognition (x-sub, ft) OneDrive action/MB_ft_NTU60_xsub.yaml 97.2% (Top1 Acc)
Action Recognition (x-view, ft) OneDrive action/MB_ft_NTU60_xview.yaml 93.0% (Top1 Acc)
Mesh (with 3DPW, ft) OneDrive mesh/MB_ft_pw3d.yaml 88.1mm (MPVE)

In most use cases (especially with finetuning), MotionBERT-Lite gives a similar performance with lower computation overhead.

TODO

  • [x] Scripts and docs for pretraining

  • [x] Demo for custom videos

Citation

If you find our work useful for your project, please consider citing the paper:

@inproceedings{motionbert2022,
  title     =   {MotionBERT: A Unified Perspective on Learning Human Motion Representations}, 
  author    =   {Zhu, Wentao and Ma, Xiaoxuan and Liu, Zhaoyang and Liu, Libin and Wu, Wayne and Wang, Yizhou},
  booktitle =   {Proceedings of the IEEE/CVF International Conference on Computer Vision},
  year      =   {2023},
}
排名相邻
同类项目