

HY-Motion 1.0: Scaling Flow Matching Models for 3D Motion Generation
🔥 News
- Jan 29, 2026: 📊 We released the evaluation prompts and code for SSAE (Structured Semantic Alignment Evaluation), a VLM-based metric designed to assess the semantic alignment of generated videos. Check the
ssaedirectory for usage details! - Dec 30, 2025: 🤗 We released the inference code and pretrained models of HY-Motion 1.0. Please give it a try via our HuggingFace Space and our Official Site!
Introduction
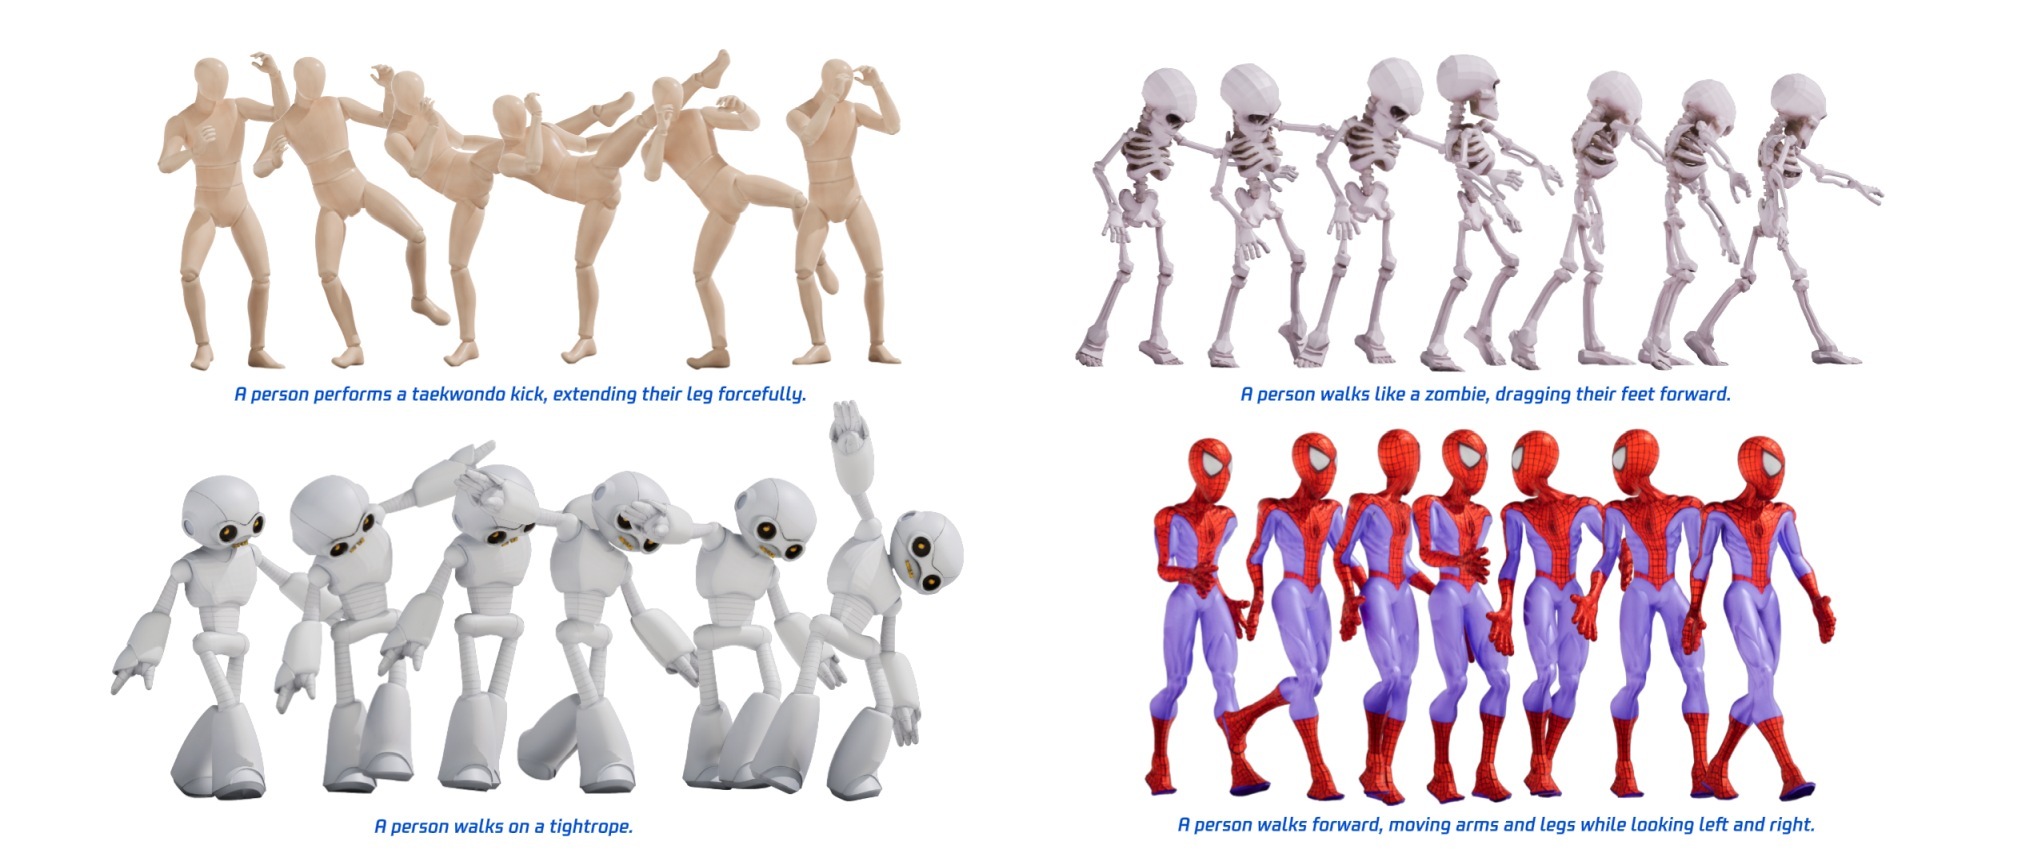
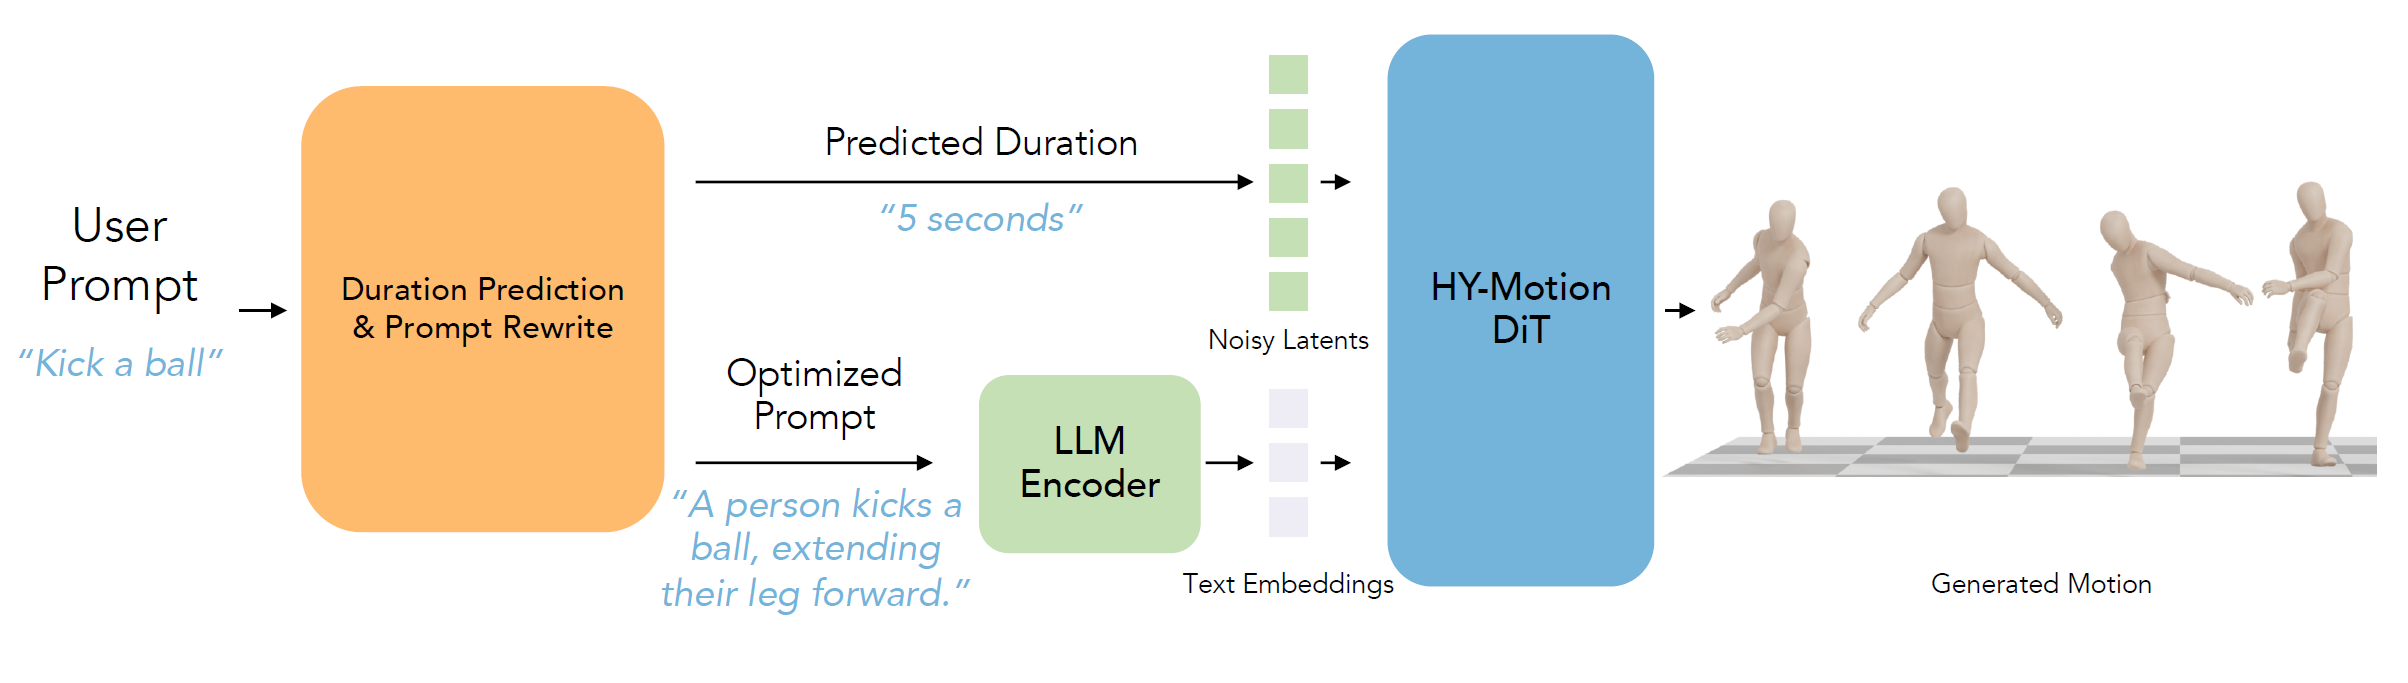
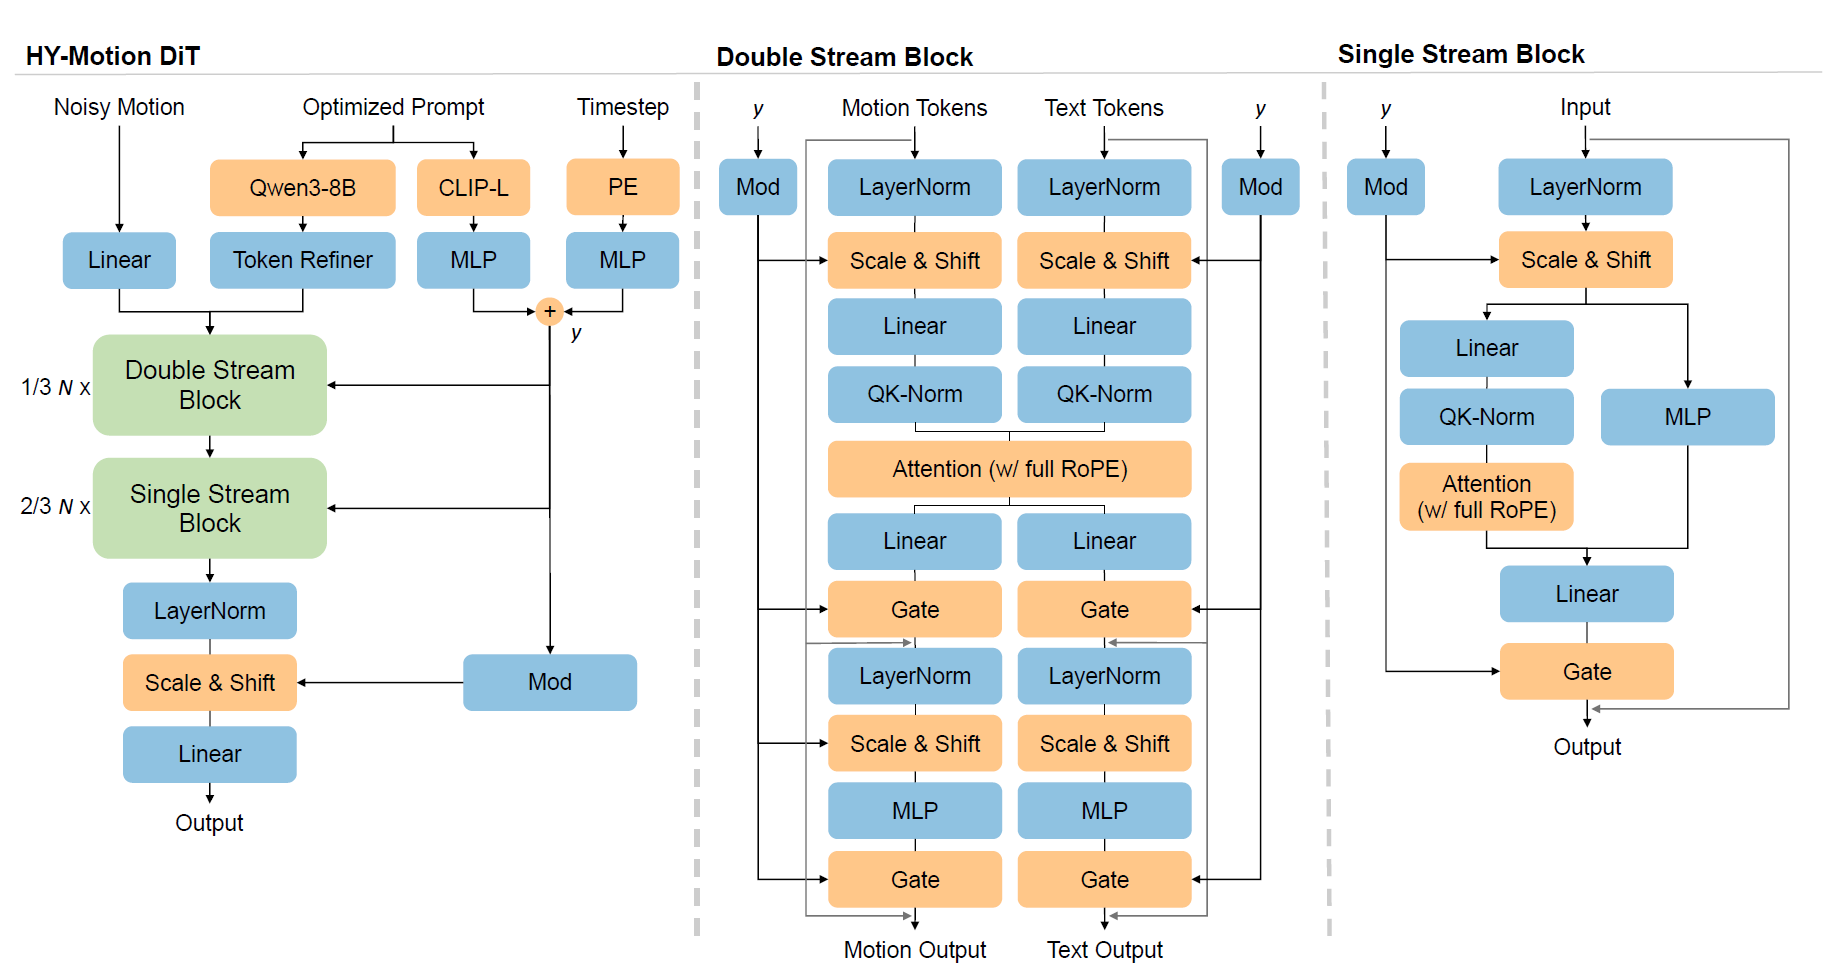
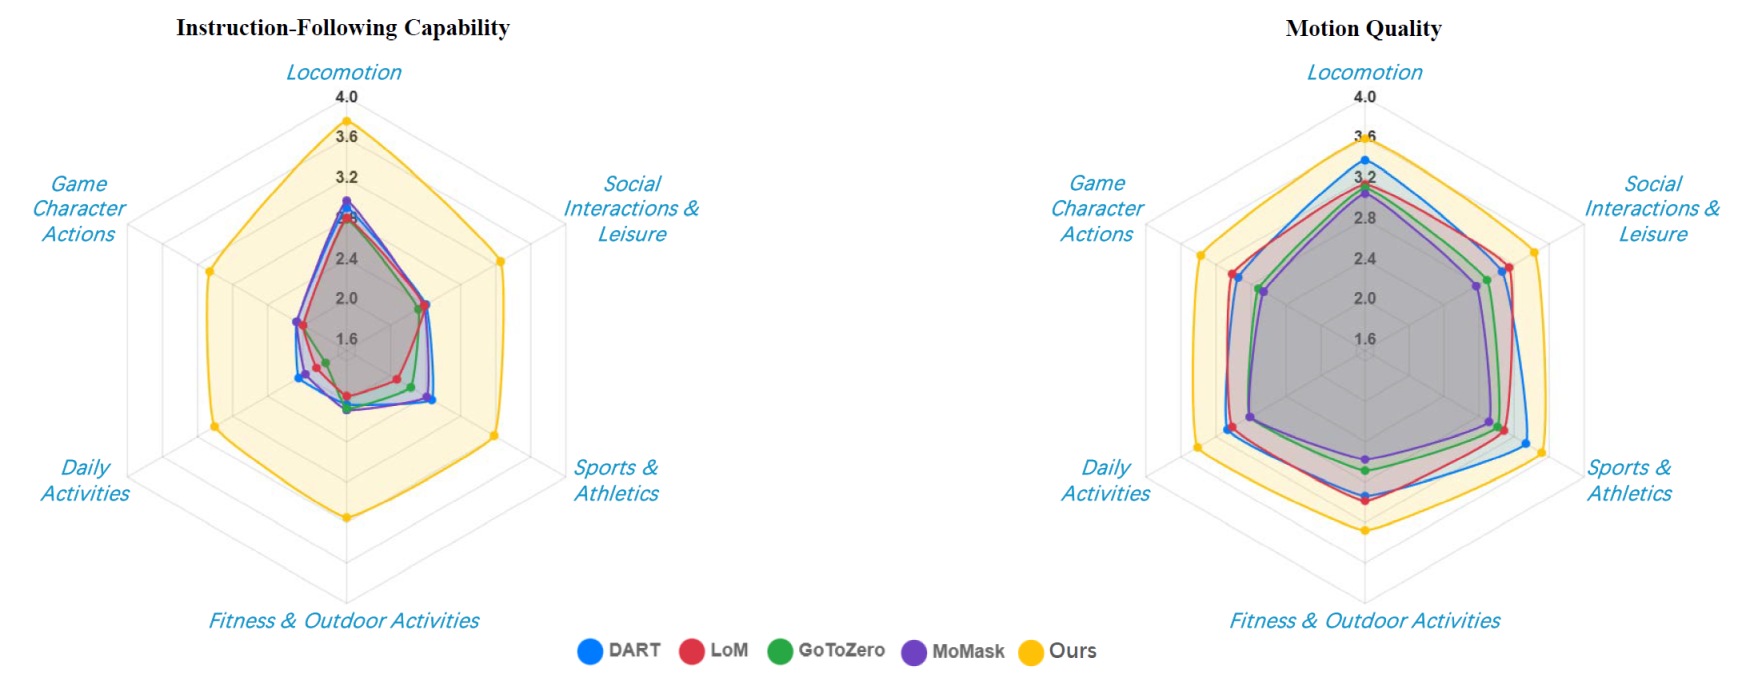
HY-Motion 1.0 is a series of text-to-3D human motion generation models based on Diffusion Transformer (DiT) and Flow Matching. It allows developers to generate skeleton-based 3D character animations from simple text prompts, which can be directly integrated into various 3D animation pipelines. This model series is the first to scale DiT-based text-to-motion models to the billion-parameter level, achieving significant improvements in instruction-following capabilities and motion quality over existing open-source models.
Key Features
-
State-of-the-Art Performance: Achieves state-of-the-art performance in both instruction-following capability and generated motion quality.
-
Billion-Scale Models: We are the first to successfully scale DiT-based models to the billion-parameter level for text-to-motion generation. This results in superior instruction understanding and following capabilities, outperforming comparable open-source models.
-
Advanced Three-Stage Training: Our models are trained using a comprehensive three-stage process:
-
Large-Scale Pre-training: Trained on over 3,000 hours of diverse motion data to learn a broad motion prior.
-
High-Quality Fine-tuning: Fine-tuned on 400 hours of curated, high-quality 3D motion data to enhance motion detail and smoothness.
-
Reinforcement Learning: Utilizes Reinforcement Learning from human feedback and reward models to further refine instruction-following and motion naturalness.
-
🎁 Model Zoo
HY-Motion 1.0 Series
| Model | Description | Date | Size | Huggingface | VRAM (min) |
|---|---|---|---|---|---|
| HY-Motion-1.0 | Standard Text2Motion Model | 2025-12-30 | 1.0B | Download | 26GB |
| HY-Motion-1.0-Lite | Lightweight Text2Motion Model | 2025-12-30 | 0.46B | Download | 24GB |
Note: To reduce GPU VRAM requirements, please use the following settings: --num_seeds=1, text prompt with less than 30 words, and motion length less than 5 seconds.
Note: This table does not includes GPU VRAM requirements for LLM-based prompt engineering feature. If you have sufficient VRAM to run HY-Motion-1.0 model but gradio fails with a VRAM-related error, Run the Gradio application with prompt engineering disabled by setting the environment variable like this: DISABLE_PROMPT_ENGINEERING=True python3 gradio_app.py
🤗 Get Started with HY-Motion 1.0
HY-Motion 1.0 supports macOS, Windows, and Linux.
1. Installation
First, install PyTorch via the official site. Then install the dependencies:
git clone https://github.com/Tencent-Hunyuan/HY-Motion-1.0.git
cd HY-Motion-1.0/
# Make sure git-lfs is installed
git lfs pull
pip install -r requirements.txt
2. Download Model Weights
Please follow the instructions in ckpts/README.md to download the necessary model weights.
Code Usage (CLI)
We provide a script for local batch inference, suitable for processing large amounts of prompts.
# HY-Motion-1.0
python3 local_infer.py --model_path ckpts/tencent/HY-Motion-1.0

# HY-Motion-1.0-Lite
python3 local_infer.py --model_path ckpts/tencent/HY-Motion-1.0-Lite
Common Parameters:
--input_text_dir: Directory containing.txtor.jsonprompt files.--output_dir: Directory to save results (default:output/local_infer).--disable_duration_est: Disable LLM-based duration estimation.--disable_rewrite: Disable LLM-based prompt rewriting.--prompt_engineering_host/--prompt_engineering_model_path: (Optional) Host address / local checkpoint for the Duration Prediction & Prompt Rewrite Module.- Download: You can download the Duration Prediction & Prompt Rewrite Module from Here.
- Note: If you do not set these parameter, you must also set
--disable_duration_estand--disable_rewrite. Otherwise, the script will raise an error due to host unavailable.
Gradio App
You can host a Gradio web interface on your local machine for interactive visualization:
python3 gradio_app.py
After running the command, open your browser and visit http://localhost:7860
Prompting Guide & Best Practices
-
Language & Length: Please use English. For optimal results, keep your prompt under 60 words. For other languages, please use the Text2MotionPrompter to rewrite the prompt.
-
Content Focus: Focus on action descriptions or detailed movements of the limbs and torso.
-
Current Limitations (NOT Supported):
- ❌ Non-humanoid Characters: Animations for animals or non-human creatures.
- ❌ Subjective/Visual Attributes: Descriptions of complex emotions, clothing, or physical appearance.
- ❌ Environment & Camera: Descriptions of objects, scenes, or camera angles.
- ❌ Multi-person Interactions: Motions involving two or more people.
- ❌ Special Modes: Seamless loop or in-place animations.
- Example Prompts:
- A person performs a squat, then pushes a barbell overhead using the power from standing up.
- A person climbs upward, moving up the slope.
- A person stands up from the chair, then stretches their arms.
- A person walks unsteadily, then slowly sits down.
🔗 BibTeX
If you found this repository helpful, please cite our reports:
@article{hymotion2025,
  title={HY-Motion 1.0: Scaling Flow Matching Models for Text-To-Motion Generation},
  author={Tencent Hunyuan 3D Digital Human Team},
  journal={arXiv preprint arXiv:2512.23464},
  year={2025}
}
🤗 Community Integrations
We appreciate the community for creating integrations for HY-Motion! Here are some third-party implementations:
- Kaggle Notebook Implementation by @kushagra77kushwaha — An optimized, one-click CLI environment pre-configured to run text-to-animation generations seamlessly on free-tier P100 GPUs.
- ComfyUI-HY-Motion1 by @jtydhr88
Acknowledgements
We would like to thank the contributors to the FLUX, diffusers, HuggingFace, SMPL/SMPLH, CLIP, Qwen3, PyTorch3D, kornia, transforms3d, FBX-SDK, GVHMR, and HunyuanVideo repositories or tools, for their open research and exploration.