← 开源
SkyworkAI

UniPic

Open-source SOTA multi-image editing model

ModelsVision modelsPython
在 GitHub 打开
增长势头
+024 小时新增 Star0.0%
877
Star
43
Fork
+0
本周
8
贡献者
创建于 2025-07-27 · 更新于 2026-10-09 · 今日第 12966 名
主要开发者

SkyworkAI/UniPic 排名第 12,966,有 877 个星标。

同类别比较

SkyworkAI/UniPic 排名第 12,966,此处有 8 个同类条目;gzerveas/mvts_transformer 排名第 12,978。

同类别比较
名称排名指标
soubhiksanyal/RingNet12,901
语言:
Python
星标数:
886
分叉数:
172
简介:
Learning to Regress 3D Face Shape and Expression from an Image without 3D Supervision
TencentARC/SEED-Story12,903
语言:
Python
星标数:
885
分叉数:
66
简介:
SEED-Story: Multimodal Long Story Generation with Large Language Model
hkchengrex/CascadePSP12,906
语言:
Python
星标数:
885
分叉数:
97
简介:
[CVPR 2020] CascadePSP: Toward Class-Agnostic and Very High-Resolution Segmentation via Global and Local Refinement
declare-lab/TangoFlux12,915
语言:
Jupyter Notebook
星标数:
884
分叉数:
79
简介:
[ICLR 2026] TangoFlux: Super Fast and Faithful Text to Audio Generation with Flow Matching
gzerveas/mvts_transformer12,978
语言:
Python
星标数:
876
分叉数:
193
简介:
Multivariate Time Series Transformer, public version
microsoft/GODEL12,981
语言:
Python
星标数:
876
分叉数:
113
简介:
Large-scale pretrained models for goal-directed dialog
SunzeY/AlphaCLIP12,993
语言:
Jupyter Notebook
星标数:
874
分叉数:
57
简介:
[CVPR 2024] Alpha-CLIP: A CLIP Model Focusing on Wherever You Want
NVIDIA/mellotron13,031
语言:
Jupyter Notebook
星标数:
870
分叉数:
187
简介:
Mellotron: a multispeaker voice synthesis model based on Tacotron 2 GST that can make a voice emote and sing without emotive or singing training data
关键参数与规格
关键参数与规格
参数值
语言Python
类别Models
子类别Vision models
关键词Image-to-image
星标数877
分叉数43
贡献者8
创建日期2025-07-27
更新日期2026-10-09
1 天星标数0
7 天星标数0
排名12,966
上次排名12,863
排名变化-103
7 天星标排名13,695
上次 7 天星标排名10,550
7 天星标排名变化-3,145
总星标排名12,347
上次总星标排名12,322
总星标排名变化-25
国家Singapore
README 摘录

Skywork-UniPic Unified multimodal model for image editing, generation, and understanding 📝 Overview Welcome to the **Skywork-UniPic** repository! Unified framework for single-image editing & multi-image composition. Supports **1–6 input images** with flexible resolutions. 5M-Kontext** and **MetaQuery** variants based on Efficient Architectures with Diffusion Post-Training, delivering state-of-the-art performance in text-to-image generation, fine-grained image editing, and multimodal reasoning. 5B parameters**, **Unified Autoregressive Modeling** for joint visual understanding and generation, enabling a single

transformer to handle both perception and synthesis tasks.

常见问题

记录了多少星标和分叉?

SkyworkAI/UniPic 有 877 个星标和 43 个分叉。

仓库排名是多少?

SkyworkAI/UniPic 排名第 12,966。

记录的语言和类别是什么?

SkyworkAI/UniPic 有 877 个星标,语言为 Python,类别为 Models。

哪个仓库排名最接近?

SkyworkAI/UniPic 与 gzerveas/mvts_transformer 比较,后者排名第 12,978,有 876 个星标。

README

Skywork-UniPic

Unified multimodal model for image editing, generation, and understanding

📝 Overview

Welcome to the Skywork-UniPic repository!
This repository hosts the model weights and official implementations of unipic unified multimodal series, featuring three distinct modeling paradigms:

  • UniPic-3 (README) — 🔥 Open-source SOTA Multi-Image Editing Model. Unified framework for single-image editing & multi-image composition. Supports 1–6 input images with flexible resolutions. 8-steps inference with 12.5× speedup via CM + DMD distillation.
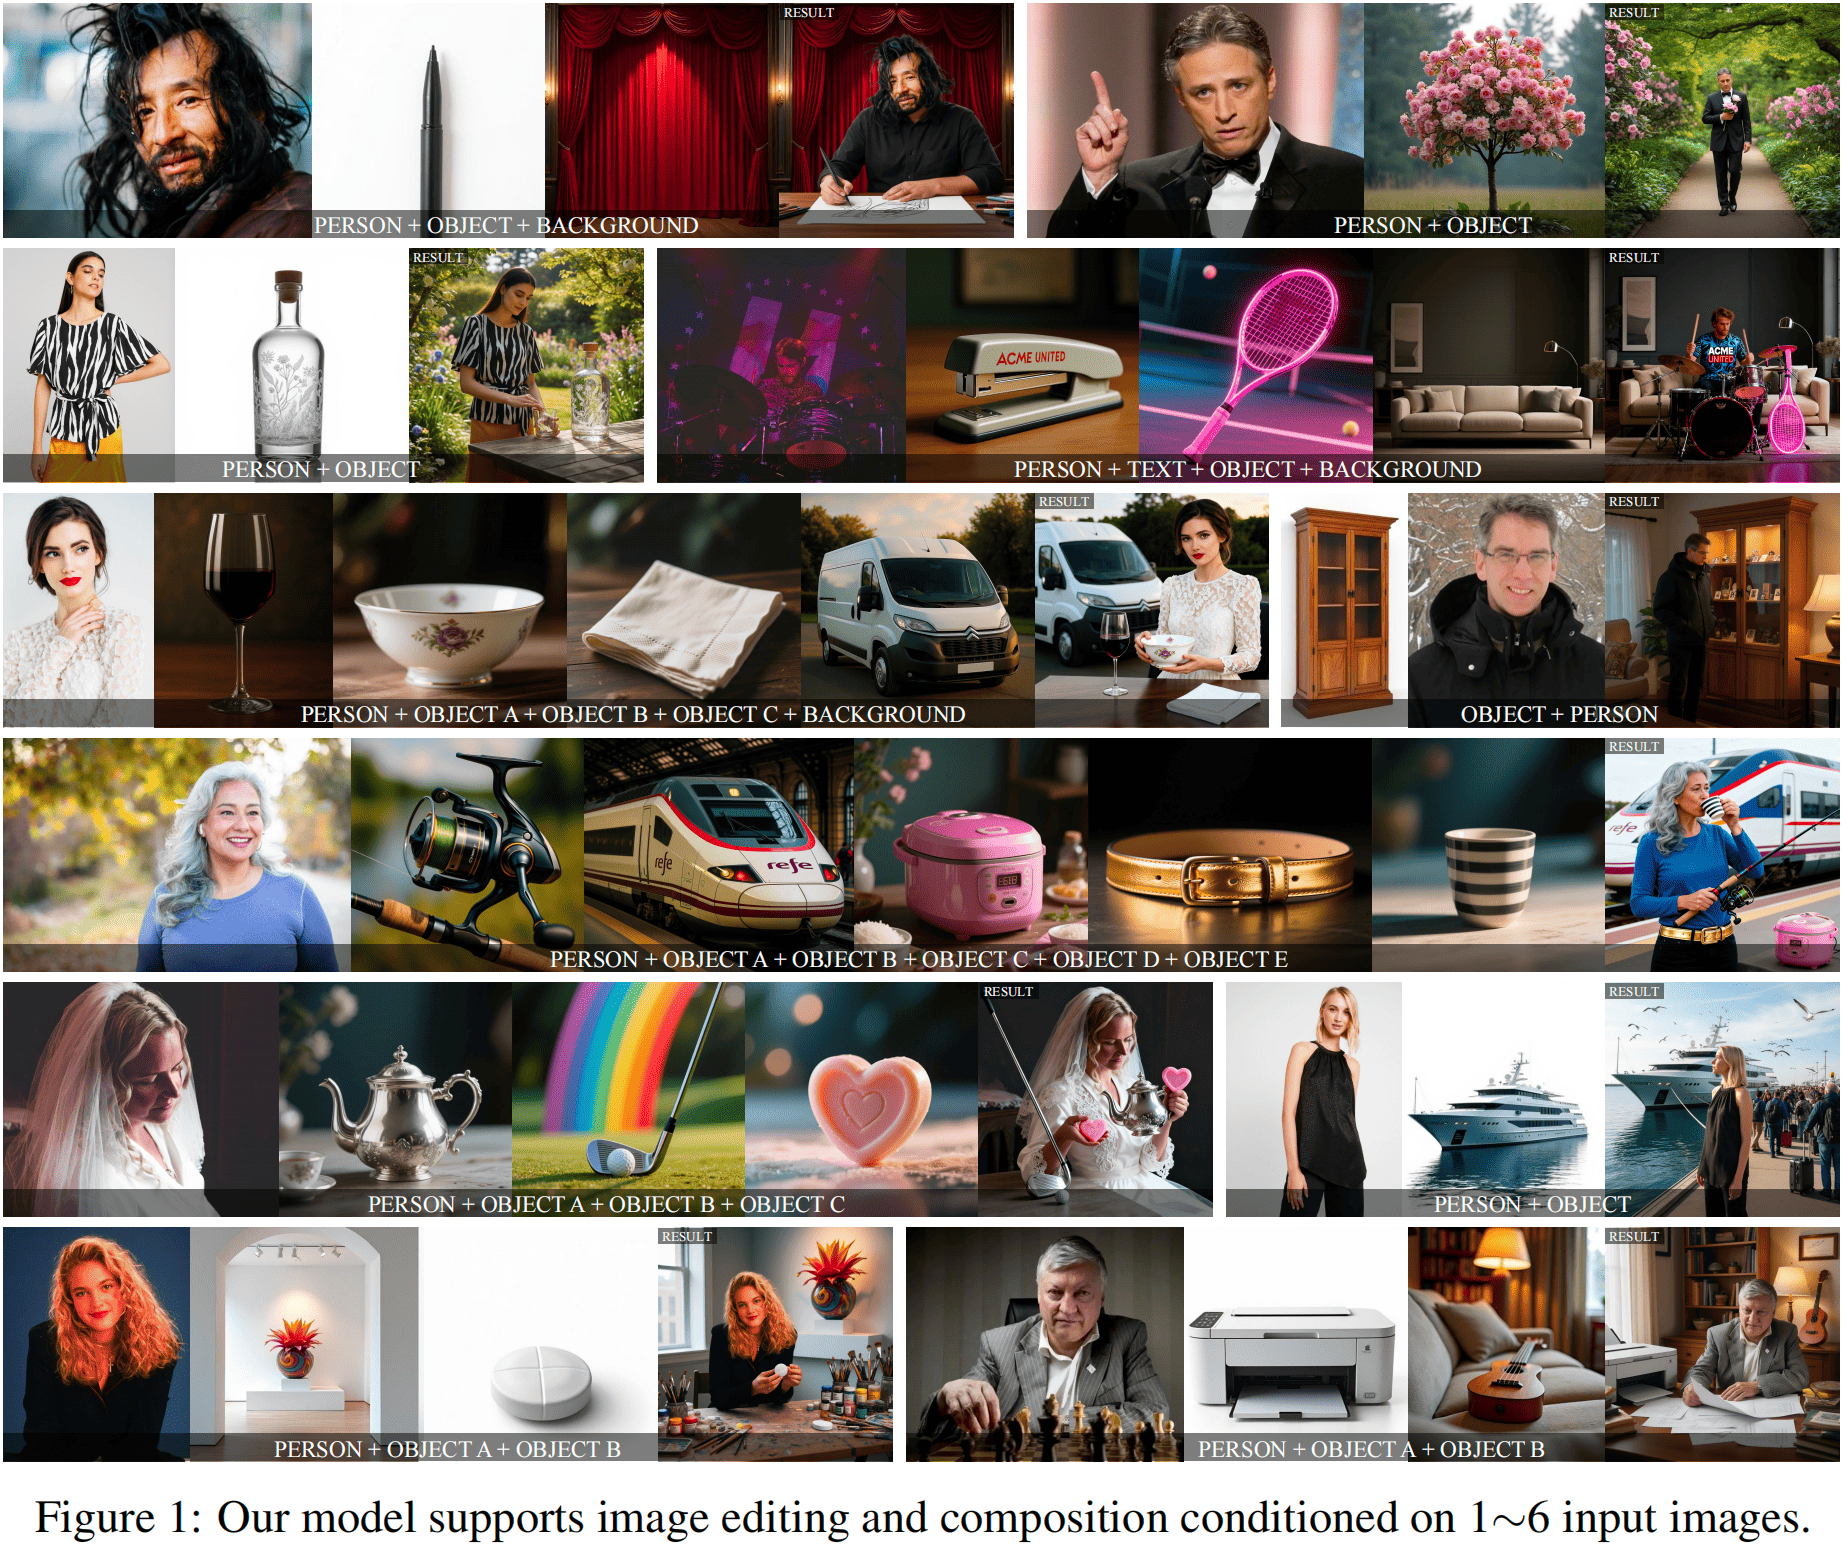
  • UniPic-2(README) — SD3.5M-Kontext and MetaQuery variants based on Efficient Architectures with Diffusion Post-Training, delivering state-of-the-art performance in text-to-image generation, fine-grained image editing, and multimodal reasoning.
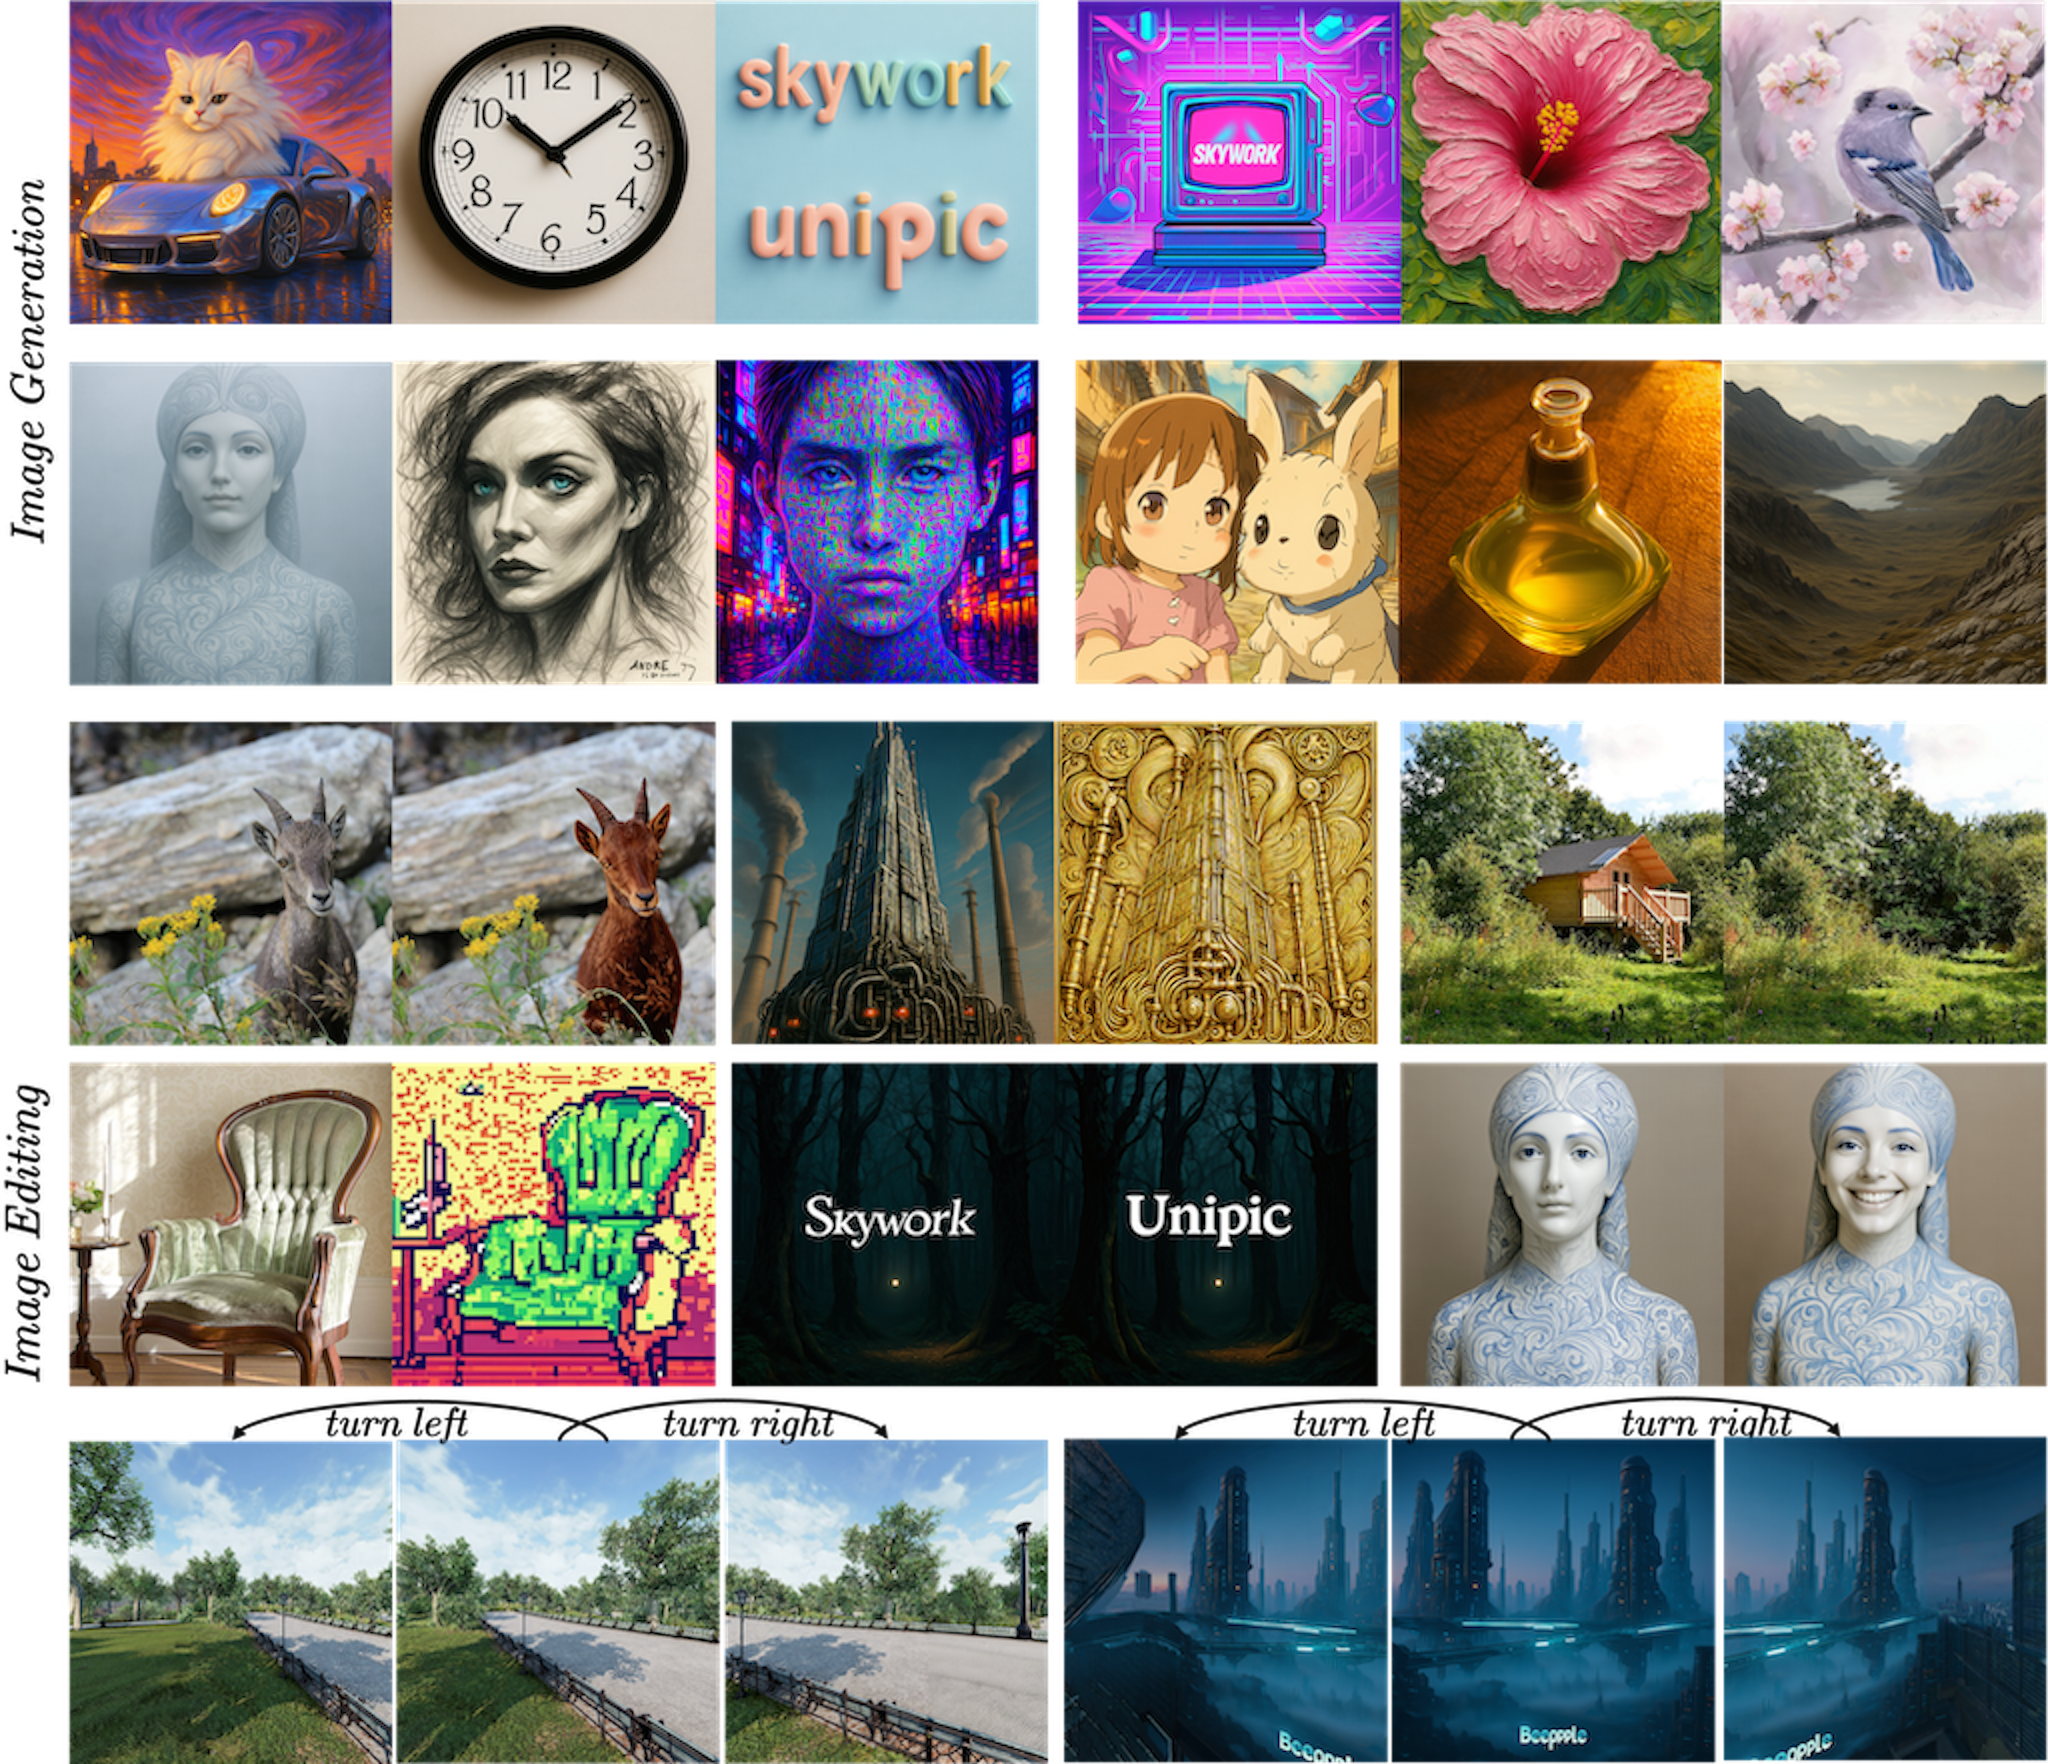
  • UniPic-1(README) — 1.5B parameters, Unified Autoregressive Modeling for joint visual understanding and generation, enabling a single transformer to handle both perception and synthesis tasks.


🔥 Latest News

Date Update
2026-01-09 Released UniPic-3 — 🔥 Open-source SOTA multi-image editing model. Support single & multi-image editing, 1–6 inputs, 8-step / 12.5× faster inference
2025-08-13 Released UniPic-2 — Unified Model Weights with Diffusion-based Post-Training
2025-07-30 Released UniPic-1 — Autoregressive unified modeling from scratch

✨ Key Features

  • 🎨 Text-to-Image Generation — High-fidelity synthesis from natural language prompts.
  • 🛠 Image Editing — Seamless inpainting, outpainting, and object manipulation.
  • 🖼 Image Understanding — Robust perception capabilities for various visual tasks.
  • ⚡ Efficient Architecture — Optimized for both accuracy and deployability.

📜 License

This project is licensed under the MIT License — see the LICENSE file for details.


排名相邻
同类项目