top CVPR 2025 papers

👋 hello
Computer Vision and Pattern Recognition is a massive conference. In 2025 alone, 13,008 papers were submitted, and 2,878 were accepted. I created this repository to help you search for crème de la crème of CVPR publications. If the paper you are looking for is not on my short list, take a peek at the full list of accepted papers.
🗞️ papers and posters
🔥 - highlighted papers
3d vision
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/33969.png?t=1748740040.9726639)
[🔥 VGGT: Visual Geometry Grounded Transformer](https://arxiv.org/abs/2503.11651)
Jianyuan Wang, Minghao Chen, Nikita Karaev, Andrea Vedaldi, Christian Rupprecht, David Novotny
[[paper](https://arxiv.org/abs/2503.11651)] [[code](https://github.com/facebookresearch/vggt)] [[video](https://youtu.be/7ZYwJEpCUUA)] [[demo](https://huggingface.co/spaces/facebook/vggt)]
Topic: 3D Vision
Session: Fri 13 Jun 2 p.m. PDT — 4 p.m. PDT Poster Session 2 #86
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/34871.png?t=1748708079.0490072)
[🔥 MASt3R-SLAM: Real-Time Dense SLAM with 3D Reconstruction Priors](https://arxiv.org/abs/2412.12392)
Riku Murai, Eric Dexheimer, Andrew J. Davison
[[paper](https://arxiv.org/abs/2412.12392)] [[code](https://github.com/rmurai0610/MASt3R-SLAM)] [[video](https://www.youtube.com/watch?v=wozt71NBFTQ)]
Topic: 3D Vision
Session: Sat 14 Jun 3 p.m. PDT — 5 p.m. PDT Poster Session 4 #83
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/35013.png?t=1748718962.8355792)
[RelationField: Relate Anything in Radiance Fields](https://arxiv.org/abs/2412.13652)
Sebastian Koch, Johanna Wald, Mirco Colosi, Narunas Vaskevicius, Pedro Hermosilla, Federico Tombari, Timo Ropinski
[[paper](https://arxiv.org/abs/2412.13652)] [[code](https://github.com/boschresearch/relationfield)] [[video](https://youtu.be/8XxWzoWnYT0)]
Topic: 3D Vision
Session: Sun 15 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 5 #190
depth estimation
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/32554.png?t=1748195633.2703488)
[UniK3D: Universal Camera Monocular 3D Estimation](https://arxiv.org/abs/2503.16591)
Luigi Piccinelli, Christos Sakaridis, Mattia Segu, Yung-Hsu Yang, Siyuan Li, Wim Abbeloos, Luc Van Gool
[[paper](https://arxiv.org/abs/2503.16591)] [[code](https://github.com/lpiccinelli-eth/UniK3D)] [[demo](https://huggingface.co/spaces/lpiccinelli/UniK3D-demo)]
Topic: Depth Estimation
Session: Fri 13 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 1 #80
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/33026.png?t=1749131392.5907311)
[🔥 DepthCrafter: Generating Consistent Long Depth Sequences for Open-world Videos](https://arxiv.org/abs/2409.02095)
Wenbo Hu, Xiangjun Gao, Xiaoyu Li, Sijie Zhao, Xiaodong Cun, Yong Zhang, Long Quan, Ying Shan
[[paper](https://arxiv.org/abs/2409.02095)] [[code](https://github.com/Tencent/DepthCrafter)] [[demo](https://huggingface.co/spaces/tencent/DepthCrafter)]
Topic: Depth Estimation
Session: Fri 13 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 1 #171
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/33862.png?t=1747997885.3577623)
[Video Depth Anything: Consistent Depth Estimation for Super-Long Videos](https://arxiv.org/abs/2501.12375)
Sili Chen, Hengkai Guo, Shengnan Zhu, Feihu Zhang, Zilong Huang, Jiashi Feng, Bingyi Kang
[[paper](https://arxiv.org/abs/2501.12375)] [[code](https://github.com/DepthAnything/Video-Depth-Anything)] [[demo](https://huggingface.co/spaces/depth-anything/Video-Depth-Anything)]
Topic: Depth Estimation
Session: Sun 15 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 5 #169
explainability and interpretability
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/34644.png?t=1748853080.0173087)
[🔥 Interpreting Object-level Foundation Models via Visual Precision Search](https://arxiv.org/abs/2411.16198)
Ruoyu Chen, Siyuan Liang, Jingzhi Li, Shiming Liu, Maosen Li, Zhen Huang, Hua Zhang, Xiaochun Cao
[[paper](https://arxiv.org/abs/2411.16198)] [[code](https://github.com/RuoyuChen10/VPS)] [[colab](https://colab.research.google.com/github/RuoyuChen10/VPS/blob/main/tutorial/Grounding_DINO_explanation.ipynb)]
Topic: Explainability and Interpretability
Session: Sun 15 Jun 2 p.m. PDT — 4 p.m. PDT Poster Session 6 #372
gaze target estimation
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/34852.png?t=1748847619.7422361)
[🔥 Gaze-LLE: Gaze Target Estimation via Large-Scale Learned Encoders](https://arxiv.org/abs/2412.09586)
Fiona Ryan, Ajay Bati, Sangmin Lee, Daniel Bolya, Judy Hoffman, James M. Rehg
[[paper](https://arxiv.org/abs/2412.09586)] [[code](https://github.com/fkryan/gazelle)] [[demo](https://huggingface.co/spaces/fffiloni/Gaze-LLE)] [[colab](https://colab.research.google.com/drive/1TSoyFvNs1-au9kjOZN_fo5ebdzngSPDq?usp=sharing)]
Topic: Gaze Target Estimation
Session: Sun 15 Jun 2 p.m. PDT — 4 p.m. PDT Poster Session 6 #98
generative models
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/33479.png?t=1748410877.7850628)
[MMAudio: Taming Multimodal Joint Training for High-Quality Video-to-Audio Synthesis](https://arxiv.org/abs/2412.15322)
Ho Kei Cheng, Masato Ishii, Akio Hayakawa, Takashi Shibuya, Alexander Schwing, Yuki Mitsufuji
[[paper](https://arxiv.org/abs/2412.15322)] [[code](https://github.com/hkchengrex/MMAudio)] [[video](https://youtu.be/YElewUT2M4M)] [[demo](https://huggingface.co/spaces/hkchengrex/MMAudio)] [[colab](https://colab.research.google.com/drive/1TAaXCY2-kPk4xE4PwKB3EqFbSnkUuzZ8?usp=sharing)]
Topic: Generative Models
Session: Sun 15 Jun 2 p.m. PDT — 4 p.m. PDT Poster Session 6 #260
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/32785.png?t=1748780647.7372541)
[SemanticDraw: Towards Real-Time Interactive Content Creation from Image Diffusion Models](https://arxiv.org/abs/2403.09055)
Jaerin Lee, Daniel Sungho Jung, Kanggeon Lee, Kyoung Mu Lee
[[paper](https://arxiv.org/abs/2403.09055)] [[code](https://github.com/ironjr/semantic-draw)] [[video](https://www.youtube.com/watch?v=qR06iiaG5nc)] [[demo](https://huggingface.co/spaces/ironjr/semantic-draw-canvas-sdxl)] [[colab](https://colab.research.google.com/github/camenduru/SemanticPalette-jupyter/blob/main/SemanticPalette_jupyter.ipynb)]
Topic: Generative Models
Session: Sat 14 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 3 #226
image matching
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/34813.png?t=1748519375.4086587)
[MINIMA: Modality Invariant Image Matching](https://arxiv.org/abs/2412.19412)
Jiangwei Ren, Xingyu Jiang, Zizhuo Li, Dingkang Liang, Xin Zhou, Xiang Bai
[[paper](https://arxiv.org/abs/2412.19412)] [[code](https://github.com/LSXI7/MINIMA)] [[demo](https://huggingface.co/spaces/lsxi77777/MINIMA)]
Topic: Image Matching
Session: Sun 15 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 5 #190
image vectorization
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/34467.png?t=1748720373.8849306)
[Layered Image Vectorization via Semantic Simplification](https://arxiv.org/abs/2406.05404)
Zhenyu Wang, Jianxi Huang, Zhida Sun, Yuanhao Gong, Daniel Cohen-Or, Min Lu
[[paper](https://arxiv.org/abs/2406.05404)] [[code](https://github.com/SZUVIZ/layered_vectorization)] [[video](https://youtu.be/oUYQKjDlwCw)]
Topic: Image Vectorization
Session: Fri 13 Jun 2 p.m. PDT — 4 p.m. PDT Poster Session 2 #226
object tracking
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/35010.png?t=1748684123.2752578)
[🔥 MITracker: Multi-View Integration for Visual Object Tracking](https://arxiv.org/abs/2502.20111)
Mengjie Xu, Yitao Zhu, Haotian Jiang, Jiaming Li, Zhenrong Shen, Sheng Wang, Haolin Huang, Xinyu Wang, Qing Yang, Han Zhang, Qian Wang
[[paper](https://arxiv.org/abs/2502.20111)] [[code](https://github.com/XuM007/MITracker)]
Topic: Object Tracking
Session: Sun 15 Jun 2 p.m. PDT — 4 p.m. PDT Poster Session 6 #98
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/33882.png?t=1748536728.1331344)
[Multiple Object Tracking as ID Prediction](https://arxiv.org/abs/2403.16848)
Ruopeng Gao, Ji Qi, Limin Wang
[[paper](https://arxiv.org/abs/2403.16848)] [[code](https://github.com/MCG-NJU/MOTIP)]
Topic: Object Tracking
Session: Sun 15 Jun 2 p.m. PDT — 4 p.m. PDT Poster Session 6 #163
[EdgeTAM: On-Device Track Anything Model](https://arxiv.org/abs/2501.07256)
Chong Zhou, Chenchen Zhu, Yunyang Xiong, Saksham Suri, Fanyi Xiao, Lemeng Wu, Raghuraman Krishnamoorthi, Bo Dai, Chen Change Loy, Vikas Chandra, Bilge Soran
[[paper](https://arxiv.org/abs/2501.07256)] [[code](https://github.com/facebookresearch/EdgeTAM)] [[demo](https://huggingface.co/spaces/facebook/EdgeTAM)]
Topic: Object Tracking
Session: Sat 14 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 3 #304
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/35133.png?t=1748777099.726237)
[A Distractor-Aware Memory for Visual Object Tracking with SAM2](https://arxiv.org/abs/2411.17576)
Jovana Videnovic, Alan Lukezic, Matej Kristan
[[paper](https://arxiv.org/abs/2411.17576)] [[code](https://github.com/jovanavidenovic/DAM4SAM)]
Topic: Object Tracking
Session: Sun 15 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 5 #309
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/32888.png?t=1747453263.5318122)
[From Poses to Identity: Training-Free Person Re-Identification via Feature Centralization](https://arxiv.org/abs/2503.00938)
Chao Yuan, Guiwei Zhang, Changxiao Ma, Tianyi Zhang, Guanglin Niu
[[paper](https://arxiv.org/abs/2503.00938)] [[code](https://github.com/yuanc3/Pose2ID)]
Topic: Object Tracking
Session: Sun 15 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 5 #190
open-world detection
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/35020.png?t=1748563484.5053573)
[🔥 Towards Zero-Shot Anomaly Detection and Reasoning with Multimodal Large Language Models](https://arxiv.org/abs/2502.07601)
Jiacong Xu, Shao-Yuan Lo, Bardia Safaei, Vishal M. Patel, Isht Dwivedi
[[paper](https://arxiv.org/abs/2502.07601)] [[code](https://github.com/honda-research-institute/Anomaly-OneVision)] [[video](https://www.youtube.com/watch?v=b3-qGTm23eA)]
Topic: Open-World Detection
Session: Sat 14 Jun 3 p.m. PDT — 5 p.m. PDT Poster Session 4 #435
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/32802.png?t=1748865568.2500262)
[🔥 Compositional Caching for Training-free Open-vocabulary Attribute Detection](https://arxiv.org/abs/2503.19145)
Marco Garosi, Alessandro Conti, Gaowen Liu, Elisa Ricci, Massimiliano Mancini
[[paper](https://arxiv.org/abs/2503.19145)] [[code](https://github.com/marco-garosi/ComCa)] [[video](https://youtu.be/ruHSAGemMa8)]
Topic: Open-World Detection
Session: Sat 14 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 3 #426
pose estimation
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/35057.png?t=1748706748.0220559)
[🔥 Reconstructing Humans with a Biomechanically Accurate Skeleton](https://arxiv.org/abs/2503.21751)
Yan Xia, Xiaowei Zhou, Etienne Vouga, Qixing Huang, Georgios Pavlakos
[[paper](https://arxiv.org/abs/2503.21751)] [[code](https://github.com/IsshikiHugh/HSMR)] [[demo](https://huggingface.co/spaces/IsshikiHugh/HSMR)] [[colab](https://colab.research.google.com/drive/1RDA9iKckCDKh_bbaKjO8bQ0-Lv5fw1CB?usp=sharing)]
Topic: Pose Estimation
Session: Fri 13 Jun 2 p.m. PDT — 4 p.m. PDT Poster Session 2 #91
segmentation
[](https://storage.googleapis.com/com-roboflow-marketing/cvpr-2025-posters/IMG_4803.JPG)
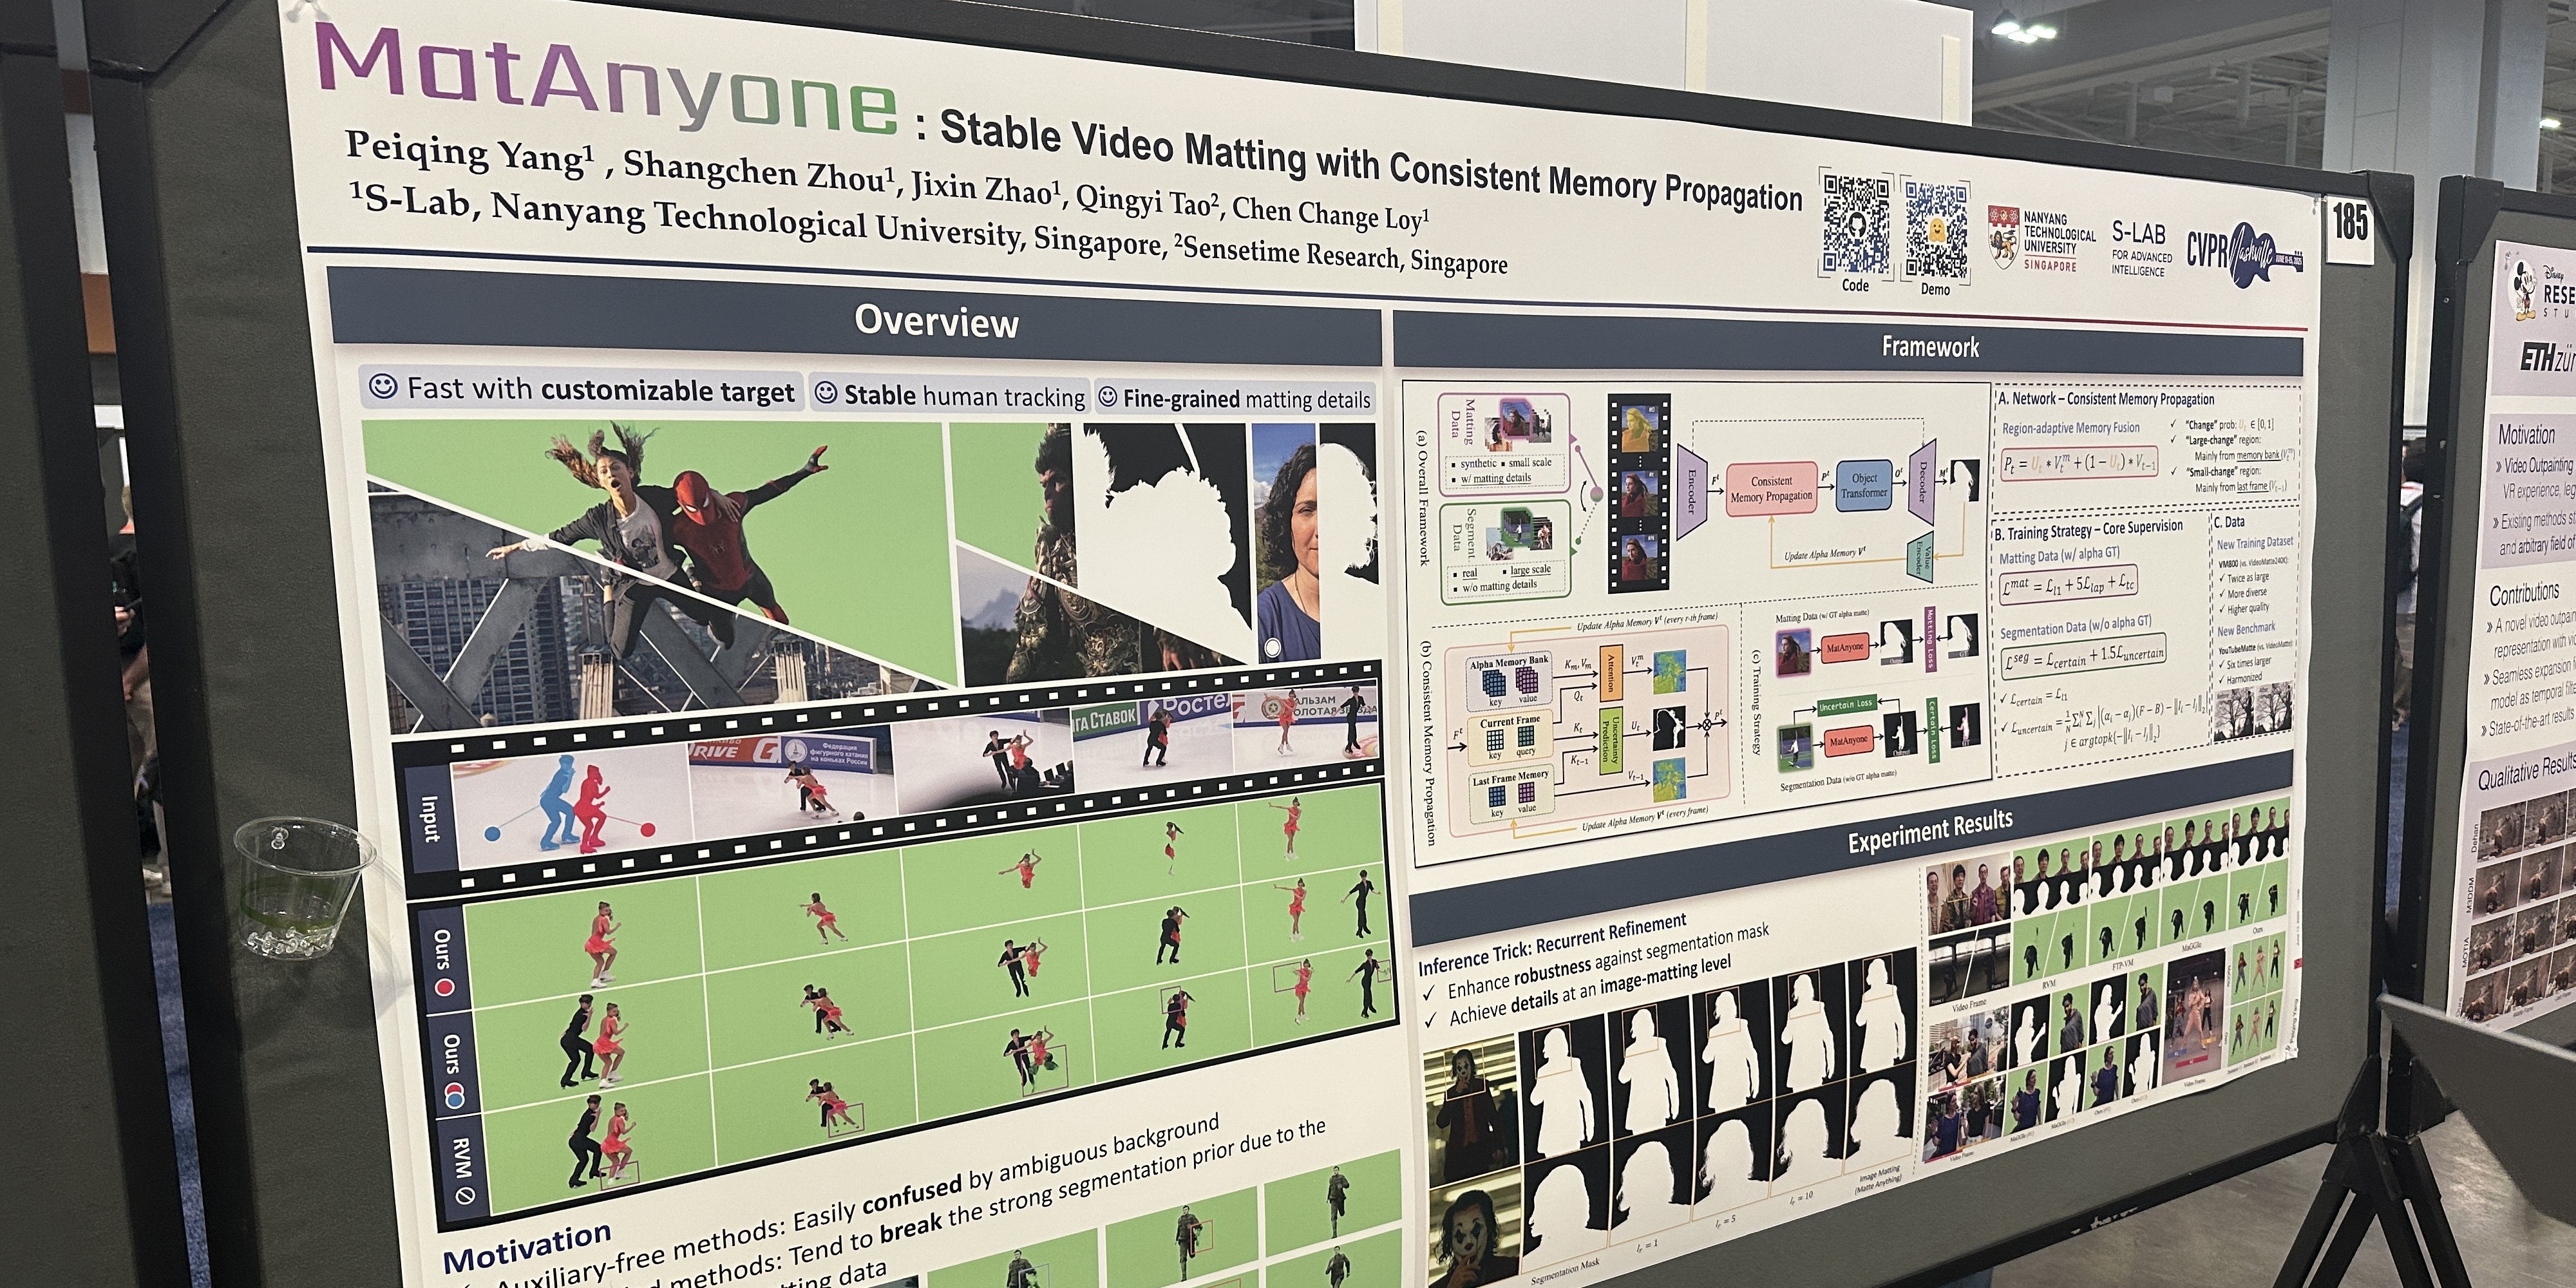
[MatAnyone: Stable Video Matting with Consistent Memory Propagation](https://arxiv.org/abs/2501.14677)
Peiqing Yang, Shangchen Zhou, Jixin Zhao, Qingyi Tao, Chen Change Loy
[[paper](https://arxiv.org/abs/2501.14677)] [[code](https://github.com/pq-yang/MatAnyone)] [[video](https://www.youtube.com/watch?v=oih0Zk-UW18)] [[demo](https://huggingface.co/spaces/PeiqingYang/MatAnyone)]
Topic: Segmentation
Session: Fri 13 Jun 2 p.m. PDT — 4 p.m. PDT Poster Session 2 #185
stereo matching
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/34330.png?t=1748714664.9139624)
[🔥 FoundationStereo: Zero-Shot Stereo Matching](https://arxiv.org/abs/2501.09898)
Bowen Wen, Matthew Trepte, Joseph Aribido, Jan Kautz, Orazio Gallo, Stan Birchfield
[[paper](https://arxiv.org/abs/2501.09898)] [[code](https://github.com/NVlabs/FoundationStereo)] [[video](https://www.youtube.com/watch?v=R7RgHxEXB3o)]
Topic: Stereo Matching
Session: Fri 13 Jun 2 p.m. PDT — 4 p.m. PDT Poster Session 2 #81
video understanding
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/32544.png?t=1748596202.019788)
[Towards Universal Soccer Video Understanding](https://arxiv.org/abs/2412.01820)
Jiayuan Rao, Haoning Wu, Hao Jiang, Ya Zhang, Yanfeng Wang, Weidi Xie
[[paper](https://arxiv.org/abs/2412.01820)] [[code](https://github.com/jyrao/UniSoccer)]
Topic: Video Understanding
Session: Fri 13 Jun 2 p.m. PDT — 4 p.m. PDT Poster Session 2 #185
vision-language models
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/32887.png?t=1747896029.4399107)
[FastVLM: Efficient Vision Encoding for Vision Language Models](https://arxiv.org/abs/2412.13303)
Pavan Kumar Anasosalu Vasu, Fartash Faghri, Chun-Liang Li, Cem Koc, Nate True, Albert Antony, Gokul Santhanam, James Gabriel, Peter Grasch, Oncel Tuzel, Hadi Pouransari
[[paper](https://arxiv.org/abs/2412.13303)] [[code](https://github.com/apple/ml-fastvlm)]
Topic: Vision-Language Models
Session: Sat 14 Jun 3 p.m. PDT — 5 p.m. PDT Poster Session 4 #378
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/33073.png?t=1748883064.876014)
[🔥 Molmo and PixMo: Open Weights and Open Data for State-of-the-Art Vision-Language Models](https://arxiv.org/abs/2409.17146)
Matt Deitke, Christopher Clark, Sangho Lee, Rohun Tripathi, Yue Yang, Jae Sung Park, Mohammadreza Salehi, Niklas Muennighoff, Kyle Lo, Luca Soldaini, Jiasen Lu, Taira Anderson, Erin Bransom, Kiana Ehsani, Huong Ngo, YenSung Chen, Ajay Patel, Mark Yatskar, Chris Callison-Burch, Andrew Head, Rose Hendrix, Favyen Bastani, Eli VanderBilt, Nathan Lambert, Yvonne Chou, Arnavi Chheda, Jenna Sparks, Sam Skjonsberg, Michael Schmitz, Aaron Sarnat, Byron Bischoff, Pete Walsh, Chris Newell, Piper Wolters, Tanmay Gupta, Kuo-Hao Zeng, Jon Borchardt, Dirk Groeneveld, Crystal Nam, Sophie Lebrecht, Caitlin Wittlif, Carissa Schoenick, Oscar Michel, Ranjay Krishna, Luca Weihs, Noah A. Smith, Hannaneh Hajishirzi, Ross Girshick, Ali Farhadi, Aniruddha Kembhavi
[[paper](https://arxiv.org/abs/2409.17146)] [[demo](https://huggingface.co/spaces/akhaliq/Molmo-7B-D-0924)]
Topic: Vision-Language Models
Session: Fri 13 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 1 #80
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/34510.png?t=1748805761.17)
[🔥 SAMWISE: Infusing Wisdom in SAM2 for Text-Driven Video Segmentation](https://arxiv.org/abs/2411.17646)
Claudia Cuttano, Gabriele Trivigno, Gabriele Rosi, Carlo Masone, Giuseppe Averta
[[paper](https://arxiv.org/abs/2411.17646)] [[code](https://github.com/ClaudiaCuttano/SAMWISE)] [[video](https://youtu.be/OL3xvzFyXCc)]
Topic: Vision-Language Models
Session: Fri 13 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 1 #308
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/34048.png?t=1748839405.5943303)
[VisionArena: 230K Real World User-VLM Conversations with Preference Labels](https://arxiv.org/abs/2412.08687)
Christopher Chou, Lisa Dunlap, Koki Mashita, Krishna Mandal, Trevor Darrell, Ion Stoica, Joseph E. Gonzalez, Wei-Lin Chiang
[[paper](https://arxiv.org/abs/2412.08687)] [[demo](https://huggingface.co/datasets/lmarena-ai/VisionArena-Battle)]
Topic: Vision-Language Models
Session: Fri 13 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 1 #353
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/33482.png?t=1748620034.1782746)
[DINOv2 Meets Text: A Unified Framework for Image- and Pixel-Level Vision-Language Alignment](https://arxiv.org/abs/2412.16334)
Cijo Jose, Théo Moutakanni, Dahyun Kang, Federico Baldassarre, Timothée Darcet, Hu Xu, Daniel Li, Marc Szafraniec, Michaël Ramamonjisoa, Maxime Oquab, Oriane Siméoni, Huy V. Vo, Patrick Labatut, Piotr Bojanowski
[[paper](https://arxiv.org/abs/2412.16334)] [[code](https://github.com/facebookresearch/dinov2)] [[video](https://youtu.be/qNsAgsvhbw4)] [[colab](https://colab.research.google.com/github/facebookresearch/dinov2/blob/main/notebooks/dinotxt.ipynb)]
Topic: Vision-Language Models
Session: Sun 15 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 5 #169
visual agents
[](https://storage.googleapis.com/com-roboflow-marketing/cvpr-2025-posters/IMG_4847_.JPG)
[Magma: A Foundation Model for Multimodal AI Agents](https://arxiv.org/abs/2502.13130)
Jianwei Yang, Reuben Tan, Qianhui Wu, Ruijie Zheng, Baolin Peng, Yongyuan Liang, Yu Gu, Mu Cai, Seonghyeon Ye, Joel Jang, Yuquan Deng, Lars Liden, Jianfeng Gao
[[paper](https://arxiv.org/abs/2502.13130)] [[code](https://github.com/microsoft/Magma)] [[video](https://www.youtube.com/watch?v=SbfzvUU5yM8)] [[demo](https://huggingface.co/spaces/microsoft/Magma-UI)]
Topic: Visual Agents
Session: Sat 14 Jun 8:30 a.m. PDT — 10:30 a.m. PDT Poster Session 3 #340
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/33472.png?t=1748798588.1133444)
[ShowUI: One Vision-Language-Action Model for GUI Visual Agent](https://arxiv.org/abs/2411.17465)
Kevin Qinghong Lin, Linjie Li, Difei Gao, Zhengyuan Yang, Shiwei Wu, Zechen Bai, Weixian Lei, Lijuan Wang, Mike Zheng Shou
[[paper](https://arxiv.org/abs/2411.17465)] [[code](https://github.com/showlab/ShowUI)] [[demo](https://huggingface.co/spaces/showlab/ShowUI)]
Topic: Visual Agents
Session: Sat 14 Jun 3 p.m. PDT — 5 p.m. PDT Poster Session 4 #352
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202025/32818.png?t=1748727014.6249733)
[Visual Agentic AI for Spatial Reasoning with a Dynamic API](https://arxiv.org/abs/2502.06787)
Damiano Marsili, Rohun Agrawal, Yisong Yue, Georgia Gkioxari
[[paper](https://arxiv.org/abs/2502.06787)] [[code](https://github.com/damianomarsili/VADAR)] [[video](https://youtu.be/zYFlDu_zsEs)]
Topic: Visual Agents
Session: Sat 14 Jun 3 p.m. PDT — 5 p.m. PDT Poster Session 4 #352
🦸 contribution
We would love your help in making this repository even better! If you know of an amazing paper that isn't listed here, or if you have any suggestions for improvement, feel free to open an issue or submit a pull request.