top CVPR 2024 papers
👋 hello
Computer Vision and Pattern Recognition is a massive conference. In 2024 alone, 11,532 papers were submitted, and 2,719 were accepted. I created this repository to help you search for crème de la crème of CVPR publications. If the paper you are looking for is not on my short list, take a peek at the full list of accepted papers.
🗞️ papers and posters
🔥 - highlighted papers
3d from multi-view and sensors
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202024/31668.png?t=1717417393.7589533)
[🔥 SpatialTracker: Tracking Any 2D Pixels in 3D Space](https://arxiv.org/abs/2404.04319)
Yuxi Xiao, Qianqian Wang, Shangzhan Zhang, Nan Xue, Sida Peng, Yujun Shen, Xiaowei Zhou
[[paper](https://arxiv.org/abs/2404.04319)] [[code](https://github.com/henry123-boy/SpaTracker)]
Topic: 3D from multi-view and sensors
Session: Fri 21 Jun 1:30 p.m. EDT — 3 p.m. EDT #84
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202024/31616.png?t=1716470830.0209699)
[ViewDiff: 3D-Consistent Image Generation with Text-to-Image Models](https://arxiv.org/abs/2403.01807)
Lukas Höllein, Aljaž Božič, Norman Müller, David Novotny, Hung-Yu Tseng, Christian Richardt, Michael Zollhöfer, Matthias Nießner
[[paper](https://arxiv.org/abs/2403.01807)] [[code](https://github.com/facebookresearch/ViewDiff)] [[video](https://youtu.be/SdjoCqHzMMk)]
Topic: 3D from multi-view and sensors
Session: Wed 19 Jun 8 p.m. EDT — 9:30 p.m. EDT #20
[OmniGlue: Generalizable Feature Matching with Foundation Model Guidance](https://arxiv.org/abs/2405.12979)
Hanwen Jiang, Arjun Karpur, Bingyi Cao, Qixing Huang, Andre Araujo
[[paper](https://arxiv.org/abs/2405.12979)] [[code](https://github.com/google-research/omniglue)] [[demo](https://huggingface.co/spaces/qubvel-hf/omniglue)]
Topic: 3D from multi-view and sensors
Session: Fri 21 Jun 1:30 p.m. EDT — 3 p.m. EDT #32
deep learning architectures and techniques
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202024/30529.png?t=1717455193.7819567)
[🔥 Florence-2: Advancing a Unified Representation for a Variety of Vision Tasks](https://arxiv.org/pdf/2311.06242)
Bin Xiao, Haiping Wu, Weijian Xu, Xiyang Dai, Houdong Hu, Yumao Lu, Michael Zeng, Ce Liu, Lu Yuan
[[paper](https://arxiv.org/pdf/2311.06242)] [[video](https://youtu.be/cOlyA00K1ec)] [[demo](https://huggingface.co/spaces/gokaygokay/Florence-2)] [[colab](https://youtu.be/cOlyA00K1ec)]
Topic: Deep learning architectures and techniques
Session: Wed 19 Jun 8 p.m. EDT — 9:30 p.m. EDT #102
document analysis and understanding
[DocRes: A Generalist Model Toward Unifying Document Image Restoration Tasks](https://arxiv.org/abs/2405.04408)


Jiaxin Zhang, Dezhi Peng, Chongyu Liu, Peirong Zhang, Lianwen Jin


[[paper](https://arxiv.org/abs/2405.04408)] [[code](https://github.com/ZZZHANG-jx/DocRes)]  [[demo](https://huggingface.co/spaces/qubvel-hf/documents-restoration)]


Topic: Document analysis and understanding


Session: Thu 20 Jun 8 p.m. EDT — 9:30 p.m. EDT #101
efficient and scalable vision
[](https://github.com/SkalskiP/top-cvpr-2024-papers/assets/26109316/e95eac04-5a45-402c-885d-14395879abd3)
[🔥 EfficientSAM: Leveraged Masked Image Pretraining for Efficient Segment Anything](https://arxiv.org/abs/2312.00863)
Yunyang Xiong, Bala Varadarajan, Lemeng Wu, Xiaoyu Xiang, Fanyi Xiao, Chenchen Zhu, Xiaoliang Dai, Dilin Wang, Fei Sun, Forrest Iandola, Raghuraman Krishnamoorthi, Vikas Chandra
[[paper](https://arxiv.org/abs/2312.00863)] [[code](https://github.com/yformer/EfficientSAM)] [[demo](https://huggingface.co/spaces/SkalskiP/EfficientSAM)]
Topic: Efficient and scalable vision
Session: Thu 20 Jun 8 p.m. EDT — 9:30 p.m. EDT #144
[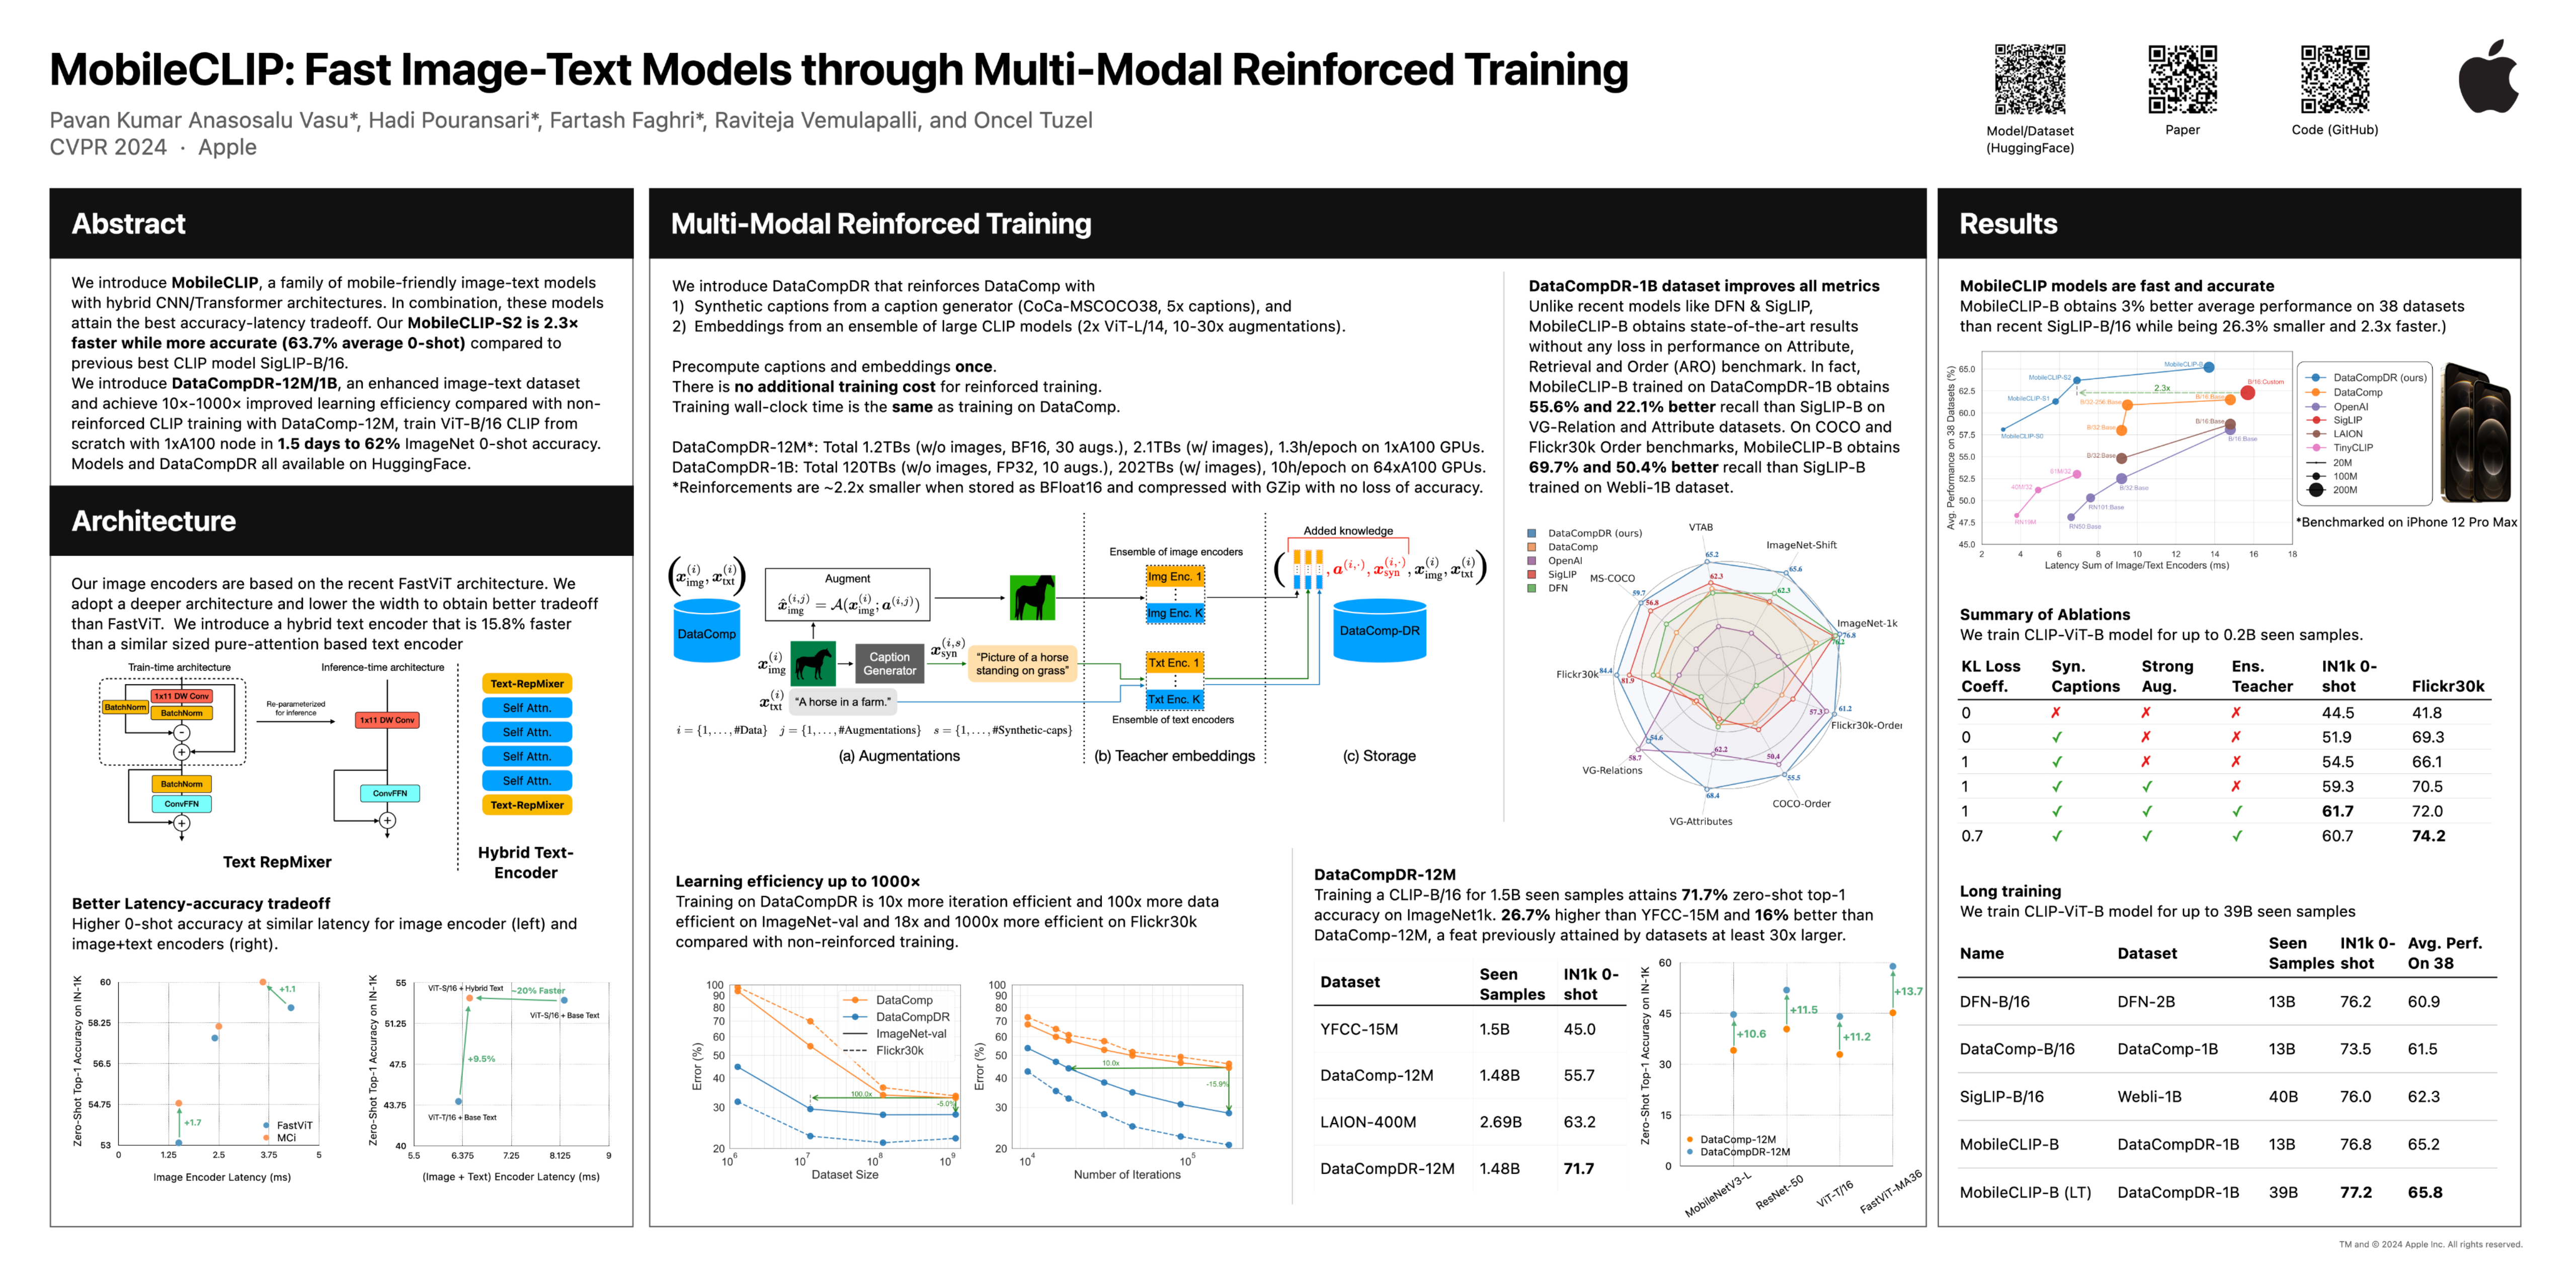](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202024/30022.png?t=1718402790.003817)
[MobileCLIP: Fast Image-Text Models through Multi-Modal Reinforced Training](https://arxiv.org/abs/2311.17049)
Pavan Kumar Anasosalu Vasu, Hadi Pouransari, Fartash Faghri, Raviteja Vemulapalli, Oncel Tuzel
[[paper](https://arxiv.org/abs/2311.17049)] [[code](https://github.com/apple/ml-mobileclip)] [[demo](https://huggingface.co/spaces/Xenova/webgpu-mobileclip)]
Topic: Efficient and scalable vision
Session: Thu 20 Jun 8 p.m. EDT — 9:30 p.m. EDT #130
explainable computer vision
[](https://github.com/SkalskiP/top-cvpr-2024-papers/assets/26109316/6d87318b-57c1-40c7-9de6-5cb47145e119)
[🔥 Describing Differences in Image Sets with Natural Language](https://arxiv.org/abs/2312.02974)
Lisa Dunlap, Yuhui Zhang, Xiaohan Wang, Ruiqi Zhong, Trevor Darrell, Jacob Steinhardt, Joseph E. Gonzalez, Serena Yeung-Levy
[[paper](https://arxiv.org/abs/2312.02974)] [[code](https://github.com/Understanding-Visual-Datasets/VisDiff)]
Topic: Explainable computer vision
Session: Fri 21 Jun 8 p.m. EDT — 9:30 p.m. EDT #115
image and video synthesis and generation
[DemoFusion: Democratising High-Resolution Image Generation With No $$$](https://arxiv.org/abs/2311.16973)
Ruoyi Du, Dongliang Chang, Timothy Hospedales, Yi-Zhe Song, Zhanyu Ma
[[paper](https://arxiv.org/abs/2311.16973)] [[code](https://github.com/PRIS-CV/DemoFusion)] [[demo](https://huggingface.co/spaces/radames/Enhance-This-DemoFusion-SDXL)] [[colab](https://colab.research.google.com/github/camenduru/DemoFusion-colab/blob/main/DemoFusion_colab.ipynb)]
Topic: Image and video synthesis and generation
Session: Wed 19 Jun 8 p.m. EDT — 9:30 p.m. EDT #132
[](https://github.com/SkalskiP/top-cvpr-2024-papers/assets/26109316/b0833f6b-6924-4f28-b409-ae85aaaa4dd6)
[🔥 DragDiffusion: Harnessing Diffusion Models for Interactive Point-based Image Editing](https://arxiv.org/abs/2306.14435)
Yujun Shi, Chuhui Xue, Jun Hao Liew, Jiachun Pan, Hanshu Yan, Wenqing Zhang, Vincent Y. F. Tan, Song Bai
[[paper](https://arxiv.org/abs/2306.14435)] [[code](https://github.com/Yujun-Shi/DragDiffusion)] [[video](https://youtu.be/rysOFTpDBhc)]
Topic: Image and video synthesis and generation
Session: Wed 19 Jun 8 p.m. EDT — 9:30 p.m. EDT #392
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202024/30657.png?t=1717473392.6694562)
[🔥 Visual Anagrams: Generating Multi-View Optical Illusions with Diffusion Models](https://arxiv.org/abs/2311.17919)
Daniel Geng, Inbum Park, Andrew Owens
[[paper](https://arxiv.org/abs/2311.17919)] [[code](https://github.com/dangeng/visual_anagrams)] [[colab](https://colab.research.google.com/github/dangeng/visual_anagrams/blob/main/notebooks/colab_demo_free_tier.ipynb)]
Topic: Image and video synthesis and generation
Session: Fri 21 Jun 8 p.m. EDT — 9:30 p.m. EDT #118
low-level vision
[](https://github.com/SkalskiP/top-cvpr-2024-papers/assets/26109316/8eb6b4f0-4ae6-4615-9921-f73fa2aa3766)
[XFeat: Accelerated Features for Lightweight Image Matching](https://arxiv.org/abs/2404.19174)
Guilherme Potje, Felipe Cadar, Andre Araujo, Renato Martins, Erickson R. Nascimento
[[paper](https://arxiv.org/abs/2404.19174)] [[code](https://github.com/verlab/accelerated_features)] [[video](https://youtu.be/RamC70IkZuI)] [[demo](https://huggingface.co/spaces/qubvel-hf/xfeat)] [[colab](https://colab.research.google.com/github/verlab/accelerated_features/blob/main/notebooks/xfeat_matching.ipynb)]
Topic: Low-level vision
Session: Wed 19 Jun 1:30 p.m. EDT — 3 p.m. EDT #245
[](https://github.com/SkalskiP/top-cvpr-2024-papers/assets/26109316/038bef8f-a6df-440d-9ebc-b58f69beb338)
[Robust Image Denoising through Adversarial Frequency Mixup](https://openaccess.thecvf.com/content/CVPR2024/html/Ryou_Robust_Image_Denoising_through_Adversarial_Frequency_Mixup_CVPR_2024_paper.html)
Donghun Ryou, Inju Ha, Hyewon Yoo, Dongwan Kim, Bohyung Han
[[paper](https://openaccess.thecvf.com/content/CVPR2024/html/Ryou_Robust_Image_Denoising_through_Adversarial_Frequency_Mixup_CVPR_2024_paper.html)] [[code](https://github.com/dhryougit/AFM)] [[video](https://youtu.be/zQ0pwFSk7uo)]
Topic: Low-level vision
Session: Wed 19 Jun 1:30 p.m. EDT — 3 p.m. EDT #250
multi-modal learning
[🔥 Improved Baselines with Visual Instruction Tuning](https://arxiv.org/abs/2310.03744)


Haotian Liu, Chunyuan Li, Yuheng Li, Yong Jae Lee


[[paper](https://arxiv.org/abs/2310.03744)] [[code](https://github.com/LLaVA-VL/LLaVA-NeXT)]


Topic: Multi-modal learning


Session: Fri 21 Jun 8 p.m. EDT — 9:30 p.m. EDT #209
recognition: categorization, detection, retrieval
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202024/31301.png?t=1717420504.9897285)
[DETRs Beat YOLOs on Real-time Object Detection](https://arxiv.org/abs/2304.08069)
Yian Zhao, Wenyu Lv, Shangliang Xu, Jinman Wei, Guanzhong Wang, Qingqing Dang, Yi Liu, Jie Chen
[[paper](https://arxiv.org/abs/2304.08069)] [[code](https://github.com/lyuwenyu/RT-DETR)] [[video](https://www.youtube.com/watch?v=UOc0qMSX4Ac)]
Topic: Recognition: Categorization, detection, retrieval
Session: Thu 20 Jun 8 p.m. EDT — 9:30 p.m. EDT #229
[](https://github.com/SkalskiP/top-cvpr-2024-papers/assets/26109316/f9023a28-aca5-4965-a194-984c62348dc0)
[YOLO-World: Real-Time Open-Vocabulary Object Detection](https://arxiv.org/abs/2401.17270)
Tianheng Cheng, Lin Song, Yixiao Ge, Wenyu Liu, Xinggang Wang, Ying Shan
[[paper](https://arxiv.org/abs/2401.17270)] [[code](https://github.com/AILab-CVC/YOLO-World)] [[video](https://youtu.be/X7gKBGVz4vs)] [[demo](https://huggingface.co/spaces/SkalskiP/YOLO-World)] [[colab](https://colab.research.google.com/github/roboflow-ai/notebooks/blob/main/notebooks/zero-shot-object-detection-with-yolo-world.ipynb)]
Topic: Recognition: Categorization, detection, retrieval
Session: Thu 20 Jun 8 p.m. EDT — 9:30 p.m. EDT #223
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202024/31732.png?t=1717298372.5822952)
[🔥 Object Recognition as Next Token Prediction](https://arxiv.org/abs/2312.02142)
Kaiyu Yue, Bor-Chun Chen, Jonas Geiping, Hengduo Li, Tom Goldstein, Ser-Nam Lim
[[paper](https://arxiv.org/abs/2312.02142)] [[code](https://github.com/kaiyuyue/nxtp)] [[video](https://youtu.be/xeI8dZIpoco)] [[colab](https://colab.research.google.com/drive/1pJX37LP5xGLDzD3H7ztTmpq1RrIBeWX3?usp=sharing)]
Topic: Recognition: Categorization, detection, retrieval
Session: Thu 20 Jun 8 p.m. EDT — 9:30 p.m. EDT #199
segmentation, grouping and shape analysis
[](https://github.com/SkalskiP/top-cvpr-2024-papers/assets/26109316/62d34981-73d6-49b2-8058-46ec99bac94d)
[🔥 RobustSAM: Segment Anything Robustly on Degraded Images](https://openaccess.thecvf.com/content/CVPR2024/html/Chen_RobustSAM_Segment_Anything_Robustly_on_Degraded_Images_CVPR_2024_paper.html)
Wei-Ting Chen, Yu-Jiet Vong, Sy-Yen Kuo, Sizhou Ma, Jian Wang
[[paper](https://openaccess.thecvf.com/content/CVPR2024/html/Chen_RobustSAM_Segment_Anything_Robustly_on_Degraded_Images_CVPR_2024_paper.html)] [[video](https://www.youtube.com/watch?v=Awukqkbs6zM)]
Topic: Segmentation, grouping and shape analysis
Session: Wed 19 Jun 1:30 p.m. EDT — 3 p.m. EDT #378
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202024/30253.png?t=1716781257.513028)
[🔥 Frozen CLIP: A Strong Backbone for Weakly Supervised Semantic Segmentation](https://openaccess.thecvf.com/content/CVPR2024/html/Zhang_Frozen_CLIP_A_Strong_Backbone_for_Weakly_Supervised_Semantic_Segmentation_CVPR_2024_paper.html)
Bingfeng Zhang, Siyue Yu, Yunchao Wei, Yao Zhao, Jimin Xiao
[[paper](https://openaccess.thecvf.com/content/CVPR2024/html/Zhang_Frozen_CLIP_A_Strong_Backbone_for_Weakly_Supervised_Semantic_Segmentation_CVPR_2024_paper.html)] [[code](https://github.com/zbf1991/WeCLIP)] [[video](https://youtu.be/Lh489nTm_M0)]
Topic: Segmentation, grouping and shape analysis
Session: Wed 19 Jun 1:30 p.m. EDT — 3 p.m. EDT #351
[](https://github.com/SkalskiP/top-cvpr-2024-papers/assets/26109316/2f2bf794-3981-48c8-992d-04dd32ee9ced)
[🔥 Semantic-aware SAM for Point-Prompted Instance Segmentation](https://arxiv.org/abs/2312.15895)
Zhaoyang Wei, Pengfei Chen, Xuehui Yu, Guorong Li, Jianbin Jiao, Zhenjun Han
[[paper](https://arxiv.org/abs/2312.15895)] [[code](https://github.com/zhaoyangwei123/SAPNet)] [[video](https://youtu.be/42-tJFmT7Ao)]
Topic: Segmentation, grouping and shape analysis
Session: Wed 19 Jun 1:30 p.m. EDT — 3 p.m. EDT #331
[🔥 In-Context Matting](https://arxiv.org/abs/2403.15789)
He Guo, Zixuan Ye, Zhiguo Cao, Hao Lu
[[paper](https://arxiv.org/abs/2403.15789)] [[code](https://github.com/tiny-smart/in-context-matting)]
Topic: Segmentation, grouping and shape analysis
Session: Wed 19 Jun 1:30 p.m. EDT — 3 p.m. EDT #343
[](https://github.com/SkalskiP/top-cvpr-2024-papers/assets/26109316/bfe79038-706d-491b-ac99-083f421dc5ec)
[🔥 General Object Foundation Model for Images and Videos at Scale](https://arxiv.org/abs/2312.09158)
Junfeng Wu, Yi Jiang, Qihao Liu, Zehuan Yuan, Xiang Bai, Song Bai
[[paper](https://arxiv.org/abs/2312.09158)] [[code](https://github.com/FoundationVision/GLEE)] [[video](https://www.youtube.com/watch?v=PSVhfTPx0GQ)]
Topic: Segmentation, grouping and shape analysis
Session: Wed 19 Jun 1:30 p.m. EDT — 3 p.m. EDT #350
self-supervised or unsupervised representation learning
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202024/30014.png?t=1717339970.9614518)
[🔥 InternVL: Scaling up Vision Foundation Models and Aligning for Generic Visual-Linguistic Tasks](https://arxiv.org/abs/2312.14238)
Zhe Chen, Jiannan Wu, Wenhai Wang, Weijie Su, Guo Chen, Sen Xing, Muyan Zhong, Qinglong Zhang, Xizhou Zhu, Lewei Lu, Bin Li, Ping Luo, Tong Lu, Yu Qiao, Jifeng Dai
[[paper](https://arxiv.org/abs/2312.14238)] [[code](https://github.com/OpenGVLab/InternVL)] [[demo](https://huggingface.co/spaces/OpenGVLab/InternVL)]
Topic: Self-supervised or unsupervised representation learning
Session: Fri 21 Jun 8 p.m. EDT — 9:30 p.m. EDT #412
video: low-level analysis, motion, and tracking
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202024/29590.png?t=1717456006.3308516)
[🔥 Matching Anything by Segmenting Anything](https://arxiv.org/abs/2406.04221)
Siyuan Li, Lei Ke, Martin Danelljan, Luigi Piccinelli, Mattia Segu, Luc Van Gool, Fisher Yu
[[paper](https://arxiv.org/abs/2406.04221)] [[code](https://github.com/siyuanliii/masa)] [[video](https://youtu.be/KDQVujKAWFQ)]
Topic: Video: Low-level analysis, motion, and tracking
Session: Thu 20 Jun 8 p.m. EDT — 9:30 p.m. EDT #421
[](https://github.com/SkalskiP/top-cvpr-2024-papers/assets/26109316/9711186c-b05b-472d-b095-d98dbe386171)
[DiffMOT: A Real-time Diffusion-based Multiple Object Tracker with Non-linear Prediction](https://arxiv.org/abs/2403.02075)
Weiyi Lv, Yuhang Huang, Ning Zhang, Ruei-Sung Lin, Mei Han, Dan Zeng
[[paper](https://arxiv.org/abs/2403.02075)] [[code](https://github.com/Kroery/DiffMOT)]
Topic: Video: Low-level analysis, motion, and tracking
Session: Thu 20 Jun 8 p.m. EDT — 9:30 p.m. EDT #455
vision, language, and reasoning
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202024/31492.png?t=1717327133.6073072)
[Alpha-CLIP: A CLIP Model Focusing on Wherever You Want](https://arxiv.org/abs/2312.03818)
Zeyi Sun, Ye Fang, Tong Wu, Pan Zhang, Yuhang Zang, Shu Kong, Yuanjun Xiong, Dahua Lin, Jiaqi Wang
[[paper](https://arxiv.org/abs/2312.03818)] [[code](https://github.com/SunzeY/AlphaCLIP)] [[video](https://youtu.be/QCEIKPZpZz0)] [[demo](https://huggingface.co/spaces/Zery/Alpha-CLIP_LLaVA-1.5)]
Topic: Vision, language, and reasoning
Session: Thu 20 Jun 1:30 p.m. EDT — 3 p.m. EDT #327
[🔥 Eyes Wide Shut? Exploring the Visual Shortcomings of Multimodal LLMs](https://arxiv.org/abs/2401.06209)
Shengbang Tong, Zhuang Liu, Yuexiang Zhai, Yi Ma, Yann LeCun, Saining Xie
[[paper](https://arxiv.org/abs/2401.06209)] [[code](https://github.com/tsb0601/MMVP)]
Topic: Vision, language, and reasoning
Session: Thu 20 Jun 1:30 p.m. EDT — 3 p.m. EDT #390
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202024/30109.png?t=1717509456.89997)
[🔥 LISA: Reasoning Segmentation via Large Language Model](https://arxiv.org/abs/2308.00692)
Xin Lai, Zhuotao Tian, Yukang Chen, Yanwei Li, Yuhui Yuan, Shu Liu, Jiaya Jia
[[paper](https://arxiv.org/abs/2308.00692)] [[code](https://github.com/dvlab-research/LISA)] [[demo](http://103.170.5.190:7870/)]
Topic: Vision, language, and reasoning
Session: Thu 20 Jun 1:30 p.m. EDT — 3 p.m. EDT #413
[](https://github.com/SkalskiP/top-cvpr-2024-papers/assets/26109316/53e03a08-4dd9-451a-975e-e3654fa5bc71)
[ViP-LLaVA: Making Large Multimodal Models Understand Arbitrary Visual Prompts](https://arxiv.org/abs/2312.00784)
Mu Cai, Haotian Liu, Dennis Park, Siva Karthik Mustikovela, Gregory P. Meyer, Yuning Chai, Yong Jae Lee
[[paper](https://arxiv.org/abs/2312.00784)] [[code](https://github.com/WisconsinAIVision/ViP-LLaVA)] [[video](https://youtu.be/j_l1bRQouzc)] [[demo](https://pages.cs.wisc.edu/~mucai/vip-llava.html)]
Topic: Vision, language, and reasoning
Session: Thu 20 Jun 1:30 p.m. EDT — 3 p.m. EDT #317
[](https://cvpr.thecvf.com/media/PosterPDFs/CVPR%202024/31040.png?t=1718300473.5736258)
[🔥 MMMU: A Massive Multi-discipline Multimodal Understanding and Reasoning Benchmark for Expert AGI](https://arxiv.org/abs/2311.16502)
Xiang Yue, Yuansheng Ni, Kai Zhang, Tianyu Zheng, Ruoqi Liu, Ge Zhang, Samuel Stevens, Dongfu Jiang, Weiming Ren, Yuxuan Sun, Cong Wei, Botao Yu, Ruibin Yuan, Renliang Sun, Ming Yin, Boyuan Zheng, Zhenzhu Yang, Yibo Liu, Wenhao Huang, Huan Sun, Yu Su, Wenhu Chen
[[paper](https://arxiv.org/abs/2311.16502)]
Topic: Vision, language, and reasoning
Session: Thu 20 Jun 1:30 p.m. EDT — 3 p.m. EDT #382
🦸 contribution
We would love your help in making this repository even better! If you know of an amazing paper that isn't listed here, or if you have any suggestions for improvement, feel free to open an issue or submit a pull request.