← 开源
Picsart-AI-Research

PAIR-Diffusion

[CVPR 2024] PAIR Diffusion: A Comprehensive Multimodal Object-Level Image Editor

ModelsVision modelsPython
在 GitHub 打开
增长势头
+024 小时新增 Star0.0%
522
Star
21
Fork
+0
本周
1
贡献者
创建于 2023-03-21 · 更新于 2026-10-13 · 今日第 17804 名
主要开发者
vidit98

Picsart-AI-Research/PAIR-Diffusion 排名第 17,804,有 522 个星标。

同类别比较

Picsart-AI-Research/PAIR-Diffusion 排名第 17,804,此处有 8 个同类条目;yl4579/StarGANv2-VC 排名第 17,795。

同类别比较
名称排名指标
HumanAIGC/Cloth2Tex17,758
语言:
Python
星标数:
524
分叉数:
140
简介:
Cloth2Tex: A Customized Cloth Texture Generation Pipeline for 3D Virtual Try-On
liusongxiang/StarGAN-Voice-Conversion17,786
语言:
Python
星标数:
523
分叉数:
92
简介:
This is a pytorch implementation of the paper: StarGAN-VC: Non-parallel many-to-many voice conversion with star generative adversarial networks
mcahny/Deep-Video-Inpainting17,787
语言:
Python
星标数:
523
分叉数:
94
简介:
Official pytorch implementation for "Deep Video Inpainting" (CVPR 2019)
yl4579/StarGANv2-VC17,795
语言:
Python
星标数:
523
分叉数:
110
简介:
StarGANv2-VC: A Diverse, Unsupervised, Non-parallel Framework for Natural-Sounding Voice Conversion
rikdz/GraphWriter17,841
语言:
Python
星标数:
521
分叉数:
91
简介:
Code for "Text Generation from Knowledge Graphs with Graph Transformers"
jdh-algo/JoyHallo17,856
语言:
Python
星标数:
520
分叉数:
51
简介:
JoyHallo: Digital human model for Mandarin
justchenhao/BIT_CD17,857
语言:
Python
星标数:
520
分叉数:
97
简介:
Official Pytorch Implementation of "Remote Sensing Image Change Detection with Transformers"
rshaojimmy/MultiModal-DeepFake17,860
语言:
Python
星标数:
520
分叉数:
44
简介:
[TPAMI 2024 & CVPR 2023] PyTorch code for DGM4: Detecting and Grounding Multi-Modal Media Manipulation and beyond
关键参数与规格
关键参数与规格
参数值
语言Python
类别Models
子类别Vision models
关键词Image production, Multimodal, Object detection, Visual understanding
星标数522
分叉数21
贡献者1
创建日期2023-03-21
更新日期2026-10-13
1 天星标数0
7 天星标数0
排名17,804
上次排名17,589
排名变化-215
7 天星标排名16,303
上次 7 天星标排名16,312
7 天星标排名变化9
总星标排名18,720
上次总星标排名18,696
总星标排名变化-24
国家USA
README 摘录

PAIR Diffusion: A Comprehensive Multimodal Object-Level Image Editor [ ] [ ] [ ] [ ] Vidit Goel 1 , Elia Peruzzo 1,2 , Yifan Jiang 3 , Dejia Xu 3 , Xingqian Xu 3 , Nicu Sebe 2 , Trevor Darrell 4 , Zhangyang Wang 1,3 and Humphrey Shi 1,5,6 Features All the operations below can be performed at an object level. Our framework is general and can be applied to any diffusion model. Multimodal control using reference images and text News [30/12/2023] Models and code released

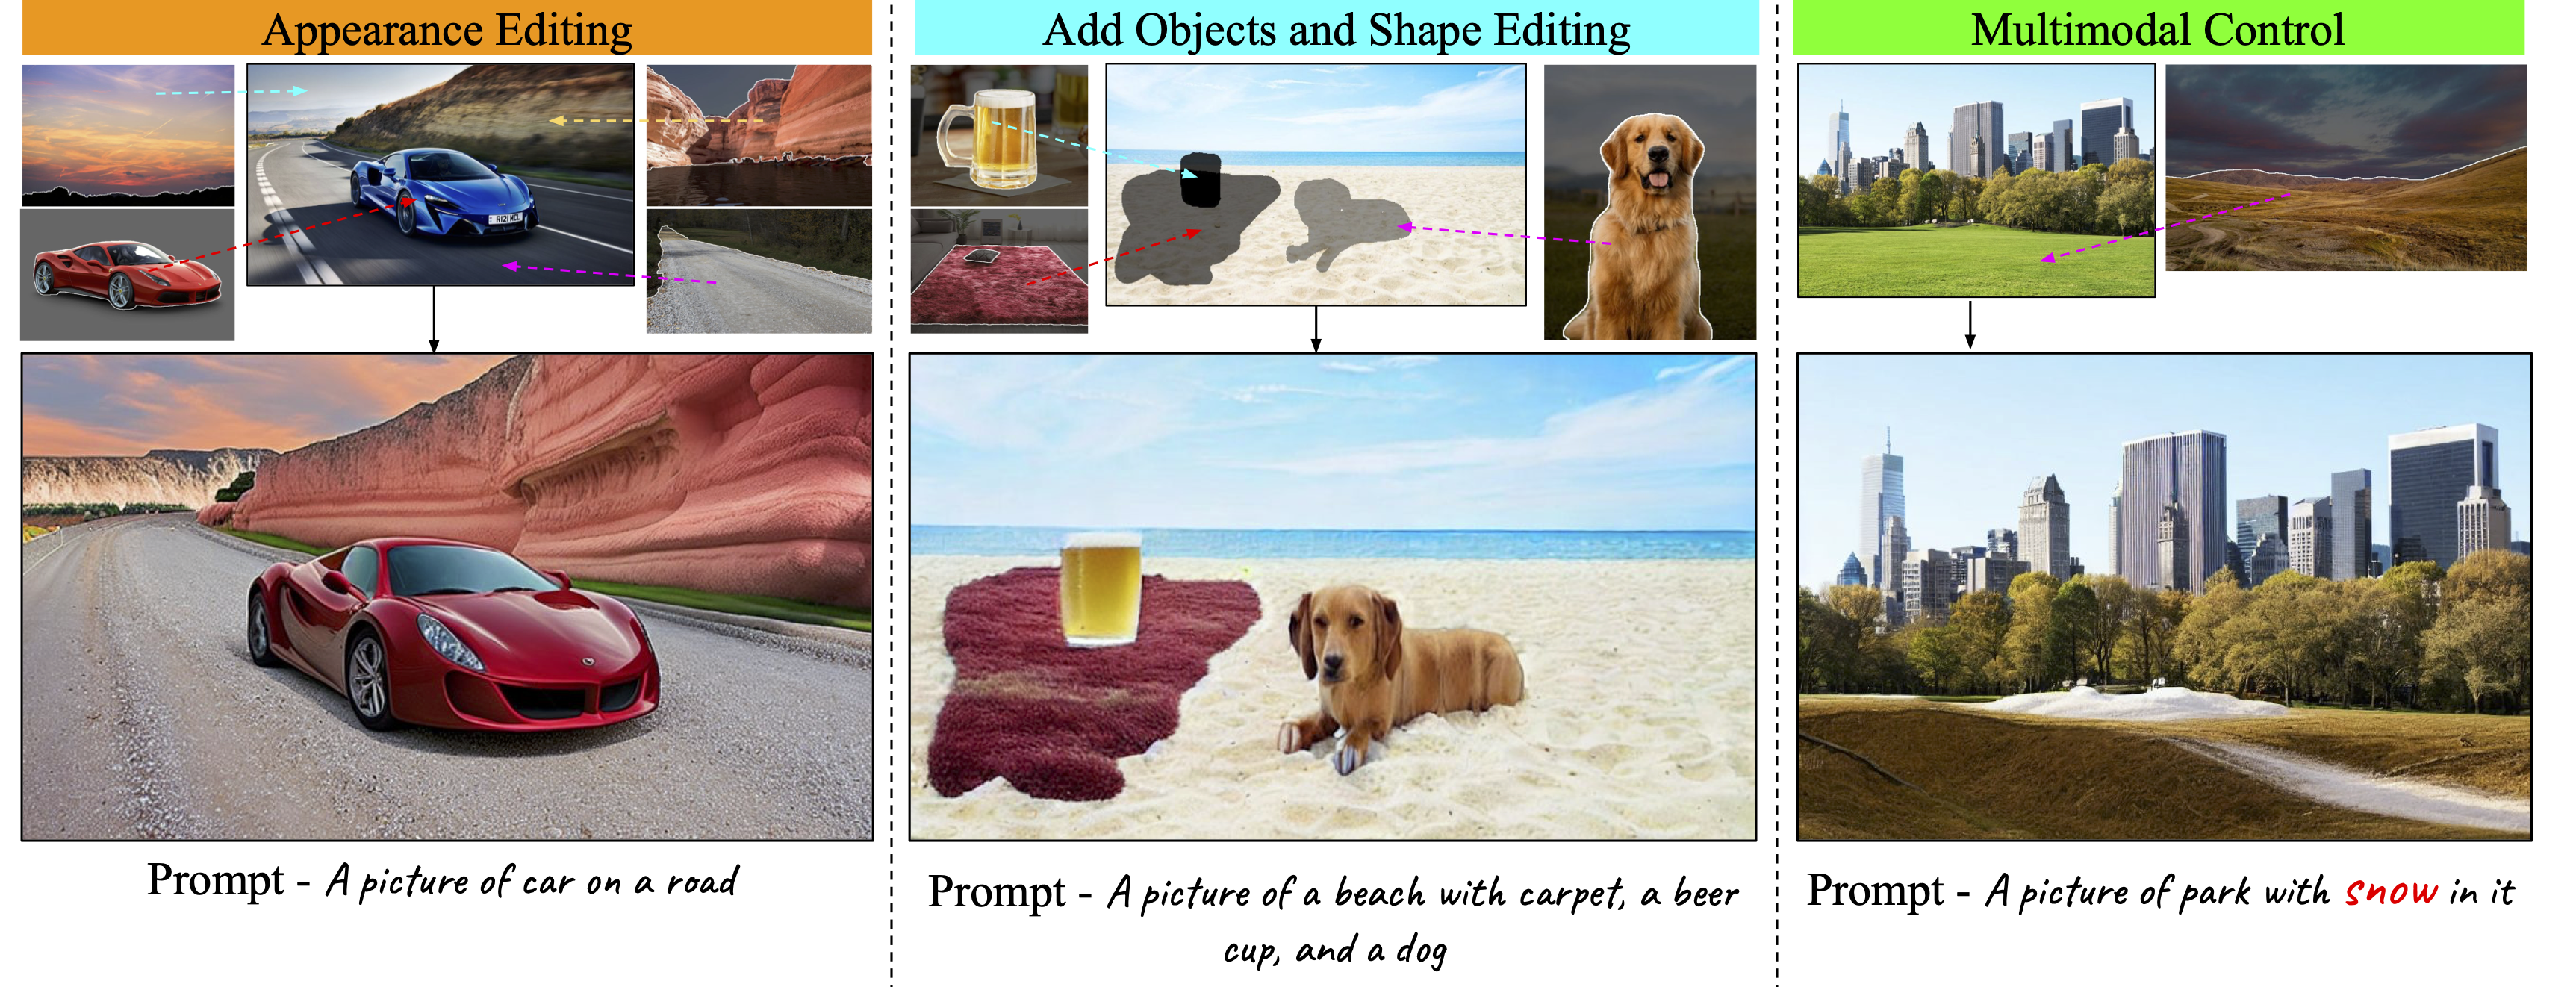
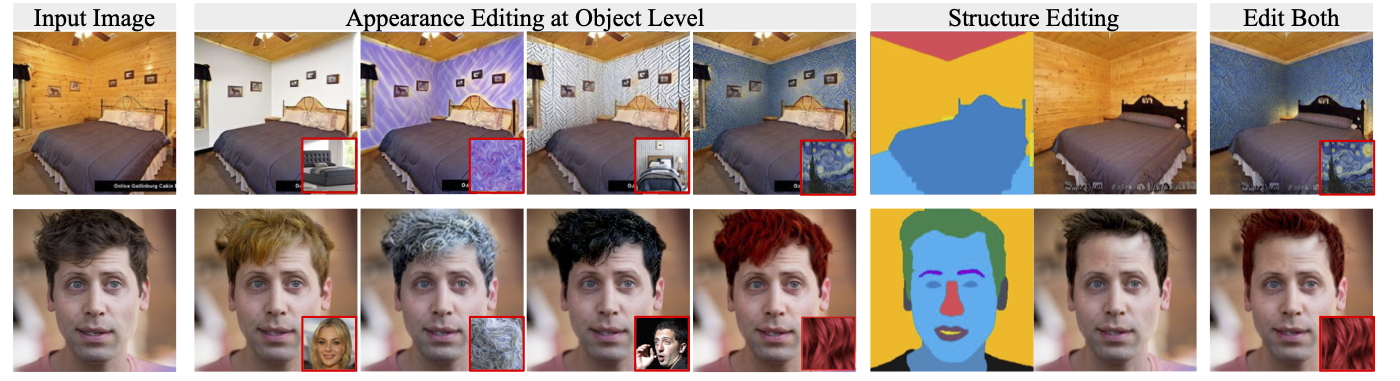
. [10/11/2023] New and improved method and models 🚀🚀. [04/09/2023] Inference code released [04/07/2023] Demo relased on 🤗Huggingface space! [03/30/2023] Paper released on arXiv Results Given below are results for appearace editing using our method on SDv1. 5 Object Level Image Editing Appearance Editing Free form Shape Editing and Adding Object For more results please refer to our project page and paper. Requirements Setup the conda environment using the command below. We use Oneformer

to get segmentation maps during inference, please setup environment for Oneformer following the repo Inference To run the model launch the gradio demo using the command below. It will download the required models as well. Pretrained Models We applied PAIR Diffusion on SDv1. 5 and uses COCO-Stuff dataset for finetuning the model. The model card can be downloaded from here BibTeX If you use our work in your research, please cite our publication:

常见问题

记录了多少星标和分叉?

Picsart-AI-Research/PAIR-Diffusion 有 522 个星标和 21 个分叉。

仓库排名是多少?

Picsart-AI-Research/PAIR-Diffusion 排名第 17,804。

记录的语言和类别是什么?

Picsart-AI-Research/PAIR-Diffusion 有 522 个星标,语言为 Python,类别为 Models。

哪个仓库排名最接近?

Picsart-AI-Research/PAIR-Diffusion 与 yl4579/StarGANv2-VC 比较,后者排名第 17,795,有 523 个星标。

README

PAIR Diffusion: A Comprehensive Multimodal Object-Level Image Editor

[Project Page] [arXiv] [pdf] [BibTeX]

Vidit Goel1, Elia Peruzzo1,2, Yifan Jiang3, Dejia Xu3, Xingqian Xu3, Nicu Sebe2, Trevor Darrell4, Zhangyang Wang1,3 and Humphrey Shi 1,5,6

Features

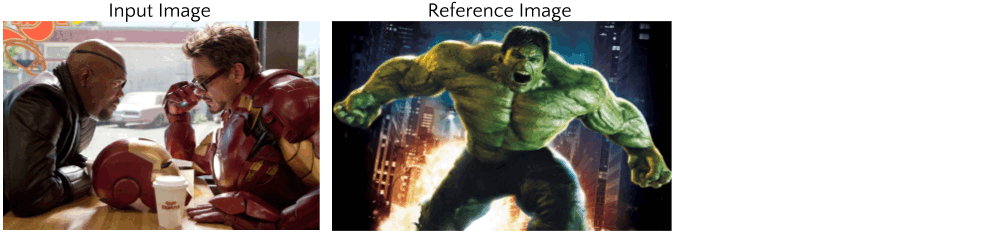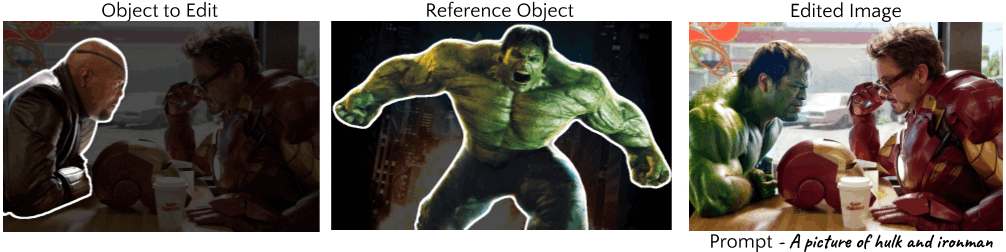
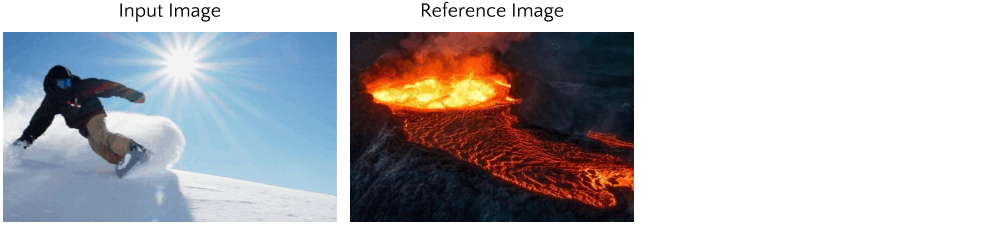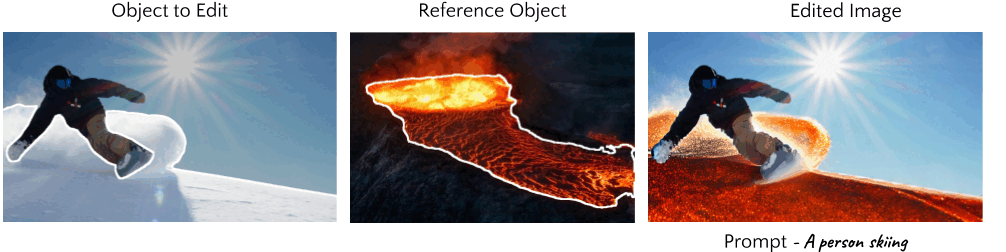
All the operations below can be performed at an object level. Our framework is general and can be applied to any diffusion model.

  1. Appearance Editing
  2. Free Form Shape Editing
  3. Adding Objects
  4. Variation
  5. Multimodal control using reference images and text

News

  • [30/12/2023] Models and code released.
  • [10/11/2023] New and improved method and models 🚀🚀. Models and code will be released soon.
  • [04/09/2023] Inference code released
  • [04/07/2023] Demo relased on 🤗Huggingface space!
  • [03/30/2023] Paper released on arXiv

Results

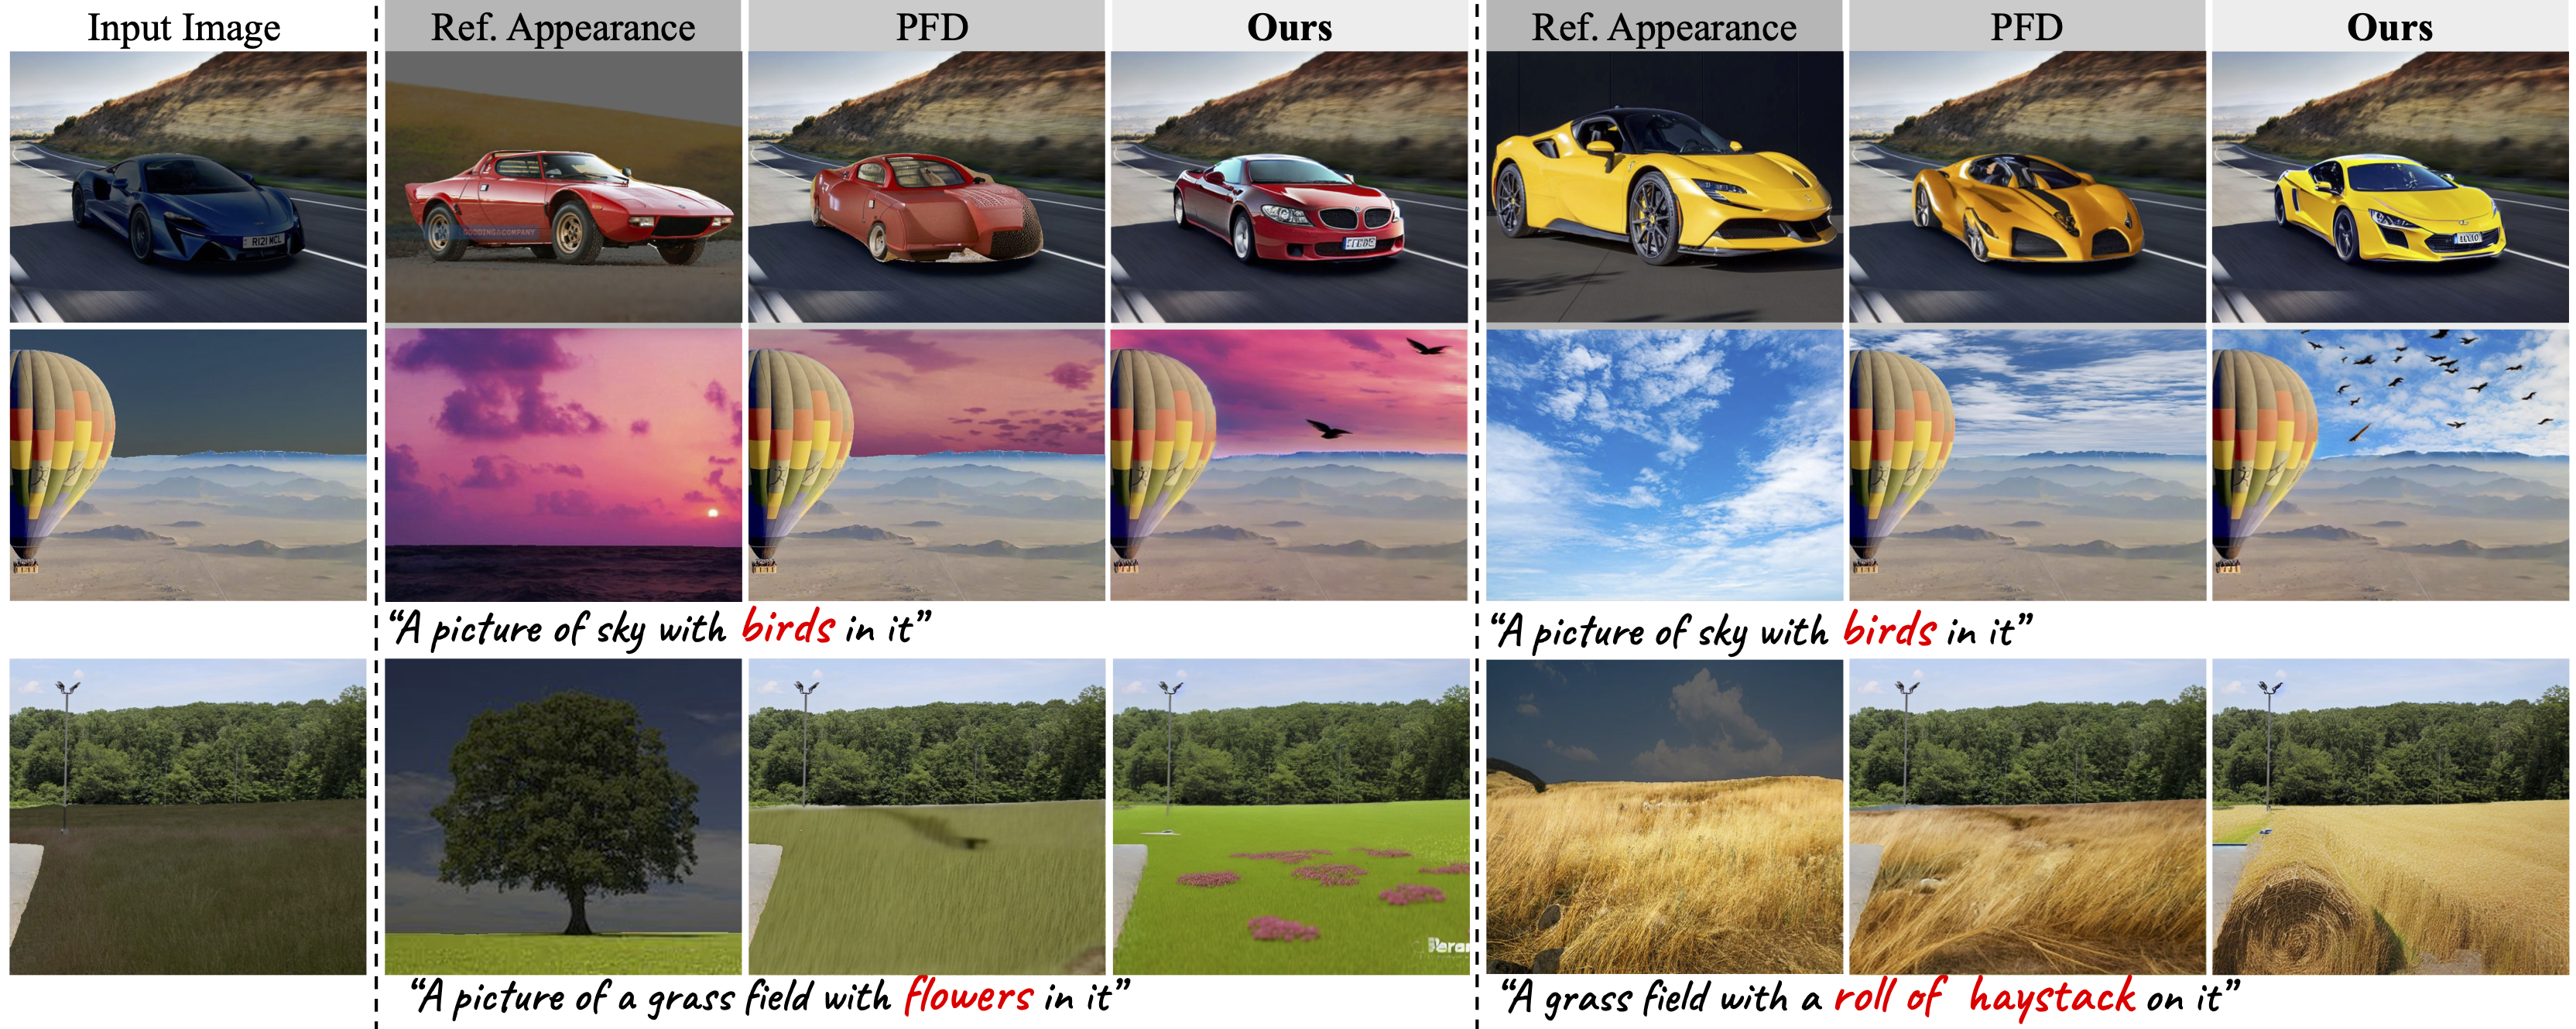
Given below are results for appearace editing using our method on SDv1.5

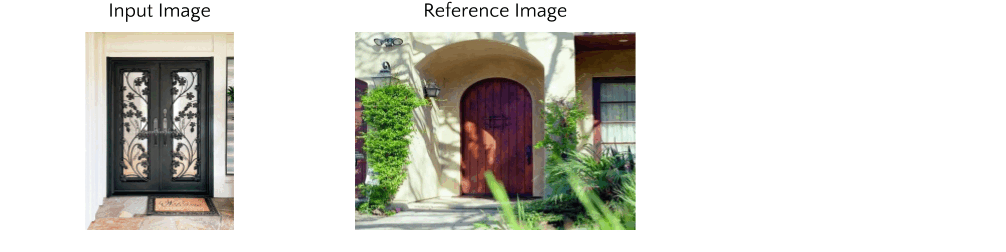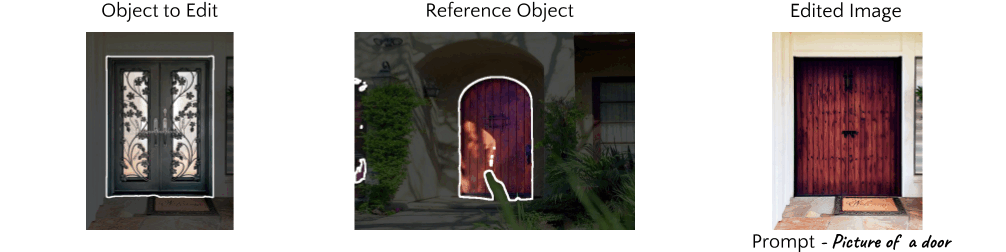
Object Level Image Editing

Appearance Editing

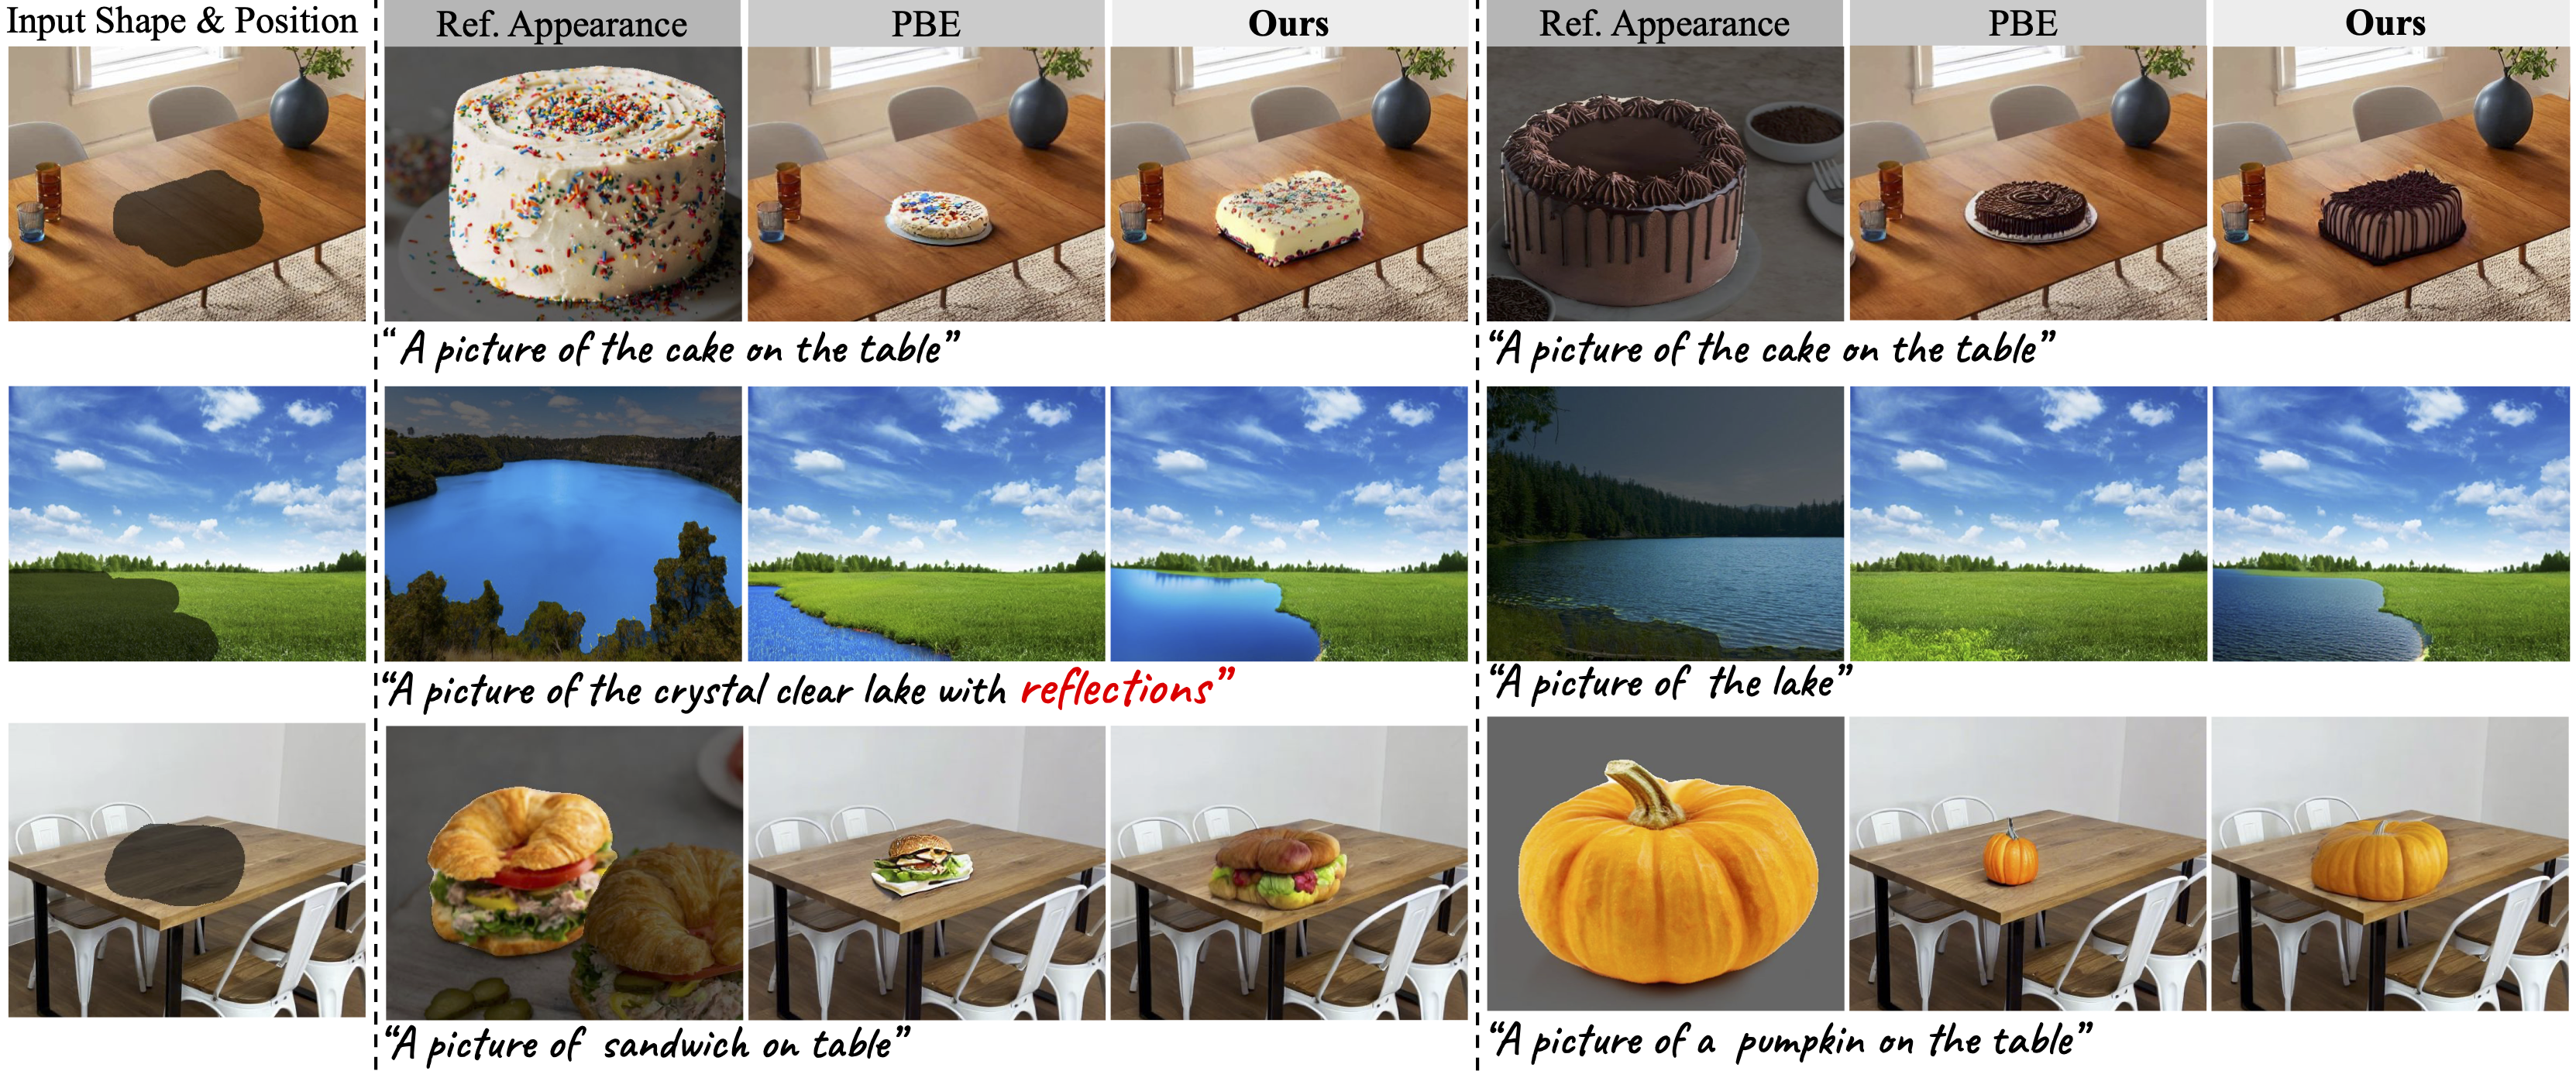
Free form Shape Editing and Adding Object

For more results please refer to our project page and paper.

Requirements

Setup the conda environment using the command below. We use Oneformer to get segmentation maps during inference, please setup environment for Oneformer following the repo

conda env create -f environment.yml
conda activate pair-diff

Inference

To run the model launch the gradio demo using the command below. It will download the required models as well.

python gradio_demo.py

Pretrained Models

We applied PAIR Diffusion on SDv1.5 and uses COCO-Stuff dataset for finetuning the model. The model card can be downloaded from here

BibTeX

If you use our work in your research, please cite our publication:

@article{goel2023pair,
      title={PAIR-Diffusion: Object-Level Image Editing with Structure-and-Appearance Paired Diffusion Models},
      author={Goel, Vidit and Peruzzo, Elia and Jiang, Yifan and Xu, Dejia and Sebe, Nicu and Darrell, Trevor and 
      Wang, Zhangyang and Shi, Humphrey},
      journal={arXiv preprint arXiv:2303.17546},
      year={2023} 
      }
排名相邻
同类项目