PINTO_model_zoo

Please read the contents of the LICENSE file located directly under each folder before using the model. My model conversion scripts are released under the MIT license, but the license of the source model itself is subject to the license of the provider repository.
Contributors
Made with contrib.rocks.
A repository for storing models that have been inter-converted between various frameworks. Supported frameworks are TensorFlow, PyTorch, ONNX, OpenVINO, TFJS, TFTRT, TensorFlowLite (Float32/16/INT8), EdgeTPU, CoreML.
TensorFlow Lite, OpenVINO, CoreML, TensorFlow.js, TF-TRT, MediaPipe, ONNX [.tflite, .h5, .pb, saved_model, tfjs, tftrt, mlmodel, .xml/.bin, .onnx]
I have been working on quantization of various models as a hobby, but I have skipped the work of making sample code to check the operation because it takes a lot of time. I welcome a pull request from volunteers to provide sample code. :smile:
[Note Jan 05, 2020] Currently, the MobileNetV3 backbone model and the Full Integer Quantization model do not return correctly.
[Note Jan 08, 2020] If you want the best performance with RaspberryPi4/3, install Ubuntu 19.10 aarch64 (64bit) instead of Raspbian armv7l (32bit). The official Tensorflow Lite is performance tuned for aarch64. On aarch64 OS, performance is about 4 times higher than on armv7l OS.
My article
-
Conversion of PyTorch->ONNX->OpenVINO IR model to Tensorflow saved_model / h5 / tflite / pb
-
[TF2 Object Detection] Converting SSD models into .tflite uint8 format #9371
-
[Japanese] Custom Operation入りのtfliteを逆コンバートしてJSON化し標準OPへ置き換えたうえでtfliteを再生成する方法
-
Add a custom OP to the TFLite runtime to build the whl installer (for Python),
MaxPoolingWithArgmax2D,MaxUnpooling2D,Convolution2DTransposeBias -
Inverse Quantization of tflite's Sparse Tensor Densify to Refine a Clean Float32 Model
-
Simple node deletion tool for onnx. I only test very miscellaneous and limited patterns as a hobby.
-
Simple tool to combine onnx models. Simple Network Combine Tool for ONNX.
-
-
List of pre-quantized models
* WQ = Weight Quantization ** OV = OpenVINO IR *** CM = CoreML **** DQ = Dynamic Range Quantization
1. Image Classification
| No. | Model Name | Link | FP32 | FP16 | INT8 | DQ | TPU | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 004 | Efficientnet | ■■■ | ⚫ | ⚫ | ⚫ | |||||||||
| 010 | Mobilenetv3 | ■■■ | ⚫ | ⚫ | ⚫ | |||||||||
| 011 | Mobilenetv2 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||||
| 016 | Efficientnet-lite | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 070 | age-gender-recognition | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 083 | Person_Reidentification | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 248,277,286,287,288,300 | ||
| 087 | DeepSort | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||
| 124 | person-attributes-recognition-crossroad-0230 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 125 | person-attributes-recognition-crossroad-0234 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 126 | person-attributes-recognition-crossroad-0238 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 175 | face-recognition-resnet100-arcface-onnx | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | RGB/BGR,112x112,[1,512] | |
| 187 | vehicle-attributes-recognition-barrier-0039 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 72x72 |
| 188 | vehicle-attributes-recognition-barrier-0042 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 72x72 |
| 191 | anti-spoof-mn3 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 128x128 | |
| 192 | open-closed-eye-0001 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 32x32 | |
| 194 | face_recognizer_fast | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 112x112 |
| 195 | person_reid_youtu | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 256x128, ReID |
| 199 | NSFW | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 224x224 |
| 244 | FINNger | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 96x96 | ||
| 256 | SFace | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 112x112 | |
| 257 | PiCANet | ■■■ | ⚫ | ⚫ | BDDA,SAGE/224x224 | |||||||||
| 259 | Emotion_FERPlus | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 64x64 | |
| 290 | AdaFace | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 112x112 | ||
| 317 | MobileOne | ■■■ | ⚫ | 224x224 | ||||||||||
| 346 | facial_expression_recognition_mobilefacenet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 112x112 | |||||
| 379 | PP-LCNetV2 | ■■■ | ⚫ | ⚫ | ⚫ | 224x224 | ||||||||
| 429 | OSNet | ■■■ | ⚫ | 256x128, ReID | ||||||||||
| 430 | FastReID | ■■■ | ⚫ | 384x128, ReID | ||||||||||
| 431 | NITEC | ■■■ | ⚫ | 224x224, Gaze Estimation | ||||||||||
| 432 | face-reidentification-retail-0095 | ■■■ | ⚫ | ⚫ | ⚫ | 128x128, FaceReID | ||||||||
| 451 | DAN | ■■■ | ⚫ | 224x224, Facial Expression | ||||||||||
| 452 | FairFace | ■■■ | ⚫ | 224x224, Face Attribute | ||||||||||
| 453 | FairDAN | ■■■ | ⚫ | 224x224, Face Attribute + Facial Expression | ||||||||||
| 462 | Gaze-LLE | ■■■ | ⚫ | 448x448, Attention | ||||||||||
| 474 | Gaze-LLE-DINOv3 | ■■■ | ⚫ | 640x640,416x416,320x320, Attention | ||||||||||
| 475 | VSDLM | ■■■ | ⚫ | 30x48, Lip motion | ||||||||||
| 476 | OCEC | ■■■ | ⚫ | 24x40, Wink/Blink | ||||||||||
| 477 | PGC | ■■■ | ⚫ | 32x32, Pointing | ||||||||||
| 478 | SC | ■■■ | ⚫ | 32x24, Sitting | ||||||||||
| 479 | PUC | ■■■ | ⚫ | 32x24, Phone Usage Classifier | ||||||||||
| 480 | HSC | ■■■ | ⚫ | 48x48, Happy smile classifier | ||||||||||
| 481 | WHC | ■■■ | ⚫ | 4x32x32,6x32x32,8x32x32, Waving Hand Classification | ||||||||||
| 483 | LVFace | ■■■ | ⚫ | Nx3x112x112, Cosine similarity | ||||||||||
| 484 | TransFace | ■■■ | ⚫ | Nx3x112x112, Cosine similarity | ||||||||||
| 486 | MWC | ■■■ | ⚫ | Nx3x48x48, Mask wearing classifier | ||||||||||
| 489 | Glasses-Detector | ■■■ | ⚫ | Glasses | ||||||||||
| 491 | SGC | ■■■ | ⚫ | Sunglasses | ||||||||||
| 492 | HHC | ■■■ | ⚫ | Hat | ||||||||||
| 494 | BPC | ■■■ | ⚫ | Background Plain classification | ||||||||||
| 495 | Comprehensive-Head-Classification | ■■■ | ⚫ | ⚫ | Comprehensive head classification | |||||||||
| 497 | PPC | ■■■ | ⚫ | Binary classification to determine whether the subject is holding a smartphone | ||||||||||
| 502 | PersonViT | ■■■ | ⚫ | Person Re-Identification | ||||||||||
| 503 | CDNet | ■■■ | ⚫ | Person Re-Identification |
2. 2D Object Detection
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | DQ | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 002 | Mobilenetv3-SSD | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||||
| 006 | Mobilenetv2-SSDlite | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||||
| 008 | Mask_RCNN_Inceptionv2 | ■■■ | ⚫ | ⚫ | ⚫ | |||||||||
| 018 | EfficientDet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 023 | Yolov3-nano | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||||
| 024 | Yolov3-lite | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||
| 031 | Yolov4 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||
| 034 | SSD_Mobilenetv2_mnasfpn | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||
| 038 | SSDlite_MobileDet_edgetpu | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||
| 039 | SSDlite_MobileDet_cpu | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||||
| 042 | Centernet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 045 | SSD_Mobilenetv2_oid_v4 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||
| 046 | Yolov4-tiny | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 047 | SpineNetMB_49 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Mobile RetinaNet | ||||||
| 051 | East_Text_Detection | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 054 | KNIFT | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | MediaPipe | |||||
| 056 | TextBoxes++ with dense blocks, separable convolution and Focal Loss | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||
| 058 | keras-retinanet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | resnet50_coco_best_v2.1.0.h5,320x320 | ||||
| 072 | NanoDet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | issue #274 | |
| 073 | RetinaNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 074 | Yolact | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 085 | Yolact_Edge | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 21/10/05 new MobileNetV2(550x550) |
| 089 | DETR | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 256x256 | ||||||
| 103 | EfficientDet_lite | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | lite0,lite1,lite2,lite3,lite4 | ||
| 116 | DroNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | DroNet,DroNetV3 | |
| 123 | YOLOR | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ssss_s2d/320x320,640x640,960x960,1280x1280 | ||
| 132 | YOLOX | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | nano,tiny,s,m,l,x/256x320,320x320,416x416,480x640,544x960,736x1280,1088x1920 | |
| 143 | RAPiD | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Fisheye, cepdof/habbof/mw_r, 608x608/1024x1024 | |||||
| 145 | text_detection_db | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 480x640 | ||
| 151 | object_detection_mobile_object_localizer | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 192x192 | |
| 169 | spaghettinet_edgetpu | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 320x320,S/M/L | |
| 174 | PP-PicoDet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | S/M/L,320x320/416x416/640x640 | |
| 178 | vehicle-detection-0200 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 256x256,PriorBoxClustered->ndarray(0.npy) |
| 179 | person-detection-0202 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 512x512,PriorBoxClustered->ndarray(0.npy) |
| 183 | pedestrian-detection-adas-0002 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 384x672,PriorBox->ndarray(0.npy) |
| 184 | pedestrian-and-vehicle-detector-adas-0001 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 384x672,PriorBox->ndarray(0.npy) |
| 185 | person-vehicle-bike-detection-crossroad-0078 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 1024x1024,PriorBoxClustered->ndarray(0.npy) | |
| 186 | person-vehicle-bike-detection-crossroad-1016 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 512x512,PriorBoxClustered->ndarray(0.npy) |
| 189 | vehicle-license-plate-detection-barrier-0106 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 300x300,PriorBoxClustered->ndarray(0.npy) |
| 190 | person-detection-asl-0001 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 320x320 | ||||
| 197 | yolact-resnet50-fpn | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | RGB,550x550 | |
| 198 | YOLOF | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | BGR/RGB,608x608 | |
| 221 | YOLACT-PyTorch | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 180x320,240x320,320x480,480x640,544x544,720x1280 | ||
| 226 | CascadeTableNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | General,320x320 only | |||||
| 262 | ByteTrack | ■■■ | ⚫ | YOLOX/nano,tiny,s,m,l,x,mot17,ablation/128x320,192x320,192x448,192x640,256x320,256x448,256x640,384x640,512x1280,736x1280 | ||||||||||
| 264 | object_localization_network | ■■■ | ⚫ | 180x320,240x320,270x480,360x480,360x480,360x640,480x640,720x1280 | ||||||||||
| 307 | YOLOv7 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | YOLOv7,YOLOv7-tiny | |||
| 308 | FastestDet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 180x320,256x320,320x480,352x352,352x640,480x640,736x1280 | ||
| 329 | YOLOX-PAI | ■■■ | ⚫ | |||||||||||
| 332 | CrowdDet | ■■■ | ⚫ | |||||||||||
| 334 | DAMO-YOLO | ■■■ | ⚫ | |||||||||||
| 336 | PP-YOLOE-Plus | ■■■ | ⚫ | |||||||||||
| 337 | FreeYOLO | ■■■ | ⚫ | |||||||||||
| 341 | YOLOv6 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||
| 356 | EdgeYOLO | ■■■ | ⚫ | |||||||||||
| 376 | RT-DETR | ■■■ | ⚫ | ResNet50,ResNet101,HgNetv2-L,HgNetv2-X | ||||||||||
| 386 | naruto_handsign_detection | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||||||
| 422 | Gold-YOLO-Head-Hand | ■■■ | ⚫ | Head,Hand | ||||||||||
| 424 | Gold-YOLO-Body | ■■■ | ⚫ | Body | ||||||||||
| 425 | Gold-YOLO-Body-Head-Hand | ■■■ | ⚫ | Body,Head,Hand | ||||||||||
| 426 | YOLOX-Body-Head-Hand | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | Body,Head,Hand, tflite float16 XNNPACK boost (ARMv8.2) | |||||||
| 434 | YOLOX-Body-Head-Hand-Face | ■■■ | ⚫ | Body,Head,Hand,Face | ||||||||||
| 441 | YOLOX-Body-Head-Hand-Face-Dist | ■■■ | ⚫ | Body,Head,Hand,Face,Complex Distorted | ||||||||||
| 442 | YOLOX-Body-Head-Face-HandLR-Dist | ■■■ | ⚫ | Body,Head,Hands,Left-Hand,Right-Hand,Face,Complex Distorted | ||||||||||
| 444 | YOLOX-Foot-Dist | ■■■ | ⚫ | Foot,Complex Distorted | ||||||||||
| 445 | YOLOX-Body-Head-Face-HandLR-Foot-Dist | ■■■ | ⚫ | Body,Head,Face,Hands,Left-Hand,Right-Hand,Foot,Complex Distorted | ||||||||||
| 446 | YOLOX-Body-With-Wheelchair | ■■■ | ⚫ | Body with WheelChair | ||||||||||
| 447 | YOLOX-Wholebody-with-Wheelchair | ■■■ | ⚫ | Wholebody with WheelChair | ||||||||||
| 448 | YOLOX-Eye-Nose-Mouth-Ear | ■■■ | ⚫ | |||||||||||
| 449 | YOLOX-WholeBody12 | ■■■ | ⚫ | Body,BodyWithWheelchair,Head,Face,Eye,Nose,Mouth,Ear,Hand,Hand-Left,Hand-Right,Foot | ||||||||||
| 450 | YOLOv9-Wholebody-with-Wheelchair | ■■■ | ⚫ | Wholebody with WheelChair | ||||||||||
| 454 | YOLOv9-Wholebody13 | ■■■ | ⚫ | Body,BodyWithWheelchair,BodyWithCrutches,Head,Face,Eye,Nose,Mouth,Ear,Hand,Hand-Left,Hand-Right,Foot | ||||||||||
| 455 | YOLOv9-Gender | ■■■ | ⚫ | Body,Male,Female | ||||||||||
| 456 | YOLOv9-Wholebody15 | ■■■ | ⚫ | Body,Male,Female,BodyWithWheelchair,BodyWithCrutches,Head,Face,Eye,Nose,Mouth,Ear,Hand,Hand-Left,Hand-Right,Foot | ||||||||||
| 457 | YOLOv9-Wholebody17 | ■■■ | ⚫ | Body,Male,Adult,Child,Female,BodyWithWheelchair,BodyWithCrutches,Head,Face,Eye,Nose,Mouth,Ear,Hand,Hand-Left,Hand-Right,Foot | ||||||||||
| 458 | YOLOv9-Discrete-HeadPose-Yaw | ■■■ | ⚫ | Head,Front,Right-Front,Right-Side,Right-Back,Back,Left-Back,Left-Side,Left-Front | ||||||||||
| 459 | YOLOv9-Wholebody25 | ■■■ | ⚫ | Body,Adult,Child,Male,Female,Body_with_Wheelchair,Body_with_Crutches,Head,Front,Right_Front,Right_Side,Right_Back,Back,Left_Back,Left_Side,Left_Front,Face,Eye,Nose,Mouth,Ear,Hand,Hand_Left,Hand_Right,Foot | ||||||||||
| 460 | RT-DETRv2-Wholebody25 | ■■■ | ⚫ | Body,Adult,Child,Male,Female,Body_with_Wheelchair,Body_with_Crutches,Head,Front,Right_Front,Right_Side,Right_Back,Back,Left_Back,Left_Side,Left_Front,Face,Eye,Nose,Mouth,Ear,Hand,Hand_Left,Hand_Right,Foot | ||||||||||
| 461 | YOLOv9-Phone | ■■■ | ⚫ | Phone | ||||||||||
| 463 | YOLOv9-Shoulder-Elbow-Knee | ■■■ | ⚫ | Shoulder,Elbow,Knee | ||||||||||
| 464 | YOLOv9-Wholebody28 | ■■■ | ⚫ | Body,Adult,Child,Male,Female,Body_with_Wheelchair,Body_with_Crutches,Head,Front,Right_Front,Right_Side,Right_Back,Back,Left_Back,Left_Side,Left_Front,Face,Eye,Nose,Mouth,Ear,Shoulder,Elbow,Hand,Hand_Left,Hand_Right,Knee,Foot | ||||||||||
| 465 | DEIM-Wholebody28 | ■■■ | ⚫ | Body,Adult,Child,Male,Female,Body_with_Wheelchair,Body_with_Crutches,Head,Front,Right_Front,Right_Side,Right_Back,Back,Left_Back,Left_Side,Left_Front,Face,Eye,Nose,Mouth,Ear,Shoulder,Elbow,Hand,Hand_Left,Hand_Right,Knee,Foot | ||||||||||
| 468 | YOLOv9-Wholebody28-Refine | ■■■ | ⚫ | Body,Adult,Child,Male,Female,Body_with_Wheelchair,Body_with_Crutches,Head,Front,Right_Front,Right_Side,Right_Back,Back,Left_Back,Left_Side,Left_Front,Face,Eye,Nose,Mouth,Ear,Shoulder,Elbow,Hand,Hand_Left,Hand_Right,Knee,Foot | ||||||||||
| 471 | YOLO-Wholebody34 | ■■■ | ⚫ | body,adult,child,male,female,body_with_wheelchair,body_with_crutches,head,front,right-front,right-side,right-back,back,left-back,left-side,left-front,face,eye,nose,mouth,ear,collarbone,shoulder,solar_plexus,elbow,wrist,hand,hand_left,hand_right,abdomen,hip_joint,knee,ankle,foot | ||||||||||
| 472 | DEIMv2-Wholebody34 | ■■■ | ⚫ | body,adult,child,male,female,body_with_wheelchair,body_with_crutches,head,front,right-front,right-side,right-back,back,left-back,left-side,left-front,face,eye,nose,mouth,ear,collarbone,shoulder,solar_plexus,elbow,wrist,hand,hand_left,hand_right,abdomen,hip_joint,knee,ankle,foot | ||||||||||
| 473 | HISDF | ■■■ | ⚫ | Object Detection x Depth Estimation x Pose Estimation x Instance Segmentation x Binary Segmentation | ||||||||||
| 482 | UHD | ■■■ | ⚫ | 64x64, Object Detection, Human Detection | ||||||||||
| 485 | DEIMv2-Wholebody40 | ■■■ | ⚫ | 40 classes | ||||||||||
| 489 | 489_Glasses-Detector | ■■■ | ⚫ | glasses |
3. 3D Object Detection
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | DQ | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 036 | Objectron | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | MediaPipe/camera,chair,chair_1stage,cup,sneakers,sneakers_1stage,ssd_mobilenetv2_oidv4_fp16 |
| 063 | 3D BoundingBox estimation for autonomous driving | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | YouTube | ||
| 107 | SFA3D | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 263 | EgoNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 321 | DID-M3D | ■■■ | ⚫ | |||||||||||
| 363 | YOLO-6D-Pose | ■■■ | ⚫ | ⚫ | ⚫ | Texas Instruments ver, PINTO Special ver |
4. 2D/3D Face Detection
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | DQ | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 025 | Head_Pose_Estimation | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 030 | BlazeFace | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | MediaPipe | |
| 032 | FaceMesh | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | MediaPipe | |
| 040 | DSFD_vgg | ■■■ | ⚫ | ⚫ | ⚫ | |||||||||
| 041 | DBFace | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | MobileNetV2/V3, 320x320,480x640,640x960,800x1280 | |
| 043 | Face_Landmark | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 049 | Iris_Landmark | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | MediaPipe |
| 095 | CenterFace | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 096 | RetinaFace | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 106 | WHENet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Real-time Fine-Grained Estimation for Wide Range Head Pose | |
| 129 | SCRFD | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | All types | |
| 134 | head-pose-estimation-adas-0001 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 60x60 |
| 144 | YuNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 120x160 | |
| 227 | face-detection-adas-0001 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 384x672,PriorBox->ndarray(0.npy) |
| 250 | Face-Mask-Detection | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | PriorBox->ndarray(0.npy) | |
| 282 | face_landmark_with_attention | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | MediaPipe,192x192 | |||
| 289 | face-detection-0100 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 256x256,PriorBoxClustered->ndarray(0.npy) | |
| 293 | Lightweight-Head-Pose-Estimation | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | HeadPose, 224x224 | ||
| 300 | 6DRepNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 6D HeadPose, 224x224 | |||
| 301 | YOLOv4_Face | ■■■ | ⚫ | 480x640 | ||||||||||
| 302 | SLPT | ■■■ | ⚫ | decoder=6/12,256x256 | ||||||||||
| 303 | FAN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Face Alignment,128x128/256x256 | ||
| 304 | SynergyNet | ■■■ | ⚫ | 6D HeadPose,224x224 | ||||||||||
| 305 | DMHead | ■■■ | ⚫ | 6D HeadPose,Multi-Model-Fused,224x224,PINTO's custom models | ||||||||||
| 311 | HHP-Net | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 6D HeadPose,No-LICENSE | ||
| 319 | ACR-Loss | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Face Alignment | ||
| 322 | YOLOv7_Head | ■■■ | ⚫ | PINTO's custom models | ||||||||||
| 383 | DirectMHP | ■■■ | ⚫ | ⚫ | ⚫ | |||||||||
| 387 | YuNetV2 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 640x640 | ||||||
| 390 | BlendshapeV2 | ■■■ | ⚫ | ⚫ | ⚫ | 1x146x2,Nx146x2,MediaPipe | ||||||||
| 399 | RetinaFace_MobileNetv2 | ■■■ | ⚫ | |||||||||||
| 410 | FaceMeshV2 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | MediaPipe | |||||
| 414 | STAR | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||
| 421 | Gold-YOLO-Head | ■■■ | ⚫ | Head (not Face) | ||||||||||
| 423 | 6DRepNet360 | ■■■ | ⚫ | 6D HeadPose, FullRange, 224x224 | ||||||||||
| 433 | FaceBoxes.PyTorch | ■■■ | ⚫ | 2D Face | ||||||||||
| 435 | MobileFaceNet | ■■■ | ⚫ | Face Alignment,112x112 | ||||||||||
| 436 | Peppa_Pig_Face_Landmark | ■■■ | ⚫ | Face Alignment,128x128,256x256 | ||||||||||
| 437 | PIPNet | ■■■ | ⚫ | Face Alignment,256x256 | ||||||||||
| 443 | Opal23_HeadPose | ■■■ | ⚫ | 6D HeadPose, FullRange, 128x128 | ||||||||||
| 504 | HRFFA | ■■■ | ⚫ | Face Alignment | ||||||||||
| 505 | YawNet | ■■■ | ⚫ | Head Pose Estimation |
5. 2D/3D Hand Detection
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | DQ | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 027 | Minimal-Hand | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||
| 033 | Hand_Detection_and_Tracking | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | MediaPipe |
| 094 | hand_recrop | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | MediaPipe | |
| 403 | trt_pose_hand | ■■■ | ⚫ | 2D | ||||||||||
| 420 | Gold-YOLO-Hand | ■■■ | ⚫ | 2D | ||||||||||
| 438 | PeCLR | ■■■ | ⚫ | 2D+3D |
6. 2D/3D Human/Animal Pose Estimation
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | DQ | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 003 | Posenet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||
| 007 | Mobilenetv2_Pose_Estimation | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||
| 029 | Human_Pose_Estimation_3D | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | RGB,180x320,240x320,360x640,480x640,720x1280 |
| 053 | BlazePose | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | MediaPipe | |
| 065 | ThreeDPoseUnityBarracuda | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | YouTube | |
| 080 | tf_pose_estimation | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 084 | EfficientPose | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | SinglePose | ||
| 088 | Mobilenetv3_Pose_Estimation | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 115 | MoveNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | lightning,thunder | |
| 137 | MoveNet_MultiPose | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | lightning,192x192,192x256,256x256,256x320,320x320,480x640,720x1280,1280x1920 | ||
| 156 | MobileHumanPose | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 3D |
| 157 | 3DMPPE_POSENET | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 3D,192x192/256x256/320x320/416x416/480x640/512x512 | |
| 265 | PoseAug | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 2D->3D/GCN,MLP,STGCN,VideoPose/Nx16x2 | ||
| 268 | Lite-HRNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | COCO,MPII/Top-Down | ||
| 269 | Higher-HRNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 192x320,256x320,320x480,384x640,480x640,512x512,576x960,736x1280/Bottom-Up | ||
| 271 | HRNet | ■■■ | ⚫ | COCO,MPII/Top-Down | ||||||||||
| 333 | E2Pose | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | COCO/CrowdPose,End-to-End | ||||||
| 350 | P-STMO | ■■■ | ⚫ | 2D->3D,in_the_wild | ||||||||||
| 355 | MHFormer | ■■■ | ⚫ | ⚫ | ⚫ | 2D->3D | ||||||||
| 365 | HTNet | ■■■ | ⚫ | ⚫ | ⚫ | 2D->3D | ||||||||
| 392 | STCFormer | ■■■ | ⚫ | ⚫ | ⚫ | 2D->3D | ||||||||
| 393 | RTMPose_WholeBody | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 2D | ||||||
| 394 | RTMPose_Animal | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 2D | ||||||
| 402 | trt_pose | ■■■ | ⚫ | 2D | ||||||||||
| 412 | pytorch_cpn | ■■■ | ⚫ | ⚫ | ⚫ | 2D | ||||||||
| 427 | RTMPose_Hand | ■■■ | ⚫ | 2D | ||||||||||
| 440 | ViTPose | ■■■ | ⚫ | 2D |
7. Depth Estimation from Monocular/Stereo Images
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | DQ | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 009 | Multi-Scale Local Planar Guidance for Monocular Depth Estimation | ■■■ | ⚫ | |||||||||||
| 014 | tf-monodepth2 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||
| 028 | struct2depth | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||||
| 064 | Dense Depth | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 066 | Footprints | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 067 | MiDaS | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 081 | MiDaS v2 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 135 | CoEx | ■■■ | ⚫ | ⚫ | WIP, onnx/OpenVINO only | |||||||||
| 142 | HITNET | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | WIP issue1,issue2,flyingthings_finalpass_xl/eth3d/middlebury_d400,120x160/240x320/256x256/480x640/720x1280 | |||||||
| 146 | FastDepth | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 128x160,224x224,256x256,256x320,320x320,480x640,512x512,768x1280 | |
| 147 | PackNet-SfM | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ddad/kitti,Convert all ResNet18 backbones only | ||
| 148 | LapDepth | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | kitti/nyu,192x320/256x320/368x640/480x640/720x1280 | ||
| 149 | depth_estimation | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | nyu,180x320/240x320/360x640/480x640/720x1280 | |
| 150 | MobileStereoNet | ■■■ | WIP. Conversion script only. | |||||||||||
| 153 | MegaDepth | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 192x256,384x512 | |
| 158 | HR-Depth | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 159 | EPCDepth | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 160 | msg_chn_wacv20 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 192x320,240x320,256x256,352x480,368x480,368x640,480x640,720x1280,1280x1920 | ||
| 162 | PyDNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 164 | MADNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Real-time-self-adaptive-deep-stereo (perform only inference mode, no-backprop, kitti) | |||
| 165 | RealtimeStereo | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 180x320,216x384,240x320,270x480,360x480,360x640,480x640,720x1280 | |||
| 166 | Insta-DM | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 192x320,256x320,256x832,384x640,480x640,736x1280 | |
| 167 | DPT | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | dpt-hybrid,480x640,ViT,ONNX 96x128/256x320/384x480/480x640 | ||
| 173 | MVDepthNet | ■■■ | ⚫ | ⚫ | 256x320 | |||||||||
| 202 | stereoDNN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | NVSmall_321x1025,NVTiny_161x513,ResNet18_321x1025,ResNet18_2d_257x513 | |||
| 203 | SRHNet | ■■■ | ⚫ | finetune2_kitti/sceneflow,maxdisp192,320x480/480x640 | ||||||||||
| 210 | SC_Depth_pl | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | kitti/nyu,320x320,320x480,480x640,640x800 | |
| 211 | Lac-GwcNet | ■■■ | ⚫ | kitti,240x320,320x480,480x640,720x1280 | ||||||||||
| 219 | StereoNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Left/180x320,240x320,320x480,360x640,480x640 | |||
| 235 | W-Stereo-Disp | ■■■ | ⚫ | Kitti,Sceneflow/320x480,384x576,480x640 | ||||||||||
| 236 | A-TVSNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Stereo only/192x320,256x320,320x480,480x640 | ||||||
| 239 | CasStereoNet | ■■■ | ⚫ | Stereo KITTI only/256x320,384x480,480x640,736x1280 | ||||||||||
| 245 | GLPDepth | ■■■ | ⚫ | ⚫ | Kitti,NYU/192x320,320x480,384x640,480x640,736x1280,non-commercial use only | |||||||||
| 258 | TinyHITNet | ■■■ | ⚫ | ⚫ | 180x320,240x320,300x400,360x640,384x512,480x640,720x960,720x1280 | |||||||||
| 266 | ACVNet | ■■■ | ⚫ | ⚫ | sceneflow,kitti/240x320,320x480,384x640,480x640,544x960,720x1280 | |||||||||
| 280 | GASDA | ■■■ | ⚫ | No-LICENSE | ||||||||||
| 284 | CREStereo | ■■■ | ⚫ | ITER2,ITER5,ITER10,ITER20/240x320,320x480,360x640,480x640,480x640,720x1280 | ||||||||||
| 292 | Graft-PSMNet | ■■■ | ⚫ | 192x320,240x320,320x480,368x640,480x640,720x1280 | ||||||||||
| 294 | FSRE-Depth | ■■■ | ⚫ | ⚫ | 192x320,256x320,320x480,368x640,480x640,736x1280 | |||||||||
| 296 | MGNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 240x320,360x480,360x640,360x1280,480x640,720x1280 | |||
| 312 | NeWCRFs | ■■■ | ⚫ | 384x384,384x576,384x768,384x960,576x768,768x1344 | ||||||||||
| 313 | PyDNet2 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Mono-Depth | |
| 327 | EMDC | ■■■ | ⚫ | RGB+SarseDepth | ||||||||||
| 338 | Fast-ACVNet | ■■■ | ⚫ | Stereo/grid_sample opset=16,no_grid_sample opset=11 | ||||||||||
| 358 | CGI-Stereo | ■■■ | ⚫ | ⚫ | ⚫ | Stereo | ||||||||
| 362 | ZoeDepth | ■■■ | ⚫ | Mono-Depth | ||||||||||
| 364 | IGEV | ■■■ | ⚫ | Stereo | ||||||||||
| 371 | Lite-Mono | ■■■ | ⚫ | Mono | ||||||||||
| 384 | TCMonoDepth | ■■■ | ⚫ | Mono | ||||||||||
| 397 | MiDaSv3.1 | ■■■ | ⚫ | Mono | ||||||||||
| 415 | High-frequency-Stereo-Matching-Network | ■■■ | ⚫ | Stereo | ||||||||||
| 439 | Depth-Anything | ■■■ | ⚫ | Mono |
8. Semantic Segmentation
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | DQ | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 001 | deeplabv3 | ■■■ | ⚫ | ⚫ | ||||||||||
| 015 | Faster-Grad-CAM | ■■■ | ⚫ | ⚫ | ⚫ | |||||||||
| 020 | EdgeTPU-Deeplab | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||||
| 021 | EdgeTPU-Deeplab-slim | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||||
| 026 | Mobile-Deeplabv3-plus | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 035 | BodyPix | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | MediaPipe,MobileNet0.50/0.75/1.00,ResNet50 | |
| 057 | BiSeNetV2 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 060 | Hair Segmentation | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | WIP,MediaPipe | ||||||
| 061 | U^2-Net | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 069 | ENet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Cityscapes,512x1024 | |||||
| 075 | ERFNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Cityscapes,256x512,384x786,512x1024 | ||
| 078 | MODNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 128x128,192x192,256x256,512x512 | ||
| 082 | MediaPipe_Meet_Segmentation | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | MediaPipe,128x128,144x256,96x160 | |
| 104 | DeeplabV3-plus | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | cityscapes,200x400,400x800,800x1600 | |||
| 109 | Selfie_Segmentation | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 256x256 | ||
| 136 | road-segmentation-adas-0001 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 138 | BackgroundMattingV2 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 720x1280,2160x4096 | ||||||
| 181 | models_edgetpu_checkpoint_and_tflite_vision_segmentation-edgetpu_tflite_default_argmax | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |
| 182 | models_edgetpu_checkpoint_and_tflite_vision_segmentation-edgetpu_tflite_fused_argmax | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |
| 196 | human_segmentation_pphumanseg | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |
| 201 | CityscapesSOTA | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 180x320,240x320,360x640,480x640,720x1280 | ||
| 206 | Matting | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | PaddleSeg/modnet_mobilenetv2,modnet_hrnet_w18,modnet_resnet50_vd/256x256,384x384,512x512,640x640 | ||
| 228 | Fast-SCNN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 192x384,384x384,384x576,576x576,576x768,768x1344 |
| 238 | SUIM-Net | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | RSB,VGG/240x320,256x320,320x480,360x640,384x480,384x640,480x640,720x1280 | |||
| 242 | RobustVideoMatting | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Mbnv3,ResNet50/192x320,240x320,320x480,384x640,480x640,720x1280,1088x1920,2160x3840 | |
| 246 | SqueezeSegV3 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 21,53/180x320,240x320,320x480,360x640,480x640,720x1280 | |||
| 267 | LIOT | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 180x320,240x320,320x480,360x640,480x640,540x960,720x1280,1080x1920 | ||
| 287 | Topformer | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Tiny,Small,Base/448x448,512x512 | ||
| 295 | SparseInst | ■■■ | ⚫ | ⚫ | r50_giam_aug/192x384,384x384,384x576,384x768,576x576,576x768,768x1344 | |||||||||
| 299 | DGNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 313 | IS-Net | ■■■ | ⚫ | 180x320,240x320,320x480,360x640,480x640,720x1280,1080x1920,1080x2048,2160x4096,N-batch,Dynamic-HeightxWidth | ||||||||||
| 335 | PIDNet | ■■■ | ⚫ | Cityscapes,CamVid/Dynamic-HeightxWidth | ||||||||||
| 343 | PP-MattingV2 | ■■■ | ⚫ | ⚫ | ⚫ | HumanSeg | ||||||||
| 347 | RGBX_Semantic_Segmentation | ■■■ | ⚫ | |||||||||||
| 369 | Segment_Anything | ■■■ | ⚫ | |||||||||||
| 380 | Skin-Clothes-Hair-Segmentation-using-SMP | ■■■ | ⚫ | ⚫ | ⚫ | |||||||||
| 391 | MagicTouch | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | MediaPipe | |||||||
| 405 | Ear_Segmentation | ■■■ | ⚫ | Ear | ||||||||||
| 417 | PopNet | ■■■ | ⚫ | Saliency | ||||||||||
| 466 | People_Segmentation | ■■■ | ⚫ | UNet | ||||||||||
| 467 | Human_Parsing | ■■■ | ⚫ | |||||||||||
| 470 | RHIS | ■■■ | ⚫ | UNet+UNet | ||||||||||
| 489 | 489_Glasses-Detector | ■■■ | ⚫ | glasses |
9. Anomaly Detection
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 005 | One_Class_Anomaly_Detection | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | |||||||
| 099 | Efficientnet_Anomaly_Detection_Segmentation | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ |
10. Artistic
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | DQ | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 017 | Artistic-Style-Transfer | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||
| 019 | White-box-Cartoonization | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 037 | First_Neural_Style_Transfer | ■■■ | ⚫ | ⚫ | ⚫ | |||||||||
| 044 | Selfie2Anime | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||||
| 050 | AnimeGANv2 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||
| 062 | Facial Cartoonization | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 068 | Colorful_Image_Colorization | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | experimental | ||||
| 101 | arbitrary_image_stylization | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | magenta | |
| 113 | Anime2Sketch | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 161 | EigenGAN-Tensorflow | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Anime,CelebA | ||
| 193 | CoCosNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | RGB,256x256 |
11. Super Resolution
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | DQ | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 012 | Fast_Accurate_and_Lightweight_Super-Resolution | ■■■ | ⚫ | ⚫ | ⚫ | |||||||||
| 022 | Learning_to_See_Moving_Objects_in_the_Dark | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||||
| 071 | Noise2Noise | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | srresnet/clear only | |||||
| 076 | Deep_White_Balance | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||
| 077 | ESRGAN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 50x50->x4, 100x100->x4 | |
| 079 | MIRNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image Enhancement/40x40,80x80,120x120,120x160,120x320,120x480,120x640,120x1280,180x480,180x640,180x1280,180x320,240x320,240x480,360x480,360x640,480x640,720x1280 |
| 086 | Defocus Deblurring Using Dual-Pixel | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 090 | Ghost-free_Shadow_Removal | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 256x256 | ||||
| 111 | SRN-Deblur | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 240x320,480x640,720x1280,1024x1280 | ||
| 112 | DeblurGANv2 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | inception/mobilenetv2:256x256,320x320,480x640,736x1280,1024x1280 | ||
| 114 | Two-branch-dehazing | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 240x320,480x640,720x1280 | |||
| 133 | Real-ESRGAN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 16x16,32x32,64x64,128x128,240x320,256x256,320x320,480x640 | |||
| 152 | DeepLPF | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||||||
| 170 | Learning-to-See-in-the-Dark | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | sony/fuji, 240x320,360x480,360x640,480x640 | ||
| 171 | Fast-SRGAN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 120x160,128x128,240x320,256x256,480x640,512x512 | |||
| 172 | Real-Time-Super-Resolution | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 64x64,96x96,128x128,256x256,240x320,480x640 | |
| 176 | StableLLVE | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image/Video Enhancement,180x240,240x320,360x640,480x640,720x1280 | |
| 200 | AGLLNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image/Video Enhancement,256x256,256x384,384x512,512x640,768x768,768x1280 | |||
| 204 | HINet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | DeBlur,DeNoise,DeRain/256x320,320x480,480x640 | |
| 205 | MBLLEN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image/Video Enhancement,180x320,240x320,360x640,480x640,720x1280 |
| 207 | GLADNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image/Video Enhancement,180x320,240x320,360x640,480x640,720x1280,No-LICENSE |
| 208 | SAPNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | DeRain,180x320,240x320,360x640,480x640,720x1280 | ||
| 209 | MSBDN-DFF | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Dehazing,192x320,240x320,320x480,384x640,480x640,720x1280,No-LICENSE | ||
| 212 | GFN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | DeBlur+SuperResolution,x4/64x64,96x96,128x128,192x192,240x320,256x256,480x640,720x1280 |
| 213 | TBEFN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image Enhancement/180x320,240x320,320x480,360x640,480x640,720x1280 |
| 214 | EnlightenGAN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image Enhancement/192x320,240x320,320x480,368x640,480x640,720x1280 | |
| 215 | AOD-Net | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | DeHazing/180x320,240x320,320x480,360x640,480x640,720x1280 |
| 216 | Zero-DCE-TF | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image Enhancement/180x320,240x320,320x480,360x640,480x640,720x1280 |
| 217 | RUAS | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image Enhancement/180x320,240x320,320x480,360x640,480x640,720x1280,No-LICENSE |
| 218 | DSLR | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image Enhancement/256x256,256x384,256x512,384x640,512x640,768x1280 | ||
| 220 | HEP | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image Enhancement/180x320,240x320,320x480,360x640,480x640 | |
| 222 | LFT | ■■■ | ⚫ | Transformer/2x,4x/65x65 | ||||||||||
| 223 | DA_dahazing | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | DeHazing/192x320,240x320,320x480,360x640,480x640,720x1280,No-LICENSE | ||
| 224 | Y-net | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | DeHazing/192x320,240x320,320x480,384x640,480x640,720x1280 | |
| 225 | DRBL | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | DeHazing/192x320,240x320,320x480,384x640,480x640,720x1280 | ||
| 230 | Single-Image-Desnowing-HDCWNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | DeSnowing/512x672 | |||||
| 231 | DRBL | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image Enhancement/180x320,240x320,320x480,360x640,480x640,720x1280,No-LICENSE | |
| 232 | MIMO-UNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | DeBlur/180x320,240x320,320x480,360x640,480x640,720x1280,No-LICENSE | |
| 234 | FBCNN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | DeNoise/180x320,240x320,320x480,360x640,480x640,720x1280 | ||
| 240 | BSRGAN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | x2,x4/64x64,96x96,128x128,160x160,180x320,240x320,No-LICENSE | ||
| 241 | SCL-LLE | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image Enhancement/180x320,240x320,320x480,480x640,720x1280,No-LICENSE |
| 243 | Zero-DCE-improved | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image Enhancement/180x320,240x320,320x480,360x640,480x640,720x1280,academic use only | |
| 249 | Real-CUGAN | ■■■ | ⚫ | ⚫ | 2x,3x,4x/64x64,96x96,128x128,120x160,160x160,180x320,240x320 | |||||||||
| 251 | AU-GAN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image Enhancement/128x256,240x320,240x640,256x512,480x640,512x1024,720x1280 | ||
| 253 | TransWeather | ■■■ | ⚫ | ⚫ | DeRain,DeHaizing,DeSnow/192x320,256x320,320x480,384x640,480x640,736x1280 | |||||||||
| 261 | EfficientDerain | ■■■ | ⚫ | v4_SPA,v4_rain100H,v4_rain1400/192x320,256x320,320x480,384x640,480x640,608x800,736x1280 | ||||||||||
| 270 | HWMNet | ■■■ | ⚫ | Low-light Image Enhancement/192x320,256x320,320x480,384x640,480x640,544x960,720x1280 | ||||||||||
| 275 | FD-GAN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | DeHaizing/192x320,256x320,384x640,480x640,720x1280,1080x1920,No-LICENSE | ||
| 277 | EDN-GTM | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | DeHaizing/192x320,240x320,384x480,480x640,512x512,720x1280,1088x1920 | |||
| 281 | IMDN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | x4/64x64,96x96,128x128,120x160,160x160,180x320,192x192,256x256,180x320,240x320,360x640,480x640 | ||
| 283 | UIE-WD | ■■■ | ⚫ | Underwater Image Enhancement/WIP issue #97/192x320,240x320,320x480,360x640,480x640,720x1280,1080x1920 | ||||||||||
| 285 | Decoupled-Low-light-Image-Enhancement | ■■■ | ⚫ | Low-light Image Enhancement/180x320,240x320,360x480,360x640,480x640,720x1280 | ||||||||||
| 286 | SCI | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Low-light Image Enhancement/180x320,240x320,360x480,360x640,480x640,720x1280 | |
| 315 | Illumination-Adaptive-Transformer | ■■■ | ⚫ | Low-light Image Enhancement | ||||||||||
| 316 | night_enhancement | ■■■ | ⚫ | Low-light Image Enhancement | ||||||||||
| 320 | Dehamer | ■■■ | ⚫ | Dehazing | ||||||||||
| 323 | Stripformer | ■■■ | ⚫ | DeBlur | ||||||||||
| 325 | DehazeFormer | ■■■ | ⚫ | Dehazing | ||||||||||
| 344 | XYDeblur | ■■■ | ⚫ | DeBlur | ||||||||||
| 348 | Bread | ■■■ | ⚫ | Low-light Image Enhancement | ||||||||||
| 348 | PMN | ■■■ | ⚫ | DeNoise, Low-light Image Enhancement | ||||||||||
| 351 | RFDN | ■■■ | ⚫ | x4 | ||||||||||
| 352 | MAXIM | ■■■ | ⚫ | ⚫ | ⚫ | Dehaze only | ||||||||
| 353 | ShadowFormer | ■■■ | ⚫ | Shadow Removal | ||||||||||
| 354 | DEA-Net | ■■■ | ⚫ | ⚫ | ⚫ | DeHaze | ||||||||
| 359 | MSPFN | ■■■ | ⚫ | ⚫ | ⚫ | DeRain | ||||||||
| 361 | KBNet | ■■■ | ⚫ | Real Image Denoising | ||||||||||
| 367 | FLW-Net | ■■■ | ⚫ | Low-light Image Enhancement | ||||||||||
| 368 | C2PNet | ■■■ | ⚫ | DeHaze | ||||||||||
| 370 | Semantic-Guided-Low-Light-Image-Enhancement | ■■■ | ⚫ | Low-light Image Enhancement | ||||||||||
| 372 | URetinex-Net | ■■■ | ⚫ | Low-light Image Enhancement | ||||||||||
| 375 | SCANet | ■■■ | ⚫ | DeHaze | ||||||||||
| 377 | DRSformer | ■■■ | ⚫ | DeRain | ||||||||||
| 385 | PairLIE | ■■■ | ⚫ | Low-light Image Enhancement | ||||||||||
| 389 | WGWS-Net | ■■■ | ⚫ | DeRain,DeRainDrop,DeHaize,DeSnow | ||||||||||
| 396 | MixDehazeNet | ■■■ | ⚫ | DeHaize | ||||||||||
| 400 | CSRNet | ■■■ | ⚫ | Low-light Image Enhancement | ||||||||||
| 404 | HDR-Transformer | ■■■ | ⚫ | |||||||||||
| 409 | nighttime_dehaze | ■■■ | ⚫ | DeHaze | ||||||||||
| 411 | UDR-S2Former_deraining | ■■■ | ⚫ | DeRain | ||||||||||
| 418 | Diffusion-Low-Light | ■■■ | ⚫ | ⚫ | ⚫ | Diffusion, Low-light Image Enhancement | ||||||||
| 469 | Face_Deblurring | ■■■ | ⚫ | 64x64, HxW |
12. Sound Classifier
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | DQ | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 013 | ml-sound-classifier | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||||
| 097 | YAMNet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 098 | SPICE | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||
| 118 | Speech-enhancement | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | WIP,EdgeTPU(LeakyLeRU) | |
| 120 | FRILL | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | nofrontend | |
| 177 | BirdNET-Lite | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | non-flex | |||||
| 381 | Whisper | ■■■ | ⚫ | |||||||||||
| 382 | Light-SERNet | ■■■ | ⚫ | ⚫ | ⚫ |
13. Natural Language Processing
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 048 | Mobile_BERT | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||
| 121 | GPT2/DistillGPT2 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 122 | DistillBert | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ |
14. Text Recognition
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 052 | Handwritten_Text_Recognition | ■■■ | ⚫ | ⚫ | ⚫ | ||||||||
| 055 | Handwritten_Japanese_Recognition | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 093 | ocr_japanese | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 120x160 |
15. Action Recognition
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | DQ | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 092 | weld-porosity-detection-0001 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 247 | PoseC3D | ■■■ | ⚫ | Skeleton-based/FineGYM,NTU60_XSub,NTU120_XSub,UCF101,HMDB51/1x20x48x64x64 | ||||||||||
| 248 | MS-G3D | ■■■ | ⚫ | Skeleton-based/Kinetics,NTU60,NTU120/1x3xTx25x2 |
16. Inpainting
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | DQ | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 100 | HiFill | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||||||
| 163 | MST_inpainting | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 273 | OPN(Onion-Peel Networks) | ■■■ | ⚫ | |||||||||||
| 274 | DeepFillv2 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ |
17. GAN
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 105 | MobileStyleGAN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 310 | attentive-gan-derainnet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | DeRain/180x320,240x320,240x360,320x480,360x640,480x640,720x1280 |
18. Transformer
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 127 | dino | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | experimental,dino_deits8/dino_deits16 |
19. Others
| No. | Model Name | Link | FP32 | FP16 | INT8 | TPU | DQ | WQ | OV | CM | TFJS | TF-TRT | ONNX | Remarks |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 091 | gaze-estimation-adas-0002 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 102 | Coconet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | magenta | |||||||
| 108 | HAWP | ■■■ | ⚫ | Line Parsing,WIP | ||||||||||
| 110 | L-CNN | ■■■ | ⚫ | Line Parsing,WIP | ||||||||||
| 117 | DTLN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||
| 119 | M-LSD | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 131 | CFNet | ■■■ | ⚫ | 256x256,512x768 | ||||||||||
| 139 | PSD-Principled-Synthetic-to-Real-Dehazing-Guided-by-Physical-Priors | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||
| 140 | Ultra-Fast-Lane-Detection | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 288x800 | |
| 141 | lanenet-lane-detection | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 256x512 | |
| 154 | driver-action-recognition-adas-0002-encoder | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 155 | driver-action-recognition-adas-0002-decoder | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | |||
| 167 | LSTR | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 180x320,240x320,360x640,480x640,720x1280 | ||||
| 229 | DexiNed | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 160x320,320x480,368x640,480x640,720x1280 | |
| 233 | HRNet-for-Fashion-Landmark-Estimation | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 192x320,256x320,320x480,384x640,480x640,736x1280 | ||
| 237 | piano_transcription | ■■■ | ⚫ | ⚫ | 1x160000,Nx160000 | |||||||||
| 252 | RAFT | ■■■ | ⚫ | small,chairs,kitti,sintel,things/iters=10,20/240x320,360x480,480x640 | ||||||||||
| 254 | FullSubNet-plus | ■■■ | ⚫ | 1x1x257x100,200,500,1000,2000,3000,5000,7000,8000,10000 | ||||||||||
| 255 | FILM | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | L1,Style,VGG/256x256,180x320,240x320,360x640,480x640,720x1280,1080x1920 | ||||
| 260 | KP2D | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ResNet/128x320,192x320,192x448,192x640,256x320,256x448,256x640,320x448,384x640,480x640,512x1280,736x1280 | |||||
| 272 | CSFlow | ■■■ | ⚫ | chairs,kitti,things/iters=10,20/192x320,240x320,320x480,384x640,480x640,736x1280 | ||||||||||
| 276 | HybridNets | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | anchor_HxW.npy/256x384,256x512,384x512,384x640,384x1024,512x640,768x1280,1152x1920 | ||
| 278 | DWARF | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | StereoDepth+OpticalFlow,/192x320,256x320,384x640,512x640,512x640,768x1280 | ||
| 279 | F-Clip | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Line Parsing/ALL/192x320,256x320,320x480,384x640,480x640,736x1280 | |||
| 288 | perceptual-reflection-removal | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Reflection-Removal/180x320,240x320,360x480,360x640,480x640,720x1280 | |||
| 291 | SeAFusion | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | 180x320,240x320,360x480,360x640,480x640,720x1280 | ||||
| 297 | GazeNet | ■■■ | ⚫ | 1x7x3x256x192/NxFx3x256x192 | ||||||||||
| 298 | DEQ-Flow | ■■■ | ⚫ | AGPL-3.0 license | ||||||||||
| 306 | GMFlowNet | ■■■ | ⚫ | OpticalFlow/192x320,240x320,320x480,360x640,480x640,720x1280 | ||||||||||
| 309 | ImageForensicsOSN | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | forgery detection/180x320,240x320,320x480,360x640,480x640,720x1280 | |||
| 318 | pips | ■■■ | ⚫ | |||||||||||
| 324 | Ultra-Fast-Lane-Detection-v2 | ■■■ | ⚫ | |||||||||||
| 326 | YOLOPv2 | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||
| 328 | Stable_Diffusion | ■■■ | ⚫ | |||||||||||
| 339 | DeepLSD | ■■■ | ⚫ | |||||||||||
| 342 | ALIKE | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | ||||||
| 357 | Unimatch | ■■■ | ⚫ | ⚫ | ⚫ | OpticalFlow, StereoDepth | ||||||||
| 360 | PARSeq | ■■■ | ⚫ | ⚫ | ⚫ | Scene Text Recognition | ||||||||
| 366 | text_recognition_CRNN | ■■■ | ⚫ | ⚫ | ⚫ | CN/CH/EN | ||||||||
| 373 | LiteTrack | ■■■ | ⚫ | ⚫ | ⚫ | Tracking | ||||||||
| 374 | LaneSOD | ■■■ | ⚫ | Lane Segmentation | ||||||||||
| 378 | P2PNet_tfkeras | ■■■ | ⚫ | ⚫ | ⚫ | |||||||||
| 388 | LightGlue | ■■■ | ⚫ | Keypoint Matching | ||||||||||
| 398 | L2CS-Net | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ⚫ | Gaze Pose 448x448 | ||||||
| 401 | CLRerNet | ■■■ | ⚫ | Lane Detection | ||||||||||
| 406 | DeDoDe | ■■■ | ⚫ | ⚫ | ⚫ | Keypoint Detection, Description, Matching | ||||||||
| 407 | Generalizing_Gaze_Estimation | ■■■ | ⚫ | ⚫ | ⚫ | Gaze Pose 160x160 | ||||||||
| 408 | UAED | ■■■ | ⚫ | Edge Detectopm | ||||||||||
| 413 | DocShadow | ■■■ | ⚫ | ⚫ | Document Shadow Removal | |||||||||
| 416 | GeoNet | ■■■ | ⚫ | ⚫ | MonoDepth, CameraPose, OpticalFlow | |||||||||
| 428 | ISR | ■■■ | ⚫ | Person ReID | ||||||||||
| 487 | DDN | ■■■ | ⚫ | edge detector | ||||||||||
| 490 | ICAONet | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | ISO/IEC 19794-5 | |||||||
| 492 | Efficient-FIQA | ■■■ | ⚫ | ⚫ | ⚫ | ⚫ | Efficient Face Image Quality Assessment | |||||||
| 496 | LGT-Net | ■■■ | ⚫ | Indoor Panoramic Room Layout Estimation | ||||||||||
| 498 | DocRes | ■■■ | ⚫ | A Generalist Model Toward Unifying Document Image Restoration Tasks | ||||||||||
| 499 | LINEA | ■■■ | ⚫ | Fast and accurate line detection using scalable transformers | ||||||||||
| 500 | ScaleLSD | ■■■ | ⚫ | Scalable Deep Line Segment Detection Streamlined | ||||||||||
| 501 | LINEAE | ■■■ | ⚫ | Line Segment Detection |
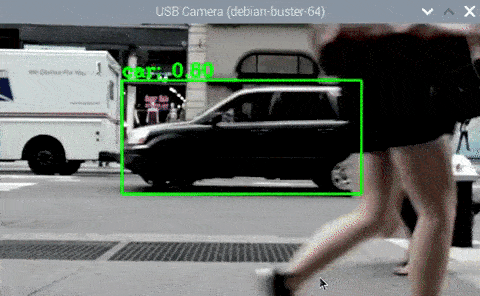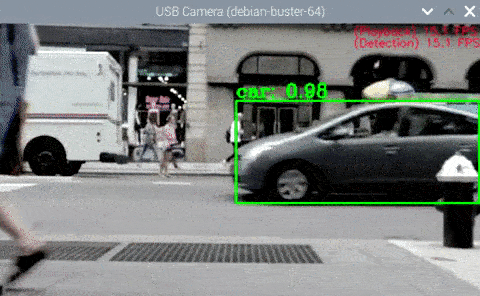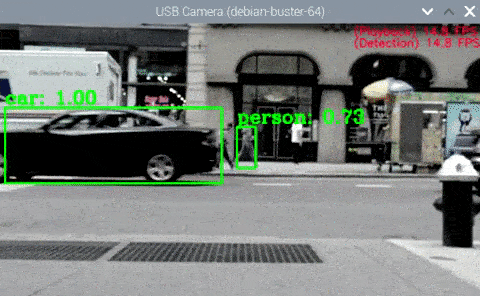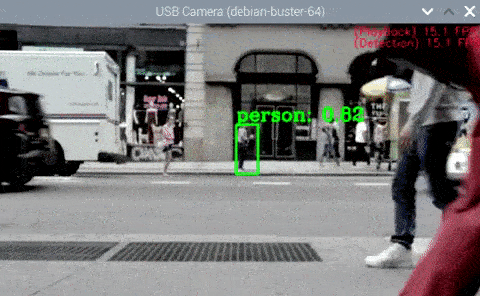
Sample.1 - Object detection by video file
- RaspberryPi4 (CPU only)
- Raspbian Buster 64bit
- Tensorflow / Tensorflow Lite with multi-thread acceleration tuning for PythonAPI
- MobileNetV2-SSDLite 300x300 Integer Quantization
- Pascal-VOC Dataset (Japanese article)
- MP4 30FPS, 640x360
- Approximately 14FPS ~ 15FPS for all processes from pre-processing, inference, post-processing, and display
$ cd 006_mobilenetv2-ssdlite/02_voc/03_integer_quantization
$ ./download.sh && cd ..
$ python3 mobilenetv2ssdlite_movie_sync.py
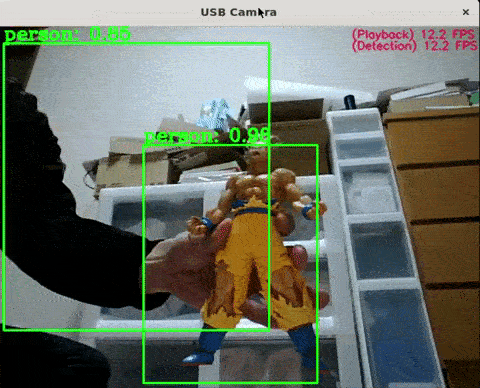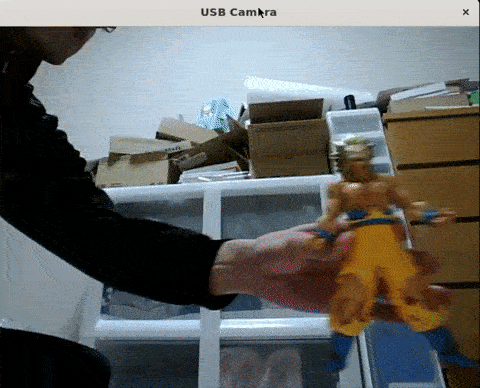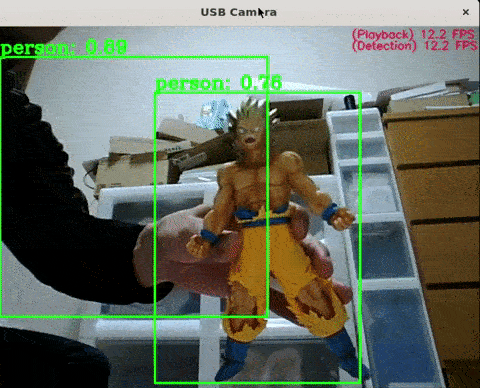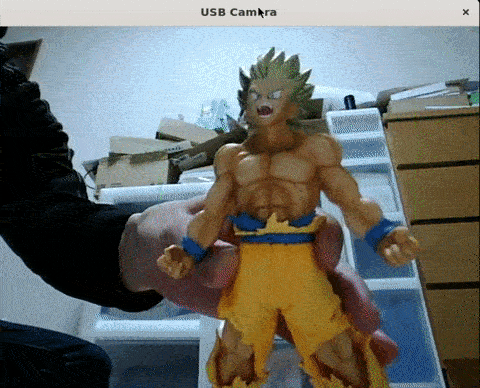
Sample.2 - Object detection by USB Camera
- RaspberryPi4 (CPU only)
- Ubuntu 19.10 64bit
- Tensorflow / Tensorflow Lite with multi-thread acceleration tuning for PythonAPI
- MobileNetV2-SSDLite 300x300 Integer Quantization
- Pascal-VOC Dataset (Japanese article)
- USB Camera, 640x480
- IPS 1080p HDMI Display
- Approximately 12FPS for all processes from pre-processing, inference, post-processing, and display
$ cd 006_mobilenetv2-ssdlite/02_voc/03_integer_quantization
$ ./download.sh && cd ..
$ python3 mobilenetv2ssdlite_usbcam_sync.py
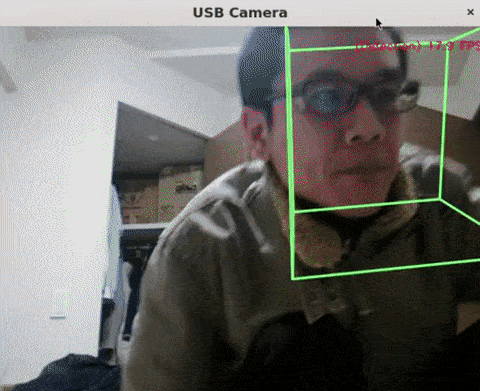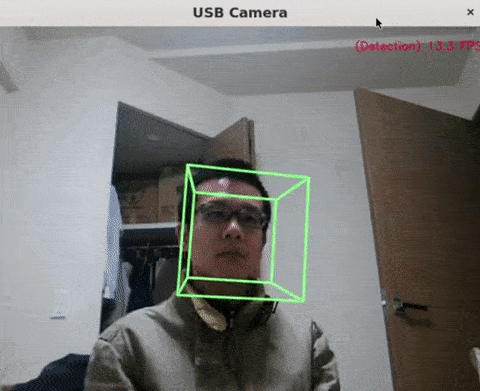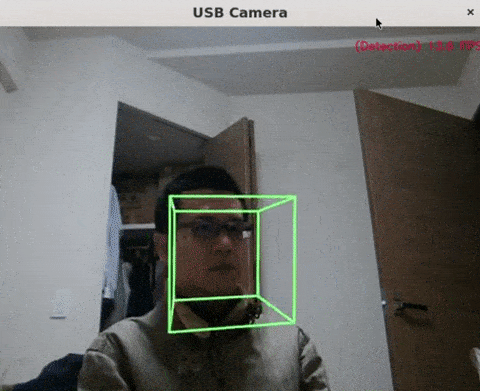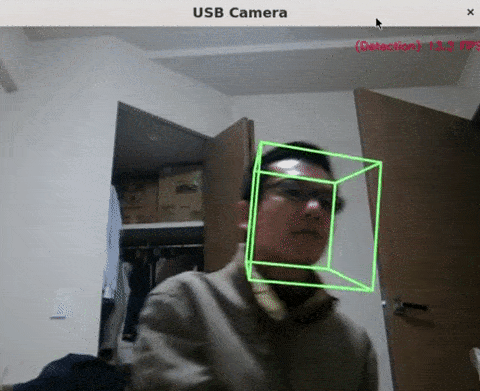
Sample.3 - Head Pose Estimation, Multi-stage inference with multi-model
- RaspberryPi4 (CPU only)
- Ubuntu 19.10 64bit
- Tensorflow / Tensorflow Lite with multi-thread acceleration tuning for PythonAPI
- [Model.1] MobileNetV2-SSDLite dm=0.5 300x300, Integer Quantization
- [Model.2] Head Pose Estimation 128x128, Integer Quantization
- WIDERFACE
- USB Camera, 640x480
- IPS 1080p HDMI Display
- Approximately 13FPS for all processes from pre-processing, inference, post-processing, and display
$ cd 025_head_pose_estimation/03_integer_quantization
$ ./download.sh
$ python3 head_pose_estimation.py
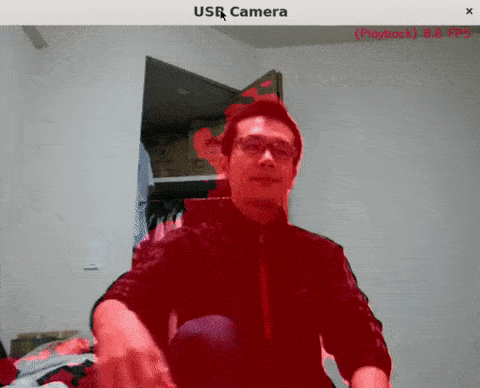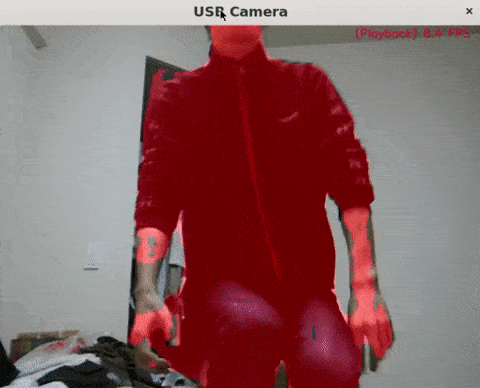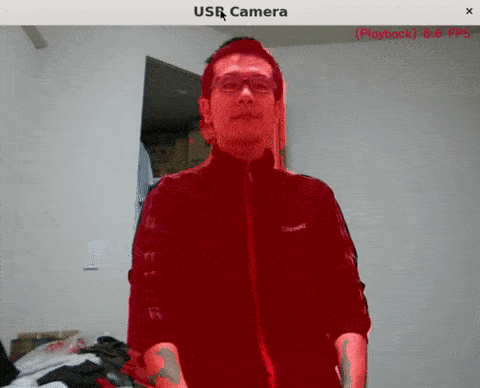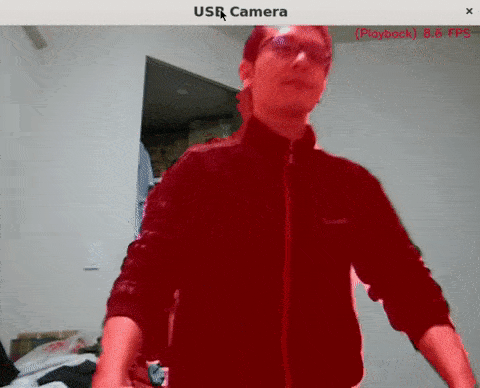
Sample.4 - Semantic Segmentation, DeeplabV3-plus 256x256
- RaspberryPi4 (CPU only)
- Ubuntu 19.10 64bit
- Tensorflow / Tensorflow Lite with multi-thread acceleration tuning for PythonAPI
- DeeplabV3-plus (MobileNetV2) Decoder 256x256, Integer Quantization
- USB Camera, 640x480
- IPS 1080p HDMI Display
- Approximately 8.5 FPS for all processes from pre-processing, inference, post-processing, and display
$ cd 026_mobile-deeplabv3-plus/03_integer_quantization
$ ./download.sh
$ python3 deeplabv3plus_usbcam.py
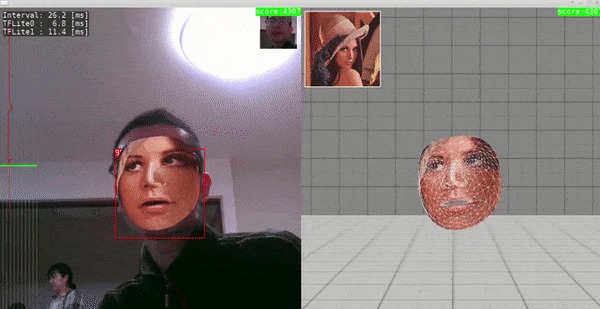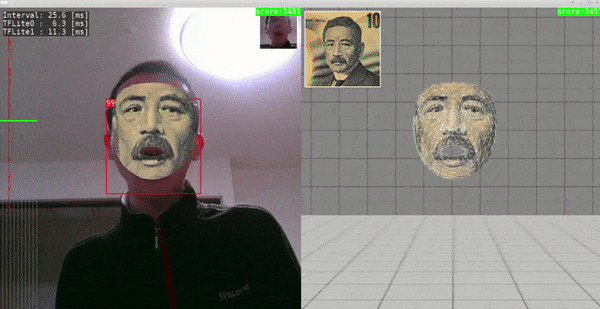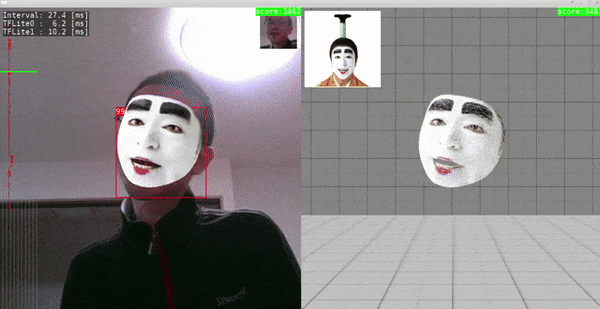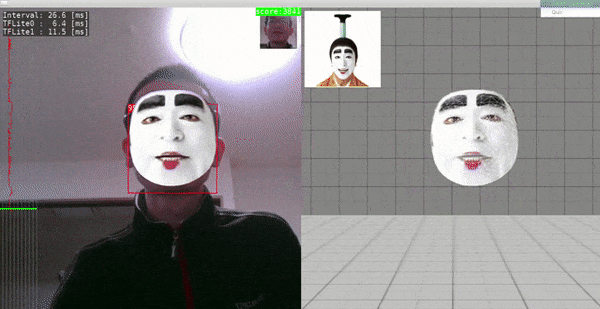
Sample.5 - MediaPipe/FaceMesh, face_detection_front_128_weight_quant, face_landmark_192_weight_quant
- Ubuntu 18.04 x86_64
- Tensorflow Lite
- C/C++
- OpenGL
- USB Camera, 640x480
$ v4l2-ctl --set-fmt-video=width=640,height=480,pixelformat=YUYV- Test Code - tflite_gles_app - gl2facemesh - @terryky
Sample.6 - MediaPipe/Objectron, object_detection_3d_chair_640x480_weight_quant
- Ubuntu 18.04 x86_64
- Tensorflow Lite
- C/C++
- OpenGL
- USB Camera, 640x480
$ v4l2-ctl --set-fmt-video=width=640,height=480,pixelformat=YUYV- Test Code - tflite_gles_app - gl2objectron - @terryky
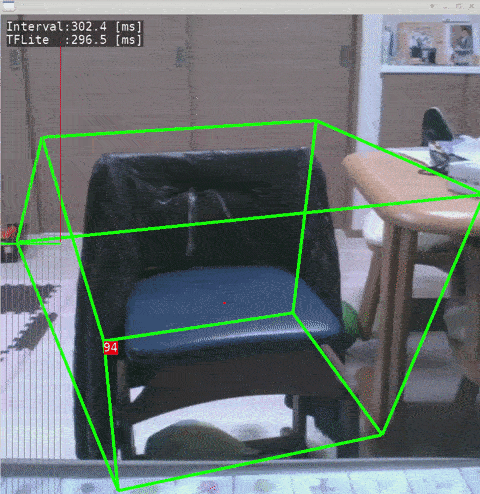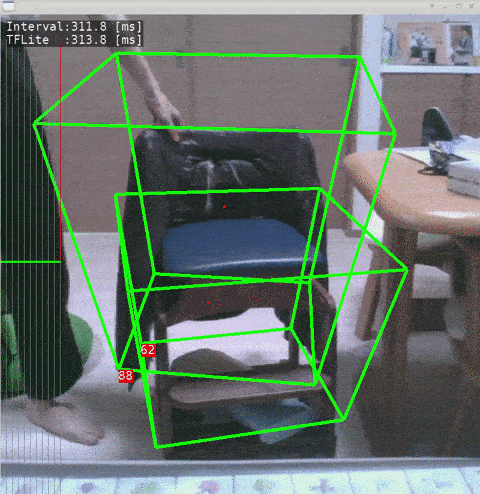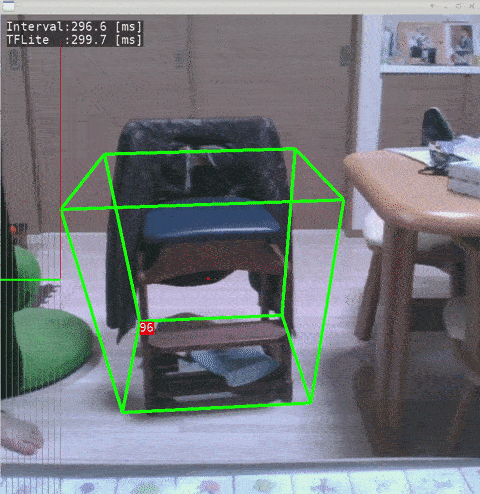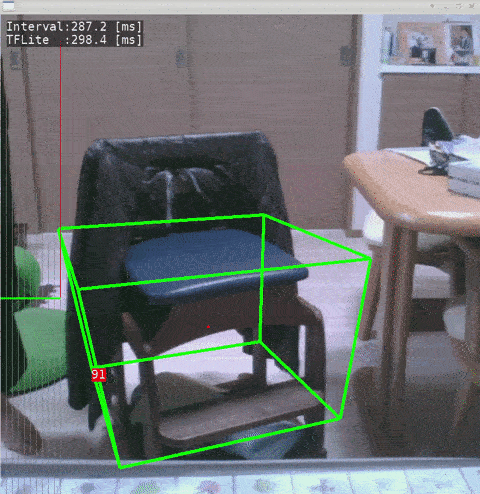
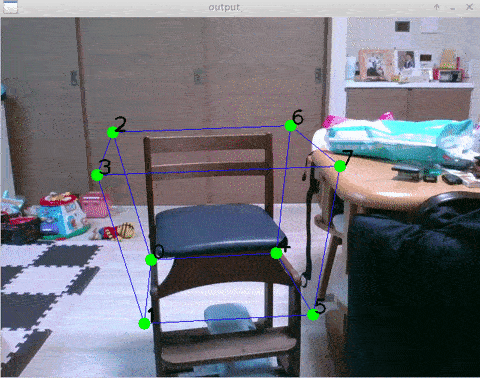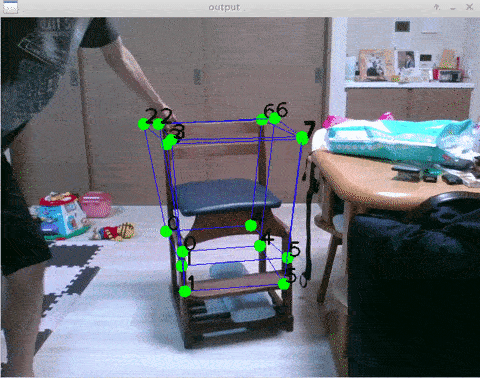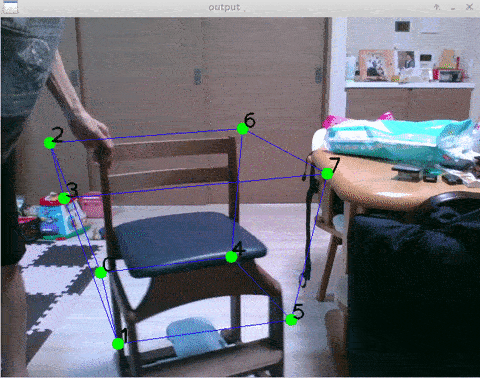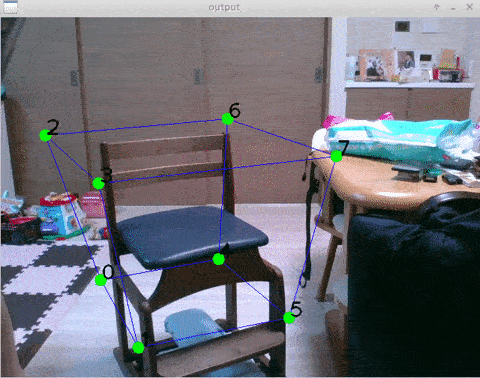
Sample.7 - MediaPipe/Objectron, object_detection_3d_chair_640x480_openvino_FP32
- Ubuntu 18.04 x86_64
- OpenVINO 2020.2
- Python
- Core i7 (CPU only)
- USB Camera, 640x480
- Test Code - objectron-3d-object-detection-openvino - @yas-sim
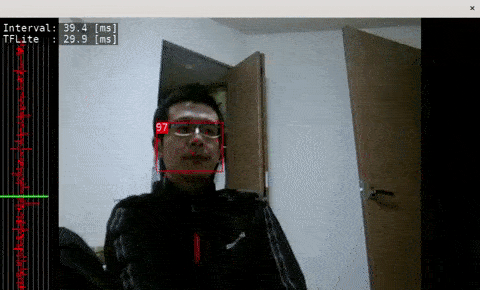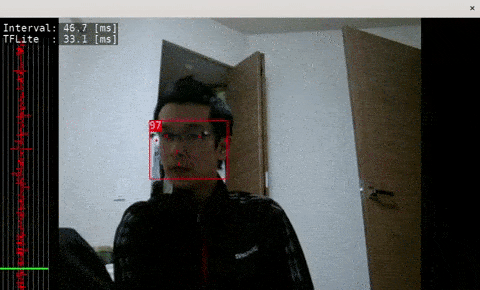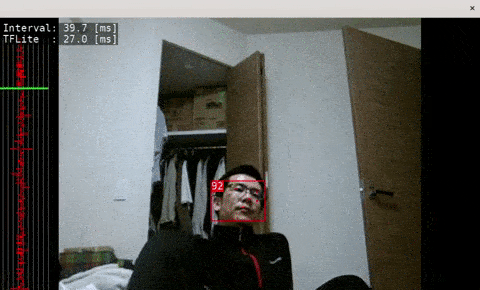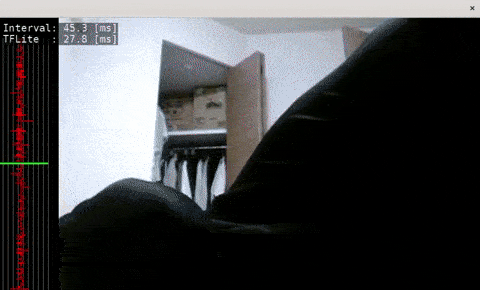
Sample.8 - MediaPipe/BlazeFace, face_detection_front_128_integer_quant
- RaspberryPi4
- Ubuntu 19.10 aarch64
- Tensorflow Lite
- C/C++
- OpenGL
- USB Camera, 640x480
$ v4l2-ctl --set-fmt-video=width=640,height=480,pixelformat=YUYV- Test Code - tflite_gles_app - gl2blazeface - @terryky
Sample.9 - MediaPipe/Hand_Detection_and_Tracking(3D Hand Pose), hand_landmark_3d_256_integer_quant.tflite + palm_detection_builtin_256_integer_quant.tflite
- RaspberryPi4
- Tensorflow Lite
- C/C++
- OpenGL
- Test Code - tflite_gles_app - gl2handpose - @terryky

Sample.10 - DBFace, 640x480_openvino_FP32
- Ubuntu 18.04 x86_64
- OpenVINO 2020.2
- Python
- Core i7 (CPU only)
- USB Camera, 640x480
- Test Code - DBFace-on-OpenVINO - @yas-sim
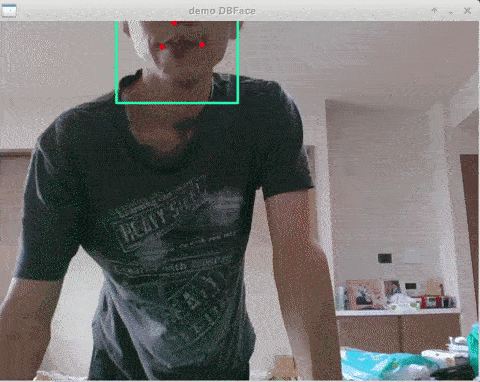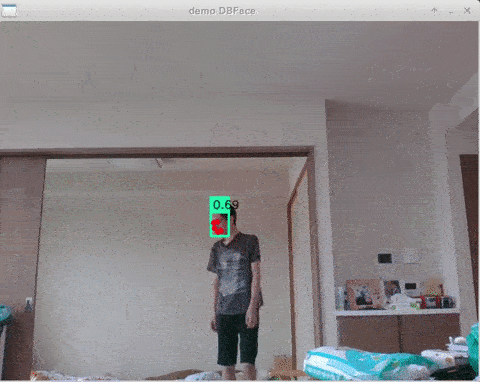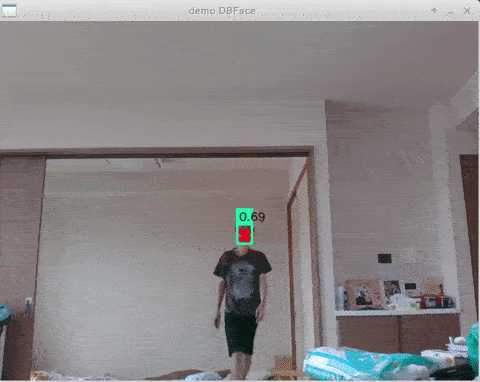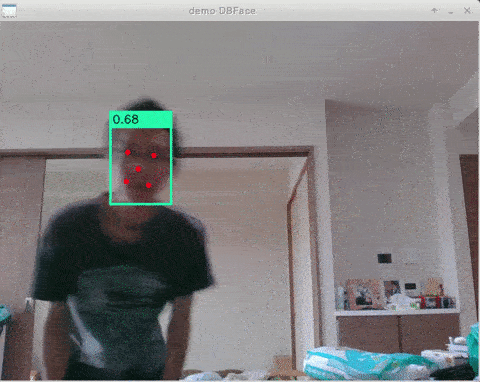
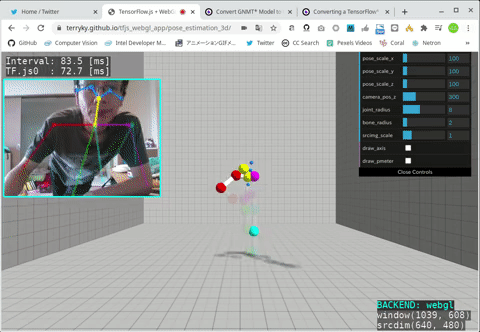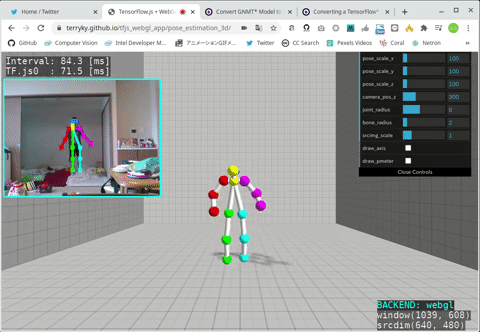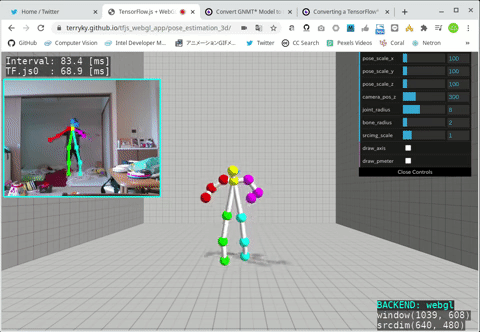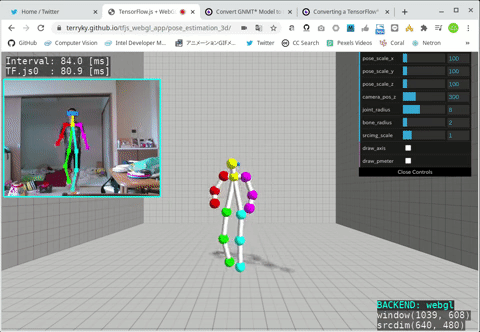
Sample.11 - Human_Pose_Estimation_3D, 640x480, Tensorflow.js + WebGL + Browser
- Ubuntu 18.04 x86_64
- Tensorflow.js
- USB Camera, 640x480
- Test Code - tfjs_webgl_app - @terryky
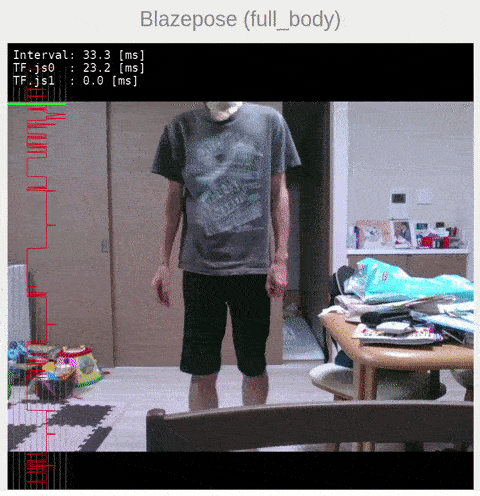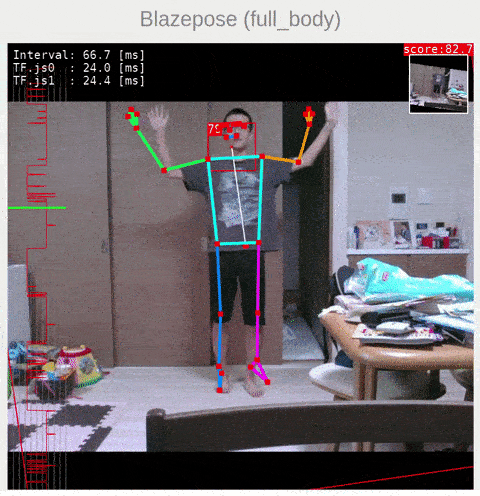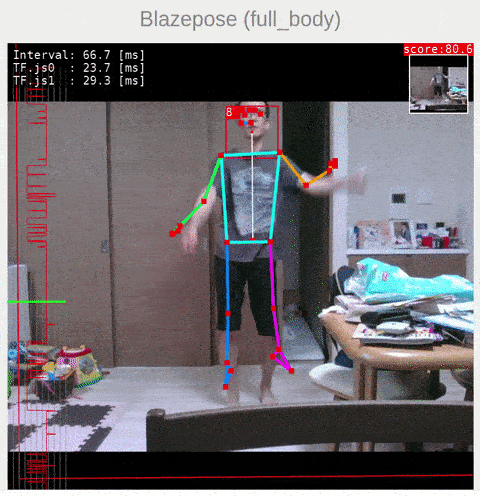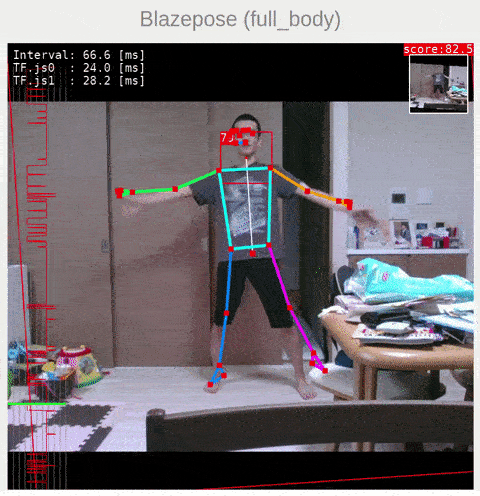
Sample.12 - BlazePose Full Body, 640x480, Tensorflow.js + WebGL + Browser
- Ubuntu 18.04 x86_64
- Tensorflow.js
- USB Camera, 640x480
- Test Code - tfjs_webgl_app - @terryky
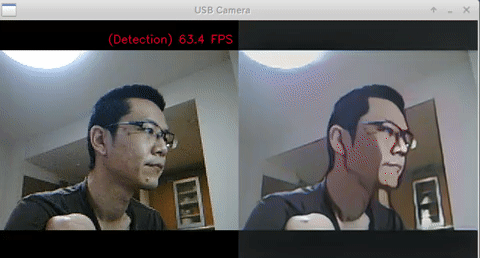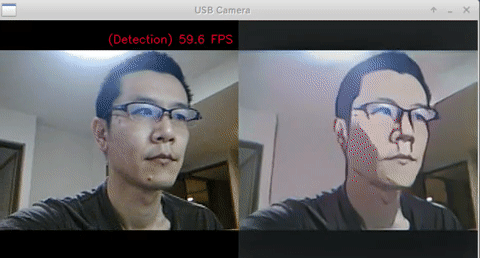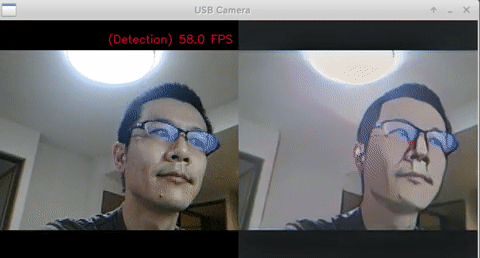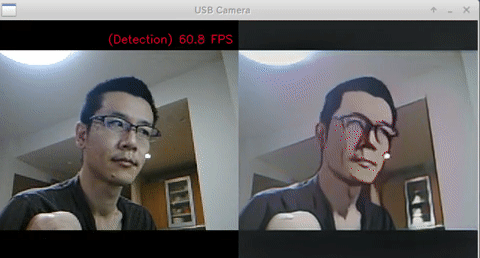
Sample.13 - Facial Cartoonization, 640x480, OpenVINO Corei7 CPU only
- Ubuntu 18.04 x86_64
- OpenVINO
- USB Camera, 640x480
- Test Code
1. Environment
- Ubuntu 18.04 x86_64
- RaspberryPi4 Raspbian Buster 32bit / Raspbian Buster 64bit / Ubuntu 19.10 aarch64
- Tensorflow-GPU v1.15.2 or Tensorflow v2.3.1+
- OpenVINO 2020.2+
- PyTorch 1.6.0+
- ONNX Opset12
- Python 3.6.8
- PascalVOC Dataset
- COCO Dataset
- Cityscapes Dataset
- Imagenette Dataset
- CelebA Dataset
- Audio file (.wav)
- WIDERFACE
- Google Colaboratory
2. Procedure
Procedure examples
2-1. MobileNetV3+DeeplabV3+PascalVOC
2-1-1. Preparation
$ cd ~
$ mkdir deeplab;cd deeplab
$ git clone --depth 1 https://github.com/tensorflow/models.git
$ cd models/research/deeplab/datasets
$ mkdir pascal_voc_seg

$ curl -sc /tmp/cookie \
  "https://drive.google.com/uc?export=download&id=1rATNHizJdVHnaJtt-hW9MOgjxoaajzdh" > /dev/null
$ CODE="$(awk '/_warning_/ {print $NF}' /tmp/cookie)"
$ curl -Lb /tmp/cookie \
  "https://drive.google.com/uc?export=download&confirm=${CODE}&id=1rATNHizJdVHnaJtt-hW9MOgjxoaajzdh" \
  -o pascal_voc_seg/VOCtrainval_11-May-2012.tar

$ sed -i -e "s/python .\/remove_gt_colormap.py/python3 .\/remove_gt_colormap.py/g" \
      -i -e "s/python .\/build_voc2012_data.py/python3 .\/build_voc2012_data.py/g" \
      download_and_convert_voc2012.sh

$ sh download_and_convert_voc2012.sh

$ cd ../..
$ mkdir -p deeplab/datasets/pascal_voc_seg/exp/train_on_train_set/train
$ mkdir -p deeplab/datasets/pascal_voc_seg/exp/train_on_train_set/eval
$ mkdir -p deeplab/datasets/pascal_voc_seg/exp/train_on_train_set/vis

$ export PATH_TO_TRAIN_DIR=${HOME}/deeplab/models/research/deeplab/datasets/pascal_voc_seg/exp/train_on_train_set/train
$ export PATH_TO_DATASET=${HOME}/deeplab/models/research/deeplab/datasets/pascal_voc_seg/tfrecord
$ export PYTHONPATH=${HOME}/deeplab/models/research:${HOME}/deeplab/models/research/deeplab:${HOME}/deeplab/models/research/slim:${PYTHONPATH}
# See feature_extractor.network_map for supported model variants.
# models/research/deeplab/core/feature_extractor.py

networks_map = {
    'mobilenet_v2': _mobilenet_v2,
    'mobilenet_v3_large_seg': mobilenet_v3_large_seg,
    'mobilenet_v3_small_seg': mobilenet_v3_small_seg,
    'resnet_v1_18': resnet_v1_beta.resnet_v1_18,
    'resnet_v1_18_beta': resnet_v1_beta.resnet_v1_18_beta,
    'resnet_v1_50': resnet_v1_beta.resnet_v1_50,
    'resnet_v1_50_beta': resnet_v1_beta.resnet_v1_50_beta,
    'resnet_v1_101': resnet_v1_beta.resnet_v1_101,
    'resnet_v1_101_beta': resnet_v1_beta.resnet_v1_101_beta,
    'xception_41': xception.xception_41,
    'xception_65': xception.xception_65,
    'xception_71': xception.xception_71,
    'nas_pnasnet': nas_network.pnasnet,
    'nas_hnasnet': nas_network.hnasnet,
}
2-1-2. "mobilenet_v3_small_seg" Float32 regular training
$ python3 deeplab/train.py \
    --logtostderr \
    --training_number_of_steps=500000 \
    --train_split="train" \
    --model_variant="mobilenet_v3_small_seg" \
    --decoder_output_stride=16 \
    --train_crop_size="513,513" \
    --train_batch_size=8 \
    --dataset="pascal_voc_seg" \
    --save_interval_secs=300 \
    --save_summaries_secs=300 \
    --save_summaries_images=True \
    --log_steps=100 \
    --train_logdir=${PATH_TO_TRAIN_DIR} \
    --dataset_dir=${PATH_TO_DATASET}
2-1-3. "mobilenet_v3_large_seg" Float32 regular training
$ python3 deeplab/train.py \
    --logtostderr \
    --training_number_of_steps=1000000 \
    --train_split="train" \
    --model_variant="mobilenet_v3_large_seg" \
    --decoder_output_stride=16 \
    --train_crop_size="513,513" \
    --train_batch_size=8 \
    --dataset="pascal_voc_seg" \
    --save_interval_secs=300 \
    --save_summaries_secs=300 \
    --save_summaries_images=True \
    --log_steps=100 \
    --train_logdir=${PATH_TO_TRAIN_DIR} \
    --dataset_dir=${PATH_TO_DATASET}
2-1-4. Visualize training status
$ tensorboard \
  --logdir ${HOME}/deeplab/models/research/deeplab/datasets/pascal_voc_seg/exp/train_on_train_set/train
2-2. MobileNetV3+DeeplabV3+Cityscaps - Post-training quantization
2-2-1. Preparation
$ cd ~
$ mkdir -p git/deeplab && cd git/deeplab
$ git clone --depth 1 https://github.com/tensorflow/models.git
$ cd models/research/deeplab/datasets
$ mkdir cityscapes && cd cityscapes

# Clone the script to generate Cityscapes Dataset.
$ git clone --depth 1 https://github.com/mcordts/cityscapesScripts.git
$ mv cityscapesScripts cityscapesScripts_ && \
  mv cityscapesScripts_/cityscapesscripts . && \
  rm -rf cityscapesScripts_

# Download Cityscapes Dataset.
# https://www.cityscapes-dataset.com/
# You will need to sign up and issue a userID and password to download the data set.
$ wget --keep-session-cookies --save-cookies=cookies.txt \
  --post-data 'username=(userid)&password=(password)&submit=Login' \
  https://www.cityscapes-dataset.com/login/
$ wget --load-cookies cookies.txt \
  --content-disposition https://www.cityscapes-dataset.com/file-handling/?packageID=1
$ wget --load-cookies cookies.txt \
  --content-disposition https://www.cityscapes-dataset.com/file-handling/?packageID=3
$ unzip gtFine_trainvaltest.zip && rm gtFine_trainvaltest.zip
$ rm README && rm license.txt
$ unzip leftImg8bit_trainvaltest.zip && rm leftImg8bit_trainvaltest.zip
$ rm README && rm license.txt

# Convert Cityscapes Dataset to TFRecords format.
$ cd ..
$ sed -i -e "s/python/python3/g" convert_cityscapes.sh
$ export PYTHONPATH=${HOME}/git/deeplab/models/research/deeplab/datasets/cityscapes:${PYTHONPATH}
$ sh convert_cityscapes.sh

# Create a checkpoint storage folder for training. If training is not required,
# there is no need to carry out.
$ cd ../..
$ mkdir -p deeplab/datasets/cityscapes/exp/train_on_train_set/train && \
  mkdir -p deeplab/datasets/cityscapes/exp/train_on_train_set/eval && \
  mkdir -p deeplab/datasets/cityscapes/exp/train_on_train_set/vis

# Download the DeepLabV3 trained model of the MobileNetV3 backbone.
$ curl -sc /tmp/cookie \
  "https://drive.google.com/uc?export=download&id=1f5ccaJmJBYwBmHvRQ77yGIUcXnqQIRY_" > /dev/null
$ CODE="$(awk '/_warning_/ {print $NF}' /tmp/cookie)"
$ curl -Lb /tmp/cookie \
  "https://drive.google.com/uc?export=download&confirm=${CODE}&id=1f5ccaJmJBYwBmHvRQ77yGIUcXnqQIRY_" \
  -o deeplab_mnv3_small_cityscapes_trainfine_2019_11_15.tar.gz
$ tar -zxvf deeplab_mnv3_small_cityscapes_trainfine_2019_11_15.tar.gz
$ rm deeplab_mnv3_small_cityscapes_trainfine_2019_11_15.tar.gz

$ curl -sc /tmp/cookie \
  "https://drive.google.com/uc?export=download&id=1QxS3G55rUQvuiBF-hztQv5zCkfPfwlVU" > /dev/null
$ CODE="$(awk '/_warning_/ {print $NF}' /tmp/cookie)"
$ curl -Lb /tmp/cookie \
  "https://drive.google.com/uc?export=download&confirm=${CODE}&id=1QxS3G55rUQvuiBF-hztQv5zCkfPfwlVU" \
  -o deeplab_mnv3_large_cityscapes_trainfine_2019_11_15.tar.gz
$ tar -zxvf deeplab_mnv3_large_cityscapes_trainfine_2019_11_15.tar.gz
$ rm deeplab_mnv3_large_cityscapes_trainfine_2019_11_15.tar.gz

$ export PATH_TO_INITIAL_CHECKPOINT=${HOME}/git/deeplab/models/research/deeplab_mnv3_small_cityscapes_trainfine/model.ckpt
$ export PATH_TO_DATASET=${HOME}/git/deeplab/models/research/deeplab/datasets/cityscapes/tfrecord
$ export PYTHONPATH=${HOME}/git/deeplab/models/research:${HOME}/git/deeplab/models/research/deeplab:${HOME}/git/deeplab/models/research/slim:${PYTHONPATH}

# Fix a bug in the data generator.
$ sed -i -e \
  "s/splits_to_sizes={'train_fine': 2975,/splits_to_sizes={'train': 2975,/g" \
  deeplab/datasets/data_generator.py

# Back up the trained model.
$ cd ${HOME}/git/deeplab/models/research
$ cp deeplab/export_model.py deeplab/export_model.py_org
$ cp deeplab_mnv3_small_cityscapes_trainfine/frozen_inference_graph.pb \
  deeplab_mnv3_small_cityscapes_trainfine/frozen_inference_graph_org.pb
$ cp deeplab_mnv3_large_cityscapes_trainfine/frozen_inference_graph.pb \
  deeplab_mnv3_large_cityscapes_trainfine/frozen_inference_graph_org.pb

# Customize "export_model.py" according to the input resolution. Must be (multiple of 8 + 1).
#   (example.1) 769 = 8 * 96 + 1
#   (example.2) 512 = 8 * 64 + 1
#   (example.3) 320 = 8 * 40 + 1
# And it is necessary to change from tf.uint8 type to tf.float32 type.
$ sed -i -e \
  "s/tf.placeholder(tf.uint8, \[1, None, None, 3\], name=_INPUT_NAME)/tf.placeholder(tf.float32, \[1, 769, 769, 3\], name=_INPUT_NAME)/g" \
  deeplab/export_model.py
2-2-2. Parameter sheet
# crop_size and image_pooling_crop_size are multiples of --decoder_output_stride + 1
# 769 = 8 * 96 + 1
# 513 = 8 * 64 + 1
# 321 = 8 * 40 + 1

# --initialize_last_layer=True initializes the final layer with the weight of
# tf_initial_checkpoint (inherits the weight)

# Named tuple to describe the dataset properties.
# deeplab/datasets/data_generator.py
DatasetDescriptor = collections.namedtuple(
    'DatasetDescriptor',
    [
        'splits_to_sizes',  # Splits of the dataset into training, val and test.
        'num_classes',  # Number of semantic classes, including the
                        # background class (if exists). For example, there
                        # are 20 foreground classes + 1 background class in
                        # the PASCAL VOC 2012 dataset. Thus, we set
                        # num_classes=21.
        'ignore_label',  # Ignore label value.
    ])

_CITYSCAPES_INFORMATION = DatasetDescriptor(
    splits_to_sizes={'train': 2975,
                     'train_coarse': 22973,
                     'trainval_fine': 3475,
                     'trainval_coarse': 23473,
                     'val_fine': 500,
                     'test_fine': 1525},
    num_classes=19,
    ignore_label=255,
)

_PASCAL_VOC_SEG_INFORMATION = DatasetDescriptor(
    splits_to_sizes={
        'train': 1464,
        'train_aug': 10582,
        'trainval': 2913,
        'val': 1449,
    },
    num_classes=21,
    ignore_label=255,
)

_ADE20K_INFORMATION = DatasetDescriptor(
    splits_to_sizes={
        'train': 20210,  # num of samples in images/training
        'val': 2000,  # num of samples in images/validation
    },
    num_classes=151,
    ignore_label=0,
)

_DATASETS_INFORMATION = {
    'cityscapes': _CITYSCAPES_INFORMATION,
    'pascal_voc_seg': _PASCAL_VOC_SEG_INFORMATION,
    'ade20k': _ADE20K_INFORMATION,
}

# A map from network name to network function. model_variant.
# deeplab/core/feature_extractor.py
networks_map = {
    'mobilenet_v2': _mobilenet_v2,
    'mobilenet_v3_large_seg': mobilenet_v3_large_seg,
    'mobilenet_v3_small_seg': mobilenet_v3_small_seg,
    'resnet_v1_18': resnet_v1_beta.resnet_v1_18,
    'resnet_v1_18_beta': resnet_v1_beta.resnet_v1_18_beta,
    'resnet_v1_50': resnet_v1_beta.resnet_v1_50,
    'resnet_v1_50_beta': resnet_v1_beta.resnet_v1_50_beta,
    'resnet_v1_101': resnet_v1_beta.resnet_v1_101,
    'resnet_v1_101_beta': resnet_v1_beta.resnet_v1_101_beta,
    'xception_41': xception.xception_41,
    'xception_65': xception.xception_65,
    'xception_71': xception.xception_71,
    'nas_pnasnet': nas_network.pnasnet,
    'nas_hnasnet': nas_network.hnasnet,
}
2-2-3. "mobilenet_v3_small_seg" Export Model
Generate Freeze Graph (.pb) with INPUT Placeholder changed from checkpoint file (.ckpt).
$ python3 deeplab/export_model.py \
    --checkpoint_path=./deeplab_mnv3_small_cityscapes_trainfine/model.ckpt \
    --export_path=./deeplab_mnv3_small_cityscapes_trainfine/frozen_inference_graph.pb \
    --num_classes=19 \
    --crop_size=769 \
    --crop_size=769 \
    --model_variant="mobilenet_v3_small_seg" \
    --image_pooling_crop_size="769,769" \
    --image_pooling_stride=4,5 \
    --aspp_convs_filters=128 \
    --aspp_with_concat_projection=0 \
    --aspp_with_squeeze_and_excitation=1 \
    --decoder_use_sum_merge=1 \
    --decoder_filters=19 \
    --decoder_output_is_logits=1 \
    --image_se_uses_qsigmoid=1 \
    --image_pyramid=1 \
    --decoder_output_stride=8
2-2-4. "mobilenet_v3_large_seg" Export Model
Generate Freeze Graph (.pb) with INPUT Placeholder changed from checkpoint file (.ckpt).
$ python3 deeplab/export_model.py \
    --checkpoint_path=./deeplab_mnv3_large_cityscapes_trainfine/model.ckpt \
    --export_path=./deeplab_mnv3_large_cityscapes_trainfine/frozen_inference_graph.pb \
    --num_classes=19 \
    --crop_size=769 \
    --crop_size=769 \
    --model_variant="mobilenet_v3_large_seg" \
    --image_pooling_crop_size="769,769" \
    --image_pooling_stride=4,5 \
    --aspp_convs_filters=128 \
    --aspp_with_concat_projection=0 \
    --aspp_with_squeeze_and_excitation=1 \
    --decoder_use_sum_merge=1 \
    --decoder_filters=19 \
    --decoder_output_is_logits=1 \
    --image_se_uses_qsigmoid=1 \
    --image_pyramid=1 \
    --decoder_output_stride=8
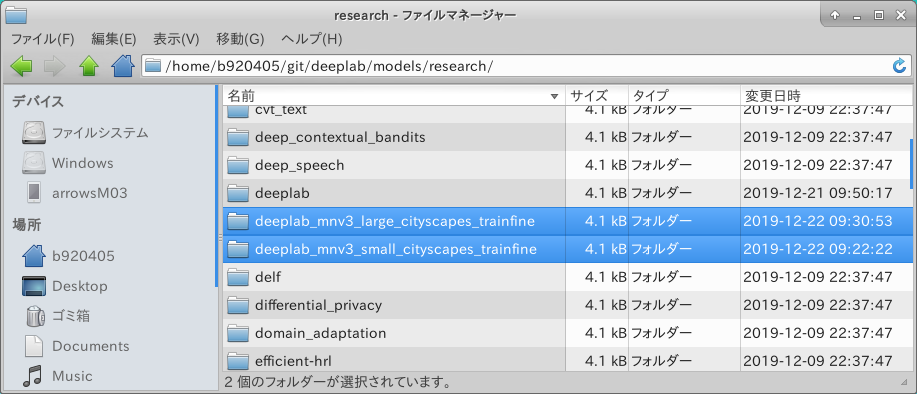
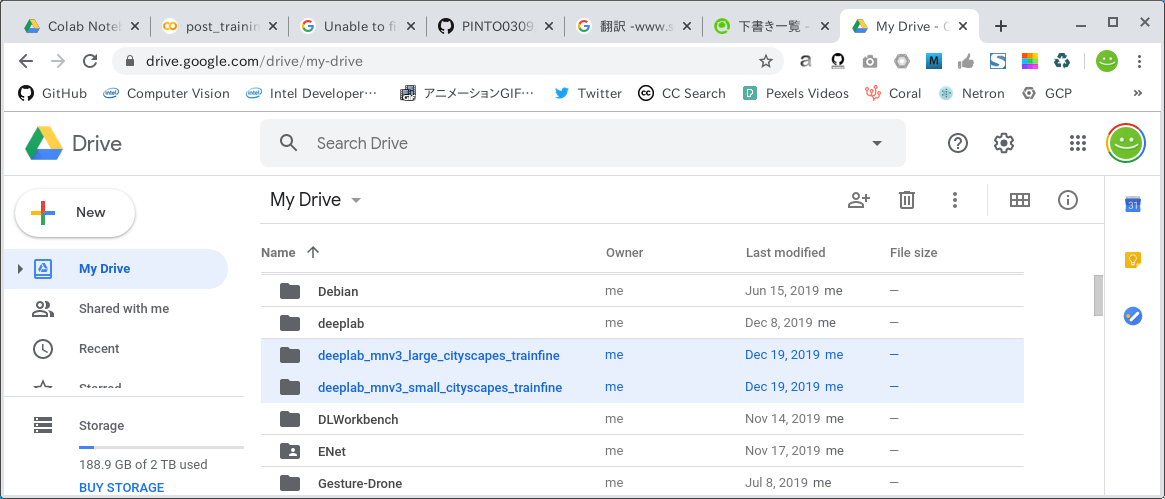
If you follow the Google Colaboratory sample procedure, copy the "deeplab_mnv3_small_cityscapes_trainfine" folder and "deeplab_mnv3_large_cityscapes_trainfine" to your Google Drive "My Drive". It is not necessary if all procedures described in Google Colaboratory are performed in a PC environment.
2-2-5. Google Colaboratory - Post-training quantization - post_training_integer_quant.ipynb
- Weight Quantization
- Integer Quantization
- Full Integer Quantization
https://colab.research.google.com/drive/1TtCJ-uMNTArpZxrf5DCNbZdn08DsiW8F
2-3. MobileNetV3+DeeplabV3+Cityscaps - Quantization-aware training
2-3-1. "mobilenet_v3_small_seg" Quantization-aware training
$ cd ${HOME}/git/deeplab/models/research
$ export PATH_TO_TRAINED_FLOAT_MODEL=${HOME}/git/deeplab/models/research/deeplab_mnv3_small_cityscapes_trainfine/model.ckpt
$ export PATH_TO_TRAIN_DIR=${HOME}/git/deeplab/models/research/deeplab/datasets/cityscapes/exp/train_on_train_set/train
$ export PATH_TO_DATASET=${HOME}/git/deeplab/models/research/deeplab/datasets/cityscapes/tfrecord

# deeplab_mnv3_small_cityscapes_trainfine
$ python3 deeplab/train.py \
    --logtostderr \
    --training_number_of_steps=5000 \
    --train_split="train" \
    --model_variant="mobilenet_v3_small_seg" \
    --train_crop_size="769,769" \
    --train_batch_size=8 \
    --dataset="cityscapes" \
    --initialize_last_layer=False \
    --base_learning_rate=3e-5 \
    --quantize_delay_step=0 \
    --image_pooling_crop_size="769,769" \
    --image_pooling_stride=4,5 \
    --aspp_convs_filters=128 \
    --aspp_with_concat_projection=0 \
    --aspp_with_squeeze_and_excitation=1 \
    --decoder_use_sum_merge=1 \
    --decoder_filters=19 \
    --decoder_output_is_logits=1 \
    --image_se_uses_qsigmoid=1 \
    --image_pyramid=1 \
    --decoder_output_stride=8 \
    --save_interval_secs=300 \
    --save_summaries_secs=300 \
    --save_summaries_images=True \
    --log_steps=100 \
    --tf_initial_checkpoint=${PATH_TO_TRAINED_FLOAT_MODEL} \
    --train_logdir=${PATH_TO_TRAIN_DIR} \
    --dataset_dir=${PATH_TO_DATASET}
2-3-2. "mobilenet_v3_large_seg" Quantization-aware training
$ cd ${HOME}/git/deeplab/models/research
$ export PATH_TO_TRAINED_FLOAT_MODEL=${HOME}/git/deeplab/models/research/deeplab_mnv3_large_cityscapes_trainfine/model.ckpt
$ export PATH_TO_TRAIN_DIR=${HOME}/git/deeplab/models/research/deeplab/datasets/cityscapes/exp/train_on_train_set/train
$ export PATH_TO_DATASET=${HOME}/git/deeplab/models/research/deeplab/datasets/cityscapes/tfrecord

# deeplab_mnv3_large_cityscapes_trainfine
$ python3 deeplab/train.py \
    --logtostderr \
    --training_number_of_steps=4350 \
    --train_split="train" \
    --model_variant="mobilenet_v3_large_seg" \
    --train_crop_size="769,769" \
    --train_batch_size=8 \
    --dataset="cityscapes" \
    --initialize_last_layer=False \
    --base_learning_rate=3e-5 \
    --quantize_delay_step=0 \
    --image_pooling_crop_size="769,769" \
    --image_pooling_stride=4,5 \
    --aspp_convs_filters=128 \
    --aspp_with_concat_projection=0 \
    --aspp_with_squeeze_and_excitation=1 \
    --decoder_use_sum_merge=1 \
    --decoder_filters=19 \
    --decoder_output_is_logits=1 \
    --image_se_uses_qsigmoid=1 \
    --image_pyramid=1 \
    --decoder_output_stride=8 \
    --save_interval_secs=300 \
    --save_summaries_secs=300 \
    --save_summaries_images=True \
    --log_steps=100 \
    --tf_initial_checkpoint=${PATH_TO_TRAINED_FLOAT_MODEL} \
    --train_logdir=${PATH_TO_TRAIN_DIR} \
    --dataset_dir=${PATH_TO_DATASET}
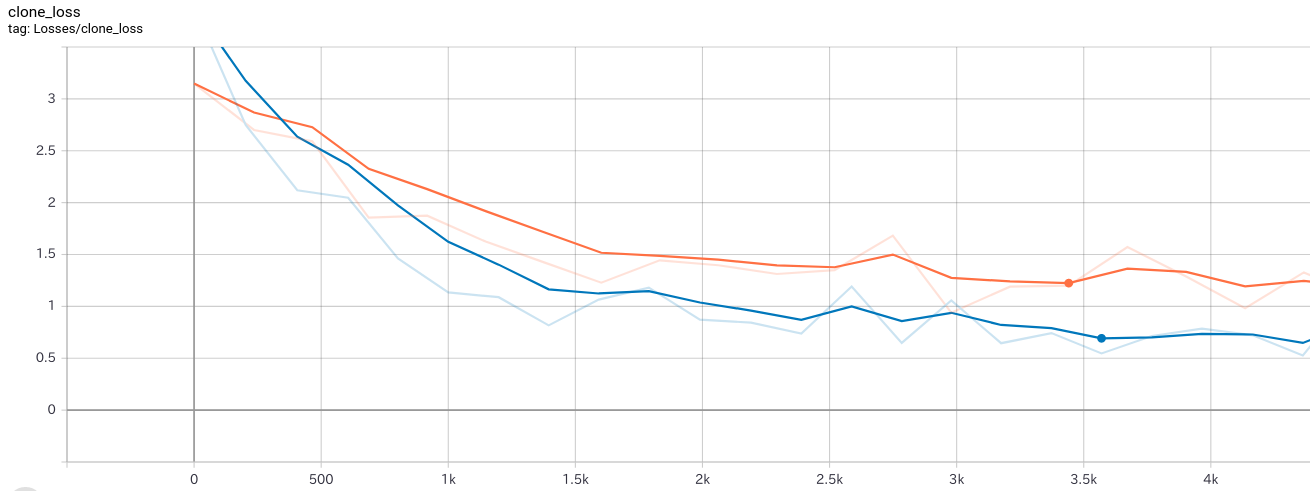
The orange line is "deeplab_mnv3_small_cityscapes_trainfine" loss.
The blue line is "deeplab_mnv3_large_cityscapes_trainfine" loss.
2-4. MobileNetV2+DeeplabV3+coco/voc - Post-training quantization
2-4-1. Preparation
$ cd ${HOME}/git/deeplab/models/research

$ wget http://download.tensorflow.org/models/deeplabv3_mnv2_dm05_pascal_trainaug_2018_10_01.tar.gz
$ tar -zxvf deeplabv3_mnv2_dm05_pascal_trainaug_2018_10_01.tar.gz
$ rm deeplabv3_mnv2_dm05_pascal_trainaug_2018_10_01.tar.gz

$ wget http://download.tensorflow.org/models/deeplabv3_mnv2_dm05_pascal_trainval_2018_10_01.tar.gz
$ tar -zxvf deeplabv3_mnv2_dm05_pascal_trainval_2018_10_01.tar.gz
$ rm deeplabv3_mnv2_dm05_pascal_trainval_2018_10_01.tar.gz

$ wget http://download.tensorflow.org/models/deeplabv3_mnv2_pascal_train_aug_2018_01_29.tar.gz
$ tar -zxvf deeplabv3_mnv2_pascal_train_aug_2018_01_29.tar.gz
$ rm deeplabv3_mnv2_pascal_train_aug_2018_01_29.tar.gz

$ sed -i -e \
  "s/tf.placeholder(tf.uint8, \[1, None, None, 3\], name=_INPUT_NAME)/tf.placeholder(tf.float32, \[1, 257, 257, 3\], name=_INPUT_NAME)/g" \
  deeplab/export_model.py

$ export PYTHONPATH=${HOME}/git/deeplab/models/research:${HOME}/git/deeplab/models/research/deeplab:${HOME}/git/deeplab/models/research/slim:${PYTHONPATH}

$ python3 deeplab/export_model.py \
  --checkpoint_path=./deeplabv3_mnv2_dm05_pascal_trainaug/model.ckpt \
  --export_path=./deeplabv3_mnv2_dm05_pascal_trainaug/frozen_inference_graph.pb \
  --model_variant="mobilenet_v2" \
  --crop_size=257 \
  --crop_size=257 \
  --depth_multiplier=0.5

$ python3 deeplab/export_model.py \
  --checkpoint_path=./deeplabv3_mnv2_dm05_pascal_trainval/model.ckpt \
  --export_path=./deeplabv3_mnv2_dm05_pascal_trainval/frozen_inference_graph.pb \
  --model_variant="mobilenet_v2" \
  --crop_size=257 \
  --crop_size=257 \
  --depth_multiplier=0.5

$ python3 deeplab/export_model.py \
  --checkpoint_path=./deeplabv3_mnv2_pascal_train_aug/model.ckpt-30000 \
  --export_path=./deeplabv3_mnv2_pascal_train_aug/frozen_inference_graph.pb \
  --model_variant="mobilenet_v2" \
  --crop_size=257 \
  --crop_size=257
2-5. MobileNetV3-SSD+coco - Post-training quantization
2-5-1. Preparation
$ cd ~
$ sudo pip3 install tensorflow-gpu==1.15.0
$ git clone --depth 1 https://github.com/tensorflow/models.git
$ cd models/research

$ git clone https://github.com/cocodataset/cocoapi.git
$ cd cocoapi/PythonAPI
$ make
$ cp -r pycocotools ../..
$ cd ../..
$ wget -O protobuf.zip https://github.com/google/protobuf/releases/download/v3.0.0/protoc-3.0.0-linux-x86_64.zip
$ unzip protobuf.zip
$ ./bin/protoc object_detection/protos/*.proto --python_out=.

$ sudo apt-get install -y protobuf-compiler python3-pil python3-lxml python3-tk
$ sudo -H pip3 install Cython contextlib2 jupyter matplotlib

$ export PYTHONPATH=${PWD}:${PWD}/object_detection:${PWD}/slim:${PYTHONPATH}

$ mkdir -p ssd_mobilenet_v3_small_coco_2019_08_14 && cd ssd_mobilenet_v3_small_coco_2019_08_14
$ curl -sc /tmp/cookie "https://drive.google.com/uc?export=download&id=1uqaC0Y-yRtzkpu1EuZ3BzOyh9-i_3Qgi" > /dev/null
$ CODE="$(awk '/_warning_/ {print $NF}' /tmp/cookie)"
$ curl -Lb /tmp/cookie "https://drive.google.com/uc?export=download&confirm=${CODE}&id=1uqaC0Y-yRtzkpu1EuZ3BzOyh9-i_3Qgi" -o ssd_mobilenet_v3_small_coco_2019_08_14.tar.gz
$ tar -zxvf ssd_mobilenet_v3_small_coco_2019_08_14.tar.gz
$ rm ssd_mobilenet_v3_small_coco_2019_08_14.tar.gz
$ cd ..

$ mkdir -p ssd_mobilenet_v3_large_coco_2019_08_14 && cd ssd_mobilenet_v3_large_coco_2019_08_14
$ curl -sc /tmp/cookie "https://drive.google.com/uc?export=download&id=1NGLjKRWDQZ_kibQHlLZ7Eetuuz1waC7X" > /dev/null
$ CODE="$(awk '/_warning_/ {print $NF}' /tmp/cookie)"
$ curl -Lb /tmp/cookie "https://drive.google.com/uc?export=download&confirm=${CODE}&id=1NGLjKRWDQZ_kibQHlLZ7Eetuuz1waC7X" -o ssd_mobilenet_v3_large_coco_2019_08_14.tar.gz
$ tar -zxvf ssd_mobilenet_v3_large_coco_2019_08_14.tar.gz
$ rm ssd_mobilenet_v3_large_coco_2019_08_14.tar.gz
$ cd ..
2-5-2. Create a conversion script from checkpoint format to saved_model format
import tensorflow as tf
import os
import shutil
from tensorflow.python.saved_model import tag_constants
from tensorflow.python.tools import freeze_graph
from tensorflow.python import ops
from tensorflow.tools.graph_transforms import TransformGraph

def freeze_model(saved_model_dir, output_node_names, output_filename):
  output_graph_filename = os.path.join(saved_model_dir, output_filename)
  initializer_nodes = ''
  freeze_graph.freeze_graph(
      input_saved_model_dir=saved_model_dir,
      output_graph=output_graph_filename,
      saved_model_tags = tag_constants.SERVING,
      output_node_names=output_node_names,
      initializer_nodes=initializer_nodes,
      input_graph=None,
      input_saver=False,
      input_binary=False,
      input_checkpoint=None,
      restore_op_name=None,
      filename_tensor_name=None,
      clear_devices=True,
      input_meta_graph=False,
  )

def get_graph_def_from_file(graph_filepath):
  tf.reset_default_graph()
  with ops.Graph().as_default():
    with tf.gfile.GFile(graph_filepath, 'rb') as f:
      graph_def = tf.GraphDef()
      graph_def.ParseFromString(f.read())
      return graph_def

def optimize_graph(model_dir, graph_filename, transforms, input_name, output_names, outname='optimized_model.pb'):
  input_names = [input_name] # change this as per how you have saved the model
  graph_def = get_graph_def_from_file(os.path.join(model_dir, graph_filename))
  optimized_graph_def = TransformGraph(
      graph_def,
      input_names,
      output_names,
      transforms)
  tf.train.write_graph(optimized_graph_def,
                      logdir=model_dir,
                      as_text=False,
                      name=outname)
  print('Graph optimized!')

def convert_graph_def_to_saved_model(export_dir, graph_filepath, input_name, outputs):
  graph_def = get_graph_def_from_file(graph_filepath)
  with tf.Session(graph=tf.Graph()) as session:
    tf.import_graph_def(graph_def, name='')
    tf.compat.v1.saved_model.simple_save(
        session,
        export_dir,# change input_image to node.name if you know the name
        inputs={input_name: session.graph.get_tensor_by_name('{}:0'.format(node.name))
            for node in graph_def.node if node.op=='Placeholder'},
        outputs={t.rstrip(":0"):session.graph.get_tensor_by_name(t) for t in outputs}
    )
    print('Optimized graph converted to SavedModel!')

tf.compat.v1.enable_eager_execution()

# Look up the name of the placeholder for the input node
graph_def=get_graph_def_from_file('./ssd_mobilenet_v3_small_coco_2019_08_14/frozen_inference_graph.pb')
input_name_small=""
for node in graph_def.node:
    if node.op=='Placeholder':
        print("##### ssd_mobilenet_v3_small_coco_2019_08_14 - Input Node Name #####", node.name) # this will be the input node
        input_name_small=node.name

# Look up the name of the placeholder for the input node
graph_def=get_graph_def_from_file('./ssd_mobilenet_v3_large_coco_2019_08_14/frozen_inference_graph.pb')
input_name_large=""
for node in graph_def.node:
    if node.op=='Placeholder':
        print("##### ssd_mobilenet_v3_large_coco_2019_08_14 - Input Node Name #####", node.name) # this will be the input node
        input_name_large=node.name

# ssd_mobilenet_v3 output names
output_node_names = ['raw_outputs/class_predictions','raw_outputs/box_encodings']
outputs = ['raw_outputs/class_predictions:0','raw_outputs/box_encodings:0']

# Optimizing the graph via TensorFlow library
transforms = []
optimize_graph('./ssd_mobilenet_v3_small_coco_2019_08_14', 'frozen_inference_graph.pb', transforms, input_name_small, output_node_names, outname='optimized_model_small.pb')
optimize_graph('./ssd_mobilenet_v3_large_coco_2019_08_14', 'frozen_inference_graph.pb', transforms, input_name_large, output_node_names, outname='optimized_model_large.pb')

# convert this to a s TF Serving compatible mode - ssd_mobilenet_v3_small_coco_2019_08_14
shutil.rmtree('./ssd_mobilenet_v3_small_coco_2019_08_14/0', ignore_errors=True)
convert_graph_def_to_saved_model('./ssd_mobilenet_v3_small_coco_2019_08_14/0',
                                 './ssd_mobilenet_v3_small_coco_2019_08_14/optimized_model_small.pb', input_name_small, outputs)

# convert this to a s TF Serving compatible mode - ssd_mobilenet_v3_large_coco_2019_08_14
shutil.rmtree('./ssd_mobilenet_v3_large_coco_2019_08_14/0', ignore_errors=True)
convert_graph_def_to_saved_model('./ssd_mobilenet_v3_large_coco_2019_08_14/0',
                                 './ssd_mobilenet_v3_large_coco_2019_08_14/optimized_model_large.pb', input_name_large, outputs)
2-5-3. Confirm the structure of saved_model 【ssd_mobilenet_v3_small_coco_2019_08_14】
$ saved_model_cli show --dir ./ssd_mobilenet_v3_small_coco_2019_08_14/0 --all

MetaGraphDef with tag-set: 'serve' contains the following SignatureDefs:

signature_def['serving_default']:
  The given SavedModel SignatureDef contains the following input(s):
    inputs['normalized_input_image_tensor'] tensor_info:
        dtype: DT_FLOAT
        shape: (1, 320, 320, 3)
        name: normalized_input_image_tensor:0
  The given SavedModel SignatureDef contains the following output(s):
    outputs['raw_outputs/box_encodings'] tensor_info:
        dtype: DT_FLOAT
        shape: (1, 2034, 4)
        name: raw_outputs/box_encodings:0
    outputs['raw_outputs/class_predictions'] tensor_info:
        dtype: DT_FLOAT
        shape: (1, 2034, 91)
        name: raw_outputs/class_predictions:0
  Method name is: tensorflow/serving/predict
2-5-4. Confirm the structure of saved_model 【ssd_mobilenet_v3_large_coco_2019_08_14】
$ saved_model_cli show --dir ./ssd_mobilenet_v3_large_coco_2019_08_14/0 --all

MetaGraphDef with tag-set: 'serve' contains the following SignatureDefs:

signature_def['serving_default']:
  The given SavedModel SignatureDef contains the following input(s):
    inputs['normalized_input_image_tensor'] tensor_info:
        dtype: DT_FLOAT
        shape: (1, 320, 320, 3)
        name: normalized_input_image_tensor:0
  The given SavedModel SignatureDef contains the following output(s):
    outputs['raw_outputs/box_encodings'] tensor_info:
        dtype: DT_FLOAT
        shape: (1, 2034, 4)
        name: raw_outputs/box_encodings:0
    outputs['raw_outputs/class_predictions'] tensor_info:
        dtype: DT_FLOAT
        shape: (1, 2034, 91)
        name: raw_outputs/class_predictions:0
  Method name is: tensorflow/serving/predict
2-5-5. Creating the destination path for the calibration test dataset 6GB
$ curl -sc /tmp/cookie "https://drive.google.com/uc?export=download&id=1Uk9F4Tc-9UgnvARIVkloSoePUynyST6E" > /dev/null
$ CODE="$(awk '/_warning_/ {print $NF}' /tmp/cookie)"
$ curl -Lb /tmp/cookie "https://drive.google.com/uc?export=download&confirm=${CODE}&id=1Uk9F4Tc-9UgnvARIVkloSoePUynyST6E" -o TFDS.tar.gz
$ tar -zxvf TFDS.tar.gz
$ rm TFDS.tar.gz
2-5-6. Quantization
2-5-6-1. ssd_mobilenet_v3_small_coco_2019_08_14
import tensorflow as tf
import tensorflow_datasets as tfds
import numpy as np

def representative_dataset_gen():
  for data in raw_test_data.take(100):
    image = data['image'].numpy()
    image = tf.image.resize(image, (320, 320))
    image = image[np.newaxis,:,:,:]
    yield [image]

tf.compat.v1.enable_eager_execution()

# Generating a calibration data set
#raw_test_data, info = tfds.load(name="coco/2017", with_info=True, split="test", data_dir="./TFDS")
raw_test_data, info = tfds.load(name="coco/2017", with_info=True, split="test", data_dir="./TFDS", download=False)
print(info)

# Weight Quantization - Input/Output=float32
converter = tf.lite.TFLiteConverter.from_saved_model('./ssd_mobilenet_v3_small_coco_2019_08_14/0')
converter.optimizations = [tf.lite.Optimize.OPTIMIZE_FOR_SIZE]
tflite_quant_model = converter.convert()
with open('./ssd_mobilenet_v3_small_coco_2019_08_14/mobilenet_v3_small_weight_quant.tflite', 'wb') as w:
    w.write(tflite_quant_model)
print("Weight Quantization complete! - mobilenet_v3_small_weight_quant.tflite")

# Integer Quantization - Input/Output=float32
converter = tf.lite.TFLiteConverter.from_saved_model('./ssd_mobilenet_v3_small_coco_2019_08_14/0')
converter.optimizations = [tf.lite.Optimize.DEFAULT]
converter.representative_dataset = representative_dataset_gen
tflite_quant_model = converter.convert()
with open('./ssd_mobilenet_v3_small_coco_2019_08_14/mobilenet_v3_small_integer_quant.tflite', 'wb') as w:
    w.write(tflite_quant_model)
print("Integer Quantization complete! - mobilenet_v3_small_integer_quant.tflite")

# Full Integer Quantization - Input/Output=int8
converter = tf.lite.TFLiteConverter.from_saved_model('./ssd_mobilenet_v3_small_coco_2019_08_14/0')
converter.optimizations = [tf.lite.Optimize.DEFAULT]
converter.representative_dataset = representative_dataset_gen
converter.target_spec.supported_ops = [tf.lite.OpsSet.TFLITE_BUILTINS_INT8]
converter.inference_input_type = tf.uint8
converter.inference_output_type = tf.uint8
tflite_quant_model = converter.convert()
with open('./ssd_mobilenet_v3_small_coco_2019_08_14/mobilenet_v3_small_full_integer_quant.tflite', 'wb') as w:
    w.write(tflite_quant_model)
print("Full Integer Quantization complete! - mobilenet_v3_small_full_integer_quant.tflite")
2-5-6-2. ssd_mobilenet_v3_large_coco_2019_08_14
import tensorflow as tf
import tensorflow_datasets as tfds
import numpy as np

def representative_dataset_gen():
  for data in raw_test_data.take(100):
    image = data['image'].numpy()
    image = tf.image.resize(image, (320, 320))
    image = image[np.newaxis,:,:,:]
    yield [image]

tf.compat.v1.enable_eager_execution()

# Generating a calibration data set
#raw_test_data, info = tfds.load(name="coco/2017", with_info=True, split="test", data_dir="./TFDS")
raw_test_data, info = tfds.load(name="coco/2017", with_info=True, split="test", data_dir="./TFDS", download=False)

# Weight Quantization - Input/Output=float32
converter = tf.lite.TFLiteConverter.from_saved_model('./ssd_mobilenet_v3_large_coco_2019_08_14/0')
converte