Enable AI assistant clients like Cursor, Windsurf and Claude Desktop to control Unreal Engine through natural language using the Model Context Protocol (MCP).
Essential utilities for building production-ready AI applications with Vercel AI SDK. State management, debugging, structured streaming, intelligent agents, and caching.
The MCP server for Azure DevOps, bringing the power of Azure DevOps directly to your agents.
关键参数与规格
关键参数与规格
参数
值
语言
Python
类别
AI Engineering
子类别
Give agent knowledge
关键词
Data processing, OCR, Unstructured data extraction
星标数
2,083
分叉数
158
贡献者
7
创建日期
2025-03-25
更新日期
2026-10-14
1 天星标数
0
7 天星标数
-2
排名
9,009
上次排名
9,055
排名变化
46
7 天星标排名
18,244
上次 7 天星标排名
18,198
7 天星标排名变化
-46
总星标排名
6,139
上次总星标排名
6,134
总星标排名变化
-5
国家
USA
README 摘录
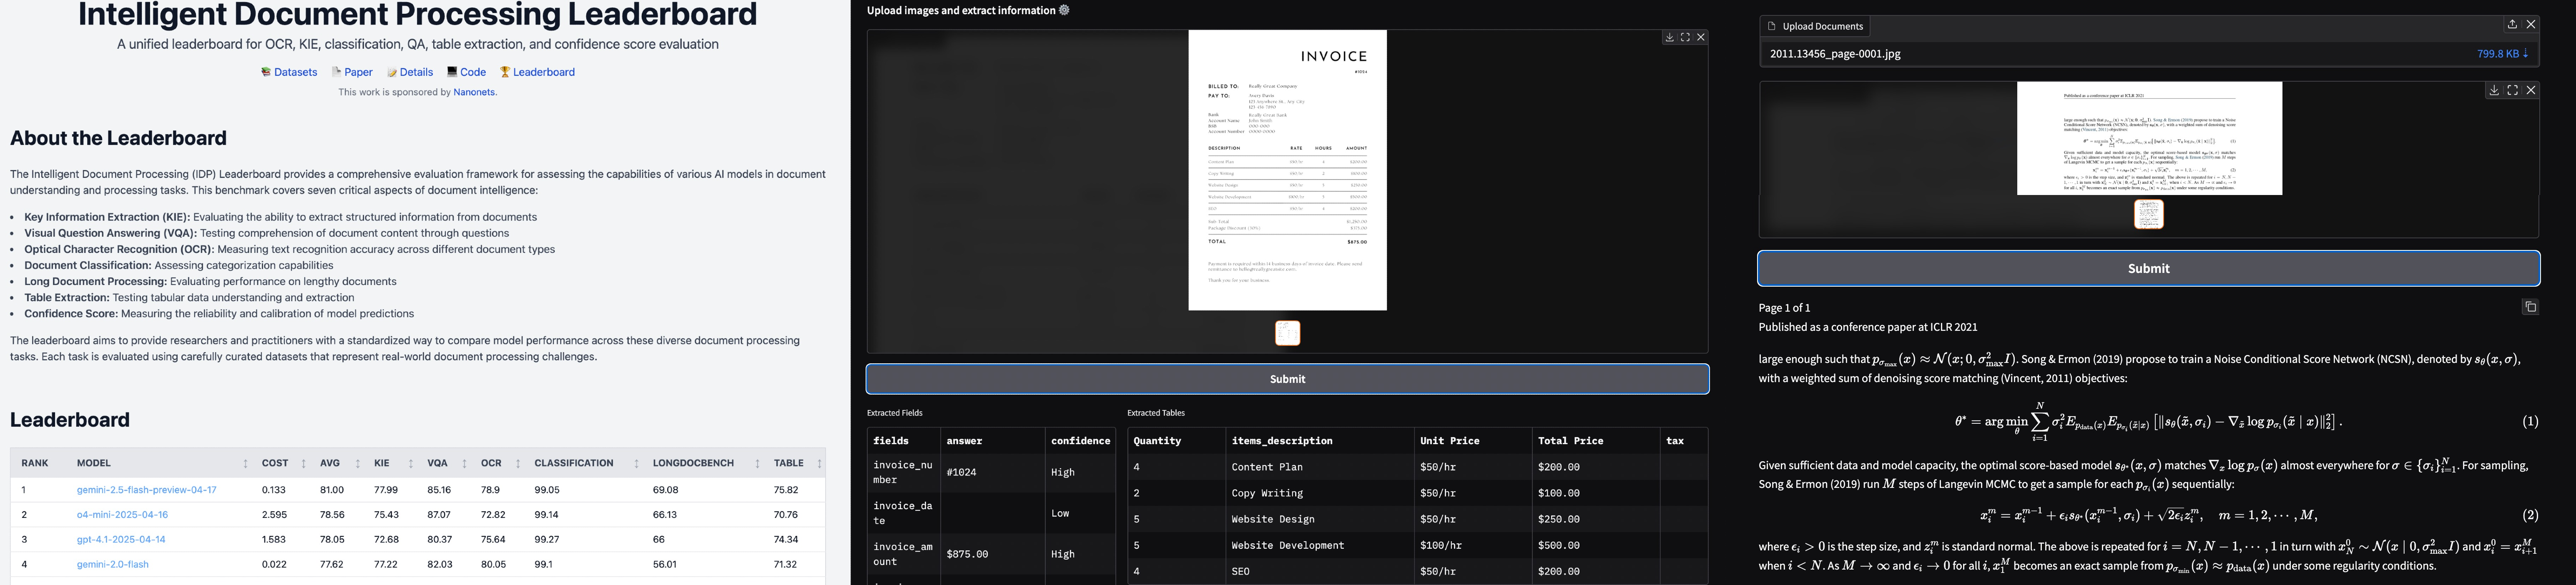
docext An on-premises document information extraction and benchmarking toolkit. New Model Release: Nanonets-OCR-s **We're excited to announce the release of Nanonets-OCR-s, a compact 3B parameter model specifically trained for efficient image to markdown conversion with semantic understanding for images, signatures, watermarks, etc. ** 📢 Read the full announcement | 🤗 Hugging Face model Overview docext is a comprehensive on-premises document intelligence toolkit powered by vision-language models (VLMs). It provides three core capabilities: **📄 PDF & Image to Markdown Conversion
**: Transform documents into structured markdown with intelligent content recognition, including LaTeX equations, signatures, watermarks, tables, and semantic tagging. **🔍 Document Information Extraction**: OCR-free extraction of structured information (fields, tables, etc. ) from documents such as invoices, passports, and other document types, with confidence scoring. **📊 Intelligent Document Processing Leaderboard**: A comprehensive benchmarking platform that tracks and evaluates vision-language model performance across OCR, Key Information Extraction (KIE), document classification, table extraction, and other intelligent document processing tasks. Features PDF and Image to
Markdown Convert both PDF and images to markdown with content recognition and semantic tagging. **LaTeX Equation Recognition**: Convert both inline and block LaTeX equations in images to markdown. **Intelligent Image Description**: Generate a detailed description for all images in the document within tags. **Signature Detection**: Detect and mark signatures and watermarks in the document. Signatures text are extracted within tags. **Watermark Detection**: Detect and mark watermarks in the document. Watermarks text are extracted within tags. **Page Number Detection**: Detect and
mark page numbers in the document. **Checkboxes and Radio Buttons**: Converts form checkboxes and radio buttons into standardized Unicode symbols (☐, ☑, ☒). **Table Detection**: Convert complex tables into html tables. 🔍 For in-depth information, see the release blog. For setup instructions and additional details, check out the full feature guide for the pdf to markdown. Intelligent Document Processing Leaderboard This benchmark evaluates performance across seven key document intelligence challenges: **Key Information Extraction (KIE)**: Extract structured fields from unstructured document text. **Visual Question
Answering (VQA)**: Assess understanding of document content via question-answering. **Optical Character Recognition (OCR)**: Measure accuracy in recognizing printed and handwritten text. **Document Classification**: Evaluate how accurately models categorize various document types. **Long Document Processing**: Test models' reasoning over lengthy, context-rich documents. **Table Extraction**: Benchmark structured data extraction from complex tabular formats. **Confidence Score Calibration**: Evaluate the reliability and confidence of model predictions. 🔍 For in-depth information, see the release blog. 📊 **Live leaderboard:** For setup instructions and additional details
, check out the full feature guide for the Intelligent Document Processing Leaderboard. Docext **Flexible extraction**: Define custom fields or use pre-built templates **Table extraction**: Extract structured tabular data from documents **Confidence scoring**: Get confidence levels for extracted information **On-premises deployment**: Run entirely on your own infrastructure (Linux, MacOS) **Multi-page support**: Process documents with multiple pages **REST API**: Programmatic access for integration with your applications **Pre-built templates**: Ready-to-use templates for common document types: Invoices Passports
Add/delete new fields/columns for other templates. For more details (Installation, Usage, and so on), please check out the
常见问题
记录了多少星标和分叉?
NanoNets/docext 有 2,083 个星标和 158 个分叉。
仓库排名是多少?
NanoNets/docext 排名第 9,009。
记录的语言和类别是什么?
NanoNets/docext 有 2,083 个星标,语言为 Python,类别为 AI Engineering。
An on-premises document information extraction and benchmarking toolkit.
New Model Release: Nanonets-OCR-s
We're excited to announce the release of Nanonets-OCR-s, a compact 3B parameter model specifically trained for efficient image to markdown conversion with semantic understanding for images, signatures, watermarks, etc.!
docext is a comprehensive on-premises document intelligence toolkit powered by vision-language models (VLMs). It provides three core capabilities:
📄 PDF & Image to Markdown Conversion: Transform documents into structured markdown with intelligent content recognition, including LaTeX equations, signatures, watermarks, tables, and semantic tagging.
🔍 Document Information Extraction: OCR-free extraction of structured information (fields, tables, etc.) from documents such as invoices, passports, and other document types, with confidence scoring.
📊 Intelligent Document Processing Leaderboard: A comprehensive benchmarking platform that tracks and evaluates vision-language model performance across OCR, Key Information Extraction (KIE), document classification, table extraction, and other intelligent document processing tasks.
Features
PDF and Image to Markdown
Convert both PDF and images to markdown with content recognition and semantic tagging.
LaTeX Equation Recognition: Convert both inline and block LaTeX equations in images to markdown.
Intelligent Image Description: Generate a detailed description for all images in the document within `` tags.
Signature Detection: Detect and mark signatures and watermarks in the document. Signatures text are extracted within `` tags.
Watermark Detection: Detect and mark watermarks in the document. Watermarks text are extracted within `` tags.
Page Number Detection: Detect and mark page numbers in the document. Page numbers are extracted within `` tags.
Checkboxes and Radio Buttons: Converts form checkboxes and radio buttons into standardized Unicode symbols (☐, ☑, ☒).
Table Detection: Convert complex tables into html tables.
Flexible extraction: Define custom fields or use pre-built templates
Table extraction: Extract structured tabular data from documents
Confidence scoring: Get confidence levels for extracted information
On-premises deployment: Run entirely on your own infrastructure (Linux, MacOS)
Multi-page support: Process documents with multiple pages
REST API: Programmatic access for integration with your applications
Pre-built templates: Ready-to-use templates for common document types:
Invoices
Passports
Add/delete new fields/columns for other templates.
For more details (Installation, Usage, and so on), please check out the feature guide.
Change Log
Latest Updates
12-06-2025 - Added pdf and image to markdown support.
06-06-2025 - Added gemini-2.5-pro-preview-06-05 evaluation metrics to the leaderboard.
04-06-2025 - Added support for PDF and multiple documents in docext extraction.
Older Changes
23-05-2025 – Added gemini-2.5-pro-preview-03-25, claude-sonnet-4 evaluation metrics to the leaderboard.
17-05-2025 – Added InternVL3-38B-Instruct, qwen2.5-vl-32b-instruct evaluation metrics to the leaderboard.
16-05-2025 – Added gemma-3-27b-it evaluation metrics to the leaderboard.
12-05-2025 – Added Claude 3.7 sonnet, mistral-medium-3 evaluation metrics to the leaderboard.
About
docext is developed by Nanonets, a leader in document AI and intelligent document processing solutions. Nanonets is committed to advancing the field of document understanding through open-source contributions and innovative AI technologies. If you are looking for information extraction solutions for your business, please visit our website to learn more.
Contributing
We welcome contributions! Please see contribution.md for guidelines.
If you have a feature request or need support for a new model, feel free to open an issue—we'd love to discuss it further!
Troubleshooting
If you encounter any issues while using docext, please refer to our Troubleshooting guide for common problems and solutions.
License
This project is licensed under the Apache License 2.0 - see the LICENSE file for details.