← 开源
JDAI-CV

CoTNet

This is an official implementation for "Contextual Transformer Networks for Visual Recognition".

Model DevelopmentArchitecturePython
在 GitHub 打开
增长势头
+024 小时新增 Star0.0%
538
Star
83
Fork
+0
本周
2
贡献者
创建于 2021-05-06 · 更新于 2026-09-30 · 今日第 17453 名
主要开发者
YehLiPanda-Peter

JDAI-CV/CoTNet 排名第 17,453,有 538 个星标。

同类别比较

JDAI-CV/CoTNet 排名第 17,453,此处有 8 个同类条目;LucasAlegre/morl-baselines 排名第 17,454。

同类别比较
名称排名指标
woodrush/neural-art-tf17,434
语言:
Python
星标数:
540
分叉数:
111
简介:
"A neural algorithm of Artistic style" in tensorflow
yym6472/ConSERT17,435
语言:
Python
星标数:
540
分叉数:
79
简介:
Code for our ACL 2021 paper - ConSERT: A Contrastive Framework for Self-Supervised Sentence Representation Transfer
fancompute/wavetorch17,442
语言:
Python
星标数:
539
分叉数:
85
简介:
🌊 Numerically solving and backpropagating through the wave equation
wl-zhao/VPD17,451
语言:
Jupyter Notebook
星标数:
539
分叉数:
33
简介:
[ICCV 2023] VPD is a framework that leverages the high-level and low-level knowledge of a pre-trained text-to-image diffusion model to downstream visual perception tasks.
LucasAlegre/morl-baselines17,454
语言:
Python
星标数:
538
分叉数:
110
简介:
Multi-Objective Reinforcement Learning algorithms implementations.
hwwang55/GraphGAN17,460
语言:
Python
星标数:
538
分叉数:
156
简介:
A tensorflow implementation of GraphGAN (Graph Representation Learning with Generative Adversarial Nets)
mlfoundations/open_lm17,463
语言:
Python
星标数:
538
分叉数:
80
简介:
A repository for research on medium sized language models.
swarm-subnet/Langostino17,465
语言:
Python
星标数:
538
分叉数:
82
简介:
Langostino - An open-source autonomous drone platform using ROS2 and AI-powered flight control. A complete reference implementation for building, understanding, and extending real-world drone autonomy.
关键参数与规格
关键参数与规格
参数值
语言Python
类别Model Development
子类别Architecture
关键词Computer vision
星标数538
分叉数83
贡献者2
创建日期2021-05-06
更新日期2026-09-30
1 天星标数0
7 天星标数0
排名17,453
上次排名17,240
排名变化-213
7 天星标排名16,110
上次 7 天星标排名16,115
7 天星标排名变化5
总星标排名18,275
上次总星标排名18,249
总星标排名变化-26
国家China
README 摘录

Introduction This repository is the official implementation of **Contextual Transformer Networks for Visual Recognition**. CoT is a unified self-attention building block, and acts as an alternative to standard convolutions in ConvNet. As a result, it is feasible to replace convolutions with their CoT counterparts for strengthening vision backbones with contextualized self-attention. 2021/3/25-2021/6/5: CVPR 2021 Open World Image Classification Challenge **Rank 1** in Open World Image Classification Challenge @ CVPR 2021. (Team name: VARMS) Usage

The code is mainly based on timm. Clone the repository: Train First, download the ImageNet dataset. To train CoTNet-50 on ImageNet on a single node with 8 gpus for 350 epochs run: The training scripts for CoTNet (e. , CoTNet-50) can be found in the cot_experiments folder. Accuracy CoTNet models consistently obtain better top-1 accuracy with less inference time than other vision backbones across both default and advanced training setups. In a word, CoTNet models seek better

inference time-accuracy trade-offs than existing vision backbones. Results on ImageNet | name | resolution | #params | FLOPs | Top-1 Acc. 6 | GoogleDrive / Baidu | | CoTNeXt-50 | 224 | 30. 9 | GoogleDrive / Baidu | | SE-CoTNetD-50 | 224 | 23. 8 | GoogleDrive / Baidu | | CoTNet-101 | 224 | 38. 2 | GoogleDrive / Baidu | | CoTNeXt-101 | 224 | 53. 4 | GoogleDrive / Baidu | | SE-CoTNetD-101 | 224 | 40. 5 | GoogleDrive / Baidu | | SE-CoTNetD-152 | 224 | 55. 0 | GoogleDrive / Baidu | | SE-CoTNetD-152 | 320 | 55. 1 | GoogleDrive / Baidu | Access code for Baidu is

**cotn** CoTNet on downstream tasks For **Object Detection and Instance Segmentation**, please see CoTNet for Object Detection and Instance Segmentation. Citing Contextual Transformer Networks Acknowledgements Thanks the contribution of timm and awesome PyTorch team.

常见问题

记录了多少星标和分叉?

JDAI-CV/CoTNet 有 538 个星标和 83 个分叉。

仓库排名是多少?

JDAI-CV/CoTNet 排名第 17,453。

记录的语言和类别是什么?

JDAI-CV/CoTNet 有 538 个星标,语言为 Python,类别为 Model Development。

哪个仓库排名最接近?

JDAI-CV/CoTNet 与 LucasAlegre/morl-baselines 比较,后者排名第 17,454,有 538 个星标。

README

Introduction

This repository is the official implementation of Contextual Transformer Networks for Visual Recognition.

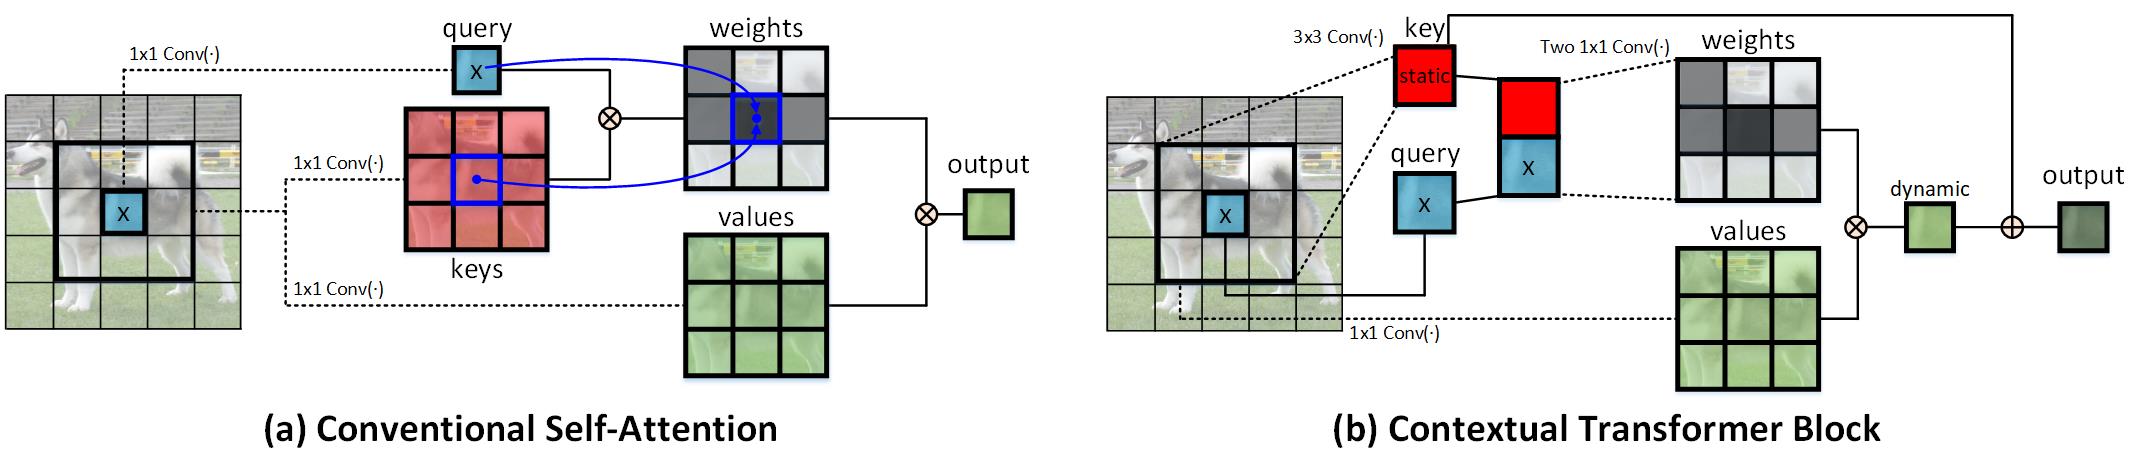
CoT is a unified self-attention building block, and acts as an alternative to standard convolutions in ConvNet. As a result, it is feasible to replace convolutions with their CoT counterparts for strengthening vision backbones with contextualized self-attention.

2021/3/25-2021/6/5: CVPR 2021 Open World Image Classification Challenge

Rank 1 in Open World Image Classification Challenge @ CVPR 2021. (Team name: VARMS)

Usage

The code is mainly based on timm.

Requirement:

  • PyTorch 1.8.0+
  • Python3.7
  • CUDA 10.1+
  • CuPy.

Clone the repository:

git clone https://github.com/JDAI-CV/CoTNet.git

Train

First, download the ImageNet dataset. To train CoTNet-50 on ImageNet on a single node with 8 gpus for 350 epochs run:

python -m torch.distributed.launch --nproc_per_node=8 train.py --folder ./experiments/cot_experiments/CoTNet-50-350epoch

The training scripts for CoTNet (e.g., CoTNet-50) can be found in the cot_experiments folder.

Inference Time vs. Accuracy

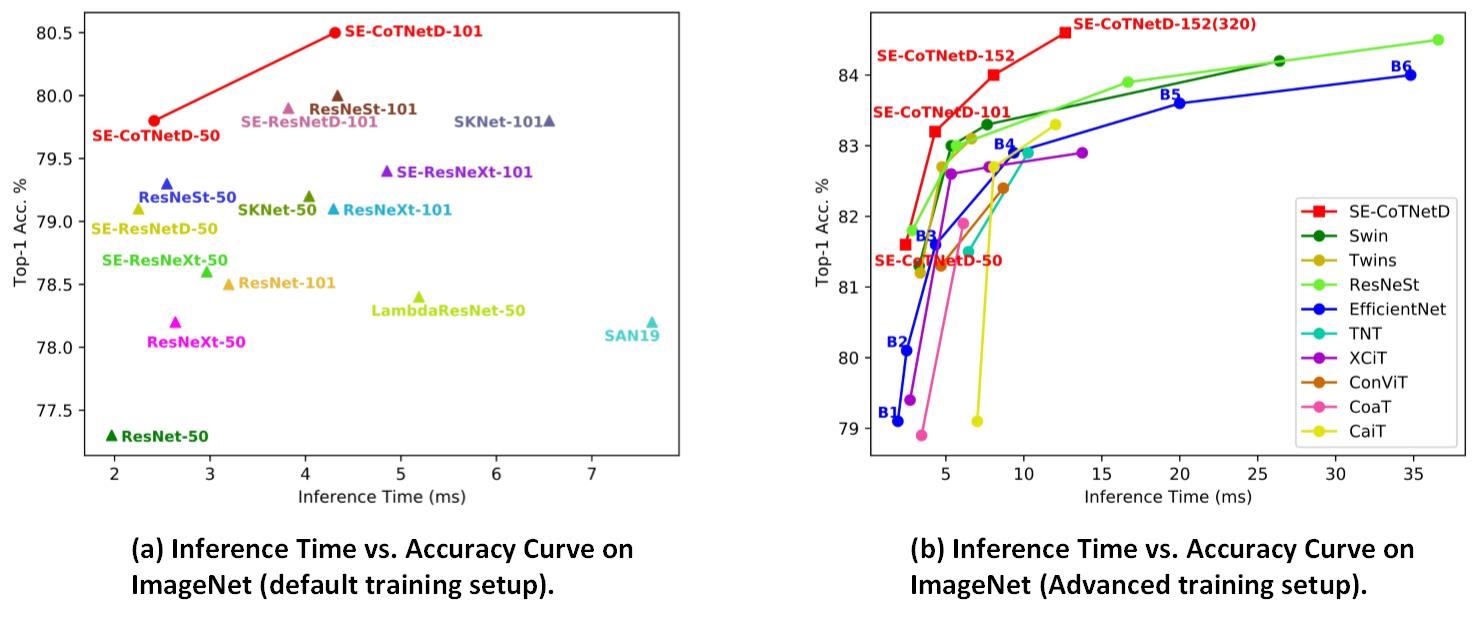
CoTNet models consistently obtain better top-1 accuracy with less inference time than other vision backbones across both default and advanced training setups. In a word, CoTNet models seek better inference time-accuracy trade-offs than existing vision backbones.
Results on ImageNet

name resolution #params FLOPs Top-1 Acc. Top-5 Acc. model
CoTNet-50 224 22.2M 3.3 81.3 95.6 GoogleDrive / Baidu
CoTNeXt-50 224 30.1M 4.3 82.1 95.9 GoogleDrive / Baidu
SE-CoTNetD-50 224 23.1M 4.1 81.6 95.8 GoogleDrive / Baidu
CoTNet-101 224 38.3M 6.1 82.8 96.2 GoogleDrive / Baidu
CoTNeXt-101 224 53.4M 8.2 83.2 96.4 GoogleDrive / Baidu
SE-CoTNetD-101 224 40.9M 8.5 83.2 96.5 GoogleDrive / Baidu
SE-CoTNetD-152 224 55.8M 17.0 84.0 97.0 GoogleDrive / Baidu
SE-CoTNetD-152 320 55.8M 26.5 84.6 97.1 GoogleDrive / Baidu

Access code for Baidu is cotn

CoTNet on downstream tasks

For Object Detection and Instance Segmentation, please see CoTNet for Object Detection and Instance Segmentation.

Citing Contextual Transformer Networks

@article{cotnet,
  title={Contextual Transformer Networks for Visual Recognition},
  author={Li, Yehao and Yao, Ting and Pan, Yingwei and Mei, Tao},
  journal={arXiv preprint arXiv:2107.12292},
  year={2021}
}

Acknowledgements

Thanks the contribution of timm and awesome PyTorch team.

排名相邻
同类项目