Grounding DINO 1.5
IDEA Research's Most Capable Open-World Object Detection Model Series.
The project provides examples for using the models, which are hosted on DeepDataSpace.

✨ First-Time Application: If you are interested in our project and wish to try our algorithm, you will need to apply for the corresponding API Token through our request API token website for your first attempt.
📌 Request Additional Token Quotas: At this stage, we now support WeChat Pay as a payment channel. Users can purchase additional API calls through our official platform. If you encounter any issues during the purchase process or have other collaboration needs, feel free to contact us via this email address: [email protected].
🔥 Grounding DINO 1.6 Release: Grounding DINO 1.6 Pro establishes new SOTA results on zero-shot transfer benchmarks: 55.4 AP on COCO , 57.7 AP on LVIS-minival, and 51.1 AP on LVIS-val. Moreover, it demonstrates significantly superior performance compared with the 1.5 Pro model in several specific detection scenarios, such as Animal Detection, Text Detection, etc. Please refer to our Official Blog for more details about the 1.6 release.
Contents
- Contents
- Introduction
- Model Framework
- Performance
- API Usage
- Case Analysis and Qualitative Visualization
- Related Work
- LICENSE
- BibTeX
Introduction
We introduce Grounding DINO 1.5, a suite of advanced open-set object detection models developed by IDEA Research, which aims to advanced the "Edge" of open-set object detection. The suite encompasses two models:
-
Grounding DINO 1.5 Pro: Our most capable model for open-set object detection, which is designed for stronger generalization capability across a wide range of scenarios.
-
Grounding DINO 1.5 Edge: Our most efficient model for edge computing scenarios, which is optimized for faster speed demanded in many applications requiring edge deployment.
Note: We use "edge" for its dual meaning both as in pushing the boundaries and as in running on edge devices.
Model Framework
The overall framework of Grounding DINO 1.5 is as the following image:

Grounding DINO 1.5 Pro preserves the core architecture of Grounding DINO which employs a deep early fusion architecture.
Performance
Side-by-Side Performance Comparison with Grounding DINO

Grounding DINO 1.5 Pro vs Grounding DINO
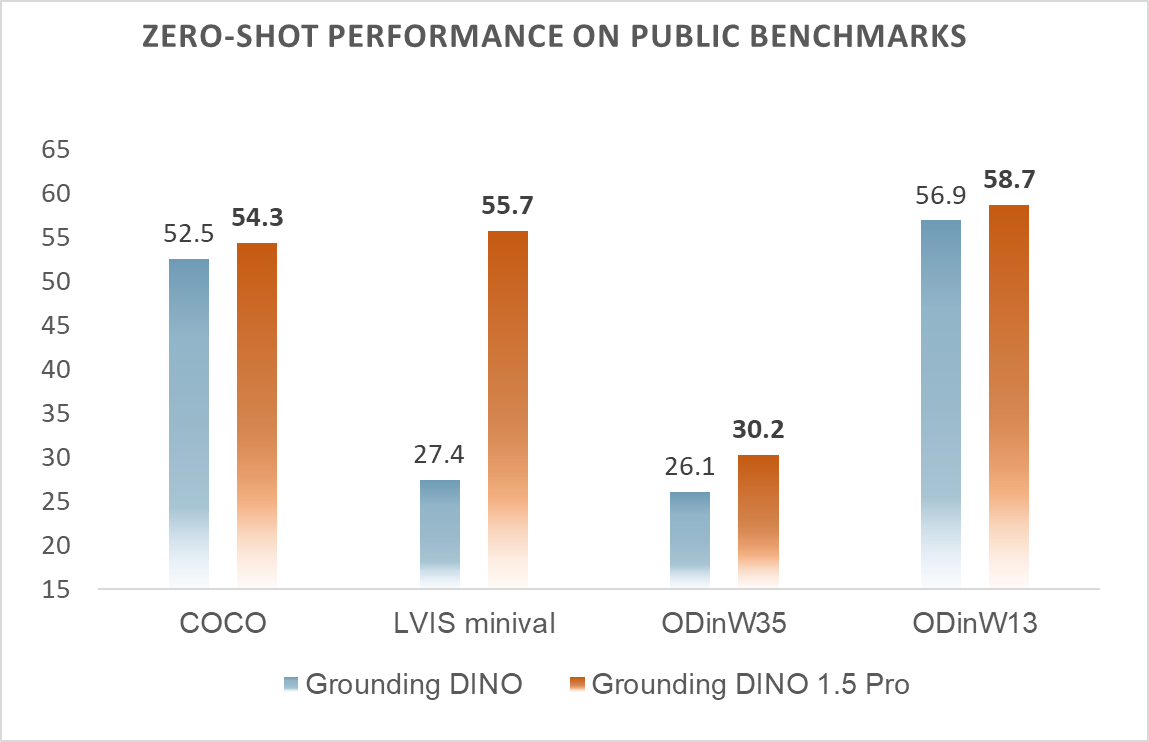
Zero-Shot Transfer Results of Grounding DINO 1.5 & 1.6 Pro
Model
COCO
(AP box)
LVIS-minival
(AP all)
LVIS-minival
(AP rare)
LVIS-val
(AP all)
LVIS-val
(AP rare)
ODinW35
(AP avg)
ODinW13
(AP avg)
Other Best
Open-Set Model
53.4
(OmDet-Turbo)
47.6
(T-Rex2 visual)
45.4
(T-Rex2 visual)
45.3
(T-Rex2 visual)
43.8
(T-Rex2 visual)
30.1
(OmDet-Turbo)
59.8
(APE-B)
DetCLIPv3
48.8
49.9
41.4
41.4
Grounding DINO
52.5
27.4
18.1
26.1
56.9
T-Rex2 (text)
52.2
54.9
49.2
45.8
42.7
22.0
Grounding DINO 1.5 Pro
54.3
55.7
56.1
47.6
44.6
30.2
58.7
Grounding DINO 1.6 Pro
55.4
57.7
57.5
51.1
51.5
- Grounding DINO 1.5 Pro achieves SOTA performance on COCO, LVIS-minival, LVIS-val, and ODinW35 zero-shot transfer benchmarks.
- Grounding DINO 1.6 Pro has significantly improved the model's performance on the COCO, LVIS zero-shot transfer benchmarks, particularly in the LVIS-rare classes.
Grounding DINO 1.5 as a Strong Few-Shot Learner
We validate the transferability of Grounding DINO 1.5 Pro on ODinW few-shot benchmarks and Grounding DINO 1.5 Pro has achieved new SOTA results on the ODinW few-shot setting.
Model
Tune
1-Shot
3-Shot
5-Shot
10-Shot
All
DyHead (COCO)
Full
31.9 ± 1.3
44.2 ± 0.3
44.7 ± 1.7
50.1 ± 1.6
63.2
DyHead (O365)
Full
33.8 ± 3.5
43.6 ± 1.0
46.4 ± 1.1
50.8 ± 1.3
60.8
GLIP-L
Full
59.9 ± 1.4
62.1 ± 0.7
64.2 ± 0.3
64.9 ± 0.7
68.9
GLIPv2-H
Full
61.7 ± 0.5
64.1 ± 0.8
64.4 ± 0.6
65.9 ± 0.3
70.4
GLEE-Pro
Full
59.4 ± 1.5
61.7 ± 0.5
64.3 ± 1.3
65.6 ± 0.4
69.0
MQ-GLIP-L
Full
62.4
64.2
65.4
66.6
71.3
Grounding DINO 1.5 Pro
Full
62.4 ± 1.1
66.3 ± 1.0
66.9 ± 0.2
67.9 ± 0.3
72.4
- "Full" means fine-tuning the full model.
- Follow GLIP, for each few-shot setting, we train the models three times using different random seeds for train/validation splits.
Fine-tuning Results on Downstream Datasets
Model
LVIS-minival
(AP all)
LVIS-minival
(AP rare)
LVIS-val
(AP all)
LVIS-val
(AP rare)
ODinW35
(AP avg)
ODinW13
(AP avg)
GLIP
68.9
GLEE-Pro
69.0
GLIPv2
59.8
70.4
OWL-ST + FT †
54.4
46.1
49.4
44.6
DetCLIPv2
58.3
60.1
53.1
49.0
70.4
DetCLIPv3
60.5
60.7
72.1
DetCLIPv3 †
60.8
56.7
54.1
45.8
Grounding DINO 1.5 Pro (zero-shot)
55.7
56.1
47.6
44.6
30.2
58.7
Grounding DINO 1.5 Pro
68.1
68.7
63.5
64.0
70.6
72.4
- † indicates results of fine-tuning with LVIS base categories only.
API Usage
1. Installation
pip install -v -e .
2. Request API from DeepDataSpace
Refer to the DeepDataSpace for API keys: https://deepdataspace.com/request_api
3. Runing demo code
python demo/demo.py --token
4. Online Grdio demo
python gradio_app.py --token
Case Analysis and Qualitative Visualization
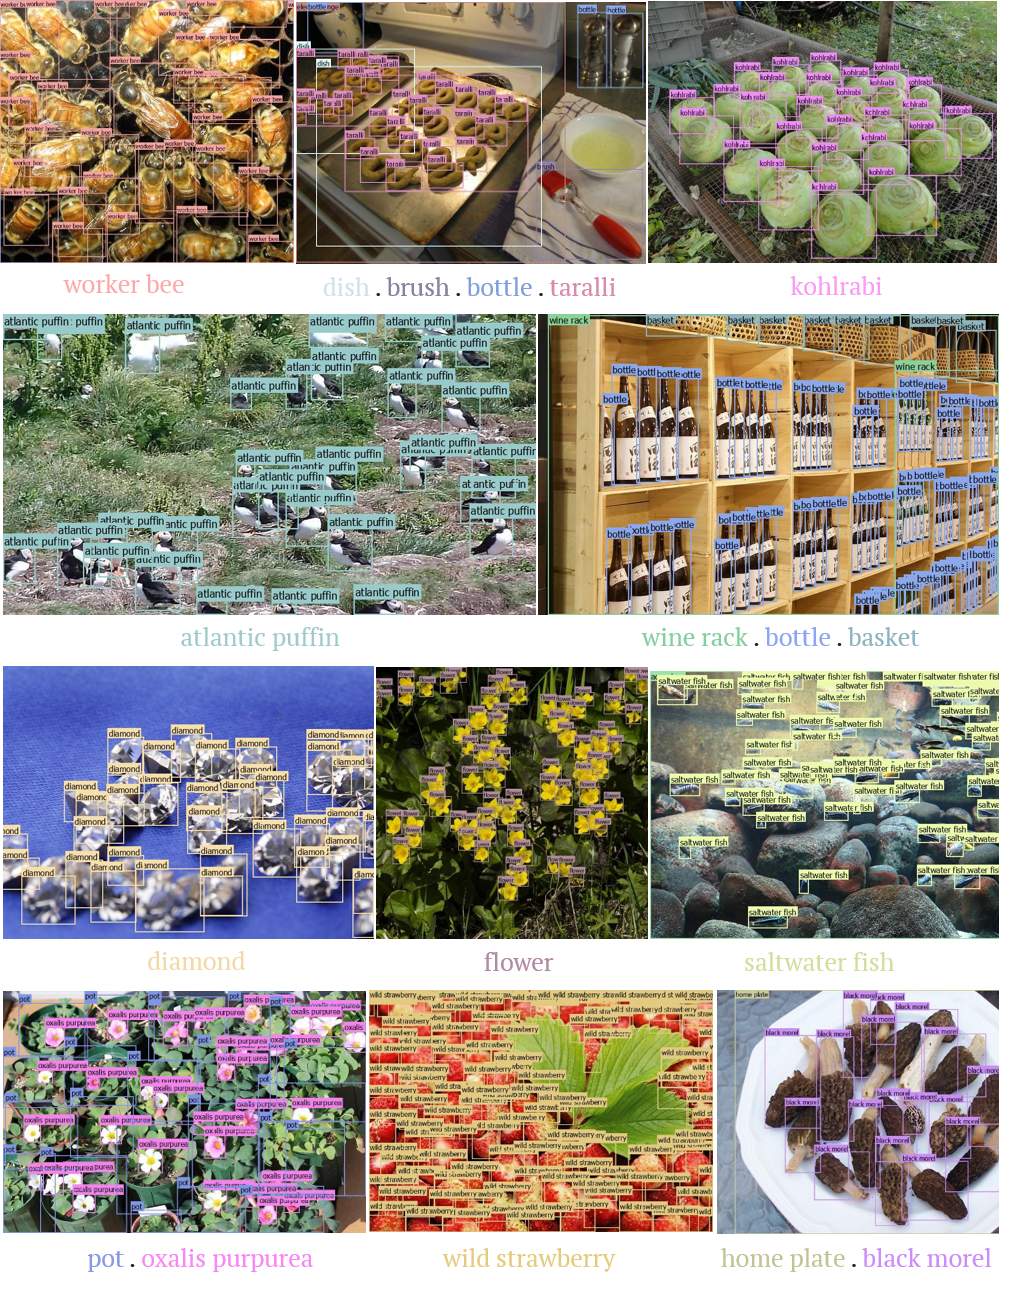
Common Object Detection


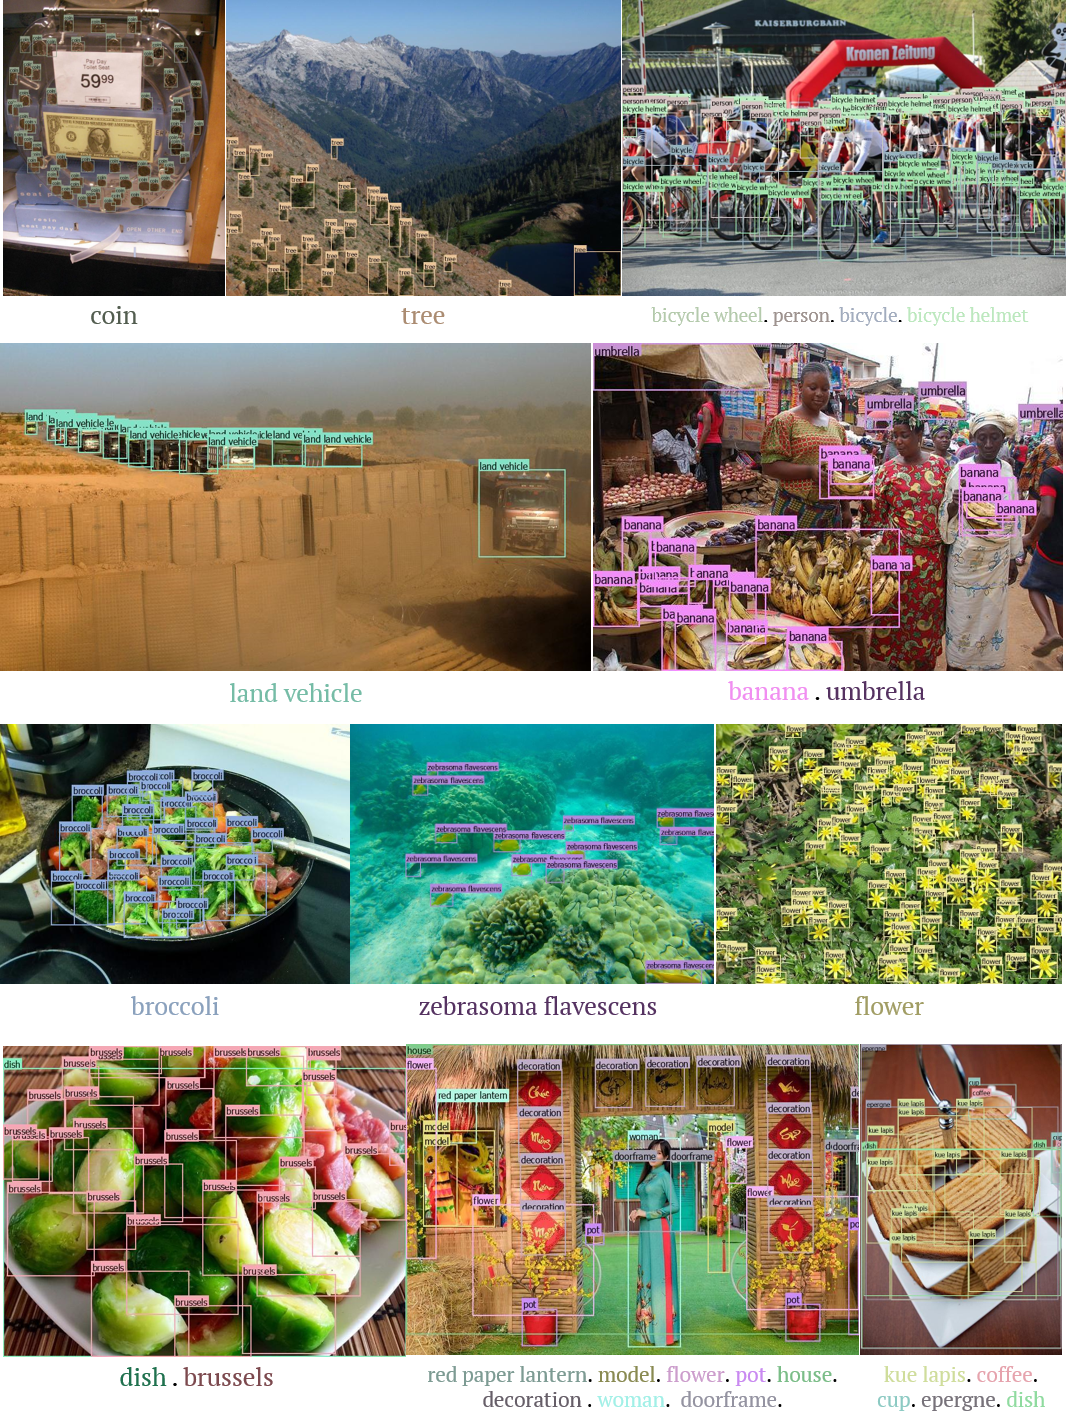
Long-tailed Object Detection

Short Caption Grounding

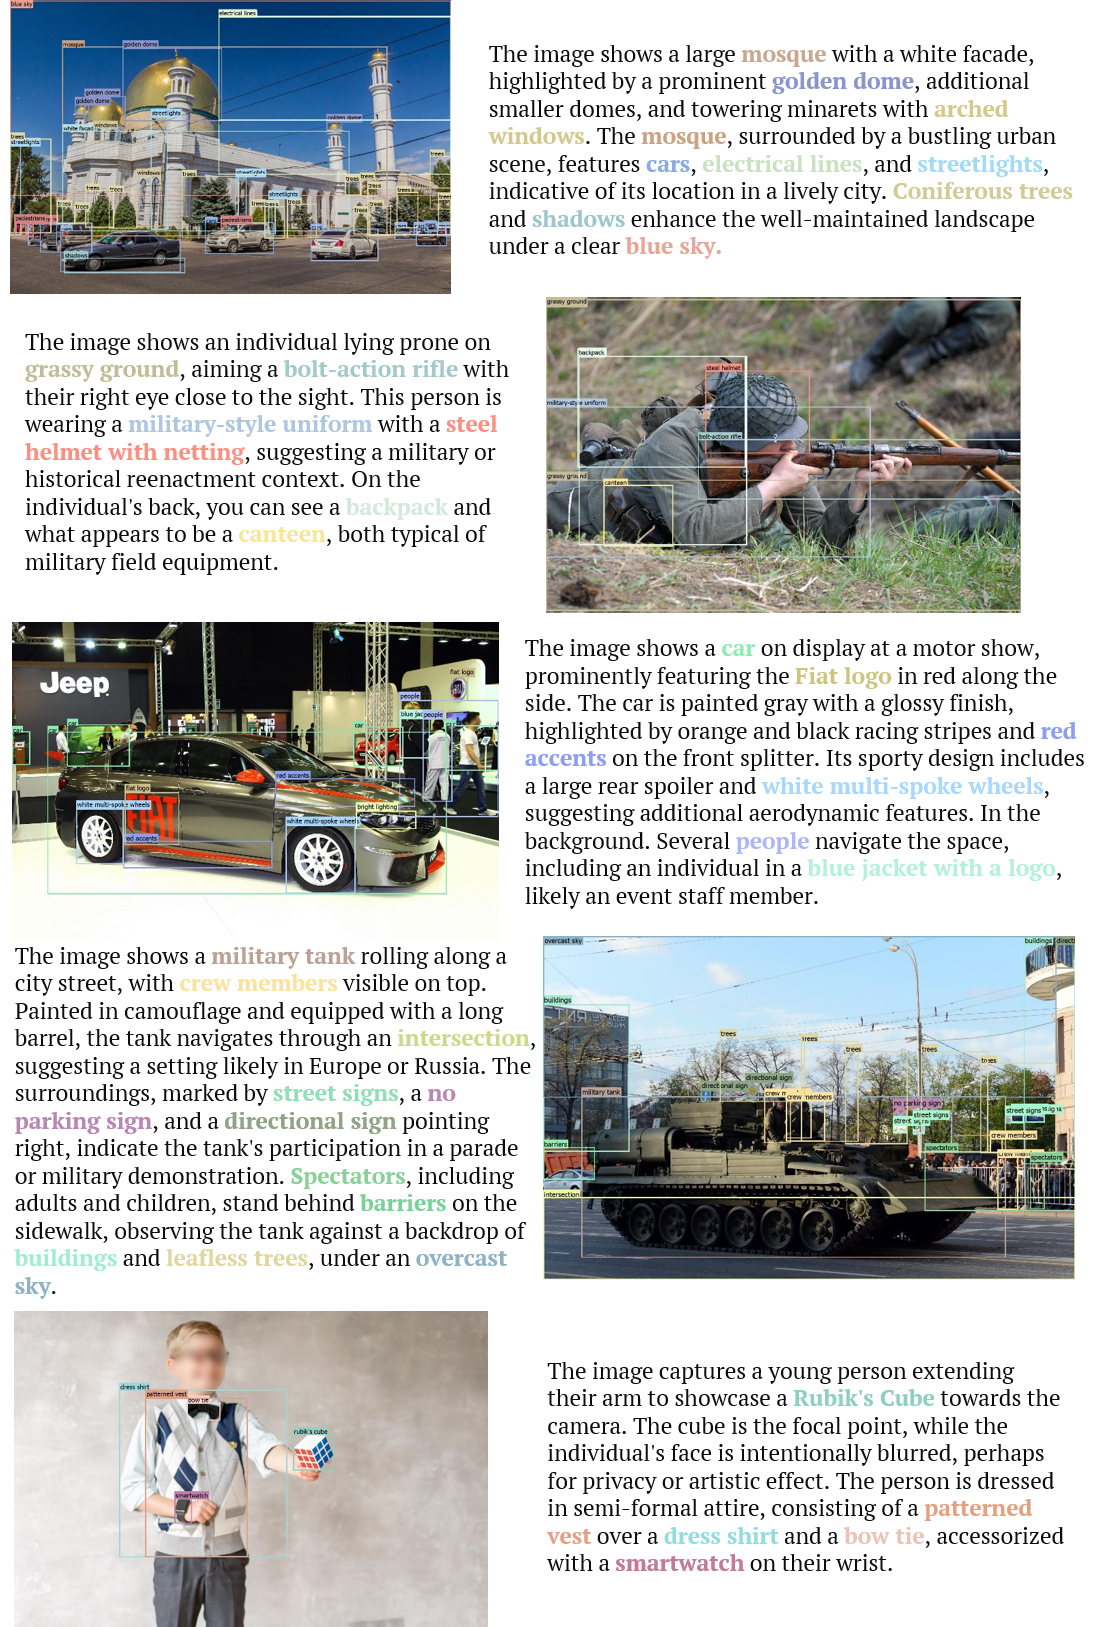
Long Caption Grounding


Dense Object Detection
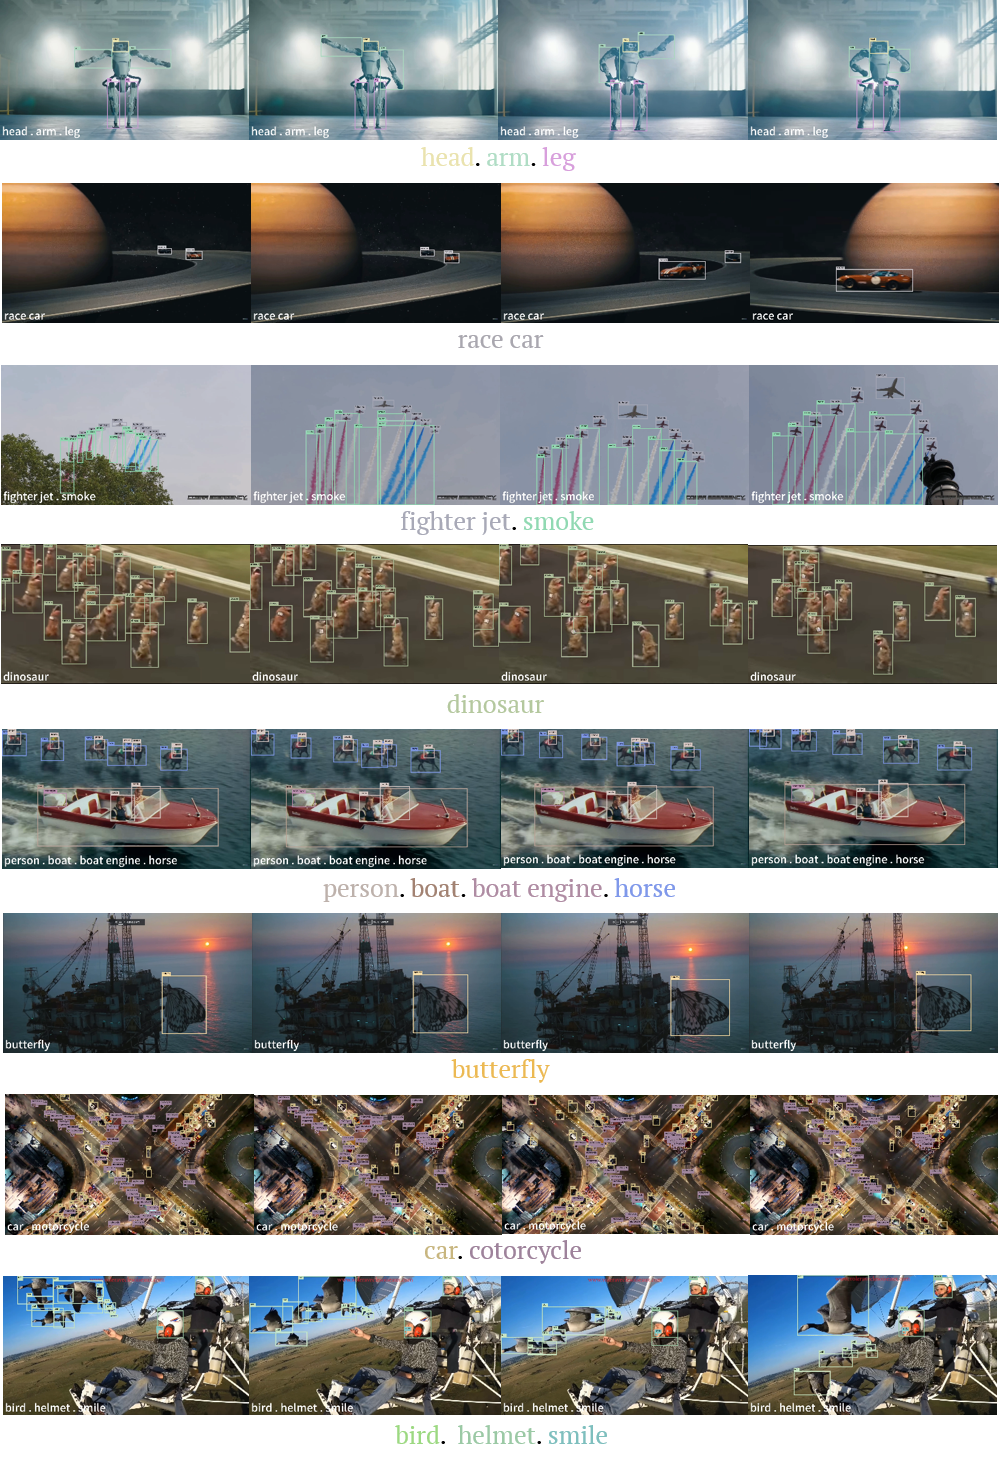
Video Object Detection
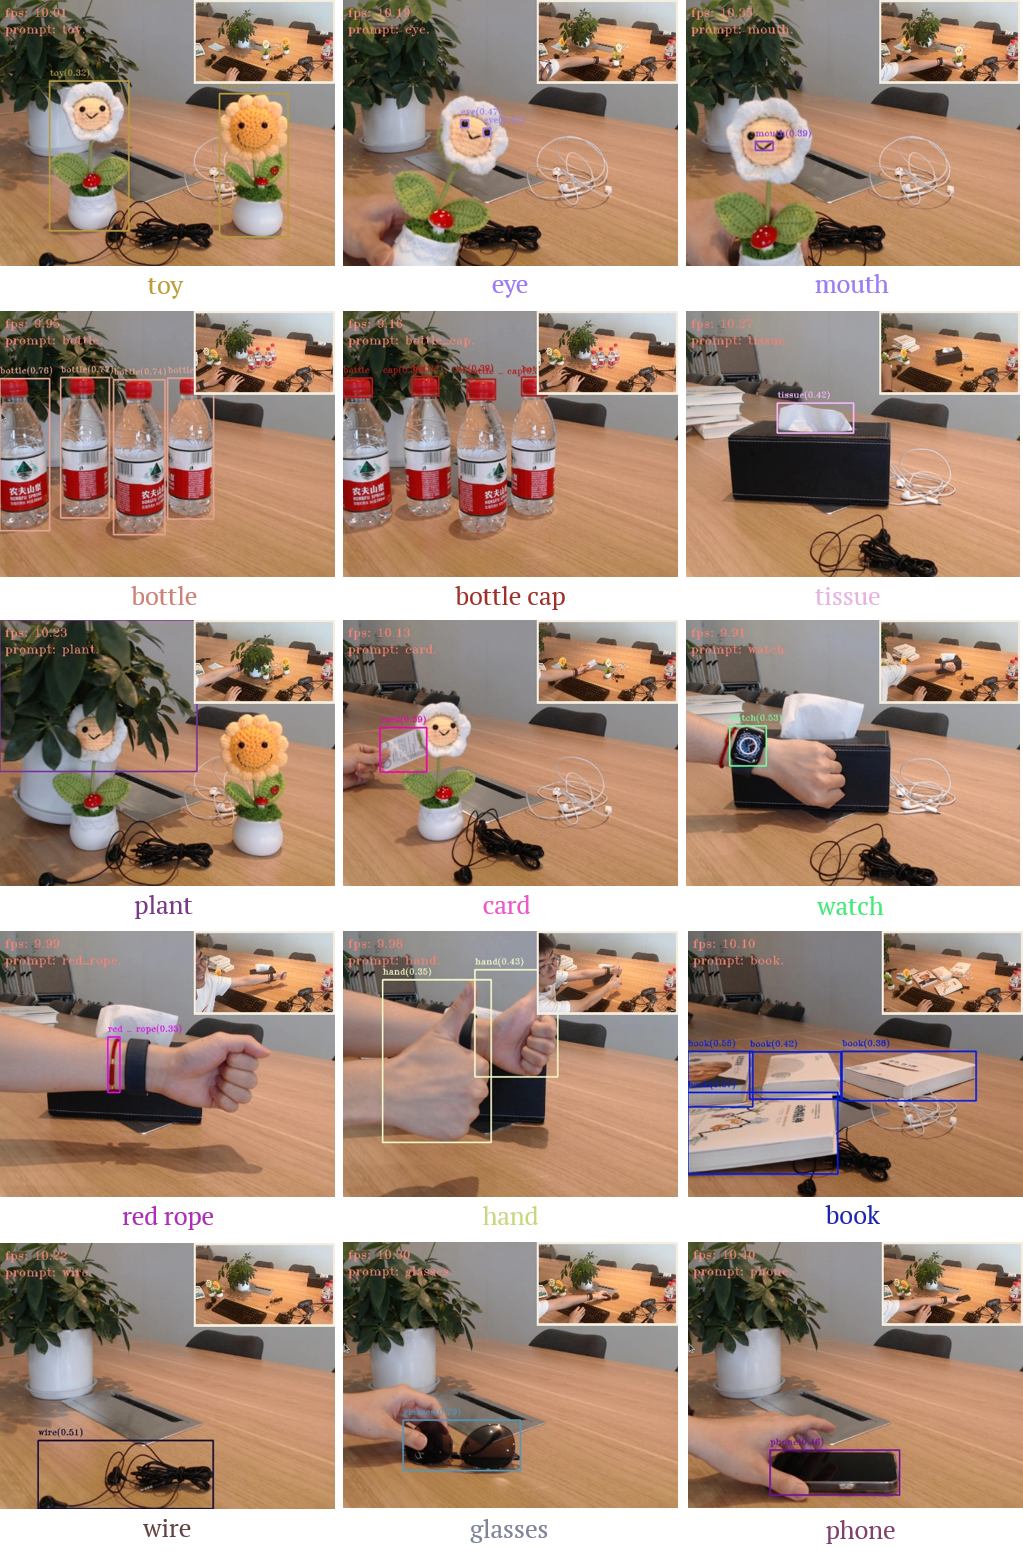
Advanced Object Detection on Edge Devices
Related Work
- Grounding DINO: Strong open-set object detection model.
- Grounded-Segment-Anything: Open-set detection and segmentation model by combining Grounding DINO with SAM.
- T-Rex/T-Rex2: Generic open-set detection model supporting both text and visual prompts.
LICENSE
Grounding DINO 1.5 API License
Grounding DINO 1.5 is released under the Apache 2.0 license. Please see the LICENSE file for more information.
Copyright (c) IDEA. All rights reserved.
Licensed under the Apache License, Version 2.0 (the "License"); you may not use these files except in compliance with the License. You may obtain a copy of the License at http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the specific language governing permissions and limitations under the License.
BibTeX
If you find our work helpful for your research, please consider citing the following BibTeX entry.
@misc{ren2024grounding,
      title={Grounding DINO 1.5: Advance the "Edge" of Open-Set Object Detection},
      author={Tianhe Ren and Qing Jiang and Shilong Liu and Zhaoyang Zeng and Wenlong Liu and Han Gao and Hongjie Huang and Zhengyu Ma and Xiaoke Jiang and Yihao Chen and Yuda Xiong and Hao Zhang and Feng Li and Peijun Tang and Kent Yu and Lei Zhang},
      year={2024},
      eprint={2405.10300},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
@misc{jiang2024trex2,
      title={T-Rex2: Towards Generic Object Detection via Text-Visual Prompt Synergy},
      author={Qing Jiang and Feng Li and Zhaoyang Zeng and Tianhe Ren and Shilong Liu and Lei Zhang},
      year={2024},
      eprint={2403.14610},
      archivePrefix={arXiv},
      primaryClass={cs.CV}
}
@article{liu2023grounding,
  title={Grounding dino: Marrying dino with grounded pre-training for open-set object detection},
  author={Liu, Shilong and Zeng, Zhaoyang and Ren, Tianhe and Li, Feng and Zhang, Hao and Yang, Jie and Li, Chunyuan and Yang, Jianwei and Su, Hang and Zhu, Jun and others},
  journal={arXiv preprint arXiv:2303.05499},
  year={2023}
}