Groma: Grounded Multimodal Assistant
Groma: Localized Visual Tokenization for Grounding Multimodal Large Language Models
Chuofan Ma, Yi Jiang, Jiannan Wu, Zehuan Yuan, Xiaojuan Qi


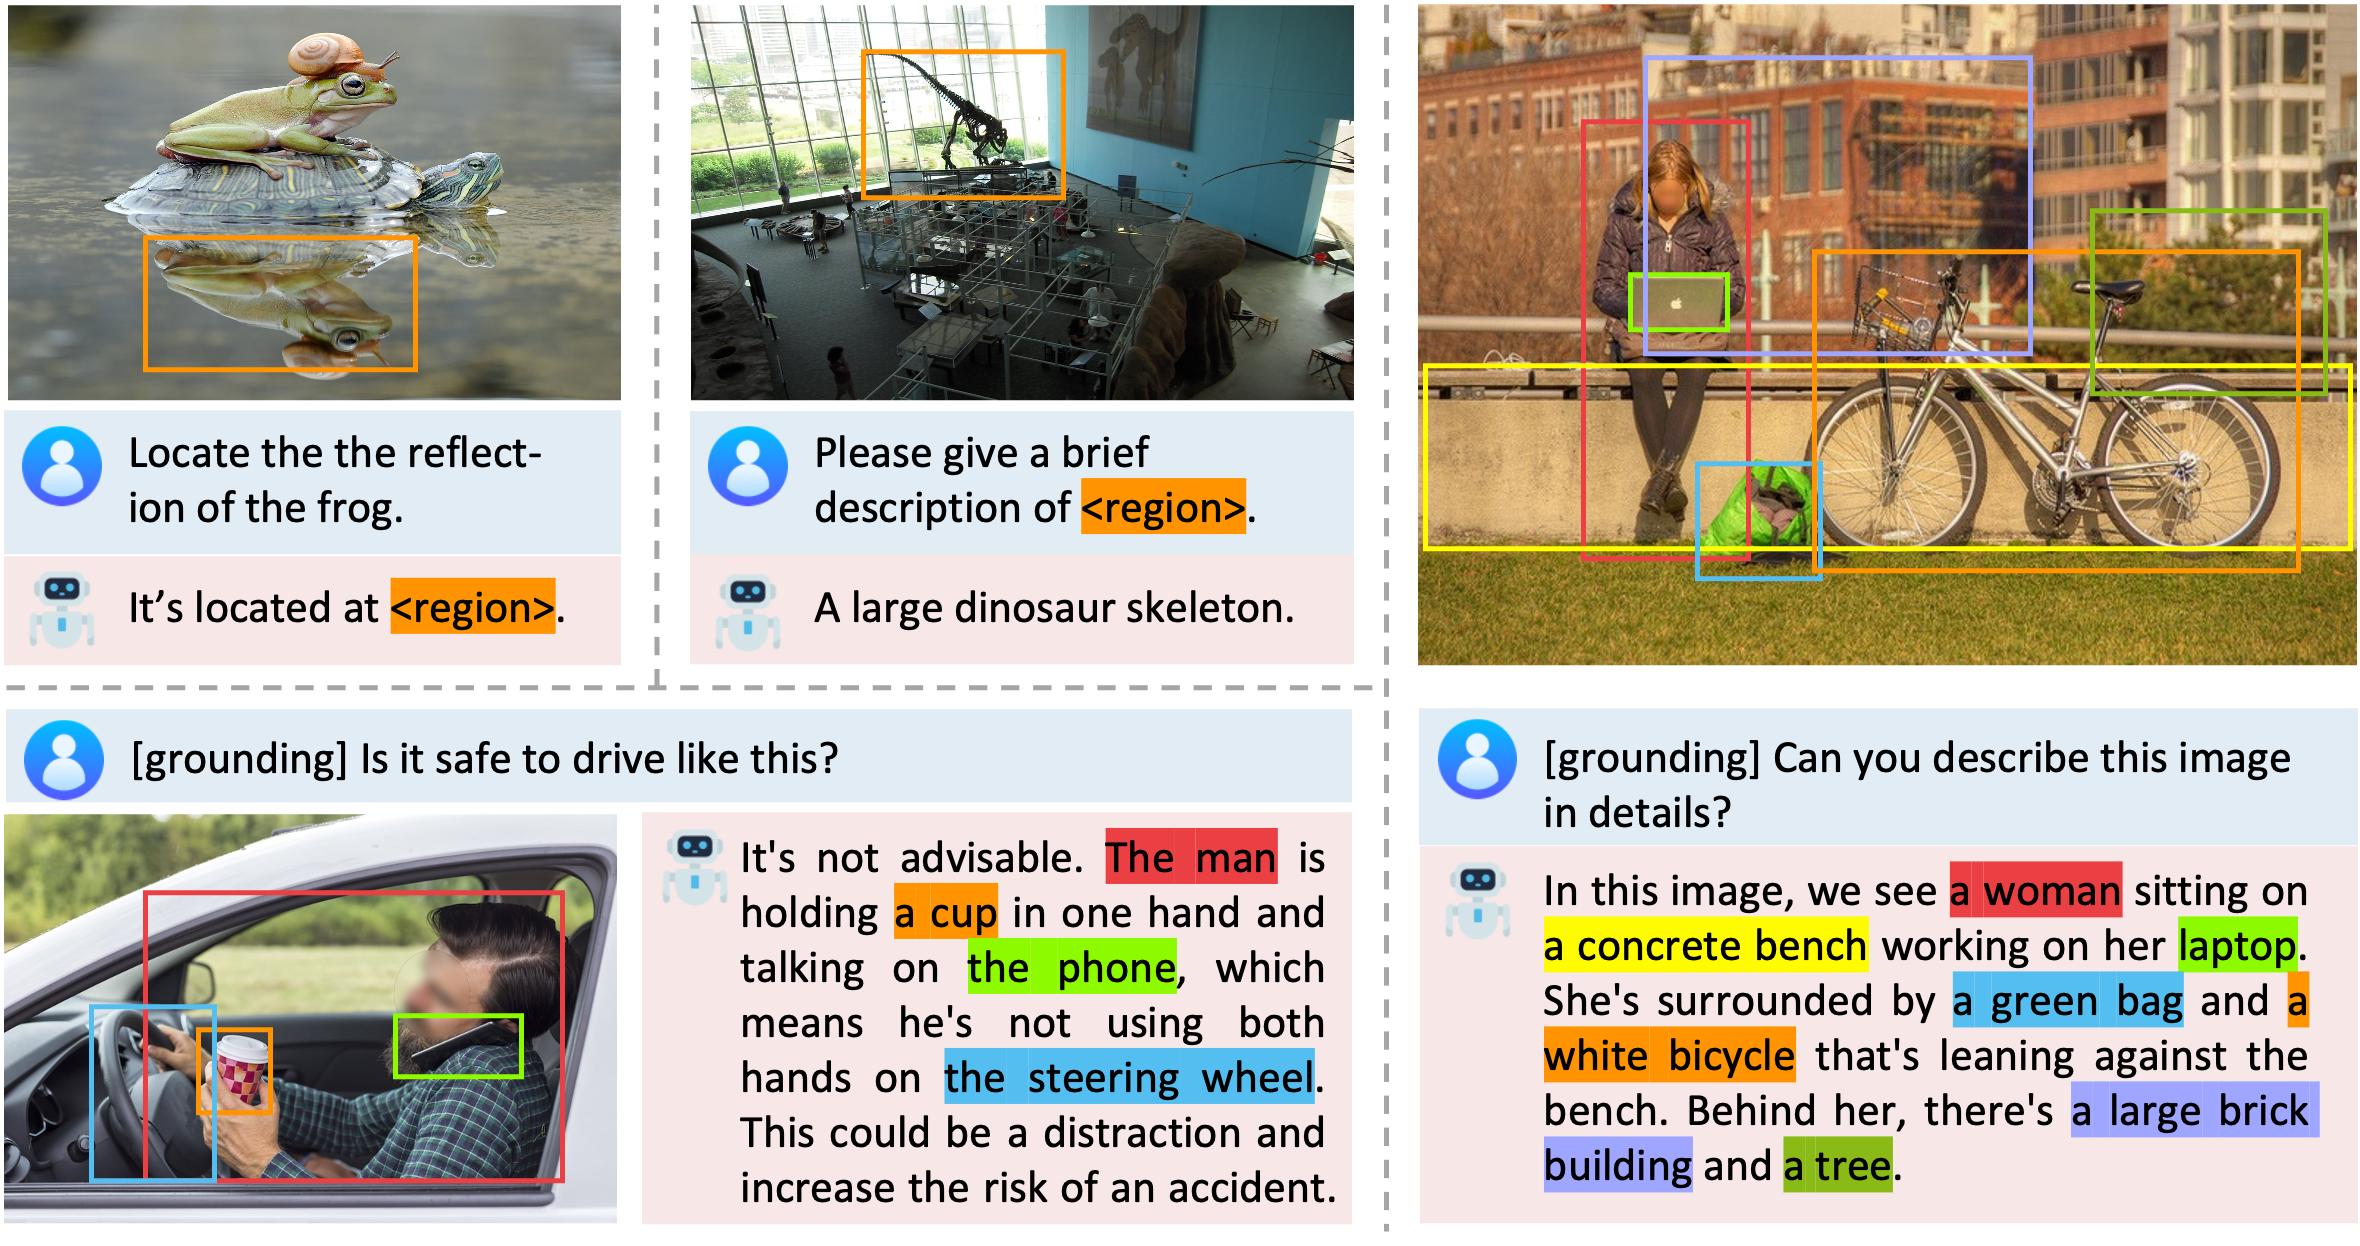
Groma is an MLLM with exceptional region understanding and visual grounding capabilities. It can take user-defined region inputs (boxes) as well as generate long-form responses that are grounded to visual context.
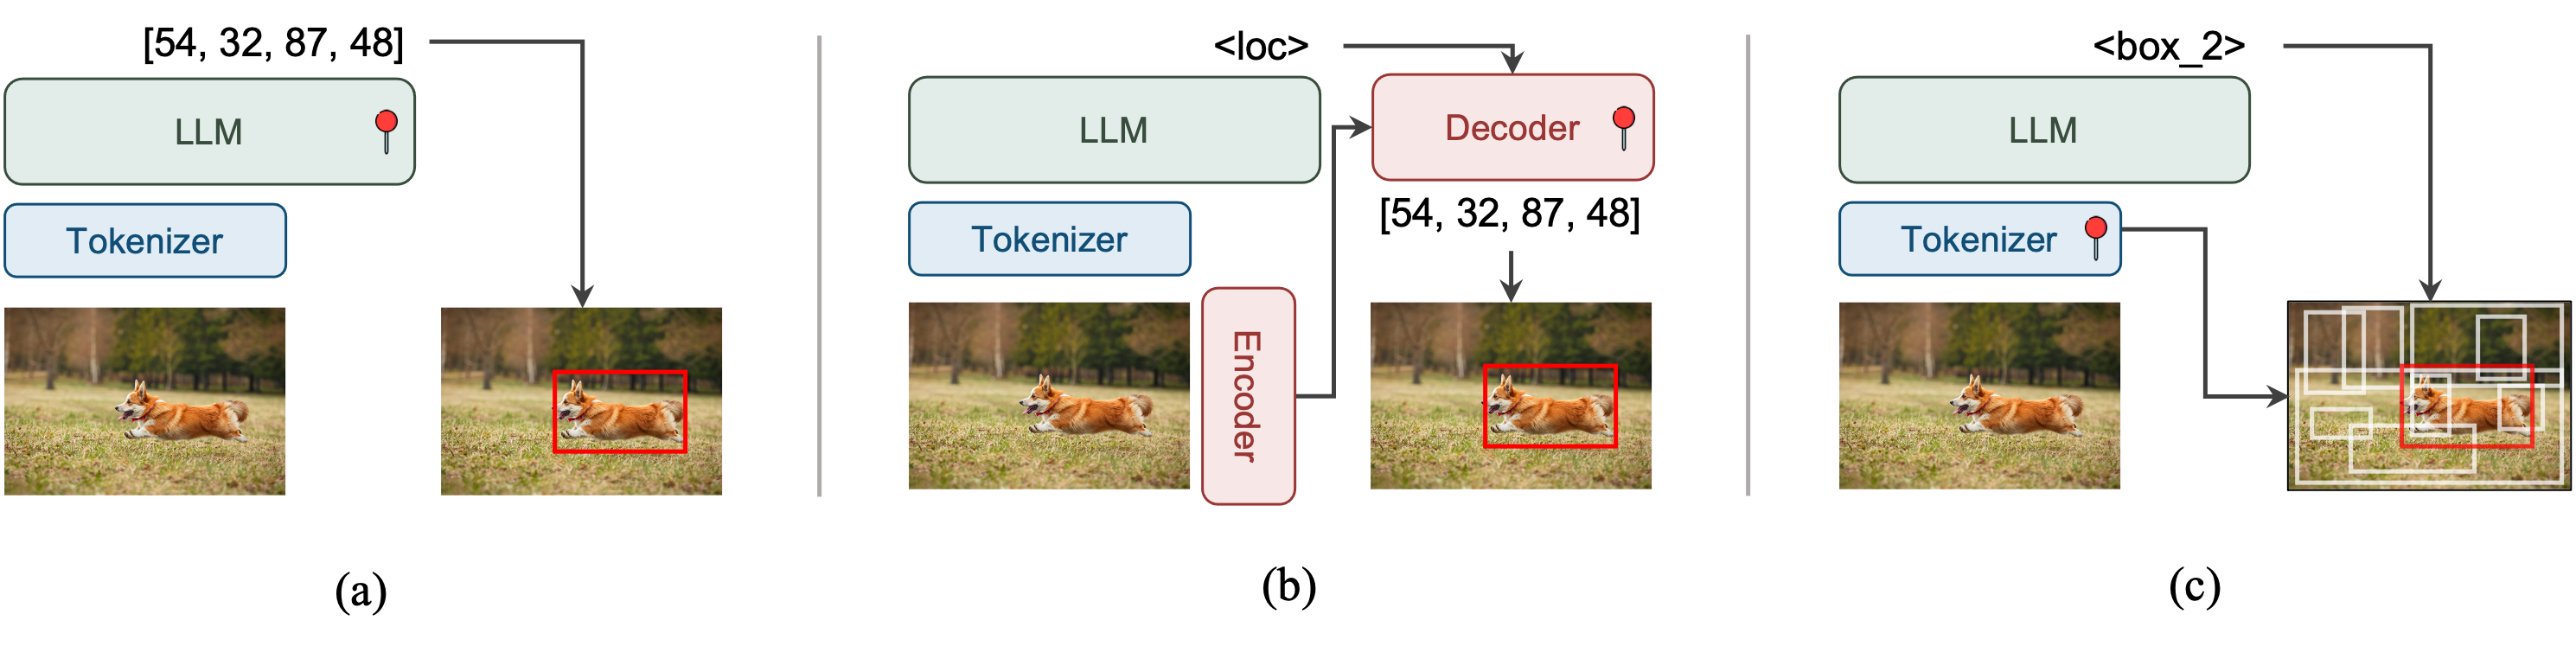
Groma presents a novel paradigm of grounded MLLMs. (a) LLM for localization (e.g., Kosmos-2, Shikra); (b) External modules for localization (e.g., Lisa); and (c) Visual tokenier for localization (Groma).
Contents
Performance
State-of-the-art performance on referring expression comprehension (REC) benchmarks among multimodal large language models.
Method
RefCOCO
RefCOCO+
RefCOCOg
Avergae
val
testA
testB
val
testA
testB
val
test
Shikra
87.01
90.61
80.24
81.60
87.36
72.12
82.27
82.19
82.93
Ferret
87.49
91.35
82.45
80.78
87.38
73.14
83.93
84.76
83.91
MiniGPT-v2
88.69
91.65
85.33
79.97
85.12
74.45
84.44
84.66
84.29
Qwen-VL
89.36
92.26
85.34
83.12
88.25
77.21
85.58
85.48
85.83
Groma
89.53
92.09
86.26
83.90
88.91
78.05
86.37
87.01
86.52
Installation
Clone the repository
git clone https://github.com/FoundationVision/Groma.git
cd Groma
Create the conda environment and install dependencies
conda create -n groma python=3.9 -y
conda activate groma
conda install pytorch==2.1.0 torchvision==0.16.0 torchaudio==2.1.0 pytorch-cuda=11.8 -c pytorch -c nvidia
pip install --upgrade pip  # enable PEP 660 support
pip install -e .

cd mmcv
MMCV_WITH_OPS=1 pip install -e .
cd ..
Install falsh-attention for training
pip install ninja
pip install flash-attn --no-build-isolation
Model Weights
To play with Groma, please download the model weights from huggingface.
We additionally provide pretrained checkpoints from intermediate training stages. You can start from any point to customize training.
| Training stage | Required checkpoints |
|---|---|
| Detection pretraining | DINOv2-L |
| Alignment pretraining | Vicuna-7b-v1.5, Groma-det-pretrain |
| Instruction finetuning | Groma-7b-pretrain |
Prepare Data
We provide instructions to download datasets used at different training stages of Groma, including Groma Instruct, a 30k viusally grounded conversation dataset constructed with GPT-4V. You don't have to download all of them unless you want to train Groma from scratch. Please follow instructions in DATA.md to prepare datasets.
Training stage
Data types
Datasets
Detection pretraining
Detection
COCO, Objects365, OpenImages, V3Det, SA1B
Alignment pretraining
Image caption
ShareGPT-4V-PT
Grounded caption
Flickr30k Entities
Region caption
Visual Genome, RefCOCOg
REC
COCO, RefCOCO/g/+, Grit-20m
Instruction finetuning
Grounded caption
Flickr30k Entities
Region caption
Visual Genome, RefCOCOg
REC
COCO, RefCOCO/g/+
Instruction following
Groma Instruct, LLaVA Instruct, ShareGPT-4V
Training
For detection pretraining, please run
bash scripts/det_pretrain.sh {path_to_dinov2_ckpt} {output_dir}
For alignment pretraining, please run
bash scripts/vl_pretrain.sh {path_to_vicuna_ckpt} {path_to_groma_det_pretrain_ckpt} {output_dir}
For instruction finetuning, please run
bash scripts/vl_finetune.sh {path_to_groma_7b_pretrain_ckpt} {output_dir}
Inference
To test on single image, you can run
python -m groma.eval.run_groma \
    --model-name {path_to_groma_7b_finetune} \
    --image-file {path_to_img} \
    --query {user_query} \
    --quant_type 'none' # support ['none', 'fp16', '8bit', '4bit'] for inference
Evaluation
For evaluation, please refer to EVAL.md for more details.
Citation
If you find this repo useful for your research, feel free to give us a star ⭐ or cite our paper:
@article{ma2024groma,
  title={Groma: Localized Visual Tokenization for Grounding Multimodal Large Language Models},
  author={Ma, Chuofan and Jiang, Yi and Wu, Jiannan and Yuan, Zehuan and Qi, Xiaojuan},
  journal={arXiv preprint arXiv:2404.13013},
  year={2024}
}
Acknowledgement
Groma is built upon the awesome works LLaVA and GPT4ROI.
LICENSE
This project is licensed under the Apache License 2.0 - see the LICENSE file for details.