HumanML3D: 3D Human Motion-Language Dataset
HumanML3D is a 3D human motion-language dataset that originates from a combination of HumanAct12 and Amass dataset. It covers a broad range of human actions such as daily activities (e.g., 'walking', 'jumping'), sports (e.g., 'swimming', 'playing golf'), acrobatics (e.g., 'cartwheel') and artistry (e.g., 'dancing').
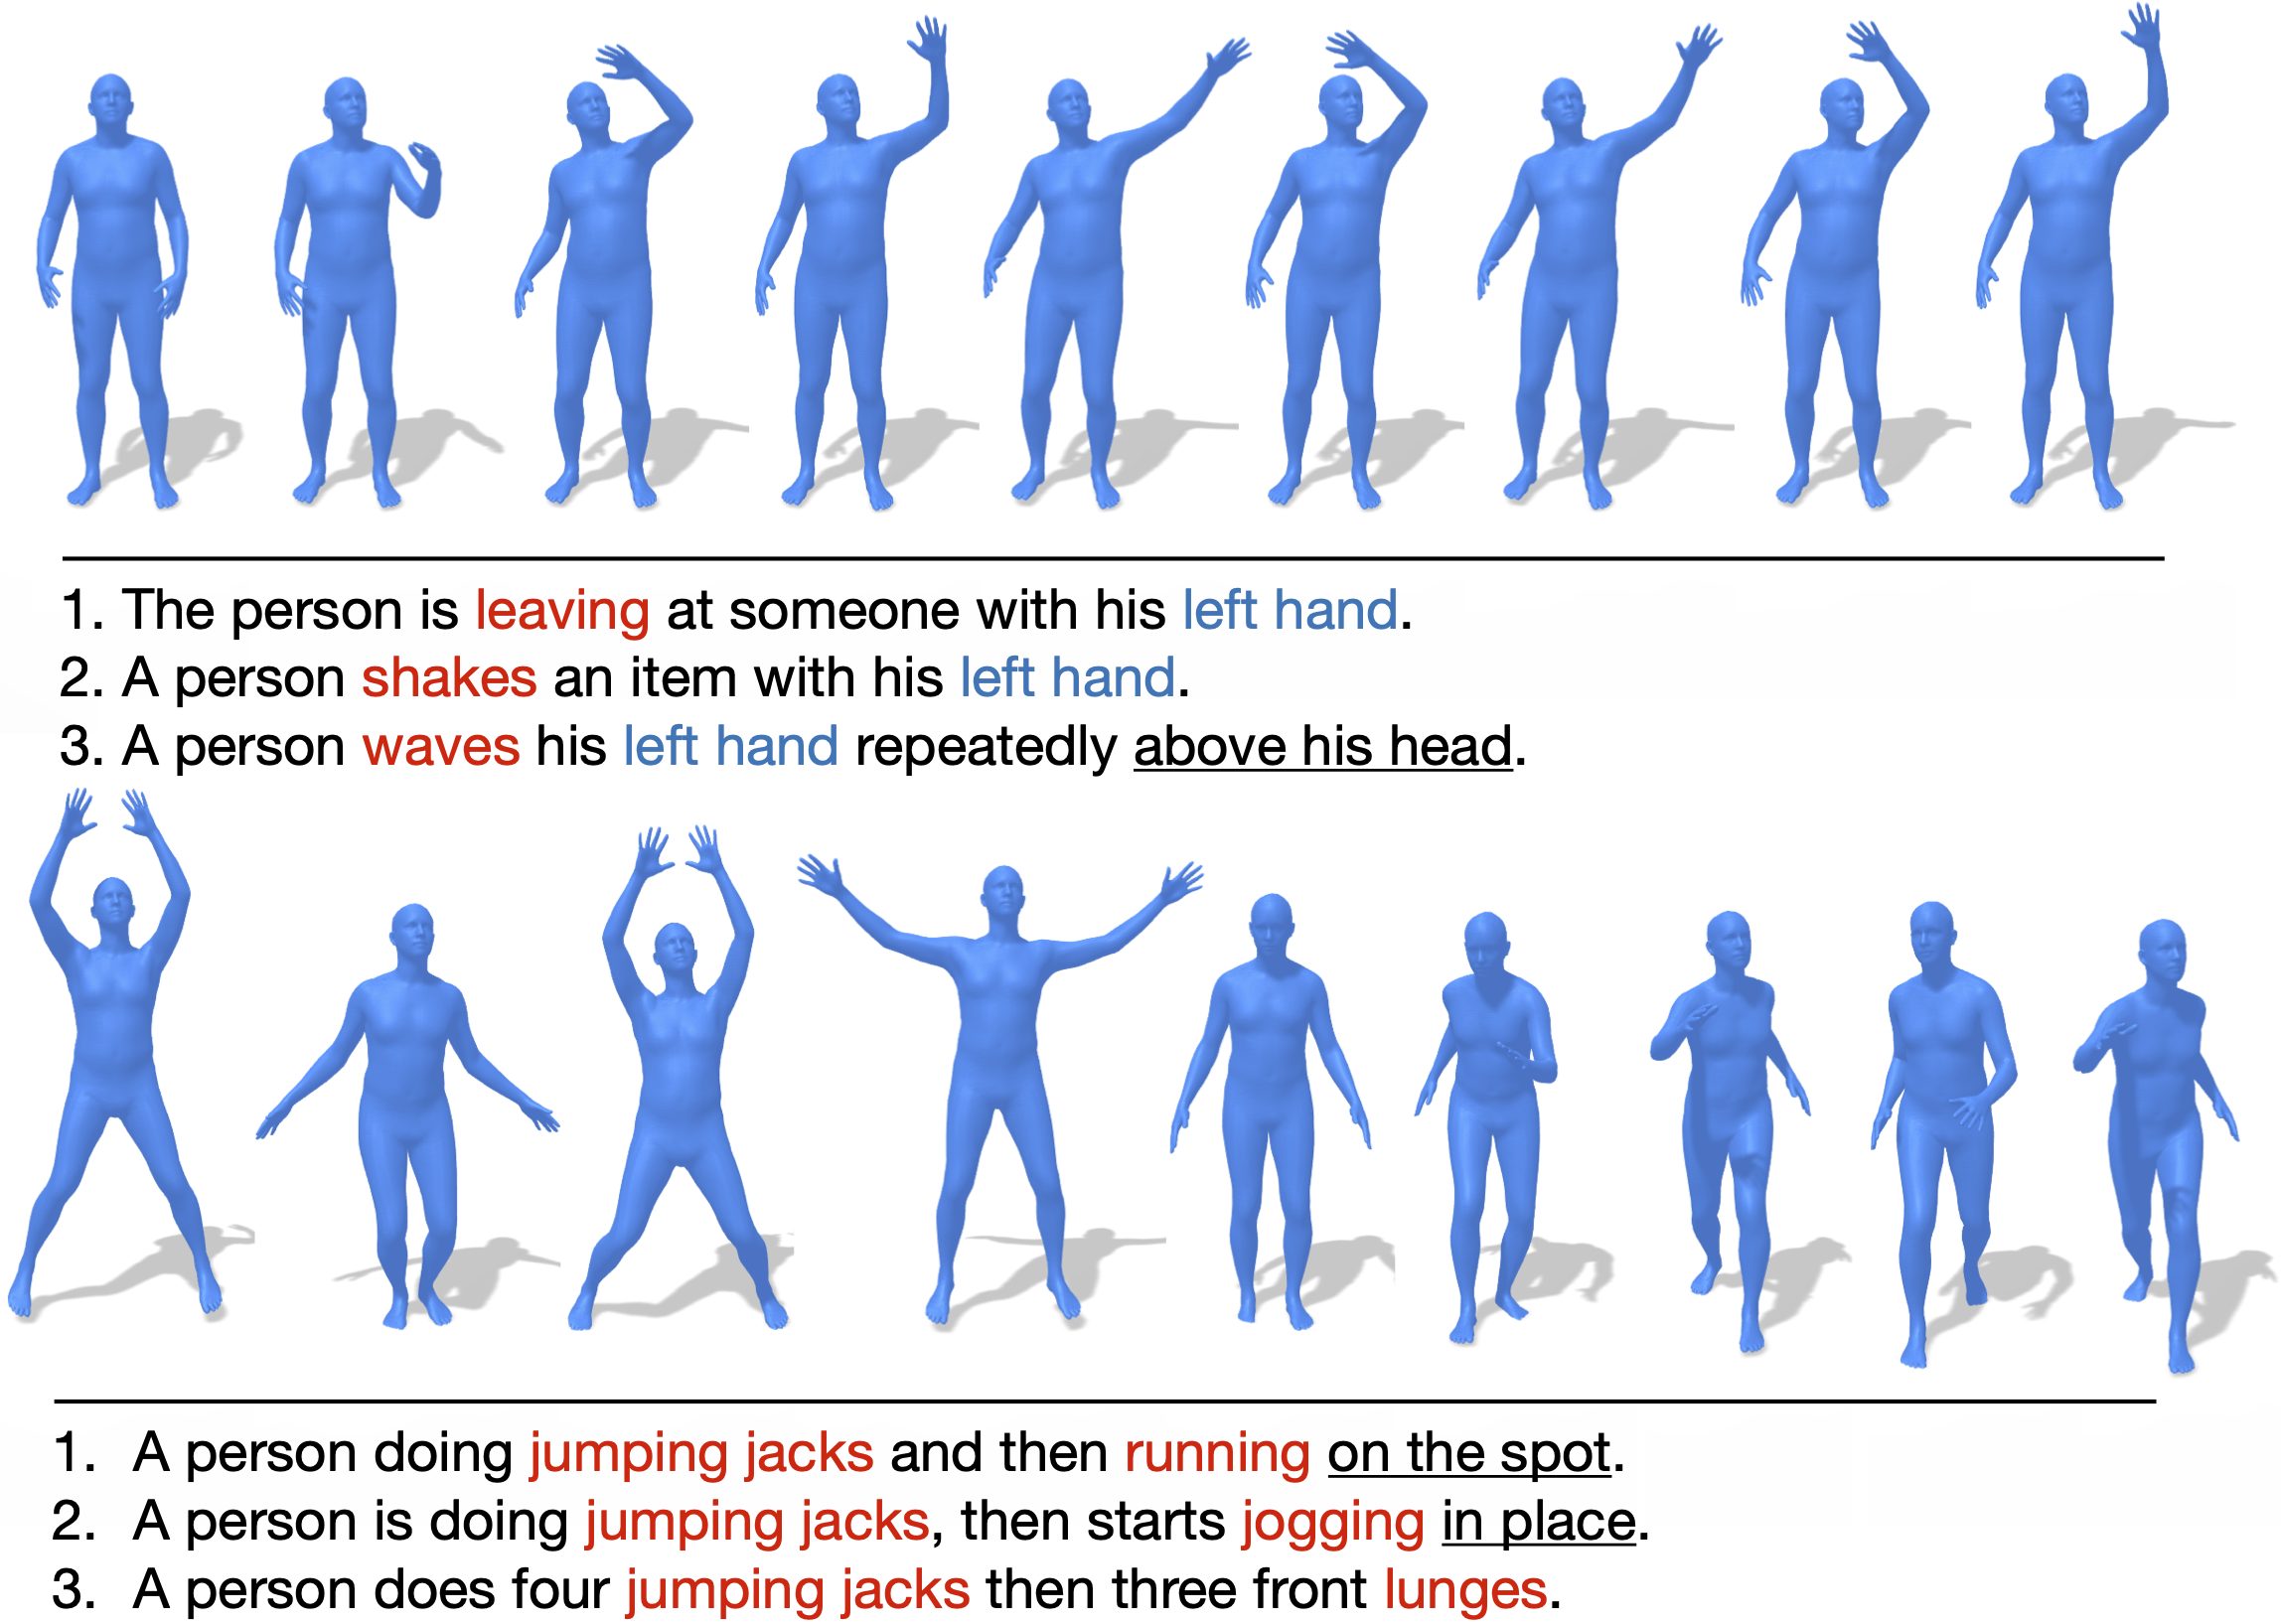
** Statistics of HumanML3D **
:bar_chart: Statistics
Each motion clip in HumanML3D comes with 3-4 single sentence descriptions annotated on Amazon Mechanical Turk. Motions are downsampled into 20 fps, with each clip lasting from 2 to 10 seconds.
Overall, HumanML3D dataset consists of 14,616 motions and 44,970 descriptions composed by 5,371 distinct words. The total length of motions amounts to 28.59 hours. The average motion length is 7.1 seconds, while average description length is 12 words.
:chart_with_upwards_trend: Data augmentation
We double the size of HumanML3D dataset by mirroring all motions and properly replacing certain keywords in the descriptions (e.g., 'left'->'right', 'clockwise'->'counterclockwise').
KIT-ML Dataset
KIT Motion-Language Dataset (KIT-ML) is also a related dataset that contains 3,911 motions and 6,278 descriptions. We processed KIT-ML dataset following the same procedures of HumanML3D dataset, and provide the access in this repository. However, if you would like to use KIT-ML dataset, please remember to cite the original paper.
If this dataset is usefule in your projects, we will apprecite your star on this codebase. 😆😆
Checkout Our Works on HumanML3D
:ok_woman: T2M - The first work on HumanML3D that learns to generate 3D motion from textual descriptions, with temporal VAE.
:running: TM2T - Learns the mutual mapping between texts and motions through the discrete motion token.
:dancer: TM2D - Generates dance motions with text instruction.
:honeybee: MoMask - New-level text2motion generation using residual VQ and generative masked modeling.
How to Obtain the Data
For KIT-ML dataset, you could directly download [Here]. Due to the distribution policy of AMASS dataset, we are not allowed to distribute the data directly. We provide a series of script that could reproduce our HumanML3D dataset from AMASS dataset.
You need to clone this repository and install the virtual environment.
[2022/12/15] Update: Installing matplotlib=3.3.4 could prevent small deviation of the generated data from reference data. See Issue
Python Virtual Environment
conda env create -f environment.yaml
conda activate torch_render
In the case of installation failure, you could alternatively install the following:
- Python==3.7.10
- Numpy
- Scipy
- PyTorch
- Tqdm
- Pandas
- Matplotlib==3.3.4     // Only for animation
- ffmpeg==4.3.1  // Only for animation
- Spacy==2.3.4   // Only for text process
Download SMPL+H and DMPL model
Download SMPL+H mode from SMPL+H (choose Extended SMPL+H model used in AMASS project) and DMPL model from DMPL (choose DMPLs compatible with SMPL). Then place all the models under "./body_model/".
Extract and Process Data
You need to run the following scripts in order to obtain HumanML3D dataset:
- raw_pose_processing.ipynb
- motion_representation.ipynb
- cal_mean_variance.ipynb
This could be optional. Run it if you need animations.
- animation.ipynb
Please remember to go through the double-check steps. These aim to check if you are on the right track of obtaining HumanML3D dataset.
After all, the data under folder "./HumanML3D" is what you finally need.
Data Structure
./animations.rar        //Animations of all motion clips in mp4 format.
./new_joint_vecs.rar    //Extracted rotation invariant feature and rotation features vectors from 3d motion positions.
./new_joints.rar        //3d motion positions.
./texts.rar             //Descriptions of motion data.
./Mean.npy              //Mean for all data in new_joint_vecs
./Std.npy               //Standard deviation for all data in new_joint_vecs
./all.txt               //List of names of all data
./train.txt             //List of names of training data
./test.txt              //List of names of testing data
./train_val.txt         //List of names of training and validation data
./val.txt               //List of names of validation data
./all.txt               //List of names of all data
HumanML3D data follows the SMPL skeleton structure with 22 joints. KIT-ML has 21 skeletal joints. Refer to paraUtils for detailed kinematic chains.
The file named in "MXXXXXX.*" (e.g., 'M000000.npy') is mirrored from file with correspinding name "XXXXXX.*" (e.g., '000000.npy'). Text files and motion files follow the same naming protocols, meaning texts in "./texts/XXXXXX.txt"(e.g., '000000.txt') exactly describe the human motions in "./new_joints(or new_joint_vecs)/XXXXXX.npy" (e.g., '000000.npy')
Each text file looks like the following:
a man kicks something or someone with his left leg.#a/DET man/NOUN kick/VERB something/PRON or/CCONJ someone/PRON with/ADP his/DET left/ADJ leg/NOUN#0.0#0.0
the standing person kicks with their left foot before going back to their original stance.#the/DET stand/VERB person/NOUN kick/VERB with/ADP their/DET left/ADJ foot/NOUN before/ADP go/VERB back/ADV to/ADP their/DET original/ADJ stance/NOUN#0.0#0.0
a man kicks with something or someone with his left leg.#a/DET man/NOUN kick/VERB with/ADP something/PRON or/CCONJ someone/PRON with/ADP his/DET left/ADJ leg/NOUN#0.0#0.0
he is flying kick with his left leg#he/PRON is/AUX fly/VERB kick/NOUN with/ADP his/DET left/ADJ leg/NOUN#0.0#0.0
with each line a distint textual annotation, composed of four parts: original description (lower case), processed sentence, start time(s), end time(s), that are seperated by #.
Since some motions are too complicated to be described, we allow the annotators to describe a sub-part of a given motion if required. In these cases, start time(s) and end time(s) denotes the motion segments that are annotated. Nonetheless, we observe these only occupy a small proportion of HumanML3D. start time(s) and end time(s) are set to 0 by default, which means the text is captioning the entire sequence of corresponding motion.
If you are not able to install ffmpeg, you could animate videos in '.gif' instead of '.mp4'. However, generating GIFs usually takes longer time and memory occupation.
Citation
If you are using KIT-ML dataset, please consider citing the following paper:
@article{Plappert2016,
    author = {Matthias Plappert and Christian Mandery and Tamim Asfour},
    title = {The {KIT} Motion-Language Dataset},
    journal = {Big Data}
    publisher = {Mary Ann Liebert Inc},
    year = 2016,
    month = {dec},
    volume = {4},
    number = {4},
    pages = {236--252},
    url = {http://dx.doi.org/10.1089/big.2016.0028},
    doi = {10.1089/big.2016.0028},
}
If you are using HumanML3D dataset, please consider citing the following papers:
@InProceedings{Guo_2022_CVPR,
    author    = {Guo, Chuan and Zou, Shihao and Zuo, Xinxin and Wang, Sen and Ji, Wei and Li, Xingyu and Cheng, Li},
    title     = {Generating Diverse and Natural 3D Human Motions From Text},
    booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
    month     = {June},
    year      = {2022},
    pages     = {5152-5161}
}
Misc
Contact Chuan Guo at cguo2@ualberta.ca for any questions or comments.