Awesome RL-VLA for Robotic Manipulation 🤖
[Paper]
A curated list of papers and resources on Reinforcement Learning of Vision-Language-Action (RL-VLA) models for Robotic Manipulation. This repository provides a comprehensive overview of training paradigms, methodologies, and state-of-the-art approaches in RL-VLA research.
📢 Latest News
🔥 [November 2025] Our comprehensive survey paper "A Survey on Reinforcement Learning of Vision-Language-Action Models for Robotic Manipulation" is now available on TechRxiv! Stay tuned for future updates.
📖 Table of Contents
- Awesome RL-VLA for Robotic Manipulation 🤖
🔍 Overview
RL training is crucial for enabling VLAs to generalize out-of-distribution (OOD) from large-scale pre-trained data. Existing RL-VLA training paradigms can be categorized into three types based on how agents obtain and utilize feedback from the environment:
- Online RL-VLA: Direct interaction with the environment during training
- Offline RL-VLA: Learning from static datasets without further environmental interaction
- Test-time RL-VLA: Models adapt their behavior during deployment without altering parameters
🚀 Training Paradigms
Offline RL-VLA
Offline RL trains VLA models on pre-collected static datasets, enabling learning independently from environment interactions. This paradigm is suitable for high-risk or resource-constrained deployment scenarios.
Key Research Directions:
- Data Utilization: Effective utilization of static datasets for policy improvement
- Objective Modification: Customizing RL objectives for novel architectures and data augmentation
Online RL-VLA
Online RL-VLA enables interactive policy learning through continuous environment interaction, empowering pre-trained VLAs with adaptive closed-loop control capability for real-world OOD environments.
Key Research Directions:
- Policy Optimization: Direct policy improvement based on environmental rewards
- Sample Efficiency: Learning effective policies with limited interaction budget
- Active Exploration: Efficient exploration strategies for higher performance gains
- Training Stability: Ensuring consistent policy updates and convergence
- Infrastructure: Scalable frameworks for online RL-VLA training
Test-time RL-VLA
Test-time RL-VLA adapts behavior during deployment through lightweight updates, addressing the expensive cost of full model fine-tuning in real-world scenarios.
Key Adaptation Mechanisms:
- Value Guidance: Using pre-trained value functions to influence action selection
- Memory Buffer Guidance: Retrieving relevant historical experiences during inference
- Planning-guided Adaptation: Explicit reasoning over future action sequences
📚 Paper Collection
Legend
- Action: AR (Autoregressive), Diffusion, Flow (Flow-matching)
- Reward: D (Dense Reward), S (Sparse Reward)
- Model Type: MB (Model-based), MF (Model-free)
- Environment: Sim. (Simulation), Real (Real-world)
- Task: MT (Multi-task), ST (Single-task)
- Policy: On-Policy, Off-Policy, Hybrid (mixed on/off-policy), Test-time (inference-time adaptation)
Offline RL-VLA
| Method | Date | Publication | Sim. | Real | Base VLA Model | Action | Reward | Algorithm | Policy | Type | Project |
|---|---|---|---|---|---|---|---|---|---|---|---|
| Q-Transformer | 2023.10 | CoRL23🔗 | ✓ | ✗ | Transformer | AR | S | CQL | Off-Policy | MF | 🔗 |
| PAC | 2024.02 | ICML24🔗 | ✓ | ✓ | Perceiver-Actor-Critic | AR | S | AC | Off-Policy | MF | 🔗 |
| GeRM(Quadruped Robot) | 2024.03 | IROS24🔗 | ✓ | ✗ | Transformer-MoE | AR | S | CQL | Off-Policy | MF | 🔗 |
| MoRE(Quadruped Robot) | 2025.03 | ICRA25🔗 | ✗ | ✓ | MLLM-MoE | AR | S | CQL | Off-Policy | MF | - |
| ReinboT | 2025.05 | ICML25🔗 | ✓ | ✓ | ReinboT | AR | D | DT + RTG | Off-Policy | MF | 🔗 |
| CO-RFT | 2025.08 | - | ✗ | ✓ | RoboVLMs | AR | D | Cal-QL + TD3 | Off-Policy | MF | - |
| ARFM | 2025.09 | AAAI26🔗 | ✓ | ✓ | π₀ | Flow | D | ARFM | Off-Policy | MF | - |
| $π^*_{0.6}$ | 2025.11 | - | ✗ | ✓ | $π_{0.6}$ | Flow | D | RECAP | Off-Policy | MF | 🔗 |
| NORA-1.5 | 2025.11 | - | ✓ | ✓ | NORA-1.5 | AR / Flow | D | DPO | Off-Policy | MB | 🔗 |
| GigaBrain-0.5M* | 2026.2 | - | ✗ | ✓ | GigaBrain-0.5 | Flow | D | RAMP | Off-Policy | MB | 🔗 |
| ARM | 2026.4 | - | ✗ | ✓ | GR00T N1.5 | Flow | D | AW-BC | Off-Policy | MF | 🔗 |
Online RL-VLA
| Method | Date | Publication | Sim. | Real | Base VLA Model | Action | Reward | Algorithm | Policy | Type | Project |
|---|---|---|---|---|---|---|---|---|---|---|---|
| FLaRe | 2024.09 | ICRA25🔗 | ✓ (ST) | ✓ (ST) | SPOC | AR | S | PPO | On-Policy | MF | 🔗 |
| PA-RL | 2024.12 | ICLR25 Workshop🔗 | ✓ (ST) | ✓ (ST) | OpenVLA | AR | S | PA-RL | Off-Policy | MF | 🔗 |
| RLDG | 2024.12 | RSS25🔗 | ✗ | ✓ (ST) | OpenVLA / Octo | AR / Diffusion | S | RLPD | Off-Policy | MF | 🔗 |
| iRe-VLA | 2025.01 | ICRA25🔗 | ✓ (MT) | ✓ (MT) | iRe-VLA | AR | S | SACfD + SFT | Off-Policy | MF | - |
| GRAPE | 2025.02 | ICRA25 Poster🔗 | ✓ (MT) | ✓ (MT) | OpenVLA | AR | D | TPO | On-Policy | MF | 🔗 |
| SafeVLA | 2025.03 | NeurIPS25 Poster🔗 | ✓ (ST) | ✗ | SPOC | AR | S | PPO | On-Policy | MF | 🔗 |
| RIPT-VLA | 2025.05 | - | ✓ (MT) | ✗ | QueST / OpenVLA-OFT | AR | S | LOOP | On-Policy | MF | 🔗 |
| VLA-RL | 2025.05 | - | ✓ (MT) | ✗ | OpenVLA | AR | D | PPO | On-Policy | MF | 🔗 |
| RLVLA | 2025.05 | NeurIPS25 Poster🔗 | ✓ (MT) | ✗ | OpenVLA | AR | S | PPO / GRPO / DPO | Hybrid | MF | 🔗 |
| RFTF | 2025.05 | - | ✓ (MT) | ✗ | GR-MG, Seer | AR | D | PPO | On-Policy | MF | - |
| TGRPO | 2025.06 | - | ✓ (ST) | ✗ | OpenVLA | AR | D | GRPO | On-Policy | MF | - |
| RLRC | 2025.06 | - | ✓ (MT) | ✗ | OpenVLA | AR | S | PPO | On-Policy | MF | 🔗 |
| ThinkAct | 2025.07 | NeurIPS25 Poster🔗 | ✓ (MT) | ✗ | MLLM + DiT | AR / Diffusion | D | GRPO (System 2) | On-Policy | MF | 🔗 |
| DiffusionRL-VLA | 2025.9 | - | ✓ | ✗ | π₀ | Flow | S | PPO(DP) + BC(VLA) | On-Policy | MF | - |
| SimpleVLA-RL | 2025.09 | ICLR26 Poster🔗 | ✓ (MT) | ✓ (ST) | OpenVLA-OFT | AR | S | GRPO | On-Policy | MF | 🔗 |
| Dual-Actor FT | 2025.09 | IROS25 Workshop Extended Abstract🔗 | ✓ (MT) | ✓ (MT) | Octo / SmolVLA | Diffusion | S | QL + BC | Off-Policy | MF | 🔗 |
| Generalist | 2025.09 | NeurIPS25 Poster🔗 | ✓ (MT) | ✓ (MT) | PaLI 3B | AR | D | REINFORCE | On-Policy | MF | 🔗 |
| VLAC | 2025.09 | - | ✗ | ✓ (MT) | VLAC | AR | D | PPO | On-Policy | MF | 🔗 |
| Robo-Dopamine | 2025.12 | CVPR26🔗 | ✓ (MT) | ✓ (MT) | Pi0.5 | Flow | D | PPO | On-Policy | MF | 🔗 |
| AC PPO | 2025.09 | - | ✓ (ST) | ✗ | Octo-small | AR | S | PPO+BC | On-Policy | MF | - |
| VLA-RFT | 2025.10 | - | ✓ (MT) | ✗ | VLA-Adapter | Flow | D | GRPO | On-Policy | MB | 🔗 |
| RLinf-VLA | 2025.10 | - | ✓ (MT) | ✓ (MT) | OpenVLA / OpenVLA-OFT | AR | S | PPO / GRPO | On-Policy | MF | 🔗 |
| FPO | 2025.10 | - | ✓ (MT) | ✗ | π₀ | Flow | S | FPO | On-Policy | MF | - |
| ReSA | 2025.10 | - | ✓ (MT) | ✗ | OpenVLA | AR | D | PPO + SFT | On-Policy | MF | - |
| π_RL | 2025.10 | - | ✓ (MT) | ✗ | π₀ / π₀.₅ | Flow | S | PPO / GRPO | On-Policy | MF | 🔗 |
| PLD | 2025.10 | ICLR26 Poster🔗 | ✓ (MT) | ✓ (MT) | OpenVLA / π₀ / Octo | AR / Flow | S | Cal-QL + SAC | Off-Policy | MF | 🔗 |
| DeepThinkVLA | 2025.10 | - | ✓ (MT) | ✗ | π₀-Fast | AR | S | GRPO | On-Policy | MF | 🔗 |
| World-Env | 2025.11 | - | ✓ (ST) | ✓ (ST) | OpenVLA-OFT | AR | D | PPO | On-Policy | MB | 🔗 |
| RobustVLA | 2025.11 | - | ✓ (MT) | ✗ | OpenVLA-OFT | AR | D | PPO | On-Policy | MF | - |
| WMPO | 2025.11 | ICLR26 Poster🔗 | ✓ (MT) | ✓ (MT) | OpenVLA-OFT | AR | S | GRPO | On-Policy | MB | 🔗 |
| ProphRL | 2025.11 | - | ✓ (ST) | ✓ (ST) | VLA-Adapter / π0.5 / OpenVLA-OFT(flow action) | Flow | S | FA-GRPO | On-Policy | MB | 🔗 |
| EVOLVE-VLA | 2025.12 | - | ✓ (MT) | ✗ | OpenVLA-OFT | AR | D | GRPO | On-Policy | MB(VLAC) | 🔗 |
| SOP | 2026.1 | - | ✗ | ✓ (MT) | π0.5 | Flow | S | HG-DAgger / RECAP | Off-Policy | MF | 🔗 |
| Green-VLA | 2026.1 | - | ✓ (MT) | ✓ (MT) | Green-VLA | Flow | S | IQL + actor-critic | Off-Policy | MF | 🔗 |
| SA-VLA | 2026.1 | - | ✓ (MT) | ✗ | π0.5 | Flow | D | PPO | On-Policy | MF | 🔗 |
| E2HiL | 2026.1 | - | ✗ | ✓ (MT) | Octo | Diffusion | S | RLPD | Off-Policy | MF | 🔗 |
| World-Gymnast | 2026.2 | ICLR26 Workshop🔗 | ✓ (MT) | ✓ (MT) | OpenVLA-OFT | AR | S | GRPO | On-Policy | MB | 🔗 |
| RL-VLA3 | 2026.2 | ICLR26 Workshop🔗 | ✓ (MT) | ✗ | π0 / π0.5 / GR00T N1.5 / OpenVLA-OFT | Flow / AR | S | PPO / GRPO | On-Policy | MF | — |
| World-VLA-Loop | 2026.2 | - | ✓ (ST) | ✓ (ST) | OpenVLA-OFT | AR | S | GRPO | On-Policy | MB | 🔗 |
| RISE | 2026.2 | - | ✗ | ✓ (ST) | π0.5 | Flow | D | RISE | On-Policy | MB | 🔗 |
| WoVR | 2026.2 | - | ✓ (MT) | ✓ (MT) | OpenVLA-OFT | AR | S | GRPO | On-Policy | MB | 🔗 |
| ALOE | 2026.2 | - | ✗ | ✓ (ST) | π₀.₅ | Flow | S | AWR(Advantage-Weighted Regression) | Off-Policy | MF | 🔗 |
| TwinRL-VLA | 2026.2 | - | ✗ | ✓ (ST) | Octo | Diffusion | S | Actor-Critic | Off-Policy | MF | — |
| RL-Co | 2026.3 | - | ✓ (ST) | ✓ (ST) | OpenVLA / π0.5 | AR / Flow | D | ReinFlow / GRPO | On-Policy | MF | — |
| π_StepNFT | 2026.3 | - | ✓ (MT) | ✗ | π₀ / π₀.₅ | Flow | S | NFT | On-Policy | MF | 🔗 |
| ROBOMETER | 2026.3 | - | ✗ | ✓ (MT) | π₀ | Flow | D | DSRL | Off-Policy | MF | 🔗 |
| AtomVLA | 2026.3 | - | ✓ (MT) | ✓ (ST) | AtomVLA | Flow | D | GRPO | On-Policy | MB | — |
| NS-VLA | 2026.3 | - | ✓ (MT) | ✗ | NS-VLA | AR | D | GRPO | On-Policy | MF | 🔗 |
| Gen3D-RL-VLA | 2026.03 | - | ✓(MT) | ✓(MT) | π₀.₅ | Flow | S | PPO | On-Policy | MB | - |
| Simple Recipe Works | 2026.03 | - | ✓(MT) | ✗ | OpenVLA-OFT / π₀ / π₀-Fast | AR / Flow | S | PPO | On-Policy | MF | 🔗 |
| RoboAlign | 2026.03 | - | ✓(MT) | ✓(MT) | MLLM + Diffusion | AR | D | GRPO | On-Policy | MF | - |
| SmoothVLA | 2026.03 | - | ✓(MT) | ✗ | OpenVLA-OFT | AR | D | GRPO | On-Policy | MF | - |
| AcceRL | 2026.03 | - | ✓(MT) | ✗ | OpenVLA-OFT | AR | S | PPO | On-Policy | MB | 🔗 |
| VLA-MBPO | 2026.03 | - | ✓(MT) | ✓(MT) | π₀ / OpenVLA | Flow / AR | S | MBPO | On-Policy | MB | - |
| VLA-OPD | 2026.03 | - | ✓(MT) | ✗ | OpenVLA-OFT | AR | D | OPD | On-Policy | MF | - |
| OmniVLA-RL | 2026.04 | - | ✓(MT) | ✗ | OmniVLA-RL (MoT) | Flow | D | Flow-GSPO | On-Policy | MF | - |
| VLAJS | 2026.04 | - | ✓(MT) | ✓(ST) | VLA-guided RL agent | AR | S | PPO | On-Policy | MF | - |
| DAERT | 2026.04 | - | ✓(MT) | ✗ | π₀ / OpenVLA | AR / Flow | S | Diversity-aware RL | On-Policy | MF | - |
| RL Token | 2026.04 | - | ✗ | ✓(ST) | π₀.₅ | Flow | D | RLPD | Off-Policy | MF | 🔗 |
| LaST-R1 | 2026.04 | - | ✓(MT) | ✗ | LaST-R1 | AR | D | LAPO | On-Policy | MF | - |
Offline + Online RL-VLA
| Method | Date | Publication | Sim. | Real | Base VLA Model | Action | Reward | Algorithm | Policy | Type | Project |
|---|---|---|---|---|---|---|---|---|---|---|---|
| ConRFT | 2025.4 | RSS26🔗 | ✗ | ✓(MT) | Octo-small | Diffusion | S | Cal-QL + BC | Off-Policy | MF | 🔗 |
| SRPO | 2025.11 | - | ✓(MT) | ✓(MT) | OpenVLA* / π₀ / π₀-Fast | AR / Flow | D | SRPO | Hybrid | MF (MB-Reward but MF-RL) | 🔗 |
| DLR | 2025.11 | - | ✓ | ✗ | π₀ / OpenVLA | Flow / AR | S | PPO(MLP) + SFT(VLA) | On-Policy | MF | - |
| GR-RL | 2025.12 | - | ✗ | ✓ | GR-3 | Flow | S | TD3 / DSRL | Off-Policy | MF | 🔗 |
| STARE-VLA | 2025.12 | - | ✓ | ✗ | OpenVLA / π₀.₅ | AR / Flow | D | PPO / TPO / SFT | On-Policy | MF | 🔗 |
| IG-RFT | 2026.2 | - | ✗ | ✓ | π₀.₅ | Flow | D | IG-AWR | off-policy | MF | — |
| POCO | 2026.04 | - | ✓(MT) | ✓(MT) | π₀ / Octo | Flow / Diffusion | D | POCO (EM + Clipped) | Off-Policy | MF | 🔗 |
Test-time RL-VLA
| Method | Date | Publication | Sim. | Real | Base VLA Model | Action | Reward | Algorithm | Policy | Type | Project |
|---|---|---|---|---|---|---|---|---|---|---|---|
| V-GPS | 2024.10 | CoRL25🔗 | ✓(MT) | ✓(MT) | Octo / RT-1 / OpenVLA | AR / Diffusion | D | Cal-QL | Test-time | MF | 🔗 |
| Hume | 2025.5 | CVPR26🔗/ | ✓(MT) | ✓(MT) | Hume | Flow | S | Value Guidance | Test-time | MF | 🔗 |
| DSRL | 2025.6 | CoRL25🔗 | ✓(MT) | ✓(MT) | DP / π₀ | Diffusion / Flow | S | Diffusion Steering | Test-time | MF | 🔗 |
| VLA-Reasoner | 2025.9 | ICRA26🔗 | ✓(ST) | ✓(ST) | OpenVLA / SpatialVLA / π₀-Fast | AR / Diffusion | D | MCTS | Test-time | MB | 🔗 |
| RoVer | 2025.10 | - | ✓(MT) | ✓(MT) | OpenVLA / π₀ / GR00T-N1.5 | AR / Flow | D | PRM Verifier | Test-time | MF | - |
| VLAPS | 2025.11 | CoRL25 Workshop🔗 | ✓(ST) | ✗ | Octo | Diffusion | S | MCTS | Test-time | MB | 🔗 |
| VLA-Pilot | 2025.11 | - | ✗ | ✓(ST) | DiVLA / RDT | AR / Diffusion | D | Value GuidanceT | Test-time | MB(MLLM) | 🔗 |
| TACO | 2025.12 | - | ✓ | ✓(ST) | π₀ / OpenVLA et al. | Flow | S | CNF estimation | Test-time | MF | 🔗 |
| TT-VLA | 2026.1 | - | ✓(ST) | ✓(ST) | Nora / OpenVLA / TraceVLA | AR | D | PPO (Value-free) | Test-time | MF | - |
| VLS | 2026.2 | - | ✓(MT) | ✓(MT) | OpenVLA / π₀ / π₀.₅ | Flow | D | gradient-based steer | Test-time | MB(VLM) | 🔗 |
| FASTER | 2026.04 | - | ✓(ST) | ✗ | π₀.₅ | Flow | D | Value-guided Denoising MDP | Test-time | MF | - |
Note: The 🔗 symbol in the Project column indicates papers with available project pages, GitHub repositories, or demo websites.
🔗 Useful Resources
🎯 RL-VLA Action Optimization
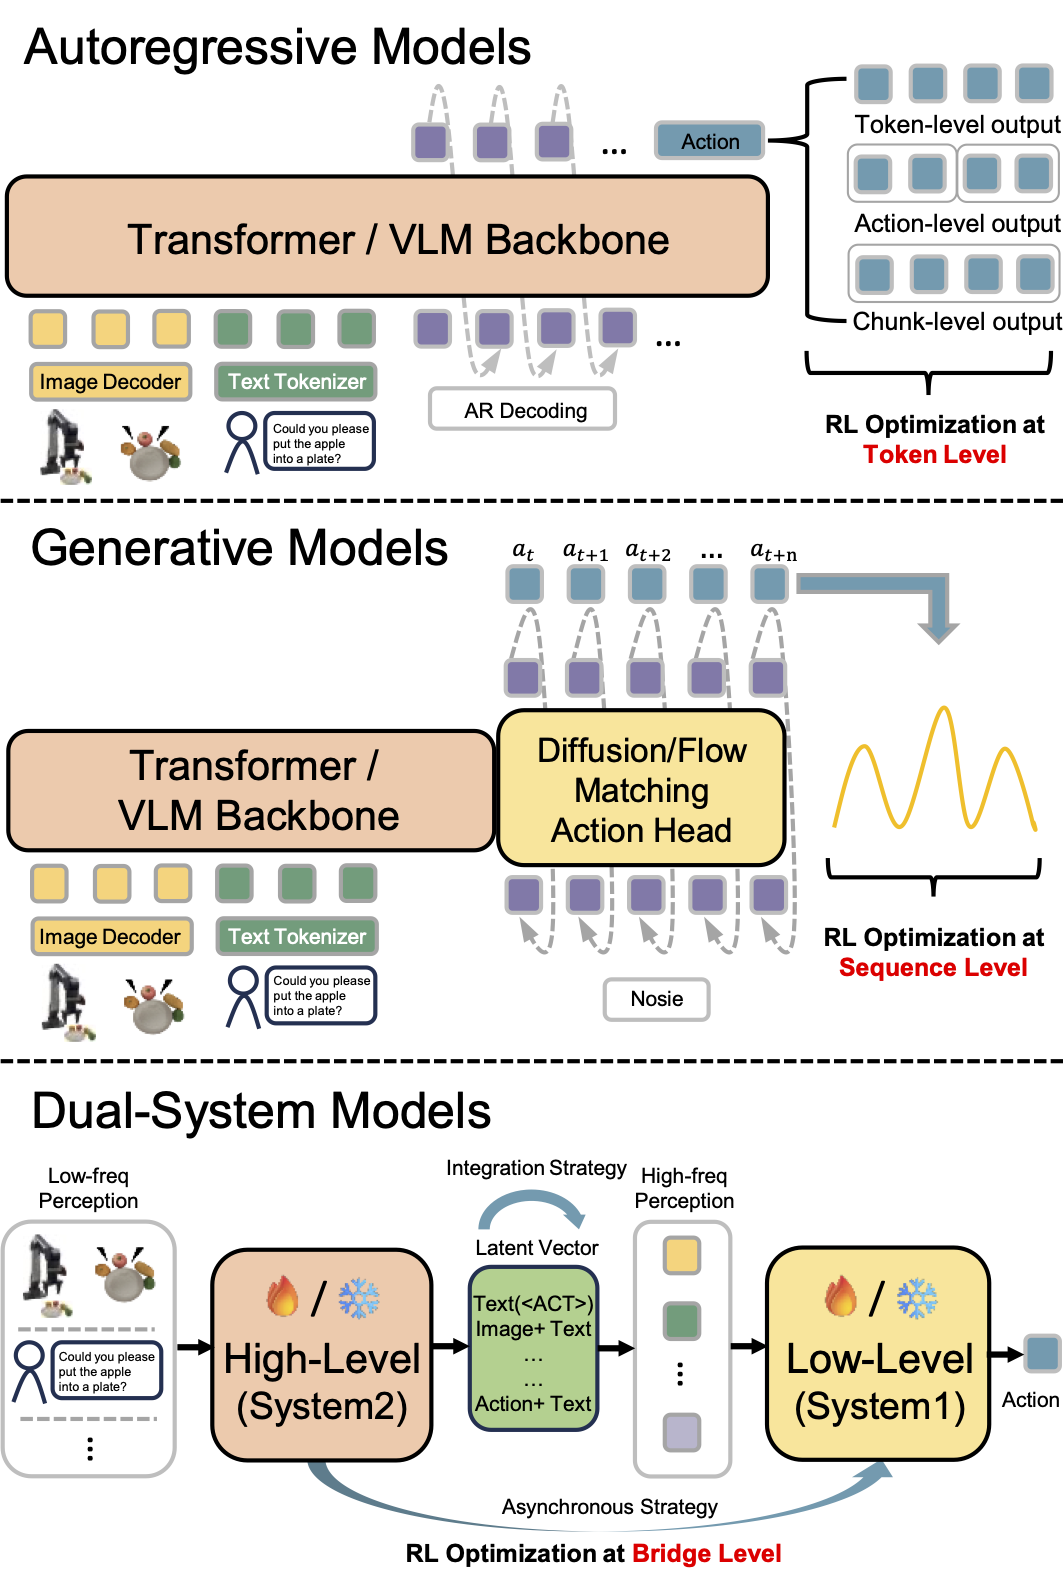
Different VLA architectures require distinct RL optimization strategies based on their action generation mechanisms:
-
🔤 Autoregressive VLA: Optimizes actions at the token-level. Each action token is individually optimized through RL, enabling fine-grained control over action sequences but requiring careful handling of sequential dependencies.
-
🌊 Generative VLA (Diffusion/Flow): Optimizes along the action generation process at the sequence-level. The entire action trajectory is optimized as a cohesive unit through the denoising or flow-matching process, providing holistic action optimization.
-
🔗 Dual-system VLA: Optimizes at the bridge-level. RL decides which high-level action proposal to pass to the fast controller, creating a hierarchical optimization approach that complements both token-level and sequence-level methods.
Base VLA Models
- GR00T-N1 - NVIDIA series
- π0 - PI series
- OpenVLA - Open-source VLA model
- Octo - Generalist robot policy
- RT-1 - Robotics Transformer
Datasets & Benchmarks
- Open X-Embodiment - Large-scale robotic datasets
- LIBERO - Benchmark for lifelong robot learning
- SimplerEnv - Benchmark for real-sim robot learning
- RoboTwin - Benchmark for bimanual robot learning
- DeepPHY - Benchmark for physical reasoning
Frameworks & Tools
- RLinf - Infrastructure for online RL fine-tuning of VLAs
- RLinfv0.2 - Infrastructure for real world RL
🤝 Contributing
We welcome contributions to this awesome list! Please feel free to:
- Add new papers: Submit a PR with new RL-VLA papers following the existing format
- Update information: Correct any errors or update paper information
- Suggest improvements: Propose better organization or additional sections
Contribution Guidelines
- Ensure papers are relevant to RL-VLA research
- Include paper links, project pages (if available), and key details
- Follow the existing table format for consistency
- Add a brief description for new paradigms or significant methodological contributions
📄 Citation
If you find this repository useful, please consider citing:
@article{pine2025rlvla,
  title={A Survey on Reinforcement Learning of Vision-Language-Action Models for Robotic Manipulation},
  author={Haoyuan Deng, Zhenyu Wu, Haichao Liu, Wenkai Guo, Yuquan Xue, Ziyu Shan, Chuanrui Zhang, Bofang Jia, Yuan Ling, Guanxing Lu, and Ziwei Wang},
  journal={TechRxiv},
  year={2025},
  doi={10.36227/techrxiv.176531955.54563920/v1},
  note={Preprint}
}
⭐ Star History
Star this repository if you find it helpful!