SpecAugment 
This is a implementation of SpecAugment that speech data augmentation method which directly process the spectrogram with Tensorflow & Pytorch, introduced by Google Brain[1]. This is currently under the Apache 2.0, Please feel free to use for your project. Enjoy!
How to use
First, you need to have python 3 installed along with Tensorflow.
Next, you need to install some audio libraries work properly. To install the requirement packages. Run the following command:
pip3 install SpecAugment
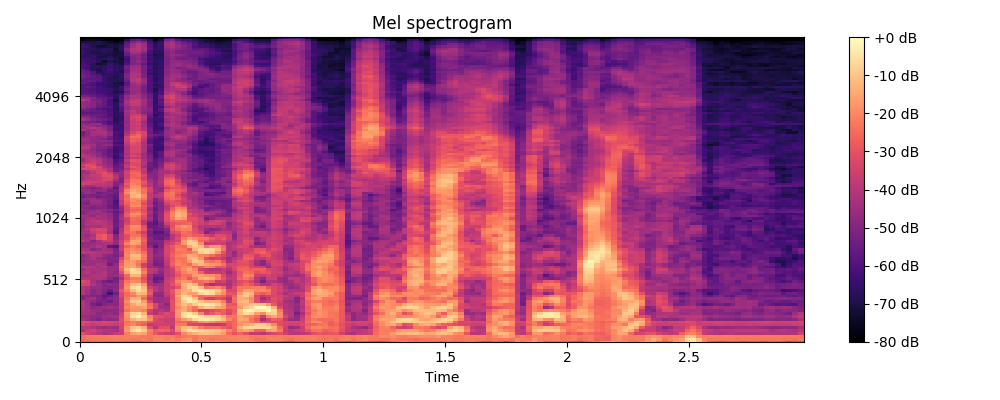
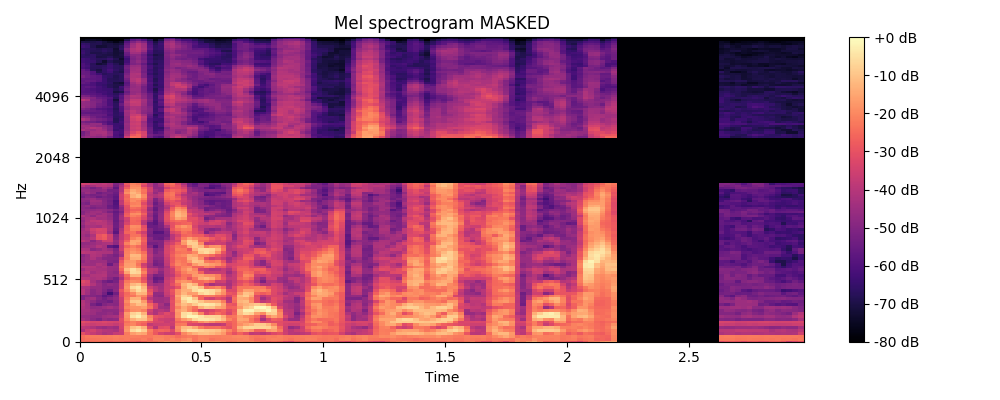
And then, run the specAugment.py program. It modifies the spectrogram by warping it in the time direction, masking blocks of consecutive frequency channels, and masking blocks of utterances in time.
Try your audio file SpecAugment
$ python3
>>> import librosa
>>> from specAugment import spec_augment_tensorflow
# If you are Pytorch, then import spec_augment_pytorch instead of spec_augment_tensorflow
>>> audio, sampling_rate = librosa.load(audio_path)
>>> mel_spectrogram = librosa.feature.melspectrogram(y=audio,
                                                     sr=sampling_rate,
                                                     n_mels=256,
                                                     hop_length=128,
                                                     fmax=8000)
>>> warped_masked_spectrogram = spec_augment_tensorflow.spec_augment(mel_spectrogram=mel_spectrogram)
>>> print(warped_masked_spectrogram)
'
[[1.54055389e-01 7.51822486e-01 7.29588015e-01 ... 1.03616300e-01
  1.04682689e-01 1.05411769e-01]
 [2.21608739e-01 1.38559084e-01 1.01564167e-01 ... 4.19907116e-02
  4.86430404e-02 5.27331798e-02]
 [3.62784019e-01 2.09934399e-01 1.79158230e-01 ... 2.42307431e-01
  3.18662338e-01 3.67405599e-01]
 ...
 [6.36117335e-07 8.06897948e-07 8.55346431e-07 ... 2.84445018e-07
  4.02975952e-07 5.57131738e-07]
 [6.27753429e-07 7.53681318e-07 8.13035033e-07 ... 1.35111146e-07
  2.74058225e-07 4.56901031e-07]
 [0.00000000e+00 7.48416680e-07 5.51771037e-07 ... 1.13901361e-07
  2.56365068e-07 4.43868592e-07]]
'
Learn more examples about how to do specific tasks in SpecAugment at the test code.
python spec_augment_test.py
In test code, we using one of the LibriSpeech dataset.