Awesome Model Quantization 
Awesome Model Quantization is a curated, continuously updated collection of papers, benchmarks, surveys, and open-source implementations on neural network and model quantization. It spans binary and ternary networks, post-training quantization, quantization-aware training, vector and lattice quantization, low-bit LLMs, multimodal and generative models, KV-cache quantization, low-precision training, and hardware-efficient deployment. The project was initiated by Haotong Qin. Thanks to all contributors for helping grow and maintain this collection.
Quick Navigation
-
2026 · 2025 · 2024 · 2023 · 2022 · 2021 · 2020 · 2019 · 2018 · 2017 · 2016 · 2015 · 2014
-
Books · Related Repositories · Researcher Homepages · Contributing / Scope
Research Landscape
Model quantization can be organized along five dimensions:
- Optimization: post-training quantization (PTQ), quantization-aware training (QAT), quantized fine-tuning, data-free methods, and low-precision training.
- Representation: scalar, vector/codebook, lattice, binary-coded, binary/ternary, and mixed-precision quantization.
- Error reduction: rotations, outlier smoothing, residual reconstruction, error compensation, and sensitivity-aware methods.
- Quantized tensors: weights, activations, KV caches, training states, gradients, and communication.
- Models and deployment: vision, language, multimodal, generative, state space, and graph models, alongside edge and hardware systems.
Methods often combine several dimensions, such as PTQ with rotations and vector codebooks.
🔎 Explore the taxonomy and method connections · Click to expand
Optimization paradigm
Post-Training Quantization (PTQ) converts a pretrained model, often with calibration: GPTQ, SmoothQuant, AWQ, OmniQuant, QuaRot, SpinQuant, FlatQuant, BiLLM. Quantization-Aware Training (QAT) models quantization during optimization: PACT, LSQ, IR-Net. Quantized Fine-Tuning / Parameter-Efficient Fine-Tuning (PEFT) adapts low-bit models: QLoRA, QA-LoRA, LoftQ, IR-QLoRA, L4Q. Data-Free / Zero-Shot Quantization avoids original training data, using model statistics or synthetic samples: ZeroQ, Qimera. Low-Precision Training also reduces precision in training computation or stored states: INT8/FP8 training, 8-bit Optimizers.
Representation / coding structure
Scalar quantization codes individual values; non-uniform, logarithmic, and floating-point quantization change the available levels (AdaLog, LLM-FP4). Vector quantization jointly codes tuples; codebook quantization stores reusable representatives; product / grouped vector quantization partitions vectors into groups (GPTVQ, VPTQ, EPQuant). Lattice quantization uses structured geometric codebooks (QuIP#, NestQuant, grouped lattice vector quantizers). Binary-coded quantization combines binary bases (AnyBCQ); binary / ternary quantization constrains values to two / three levels (IR-Net, BiBERT, PT²-LLM). Mixed precision allocates different bit widths or formats across tensors or groups (HAWQ, SliM-LLM).
Transformation / error handling
Rotation / orthogonal transforms redistribute coordinates (QuaRot, SpinQuant); outlier smoothing / redistribution balances quantization difficulty (SmoothQuant, AWQ). Residual / low-rank reconstruction models remaining errors or outliers (LQER, SVDQuant); error compensation corrects quantization effects (GPTQ, First-Order Error Matters). Saliency-aware / Hessian-aware quantization uses importance or curvature to guide precision, reconstruction, or rounding (HAWQ, GPTQ, BiLLM). These techniques can accompany scalar or structured coding.
Quantized object
Weights (GPTQ, AWQ); activations (PACT); weight + activation (SmoothQuant, BiBERT); KV cache (KIVI, KVQuant, ZipCache, PM-KVQ); training states / optimizer states (ActNN, 8-bit Optimizers); gradients / communication (DoReFa-Net, SDP4Bit). Weight bit width does not imply the same activation, accumulator, or cache precision.
Model family / deployment
CNNs / classical vision (XNOR-Net, BRECQ); Vision Transformers (PTQ4ViT); Large Language Models (GPTQ, QLoRA); multimodal / VLM / VLA (Q-VLM, MQuant, AutoQVLA); diffusion / generative models (PTQ4DM, Q-Diffusion, PTQD, ViDiT-Q, SVDQuant, BinaryDM, Q-VDiT, S²Q-VDiT, QuantSparse); Mamba / state space models (Quamba2, SSDi8); graph / point cloud models (EPQuant, BiPointNet); edge / embedded / hardware-oriented systems (HAQ, FINN, LUT-GEMM).
For the structured-coding lineage, QuIP introduces incoherence processing for low-bit LLM quantization; QuIP# connects this direction to lattice codebooks, while QTIP uses trellis coding. GPTVQ, VPTQ, and NestQuant explore vector or lattice representations. TurboQuant and RaBitQ are also retained for their vector-quantization methodology; RaBitQ targets approximate nearest-neighbor search rather than LLM weight quantization.
Bit width alone does not specify storage overhead, arithmetic precision, or deployment speed.
Representative Works
Selected works grouped by technical approach, with authors and short method summaries. Each paper has one primary home here; the yearly collection includes the wider literature.
- Foundations: Classical / QAT · Data-free · Binary / ternary · Vector / codebook
- Language models: Transformer / LLM · Quantized fine-tuning · KV cache
- Models and systems: Generative models · Multimodal / state space · Vision / hardware · Floating-point formats · Training
Reading the links: Scholar opens a title search on Google Scholar, where citation counts can be viewed. Star badges show the linked GitHub repository’s stars, which may cover several papers. These are discovery aids, not rankings.
Classical Quantization and QAT
From binary weights and learned codebooks to integer arithmetic, learned quantizers and reconstruction-based PTQ.
-
BinaryConnect: Training Deep Neural Networks with binary weights during propagations
Matthieu Courbariaux, Yoshua Bengio, Jean-Pierre David
NeurIPS 2015 ·
Neural NetworksQATBinary Weights· Paper · Code · ScholarTrains neural networks with binary weights during forward and backward propagation.
-
XNOR-Net: ImageNet Classification Using Binary Convolutional Neural Networks
Mohammad Rastegari, Vicente Ordonez, Joseph Redmon, Ali Farhadi
ECCV 2016 ·
CNNBinaryWeight + Activation· Paper · Code · ScholarApproximates convolutions with binary weights and inputs for efficient CNN inference.
-
Deep Compression: Compressing Deep Neural Networks with Pruning, Trained Quantization and Huffman Coding
Song Han, Huizi Mao, William J. Dally
ICLR 2016 ·
CNNWeight SharingCodebook· Paper · ScholarCombines pruning, trained weight sharing and Huffman coding, connecting learned quantization to compressed model storage.
-
PACT: Parameterized Clipping Activation for Quantized Neural Networks
Jungwook Choi, Zhuo Wang, Swagath Venkataramani, Pierce I-Jen Chuang, Vijayalakshmi Srinivasan, Kailash Gopalakrishnan
ICLR 2018 ·
CNNQATActivations· Paper · ScholarLearns activation clipping thresholds to support low-bit network training.
-
Quantization and Training of Neural Networks for Efficient Integer-Arithmetic-Only Inference
Benoit Jacob, Skirmantas Kligys, Bo Chen, Menglong Zhu, Matthew Tang, Andrew Howard, Hartwig Adam, Dmitry Kalenichenko
CVPR 2018 ·
QATINT8Integer-Only Inference· Paper · ScholarCo-designs quantization-aware training and integer arithmetic for mobile inference, including scale and zero-point handling.
-
HAWQ: Hessian AWare Quantization of Neural Networks With Mixed-Precision
Zhen Dong, Zhewei Yao, Amir Gholami, Michael W. Mahoney, Kurt Keutzer
ICCV 2019 ·
Mixed PrecisionHessian-Aware· Paper · ScholarUses Hessian information to guide mixed-precision neural network quantization.
-
Learned Step Size Quantization
Steven K. Esser, Jeffrey L. McKinstry, Deepika Bablani, Rathinakumar Appuswamy, Dharmendra S. Modha
ICLR 2020 ·
QATLow-Bit· Paper · ScholarLearns quantizer step sizes alongside network parameters.
-
Up or Down? Adaptive Rounding for Post-Training Quantization
Markus Nagel, Rana Ali Amjad, Mart van Baalen, Christos Louizos, Tijmen Blankevoort
ICML 2020 ·
PTQRounding· Paper · ScholarOptimizes rounding decisions when converting pretrained weights to low precision.
-
HAWQ-V2: Hessian Aware trace-Weighted Quantization of Neural Networks
Zhen Dong, Zhewei Yao, Daiyaan Arfeen, Amir Gholami, Michael Mahoney, Kurt Keutzer
NeurIPS 2020 ·
Mixed PrecisionHessian-Aware· Paper · ScholarDevelops trace-weighted Hessian sensitivity for mixed-precision allocation.
-
BRECQ: Pushing the Limit of Post-Training Quantization by Block Reconstruction
Yuhang Li, Ruihao Gong, Xu Tan, Yang Yang, Peng Hu, Qi Zhang, Fengwei Yu, Wei Wang, Shi Gu
ICLR 2021 ·
CNNPTQReconstruction· Paper · Code · ScholarUses block reconstruction to reduce post-training quantization error.
-
QDrop: Randomly Dropping Quantization for Extremely Low-bit Post-Training Quantization
Xiuying Wei, Ruihao Gong, Yuhang Li, Xianglong Liu, Fengwei Yu
ICLR 2022 ·
PTQActivationsReconstruction· Paper · Code · ScholarRandomly bypasses activation quantization during reconstruction to improve low-bit generalization beyond the calibration data.
Data-Free and Zero-Shot Quantization
These methods replace access to the original dataset with model statistics or generated samples; they may still require calibration or optimization.
-
Data-Free Quantization Through Weight Equalization and Bias Correction
Markus Nagel, Mart van Baalen, Tijmen Blankevoort, Max Welling
ICCV 2019 ·
CNNPTQData-Free· Paper · ScholarEqualizes channel ranges and corrects quantization-induced bias using model parameters and statistics.
-
ZeroQ: A Novel Zero Shot Quantization Framework
Yaohui Cai, Zhewei Yao, Zhen Dong, Amir Gholami, Michael W. Mahoney, Kurt Keutzer
CVPR 2020 ·
CNNData-FreeMixed Precision· Paper · Code · ScholarSynthesizes calibration inputs from batch-normalization statistics to quantize without the original training dataset.
-
Diversifying Sample Generation for Accurate Data-Free Quantization
Xiangguo Zhang, Haotong Qin, Yifu Ding, Ruihao Gong, Qinghua Yan, Renshuai Tao, Yuhang Li, Fengwei Yu, Xianglong Liu
CVPR 2021 · Oral ·
CNNData-FreeSynthetic DataPTQ· Paper · ScholarRelaxes batch-normalization statistic matching and varies layer-wise emphasis to diversify synthetic calibration samples for data-free quantization.
-
Diverse Sample Generation: Pushing the Limit of Generative Data-Free Quantization
Haotong Qin, Yifu Ding, Xiangguo Zhang, Jiakai Wang, Xianglong Liu, Jiwen Lu
IEEE TPAMI 2023 ·
CNNData-FreePTQ + QATSample Diversity· Paper · Code · ScholarExtends the CVPR 2021 DSG method with theoretical analysis and inter-sample decorrelation, improving synthetic-data generation for both PTQ and QAT.
-
LLM-QAT: Data-Free Quantization Aware Training for Large Language Models
Zechun Liu, Barlas Oguz, Changsheng Zhao, Ernie Chang, Pierre Stock, Yashar Mehdad, Yangyang Shi, Raghuraman Krishnamoorthi, Vikas Chandra
ACL Findings 2024 ·
LLMQATData-FreeKV Cache· Paper · ScholarUses the pretrained model’s generated text for distillation-based QAT of weights, activations and KV caches.
Transformer and LLM Quantization
Weight-only compression, weight–activation quantization and QAT address different deployment needs. Sparse outlier handling and rotations offer complementary ways to control error.
-
LLM.int8(): 8-bit Matrix Multiplication for Transformers at Scale
Tim Dettmers, Mike Lewis, Younes Belkada, Luke Zettlemoyer
NeurIPS 2022 ·
TransformerINT8Mixed Precision· Paper · Code · ScholarEnables 8-bit matrix multiplication at transformer scale while handling outlier features in higher precision.
-
GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers
Elias Frantar, Saleh Ashkboos, Torsten Hoefler, Dan Alistarh
ICLR 2023 ·
LLMPTQWeights· Paper · Code · ScholarUses approximate second-order information and error compensation for low-bit weight quantization.
-
SmoothQuant: Accurate and Efficient Post-Training Quantization for Large Language Models
Guangxuan Xiao, Ji Lin, Mickael Seznec, Hao Wu, Julien Demouth, Song Han
ICML 2023 ·
LLMPTQWeight + Activation· Paper · Code · ScholarRedistributes activation outlier difficulty into weights to enable low-precision matrix multiplication.
-
AWQ: Activation-aware Weight Quantization for On-Device LLM Compression and Acceleration
Ji Lin, Jiaming Tang, Haotian Tang, Shang Yang, Wei-Ming Chen, Wei-Chen Wang, Guangxuan Xiao, Xingyu Dang, Chuang Gan, Song Han
MLSys 2024 ·
LLMPTQWeightsSaliency-Aware· Paper · Code · ScholarUses activation information to guide weight quantization for on-device compression and acceleration.
-
OmniQuant: Omnidirectionally Calibrated Quantization for Large Language Models
Wenqi Shao, Mengzhao Chen, Zhaoyang Zhang, Peng Xu, Lirui Zhao, Zhiqian Li, Kaipeng Zhang, Peng Gao, Yu Qiao, Ping Luo
ICLR 2024 ·
LLMPTQCalibration· Paper · Code · ScholarOptimizes clipping and equivalent transformations to calibrate low-bit LLMs.
-
QuaRot: Outlier-Free 4-Bit Inference in Rotated LLMs
Saleh Ashkboos, Amirkeivan Mohtashami, Maximilian L. Croci, Bo Li, Pashmina Cameron, Martin Jaggi, Dan Alistarh, Torsten Hoefler, James Hensman
NeurIPS 2024 ·
LLMPTQ4-BitRotation· Paper · Code · ScholarUses rotations to suppress outliers and enable 4-bit inference.
-
SpQR: A Sparse-Quantized Representation for Near-Lossless LLM Weight Compression
Tim Dettmers, Ruslan Svirschevski, Vage Egiazarian, Denis Kuznedelev, Elias Frantar, Saleh Ashkboos, Alexander Borzunov, Torsten Hoefler, Dan Alistarh
ICLR 2024 ·
LLMPTQWeightsSparse Outliers· Paper · Code · ScholarSeparates sensitive outlier weights into a sparse higher-precision component while quantizing the remaining weights.
-
SqueezeLLM: Dense-and-Sparse Quantization
Sehoon Kim, Coleman Hooper, Amir Gholami, Zhen Dong, Xiuyu Li, Sheng Shen, Michael W. Mahoney, Kurt Keutzer
ICML 2024 ·
LLMPTQNon-uniformSparse Outliers· Paper · Code · ScholarCombines sensitivity-weighted non-uniform scalar quantization with a sparse component for outlier weights.
-
SpinQuant: LLM Quantization with Learned Rotations
Zechun Liu, Changsheng Zhao, Igor Fedorov, Bilge Soran, Dhruv Choudhary, Raghuraman Krishnamoorthi, Vikas Chandra, Yuandong Tian, Tijmen Blankevoort
ICLR 2025 ·
LLMPTQLearned Rotation· Paper · Code · ScholarLearns rotations to make LLM representations more amenable to quantization.
-
FlatQuant: Flatness Matters for LLM Quantization
Yuxuan Sun, Ruikang Liu, Haoli Bai, Han Bao, Kang Zhao, Yuening Li, Jiaxin Hu, Xianzhi Yu, Lu Hou, Chun Yuan, Xin Jiang, Wulong Liu, Jun Yao
ICML 2025 ·
LLMPTQTransformation· Paper · Code · ScholarTargets distribution flatness to improve LLM quantization.
-
EfficientQAT: Efficient Quantization-Aware Training for Large Language Models
Mengzhao Chen, Wenqi Shao, Peng Xu, Jiahao Wang, Peng Gao, Kaipeng Zhang, Ping Luo
ACL 2025 ·
LLMQATLow-Bit· Paper · Code · ScholarTrains block parameters first, then quantization parameters end to end, to reduce the cost of LLM QAT.
Quantized Fine-Tuning
QLoRA and related methods adapt low-bit bases with low-rank updates; PV-Tuning also optimizes discrete compressed representations.
-
QLoRA: Efficient Finetuning of Quantized LLMs
Tim Dettmers, Artidoro Pagnoni, Ari Holtzman, Luke Zettlemoyer
NeurIPS 2023 ·
LLMPEFT4-Bit· Paper · Code · ScholarFine-tunes low-rank adapters through a frozen 4-bit quantized base model.
-
QA-LoRA: Quantization-Aware Low-Rank Adaptation of Large Language Models
Yuhui Xu, Lingxi Xie, Xiaotao Gu, Xin Chen, Heng Chang, Hengheng Zhang, Zhengsu Chen, Xiaopeng Zhang, Qi Tian
ICLR 2024 ·
LLMPEFTQuantization-Aware· Paper · Code · ScholarCombines quantization-aware optimization with low-rank adaptation.
-
LoftQ: LoRA-Fine-Tuning-aware Quantization for Large Language Models
Yixiao Li, Yifan Yu, Chen Liang, Pengcheng He, Nikos Karampatziakis, Weizhu Chen, Tuo Zhao
ICLR 2024 ·
LLMPEFTLow-Bit· Paper · Code · ScholarAligns quantization with LoRA initialization to reduce the error encountered during adaptation.
-
Accurate LoRA-Finetuning Quantization of LLMs via Information Retention
Haotong Qin, Xudong Ma, Xingyu Zheng, Xiaoyang Li, Yang Zhang, Shouda Liu, Jie Luo, Xianglong Liu, Michele Magno
ICML 2024 ·
LLMPEFTInformation-Aware· Paper · Code · ScholarUses information retention to improve low-bit quantization and LoRA adaptation.
-
PV-Tuning: Beyond Straight-Through Estimation for Extreme LLM Compression
Vladimir Malinovskii, Denis Mazur, Ivan Ilin, Denis Kuznedelev, Konstantin Burlachenko, Kai Yi, Dan Alistarh, Peter Richtarik
NeurIPS 2024 ·
LLMQuantized Fine-TuningDiscrete Optimization· Paper · Code · ScholarAlternates continuous and discrete optimization to fine-tune extremely compressed models, including additive-codebook representations.
-
L4Q: Parameter Efficient Quantization-Aware Fine-Tuning on Large Language Models
Hyesung Jeon, Yulhwa Kim, Jae-Joon Kim
ACL 2025 ·
LLMPEFTQAT· Paper · ScholarCombines parameter-efficient fine-tuning with quantization-aware training.
Extreme Low-Bit, Binary and Ternary
Binary CNNs and transformers, post-training binarization, and native ternary pretraining have different training costs and arithmetic requirements.
-
Bi-Real Net: Enhancing the Performance of 1-bit CNNs With Improved Representational Capability and Advanced Training Algorithm
Zechun Liu, Baoyuan Wu, Wenhan Luo, Xin Yang, Wei Liu, Kwang-Ting Cheng
ECCV 2018 ·
CNNBinaryQAT· Paper · Code · ScholarConnects real-valued intermediate activations through shortcuts to improve information flow in 1-bit CNNs.
-
Forward and Backward Information Retention for Accurate Binary Neural Networks
Haotong Qin, Ruihao Gong, Xianglong Liu, Mingzhu Shen, Ziran Wei, Fengwei Yu, Jingkuan Song
CVPR 2020 ·
CNNQATBinary1-Bit· Paper · Code · ScholarRetains information in both forward activations and backward gradients when training binary neural networks.
-
ReActNet: Towards Precise Binary Neural Network with Generalized Activation Functions
Zechun Liu, Zhiqiang Shen, Marios Savvides, Kwang-Ting Cheng
ECCV 2020 ·
CNNBinaryQAT· Paper · Code · ScholarLearns activation shifts and reshaping functions to reduce the accuracy gap between binary and real-valued networks.
-
BiBERT: Accurate Fully Binarized BERT
Haotong Qin, Yifu Ding, Mingyuan Zhang, Qinghua Yan, Aishan Liu, Qingqing Dang, Ziwei Liu, Xianglong Liu
ICLR 2022 ·
TransformerNLPBinaryWeight + Activation· Paper · Code · ScholarTargets fully binarized BERT, extending binary networks to transformer language models.
-
BiLLM: Pushing the Limit of Post-Training Quantization for LLMs
Wei Huang, Yangdong Liu, Haotong Qin, Ying Li, Shiming Zhang, Xianglong Liu, Michele Magno, Xiaojuan Qi
ICML 2024 ·
LLMPTQBinaryExtreme Low-Bit· Paper · Code · ScholarUses saliency-aware binarization to push pretrained LLM weights into the extreme low-bit regime.
-
DB-LLM: Accurate Dual-Binarization for Efficient LLMs
Hong Chen, Chengtao Lv, Liang Ding, Haotong Qin, Xiabin Zhou, Yifu Ding, Xuebo Liu, Min Zhang, Jinyang Guo, Xianglong Liu, Dacheng Tao
ACL Findings 2024 ·
LLMDual BinarizationExtreme Low-Bit· Paper · ScholarUses dual binarization to compress LLMs while retaining accuracy.
-
The Era of 1-bit LLMs: All Large Language Models are in 1.58 Bits
Shuming Ma, Hongyu Wang, Lingxiao Ma, Lei Wang, Wenhui Wang, Shaohan Huang, Li Dong, Ruiping Wang, Jilong Xue, Furu Wei
arXiv 2024 ·
LLMQATTernary Weights8-Bit Activations· Paper · ScholarExtends BitNet’s quantization-aware pretraining to ternary weights; this is a training recipe, distinct from post-training binarization.
-
ARB-LLM: Alternating Refined Binarizations for Large Language Models
Zhiteng Li, Xianglong Yan, Tianao Zhang, Haotong Qin, Dong Xie, Jiang Tian, Zhongchao Shi, Linghe Kong, Yulun Zhang, Xiaokang Yang
ICLR 2025 ·
LLMBinaryExtreme Low-Bit· Paper · Code · ScholarRefines alternating binarizations for low-bit LLM representation.
-
PTQ1.61: Push the Real Limit of Extremely Low-Bit Post-Training Quantization Methods for Large Language Models
Jiaqi Zhao, Miao Zhang, Ming Wang, Yuzhang Shang, Kaihao Zhang, Weili Guan, Yaowei Wang, Min Zhang
ACL 2025 ·
LLMPTQExtreme Low-Bit· Paper · Code · ScholarExplores extremely low-bit post-training quantization for LLMs.
-
PT²-LLM: Post-Training Ternarization for Large Language Models
Xianglong Yan, Chengzhu Bao, Zhiteng Li, Tianao Zhang, Kaicheng Yang, Haotong Qin, Ruobing Xie, Xingwu Sun, Yulun Zhang
ICLR 2026 ·
LLMPTQTernary· Paper · Code · ScholarConverts pretrained large language models to ternary representations.
Vector, Lattice and Codebook Quantization
From CNN product quantization to LLM additive, lattice and trellis codes. QuIP provides the incoherence-processing precursor; RaBitQ contributes vector-search methodology.
-
Compressing Deep Convolutional Networks using Vector Quantization
Yunchao Gong, Liu Liu, Ming Yang, Lubomir Bourdev
arXiv 2014 ·
CNNVector QuantizationProduct Quantization· Paper · ScholarStudies clustering and product quantization of CNN parameters as early approaches to reducing model storage.
-
QuIP: 2-Bit Quantization of Large Language Models With Guarantees
Jerry Chee, Yaohui Cai, Volodymyr Kuleshov, Christopher De Sa
NeurIPS 2023 ·
LLMPTQ2-BitIncoherence· Paper · Code · ScholarUses incoherence processing for low-bit quantization with guarantees, forming a precursor to the QuIP# lattice-codebook lineage.
-
QuIP#: Even Better LLM Quantization with Hadamard Incoherence and Lattice Codebooks
Albert Tseng, Jerry Chee, Qingyao Sun, Volodymyr Kuleshov, Christopher De Sa
ICML 2024 ·
LLMLatticeCodebookHadamard· Paper · Code · ScholarCombines Hadamard incoherence processing with lattice codebooks for LLM quantization.
-
QTIP: Quantization with Trellises and Incoherence Processing
Albert Tseng, Qingyao Sun, David Hou, Christopher De Sa
NeurIPS 2024 ·
LLMTrellis CodingIncoherence· Paper · Code · ScholarCombines trellis-based quantization with incoherence processing for compact LLM representation.
-
GPTVQ: The Blessing of Dimensionality for LLM Quantization
Mart van Baalen, Andrey Kuzmin, Ivan Koryakovskiy, Markus Nagel, Peter Couperus, Cedric Bastoul, Eric Mahurin, Tijmen Blankevoort, Paul Whatmough
arXiv 2024 ·
LLMVector QuantizationWeights· Paper · Code · ScholarExploits joint quantization of multiple weight coordinates rather than coding each weight independently.
-
VPTQ: Extreme Low-bit Vector Post-Training Quantization for Large Language Models
Yifei Liu, Jicheng Wen, Yang Wang, Shengyu Ye, Li Lyna Zhang, Ting Cao, Cheng Li, Mao Yang
EMNLP 2024 ·
LLMPTQVector QuantizationExtreme Low-Bit· Paper · Code · ScholarUses vector post-training quantization for extremely low-bit LLM compression.
-
RaBitQ: Quantizing High-Dimensional Vectors with a Theoretical Error Bound for Approximate Nearest Neighbor Search
Jianyang Gao, Cheng Long
SIGMOD 2024 ·
Vector QuantizationBinary CodesVector Search· Paper · Code · ScholarQuantizes high-dimensional vectors with a theoretical error bound for approximate nearest-neighbor search.
-
Extreme Compression of Large Language Models via Additive Quantization
Vage Egiazarian, Andrei Panferov, Denis Kuznedelev, Elias Frantar, Artem Babenko, Dan Alistarh
ICML 2024 ·
LLMPTQAdditive Codebooks2–3 Bit· Paper · Code · ScholarRepresents weight vectors as sums of learned codewords and jointly optimizes codebooks within transformer blocks.
-
NestQuant: nested lattice quantization for matrix products and LLMs
Semyon Savkin, Eitan Porat, Or Ordentlich, Yury Polyanskiy
ICML 2025 ·
LLMLatticeMatrix Products· Paper · ScholarUses nested lattice quantization for matrix products and LLMs.
-
Learning Grouped Lattice Vector Quantizers for Low-Bit Large Language Models
Xi Zhang, Xiaolin Wu, Jiamang Wang, Weisi Lin
NeurIPS 2025 ·
LLMGrouped Vector QuantizationLattice· Paper · ScholarLearns grouped lattice vector quantizers for low-bit LLM representation.
-
AnyBCQ: Hardware Efficient Flexible Binary-Coded Quantization for Multi-Precision LLMs
Gunho Park, Jeongin Bae, Beomseok Kwon, Byeongwook Kim, Se Jung Kwon, Dongsoo Lee
ICLR 2026 ·
LLMBinary-CodedMixed PrecisionHardware· Paper · Code · ScholarDevelops flexible binary-coded quantization for hardware-efficient multi-precision LLMs.
-
TurboQuant: Online Vector Quantization with Near-optimal Distortion Rate
Amir Zandieh, Majid Daliri, Majid Hadian, Vahab Mirrokni
ICLR 2026 ·
Vector QuantizationOnlineDistortion· Paper · ScholarStudies online vector quantization with near-optimal distortion rate.
KV Cache Quantization
These methods compress inference-time key and value tensors; their bit widths are separate from model weight precision.
-
KIVI: A Tuning-Free Asymmetric 2bit Quantization for KV Cache
Zirui Liu, Jiayi Yuan, Hongye Jin, Shaochen Zhong, Zhaozhuo Xu, Vladimir Braverman, Beidi Chen, Xia Hu
ICML 2024 ·
LLMKV Cache2-Bit· Paper · Code · ScholarUses asymmetric, tuning-free 2-bit quantization to compress key and value caches.
-
KVQuant: Towards 10 Million Context Length LLM Inference with KV Cache Quantization
Coleman Hooper, Sehoon Kim, Hiva Mohammadzadeh, Michael Mahoney, Sophia Shao, Kurt Keutzer, Amir Gholami
NeurIPS 2024 ·
LLMKV CacheLong Context· Paper · Code · ScholarTargets long-context inference by reducing the memory occupied by the KV cache.
-
ZipCache: Accurate and Efficient KV Cache Quantization with Salient Token Identification
Yefei He, Luoming Zhang, Weijia Wu, Jing Liu, Hong Zhou, Bohan Zhuang
NeurIPS 2024 ·
LLMKV CacheSalient Tokens· Paper · Code · ScholarUses salient-token identification to guide accurate and efficient cache quantization.
-
PM-KVQ: Progressive Mixed-precision KV Cache Quantization for Long-CoT LLMs
Tengxuan Liu, Shiyao Li, Jiayi Yang, Tianchen Zhao, Feng Zhou, Xiaohui Song, Guohao Dai, Shengen Yan, Huazhong Yang, Yu Wang
ICLR 2026 ·
LLMKV CacheMixed Precision· Paper · Code · ScholarProgressively quantizes KV caches with mixed precision for long chain-of-thought inference.
Diffusion and Generative Model Quantization
Early diffusion PTQ addresses denoising-step sensitivity; later work extends to diffusion transformers, low-rank outlier handling and video generation.
-
Post-training Quantization on Diffusion Models
Yuzhang Shang, Zhihang Yuan, Bin Xie, Bingzhe Wu, Yan Yan
CVPR 2023 ·
DiffusionPTQ· Paper · Code · ScholarAdapts post-training quantization to diffusion model inference.
-
Q-diffusion: Quantizing Diffusion Models
Xiuyu Li, Yijiang Liu, Long Lian, Huanrui Yang, Zhen Dong, Daniel Kang, Shanghang Zhang, Kurt Keutzer
ICCV 2023 ·
DiffusionPTQ· Paper · Code · ScholarQuantizes diffusion models to reduce the cost of iterative generation.
-
PTQD: Accurate Post-Training Quantization for Diffusion Models
Yefei He, Luping Liu, Jing Liu, Weijia Wu, Hong Zhou, Bohan Zhuang
NeurIPS 2023 ·
DiffusionPTQError Handling· Paper · Code · ScholarTargets accurate diffusion generation through post-training quantization error handling.
-
ViDiT-Q: Efficient and Accurate Quantization of Diffusion Transformers for Image and Video Generation
Tianchen Zhao, Tongcheng Fang, Haofeng Huang, Rui Wan, Widyadewi Soedarmadji, Enshu Liu, Shiyao Li, Zinan Lin, Guohao Dai, Shengen Yan, Huazhong Yang, Xuefei Ning, Yu Wang
ICLR 2025 ·
Diffusion TransformerImage + VideoLow-Bit· Paper · Code · ScholarQuantizes diffusion transformers for both image and video generation.
-
SVDQuant: Absorbing Outliers by Low-Rank Component for 4-Bit Diffusion Models
Muyang Li, Yujun Lin, Zhekai Zhang, Tianle Cai, Xiuyu Li, Junxian Guo, Enze Xie, Chenlin Meng, Jun-Yan Zhu, Song Han
ICLR 2025 ·
Diffusion4-BitLow-Rank· Paper · Code · ScholarAbsorbs outliers into a low-rank component to support 4-bit diffusion models.
-
BinaryDM: Accurate Weight Binarization for Efficient Diffusion Models
Xingyu Zheng, Xianglong Liu, Haotong Qin, Xudong Ma, Mingyuan Zhang, Haojie Hao, Jiakai Wang, Zixiang Zhao, Jinyang Guo, Michele Magno
ICLR 2025 ·
DiffusionBinary Weights· Paper · Code · ScholarBinarizes diffusion model weights for efficient generation.
-
Q-VDiT: Towards Accurate Quantization and Distillation of Video-Generation Diffusion Transformers
Weilun Feng, Chuanguang Yang, Haotong Qin, Xiangqi Li, Yu Wang, Zhulin An, Libo Huang, Boyu Diao, Zixiang Zhao, Yongjun Xu, Michele Magno
ICML 2025 ·
Video DiffusionQuantizationDistillation· Paper · Code · ScholarCombines quantization and distillation for video-generation diffusion transformers.
-
S²Q-VDiT: Accurate Quantized Video Diffusion Transformer with Salient Data and Sparse Token Distillation
Weilun Feng, Haotong Qin, Chuanguang Yang, Xiangqi Li, Han Yang, Yuqi Li, Zhulin An, Libo Huang, Michele Magno, Yongjun Xu
NeurIPS 2025 ·
Video DiffusionQuantizationDistillation· Paper · Code · ScholarUses salient data and sparse-token distillation to improve quantized video diffusion transformers.
-
QuantSparse: Comprehensively Compressing Video Diffusion Transformer with Model Quantization and Attention Sparsification
Weilun Feng, Chuanguang Yang, Haotong Qin, Mingqiang Wu, Yuqi Li, Xiangqi Li, Zhulin An, Libo Huang, Yulun Zhang, Michele Magno, Yongjun Xu
ICLR 2026 ·
Video DiffusionQuantizationAttention Sparsity· Paper · Code · ScholarCombines model quantization and attention sparsification to compress video diffusion transformers.
Multimodal and State Space Models
Vision-language models and selective state space models introduce quantization sensitivities beyond those of language-only transformers.
-
Q-VLM: Post-training Quantization for Large Vision-Language Models
Changyuan Wang, Ziwei Wang, Xiuwei Xu, Yansong Tang, Jie Zhou, Jiwen Lu
NeurIPS 2024 ·
VLMPTQCross-Layer Dependency· Paper · Code · ScholarUses cross-layer dependencies to guide block partitioning and quantization of vision-language models.
-
Quamba2: A Robust and Scalable Post-training Quantization Framework for Selective State Space Models
Hung-Yueh Chiang, Chi-Chih Chang, Natalia Frumkin, Kai-Chiang Wu, Mohamed S. Abdelfattah, Diana Marculescu
ICML 2025 ·
MambaState Space ModelsPTQW4A8 / W8A8· Paper · Code · ScholarUses channel clustering and state-group quantization to accommodate the sensitivity of Mamba’s selective state-space computations.
Vision, Edge and Hardware
Vision methods and deployment systems connect quantizer design to integer kernels, memory movement and hardware costs.
-
FINN: A Framework for Fast, Scalable Binarized Neural Network Inference
Yaman Umuroglu, Nicholas J. Fraser, Giulio Gambardella, Michaela Blott, Philip Leong, Magnus Jahre, Kees Vissers
FPGA 2017 ·
Binary NetworksFPGAInference· Paper · Code · ScholarProvides a framework for fast, scalable binarized neural network inference on FPGA hardware.
-
HAQ: Hardware-Aware Automated Quantization with Mixed Precision
Kuan Wang, Zhijian Liu, Yujun Lin, Ji Lin, Song Han
CVPR 2019 ·
CNNMixed PrecisionHardware-Aware· Paper · Code · ScholarAutomates mixed-precision quantization with hardware deployment costs in view.
-
BiPointNet: Binary Neural Network for Point Clouds
Haotong Qin, Zhongang Cai, Mingyuan Zhang, Yifu Ding, Haiyu Zhao, Shuai Yi, Xianglong Liu, Hao Su
ICLR 2021 ·
Point CloudsBinaryQAT1-Bit· Paper · Code · ScholarUses entropy-maximizing aggregation and layer-wise scale recovery to address feature homogenization and scale distortion in binary point-cloud networks.
-
PTQ4ViT: Post-Training Quantization for Vision Transformers with Twin Uniform Quantization
Zhihang Yuan, Chenhao Xue, Yiqi Chen, Qiang Wu, Guangyu Sun
ECCV 2022 ·
Vision TransformerPTQ· Paper · Code · ScholarUses twin uniform quantization to support post-training compression of vision transformers.
-
QuantSR: Accurate Low-bit Quantization for Efficient Image Super-Resolution
Haotong Qin, Yulun Zhang, Yifu Ding, Yifan Liu, Xianglong Liu, Martin Danelljan, Fisher Yu
NeurIPS 2023 ·
Super-ResolutionQAT2–4 Bit· Paper · Code · ScholarCombines a redistribution-driven learnable quantizer with a depth-dynamic architecture for accurate low-bit image super-resolution.
-
LUT-GEMM: Quantized Matrix Multiplication based on LUTs for Efficient Inference in Large-Scale Generative Language Models
Gunho Park, Baeseong Park, Minsub Kim, Sungjae Lee, Jeonghoon Kim, Beomseok Kwon, Se Jung Kwon, Byeongwook Kim, Youngjoo Lee, Dongsoo Lee
ICLR 2024 ·
LLMQuantized Matrix MultiplicationLookup Tables· Paper · ScholarUses lookup tables for efficient quantized matrix multiplication in generative language models.
-
Quant-LLM: Accelerating the Serving of Large Language Models via FP6-Centric Algorithm-System Co-Design on Modern GPUs
Haojun Xia, Zhen Zheng, Xiaoxia Wu, Shiyang Chen, Zhewei Yao, Stephen Youn, Arash Bakhtiari, Michael Wyatt, Donglin Zhuang, Zhongzhu Zhou, Olatunji Ruwase, Yuxiong He, Shuaiwen Leon Song
USENIX ATC 2024 ·
LLMFP6GPU Kernels· Paper · Code · ScholarUses TC-FPx kernels to support non-power-of-two weight formats efficiently on GPUs; the codebase is also known as FP6-LLM.
-
QServe: W4A8KV4 Quantization and System Co-design for Efficient LLM Serving
Yujun Lin, Haotian Tang, Shang Yang, Zhekai Zhang, Guangxuan Xiao, Chuang Gan, Song Han
MLSys 2025 ·
LLMW4A8KV4GPU Serving· Paper · Code · ScholarCo-designs progressive quantization, attention and GPU kernels to turn reduced precision into serving throughput.
Floating-Point and Microscaling Formats
Low-bit floating-point and shared-scale formats complement integer quantization. Format design and model calibration are separate choices.
-
FP8 Formats for Deep Learning
Paulius Micikevicius, Dusan Stosic, Neil Burgess, Marius Cornea, Pradeep Dubey, Richard Grisenthwaite, Sangwon Ha, Alexander Heinecke, Patrick Judd, John Kamalu, Naveen Mellempudi, Stuart Oberman, Mohammad Shoeybi, Michael Siu, Hao Wu
arXiv 2022 ·
FP8E4M3 / E5M2Training + Inference· Paper · ScholarDefines complementary FP8 encodings and evaluates their use in neural network training and inference.
-
Microscaling Data Formats for Deep Learning
Bita Darvish Rouhani, Ritchie Zhao, Ankit More, Mathew Hall, Alireza Khodamoradi, Summer Deng, Dhruv Choudhary, Marius Cornea, Eric Dellinger, Kristof Denolf, Stosic Dusan, Venmugil Elango, Maximilian Golub, Alexander Heinecke, Phil James-Roxby, Dharmesh Jani, Gaurav Kolhe, Martin Langhammer, Ada Li, Levi Melnick, Maral Mesmakhosroshahi, Andres Rodriguez, Michael Schulte, Rasoul Shafipour, Lei Shao, Michael Siu, Pradeep Dubey, Paulius Micikevicius, Maxim Naumov, Colin Verrilli, Ralph Wittig, Doug Burger, Eric Chung
arXiv 2023 ·
MX FormatsBlock ScalingTraining + Inference· Paper · Code · ScholarCombines shared block scales with narrow element formats to balance numerical range and hardware efficiency.
-
LLM-FP4: 4-Bit Floating-Point Quantized Transformers
Shih-yang Liu, Zechun Liu, Xijie Huang, Pingcheng Dong, Kwang-Ting Cheng
EMNLP 2023 ·
LLMPTQFP4· Paper · Code · ScholarSearches exponent configurations and quantization parameters to handle weight and activation range differences in 4-bit floating point.
Low-Precision Training and States
Quantization can reduce saved activations, optimizer states, gradient communication or training arithmetic; each targets a different part of the training cost.
-
QSGD: Communication-Efficient SGD via Gradient Quantization and Encoding
Dan Alistarh, Demjan Grubic, Jerry Li, Ryota Tomioka, Milan Vojnovic
NeurIPS 2017 ·
TrainingGradientsCommunication· Paper · ScholarUses randomized gradient quantization with convergence guarantees to trade communication bandwidth against estimator variance.
-
ActNN: Reducing Training Memory Footprint via 2-Bit Activation Compressed Training
Jianfei Chen, Lianmin Zheng, Zhewei Yao, Dequan Wang, Ion Stoica, Michael Mahoney, Joseph Gonzalez
ICML 2021 ·
TrainingActivations2-Bit· Paper · Code · ScholarCompresses saved activations to reduce the memory footprint of neural network training.
-
8-bit Optimizers via Block-wise Quantization
Tim Dettmers, Mike Lewis, Sam Shleifer, Luke Zettlemoyer
ICLR 2022 ·
TrainingOptimizer States8-Bit· Paper · Code · ScholarUses block-wise quantization to reduce optimizer-state memory.
-
SDP4Bit: Toward 4-bit Communication Quantization in Sharded Data Parallelism for LLM Training
Jinda Jia, Cong Xie, Hanlin Lu, Daoce Wang, Hao Feng, Chengming Zhang, Baixi Sun, Haibin Lin, Zhi Zhang, Xin Liu, Dingwen Tao
NeurIPS 2024 ·
LLM TrainingCommunication4-Bit· Paper · Code · ScholarTargets 4-bit communication quantization in sharded data-parallel LLM training.
-
Optimizing Large Language Model Training Using FP4 Quantization
Ruizhe Wang, Yeyun Gong, Xiao Liu, Guoshuai Zhao, Ziyue Yang, Baining Guo, Zhengjun Zha, Peng Cheng
ICML 2025 ·
LLM TrainingFP4Gradient Estimation· Paper · ScholarCombines differentiable quantization estimation with outlier handling to stabilize FP4 LLM training.
Benchmarks
Choose by evaluation scope: deployment reproducibility, binary networks, LLM capabilities or robustness. Expand a resource below for authors, figures and citation details.
| Resource | What it covers |
|---|---|
| MQBench: Towards Reproducible and Deployable Model Quantization Benchmark | |
| NeurIPS 2021 Datasets and Benchmarks | |
| Code · Scholar |
QAT + deployment |
| Compares quantization algorithms under reproducible settings and hardware backend constraints. | |
| BiBench: Benchmarking and Analyzing Network Binarization | |
| ICML 2023 | |
| Code · Scholar |
Binary networks |
| Compares binarization methods across tasks, architectures and deployment settings. | |
| Evaluating Quantized Large Language Models | |
| ICML 2024 | |
| Code · Scholar |
Weights, activations + KV cache |
| Evaluates 11 model families on basic NLP, emergent abilities, trustworthiness, dialogue and long-context tasks. | |
| LLMC: Benchmarking Large Language Model Quantization with a Versatile Compression Toolkit | |
| EMNLP 2024 Industry Track | |
| Code · Scholar |
LLM toolkit |
| Compares calibration data, method pipelines and quantization configurations; the toolkit is now LightCompress. | |
| An empirical study of LLaMA3 quantization: from LLMs to MLLMs | |
| Visual Intelligence 2024 | |
| Code · Scholar |
LLMs + multimodal |
| Examines low-bit behavior across LLaMA3 language and multimodal models. | |
| An Empirical Study of Qwen3 Quantization | |
| Visual Intelligence 2026 | |
| Code · Scholar |
Dense + MoE LLMs |
| Studies quantization across Qwen3 model sizes, architectures and reasoning settings. | |
| RobustMQ: Benchmarking Robustness of Quantized Models | |
| Visual Intelligence 2023 | |
| Scholar | Model robustness |
| Tests quantized models beyond clean accuracy, including robustness under input perturbations. |
MQBench · Authors and BibTeX
Yuhang Li, Mingzhu Shen, Jian Ma, Yan Ren, Mingxin Zhao, Qi Zhang, Ruihao Gong, Fengwei Yu, Junjie Yan
@inproceedings{li2021mqbench,
  title={MQBench: Towards Reproducible and Deployable Model Quantization Benchmark},
  author={Li, Yuhang and Shen, Mingzhu and Ma, Jian and Ren, Yan and Zhao, Mingxin and Zhang, Qi and Gong, Ruihao and Yu, Fengwei and Yan, Junjie},
  booktitle={NeurIPS Datasets and Benchmarks},
  year={2021}
}
BiBench · Authors, overview and BibTeX
Haotong Qin, Mingyuan Zhang, Yifu Ding, Aoyu Li, Zhongang Cai, Ziwei Liu, Fisher Yu, Xianglong Liu
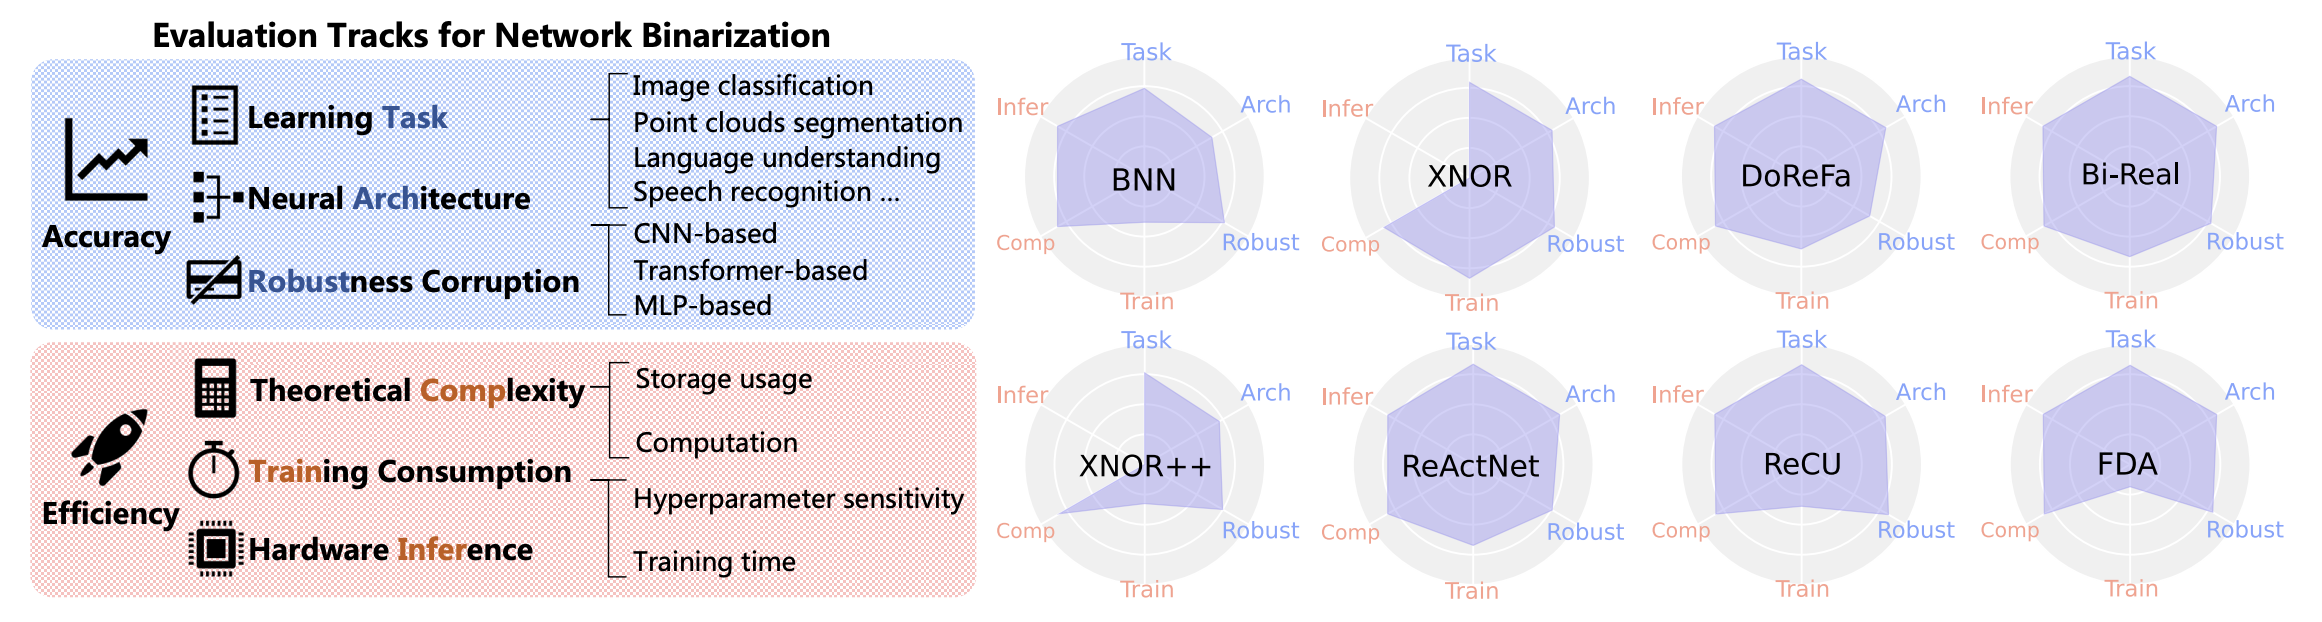
@inproceedings{qin2023bibench,
  title={BiBench: Benchmarking and Analyzing Network Binarization},
  author={Qin, Haotong and Zhang, Mingyuan and Ding, Yifu and Li, Aoyu and Cai, Zhongang and Liu, Ziwei and Yu, Fisher and Liu, Xianglong},
  booktitle={International Conference on Machine Learning (ICML)},
  year={2023}
}
QLLM-Eval · Authors and BibTeX
Shiyao Li, Xuefei Ning, Luning Wang, Tengxuan Liu, Xiangsheng Shi, Shengen Yan, Guohao Dai, Huazhong Yang, Yu Wang
@inproceedings{li2024evaluating,
  title={Evaluating Quantized Large Language Models},
  author={Li, Shiyao and Ning, Xuefei and Wang, Luning and Liu, Tengxuan and Shi, Xiangsheng and Yan, Shengen and Dai, Guohao and Yang, Huazhong and Wang, Yu},
  booktitle={International Conference on Machine Learning},
  year={2024},
  url={https://proceedings.mlr.press/v235/li24bb.html}
}
LLMC · Authors, overview and BibTeX
Ruihao Gong, Yang Yong, Shiqiao Gu, Yushi Huang, Chengtao Lv, Yunchen Zhang, Dacheng Tao, Xianglong Liu
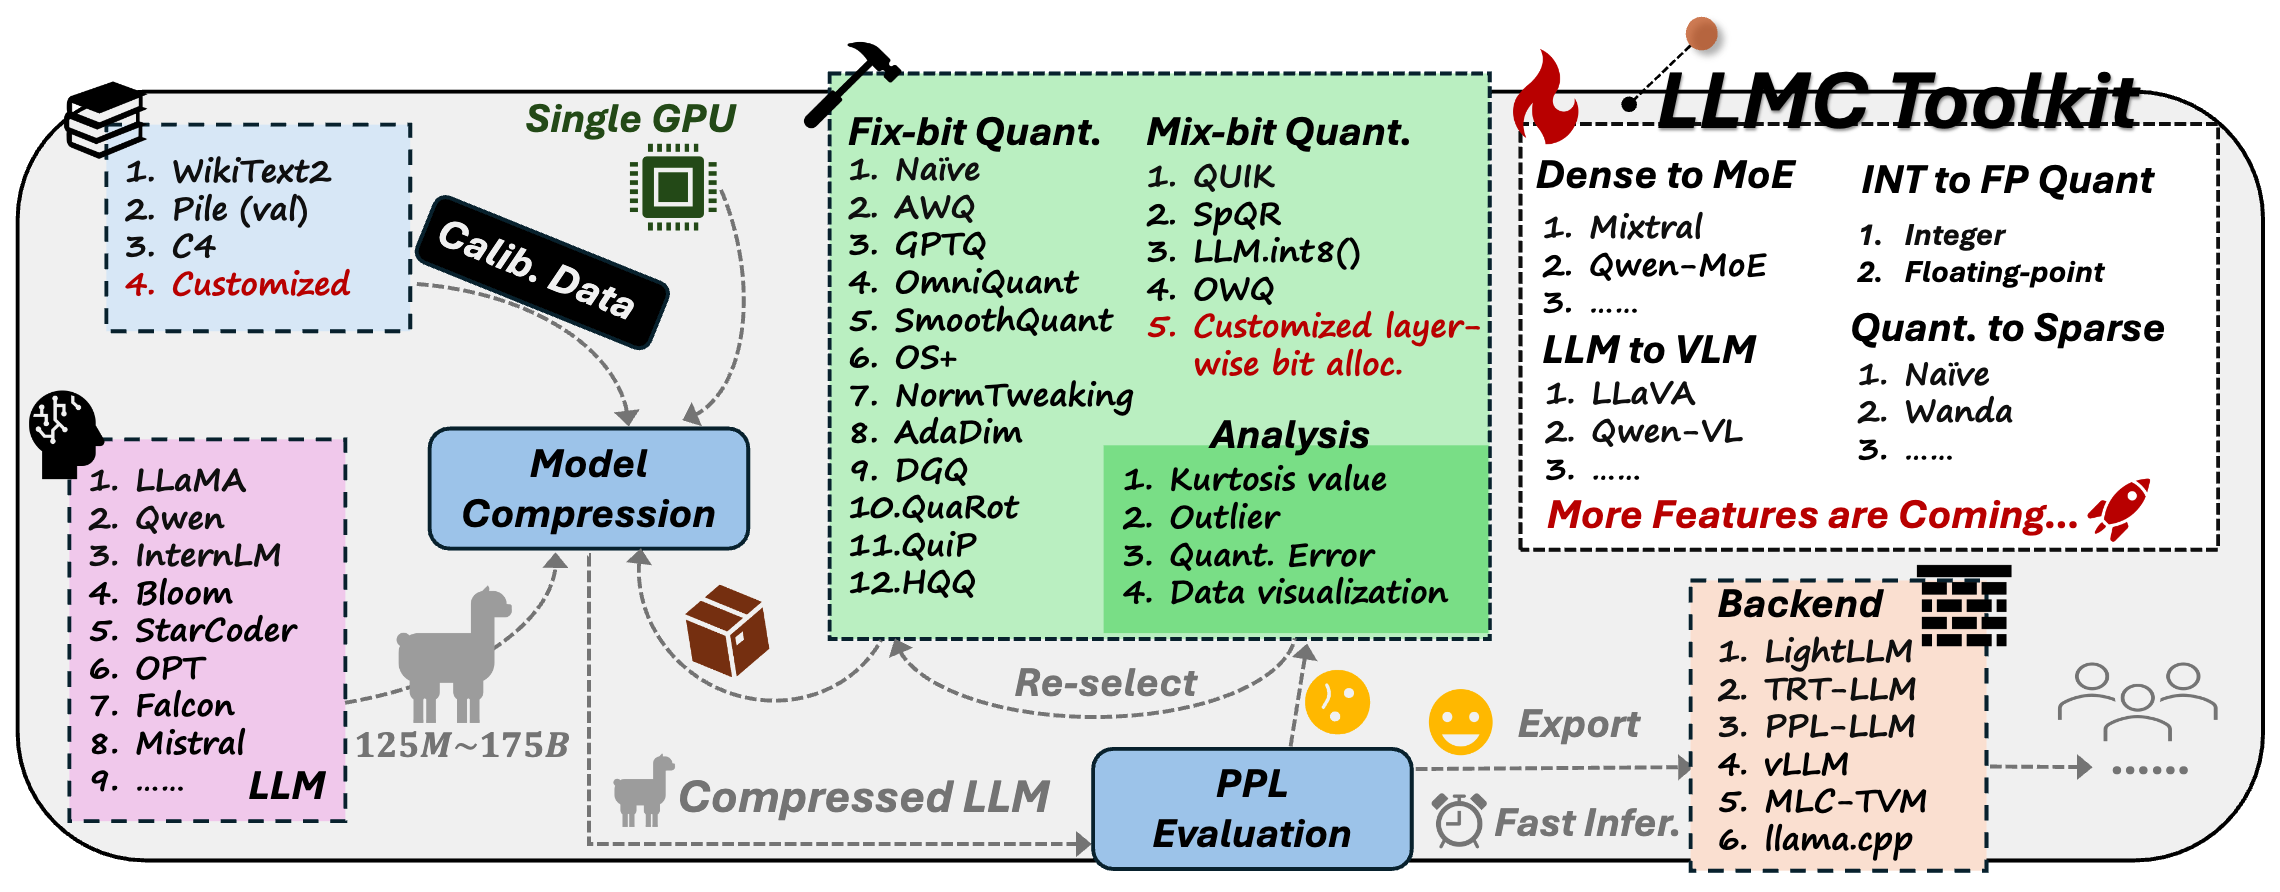
@inproceedings{gong2024llmc,
  title={Llmc: Benchmarking large language model quantization with a versatile compression toolkit},
  author={Gong, Ruihao and Yong, Yang and Gu, Shiqiao and Huang, Yushi and Lv, Chengtao and Zhang, Yunchen and Tao, Dacheng and Liu, Xianglong},
  booktitle={Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing: Industry Track},
  pages={132--152},
  year={2024}
}
LLaMA3 study · Authors, overview and BibTeX
Wei Huang, Xingyu Zheng, Xudong Ma, Haotong Qin, Chengtao Lv, Hong Chen, Jie Luo, Xiaojuan Qi, Xianglong Liu, Michele Magno
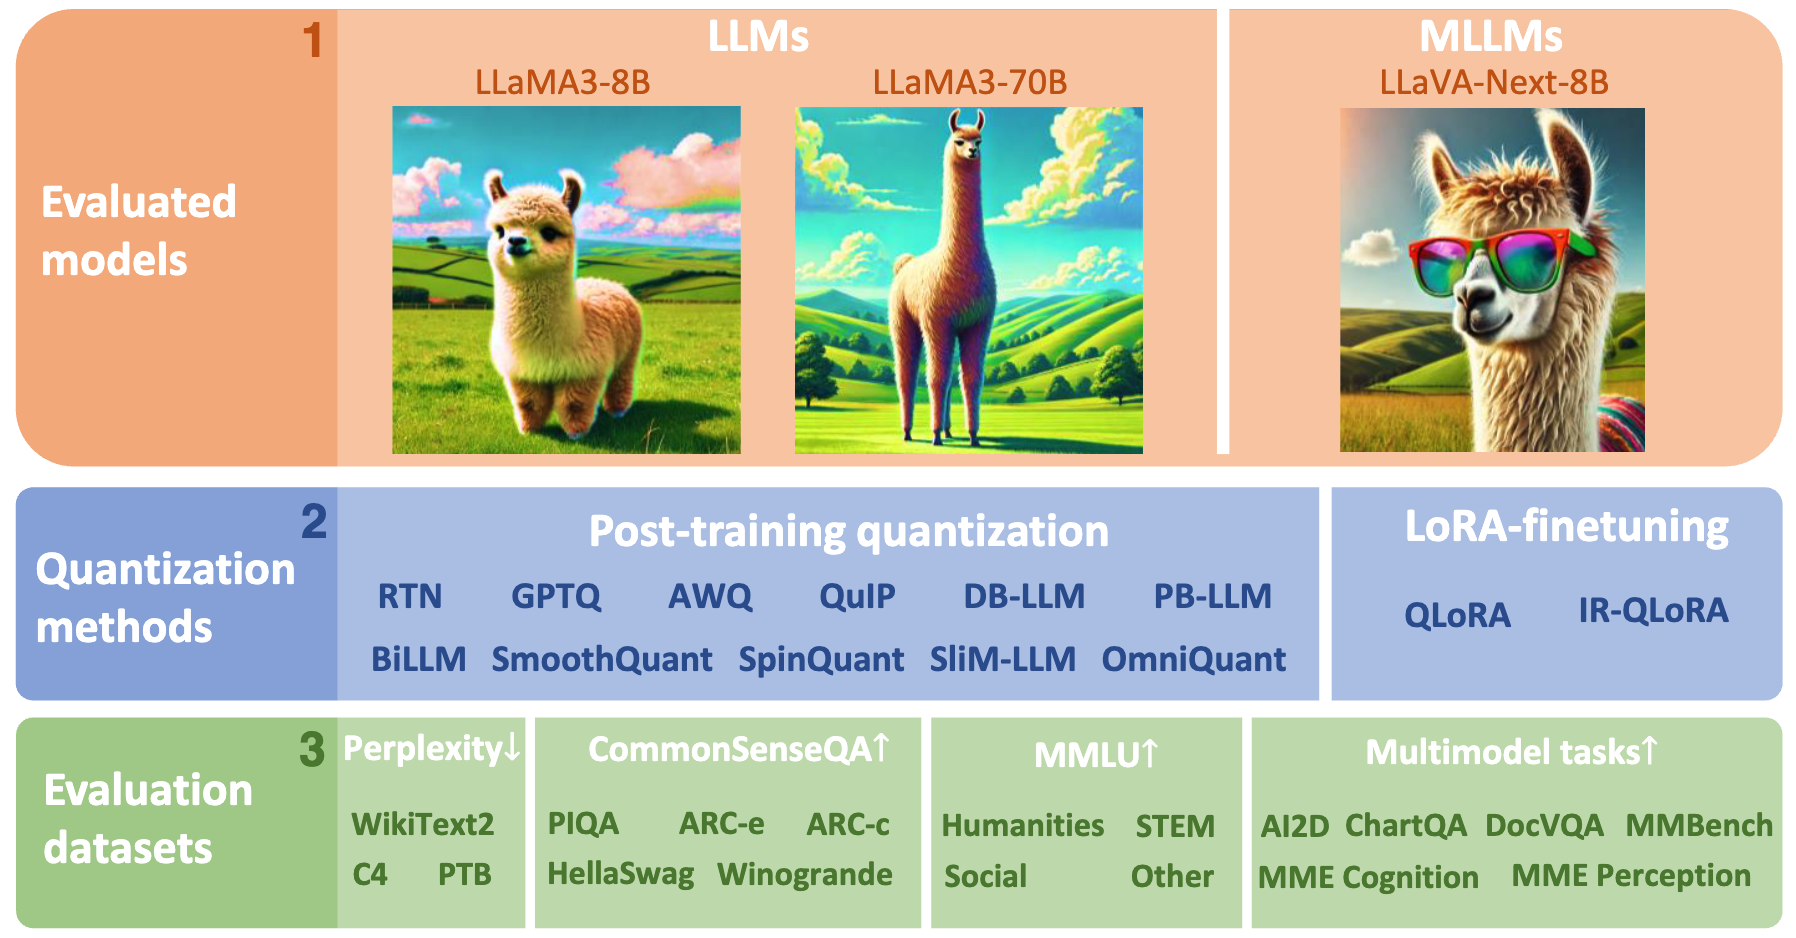
@article{huang2024empirical,
  title={An empirical study of llama3 quantization: From llms to mllms},
  author={Huang, Wei and Zheng, Xingyu and Ma, Xudong and Qin, Haotong and Lv, Chengtao and Chen, Hong and Luo, Jie and Qi, Xiaojuan and Liu, Xianglong and Magno, Michele},
  journal={Visual Intelligence},
  volume={2},
  number={1},
  pages={36},
  year={2024},
  publisher={Springer}
}
Qwen3 study · Authors, overview and BibTeX
Xingyu Zheng, Yuye Li, Haoran Chu, Yue Feng, Xudong Ma, Zining Wang, Jie Luo, Jinyang Guo, Haotong Qin, Michele Magno, Xianglong Liu
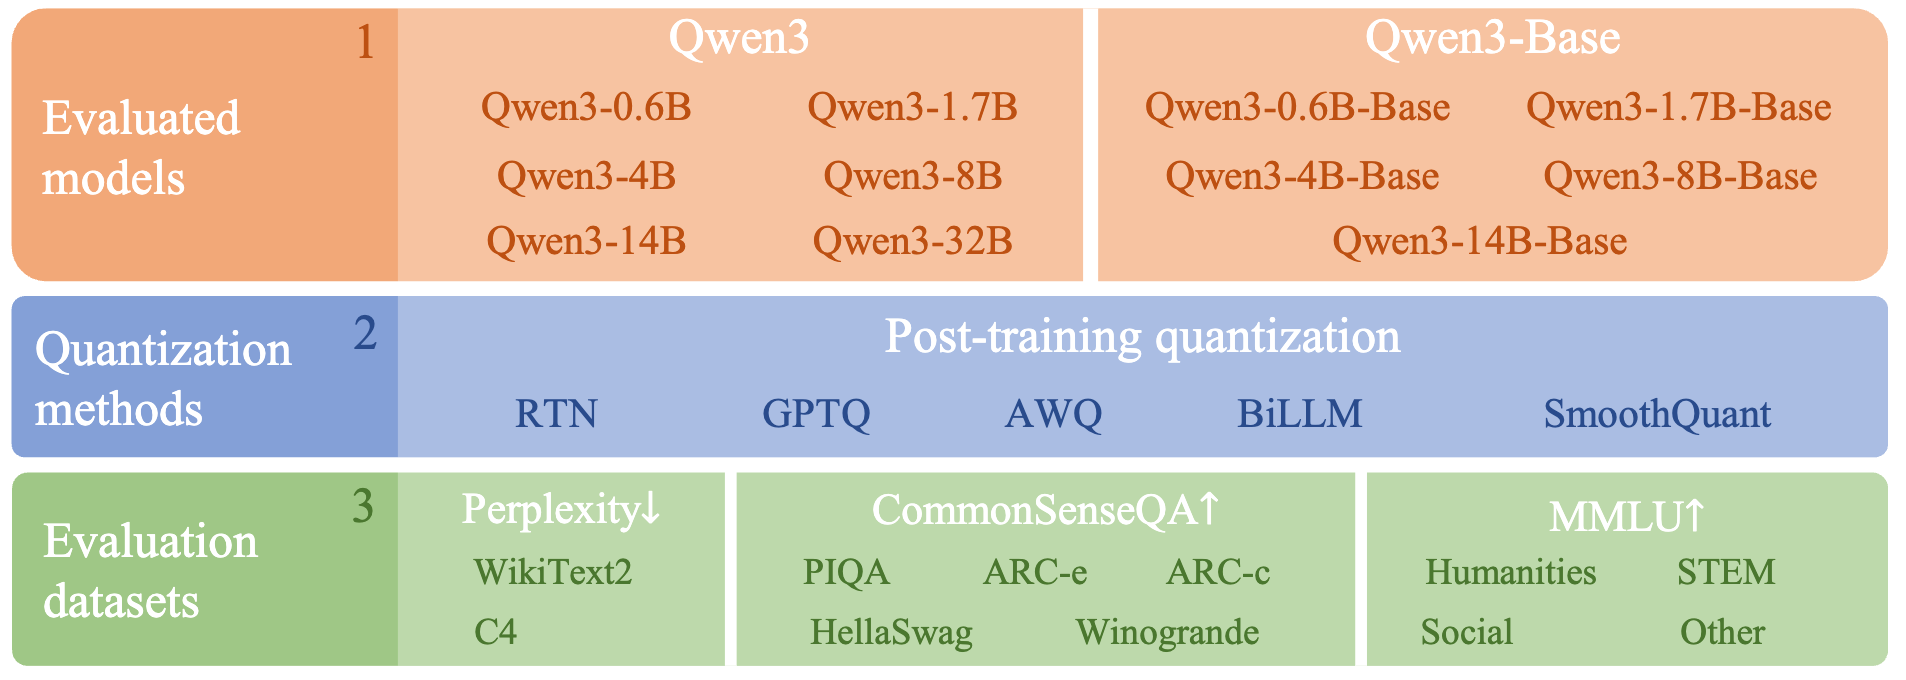
@article{zheng2026empirical,
  title={An empirical study of Qwen3 quantization},
  author={Zheng, Xingyu and Li, Yuye and Chu, Haoran and Feng, Yue and Ma, Xudong and Wang, Zining and Luo, Jie and Guo, Jinyang and Qin, Haotong and Magno, Michele and Liu, Xianglong},
  journal={Visual Intelligence},
  volume={4},
  pages={11},
  year={2026},
  doi={10.1007/s44267-026-00114-4}
}
RobustMQ · Authors, overview and BibTeX
Yisong Xiao, Aishan Liu, Tianyuan Zhang, Haotong Qin, Jinyang Guo, Xianglong Liu
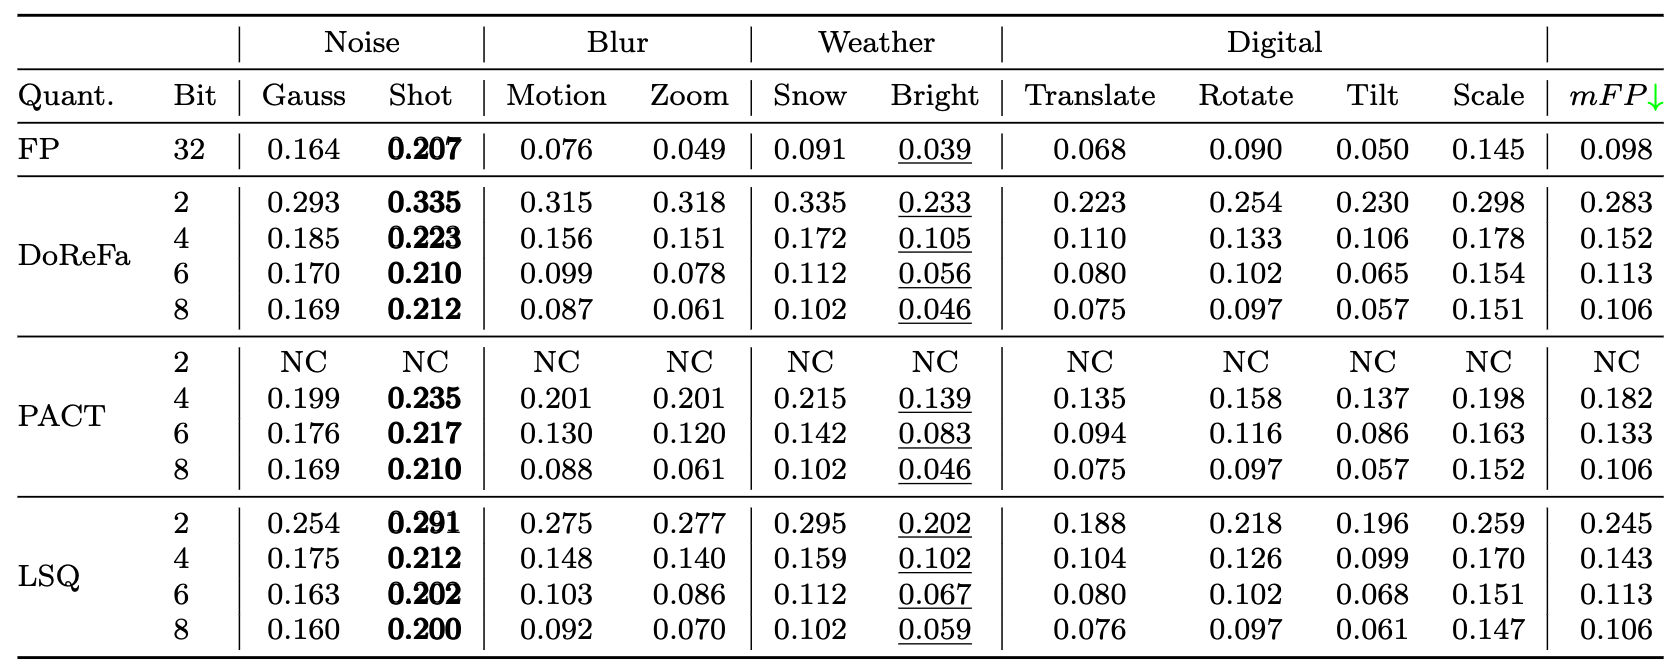
@article{xiao2023robustmq,
  title={Robustmq: benchmarking robustness of quantized models},
  author={Xiao, Yisong and Liu, Aishan and Zhang, Tianyuan and Qin, Haotong and Guo, Jinyang and Liu, Xianglong},
  journal={Visual Intelligence},
  volume={1},
  number={1},
  pages={30},
  year={2023},
  publisher={Springer}
}
Survey Papers
Start with the white paper for practical PTQ/QAT, then choose a survey for broader context or a specific model family. Figures and citation details are available below.
| Resource | What it covers |
|---|---|
| A White Paper on Neural Network Quantization | |
| arXiv 2021 | |
| Scholar | Practical PTQ + QAT |
| Explains quantizer design, common failure modes and practical post-training and quantization-aware training workflows. | |
| A Survey of Quantization Methods for Efficient Neural Network Inference | |
| arXiv 2021 | |
| Scholar | Foundations + taxonomy |
| Reviews quantization design choices, mixed precision and the trade-offs between model accuracy and efficient inference. | |
| Binary Neural Networks: A Survey | |
| Pattern Recognition 2020 | |
| Scholar | Binary networks |
| Surveys binary network representations, training methods and applications. | |
| A Survey of Low-bit Large Language Models: Basics, Systems, and Algorithms | |
| Neural Networks 2025 | |
| Scholar | LLM algorithms + systems |
| Connects low-bit LLM algorithms with numerical formats and inference systems. | |
| Low-bit Model Quantization for Deep Neural Networks: A Survey | |
| arXiv 2025 | |
| Scholar | Broad low-bit methods |
| Maps low-bit quantization methods across neural network architectures and applications. |
Quantization white paper · Authors and BibTeX
Markus Nagel, Marios Fournarakis, Rana Ali Amjad, Yelysei Bondarenko, Mart van Baalen, Tijmen Blankevoort
@article{nagel2021white,
  title={A White Paper on Neural Network Quantization},
  author={Nagel, Markus and Fournarakis, Marios and Amjad, Rana Ali and Bondarenko, Yelysei and van Baalen, Mart and Blankevoort, Tijmen},
  journal={arXiv preprint arXiv:2106.08295},
  year={2021}
}
Quantization methods survey · Authors and BibTeX
Amir Gholami, Sehoon Kim, Zhen Dong, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer
@article{gholami2021survey,
  title={A Survey of Quantization Methods for Efficient Neural Network Inference},
  author={Gholami, Amir and Kim, Sehoon and Dong, Zhen and Yao, Zhewei and Mahoney, Michael W. and Keutzer, Kurt},
  journal={arXiv preprint arXiv:2103.13630},
  year={2021}
}
Binary networks survey · Authors, overview and BibTeX
Haotong Qin, Ruihao Gong, Xianglong Liu, Xiao Bai, Jingkuan Song, Nicu Sebe
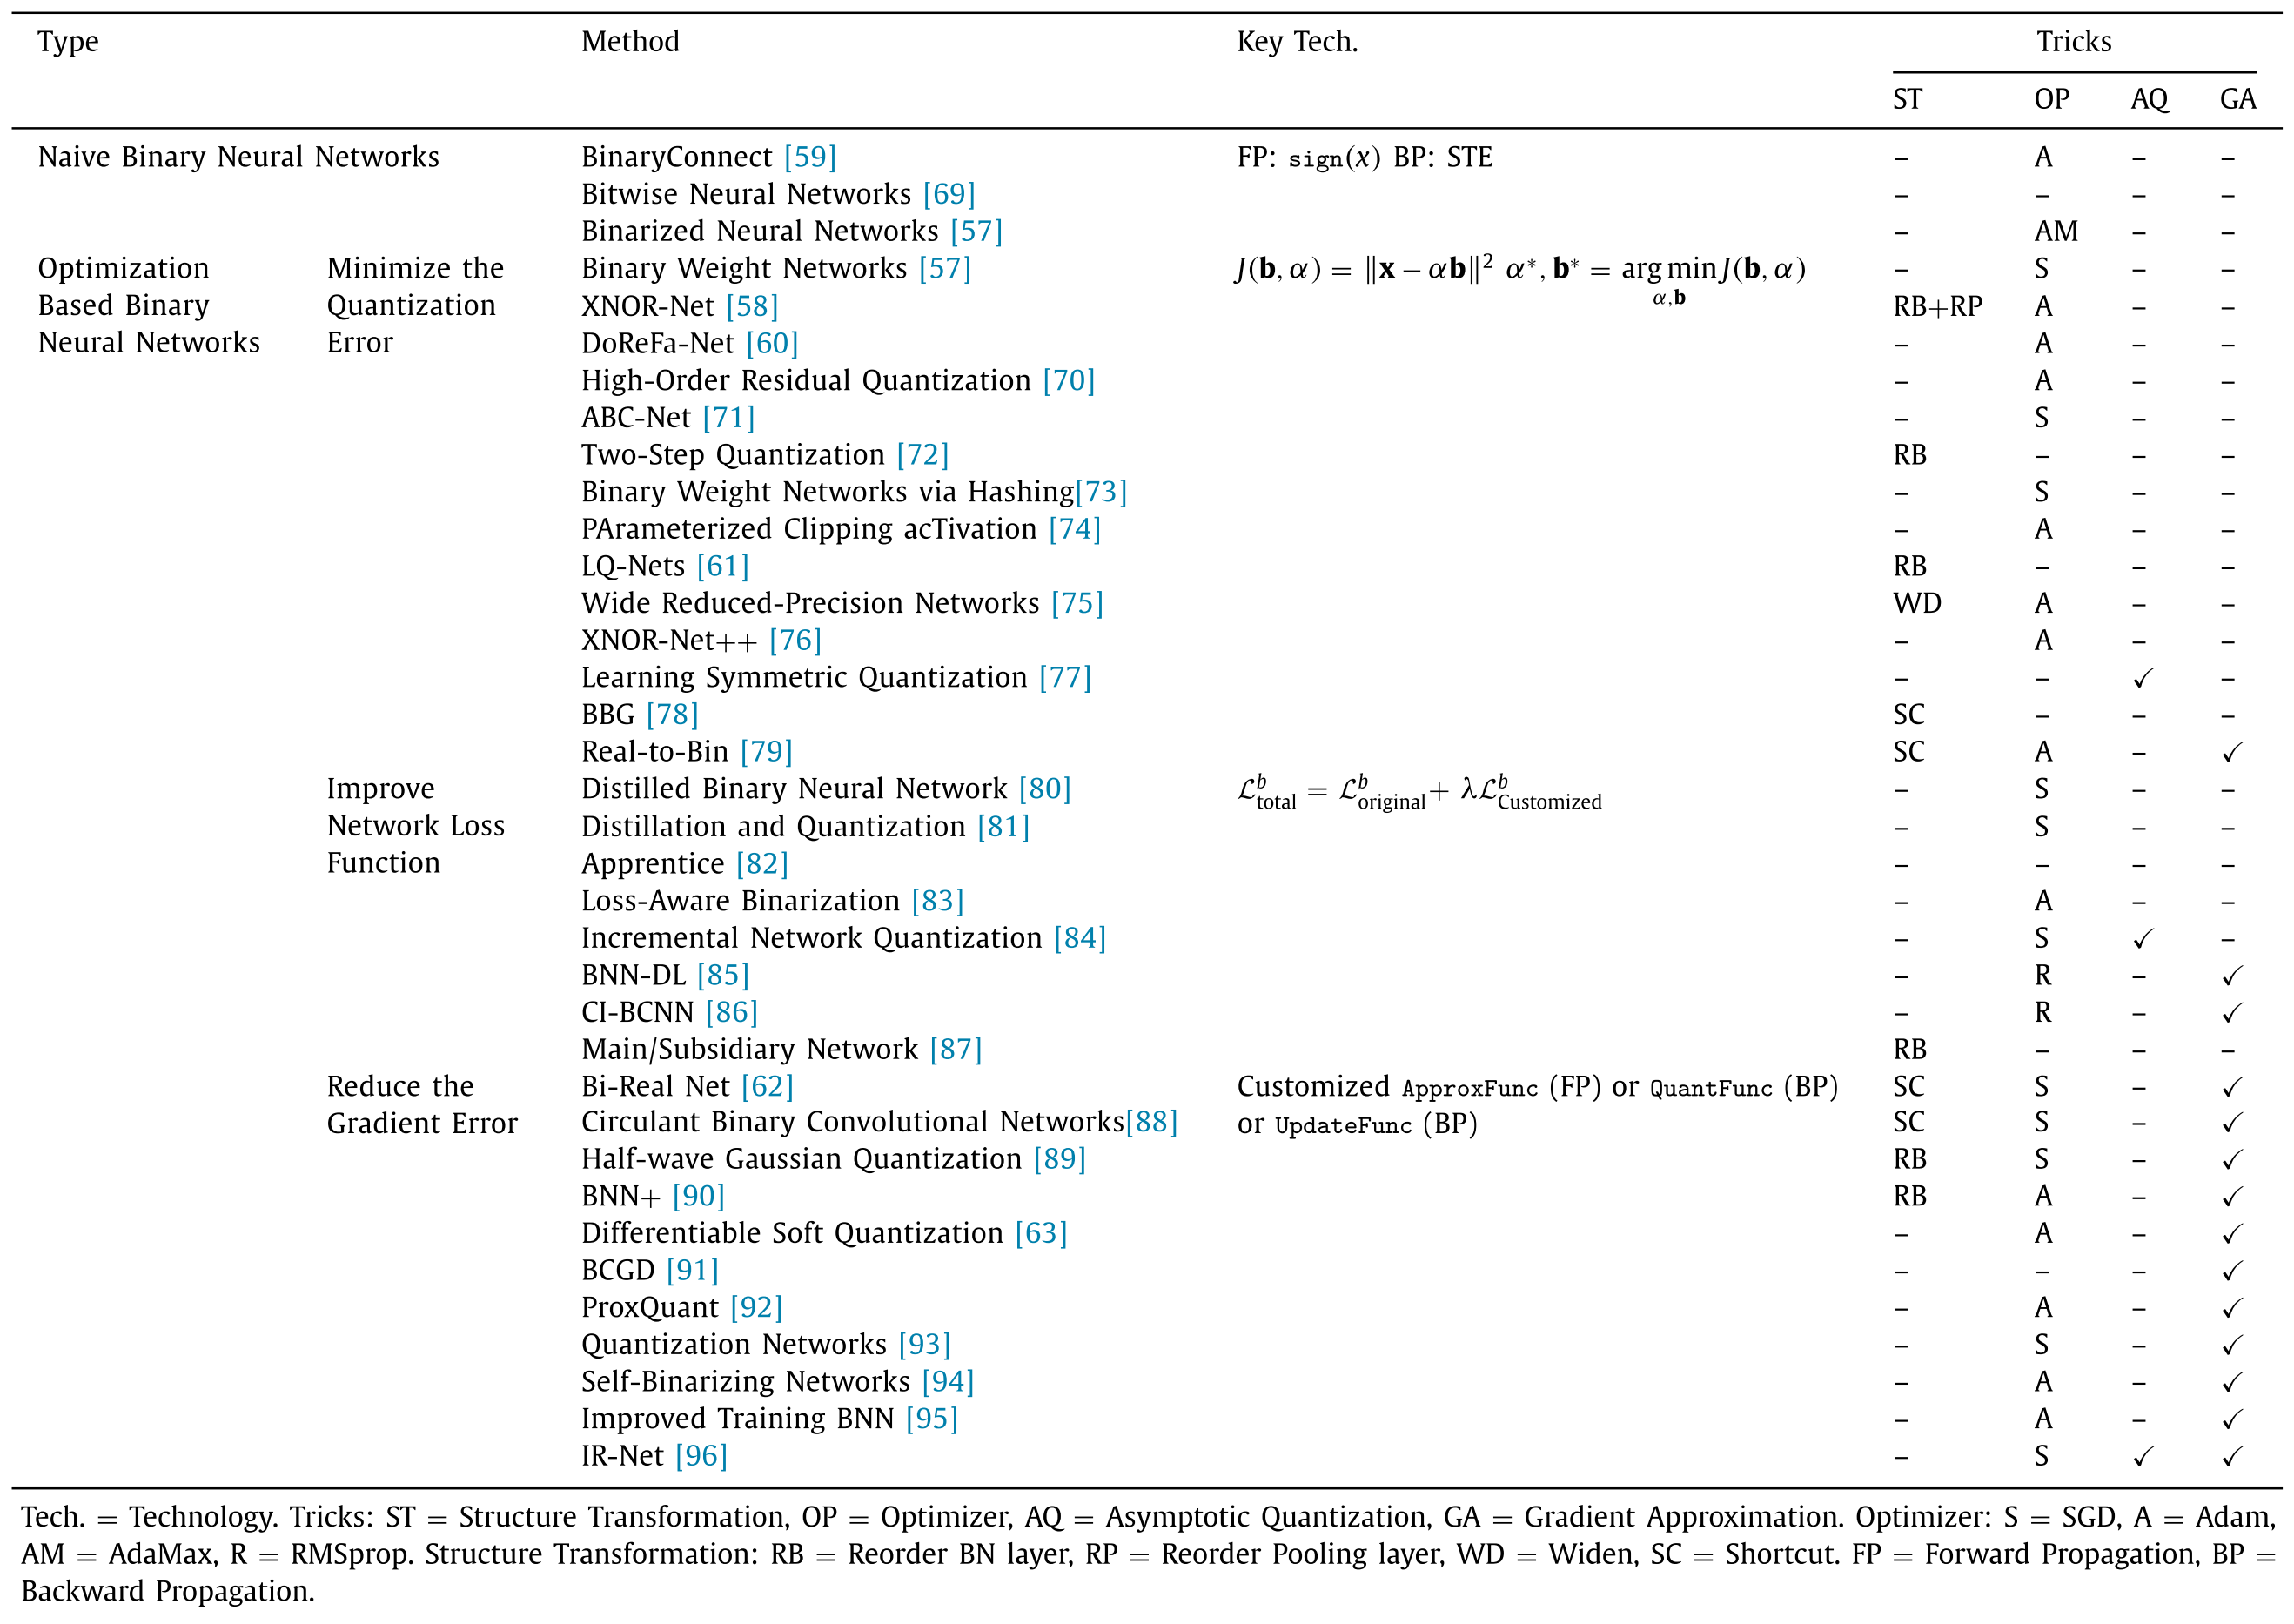
@article{Qin:pr20_bnn_survey,
    title = "Binary neural networks: A survey",
    author = "Haotong Qin and Ruihao Gong and Xianglong Liu and Xiao Bai and Jingkuan Song and Nicu Sebe",
    journal = "Pattern Recognition",
    volume = "105",
    pages = "107281",
    year = "2020"
}
Low-bit LLM survey · Authors, overview and BibTeX
Ruihao Gong, Yifu Ding, Zining Wang, Chengtao Lv, Xingyu Zheng, Jinyang Du, Yang Yong, Shiqiao Gu, Haotong Qin, Jinyang Guo, Dahua Lin, Michele Magno, Xianglong Liu
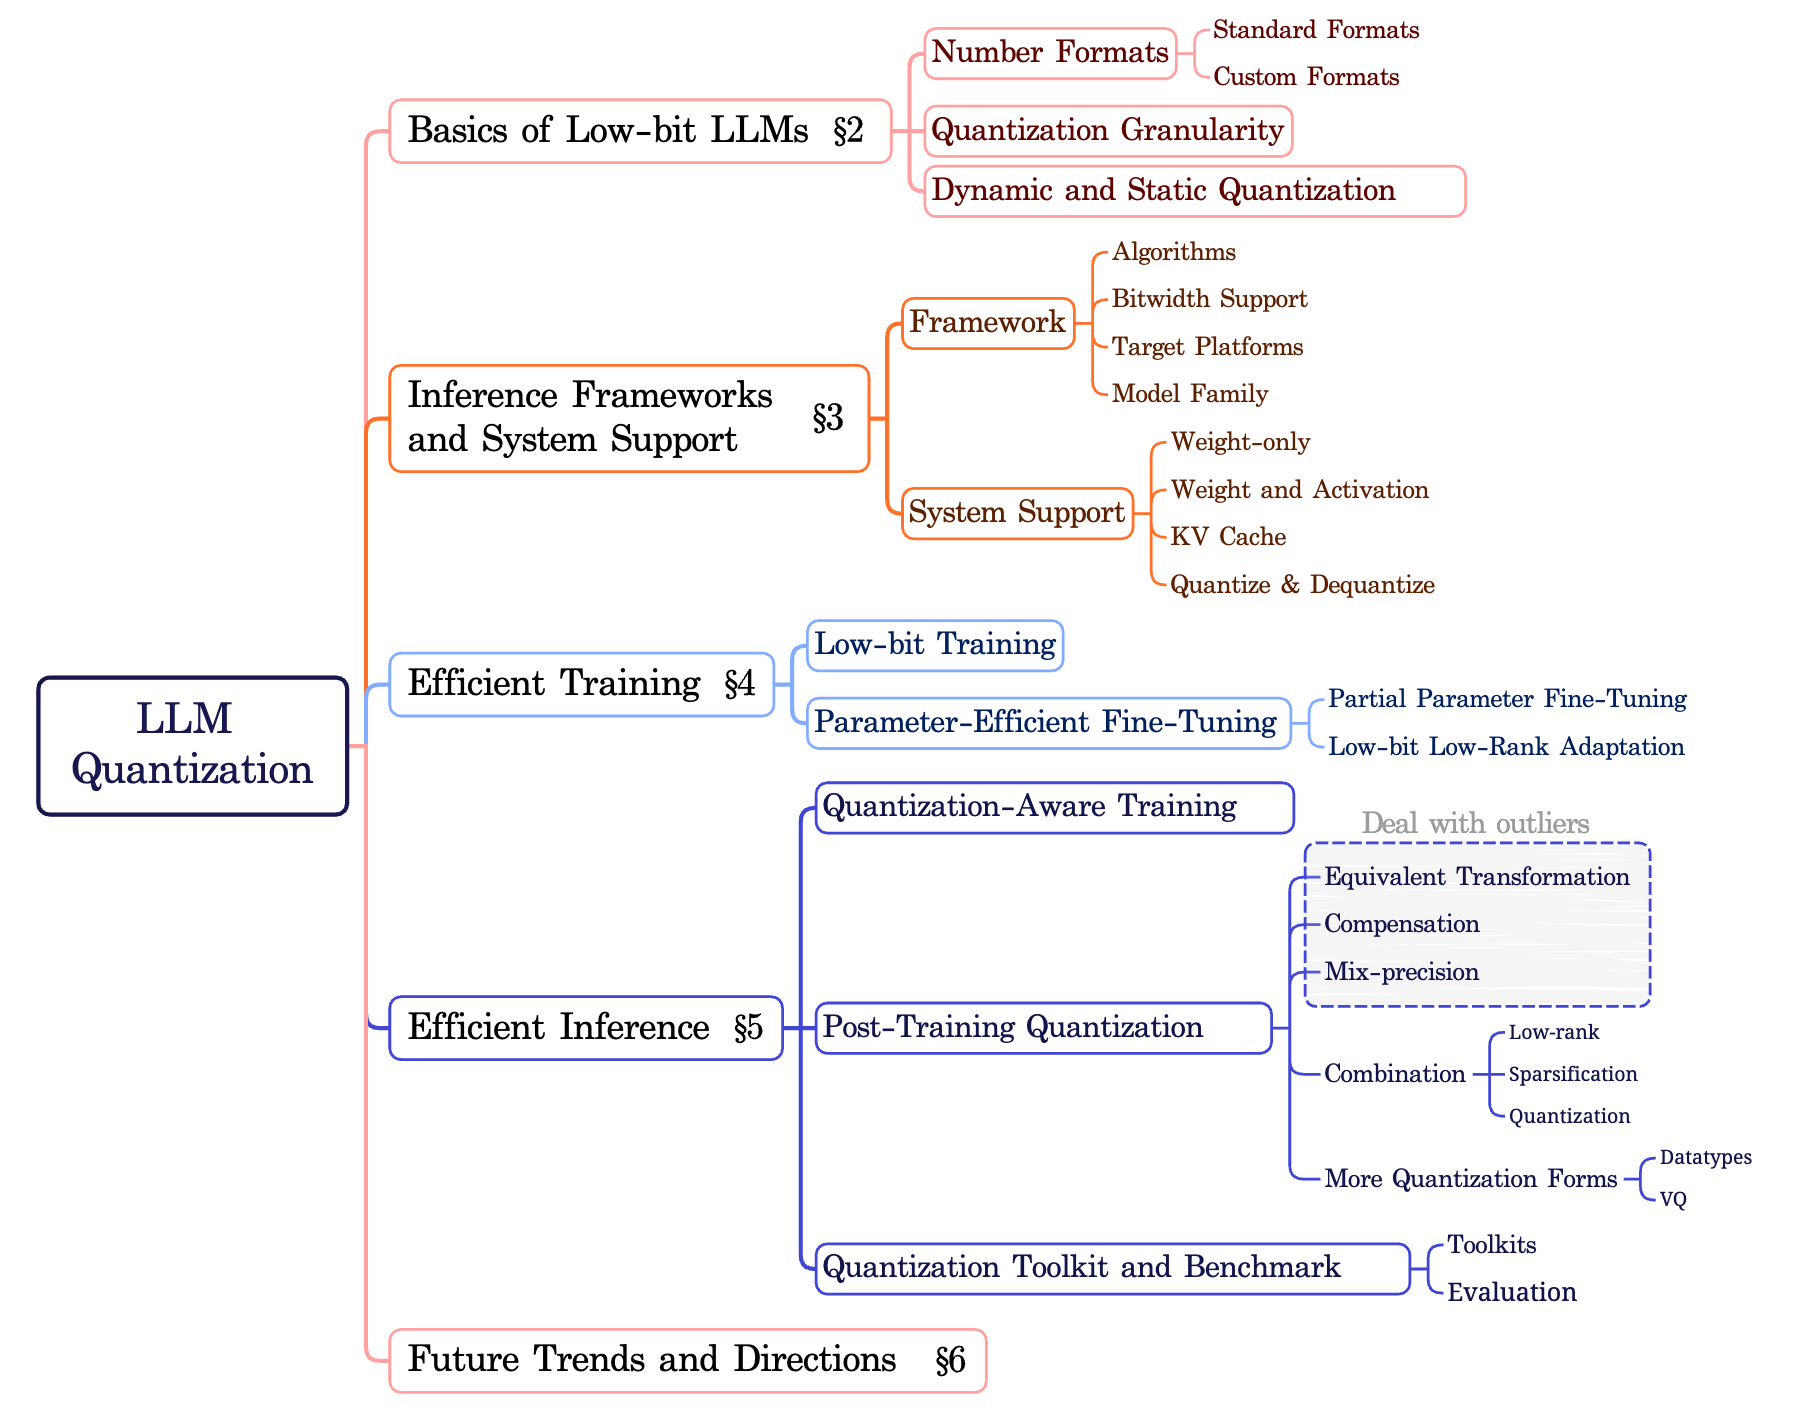
@article{gong2025survey,
  title={A survey of low-bit large language models: Basics, systems, and algorithms},
  author={Gong, Ruihao and Ding, Yifu and Wang, Zining and Lv, Chengtao and Zheng, Xingyu and Du, Jinyang and Yong, Yang and Gu, Shiqiao and Qin, Haotong and Guo, Jinyang and Lin, Dahua and Magno, Michele and Liu, Xianglong},
  journal={Neural Networks},
  pages={107856},
  year={2025}
}
Low-bit model survey · Authors, overview and BibTeX
Kai Liu, Qian Zheng, Kaiwen Tao, Zhiteng Li, Haotong Qin, Wenbo Li, Yong Guo, Xianglong Liu, Linghe Kong, Guihai Chen, Yulun Zhang, Xiaokang Yang

@article{liu2025low,
  title={Low-bit Model Quantization for Deep Neural Networks: A Survey},
  author={Liu, Kai and Zheng, Qian and Tao, Kaiwen and Li, Zhiteng and Qin, Haotong and Li, Wenbo and Guo, Yong and Liu, Xianglong and Kong, Linghe and Chen, Guihai and Zhang, Yulun and Yang, Xiaokang},
  journal={arXiv preprint arXiv:2505.05530},
  year={2025}
}
Papers by Year
All paper titles and links are kept in this README. Published work is grouped by venue year where verified; otherwise the recorded preprint year is used. Representative works, benchmarks and surveys also appear here for chronological browsing. Within each year, entries are grouped by conference or journal, with preprints at the end.
2026
- [AAAI] First-Order Error Matters: Accurate Compensation for Quantized Large Language Models [code]
- [AAAI] TR-DQ: Time-Rotation Diffusion Quantization
- [ICLR] PT²-LLM: Post-Training Ternarization for Large Language Models [code]
- [ICLR] Quant-dLLM: Post-Training Extreme Low-Bit Quantization for Diffusion Large Language Models
- [ICLR] DVD-Quant: Data-free Video Diffusion Transformers Quantization
- [ICLR] Q&C: When Quantization Meets Cache in Efficient Generation
- [ICLR] Quantized Visual Geometry Grounded Transformer
- [ICLR] Post-Training Quantization for Video Matting
- [ICLR] QVGen: Pushing the Limit of Quantized Video Generative Models
- [ICLR] QuantSparse: Comprehensively Compressing Video Diffusion Transformer with Model Quantization and Attention Sparsification [code]
- [ICLR] TurboQuant: Online Vector Quantization with Near-optimal Distortion Rate
- [ICLR] Optimal Brain Restoration for Joint Quantization and Sparsification of LLMs [code]
- [ICLR] AnyBCQ: Hardware Efficient Flexible Binary-Coded Quantization for Multi-Precision LLMs [code]
- [ICLR] Tequila: Deadzone-free Ternary Quantization for Large Language Models
- [ICLR] LogART: Pushing the Limit of Efficient Logarithmic Post-Training Quantization [code]
- [ICLR] ParoQuant: Pairwise Rotation Quantization for Efficient Reasoning LLM Inference [code]
- [ICLR] Improving Block-Wise LLM Quantization by 4-bit Generalized Normal Float Formats
- [ICLR] Channel-Aware Mixed-Precision Quantization for Efficient Long-Context Inference
- [ICLR] CodeQuant: Unified Clustering and Quantization for Enhanced Outlier Smoothing in Low-Precision Mixture-of-Experts
- [ICLR] QeRL: Beyond Efficiency - Quantization-enhanced Reinforcement Learning for LLMs [code]
- [ICLR] AutoQVLA: Not All Channels Are Equal in Vision-Language-Action Model's Quantization
- [ICLR] Achieving low-bit Muon through subspace preservation and grid quantization
- [ICLR] Shift-and-Sum Quantization for Visual Autoregressive Models
- [ICLR] Inlier-Centric Post-Training Quantization for Object Detection Models
- [ICLR] Efficient Quantization of Mixture-of-Experts with Theoretical Generalization Guarantees
- [ICLR] BBQ: Boosting Quantization Entropy with Bell Box Quantization
- [ICLR] Improving Block-Wise LLM Quantization by 4-bit Block-Wise Optimal Float (BOF4): Analysis and Variations [code]
- [ICLR] Learning under Quantization for High-Dimensional Linear Regression
- [ICLR] On-the-Fly Adaptation to Quantization: Configuration-Aware LoRA for Efficient Fine-Tuning of Quantized LLMs
- [ICLR] Bridging the Gap Between Promise and Performance for FP4 Quantization [code]
- [ICLR] KBVQ-MoE: KLT-guided SVD with Bias-Corrected Vector Quantization for MoE Large Language Models [code]
- [ICLR] UniQL: Unified Quantization and Low-rank Compression for Adaptive Edge LLMs [code]
- [ICLR] The Lattice Geometry of Neural Network Quantization: A Short Equivalence Proof of GPTQ and Babai's algorithm
- [ICLR] DPQuant: Efficient and Private Model Training via Dynamic Quantization Scheduling
- [ICLR] Towards Quantization-Aware Training for Ultra-Low-Bit Reasoning LLMs
- [ICLR] A Convergence Analysis of Adaptive Optimizers under Floating-point Quantization
- [ICLR] Training Dynamics Impact Post-Training Quantization Robustness [code]
- [ICLR] SSDi8: Accurate and Efficient 8-bit Quantization for State Space Duality
- [ICLR] The Geometry of LLM Quantization: GPTQ as Babai's Nearest Plane Algorithm
- [ICLR] PTQ4ARVG: Post-Training Quantization for AutoRegressive Visual Generation Models [code]
- [ICLR] QWHA: Quantization-Aware Walsh-Hadamard Adaptation for Parameter-Efficient Fine-Tuning on Large Language Models [code]
- [ICLR] Gradient-Aligned Calibration for Post-Training Quantization of Diffusion Models
- [ICLR] SERQ: Saliency-Aware Low-Rank Error Reconstruction for LLM Quantization
- [ICLR] Compute-Optimal Quantization-Aware Training
- [ICLR] PM-KVQ: Progressive Mixed-precision KV Cache Quantization for Long-CoT LLMs [code]
- [ICLR] Beyond Outliers: A Study of Optimizers Under Quantization
- [ICLR] Qronos: Correcting the Past by Shaping the Future... in Post-Training Quantization
- [ICLR] MicroMix: Efficient Mixed-Precision Quantization with Microscaling Formats for Large Language Models [code]
- [ICLR] TurboBoA: Faster and Exact Attention-aware Quantization without Backpropagation
- [ICLR] Beyond Uniformity: Sample and Frequency Meta Weighting for Post-Training Quantization of Diffusion Models
- [ICLR] Rethinking Residual Errors in Compensation-based LLM Quantization
- [ICLR] SPR²Q: Static Priority-based Rectifier Routing Quantization for Image Super-Resolution [code]
- [ICLR] STaMP: Sequence Transformation and Mixed Precision for Low-Precision Activation Quantization
- [CVPR Findings] Q-MambaIR: Accurate Quantized Mamba for Efficient Image Restoration
- [ICCAD] Interface-Aware KV Cache Quantization for Dense On-Chip NVM in Long-Context LLM Decoding [Scholar]
- [EMNLP] All for 1-Bit: Towards Genuine 1-Bit Post-Training Quantization for LLMs [Scholar]
- [EMNLP] Colla-Q: Toward Collaborative Experts in MoE Quantization via Minimax Precision Balancing [code]
[Scholar]
- [NeurIPS] SPHQuant: Efficient extreme low bit weight quantization for Vision-Language Models [official repository; code pending]
[Scholar]
- [NeurIPS] D²Quant: Accurate Low-bit Post-Training Weight Quantization for LLMs [code]
[Scholar]
- [NeurIPS] OSCAR: Offline Spectral Covariance-Aware Rotation for 2-bit KV Cache Quantization [code]
[Scholar]
- [NeurIPS] HESTIA: A Hessian-Guided Differentiable Quantization-Aware Training Framework for Extremely Low-Bit LLMs [code]
[Scholar]
- [NeurIPS] KroQuant: Kronecker-Structured Block Transforms for Efficient Post-Training Quantization of Diffusion Transformers [Scholar]
- [NeurIPS] AlphaQ: Calibration-Free Bit Allocation for Mixture-of-Experts Quantization [code]
[Scholar]
- [NeurIPS] MoBiQuant: Mixture-of-Bits Quantization for Token-Adaptive Any-Precision LLM [Scholar]
- [NeurIPS] Normalized Architectures are Natively 4-Bit [code]
[Scholar]
- [Visual Intelligence] An Empirical Study of Qwen3 Quantization [code]
[arXiv]
- [arXiv] EdgeRazor: A Lightweight Framework for Large Language Models via Mixed-Precision Quantization-Aware Distillation [code]
- [arXiv] Sherry: Hardware-Efficient 1.25-Bit Ternary Quantization via Fine-grained Sparsification [code]
- [arXiv] QuantLRM: Quantization of Large Reasoning Models via Fine-Tuning Signals
- [arXiv] SliderQuant: Accurate Post-Training Quantization for LLMs
- [arXiv] What Makes Low-Bit Quantization-Aware Training Work for Reasoning LLMs? A Systematic Study
- [arXiv] OneComp: One-Line Revolution for Generative AI Model Compression [Code]
2025
- [AAAI] MPQ-DM: Mixed Precision Quantization for Extremely Low Bit Diffusion Models
- [AAAI] JAQ: Joint Efficient Architecture Design and Low-Bit Quantization
- [AAAI] OAC: Output-adaptive Calibration for Accurate Post-Training Quantization of LLMs
- [AAAI] Optimizing Quantized Diffusion Models via Distillation with Decay Timestep-Aware Loss
- [AAAI] Quantifiable Quantization Sensitivity of Diffusion Models
- [AAAI] TCAQ-DM: Timestep-Channel Adaptive Quantization for Diffusion Models
- [AAAI] Thinking in Granularity: Dynamic Quantization for Image Super-Resolution by Intriguing Multi-Granularity Clues [code]
- [AAAI] D2-DPM: Dual Denoising for Quantized Diffusion Probabilistic Models [code]
- [ICLR] ARB-LLM: Alternating Refined Binarizations for Large Language Models [code]
- [ICLR] BinaryDM: Accurate Weight Binarization for Efficient Diffusion Models [code]
- [ICLR] CBQ: Cross-Block Quantization for Large Language Models
- [ICLR] DGQ: Distribution-Aware Group Quantization for Text-to-Image Diffusion Models
- [ICLR] LeanQuant: Accurate and Scalable Large Language Model Quantization with Loss-error-aware Grid
- [ICLR] OSTQuant: Refining Large Language Model Quantization with Orthogonal and Scaling Transformations for Better Distribution Fitting [code]
- [ICLR] QERA: an Analytical Framework for Quantization Error Reconstruction [code]
- [ICLR] SpinQuant: LLM Quantization with Learned Rotations [code]
- [ICLR] SVDQuant: Absorbing Outliers by Low-Rank Component for 4-Bit Diffusion Models [code]
- [ICLR] ViDiT-Q: Efficient and Accurate Quantization of Diffusion Transformers for Image and Video Generation [code]
- [ICLR] SynQ: Accurate Zero-shot Quantization by Synthesis-aware Fine-tuning [code]
- [MLSys] QServe: W4A8KV4 Quantization and System Co-design for Efficient LLM Serving [code]
- [CVPR] PassionSR: Post-Training Quantization with Adaptive Scale in One-Step Diffusion based Image Super-Resolution [code]
- [CVPR] Quantization without Tears
- [CVPR] APHQ-ViT: Post-Training Quantization with Average Perturbation Hessian Based Reconstruction for Vision Transformer [code]
- [SIGMOD] Practical and Asymptotically Optimal Quantization of High-Dimensional Vectors in Euclidean Space for Approximate Nearest Neighbor Search [code]
- [ICML] Q-VDiT: Towards Accurate Quantization and Distillation of Video-Generation Diffusion Transformers [code]
- [ICML] SliM-LLM: Salience-Driven Mixed-Precision Quantization for Large Language Models [code]
- [ICML] FlatQuant: Flatness Matters for LLM Quantization [code]
- [ICML] RoSTE: An Efficient Quantization-Aware Supervised Fine-Tuning Approach for Large Language Models [code]
- [ICML] GANQ: GPU-Adaptive Non-Uniform Quantization for Large Language Models
- [ICML] Modulated Diffusion: Accelerating Generative Modeling with Modulated Quantization [code]
- [ICML] GuidedQuant: Large Language Model Quantization via Exploiting End Loss Guidance [code]
- [ICML] ResQ: Mixed-Precision Quantization of Large Language Models with Low-Rank Residuals [code]
- [ICML] MxMoE: Mixed-precision Quantization for MoE with Accuracy and Performance Co-Design [code]
- [ICML] Learning from Loss Landscape: Generalizable Mixed-Precision Quantization via Adaptive Sharpness-Aware Gradient Aligning
- [ICML] PARQ: Piecewise-Affine Regularized Quantization [code]
- [ICML] Quamba2: A Robust and Scalable Post-training Quantization Framework for Selective State Space Models [code]
- [ICML] LRA-QViT: Integrating Low-Rank Approximation and Quantization for Robust and Efficient Vision Transformers
- [ICML] BoA: Attention-aware Post-training Quantization without Backpropagation
- [ICML] MoEQuant: Enhancing Quantization for Mixture-of-Experts Large Language Models via Expert-Balanced Sampling and Affinity Guidance [code]
- [ICML] NestQuant: nested lattice quantization for matrix products and LLMs
- [ICML] Q-resafe: Assessing Safety Risks and Quantization-aware Safety Patching for Quantized Large Language Models [code]
- [ICML] SLiM: One-shot Quantization and Sparsity with Low-rank Approximation for LLM Weight Compression [code]
- [ICML] QT-DoG: Quantization-Aware Training for Domain Generalization [code]
- [ICML] Matryoshka Quantization
- [ICML] Merge-Friendly Post-Training Quantization for Multi-Target Domain Adaptation [code]
- [ICML] Layer-wise Quantization for Quantized Optimistic Dual Averaging
- [ICML] Outlier-Aware Post-Training Quantization for Discrete Graph Diffusion Models
- [ICML] BlockDialect: Block-wise Fine-grained Mixed Format Quantization for Energy-Efficient LLM Inference
- [ICML] GPTAQ: Efficient Finetuning-Free Quantization with Asymmetric Calibration [code]
- [ICML] Optimizing Large Language Model Training Using FP4 Quantization
- [ICML] SKIM: Any-bit Quantization Pushing The Limits of Post-Training Quantization
- [ICML] SageAttention2: Efficient Attention with Thorough Outlier Smoothing and Per-thread INT4 Quantization [code]
- [ACL] EfficientQAT: Efficient Quantization-Aware Training for Large Language Models [code]
- [ACL] L4Q: Parameter Efficient Quantization-Aware Fine-Tuning on Large Language Models
- [ACL] MoQAE: Mixed-Precision Quantization for Long-Context LLM Inference via Mixture of Quantization-Aware Experts
- [ACL] Outlier-Safe Pre-Training for Robust 4-Bit Quantization of Large Language Models
- [ACL] PTQ1.61: Push the Real Limit of Extremely Low-Bit Post-Training Quantization Methods for Large Language Models [code]
- [ACL] Unifying Uniform and Binary-coding Quantization for Accurate Compression of Large Language Models
- [ACL] “Give Me BF16 or Give Me Death”? Accuracy-Performance Trade-Offs in LLM Quantization
- [ACL Findings] Achieving Binary Weight and Activation for LLMs using Post-Training Quantization
- [ICCV] Scheduling Weight Transitions for Quantization-Aware Training [code]
- [ICCV] Task-Specific Zero-shot Quantization-Aware Training for Object Detection [code]
- [ICCV] OuroMamba: A Data-Free Quantization Framework for Vision Mamba
- [ICCV] FedWSQ: Efficient Federated Learning with Weight Standardization and Distribution-Aware Non-Uniform Quantization [code]
- [ICCV] Semantic Alignment and Reinforcement for Data-Free Quantization of Vision Transformers [code]
- [ICCV] QuantCache: Adaptive Importance-Guided Quantization with Hierarchical Latent and Layer Caching for Video Generation [code]
- [ICCV] MixA-Q: Revisiting Activation Sparsity for Vision Transformers from a Mixed-Precision Quantization Perspective
- [ICCV] DMQ: Dissecting Outliers of Diffusion Models for Post-Training Quantization [code]
- [ICCV] AHCPTQ: Accurate and Hardware-Compatible Post-Training Quantization for Segment Anything Model
- [ICCV] MSQ: Memory-Efficient Bit Sparsification Quantization
- [ICCV] QuEST: Low-bit Diffusion Model Quantization via Efficient Selective Finetuning [code]
- [ACM MM] DilateQuant: Accurate and Efficient Quantization-Aware Training for Diffusion Models via Weight Dilation
- [ACM MM] Learning Binarized Representations with Pseudo-positive Distillation
- [ACM MM] MQuant: Unleashing the Inference Potential of Multimodal Large Language Models with Post-Training Quantization
- [ACM MM] Pushing the Limit of Binarized Neural Network for Image Super Resolution with Smooth Information Transmission
- [ACM MM] Quantization Meets OOD: Generalizable Quantization-aware Training from a Flatness Perspective
- [EMNLP] AMQ: Enabling AutoML for Mixed-precision Weight-Only Quantization of Large Language Models
- [EMNLP] Does quantization affect models' performance on long-input and long-output tasks?
- [EMNLP Findings] KurTail: Kurtosis-based LLM Quantization
- [NeurIPS] S²Q-VDiT: Accurate Quantized Video Diffusion Transformer with Salient Data and Sparse Token Distillation [code]
- [NeurIPS] DartQuant: Efficient Rotational Distribution Calibration for LLM Quantization [code]
- [NeurIPS] A Double Norm